
Finetuning Llms For Human Behavior Prediction In Social Science

Finetuning LLMs for Human Behavior Prediction in Social Science ...

Figure 1 from Finetuning LLMs for Human Behavior Prediction in Social ...

Paper page - Finetuning LLMs for Human Behavior Prediction in Social ...

[논문 리뷰] Aligning Video Models with Human Social Judgments via Behavior ...
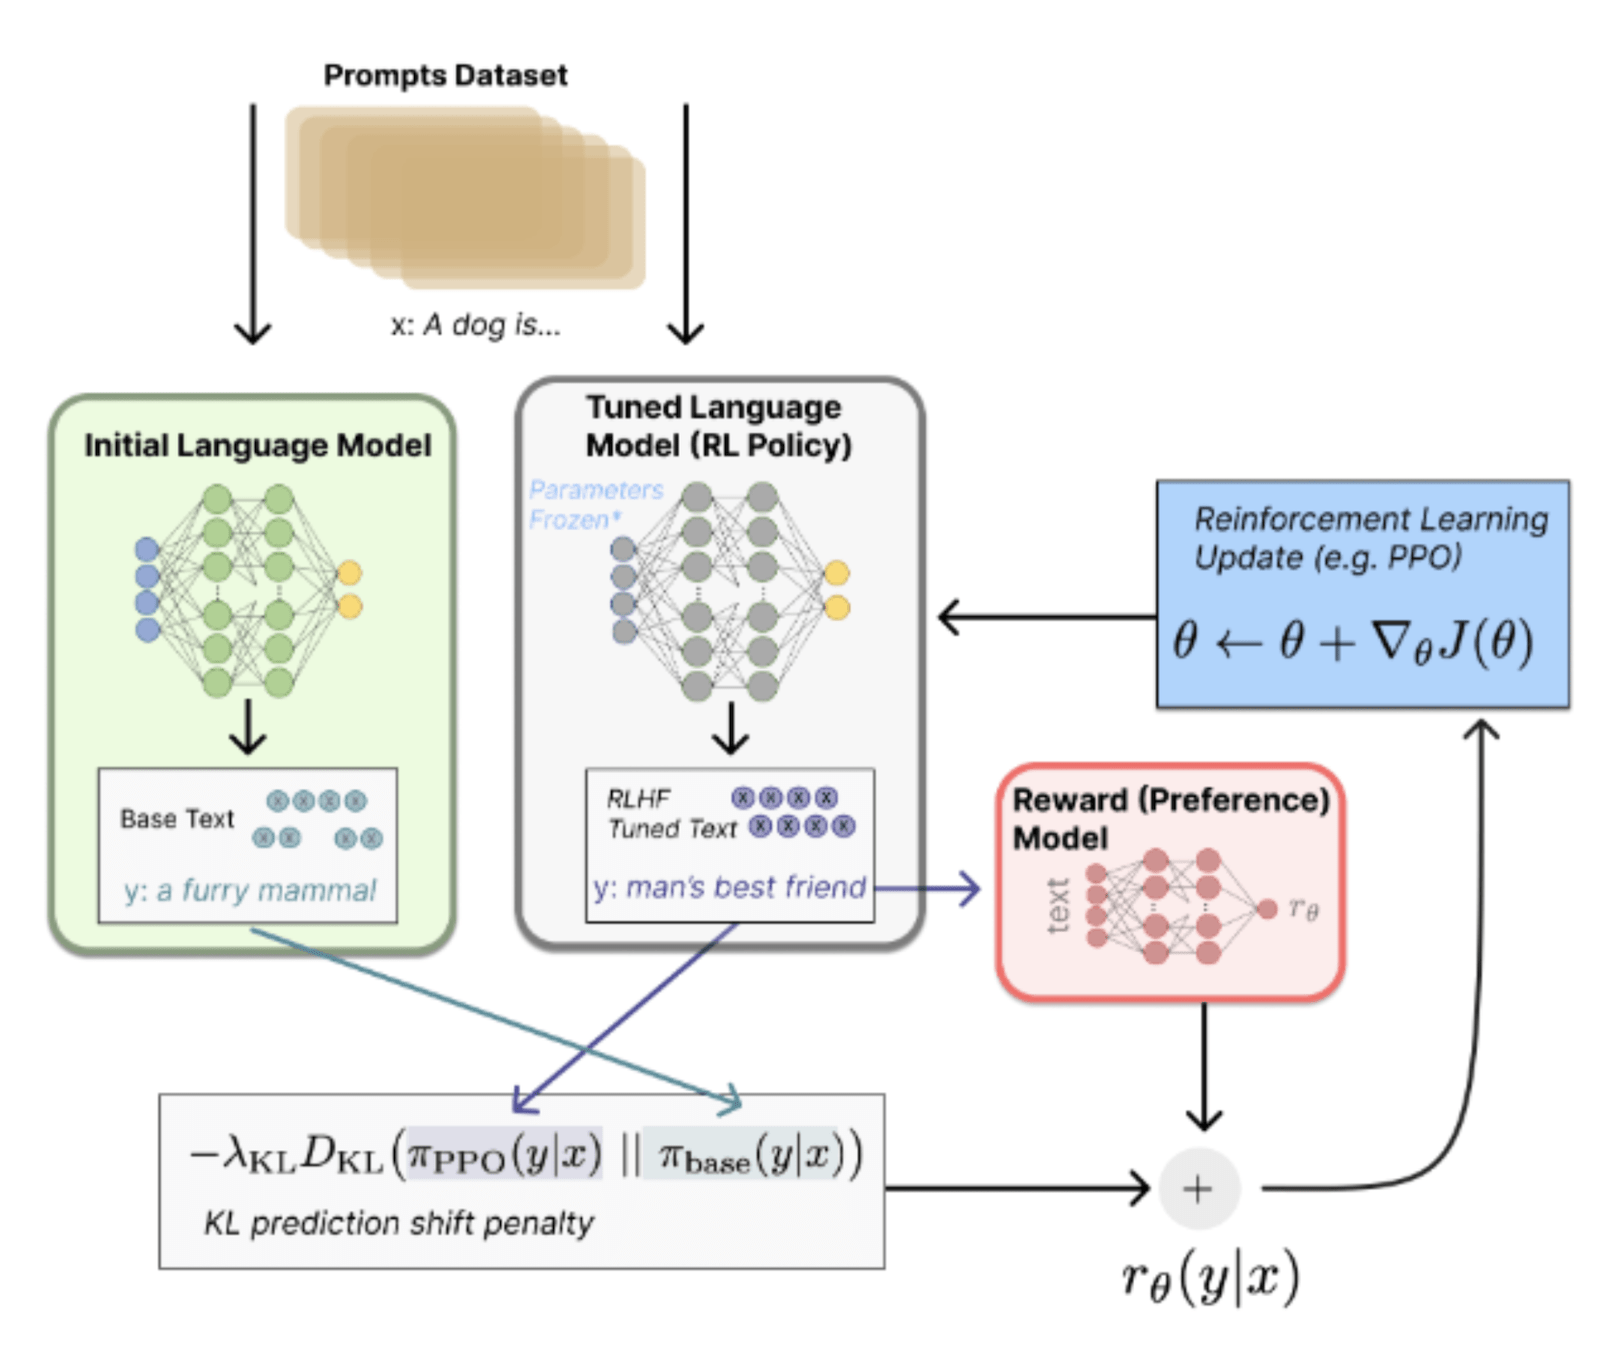
Reinforcement Learning from Human Feedback (RLHF) for LLMs - deepsense.ai

LLMs for Social Simulation: Progress, Opportunities and Challenges ...

TruthTensor: Evaluating LLMs Human Imitation through Prediction Market ...
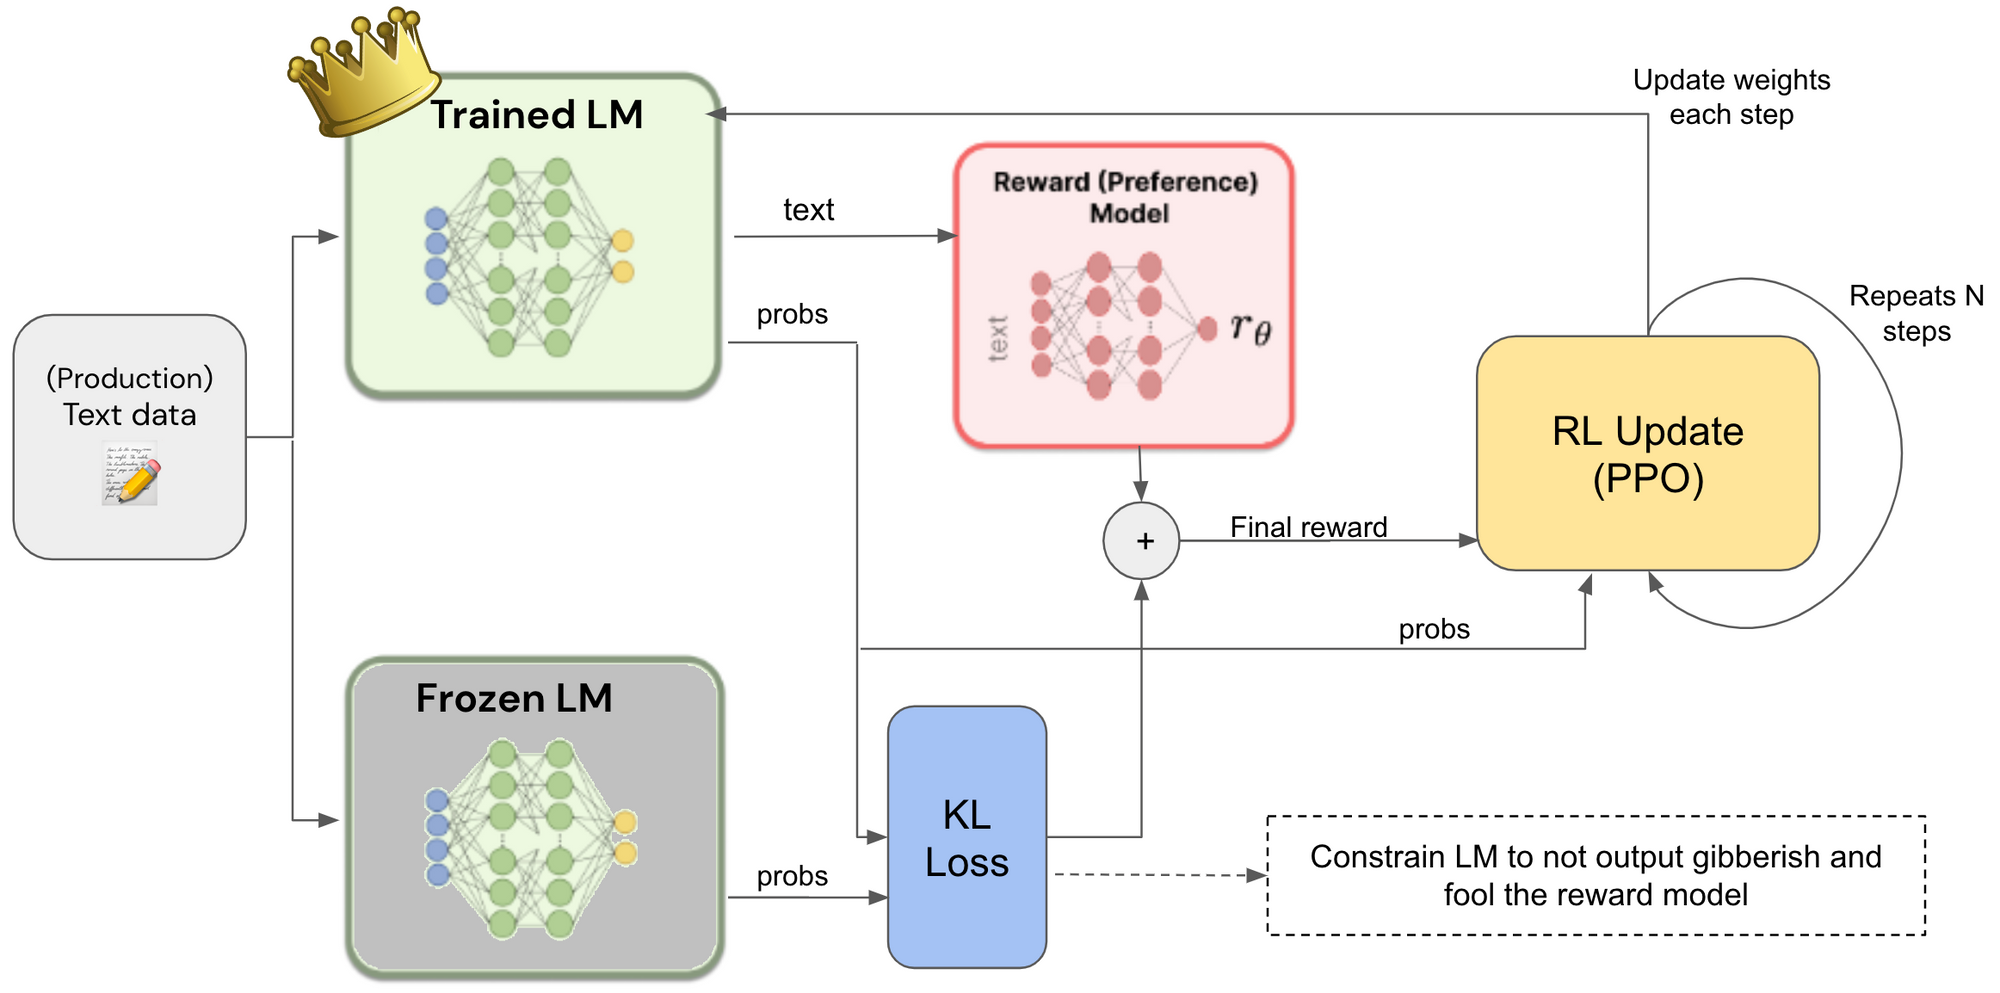
Reinforcement learning with human feedback (RLHF) for LLMs

Finetuning LLMs | PDF | Machine Learning | Information Science

Practical Tips for Finetuning LLMs Using LoRA (Low-Rank Adaptation)
Advertisement Space (300x250)

Detailed Visual Guide for Finetuning LLMs | by Parth Chokhra | Data ...

(PDF) Fine-tuning LLMs in behavioral psychology for scalable health ...

Finetuning in large language models | ai-data-science

Finetuning LLMs Efficiently with Adapters

Figure 3 from Instruction-tuning Aligns LLMs to the Human Brain ...

Figure 1 from Instruction-tuning Aligns LLMs to the Human Brain ...

LLM Agents as Social Scientists: A Human–AI Collaborative Platform for ...

[论文评述] Beyond Believability: Accurate Human Behavior Simulation with ...

Fine-tuning Open LLMs with Reinforcement Learning from Human Feedback ...

Figure 3 from The Challenge of Using LLMs to Simulate Human Behavior: A ...
Advertisement Space (336x280)

How to Fine-Tune LLMs for Domain-Specific Tasks | by Parth Raval | Medium

Parameter-Efficient Fine-Tuning Guide for LLM | Towards Data Science

Fine-tuning Open LLMs with Reinforcement Learning from Human Feedback ...
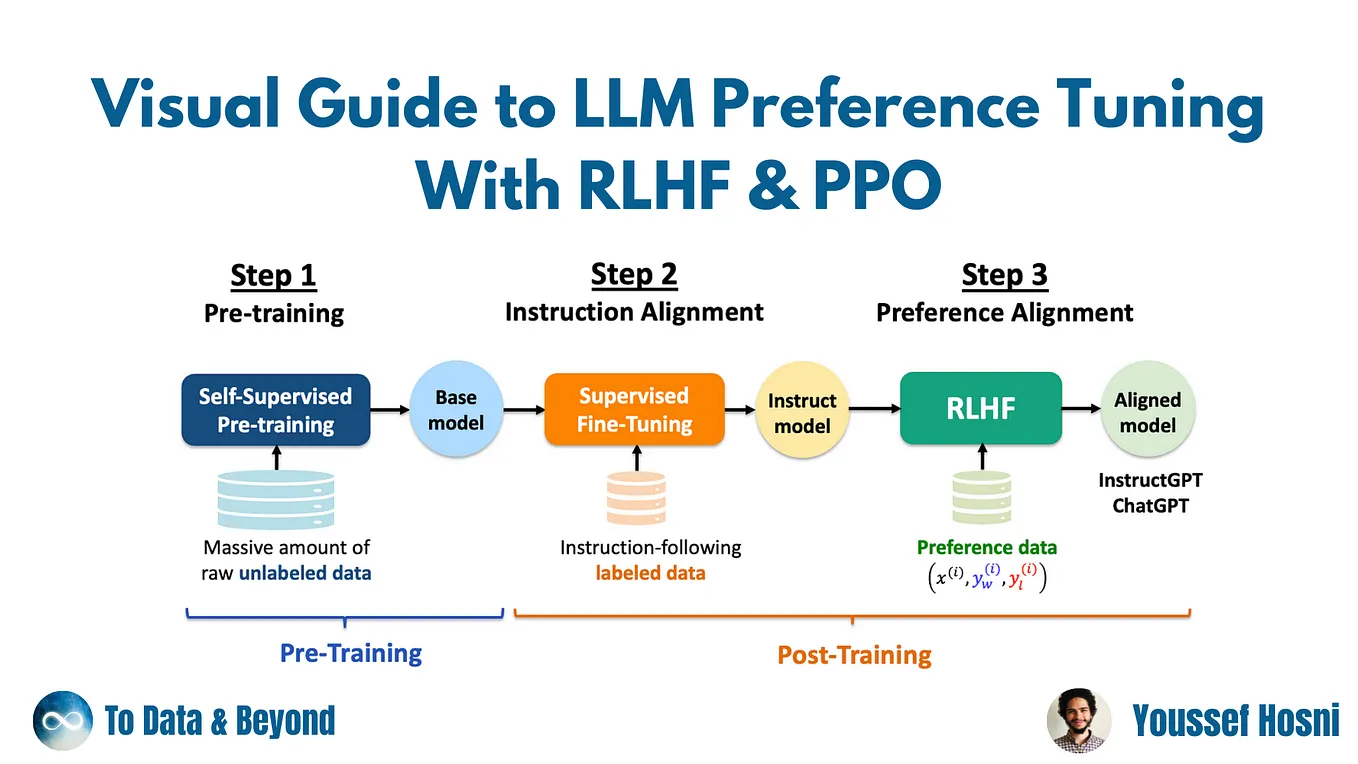
Fine-Tuning vs. Human Guidance: SFT and RLHF in Language Model Tuning ...
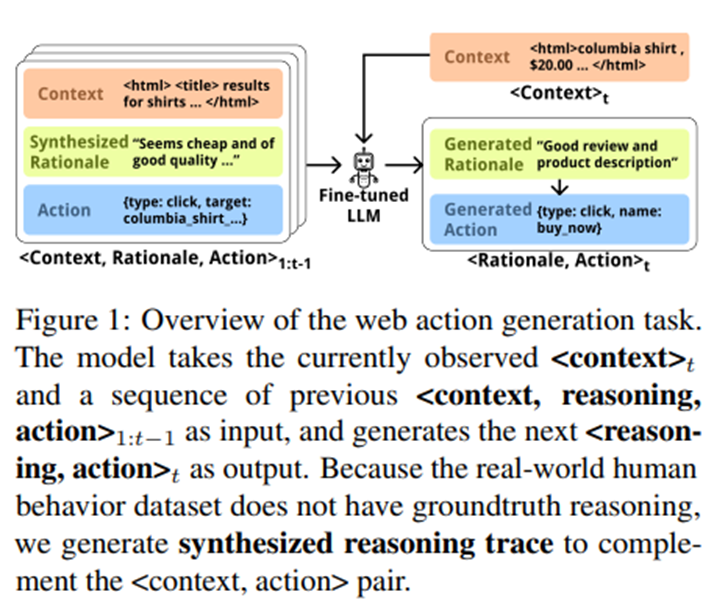
Beyond Believability: Accurate Human Behavior Simulation with Fine ...
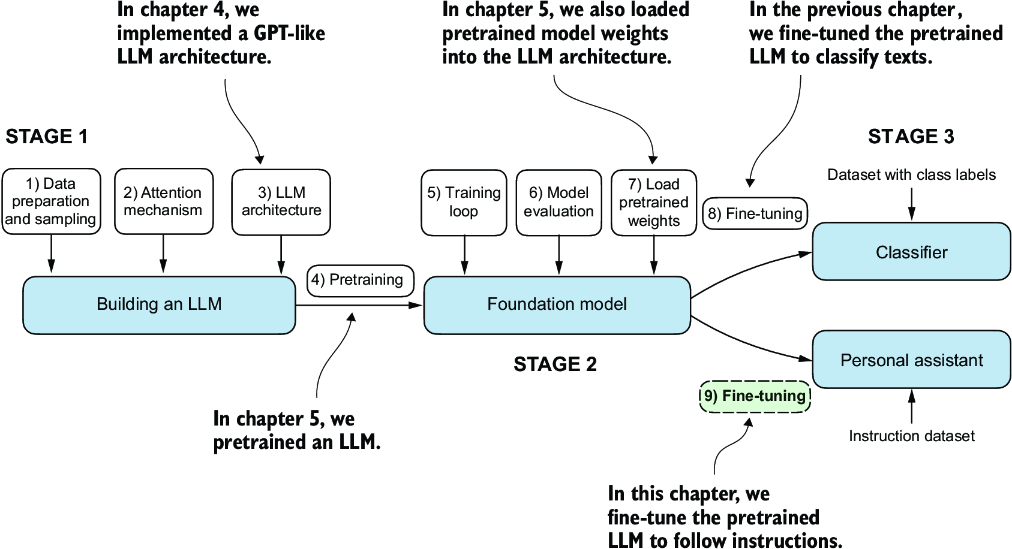
LLMs From Scratch - Chapter 7: Fine-tuning for Instruction Following ...

Re-training Strategy for fine-tuned LLMs

Figure 2 from The Challenge of Using LLMs to Simulate Human Behavior: A ...
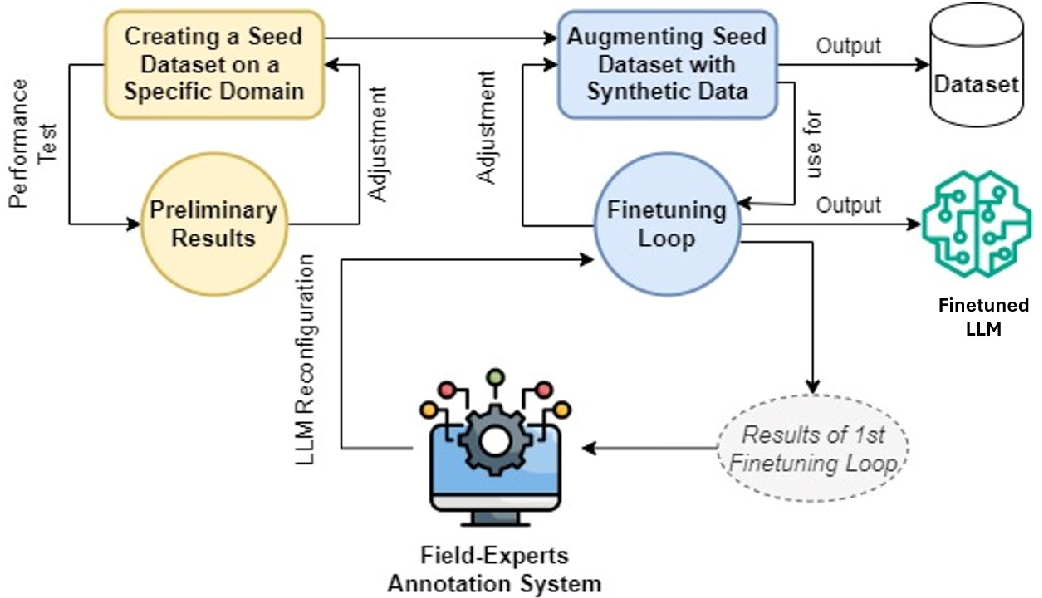
Figure 2 from Active Learning Methodology in LLMs Fine-Tuning ...

Fine-tuning Open LLMs with Reinforcement Learning from Human Feedback ...
Advertisement Space (336x280)

How to Improve Machine Utilization for Multiple Fine-Tuned LLMs with ...

Fine-Tuning LLMs With Fine-Grained Human Feedback On Text Spans 2512 ...
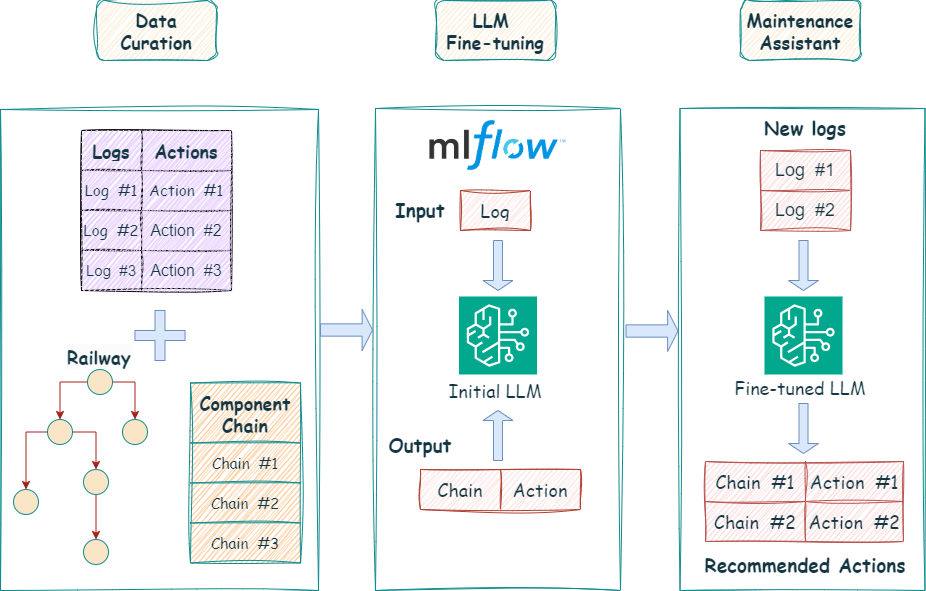
How To Generate Synthetic Data for Fine-Tuning LLMs with AI Alignment ...

Rethinking Scale: The Efficacy of Fine-Tuned Open-Source LLMs in Large ...
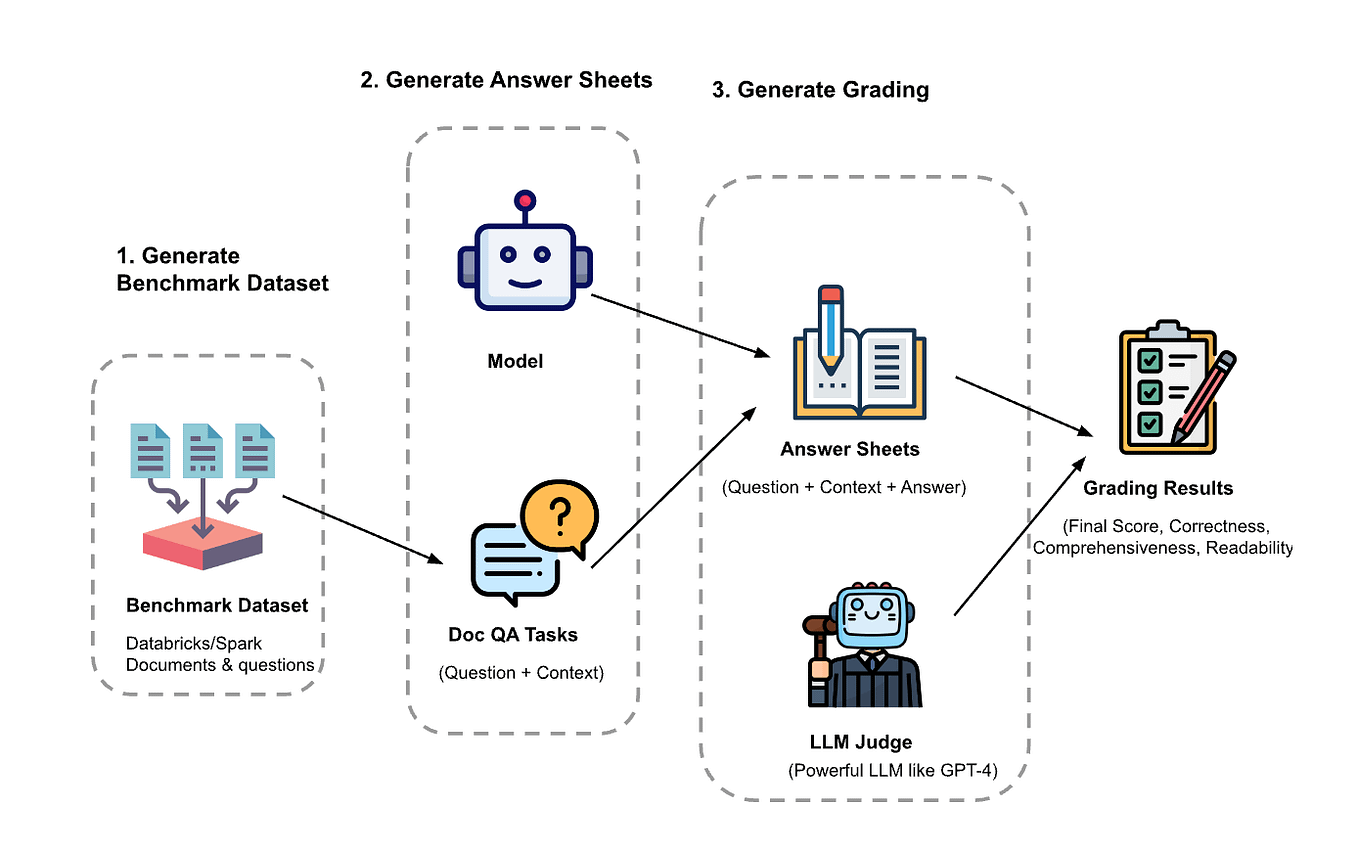
How To Generate Synthetic Data for Fine-Tuning LLMs with AI Alignment ...
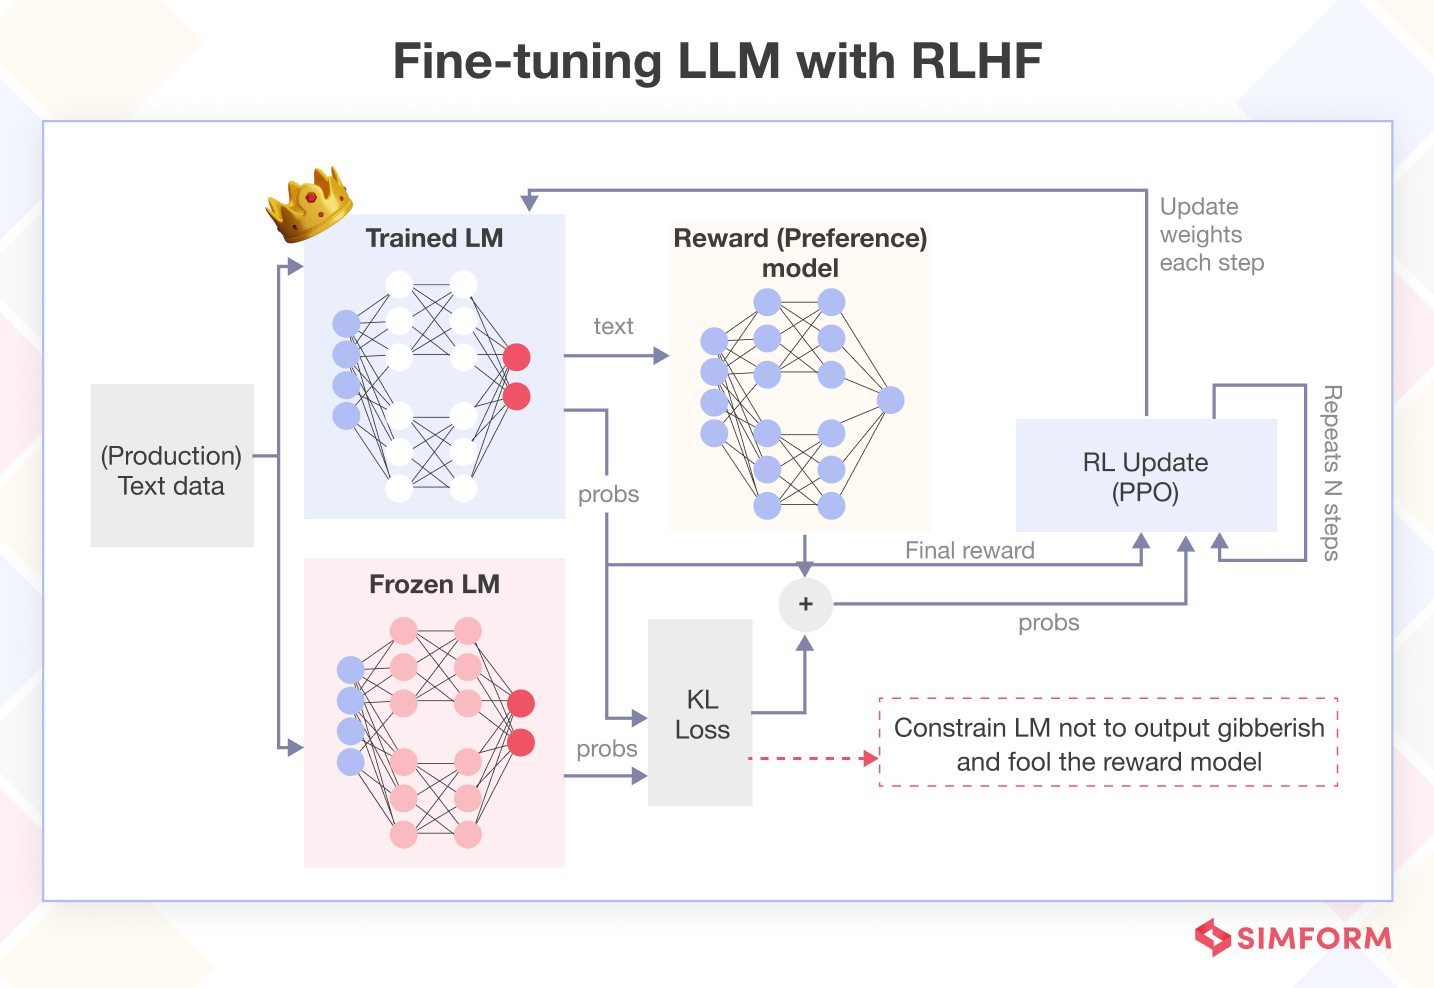
What is Reinforcement Learning from Human Feedback (RLHF)?