
Figure 1 From Hermes Kv Cache As Hierarchical Memory For Efficient
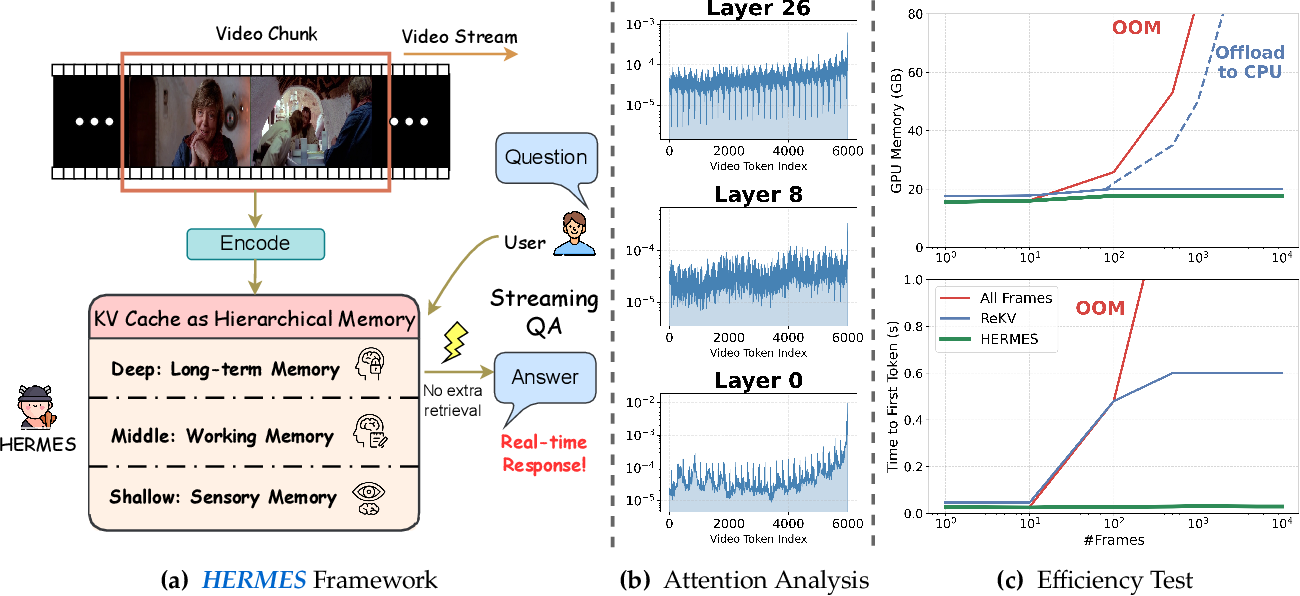
Figure 1 from HERMES: KV Cache as Hierarchical Memory for Efficient ...
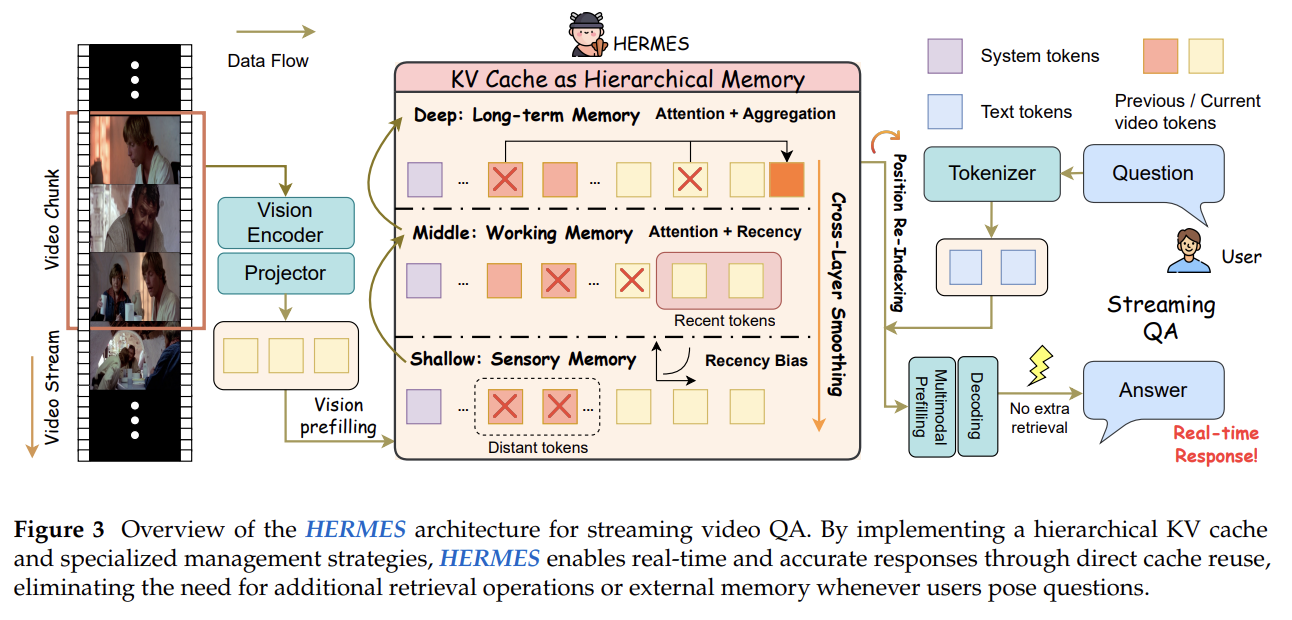
[Paper review] HERMES: KV Cache as Hierarchical Memory for Efficient ...
HERMES: KV Cache as Hierarchical Memory for Efficient Streaming Video ...

Paper page - HERMES: KV Cache as Hierarchical Memory for Efficient ...
HERMES: KV Cache as Hierarchical Memory for Efficient Streaming Video ...

HERMES: KV Cache as Hierarchical Memory for Efficient Streaming Video ...
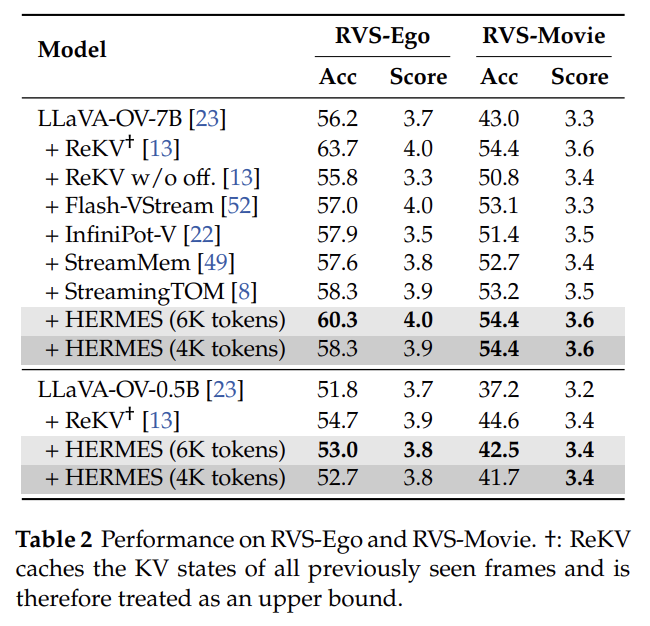
[Paper review] HERMES: KV Cache as Hierarchical Memory for Efficient ...
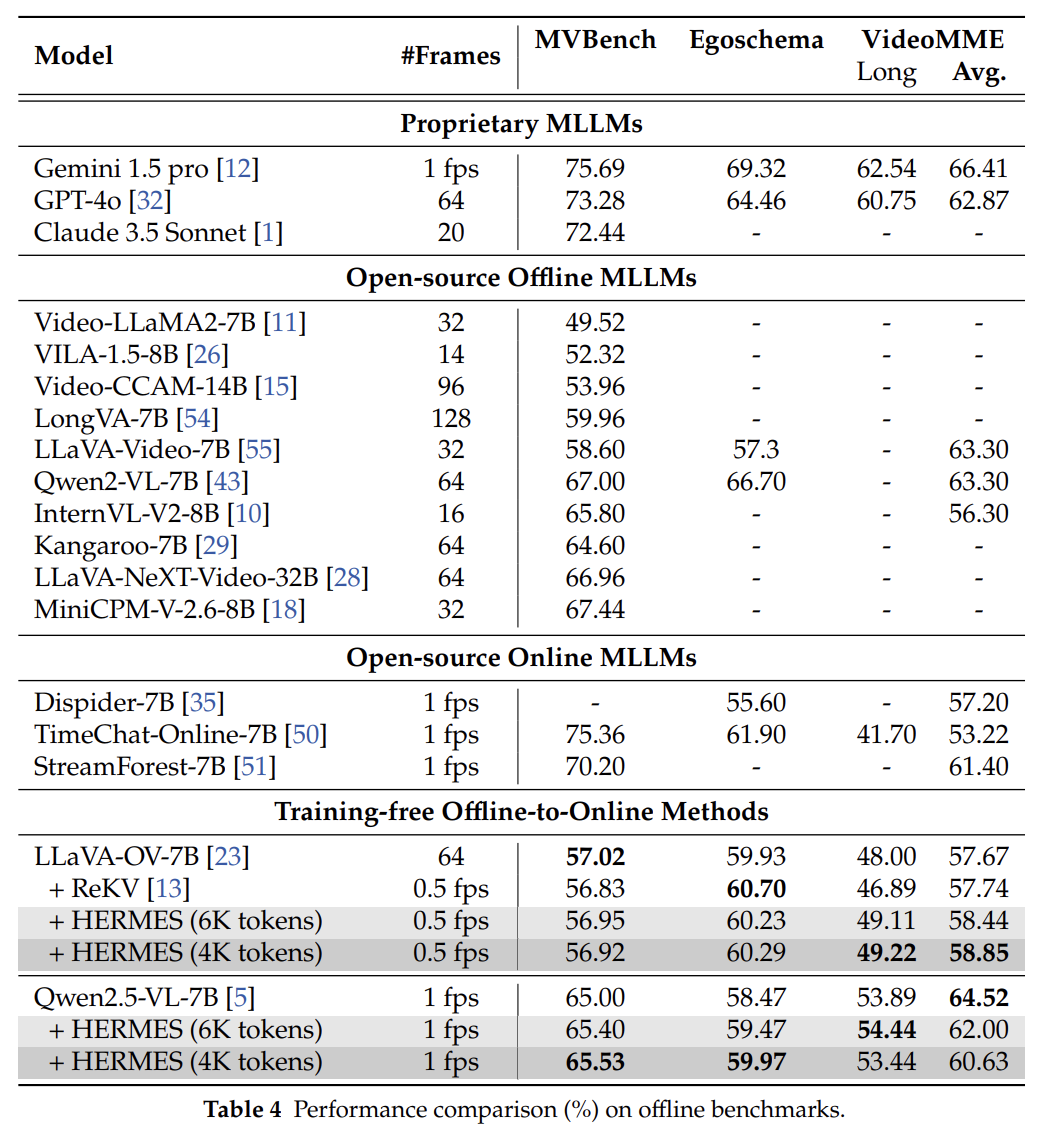
[Paper review] HERMES: KV Cache as Hierarchical Memory for Efficient ...
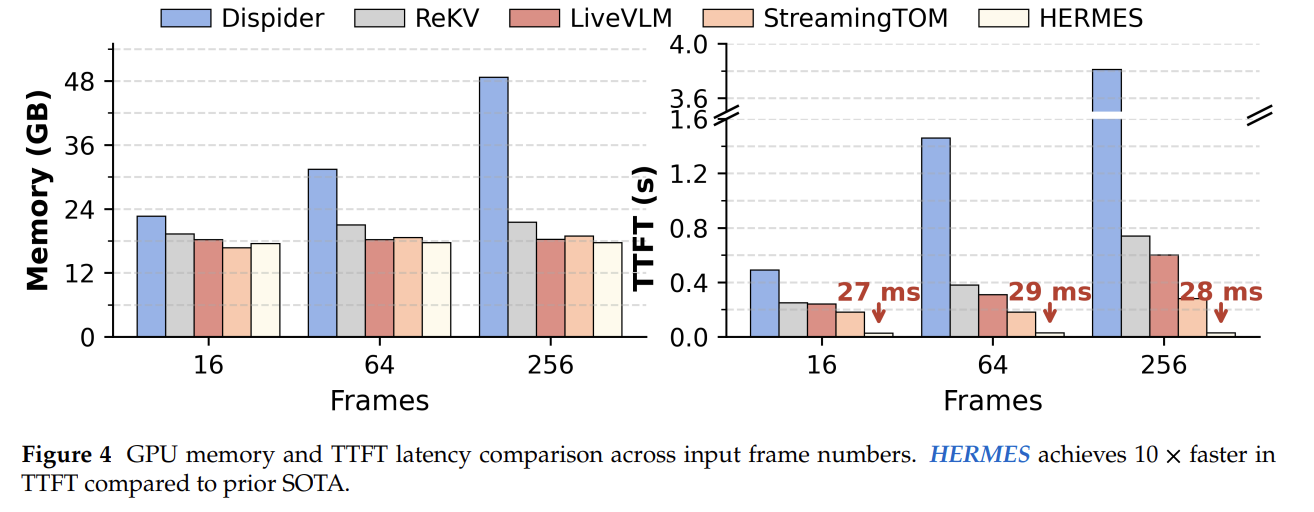
[Paper review] HERMES: KV Cache as Hierarchical Memory for Efficient ...
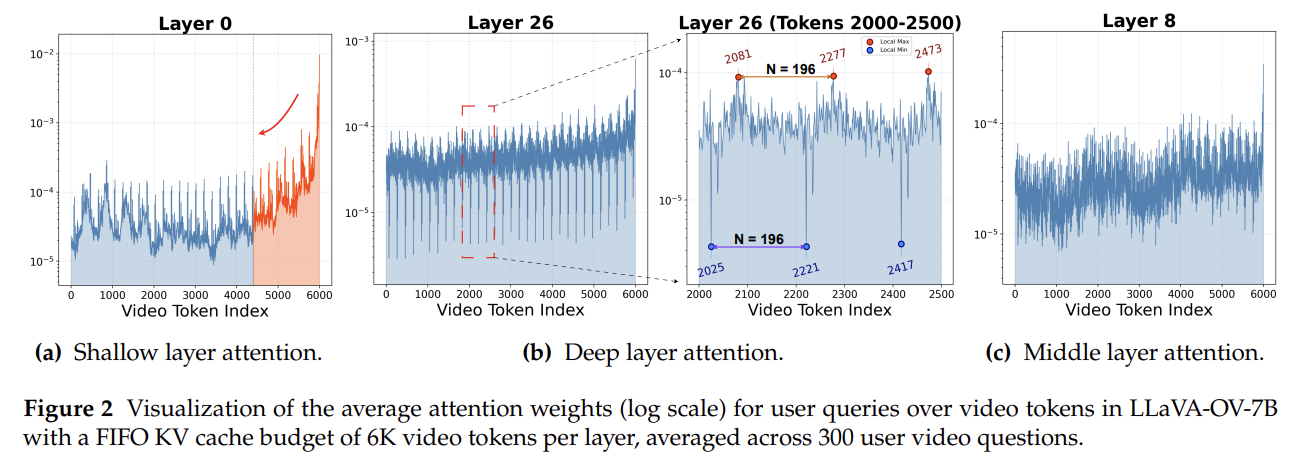
[Paper review] HERMES: KV Cache as Hierarchical Memory for Efficient ...
Advertisement Space (300x250)
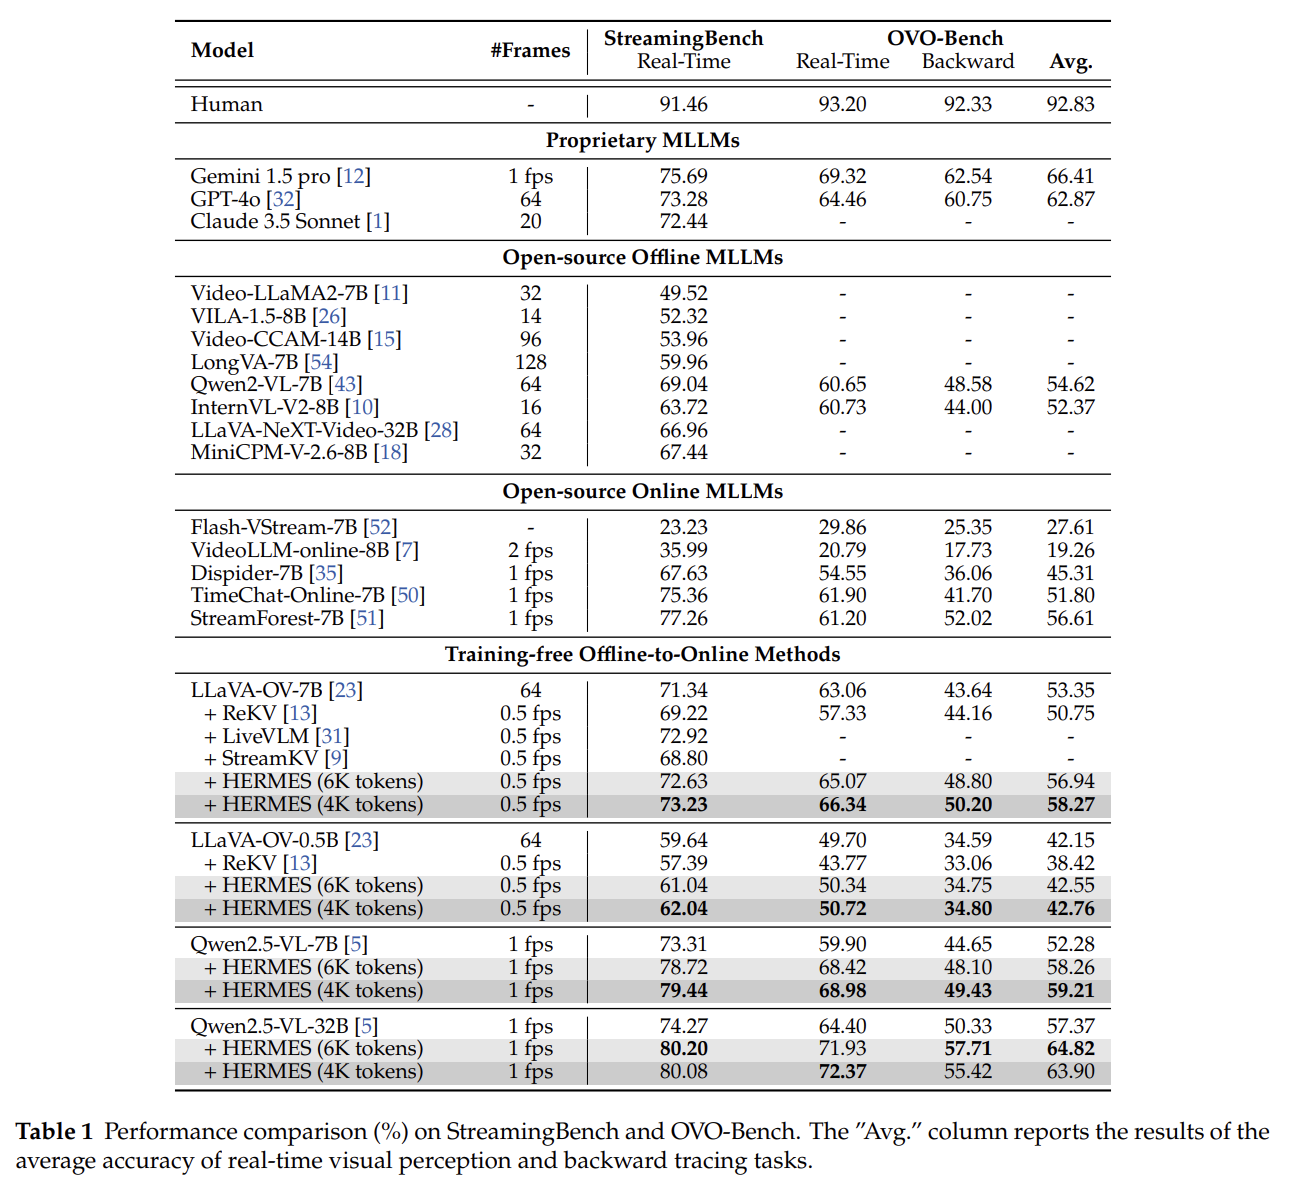
[Paper review] HERMES: KV Cache as Hierarchical Memory for Efficient ...
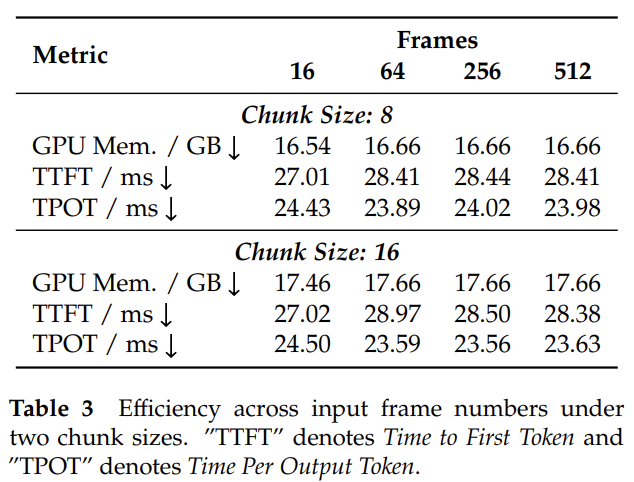
[Paper review] HERMES: KV Cache as Hierarchical Memory for Efficient ...
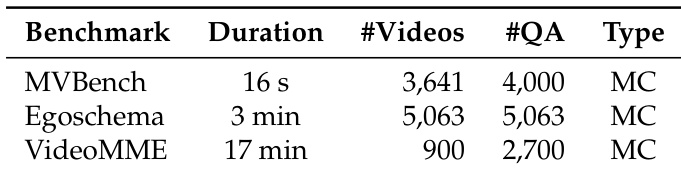
HERMES: KV Cache as Hierarchical Memory for Efficient Streaming Video ...

Figure 1 from Efficient KV Cache Spillover Management on Memory ...
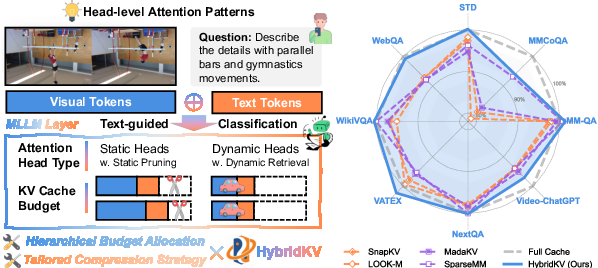
Figure 1 from HybridKV: Hybrid KV Cache Compression for Efficient ...

Figure 1 from KV Cache Optimization Strategies for Scalable and ...
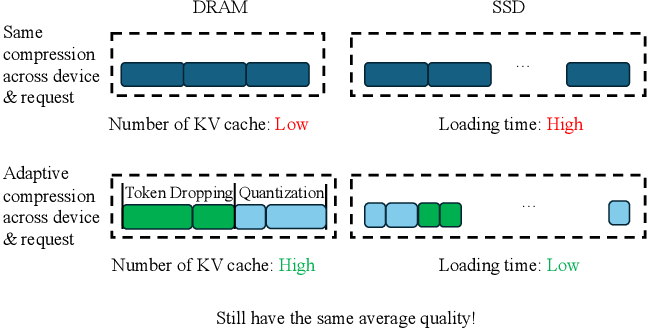
Figure 1 from AdaptCache: KV Cache Native Storage Hierarchy for Low ...

Figure 1 from KEEP: A KV-Cache-Centric Memory Management System for ...

Figure 1 from Accelerating LLM Inference via Dynamic KV Cache Placement ...

[2412.05896] XKV: Personalized KV Cache Memory Reduction for Long ...
Advertisement Space (336x280)
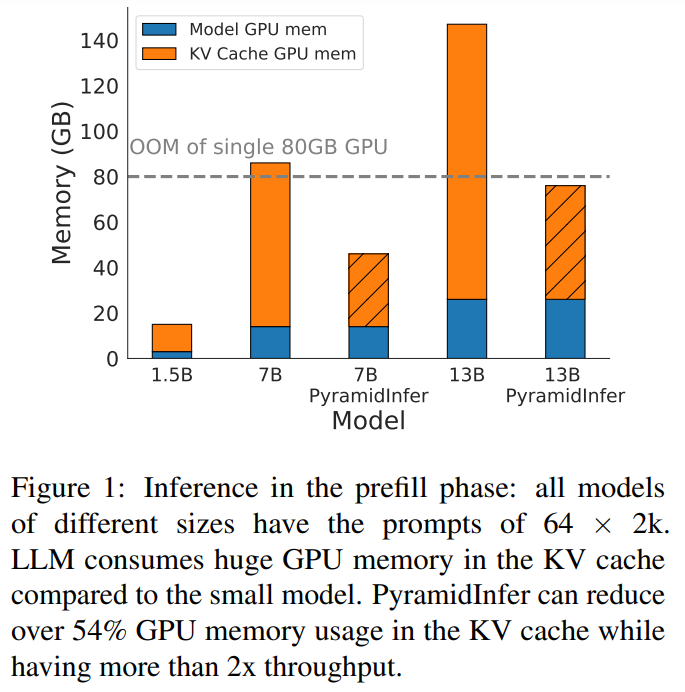
PyramidInfer: Allowing Efficient KV Cache Compression for Scalable LLM ...
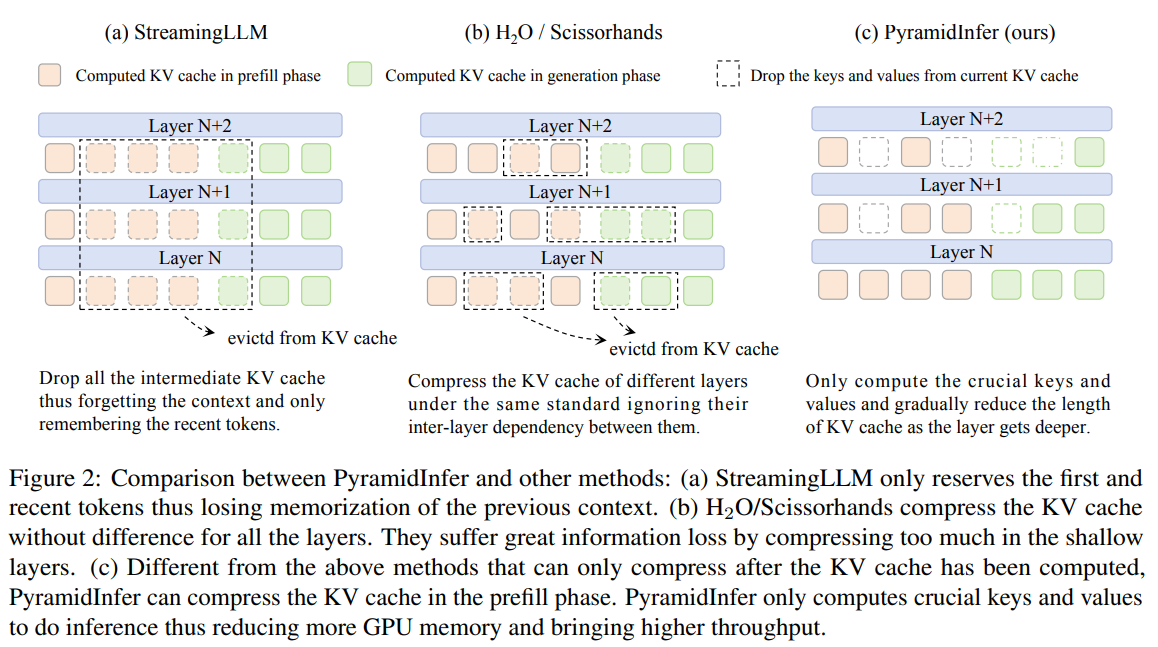
PyramidInfer: Allowing Efficient KV Cache Compression for Scalable LLM ...

Hierarchical Adaptive Eviction for KV Cache Management in Multimodal ...

Figure 1 from Cost-Efficient VM Selection for Cloud-Based LLM Inference ...

Efficient KV Cache Spillover Management on Memory-Constrained GPU for ...
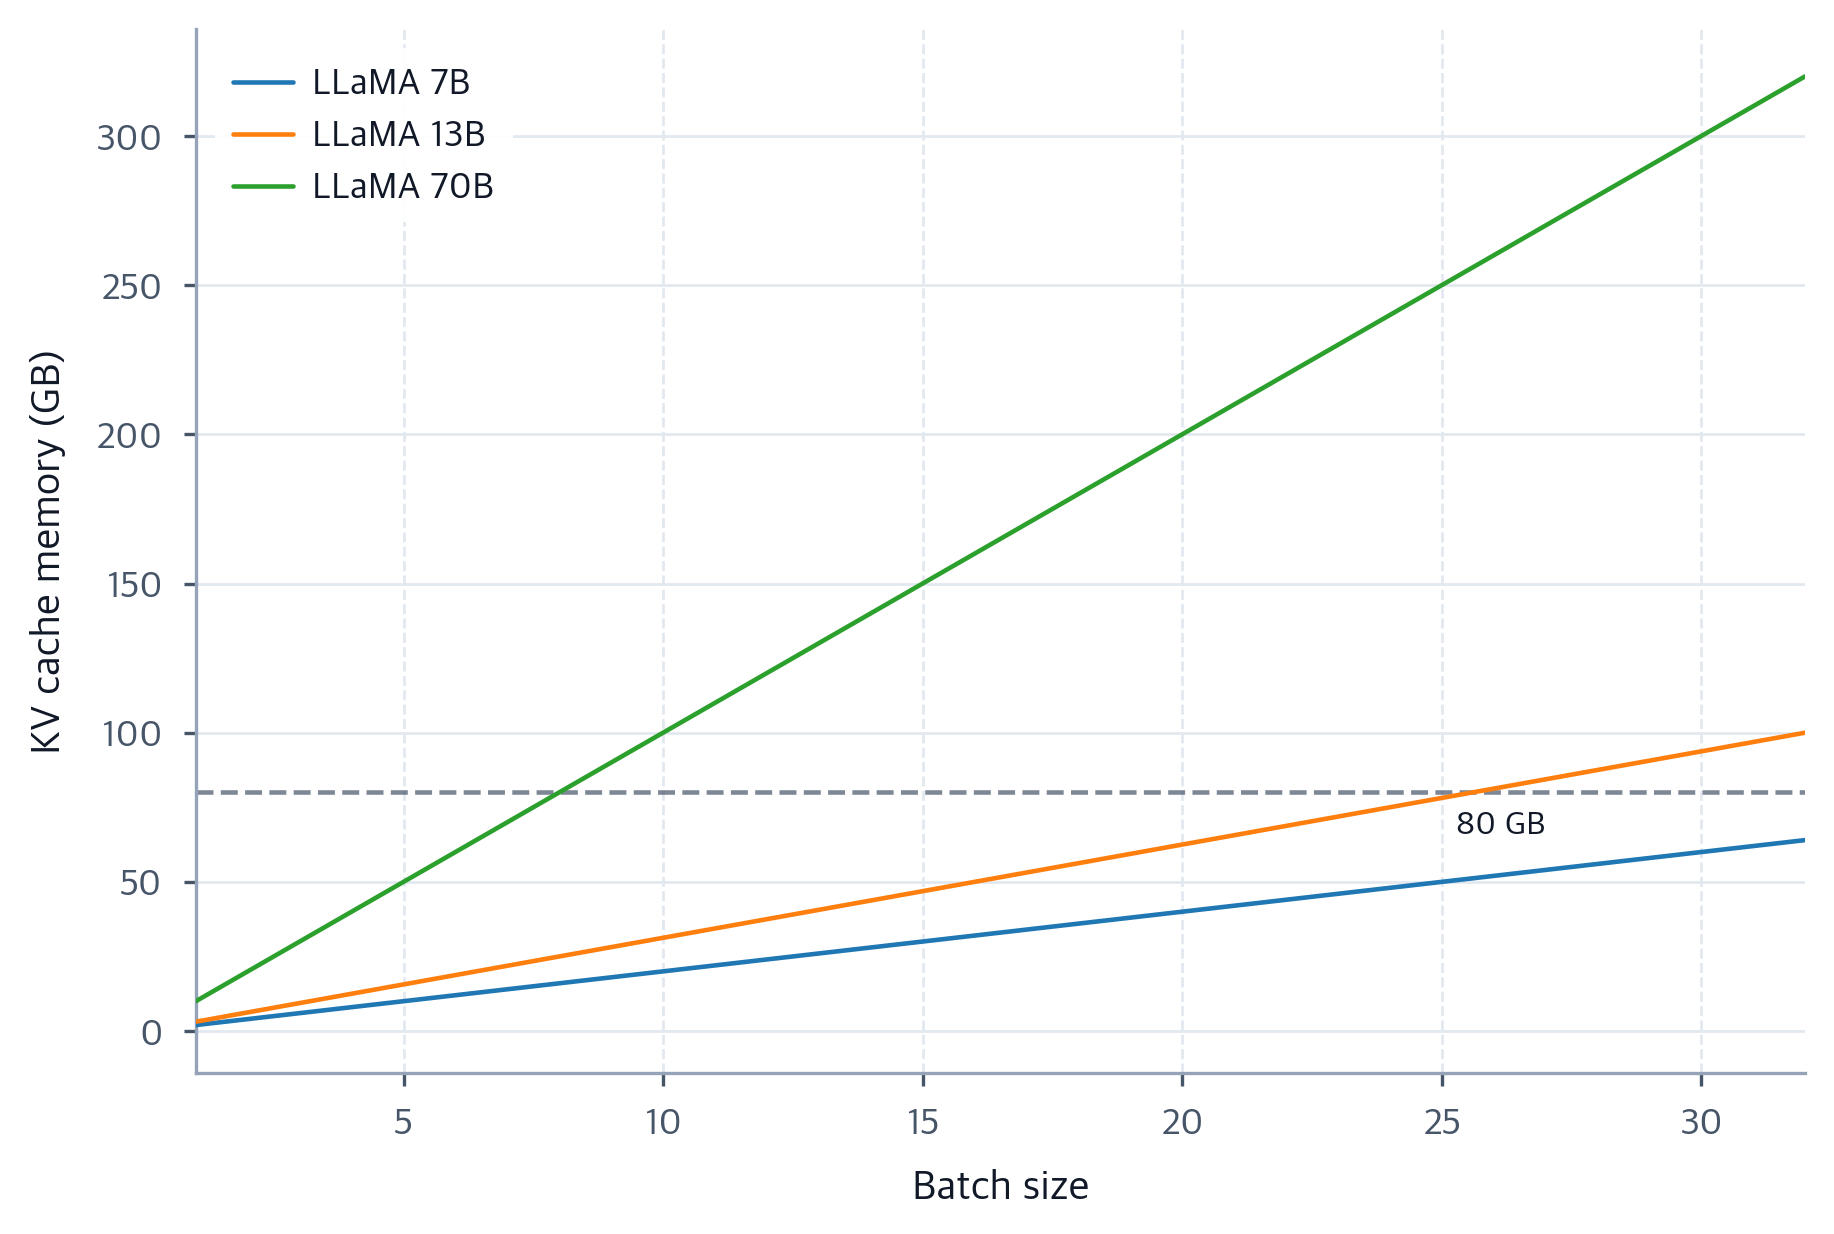
KV Cache Explained: Efficient Attention for LLM Generation ...
LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference ...

Paper page - LMCache: An Efficient KV Cache Layer for Enterprise-Scale ...
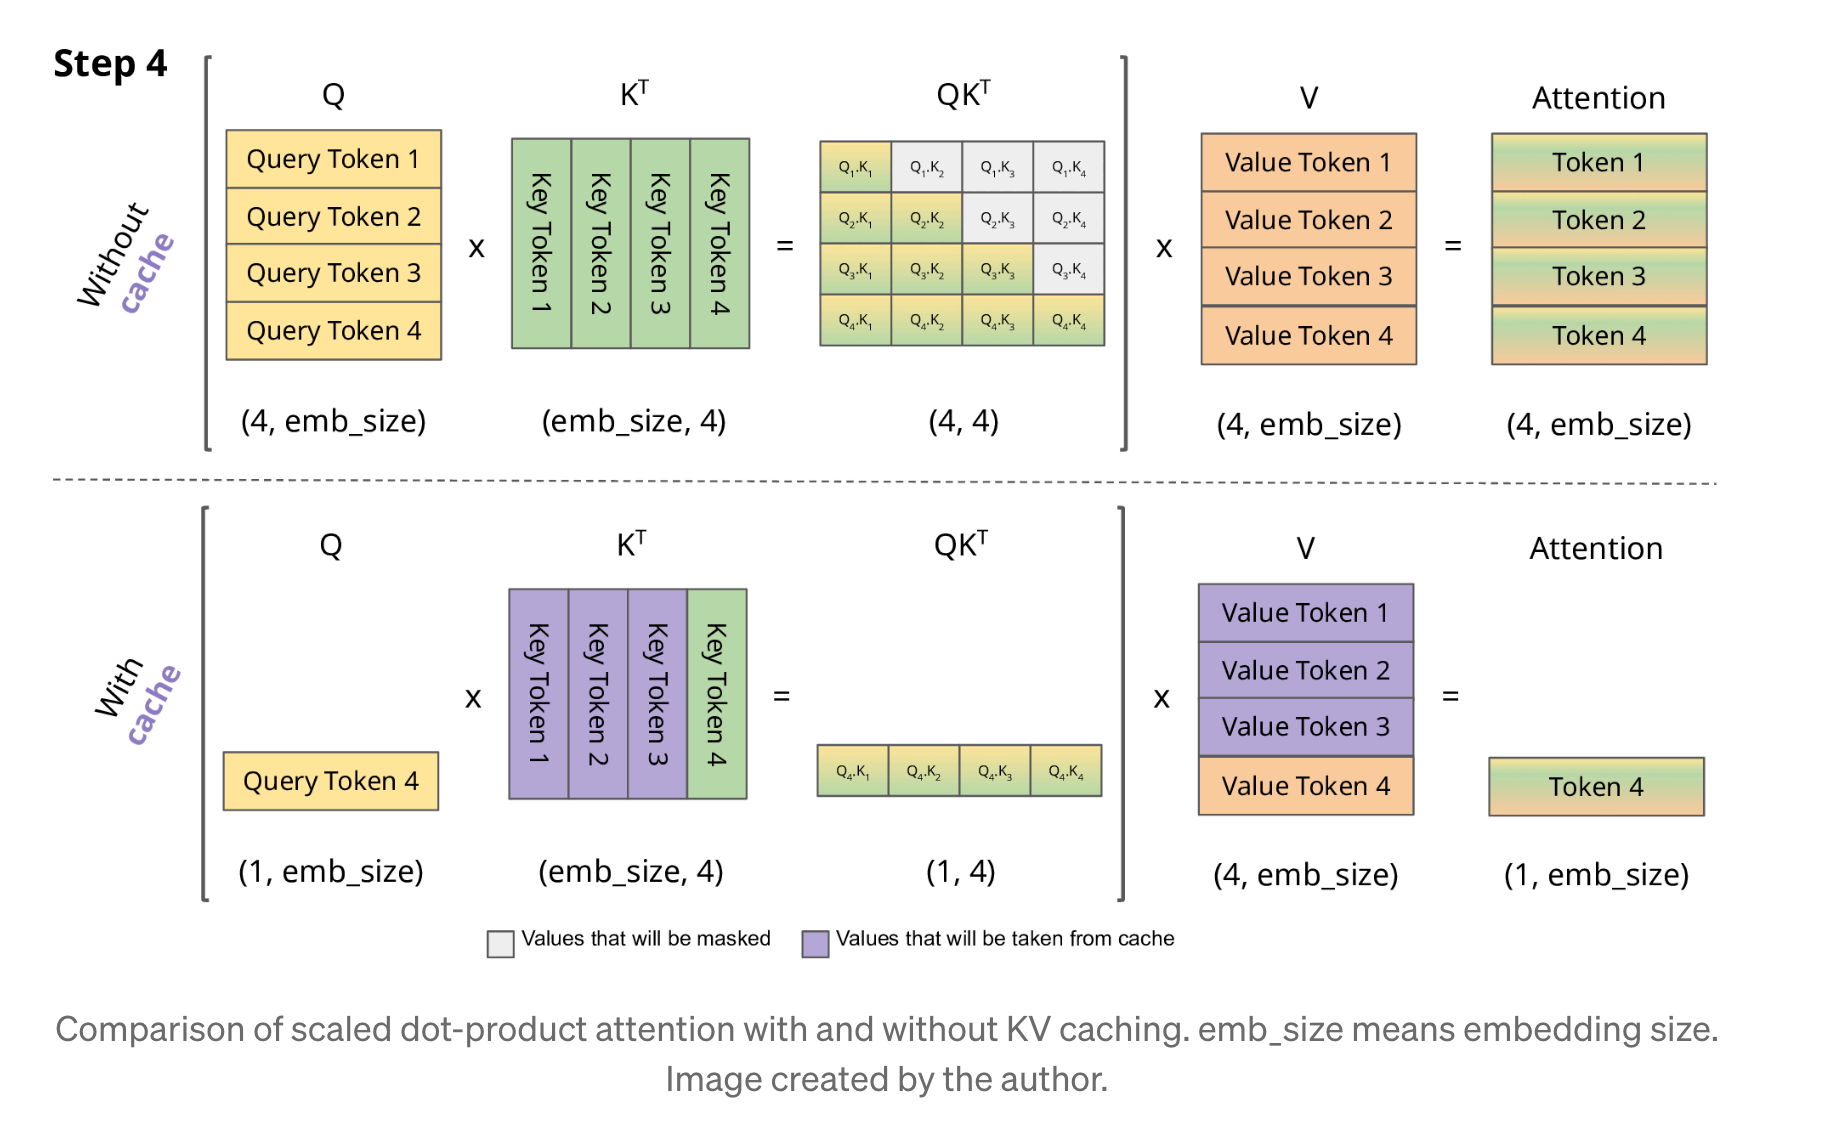
[논문 리뷰] Efficient Memory Management for Large Language Model Serving ...
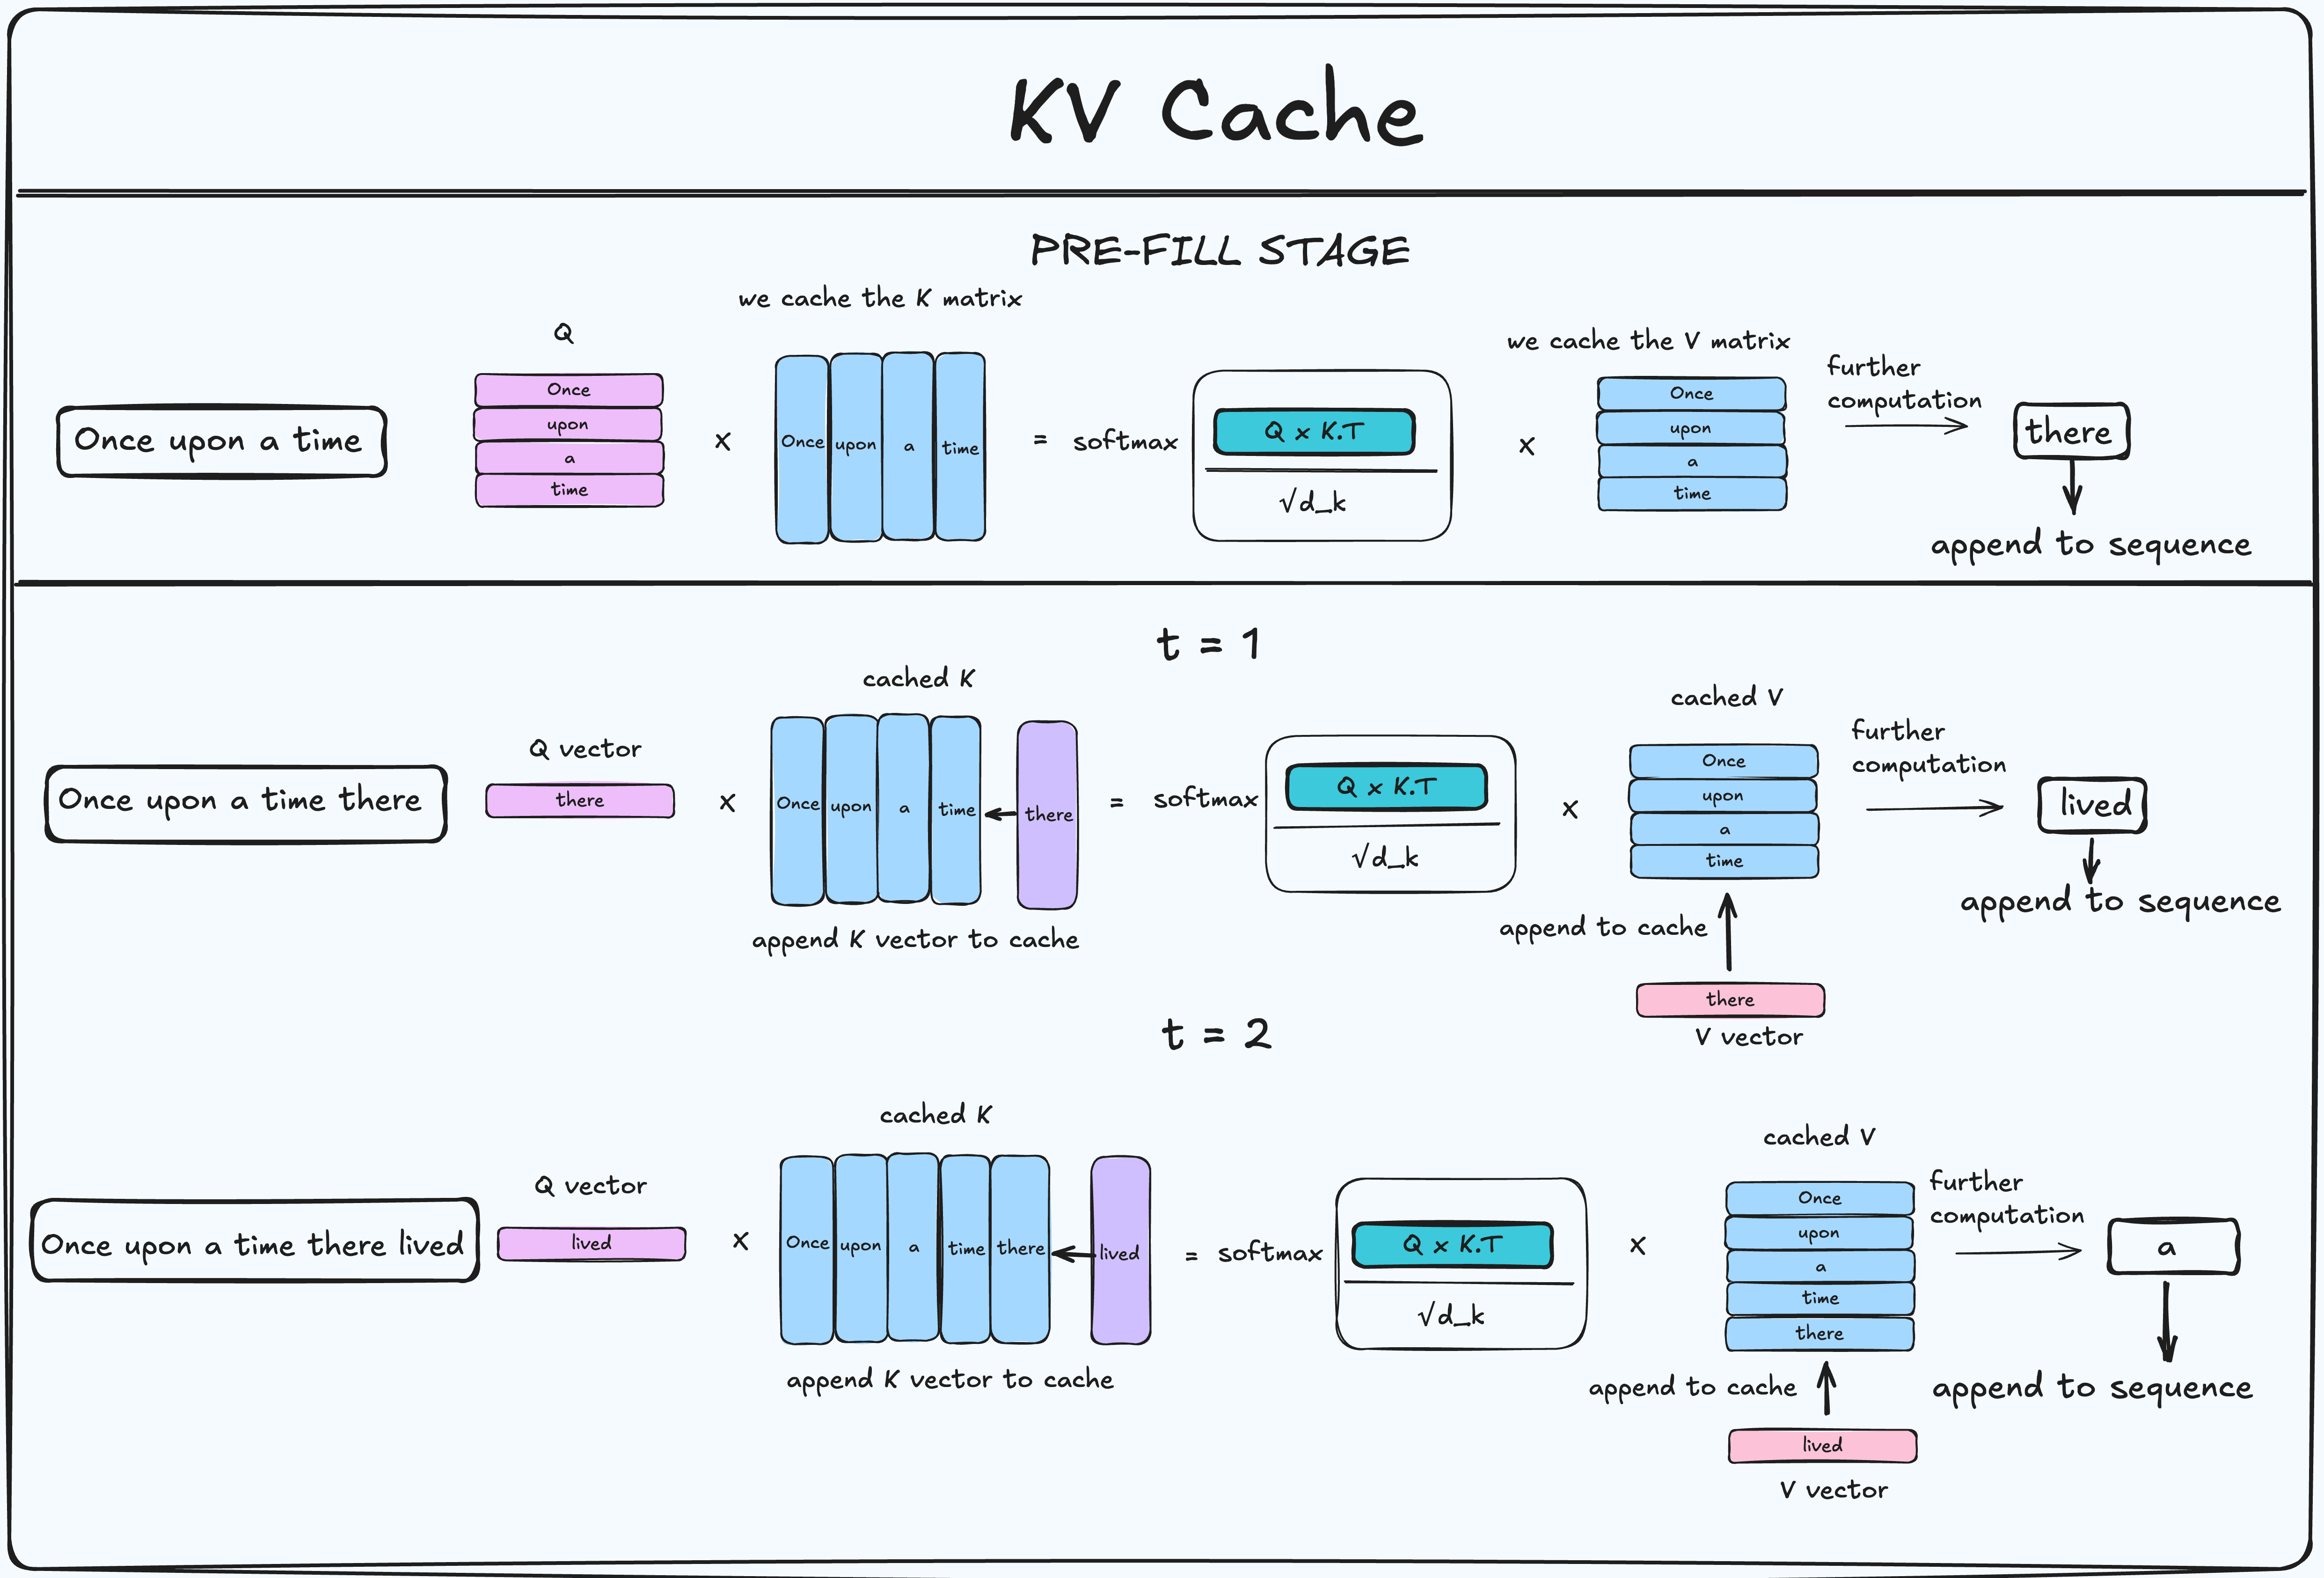
KV Cache From First Principles
Advertisement Space (336x280)
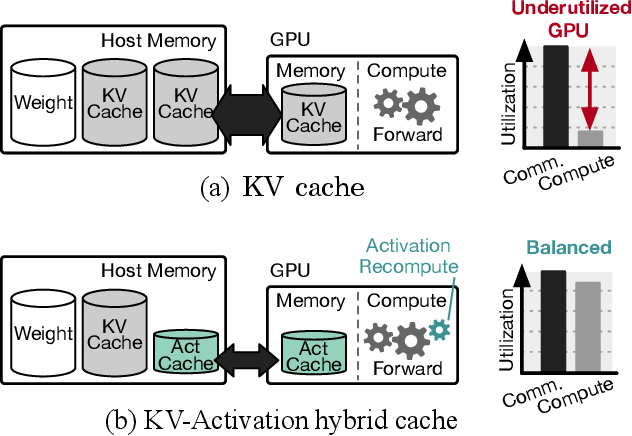
Figure 1 from Throughput-Oriented LLM Inference via KV-Activation ...

[论文评述] KVSharer: Efficient Inference via Layer-Wise Dissimilar KV Cache ...

KEEP: A KV-Cache-Centric Memory Management System for Efficient ...

KEEP: A KV-Cache-Centric Memory Management System for Efficient ...

KV Cache Is Becoming the Memory Hierarchy of Inference | Touchdown Labs
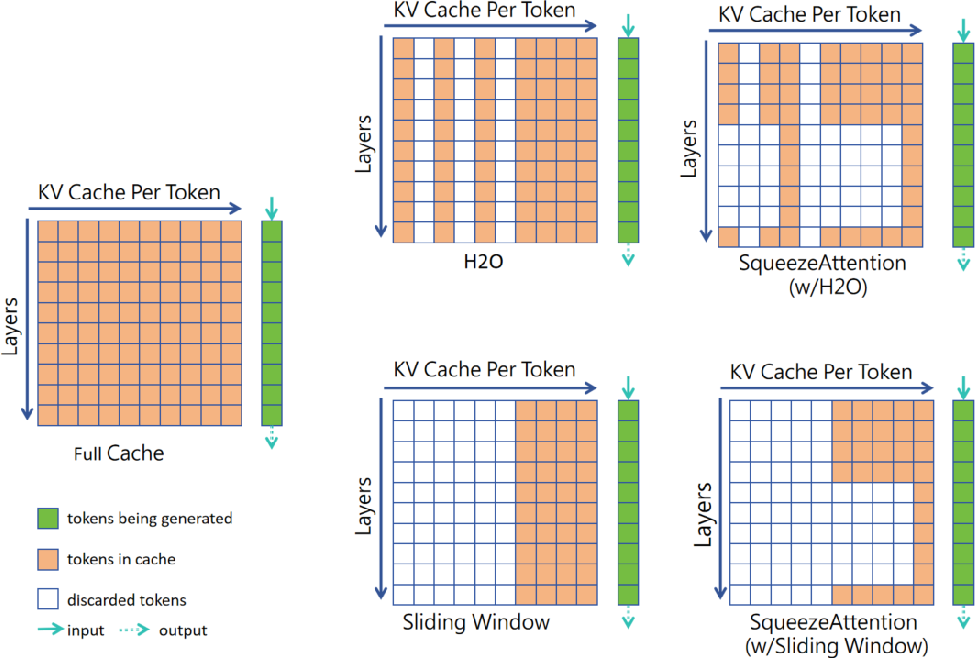
Figure 1 from SqueezeAttention: 2D Management of KV-Cache in LLM ...