
Figure 1 From Multi Grained Alignment For Visual Grounding Semantic

Figure 1 from Multi-Grained Alignment for Visual Grounding | Semantic ...

Figure 1 from Multi-Grained Alignment for Visual Grounding | Semantic ...

Figure 1 from Multi-Grained Alignment for Visual Grounding | Semantic ...

Table 1 from Multi-Grained Alignment for Visual Grounding | Semantic ...
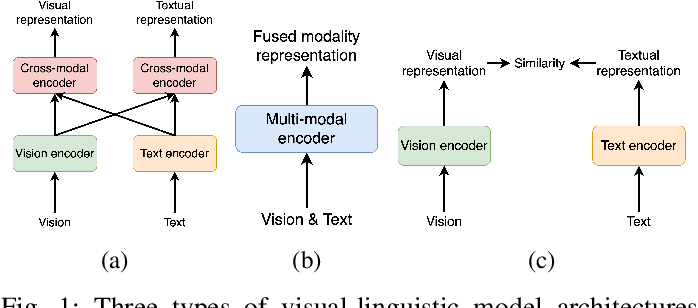
Figure 1 from A Multi -level Alignment Training Scheme for Video-and ...

Figure 1 from Visual Grounding with Transformers | Semantic Scholar

Figure 1 from Fine-grained Semantic Alignment Network for Weakly ...

Figure 1 from Visual Grounding with Transformers | Semantic Scholar
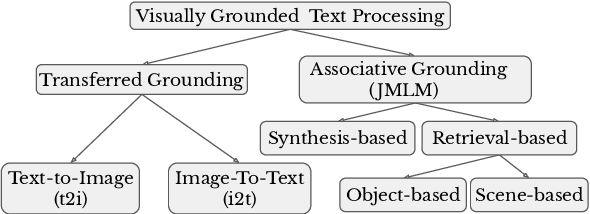
Figure 1 from Visual Grounding Strategies for Text-Only Natural ...

Figure 1 from Revisiting Visual Grounding | Semantic Scholar
Advertisement Space (300x250)
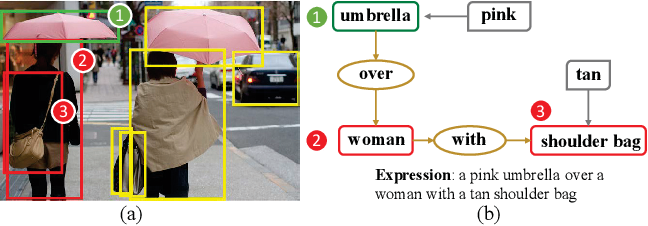
Figure 1 from Visual-Semantic Graph Matching for Visual Grounding ...
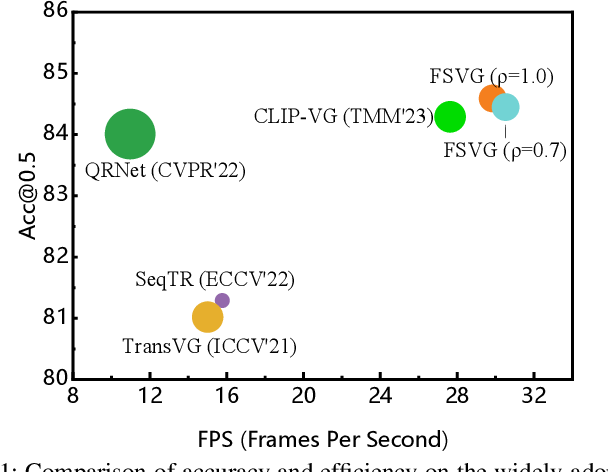
Figure 1 from A Simple and Better Baseline for Visual Grounding ...
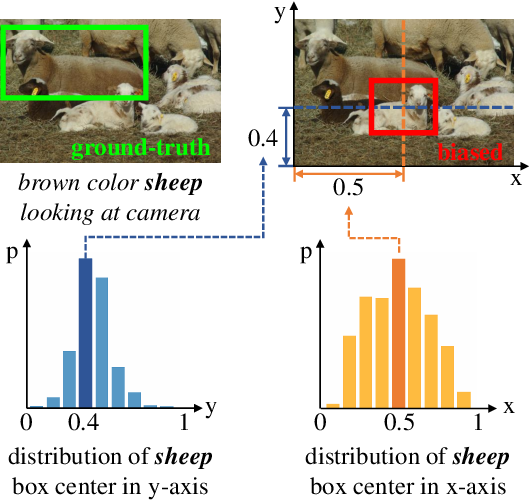
Figure 1 from Deconfounded Visual Grounding | Semantic Scholar
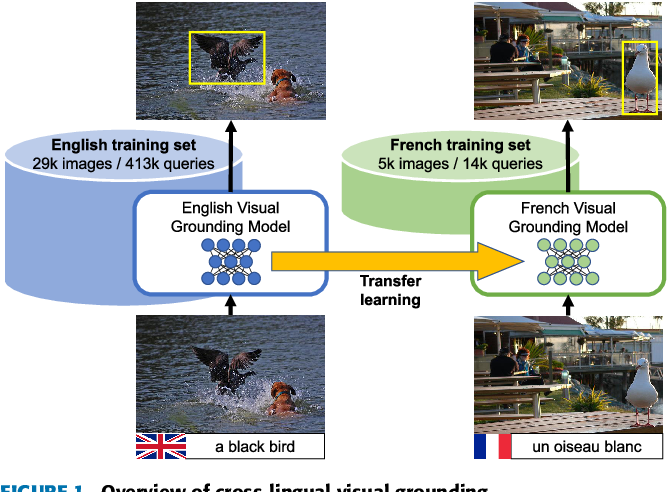
Figure 1 from Cross-Lingual Visual Grounding | Semantic Scholar

Figure 1 from Grounding Visual Representations with Texts for Domain ...
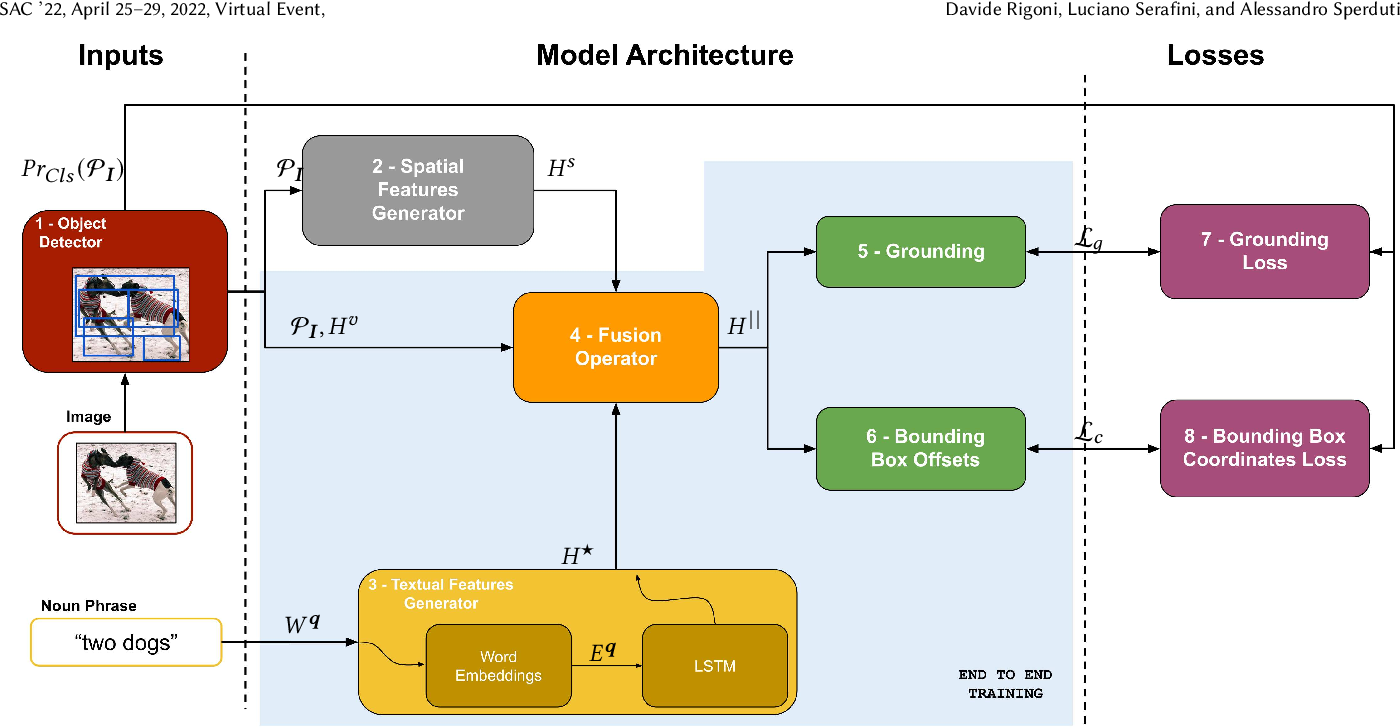
Figure 1 from A better loss for visual-textual grounding | Semantic Scholar

Figure 1 from Prototype-Aware Multimodal Alignment for Open-Vocabulary ...
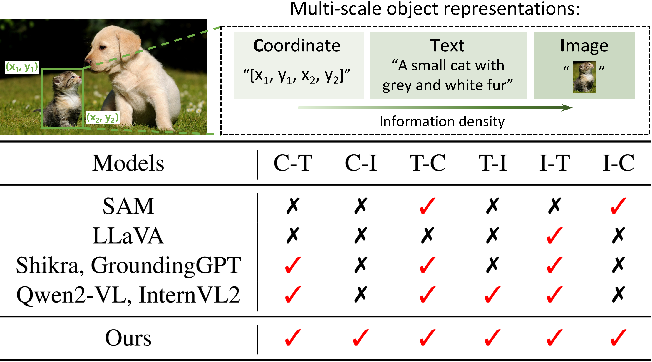
Figure 1 from Advancing Fine-Grained Visual Understanding with Multi ...
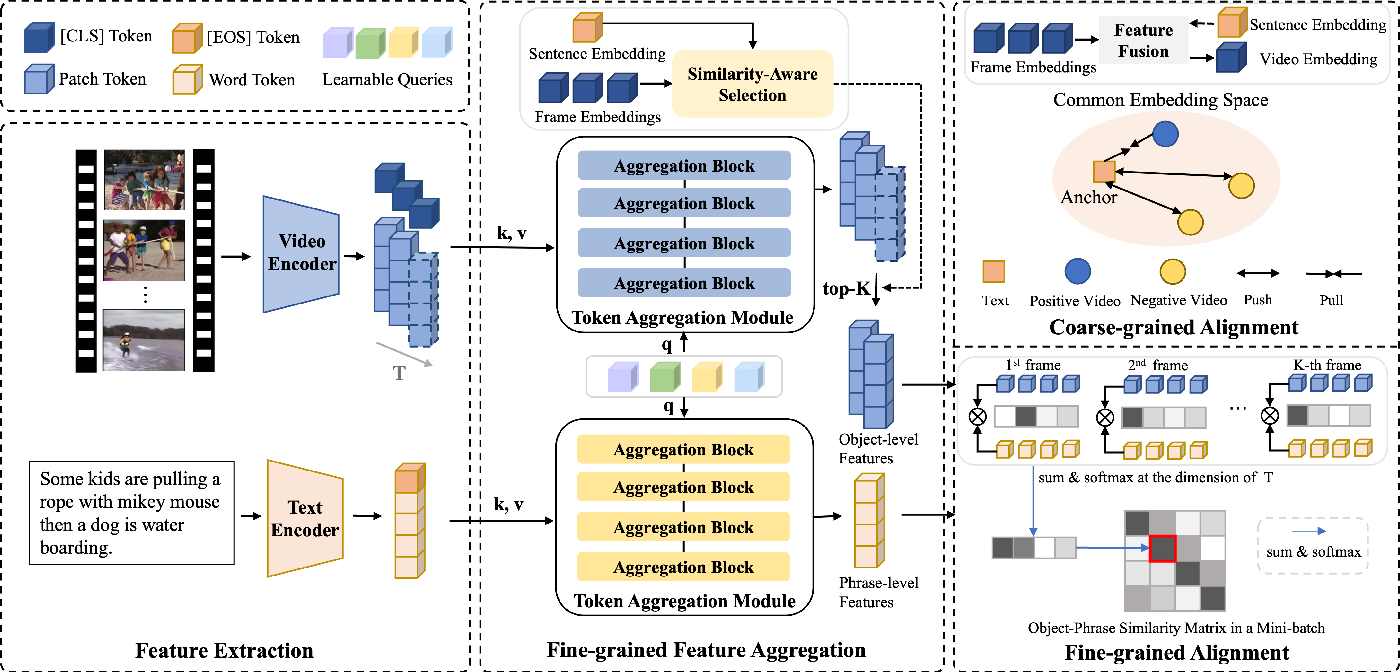
Figure 1 from Selective Multi-grained Alignment for Text-Video ...
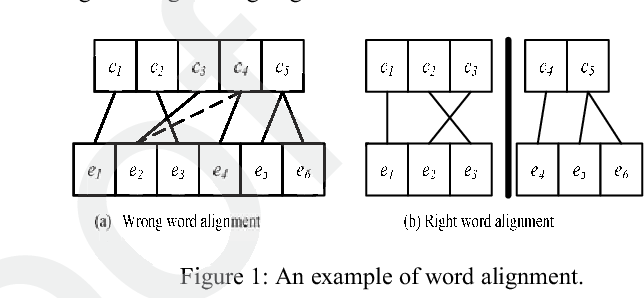
Figure 1 from Word Alignment Based on Multi-Grain Model | Semantic Scholar
Advertisement Space (336x280)
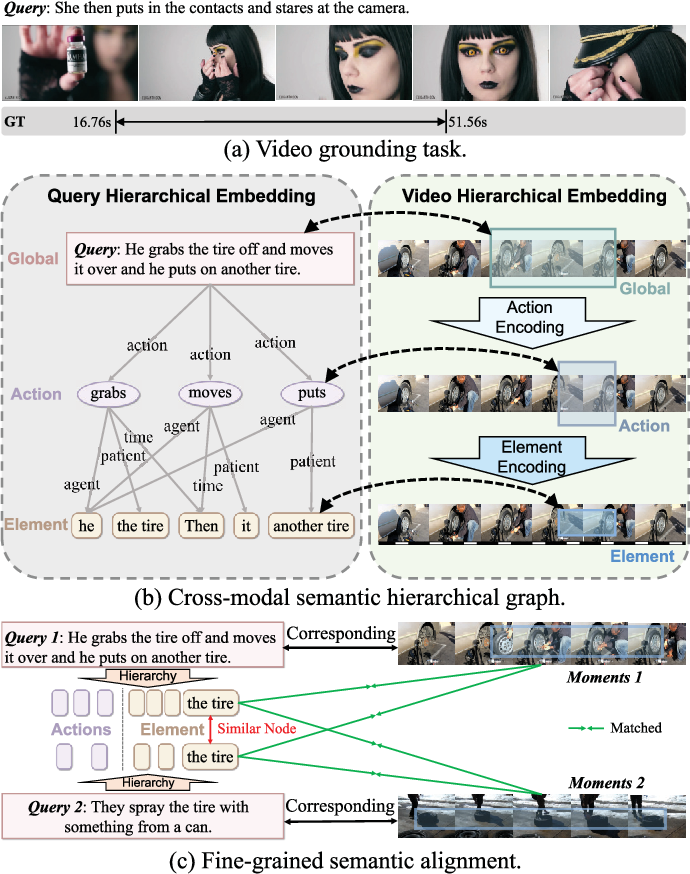
Figure 1 from Fine-Grained Alignment and Interaction for Video ...
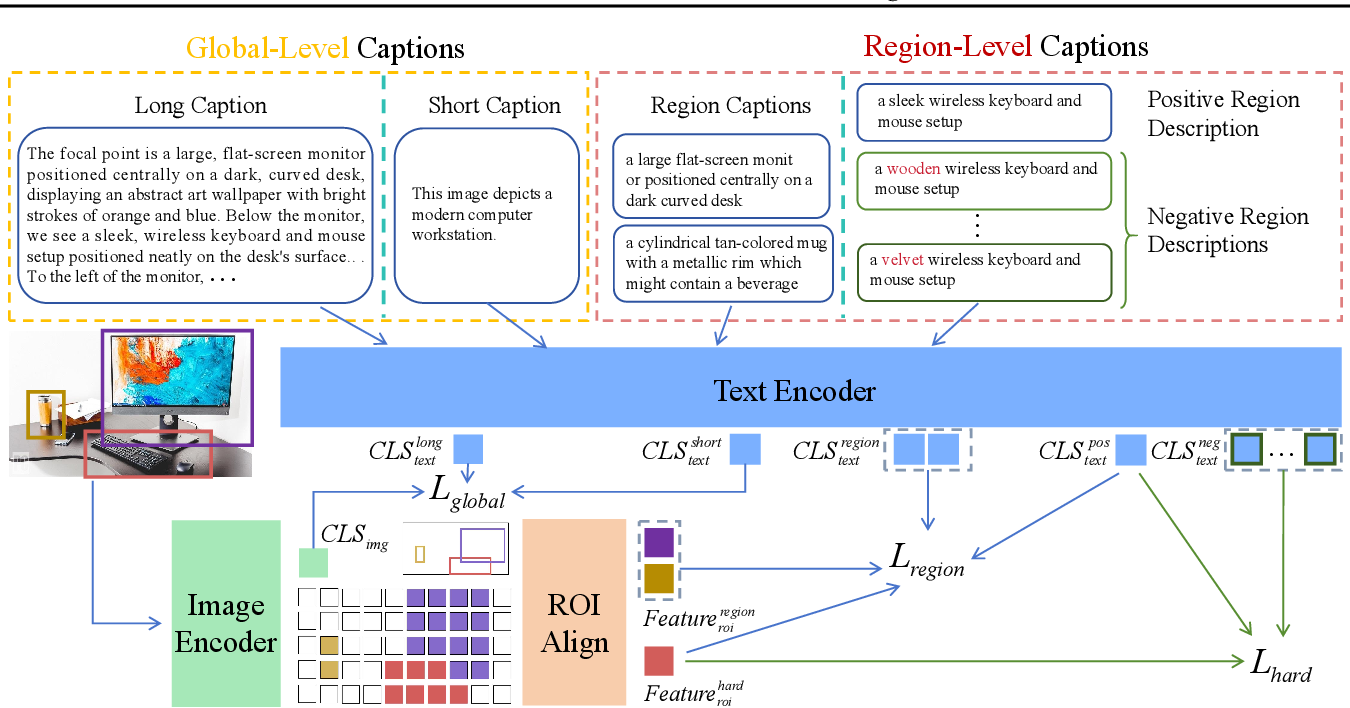
Figure 1 from FG-CLIP: Fine-Grained Visual and Textual Alignment ...

Figure 1 from End-to-end visual grounding via region proposal networks ...

Figure 1 from Visual Grounding with Feature Enhancement and Language ...

Figure 1 from Improving Visual Grounding with Visual-Linguistic ...

Figure 1 from Advancing Fine-Grained Visual Understanding with Multi ...
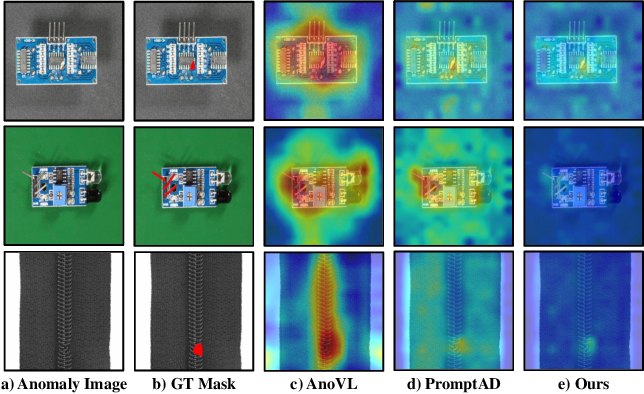
Figure 1 from Towards Fine-Grained Vision-Language Alignment for Few ...
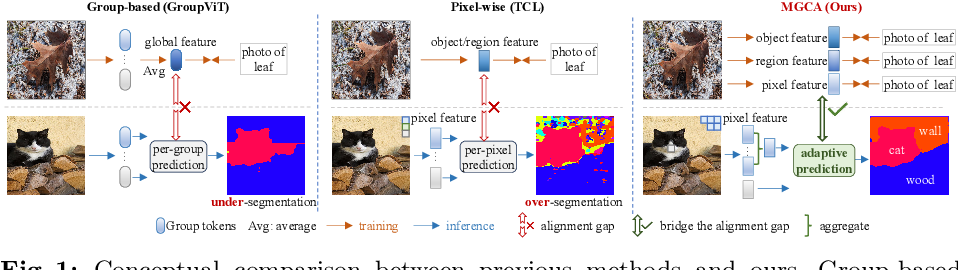
Figure 1 from Multi-Grained Cross-modal Alignment for Learning Open ...
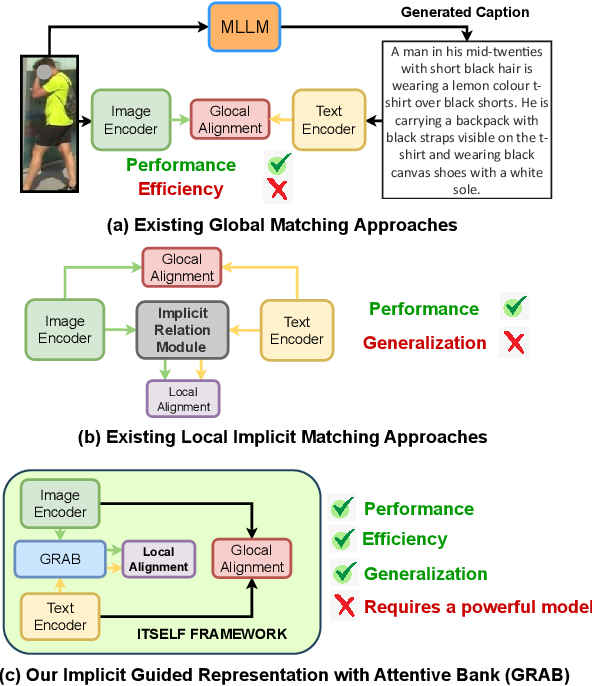
Figure 1 from ITSELF: Attention Guided Fine-Grained Alignment for ...

Figure 1 from Learning Point-Language Hierarchical Alignment for 3D ...
Advertisement Space (336x280)
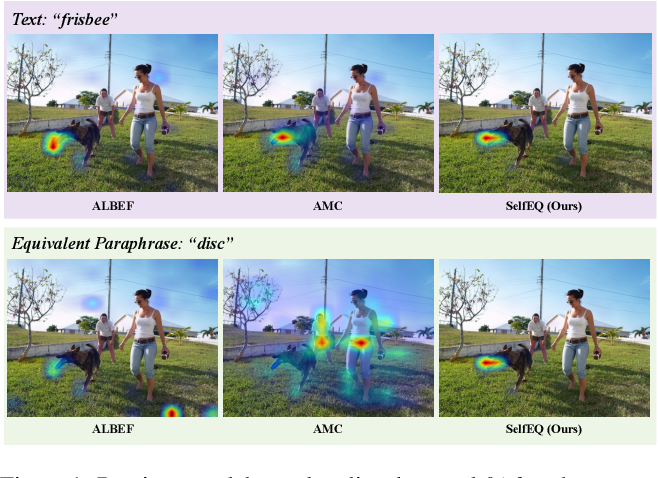
Figure 1 from Improved Visual Grounding through Self-Consistent ...

Figure 1 from Weakly-Supervised 3D Visual Grounding based on Visual ...

Figure 1 from Semantic-Guided Information Alignment Network for Fine ...

Figure 1 from Fine-Grained Spatiotemporal Motion Alignment for ...

Figure 1 from Towards Fine-Grained Vision-Language Alignment for Few ...

Figure 1 from Learning Visual Grounding from Generative Vision and ...