
Figure 1 From Pretrained Semantic Speech Embeddings For End To End

Figure 1 from Pretrained Semantic Speech Embeddings for End-to-End ...

Figure 1 from Attention based end to end Speech Recognition for Voice ...

Table 1 from Pretrained Semantic Speech Embeddings for End-to-End ...

Figure 1 from Acoustic Word Embeddings for End-to-End Speech Synthesis ...

Figure 1 from Textually Pretrained Speech Language Models | Semantic ...
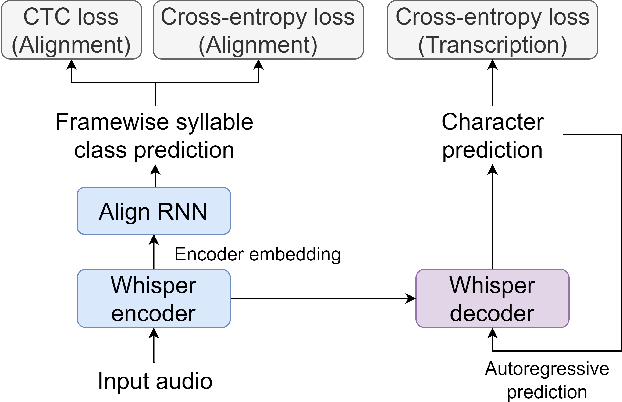
Figure 1 from Adapting Pretrained Speech Model for Mandarin Lyrics ...

Figure 1 from Neural Speech Embeddings for Speech Synthesis Based on ...

Figure 1 from Integrating Pre-Trained Speech and Language Models for ...

Figure 1 from End-to-end model for named entity recognition from speech ...

Figure 1 from Adapting Large Language Model with Speech for Fully ...
Advertisement Space (300x250)

Figure 1 from Pre-Trained Text Embeddings for Enhanced Text-to-Speech ...
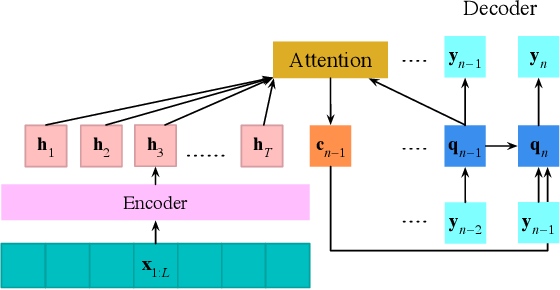
Figure 1 from End-to-end Anchored Speech Recognition | Semantic Scholar

Figure 1 from Semi-Supervised End-to-End Speech Recognition | Semantic ...

Figure 1 from Neural Noise Embedding for End-To-End Speech Enhancement ...

Figure 1 from TASTE: Text-Aligned Speech Tokenization and Embedding for ...

Figure 1 from End-to-End Accented Speech Recognition | Semantic Scholar

(PDF) Pretrained Semantic Speech Embeddings for End-to-End Spoken ...

Figure 1 from Towards Transfer Learning for end-to-end Sinhala Speech ...
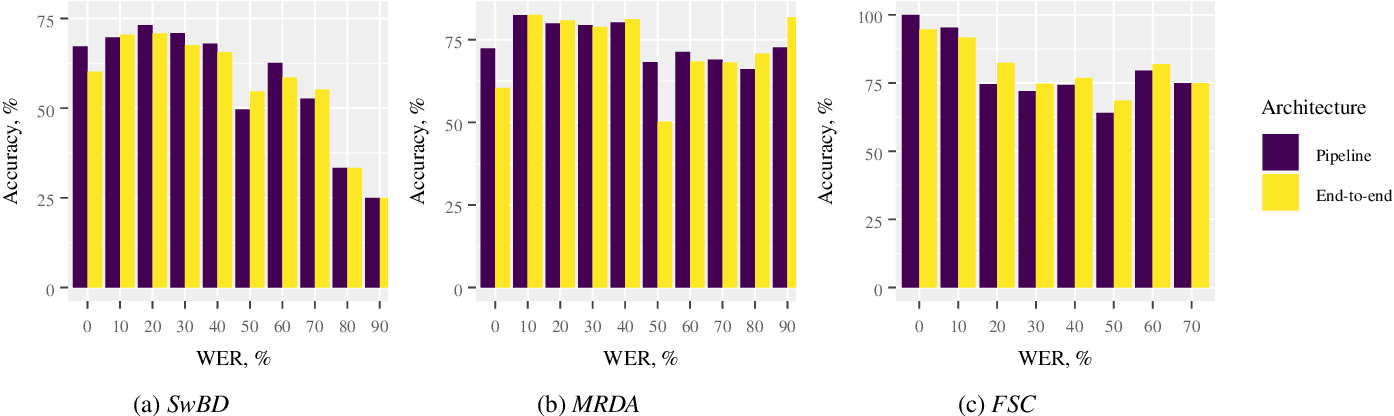
Pretrained Semantic Speech Embeddings for End-to-End Spoken Language ...

Figure 1 from An Investigation of End-to-End Models for Robust Speech ...
Advertisement Space (336x280)

Figure 1 from A Reality Check and a Practical Baseline for Semantic ...
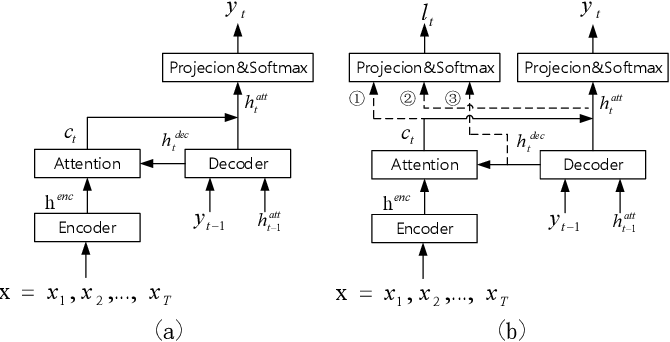
Figure 1 from Investigating End-to-end Speech Recognition for Mandarin ...

Figure 1 from Leveraging Language Embeddings for Cross-Lingual Self ...

Figure 1 from Decoder-only Architecture for Streaming End-to-end Speech ...

Figure 1 from Speech Sequence Embeddings using Nearest Neighbors ...

Figure 1 from Tight Integrated End-to-End Training for Cascaded Speech ...
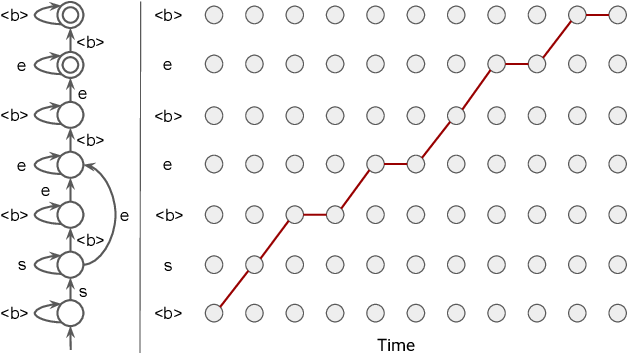
Figure 1 from End-to-End Speech Recognition: A Survey | Semantic Scholar

Figure 1 from How to get better embeddings with code pre-trained models ...
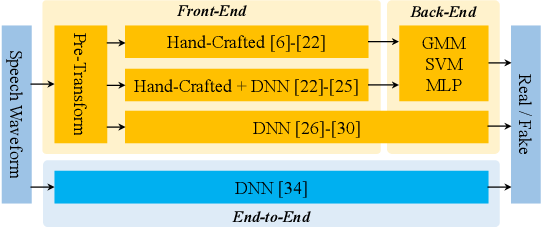
Figure 1 from Towards End-to-End Synthetic Speech Detection | Semantic ...
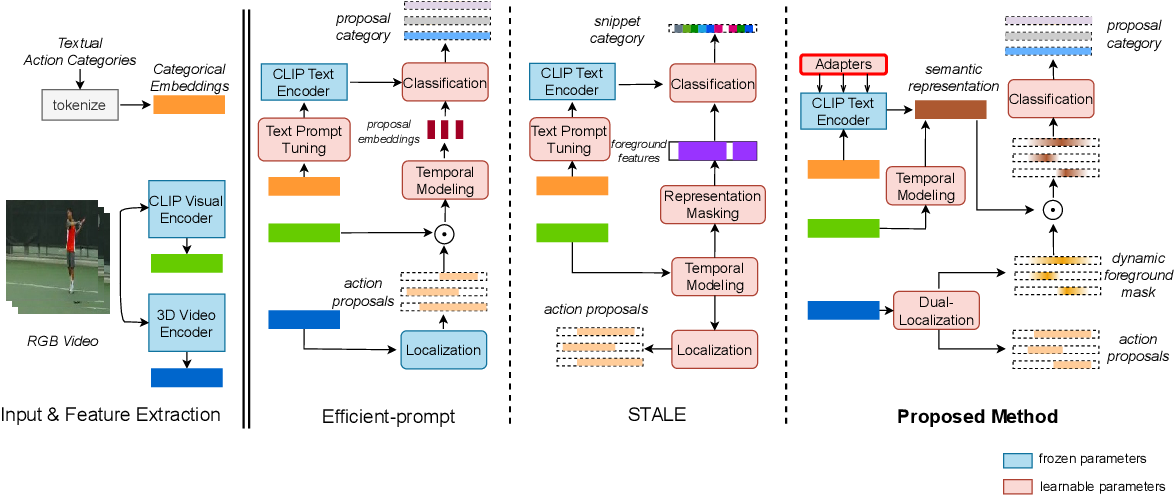
Figure 1 from ZEETAD: Adapting Pretrained Vision-Language Model for ...
Advertisement Space (336x280)

Figure 2 from End to End Spoken Language Diarization with Wav2vec ...

Figure 1 from MPE4G : Multimodal Pretrained Encoder for Co-Speech ...

Figure 1 from Joint Fine-tuning and Conversion of Pretrained Speech and ...
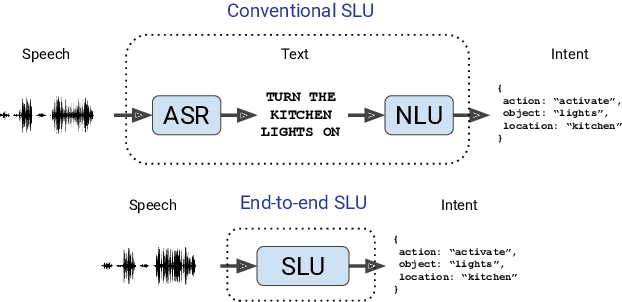
Figure 1 from Speech Model Pre-training for End-to-End Spoken Language ...

Figure 1 from Robust Semantic Communications for Speech-to-Text ...

Figure 1 from Decoder-only Architecture for Streaming End-to-end Speech ...