
Figure 1 From Voice Conversion With Just Nearest Neighbors Semantic
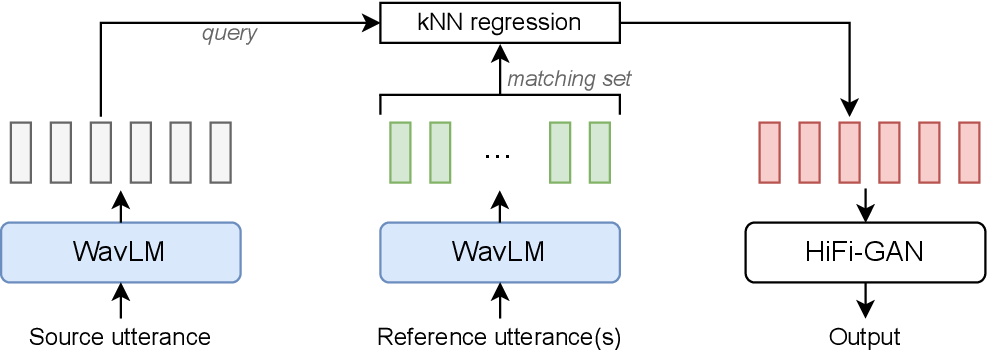
Figure 1 from Voice Conversion With Just Nearest Neighbors | Semantic ...
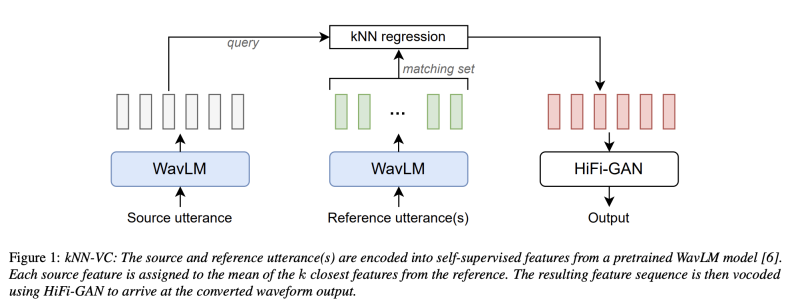
Voice Conversion With Just Nearest Neighbors
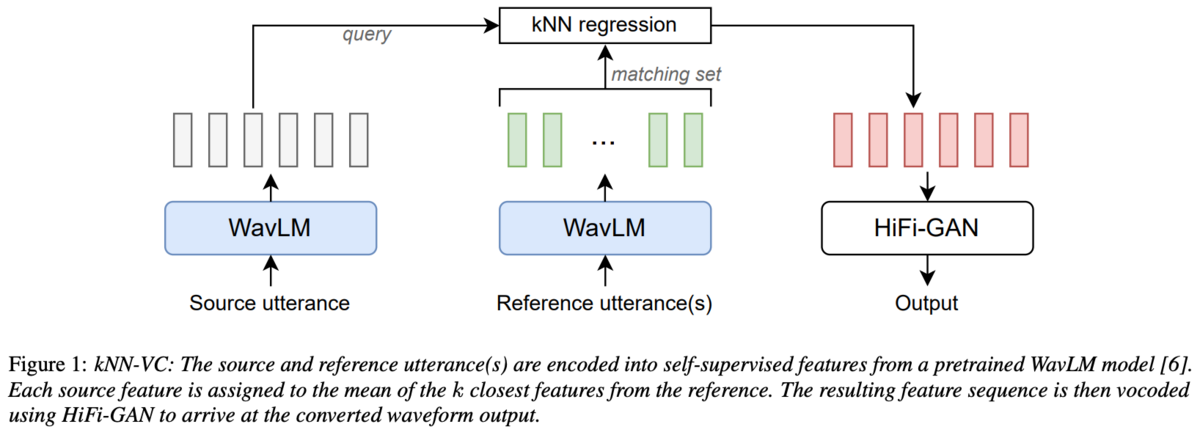
[論文メモ] Voice Conversion With Just Nearest Neighbors - にんひどりんはんのう
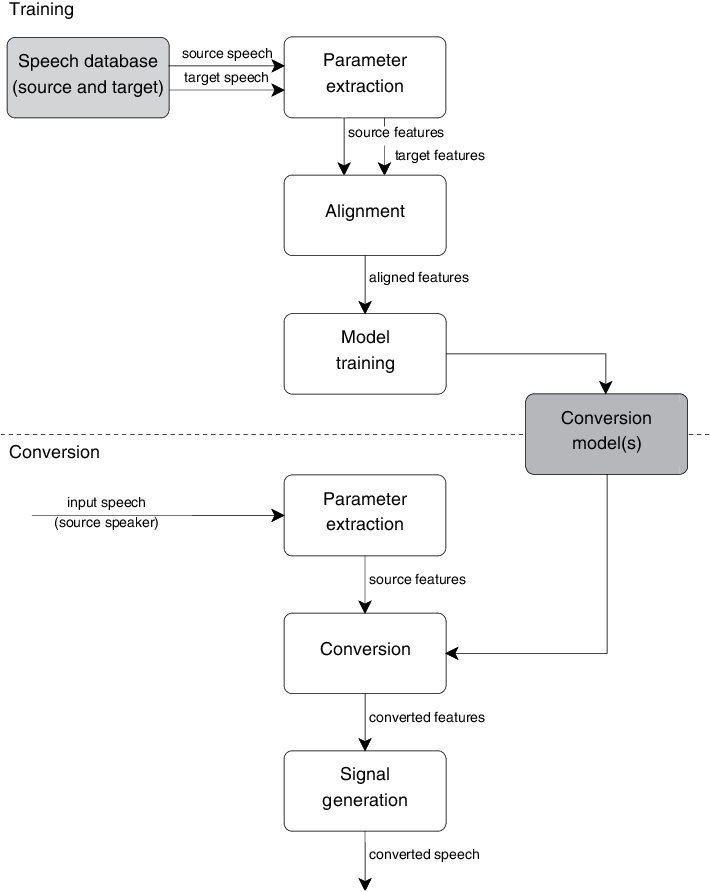
Figure 1 from Voice conversion | Semantic Scholar

Figure 1 from Neural Voice Cloning with a Few Samples | Semantic Scholar
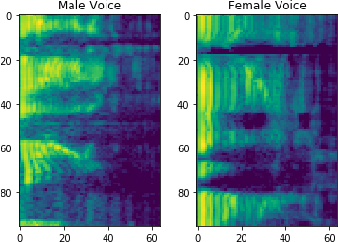
Figure 1 from Voice Conversion using Generative Techniques | Semantic ...
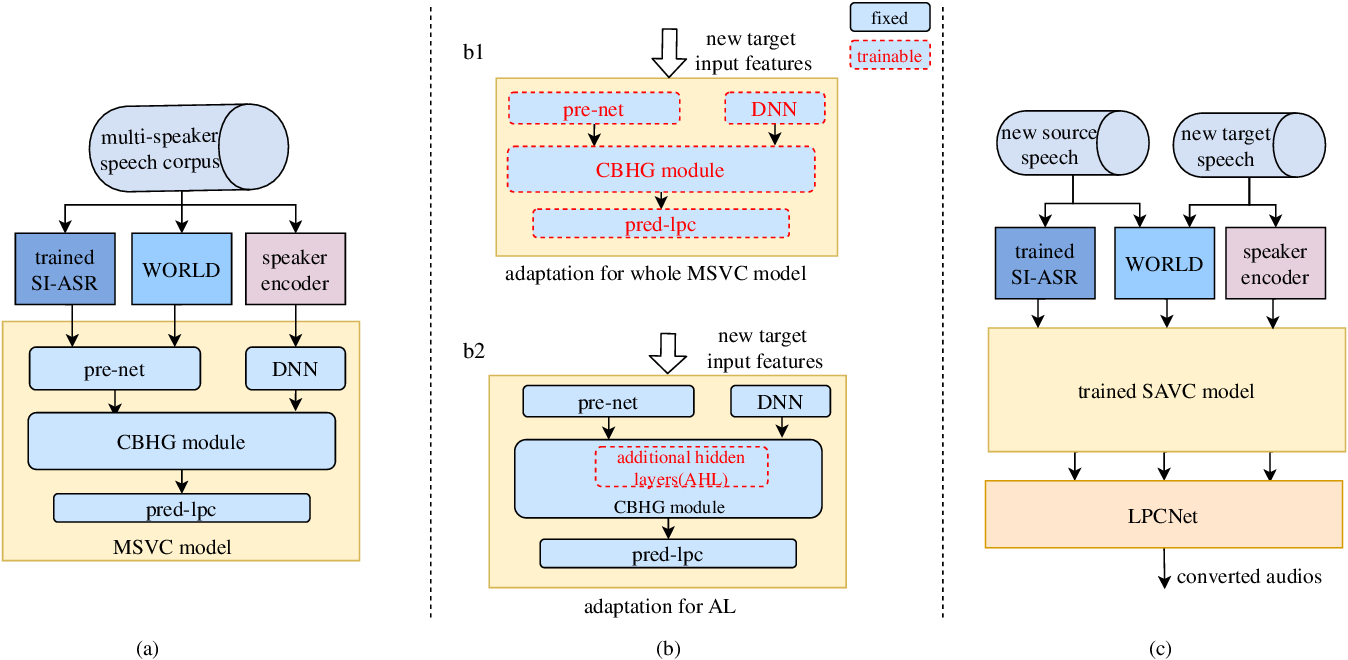
Figure 1 from Voice Conversion towards Arbitrary Speakers With Limited ...
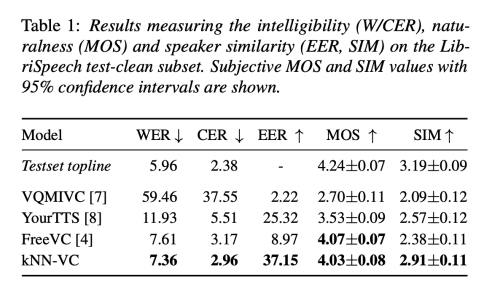
Voice Conversion With Just Nearest Neighbors
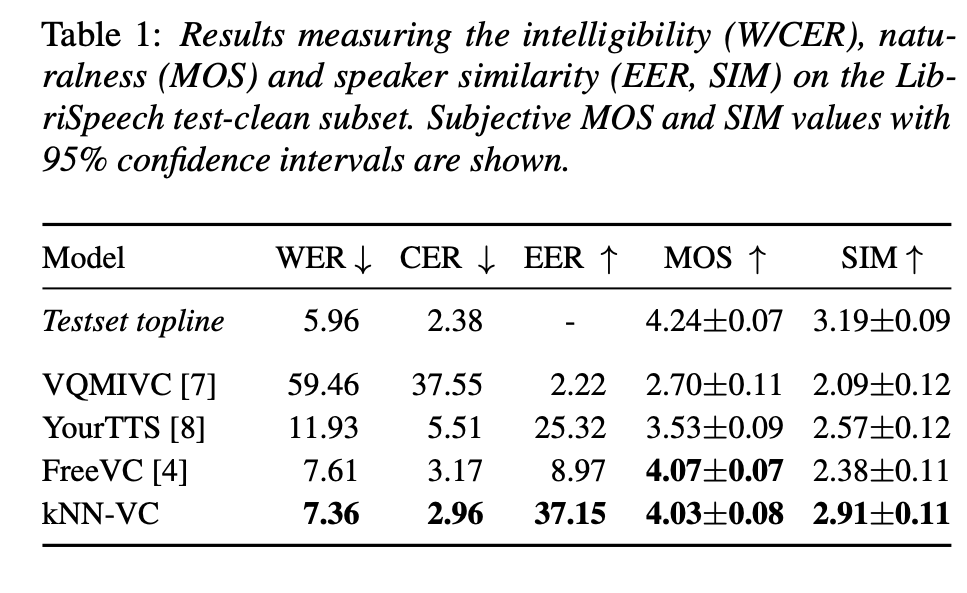
[論文メモ] Voice Conversion With Just Nearest Neighbors - にんひどりんはんのう
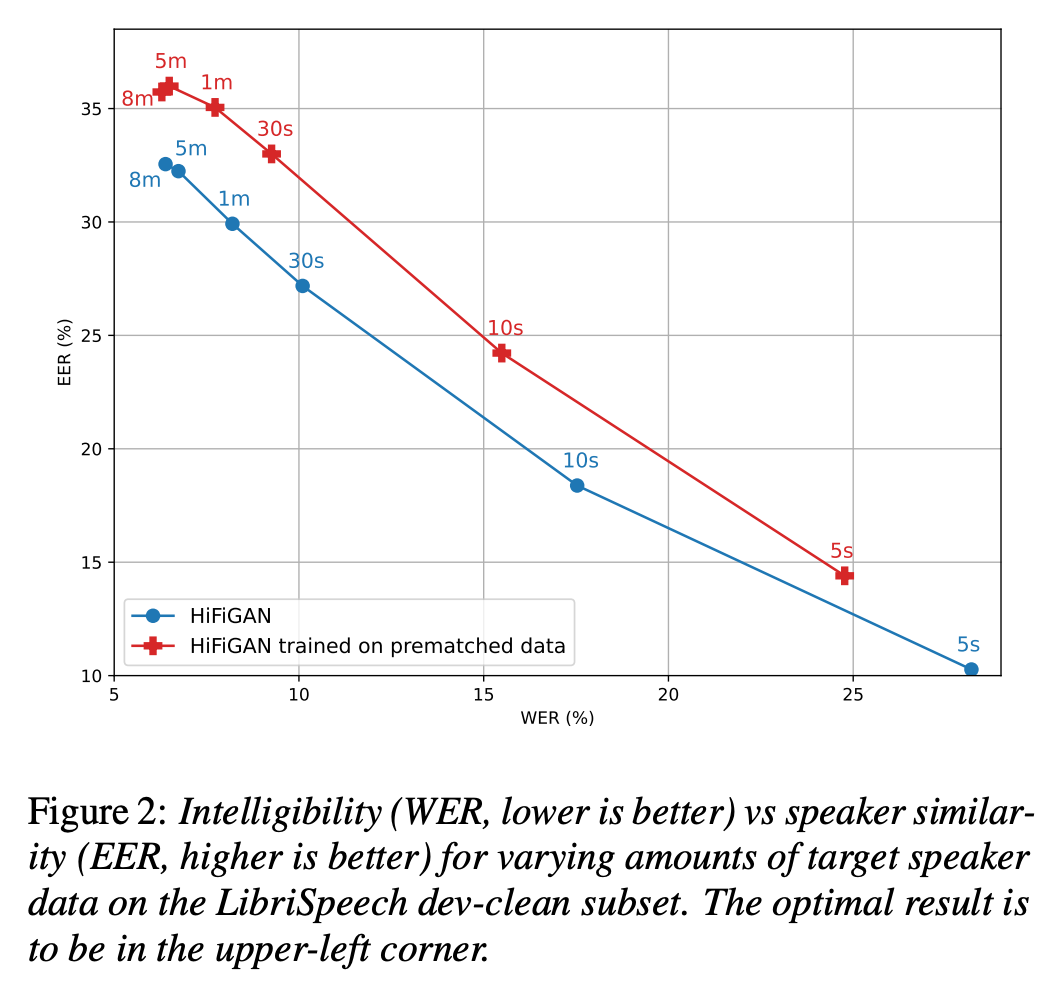
[論文メモ] Voice Conversion With Just Nearest Neighbors - にんひどりんはんのう
Advertisement Space (300x250)
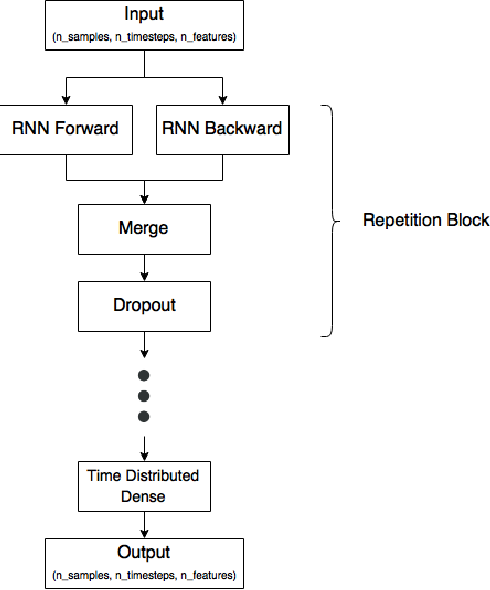
Figure 3 from Voice Conversion with Deep Learning | Semantic Scholar
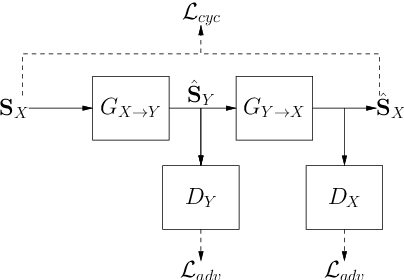
Figure 1 from The UFRJ Entry for the Voice Conversion Challenge 2020 ...

Figure 1 from NU Voice Conversion System for the Voice Conversion ...
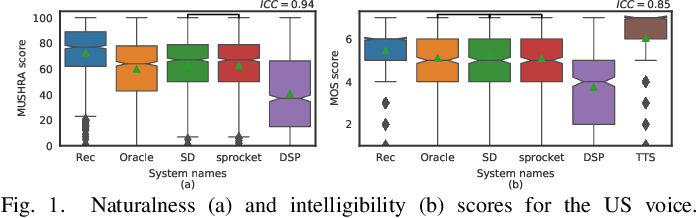
Figure 1 from Voice Conversion for Whispered Speech Synthesis ...
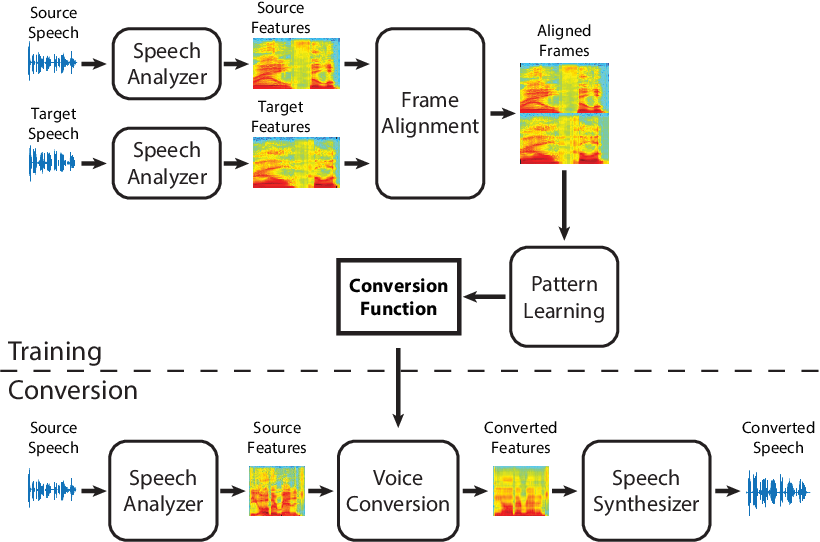
Figure 2.1 from Voice Conversion using Deep Neural Networks | Semantic ...
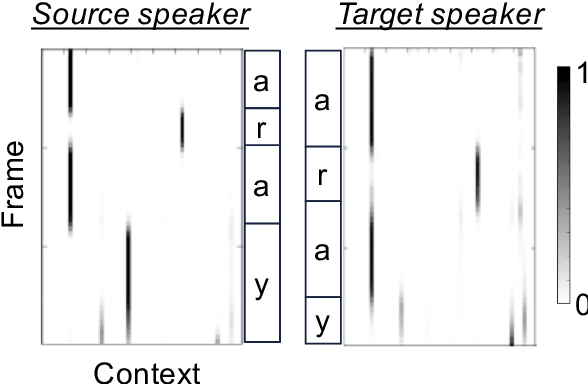
Figure 1 from Voice Conversion Using Sequence-to-Sequence Learning of ...

Figure 1 from Text-independent voice conversion using deep neural ...
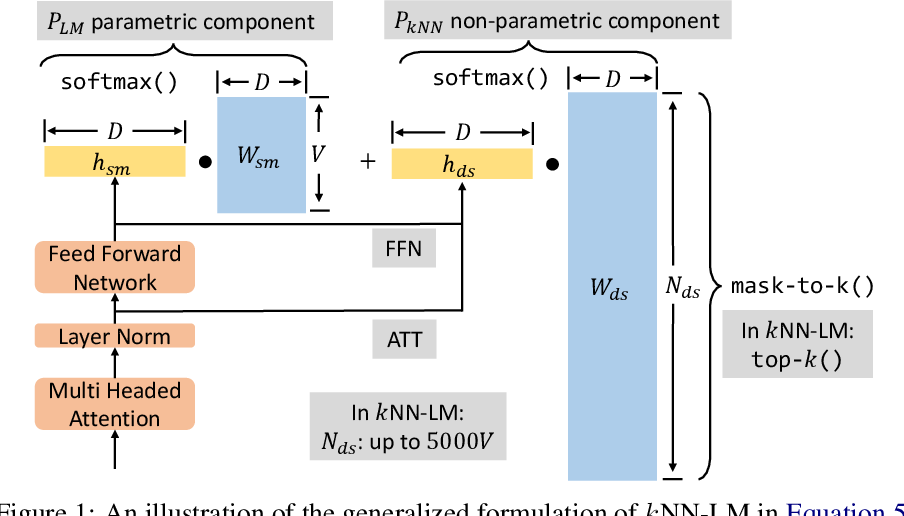
Figure 1 from Why do Nearest Neighbor Language Models Work? | Semantic ...

Figure 1 from Enhance Vision-Language Alignment with Noise | Semantic ...

Figure 4 from Sequence-to-Sequence Voice Conversion with Similarity ...
Advertisement Space (336x280)
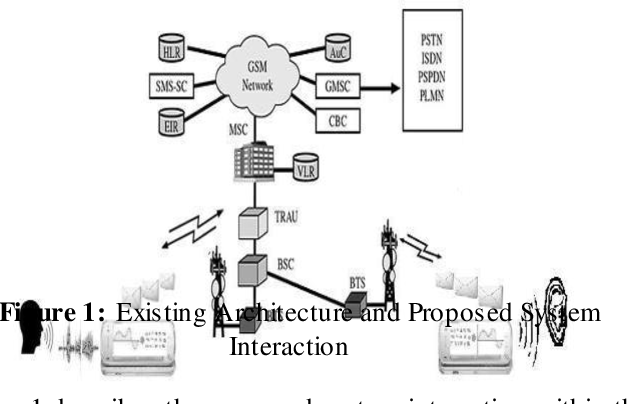
Figure 1 from CONVERSION OF VOICE SIGNAL INTO CHARACTERS USING ...
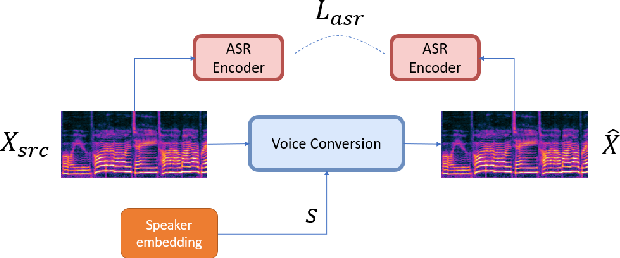
Figure 1 from Iteratively Improving Speech Recognition and Voice ...

Figure 2 from Voice Conversion Using Sequence-to-Sequence Learning of ...
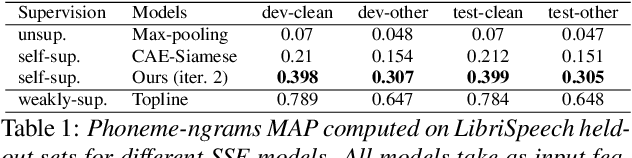
Table 1 from Speech Sequence Embeddings using Nearest Neighbors ...
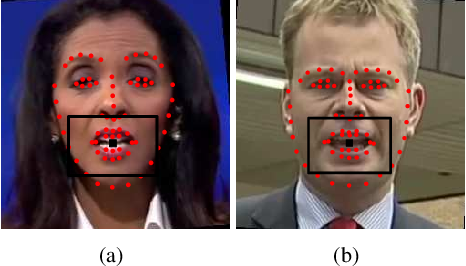
Figure 1 from End-to-End Audiovisual Speech Recognition | Semantic Scholar
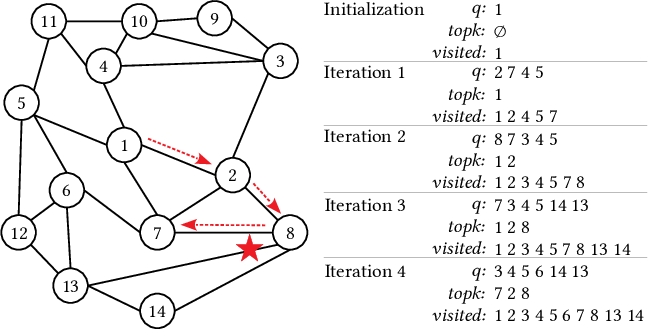
Figure 1 from SONG: Approximate Nearest Neighbor Search on GPU ...

Figure 1 from Signal Conversion from Natural Audio Speech to Synthetic ...

Figure 2 from High Quality and Similarity One-Shot Voice Conversion ...

Figure 1 from Visual word proximity and linguistics for semantic video ...
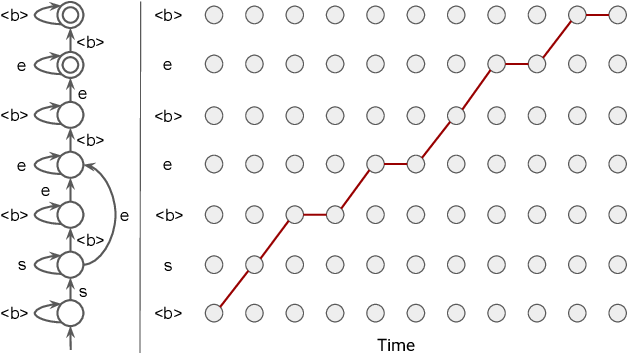
Figure 1 from End-to-End Speech Recognition: A Survey | Semantic Scholar
Advertisement Space (336x280)

Figure 1 from Contextualized End-to-End Speech Recognition with ...

Figure 4 from NU Voice Conversion System for the Voice Conversion ...

Figure 8 from NU Voice Conversion System for the Voice Conversion ...

Table 1 from A Voice Conversion Mapping Function Based on a Stacked ...

Figure 9 from NU Voice Conversion System for the Voice Conversion ...

Figure 7 from NU Voice Conversion System for the Voice Conversion ...