
Figure 2 From Dense Object Grounding In 3d Scenes Semantic Scholar

Figure 2 from Dense Object Grounding in 3D Scenes | Semantic Scholar

Figure 1 from Dense Object Grounding in 3D Scenes | Semantic Scholar

Figure 3 from Dense Object Grounding in 3D Scenes | Semantic Scholar

Table 2 from Dense Object Grounding in 3D Scenes | Semantic Scholar

Table 1 from Dense Object Grounding in 3D Scenes | Semantic Scholar
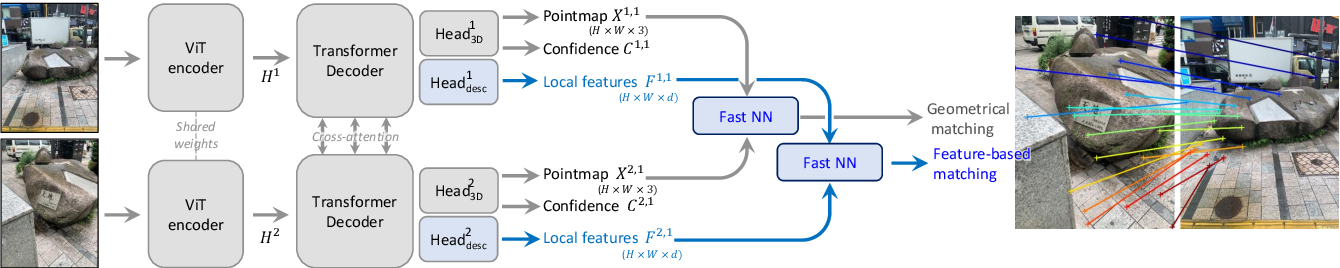
Figure 2 from Grounding Image Matching in 3D with MASt3R | Semantic Scholar
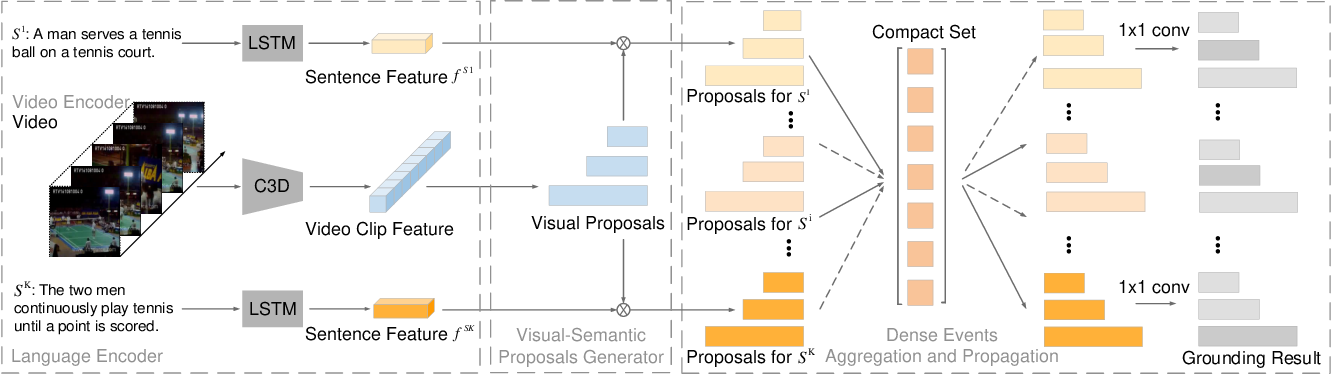
Figure 2 from Dense Events Grounding in Video | Semantic Scholar

Figure 2 from Rethinking 3D Dense Caption and Visual Grounding in A ...

Figure 2 from 3D Concept Grounding on Neural Fields | Semantic Scholar
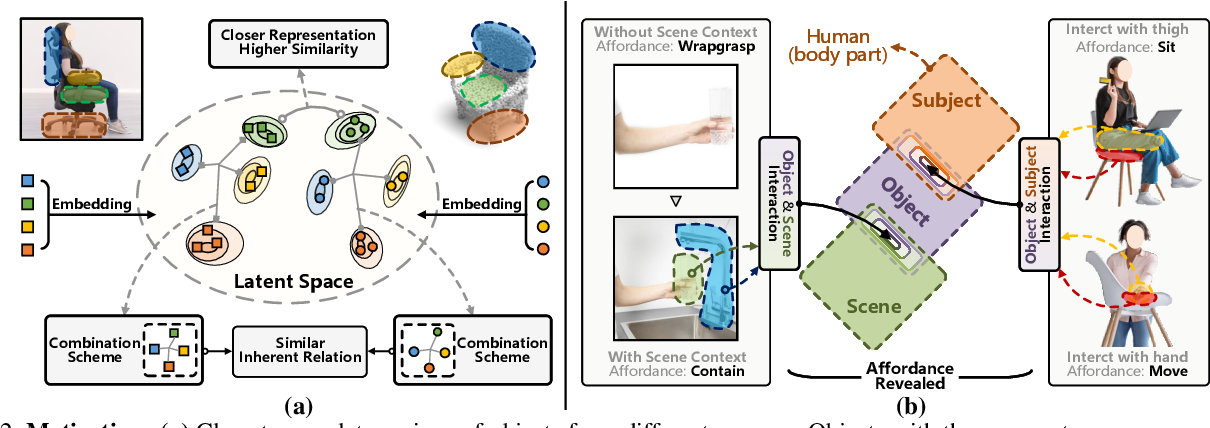
Figure 2 from Grounding 3D Object Affordance from 2D Interactions in ...
Advertisement Space (300x250)

Figure 1 from Rethinking 3D Dense Caption and Visual Grounding in A ...

Figure 3 from Grounding 3D Object Affordance from 2D Interactions in ...

Figure 5 from Grounding 3D Object Affordance from 2D Interactions in ...

Figure 3 from Task-oriented Sequential Grounding in 3D Scenes ...

Table 1 from Task-oriented Sequential Grounding in 3D Scenes | Semantic ...

Figure 15 from Grounding 3D Object Affordance from 2D Interactions in ...

Figure 7 from Grounding 3D Object Affordance from 2D Interactions in ...
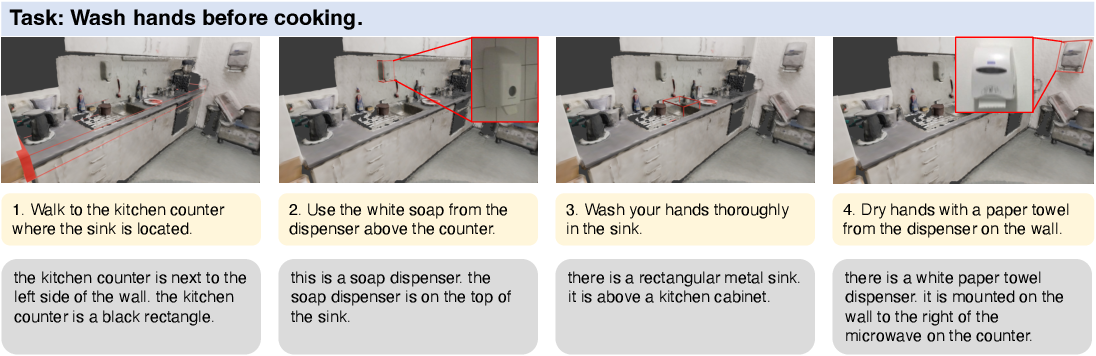
Figure 2 from Task-oriented Sequential Grounding and Navigation in 3D ...

Figure 2 from A Comprehensive Survey of 3D Dense Captioning: Localizing ...

Figure 2 from NS3D: Neuro-Symbolic Grounding of 3D Objects and ...
Advertisement Space (336x280)

Figure 2 from Multi3DRefer: Grounding Text Description to Multiple 3D ...
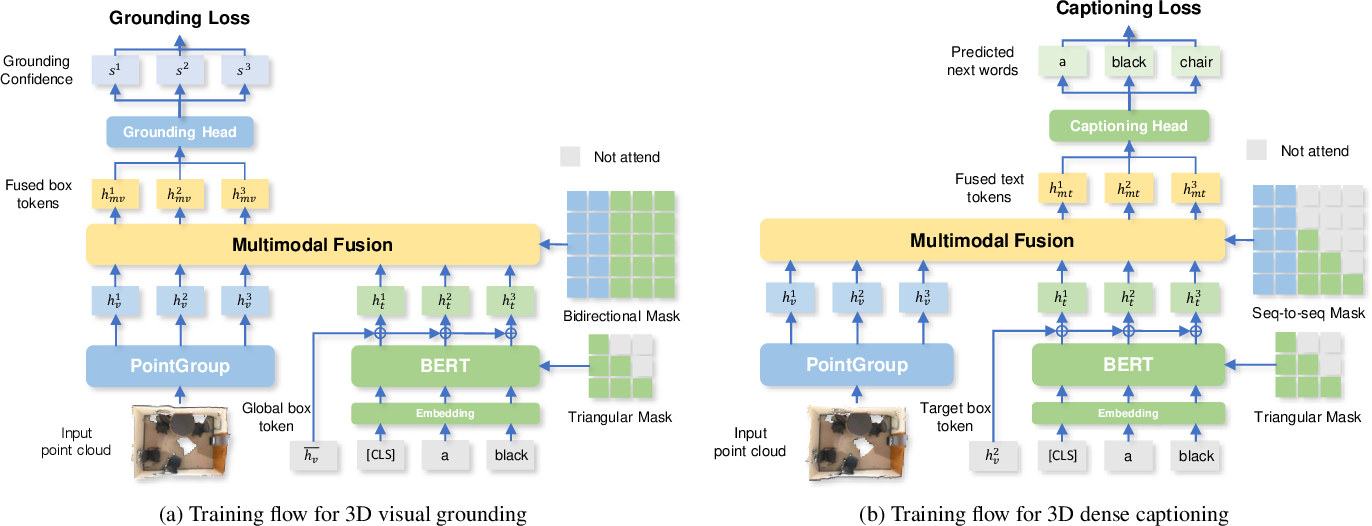
Figure 2 from UniT3D: A Unified Transformer for 3D Dense Captioning and ...

Figure 2 from Layout2Scene: 3D Semantic Layout Guided Scene Generation ...

Figure 2 from EDA: Explicit Text-Decoupling and Dense Alignment for 3D ...
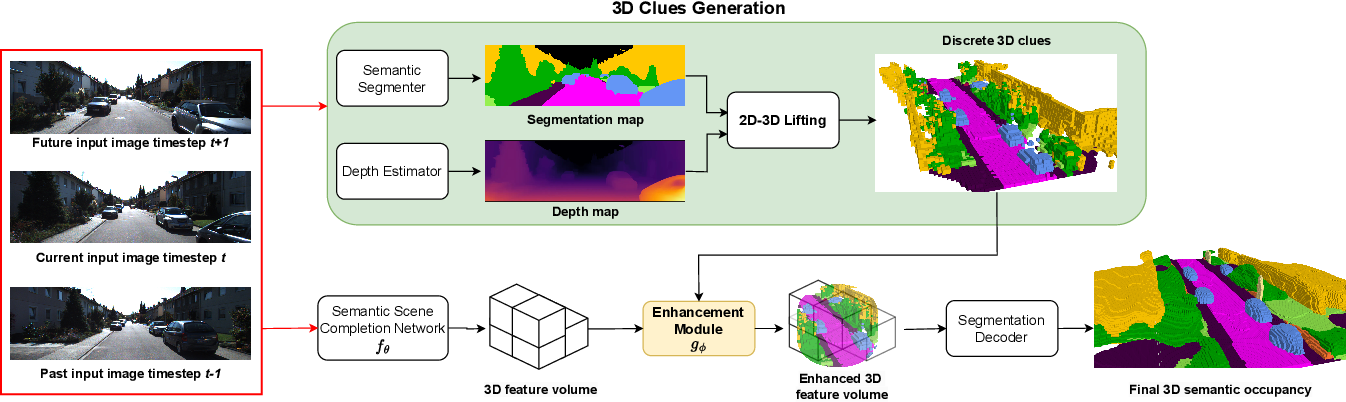
Figure 2 from Semi-supervised 3D Semantic Scene Completion with 2D ...
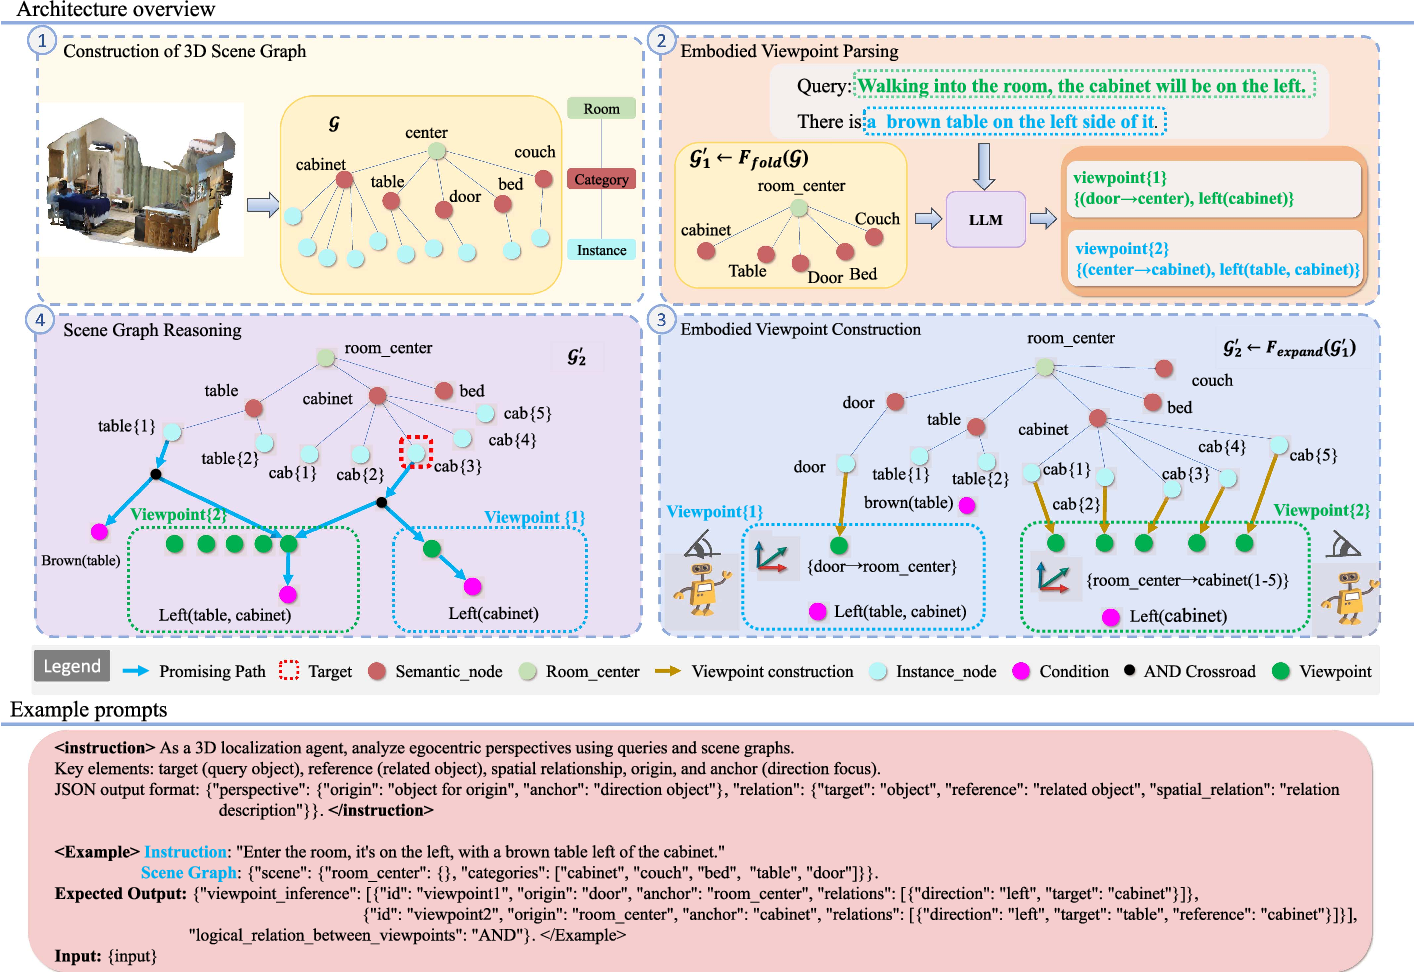
Figure 2 from ViewInfer3D: 3D Visual Grounding Based on Embodied ...
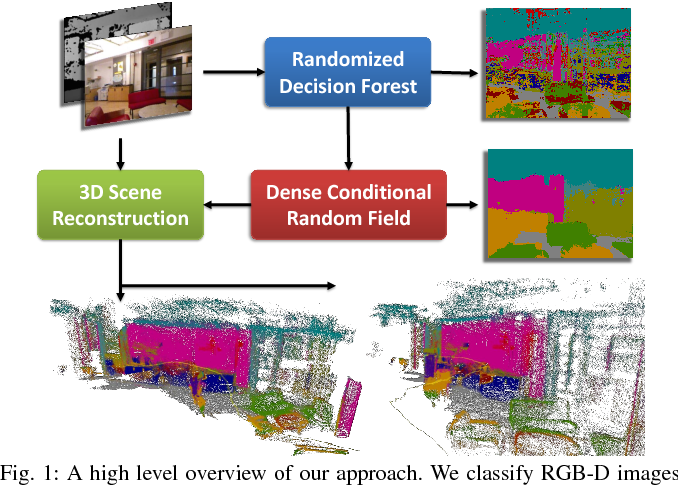
Figure 1 from Dense 3 D Semantic Mapping of Indoor Scenes from RGB-D ...

Figure 2 from Multi3DRefer: Grounding Text Description to Multiple 3D ...

Figure 1 from Revisiting Visual Grounding | Semantic Scholar
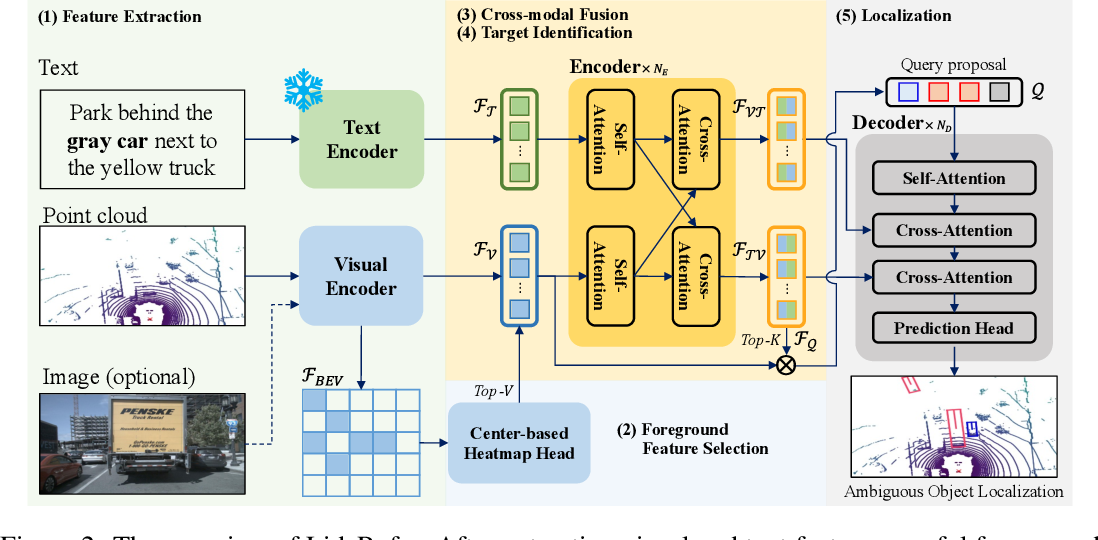
Figure 2 from LidaRefer: Outdoor 3D Visual Grounding for Autonomous ...
Advertisement Space (336x280)

Figure 1 from 3D Object Dense Reconstruction from a Single Depth View ...

Figure 2 from Context-Aware Entity Grounding with Open-Vocabulary 3D ...

Figure 2 from Naturally Supervised 3D Visual Grounding with Language ...

Figure 2 from Open-Vocabulary SAM3D: Understand Any 3D Scene | Semantic ...

Figure 2 from Cross-Modal Match for Language Conditioned 3D Object ...

Figure 2 from Efficient 3D Scene Semantic Segmentation via Active ...