
Figure 3 From Dense Object Grounding In 3d Scenes Semantic Scholar

Figure 3 from Dense Object Grounding in 3D Scenes | Semantic Scholar

Figure 2 from Dense Object Grounding in 3D Scenes | Semantic Scholar

Figure 1 from Dense Object Grounding in 3D Scenes | Semantic Scholar

Table 1 from Dense Object Grounding in 3D Scenes | Semantic Scholar

Table 2 from Dense Object Grounding in 3D Scenes | Semantic Scholar

Figure 3 from Grounding 3D Object Affordance from 2D Interactions in ...

Figure 3 from Task-oriented Sequential Grounding in 3D Scenes ...
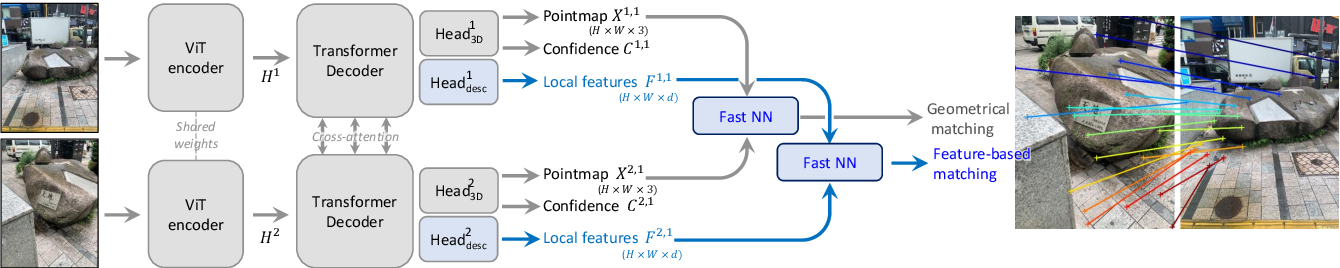
Figure 2 from Grounding Image Matching in 3D with MASt3R | Semantic Scholar

Figure 3 from Multi-Modal Streaming 3D Object Detection | Semantic Scholar
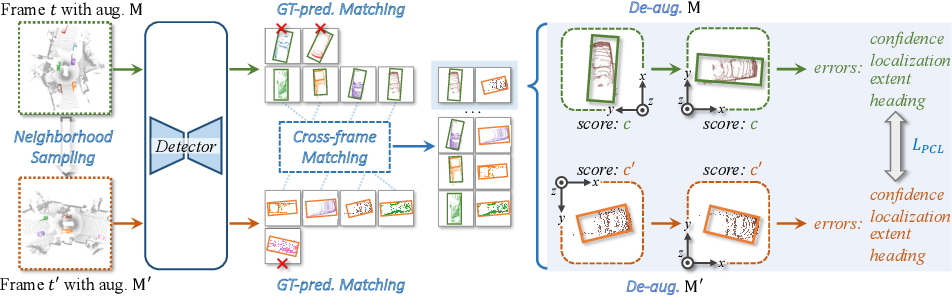
Figure 3 from Towards Stable 3D Object Detection | Semantic Scholar
Advertisement Space (300x250)

Figure 1 from Rethinking 3D Dense Caption and Visual Grounding in A ...
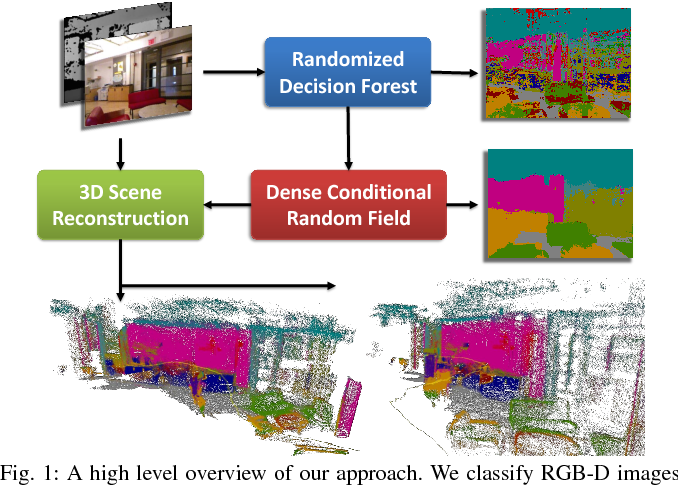
Figure 1 from Dense 3 D Semantic Mapping of Indoor Scenes from RGB-D ...

Figure 5 from Grounding 3D Object Affordance from 2D Interactions in ...

Figure 4 from Sparse Dense Fusion for 3D Object Detection | Semantic ...

Figure 1 from 3D Object Detection with Pointformer | Semantic Scholar

Table 1 from Task-oriented Sequential Grounding in 3D Scenes | Semantic ...

Figure 7 from Grounding 3D Object Affordance from 2D Interactions in ...

Figure 15 from Grounding 3D Object Affordance from 2D Interactions in ...
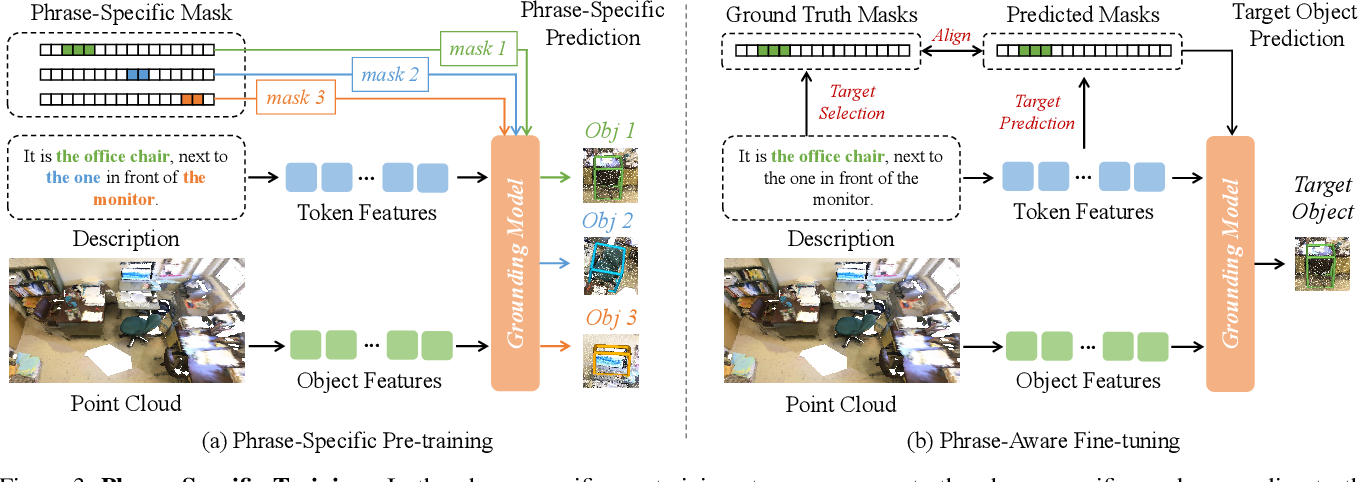
Figure 3 from Toward Explainable and Fine-Grained 3D Grounding through ...

Figure 3 from Multi3DRefer: Grounding Text Description to Multiple 3D ...
Advertisement Space (336x280)
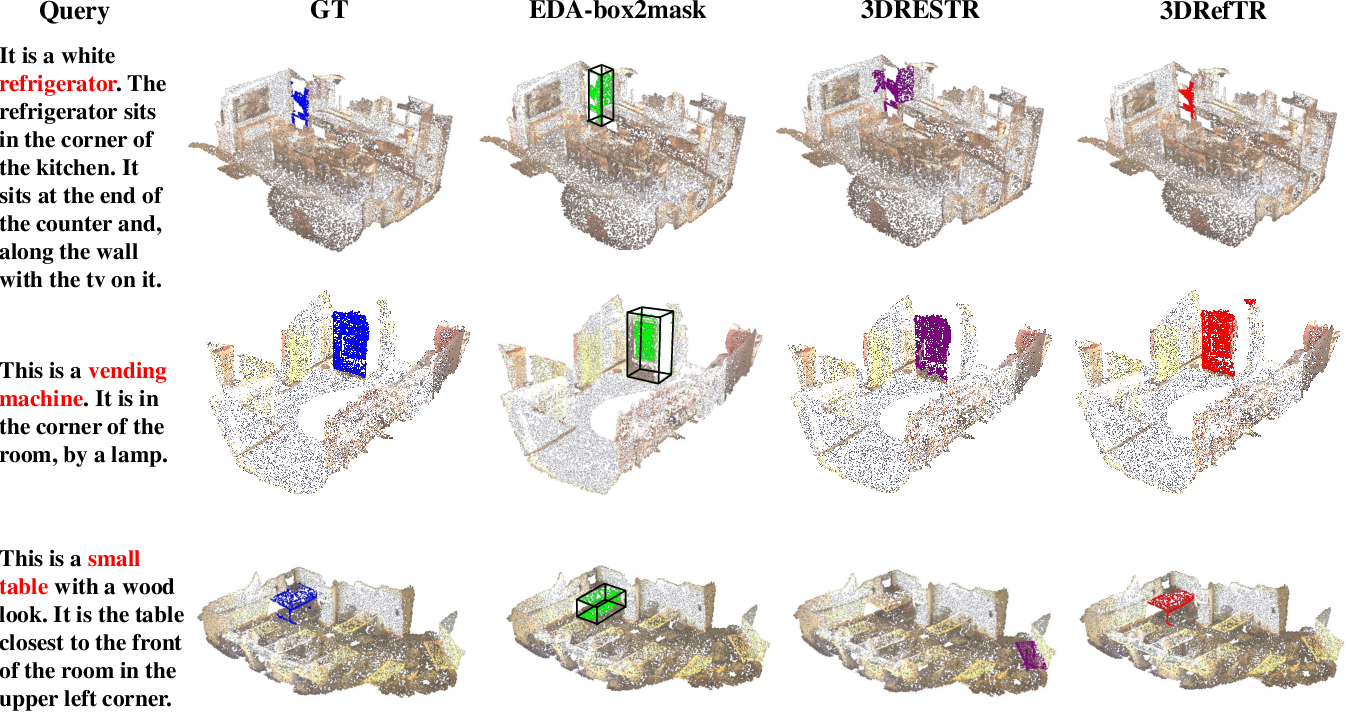
Figure 3 from A Unified Framework for 3D Point Cloud Visual Grounding ...

Figure 1 from 3D Object Dense Reconstruction from a Single Depth View ...
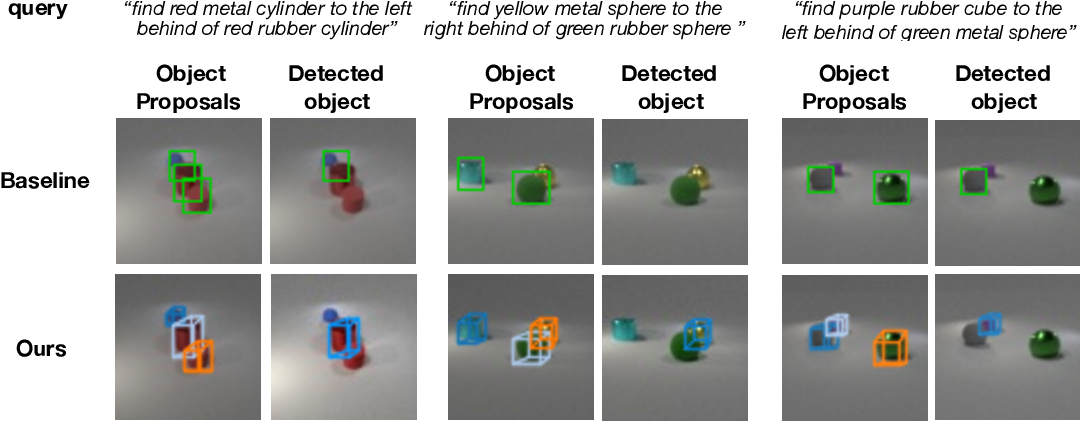
Figure 3 from Embodied Language Grounding with Implicit 3D Visual ...

Figure 1 from Revisiting Visual Grounding | Semantic Scholar
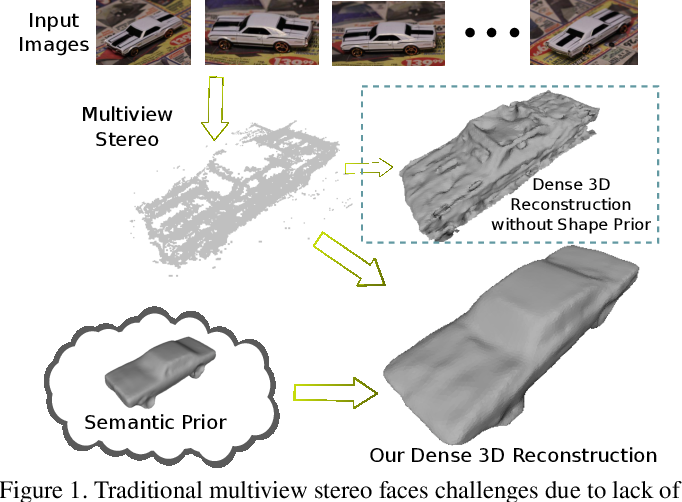
Figure 1 from Dense Object Reconstruction with Semantic Priors ...

Figure 3 from Naturally Supervised 3D Visual Grounding with Language ...

Figure 3 from Example-based synthesis of 3D object arrangements ...
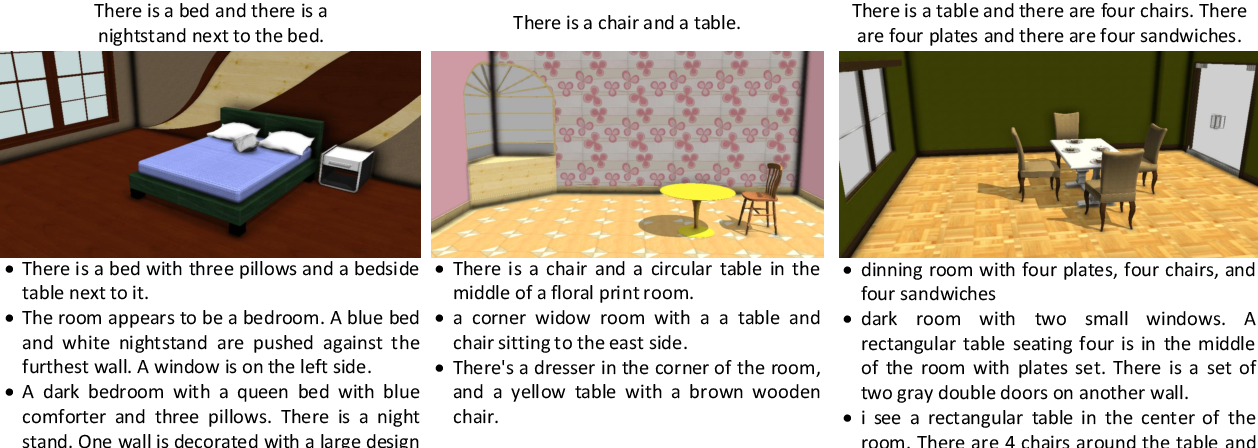
Figure 3 from Text to 3D Scene Generation with Rich Lexical Grounding ...

Figure 3 from LLM-Grounder: Open-Vocabulary 3D Visual Grounding with ...

Figure 1 from Toward Explainable and Fine-Grained 3D Grounding through ...
Advertisement Space (336x280)

Figure 3 from SGRec3D: Self-Supervised 3D Scene Graph Learning via ...

Figure 1 from Cross3DVG: Cross-Dataset 3D Visual Grounding on Different ...

Figure 1 from AugRefer: Advancing 3D Visual Grounding via Cross-Modal ...
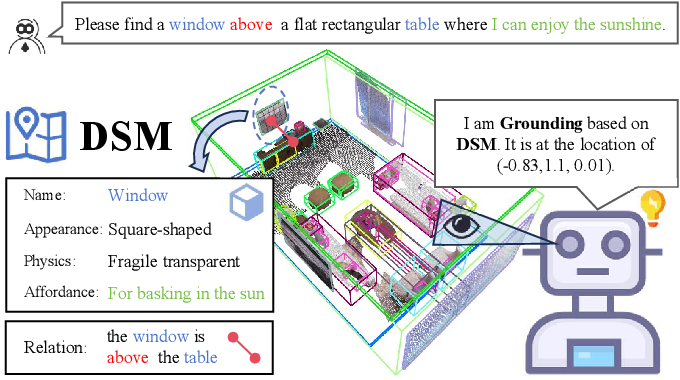
Figure 1 from DSM: Constructing a Diverse Semantic Map for 3D Visual ...

Figure 1 from SeCG: Semantic-Enhanced 3D Visual Grounding via Cross ...

Figure 1 from Incremental Object Grounding Using Scene Graphs ...