
Figure 2 From Text Spotting Transformers Semantic Scholar
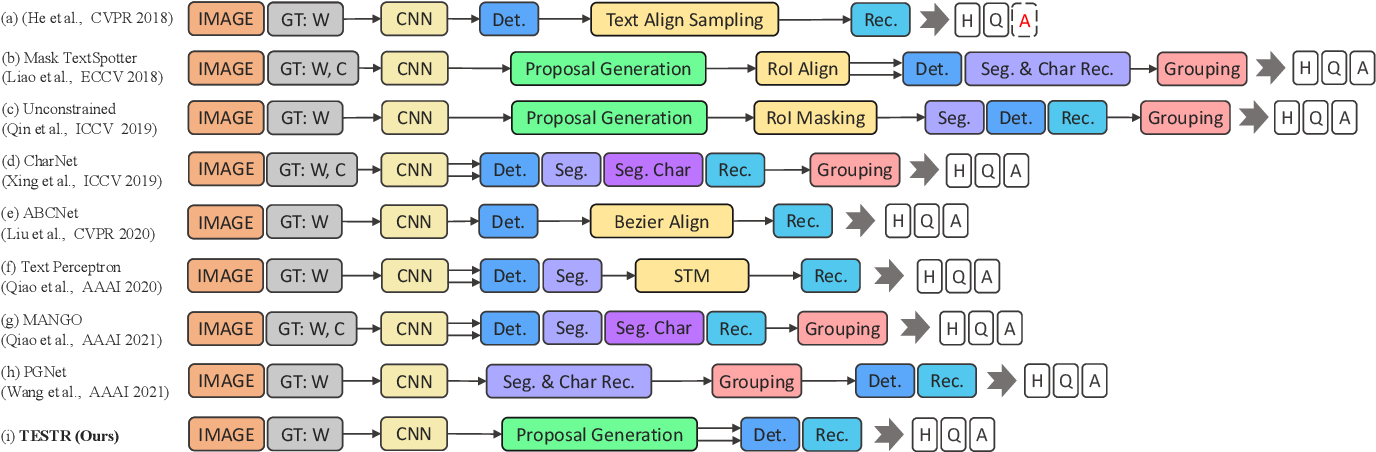
Figure 2 from Text Spotting Transformers | Semantic Scholar
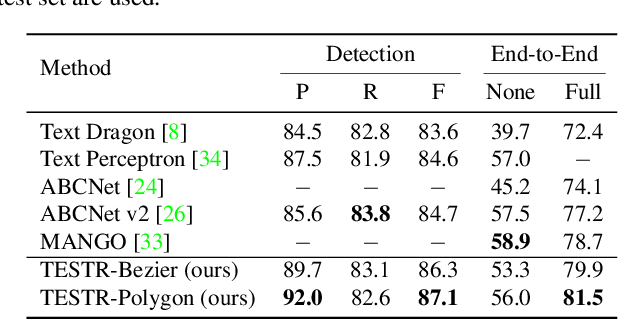
Table 2 from Text Spotting Transformers | Semantic Scholar
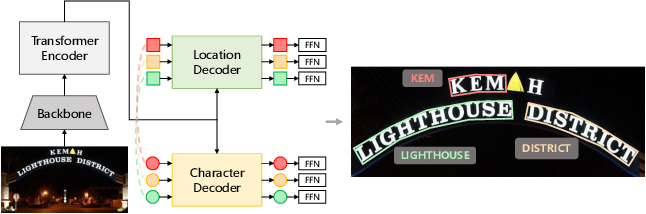
Figure 1 from Text Spotting Transformers | Semantic Scholar
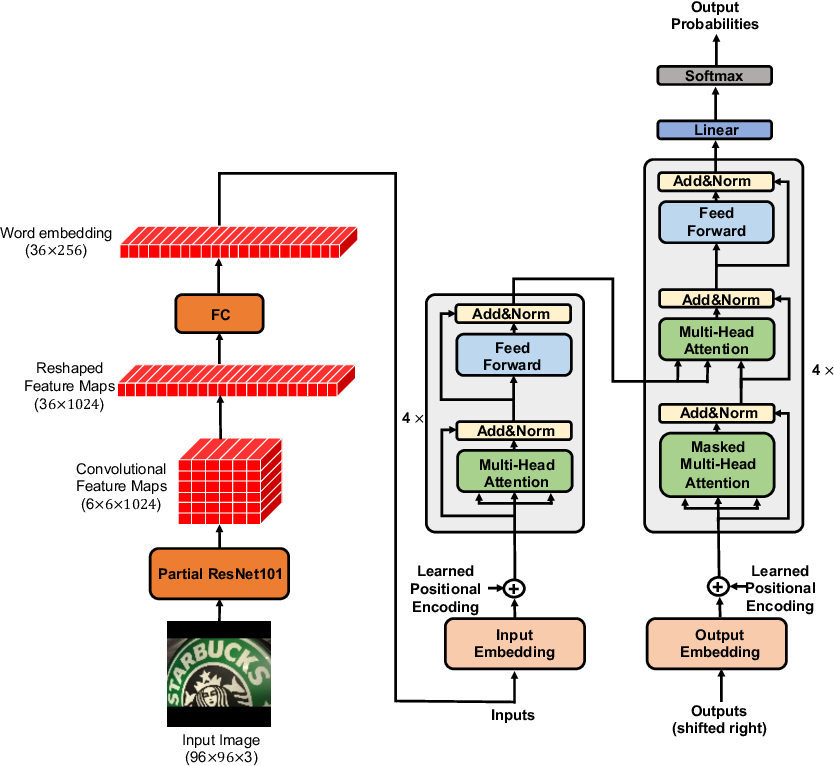
Figure 2 from Scene Text Recognition via Transformer | Semantic Scholar
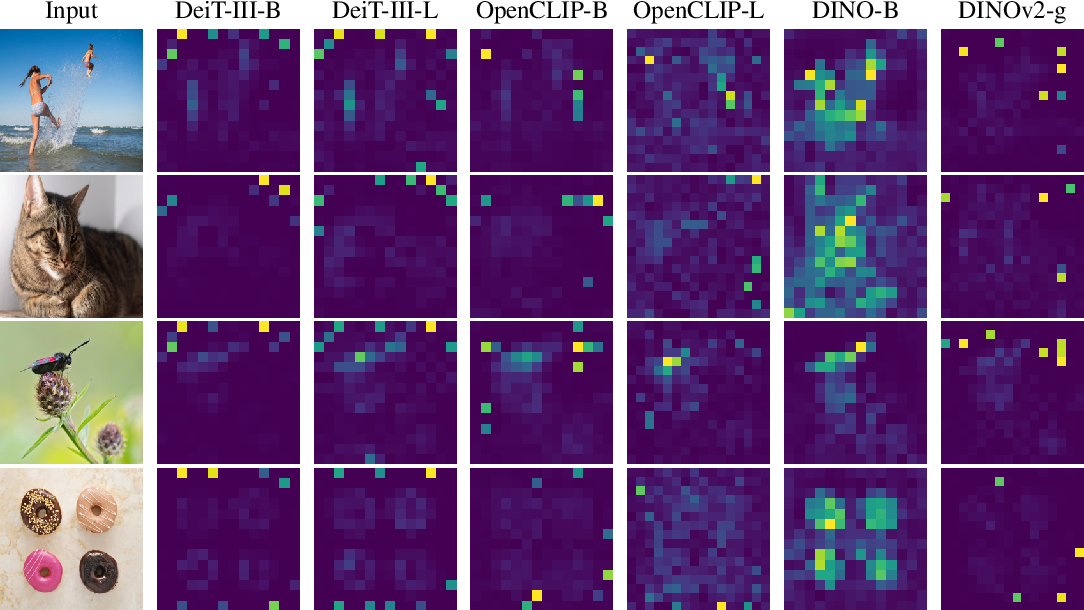
Figure 2 from Vision Transformers Need Registers | Semantic Scholar
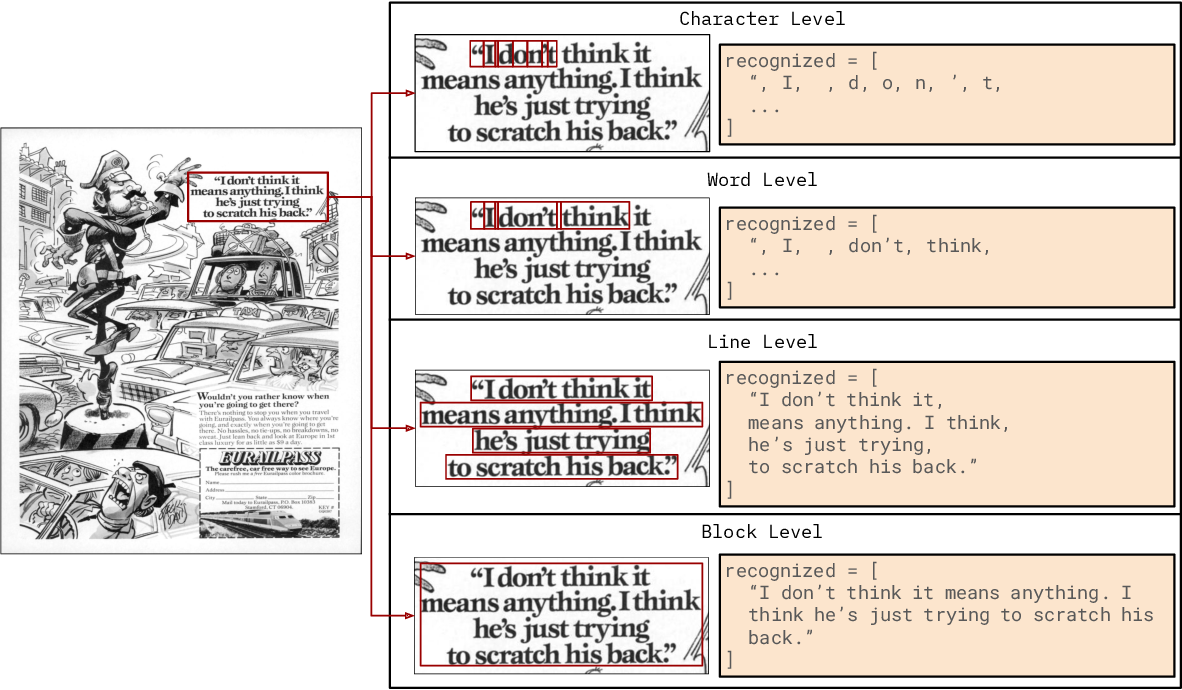
Figure 1 from Block-level Text Spotting with LLMs | Semantic Scholar

Figure 2 from Text Spotting with a Unified Transformer Decoder ...

Figure 2 from Towards Weakly-Supervised Text Spotting using a Multi ...
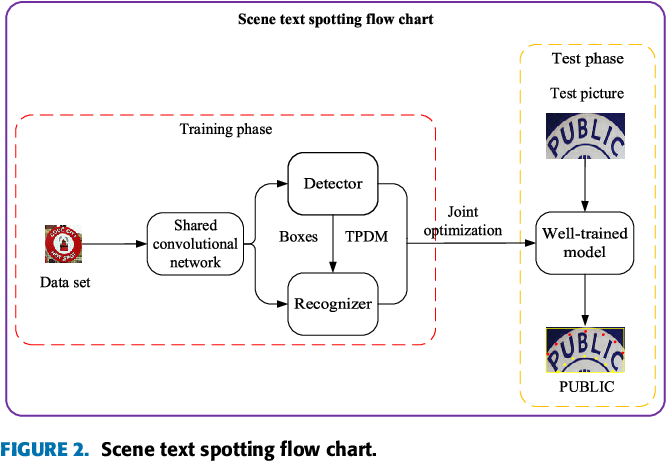
Figure 2 from Toward Arbitrary-Shaped Text Spotting Based on End-to-End ...
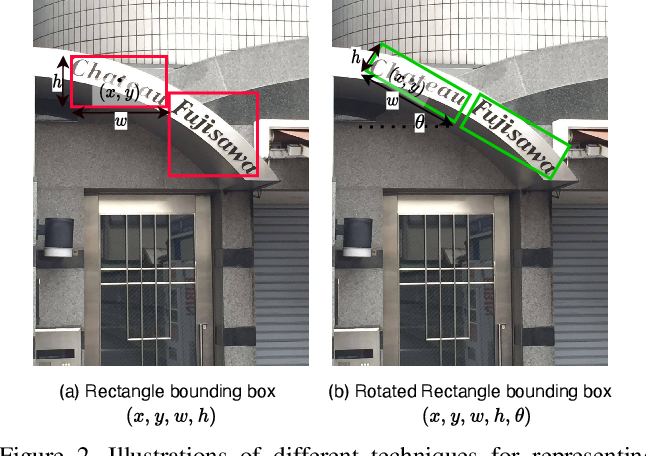
Figure 2 from Transformer-based Text Detection in the Wild | Semantic ...
Advertisement Space (300x250)

Figure 2 from ABCNet: Real-Time Scene Text Spotting With Adaptive ...
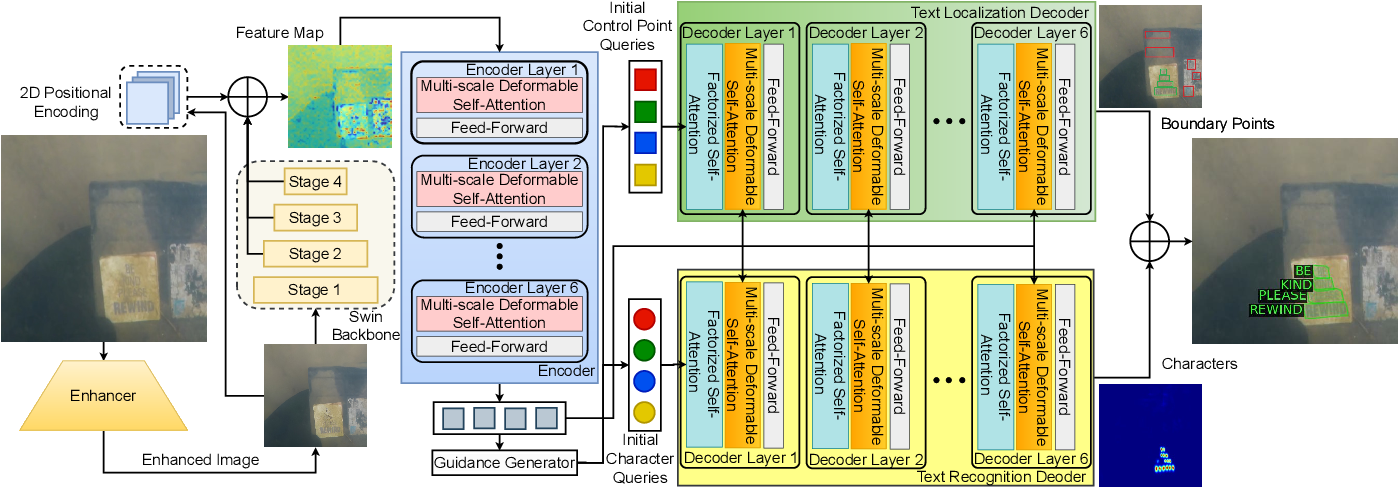
Figure 2 from Diving into the Depths of Spotting Text in Multi-Domain ...
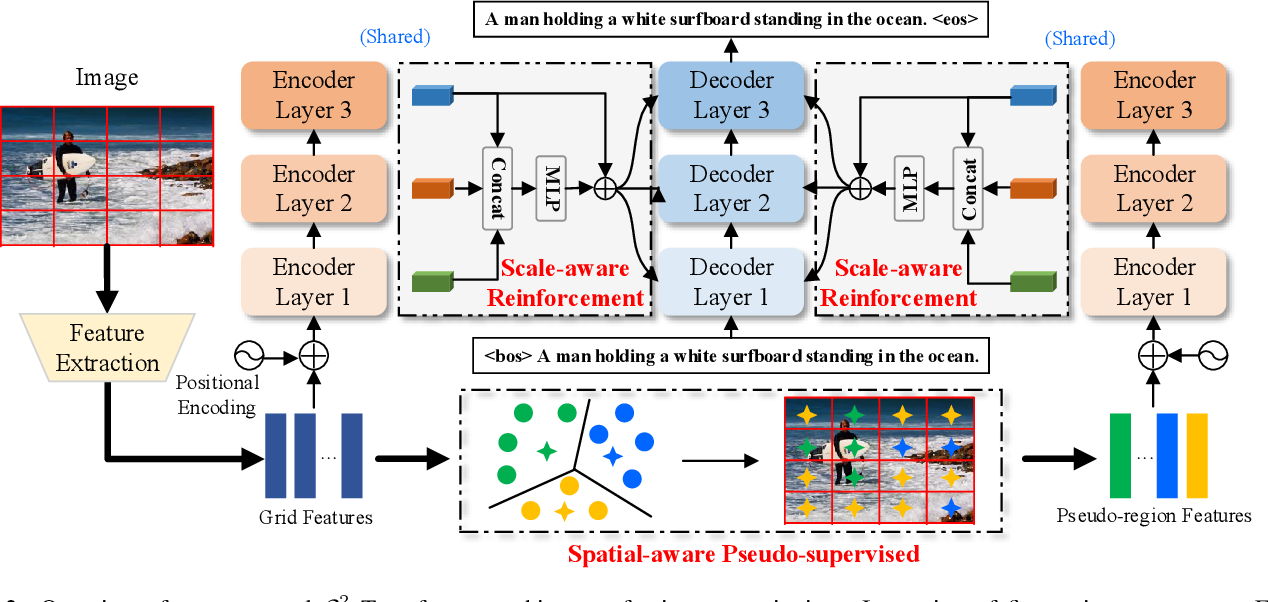
Figure 2 from S2 Transformer for Image Captioning | Semantic Scholar
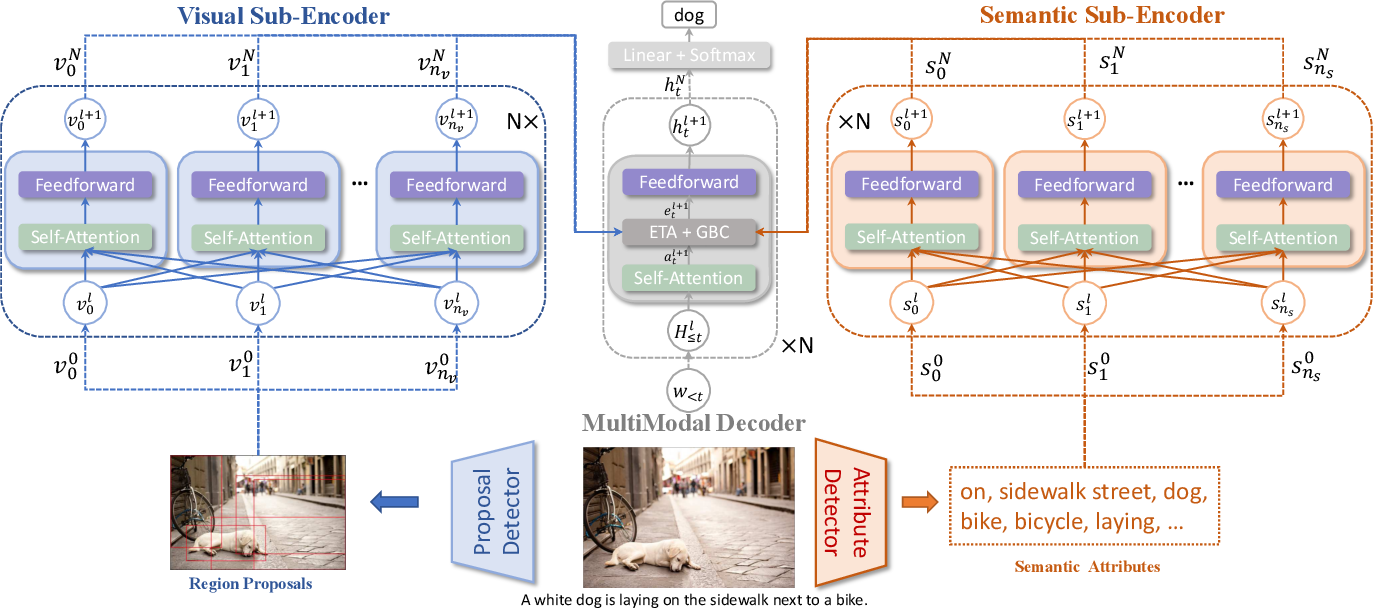
Figure 2 from Entangled Transformer for Image Captioning | Semantic Scholar
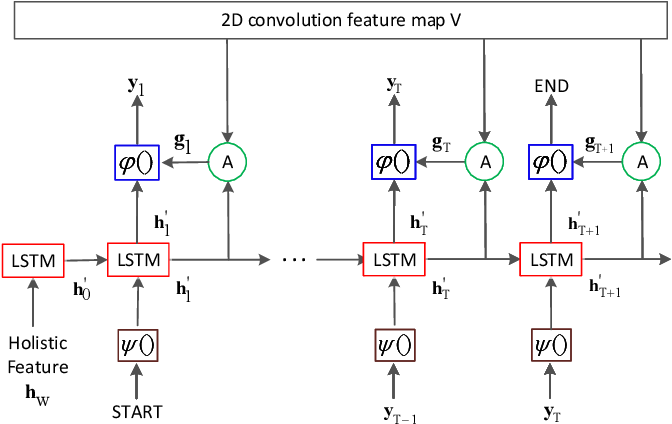
Figure 2 from Towards End-to-End Text Spotting in Natural Scenes ...

Figure 1 from ArTST: Arabic Text and Speech Transformer | Semantic Scholar

Figure 2 from SwinTextSpotter: Scene Text Spotting via Better Synergy ...
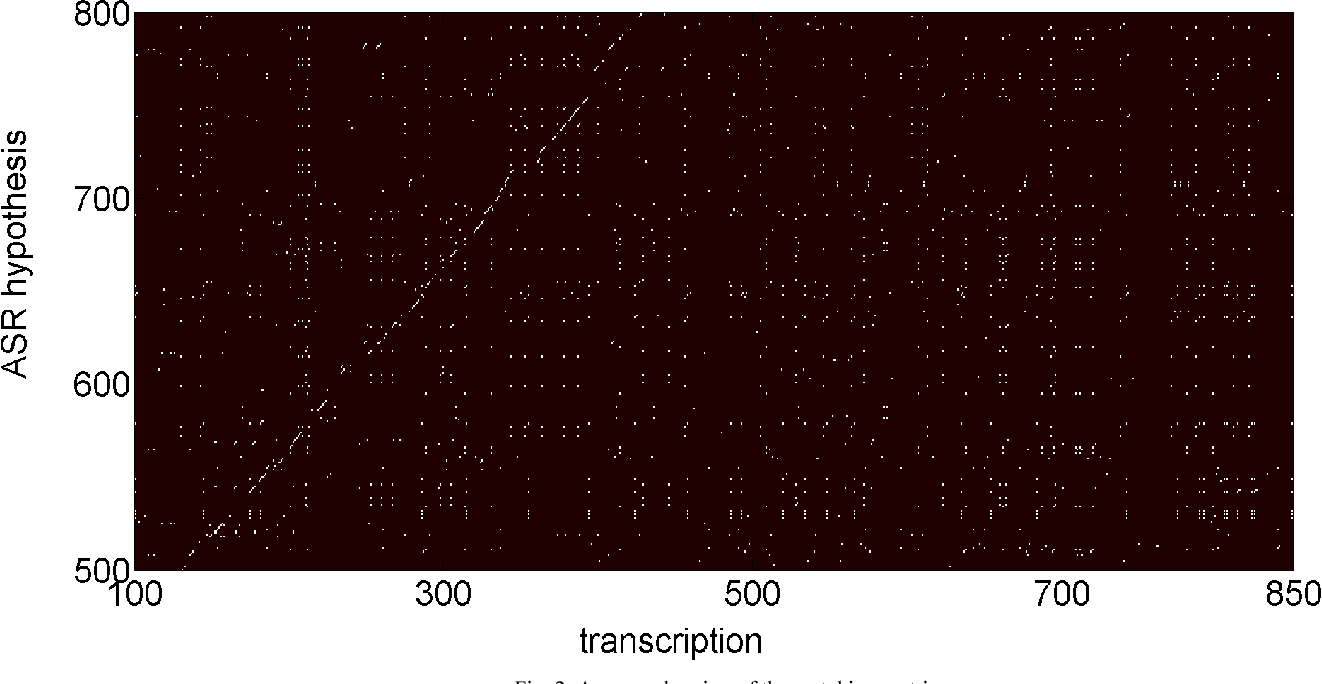
Figure 2 from Text spotting in large speech databases for under ...

Figure 2 from Transformer Tracking | Semantic Scholar

Figure 1 from Memorizing Transformers | Semantic Scholar
Advertisement Space (336x280)

Figure 1 from A fast and robust text spotter | Semantic Scholar

Figure 1 from Semantic Correspondence with Transformers | Semantic Scholar
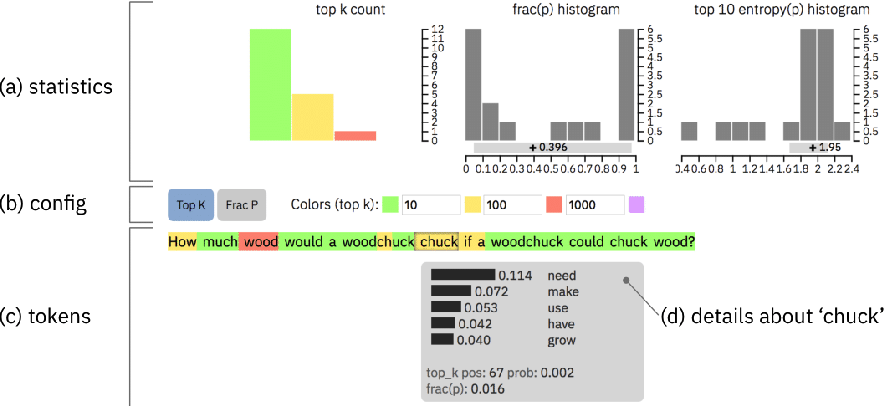
Figure 2.1 from Artificial Text Detection | Semantic Scholar
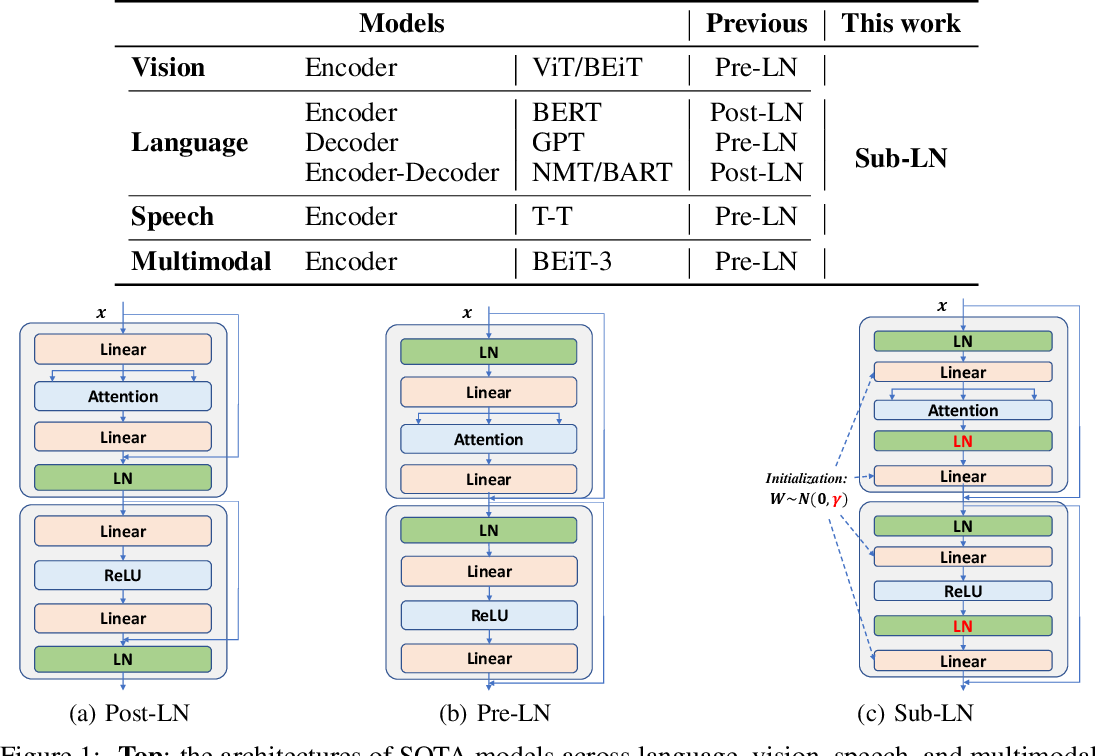
Figure 1 from Foundation Transformers | Semantic Scholar
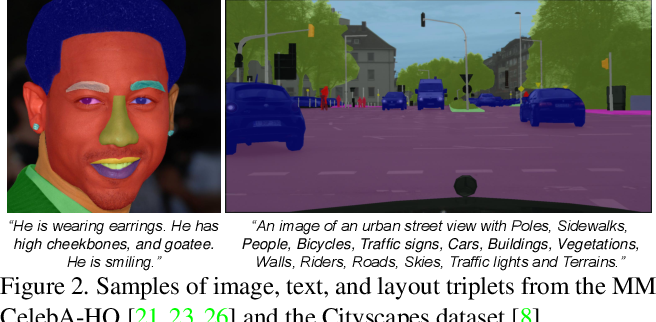
Figure 2 from Learning to Generate Semantic Layouts for Higher Text ...

Figure 1 from Textual Visual Semantic Dataset for Text Spotting ...

Figure 1 from Language Models with Transformers | Semantic Scholar

Figure 10 from A Survey of Visual Transformers | Semantic Scholar

Figure 2 from Spotting AI's Touch: Identifying LLM-Paraphrased Spans in ...

Figure 2 from Automatic Title Generation for Text with Pre-trained ...
Advertisement Space (336x280)
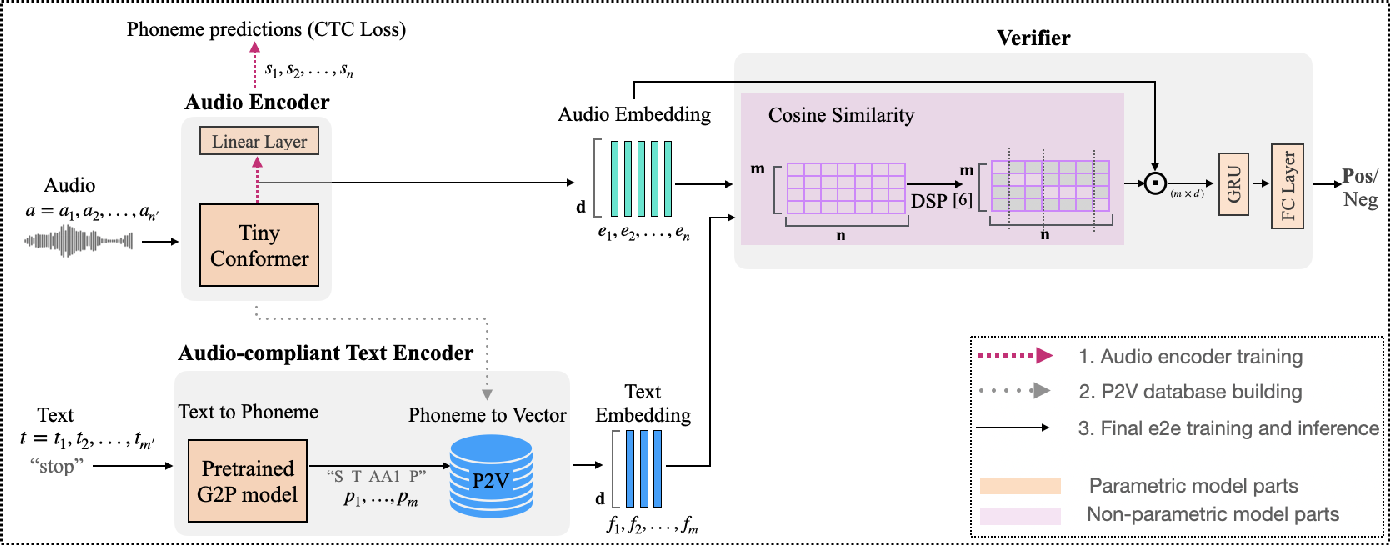
Figure 2 from Flexible Keyword Spotting Based on Homogeneous Audio-Text ...

Figure 1 from Towards Accurate Video Text Spotting with Text-wise ...
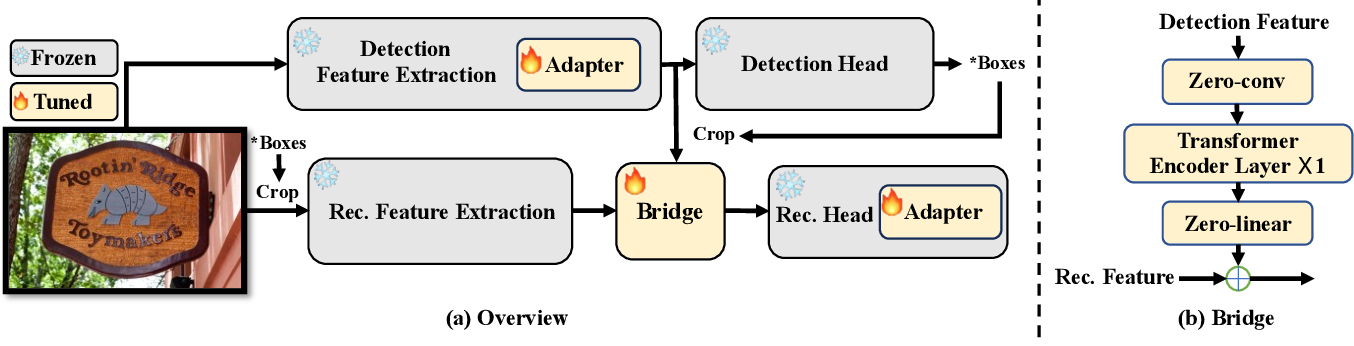
Figure 2 from Bridging the Gap Between End-to-End and Two-Step Text ...
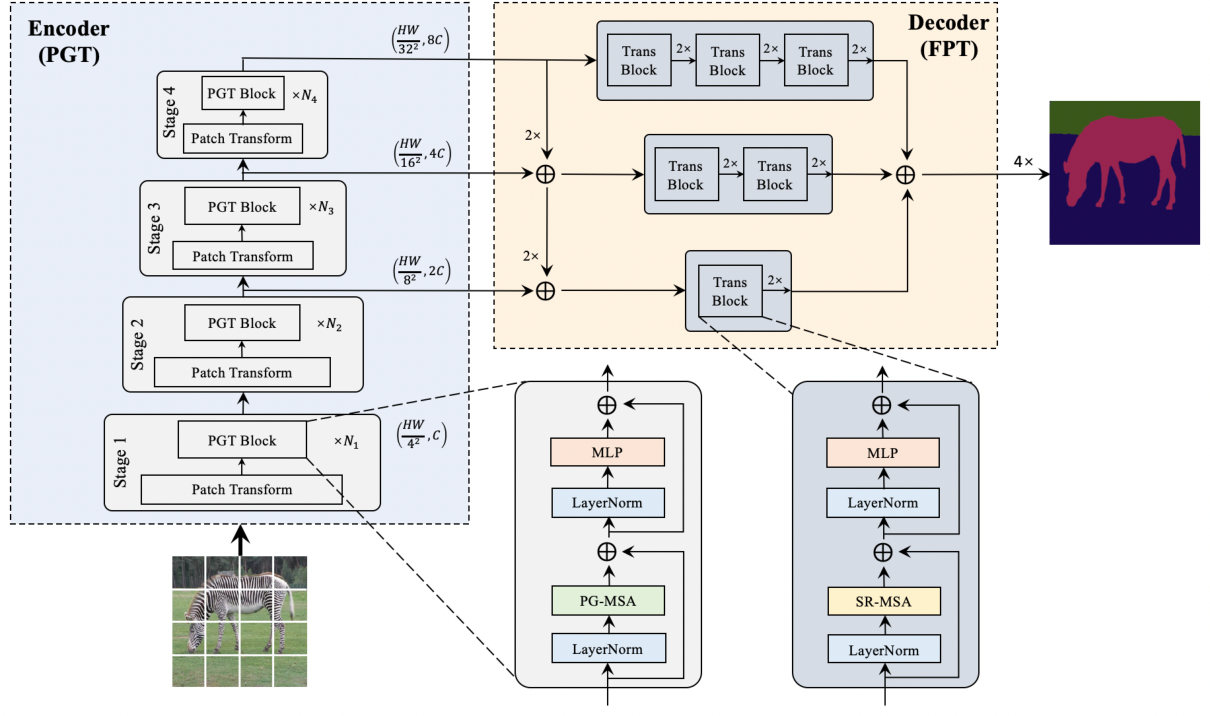
Figure 2 from Fully Transformer Networks for Semantic Image ...

Table 6 from End-to-End Video Text Spotting with Transformer | Semantic ...

Figure 3 from Towards Unified Scene Text Spotting Based on Sequence ...