
Figure 2 From Visual To Speech Conversion Based On Maximum Likelihood

Figure 2 from Low-delay voice conversion based on maximum likelihood ...

Figure 2 from Maximum likelihood voice conversion based on GMM with ...
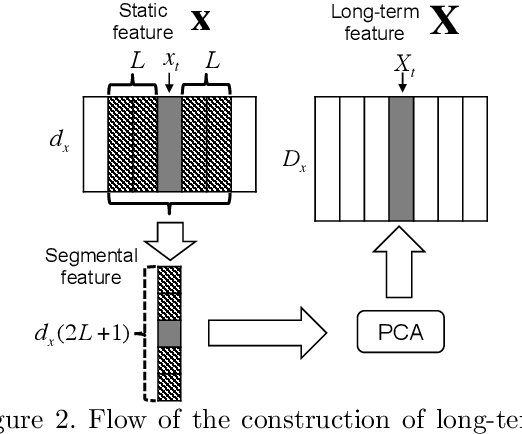
Figure 2 from Visual-to-speech conversion based on maximum likelihood ...

Figure 2 from Maximum likelihood approach to speech enhancement for ...
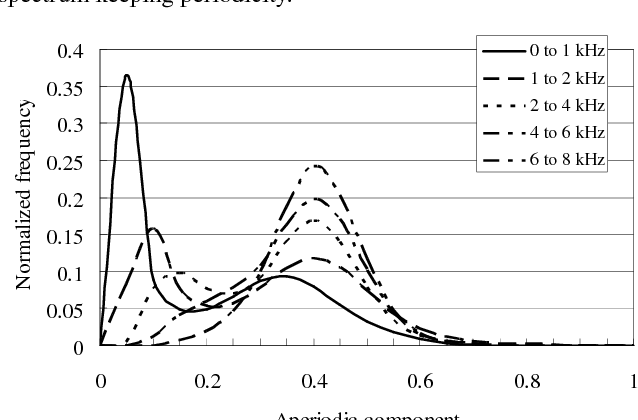
Figure 3 from Maximum likelihood voice conversion based on GMM with ...

Figure 1 from Visual Speech Synthesis Based on Parameter Generation ...
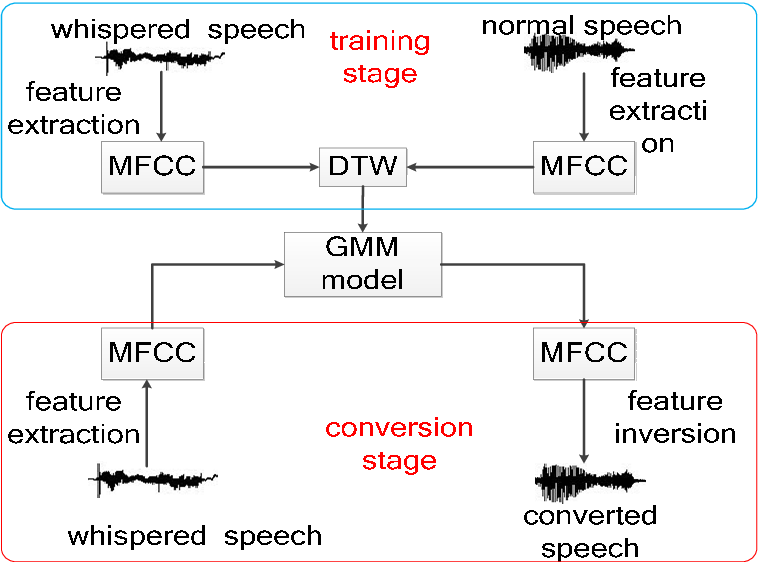
Figure 1 from Whispered Speech Conversion Based on the Inversion of Mel ...
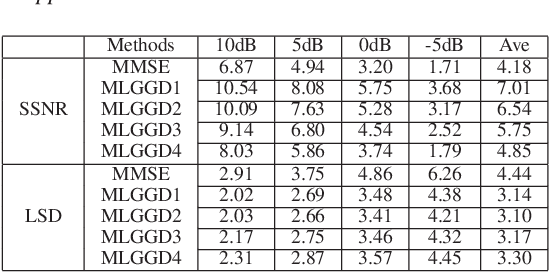
Table 2 from A Maximum Likelihood Approach to Masking-based Speech ...
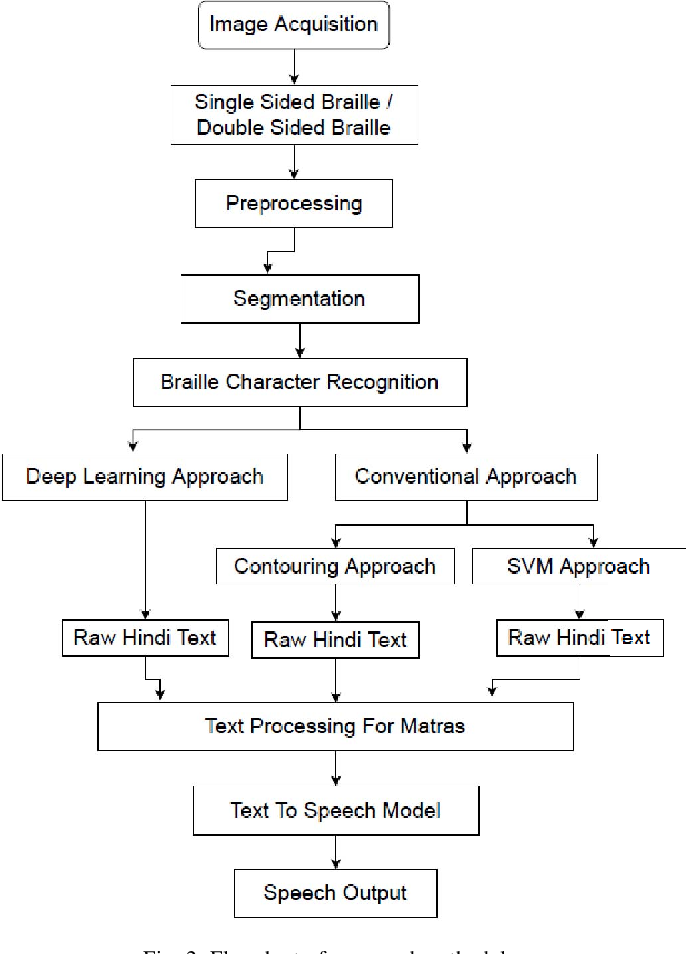
Figure 2 from Conversion of Hindi Braille to Speech using Image and ...

Figure 2 from A Framework for Sign Language to Speech Conversion Using ...
Advertisement Space (300x250)

Figure 2 from Improving the Gap in Visual Speech Recognition Between ...

Figure 2 from Deep Learning for Visual Speech Analysis: A Survey ...

Figure 2 from Infants and Adults Use Visual Cues to Improve Detection ...

Figure 2 from An Overview of Affective Speech Synthesis and Conversion ...

Figure 1 from Text-to-audio-visual speech synthesis based on parameter ...

(PDF) Low-delay voice conversion based on maximum likelihood estimation ...

(PDF) Maximum likelihood voice conversion based on GMM with STRAIGHT ...

Proposed system for Emotion based text to speech conversion Table 2 ...

Figure 1 from Whisper to normal speech conversion using pitch estimated ...

Figure 2 from Aalborg Universitet Maximum Likelihood PSD Estimation for ...
Advertisement Space (336x280)
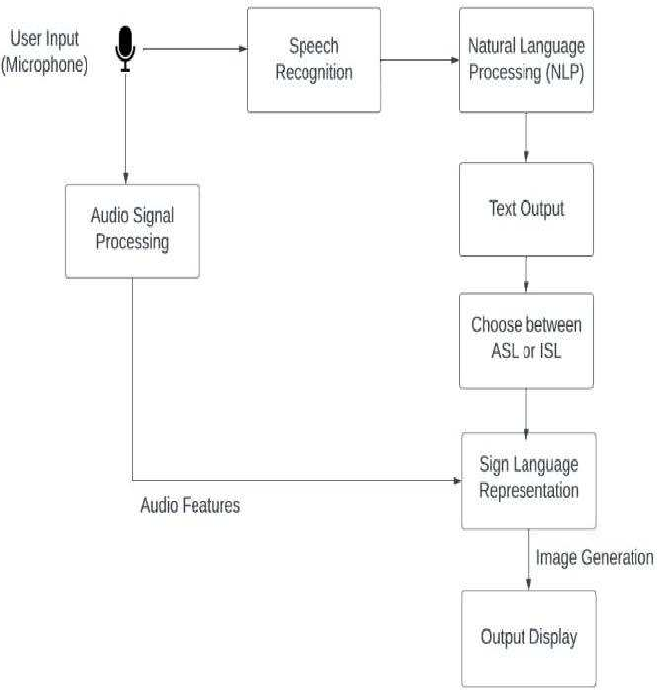
Figure 1 from An Efficient Speech to Sign Language Conversion and Text ...

Text to Speech Conversion based on Emotion using Recurrent Neural Network

Figure 1 from Diffusion-Based Voice Conversion with Fast Maximum ...
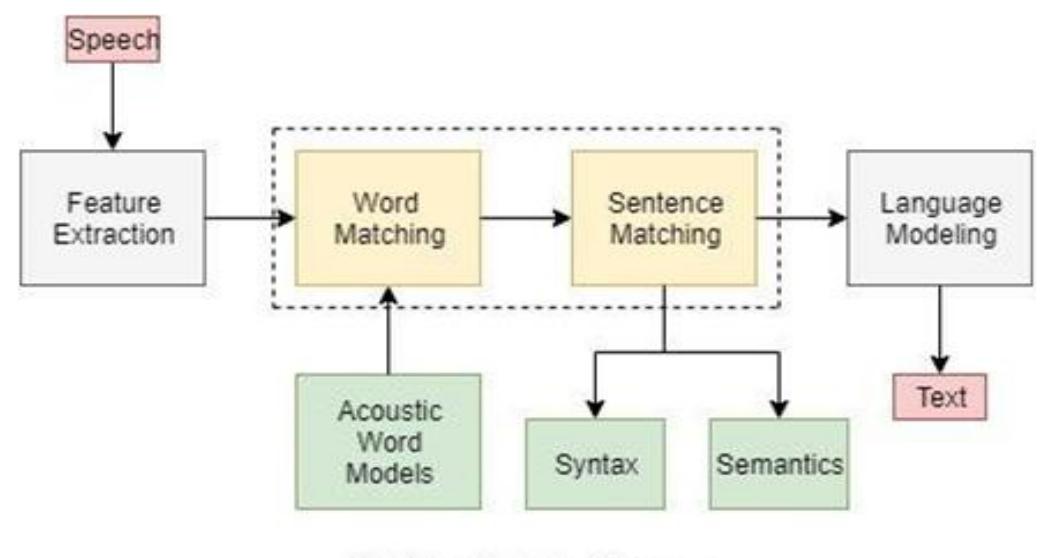
Figure 2 - from A REVIEW ON METHODS FOR SPEECH-TO-TEXT AND

Figure 2 from Real-time Detection of AI-Generated Speech for DeepFake ...
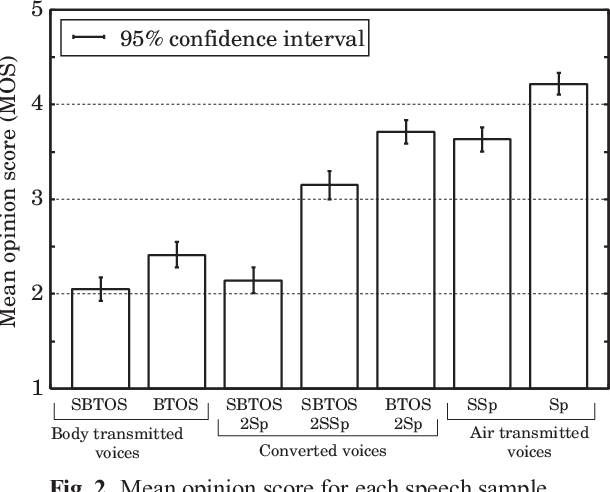
Figure 2 from Voice conversion for various types of body transmitted ...
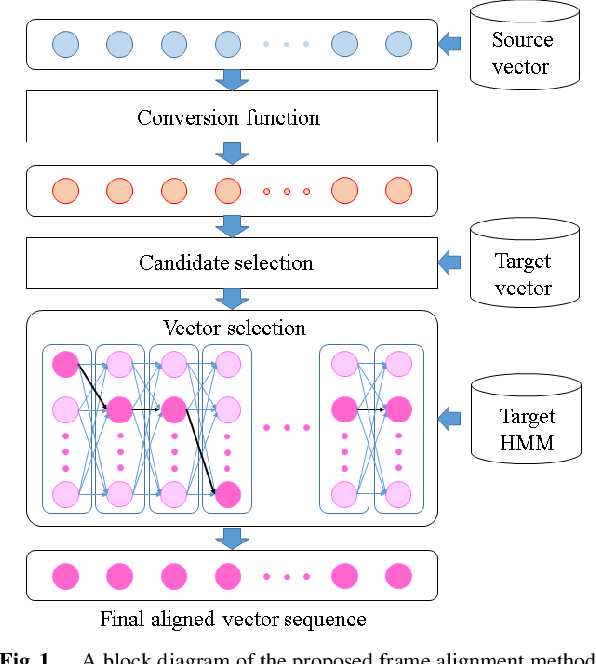
Figure 1 from HMM-Based Maximum Likelihood Frame Alignment for Voice ...

Figure 2 from Speech-to-Face Conversion Using Denoising Diffusion ...
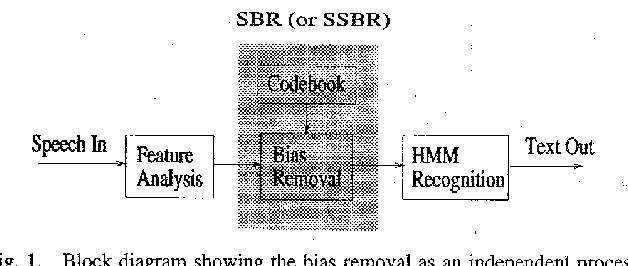
Figure 1 from Signal bias removal by maximum likelihood estimation for ...

Dimensional Affective Speech Synthesis Based on Voice Conversion ...
Advertisement Space (336x280)
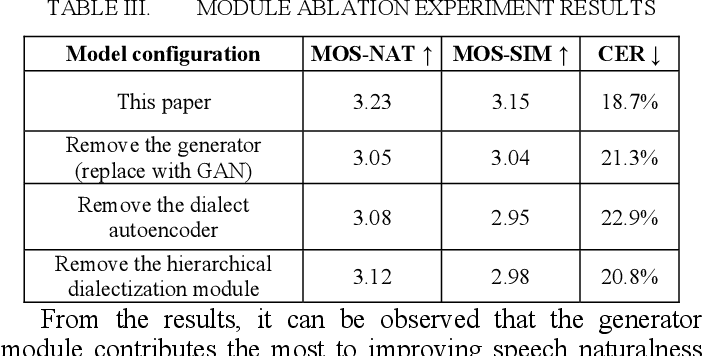
Figure 2 from A Diffusion Model-Based Few-Shot Tibetan Dialect Speech ...
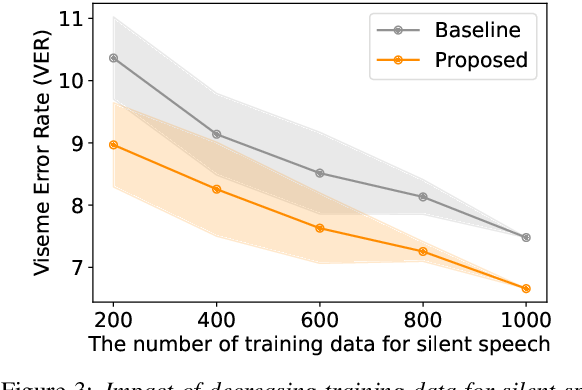
Figure 3 from Improving the Gap in Visual Speech Recognition Between ...
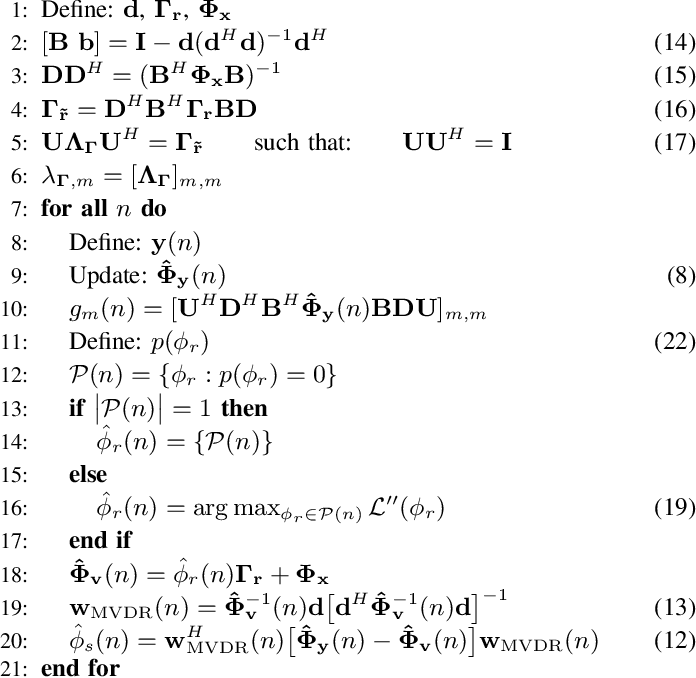
Figure 1 from Aalborg Universitet Maximum Likelihood PSD Estimation for ...

Figure 1 from Improving the Gap in Visual Speech Recognition Between ...

(PDF) A maximum likelihood approach to continuous speech recognition

(PDF) A Maximum Likelihood Approach to Continuous Speech Recognition