
Floemoe50floe On The Fly Moe Inference On Memory

[PDF] MoE-Lightning: High-Throughput MoE Inference on Memory ...
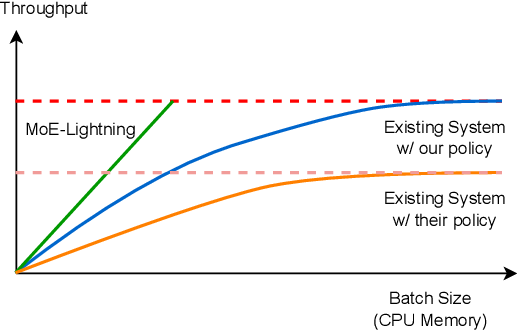
Figure 1 from MoE-Lightning: High-Throughput MoE Inference on Memory ...

[PDF] MoE-Lightning: High-Throughput MoE Inference on Memory ...

[PDF] MoE-Lightning: High-Throughput MoE Inference on Memory ...

[PDF] MoE-Lightning: High-Throughput MoE Inference on Memory ...

Influence of the orb2 3'UTR deletion on fly locomotion and memory ...

ICML Poster FloE: On-the-Fly MoE Inference on Memory-constrained GPU
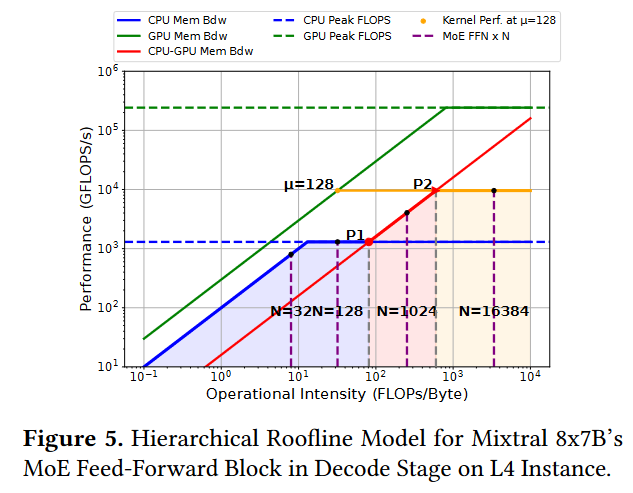
MoE-Lightning: High-Throughput MoE Inference on Memory-constrained GPUs

MoE-Lightning: High-Throughput MoE Inference on Memory-constrained GPUs

MoE-Gen: High-Throughput MoE Inference on a Single GPU with Module ...
Advertisement Space (300x250)

[论文评述] A Scheduling Framework for Efficient MoE Inference on Edge GPU ...

MoE Inference On AnyScale - 知乎
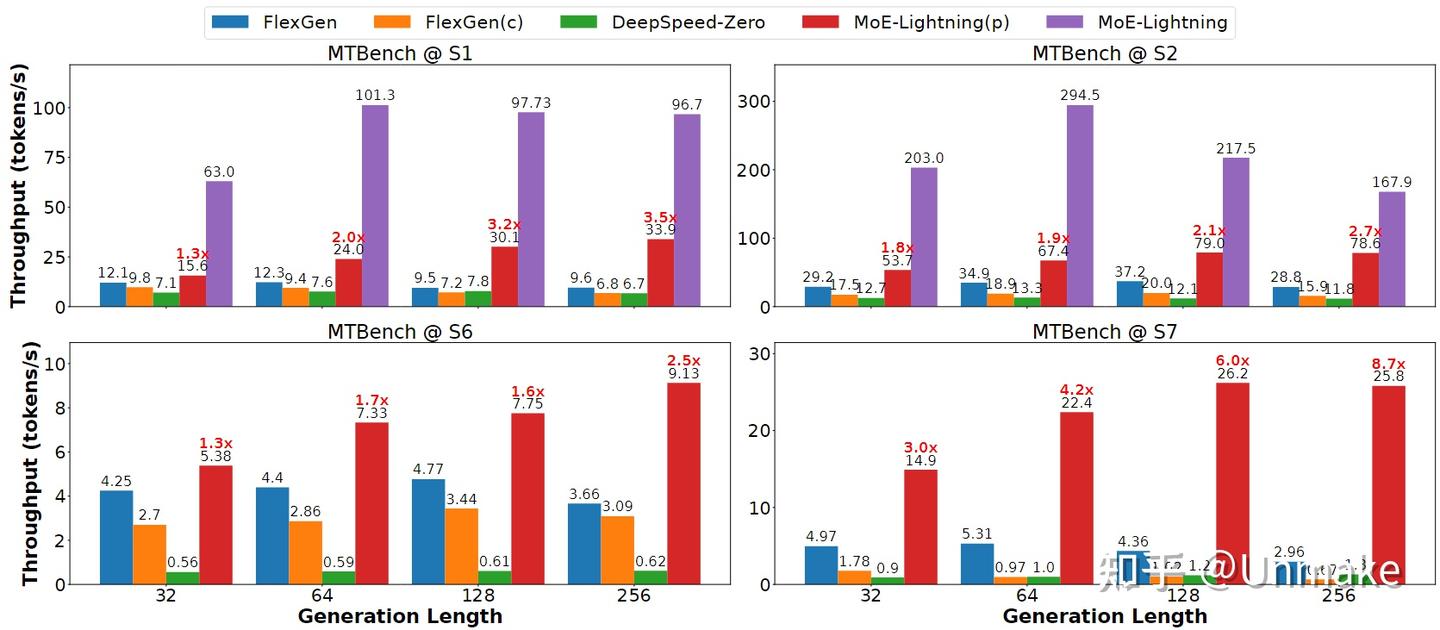
MoE-Lightning: High-Throughput MoE Inference on Memory-constrained GPUs ...

Paper page - MoE-SpAc: Efficient MoE Inference Based on Speculative ...

A Scheduling Framework for Efficient MoE Inference on Edge GPU-NDP ...
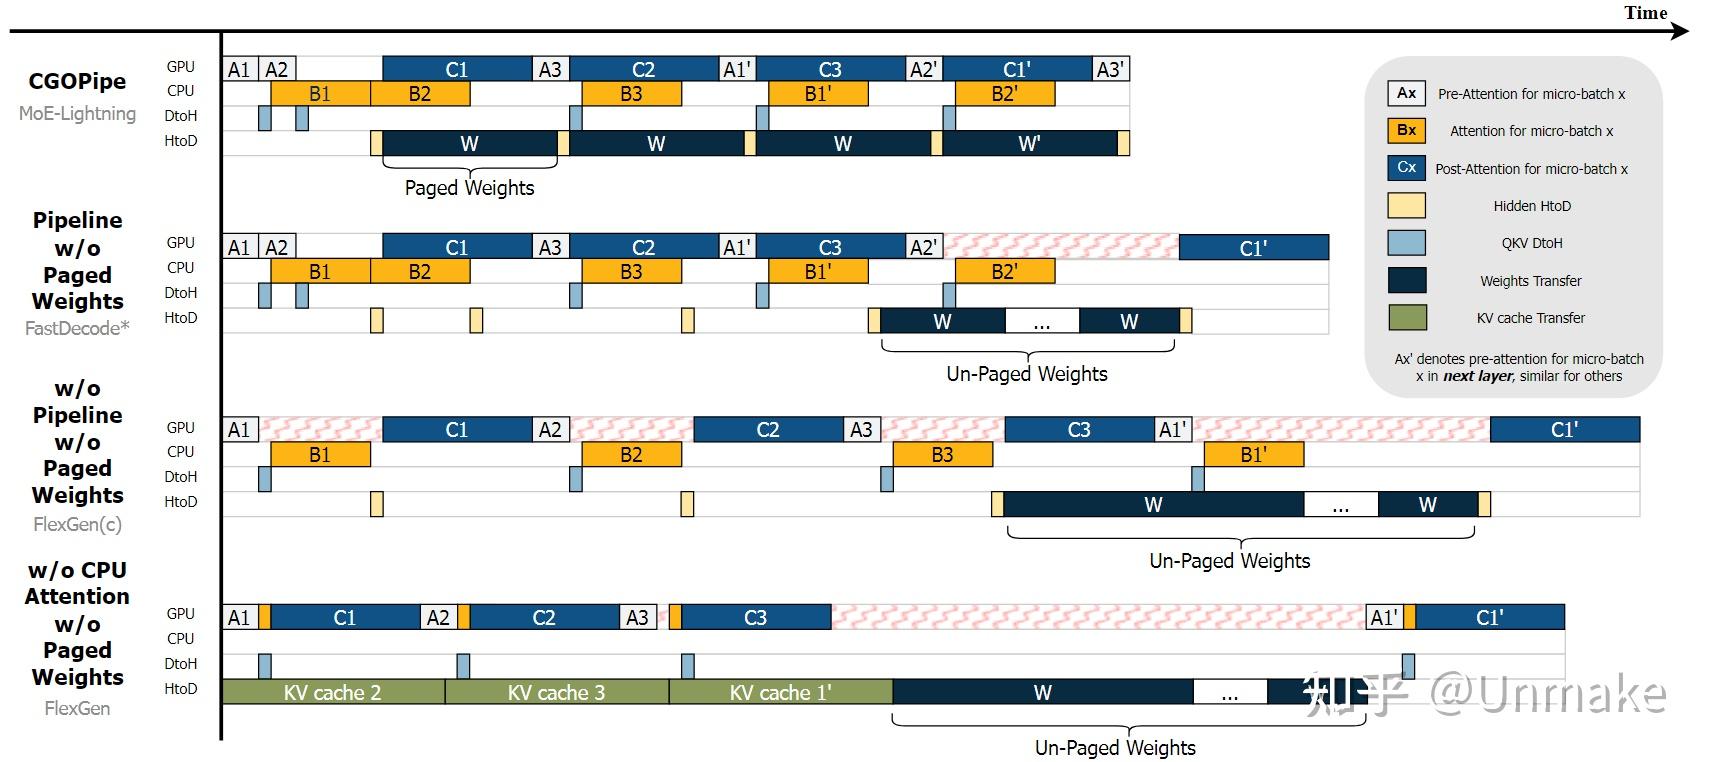
MoE-Lightning: High-Throughput MoE Inference on Memory-constrained GPUs ...
MoE-Lightning: High-Throughput MoE Inference on Memory-constrained GPUs ...

MoE-Lightning: High-Throughput MoE Inference on Memory-constrained GPUs
MoE Model Inference on GPU Cloud: Expert Parallelism, Memory, and Cost ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...
Advertisement Space (336x280)

[论文评述] Efficient CPU-GPU Collaborative Inference for MoE-based LLMs on ...
MoE Inference Costs 8.6x GPU Memory of Dense Models

(PDF) FloE: On-the-Fly MoE Inference
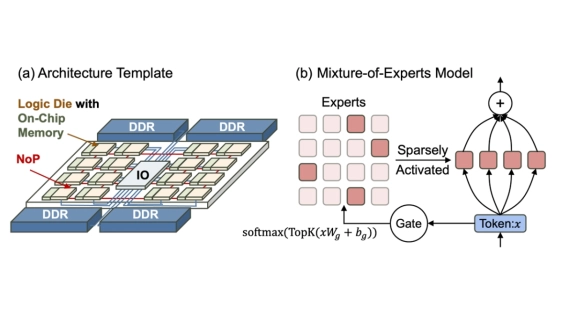
Expert Streaming: Accelerating Low-Batch MoE Inference via Multi ...

[논문 리뷰] MiLo: Efficient Quantized MoE Inference with Mixture of Low ...

[论文评述] SecMoE: Communication-Efficient Secure MoE Inference via Select ...

TIDE: Efficient and Lossless MoE Diffusion LLM Inference with I/O-aware ...
GitHub - zju-stu-lizheng/FloE: The code for paper "FloE: On-the-Fly MoE ...

MiLo: Efficient Quantized MoE Inference with Mixture of Low-Rank ...

ReaLB: Real-Time Load Balancing for Multimodal MoE Inference
Advertisement Space (336x280)

[2502.12224] Accurate Expert Predictions in MoE Inference via Cross ...
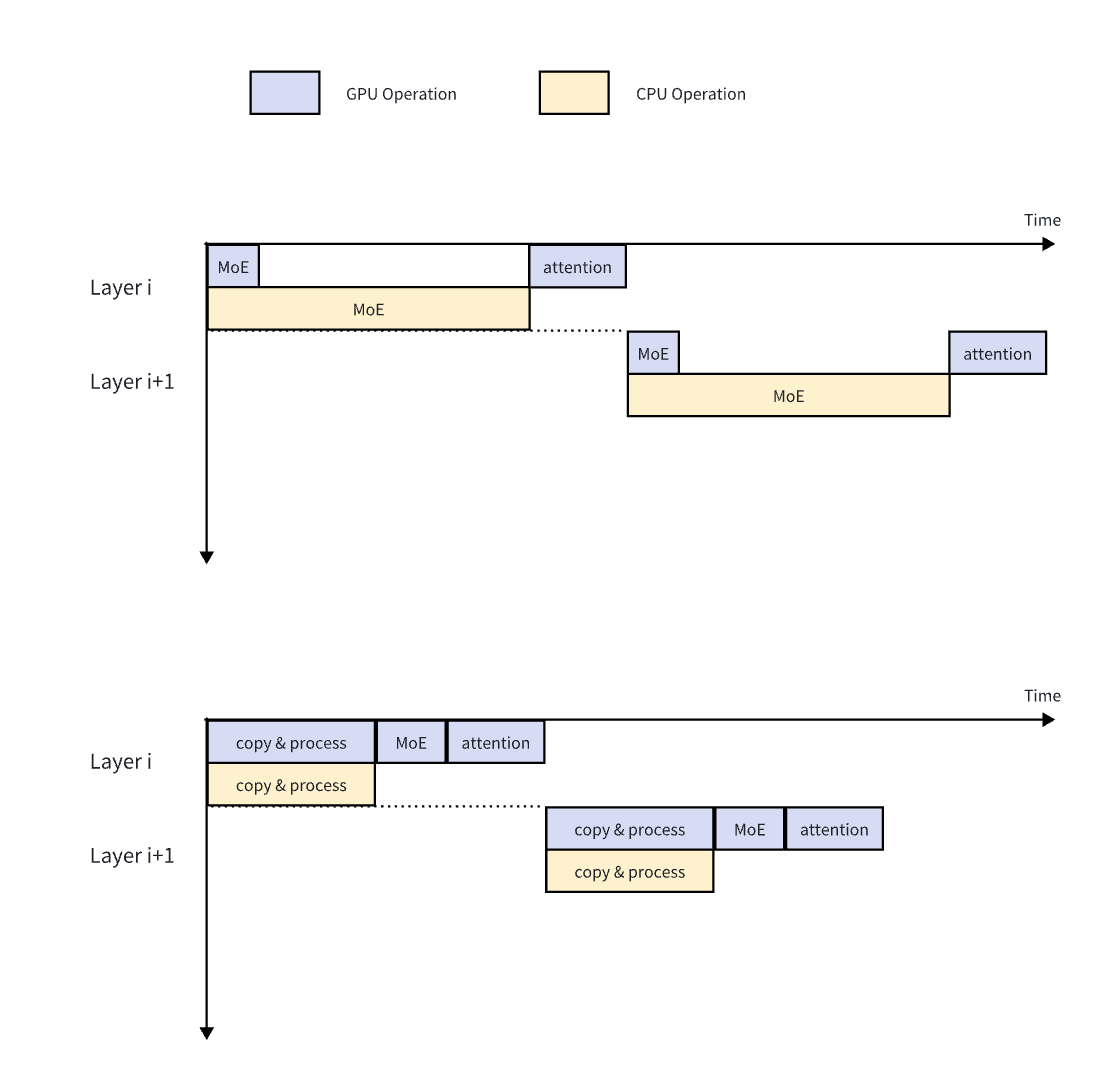
KTransformers — Workstation Heterogeneous Inference for Frontier MoE Models

[논문 리뷰] Accelerating MoE Model Inference with Expert Sharding

Expertflow Achieves Efficient MoE Inference With Adaptive
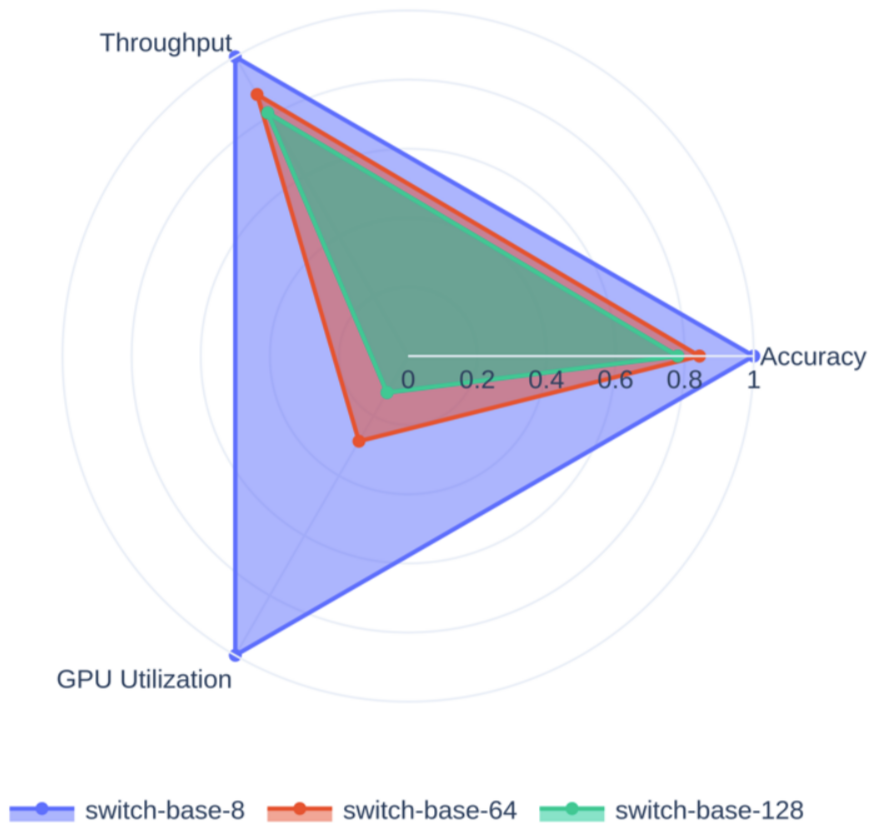
[논문 리뷰] Fast MoE Inference via Predictive Prefetching and Expert ...

[논문 리뷰] Faster MoE LLM Inference for Extremely Large Models