
Moe Lightning High Throughput Moe Inference On Memory Constrained Gpus

[PDF] MoE-Lightning: High-Throughput MoE Inference on Memory ...

MoE-Lightning: High-Throughput MoE Inference on Memory-constrained GPUs

[PDF] MoE-Lightning: High-Throughput MoE Inference on Memory ...

MoE-Lightning: High-Throughput MoE Inference on Memory-constrained GPUs
MoE-Lightning: High-Throughput MoE Inference on Memory-constrained GPUs

[PDF] MoE-Lightning: High-Throughput MoE Inference on Memory ...

MoE-Lightning: High-Throughput MoE Inference on Memory-constrained GPUs
MoE-Lightning: High-Throughput MoE Inference on Memory-constrained GPUs ...

[PDF] MoE-Lightning: High-Throughput MoE Inference on Memory ...
MoE-Lightning: High-Throughput MoE Inference on Memory-constrained GPUs ...
Advertisement Space (300x250)

[PDF] MoE-Lightning: High-Throughput MoE Inference on Memory ...

大模型论文 | FloE:让MoE模型“瘦身“提速50倍!_floe: on-the-fly moe inference on memory ...

MoE-Lightning: High-Throughput MoE Inference on Memory-constrained GPUs
MoE-Lightning: High-Throughput MoE Inference on Memory-constrained GPUs ...

MoE-Lightning: High-Throughput MoE Inference on Memory-constrained GPUs ...

ICML Poster FloE: On-the-Fly MoE Inference on Memory-constrained GPU

Figure 1 from A Scheduling Framework for Efficient MoE Inference on ...

MoE-Gen: High-Throughput MoE Inference on a Single GPU with Module ...

Paper page - MoE-Gen: High-Throughput MoE Inference on a Single GPU ...

(PDF) MoE-Gen: High-Throughput MoE Inference on a Single GPU with ...
Advertisement Space (336x280)

MoE Inference On AnyScale - 知乎
MoE Model Inference on GPU Cloud: Expert Parallelism, Memory, and Cost ...

[논문 리뷰] A Scheduling Framework for Efficient MoE Inference on Edge GPU ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

Diff-MoE: Efficient Batched MoE Inference with Priority-Driven ...
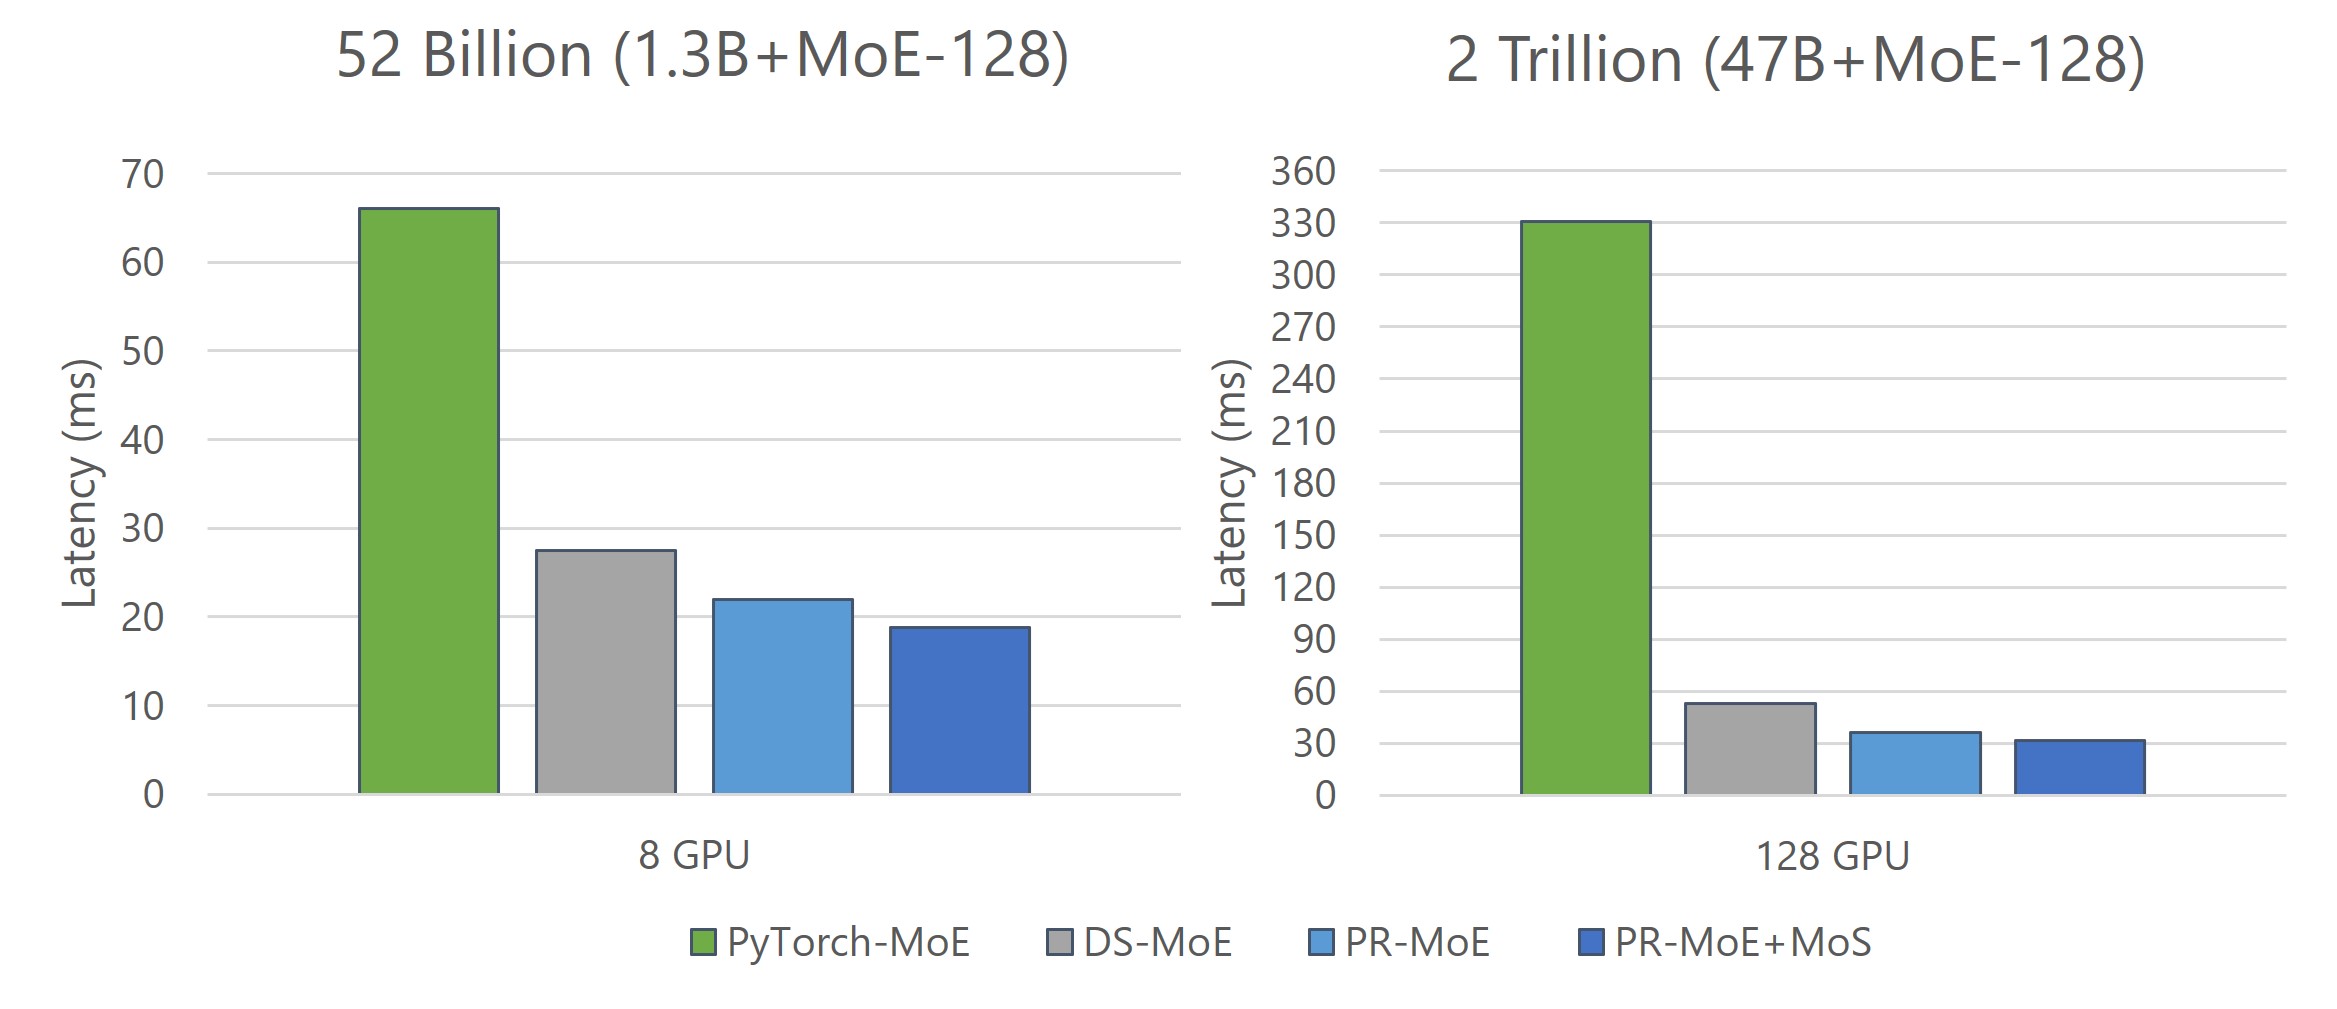
DeepSpeed: Advancing MoE inference and training to power next ...

Diff-MoE: Efficient Batched MoE Inference with Priority-Driven ...

Diff-MoE: Efficient Batched MoE Inference with Priority-Driven ...

CoX-MoE: Coalesced Expert Execution for High-Throughput MoE Inference ...

Diff-MoE: Efficient Batched MoE Inference with Priority-Driven ...
Advertisement Space (336x280)

[논문 리뷰] Accelerating MoE with Dynamic In-Switch Computing on Multi-GPUs
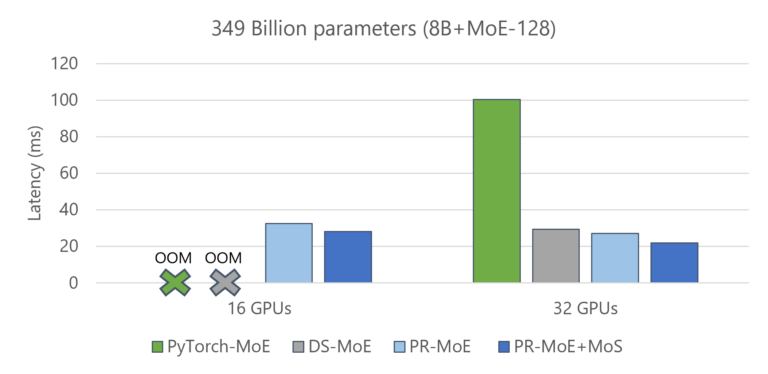
DeepSpeed: Advancing MoE inference and training to power next ...

HarMoEny: Efficient Multi-GPU Inference of MoE Models | AI Research ...

CoX-MoE: Coalesced Expert Execution for High-Throughput MoE Inference ...

Diff-MoE: Efficient Batched MoE Inference with Priority-Driven ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...