
Moe Gen High Throughput Moe Inference On A Single Gpu With Module

MoE-Gen: High-Throughput MoE Inference on a Single GPU with Module ...

(PDF) MoE-Gen: High-Throughput MoE Inference on a Single GPU with ...

Paper page - MoE-Gen: High-Throughput MoE Inference on a Single GPU ...

[论文评述] A Scheduling Framework for Efficient MoE Inference on Edge GPU ...

Figure 1 from A Scheduling Framework for Efficient MoE Inference on ...
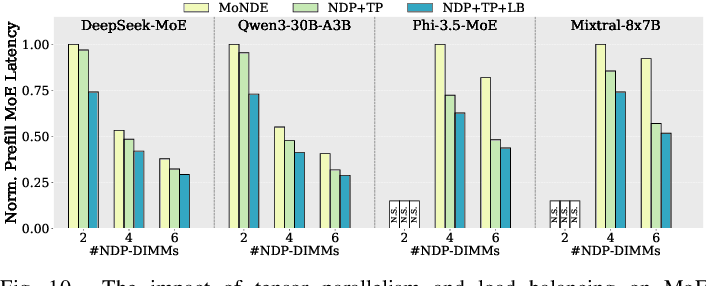
Figure 10 from A Scheduling Framework for Efficient MoE Inference on ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

[PDF] MoE-Lightning: High-Throughput MoE Inference on Memory ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

MoE-Lightning: High-Throughput MoE Inference on Memory-constrained GPUs
Advertisement Space (300x250)

[PDF] MoE-Lightning: High-Throughput MoE Inference on Memory ...
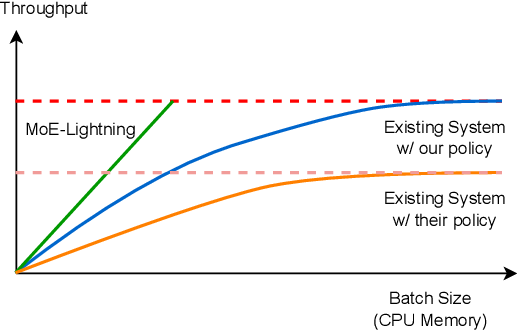
Figure 1 from MoE-Lightning: High-Throughput MoE Inference on Memory ...

[PDF] MoE-Lightning: High-Throughput MoE Inference on Memory ...

Diff-MoE: Efficient Batched MoE Inference with Priority-Driven ...

[PDF] MoE-Lightning: High-Throughput MoE Inference on Memory ...

[PDF] MoE-Lightning: High-Throughput MoE Inference on Memory ...
MoE-Lightning: High-Throughput MoE Inference on Memory-constrained GPUs ...
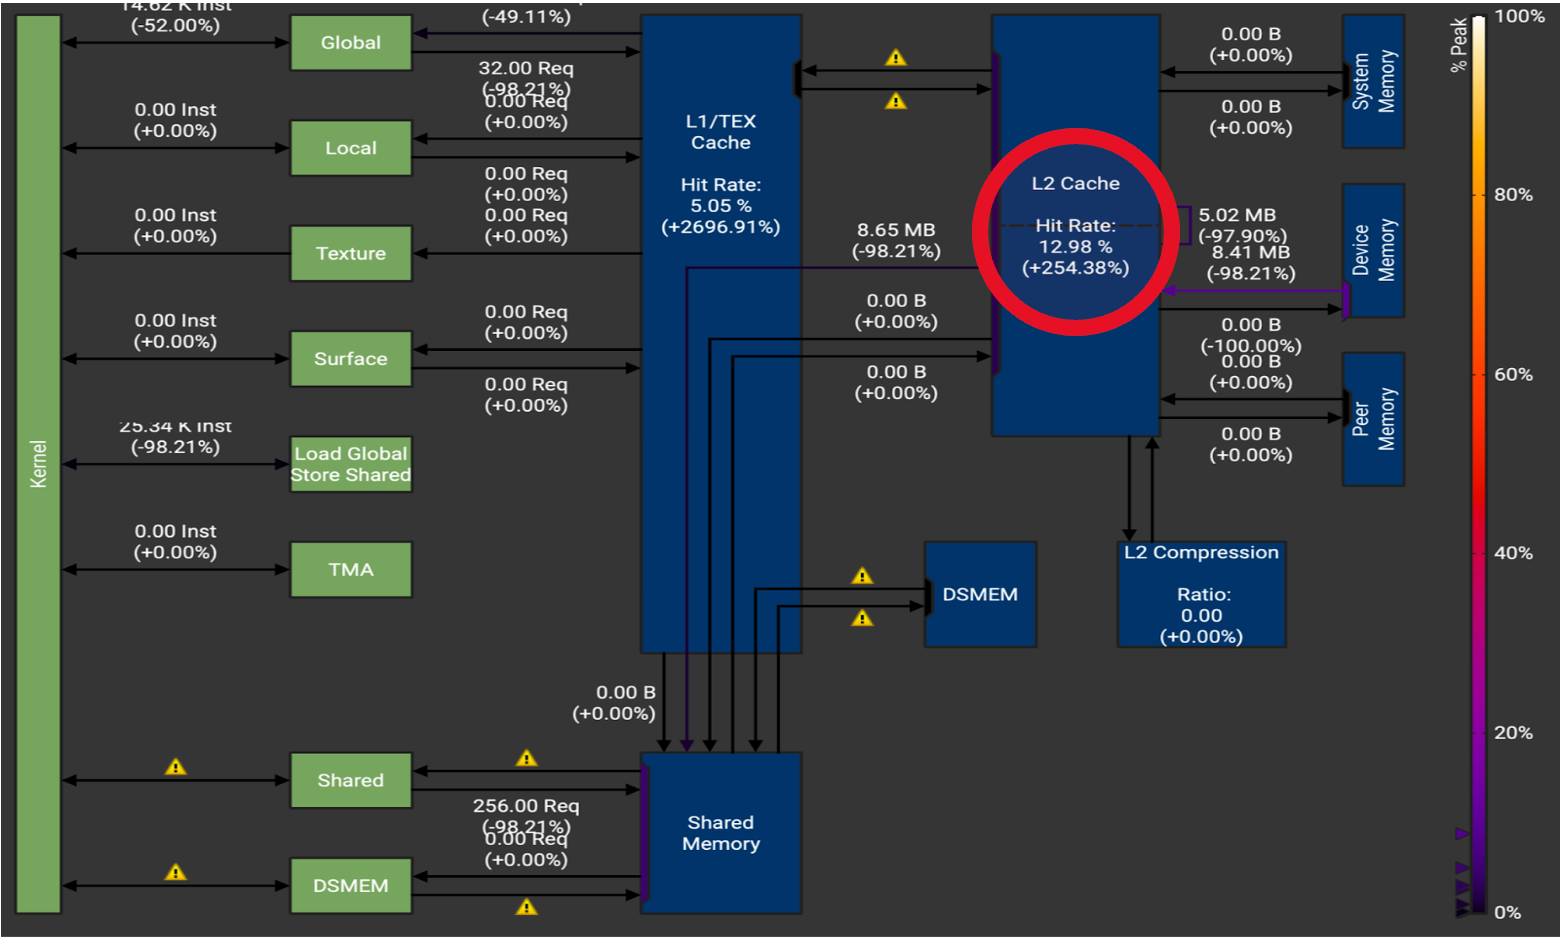
Accelerating MoE model inference with Locality-Aware Kernel Design ...

Diff-MoE: Efficient Batched MoE Inference with Priority-Driven ...
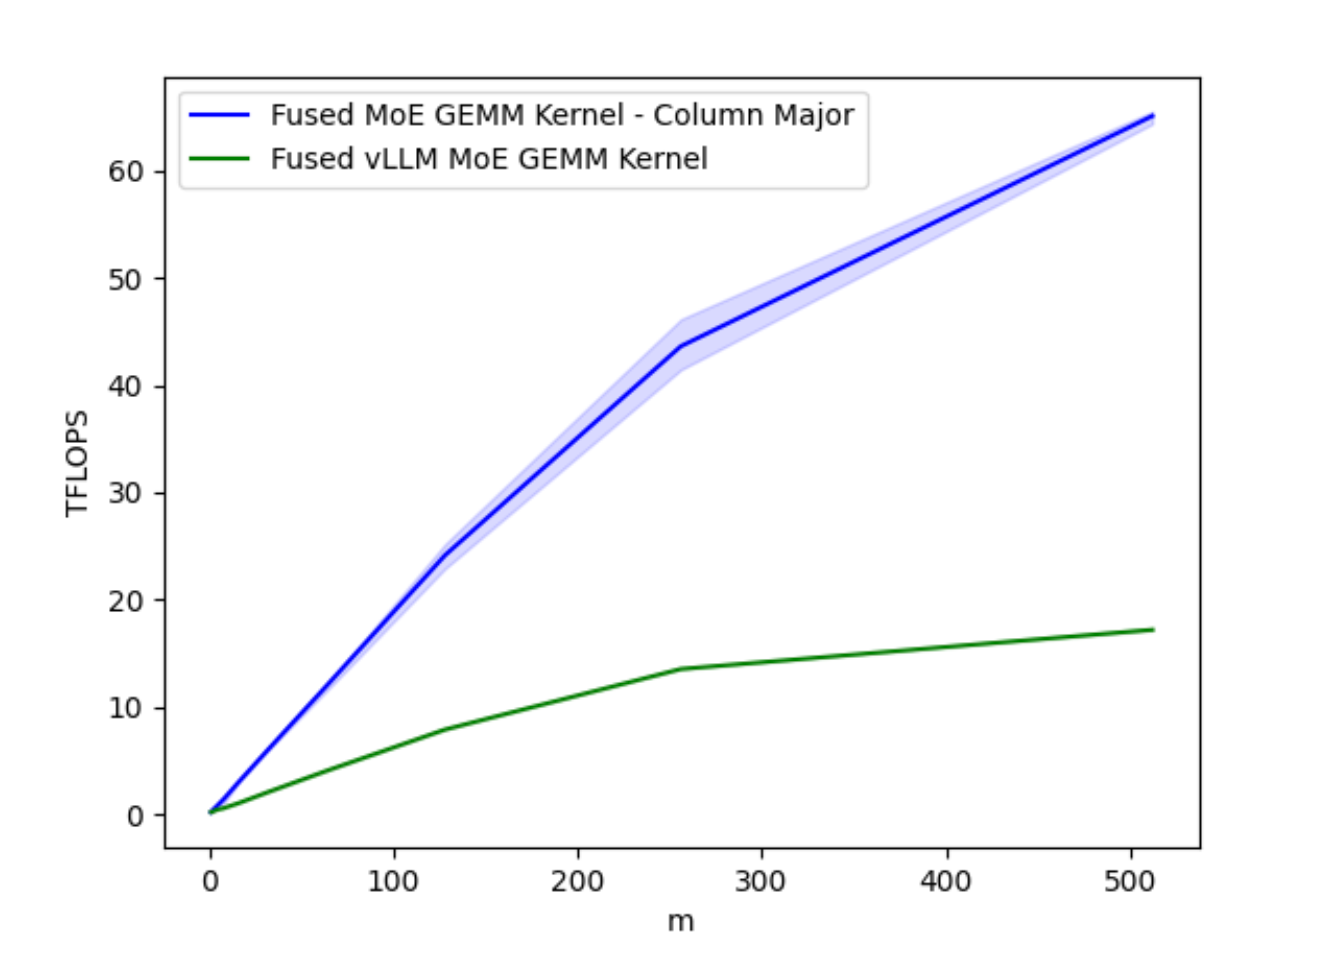
Accelerating MoE model inference with Locality-Aware Kernel Design ...
Advertisement Space (336x280)

MoE-Lightning: High-Throughput MoE Inference on Memory-constrained GPUs

MoE Inference On AnyScale - 知乎

MoE-Lightning: High-Throughput MoE Inference on Memory-constrained GPUs

Diff-MoE: Efficient Batched MoE Inference with Priority-Driven ...

MoE Inference for Mortals: Routing, Tokens, and GPU Utilization | by ...

Diff-MoE: Efficient Batched MoE Inference with Priority-Driven ...

[논문 리뷰] MiLo: Efficient Quantized MoE Inference with Mixture of Low ...

Diff-MoE: Efficient Batched MoE Inference with Priority-Driven ...
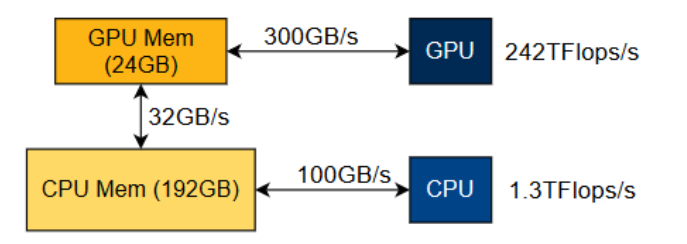
MoE-Lightning: High-Throughput MoE Inference on Memory-constrained GPUs

DeepSpeed: Advancing MoE inference and training to power next ...
Advertisement Space (336x280)

TriMoE: Augmenting GPU with AMX-Enabled CPU and DIMM-NDP for High ...

HarMoEny: Efficient Multi-GPU Inference of MoE Models | AI Research ...

CoX-MoE: Coalesced Expert Execution for High-Throughput MoE Inference ...
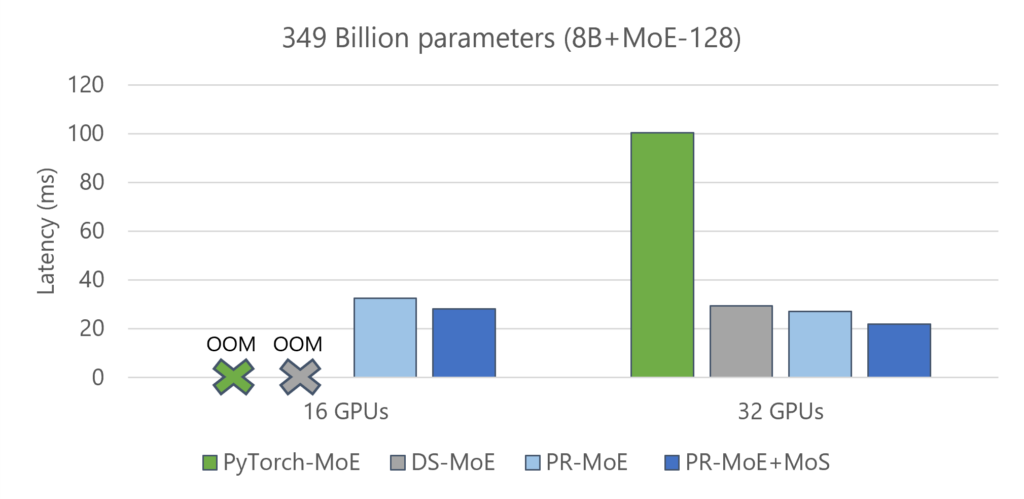
DeepSpeed: Advancing MoE inference and training to power next ...
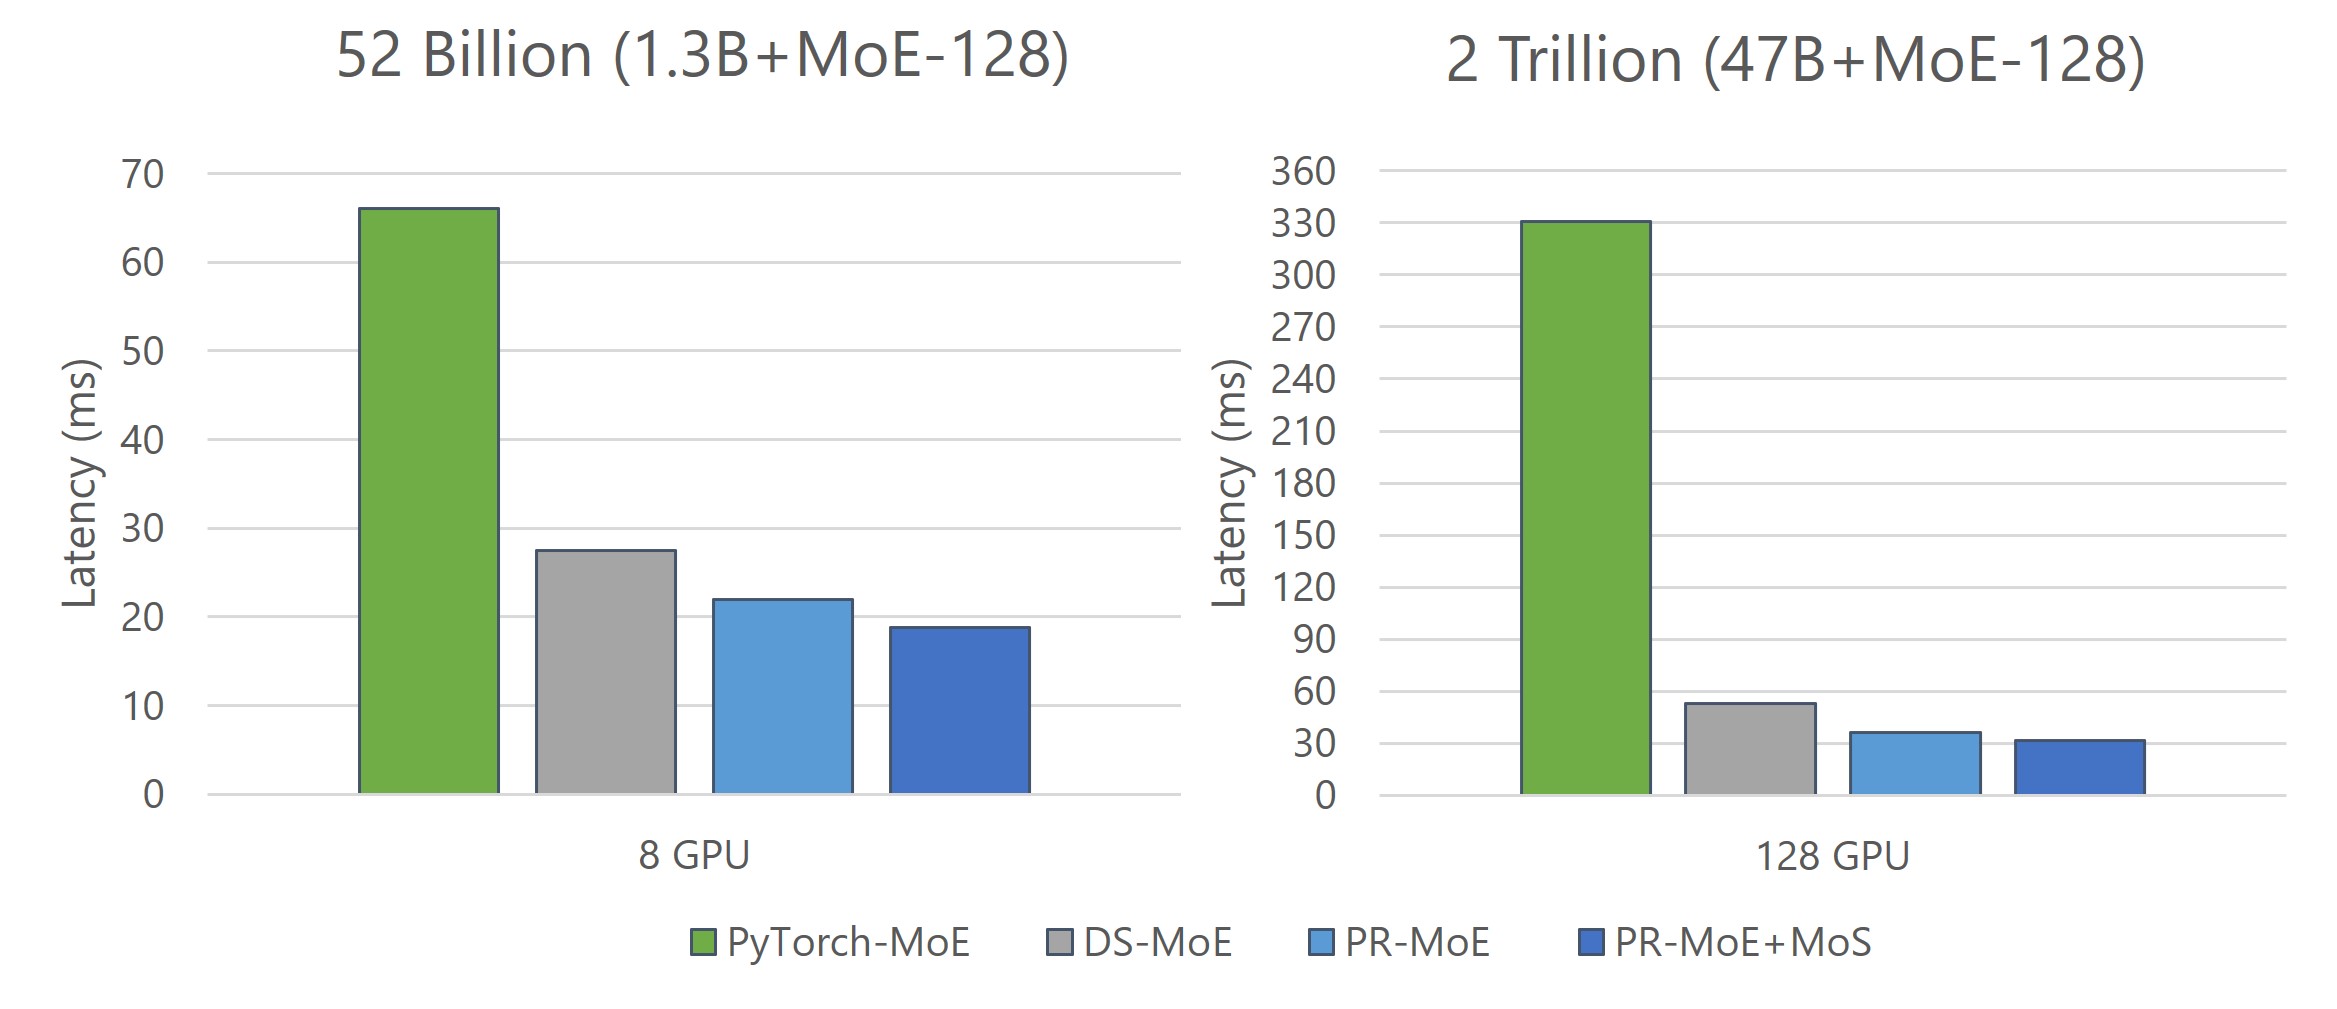
DeepSpeed: Advancing MoE inference and training to power next ...

CoX-MoE: Coalesced Expert Execution for High-Throughput MoE Inference ...