
From Kv Caching To Pagedattention A Deep Dive Into Gpu Memory In Llm

From KV Caching to PagedAttention: A Deep Dive into GPU Memory in LLM ...

KV Cache Optimization: A Deep Dive into PagedAttention & FlashAttention ...

A Deep Dive into vLLM and PagedAttention | by Paras Jain | Apr, 2026 ...

LLM Inference Bottleneck: KV Cache vs GPU Memory | Osama Altaf posted ...

KV Cache Compression Revolution: Deep Dive into NVIDIA's 20x ...
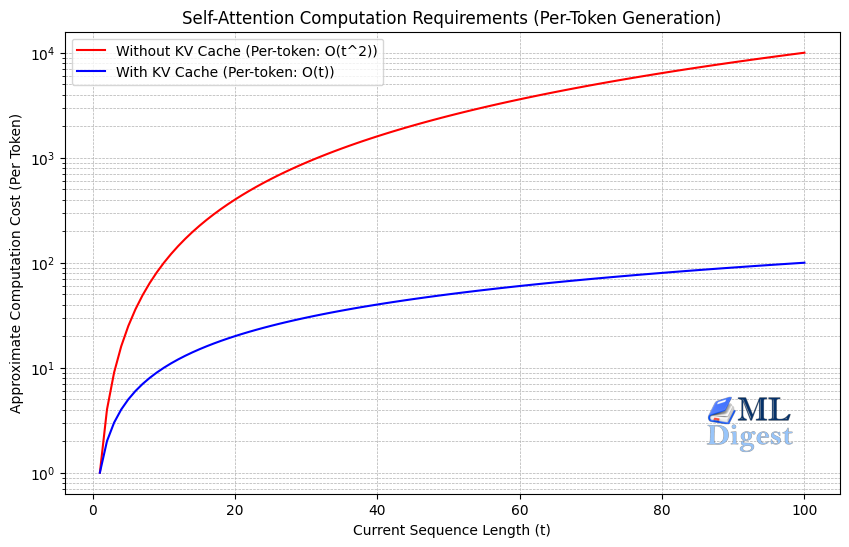
KV Caching Made Simple: The Key To Efficient LLM Inference - ML Digest
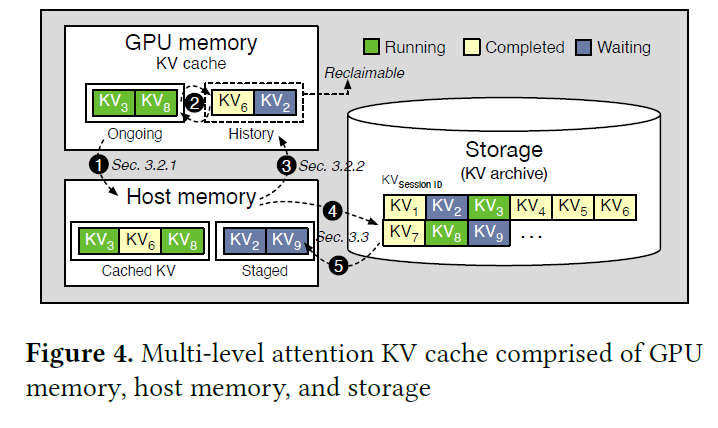
How KV Cache Works & Why It Eats Memory | by M | Foundation Models Deep ...
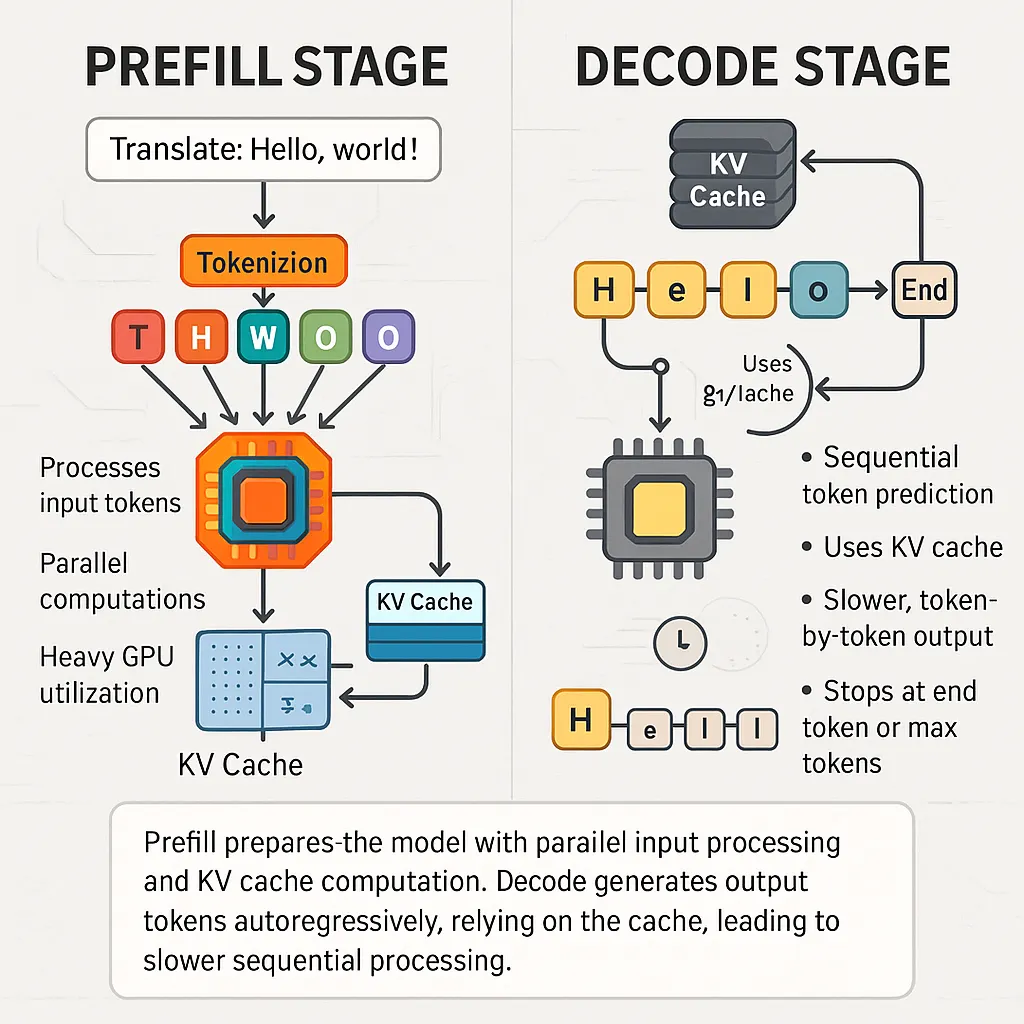
How KV Cache Works & Why It Eats Memory | by M | Foundation Models Deep ...

LMCache: Accelerating LLM Inference with Smart KV Caching (Part 1 of 2 ...
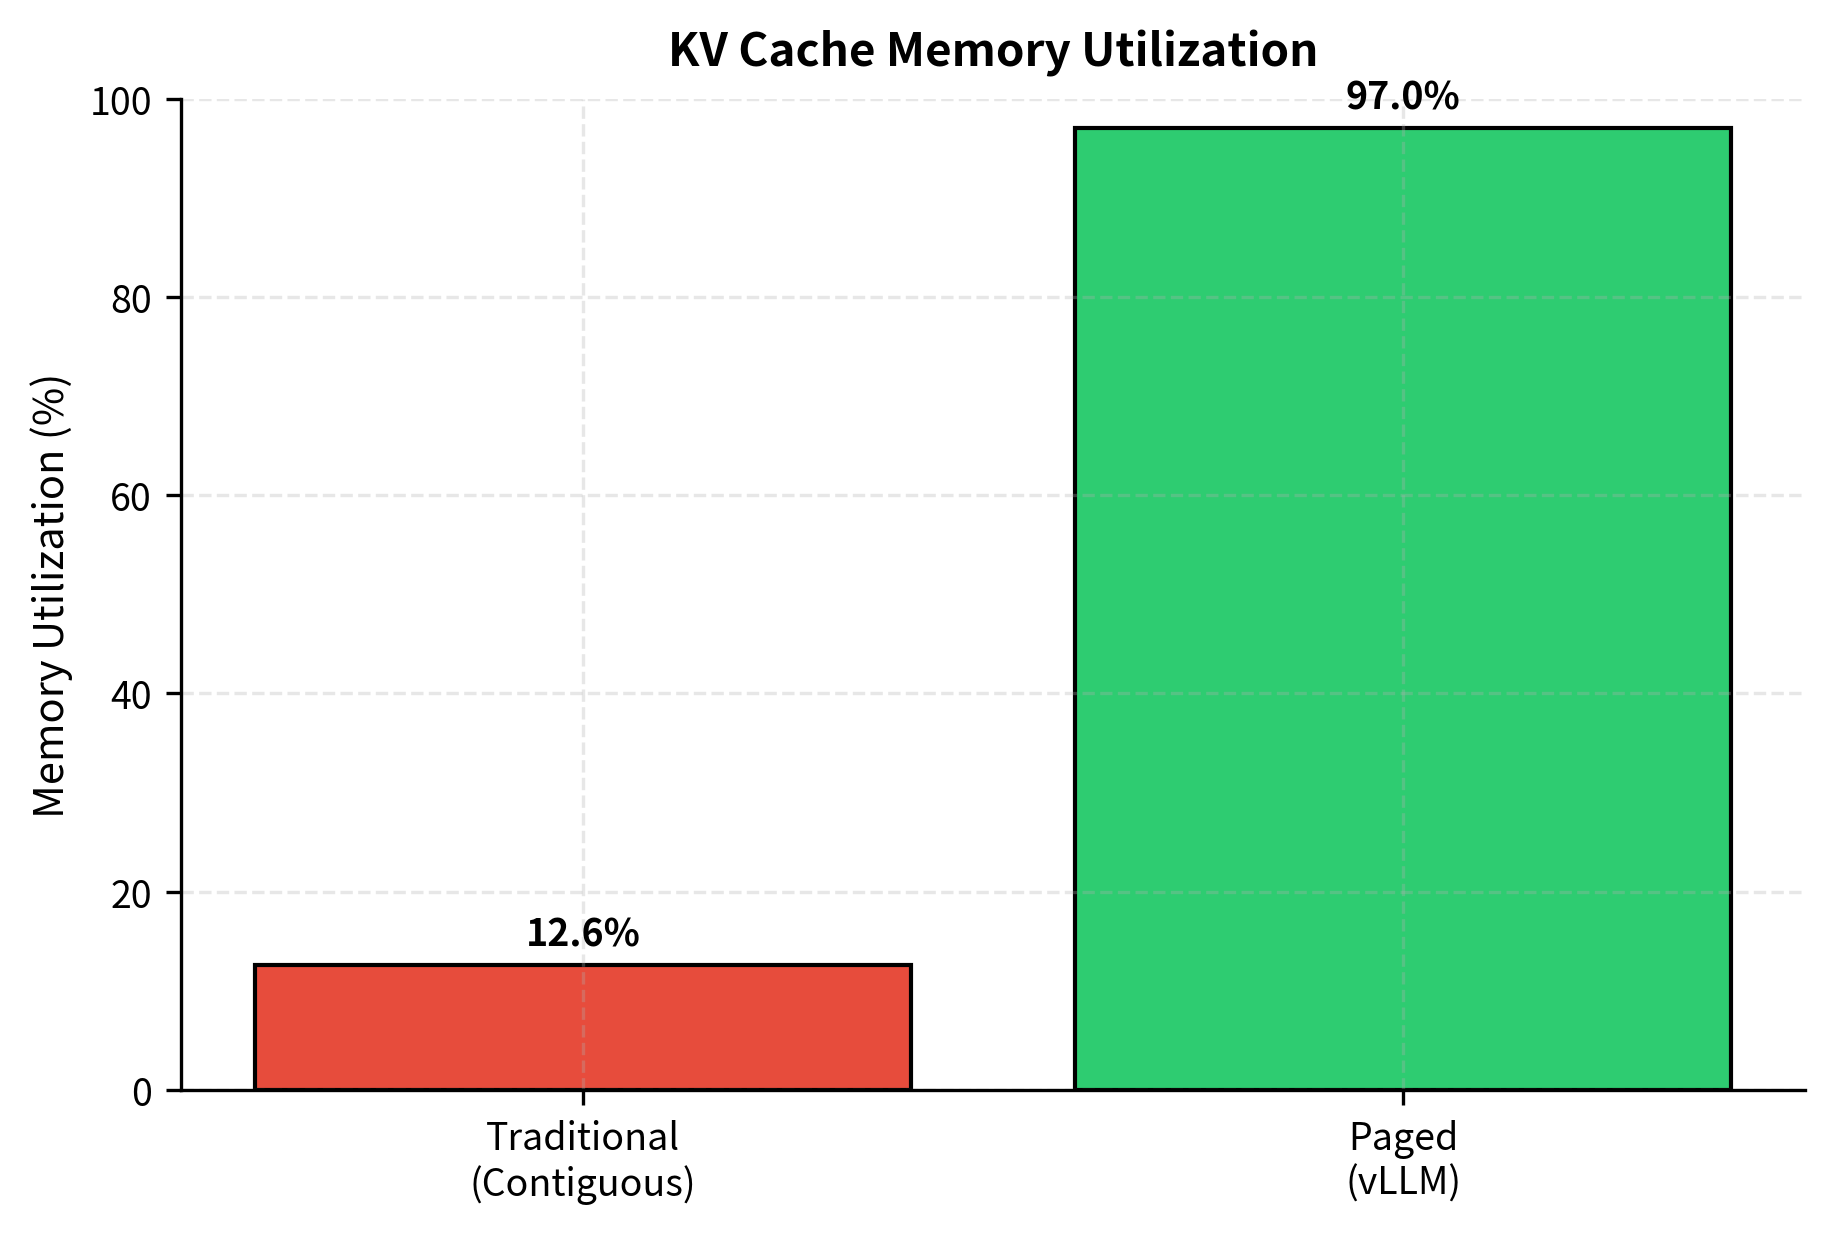
PagedAttention: Solving LLM KV Cache Memory Fragmentation - Interactive ...
Advertisement Space (300x250)
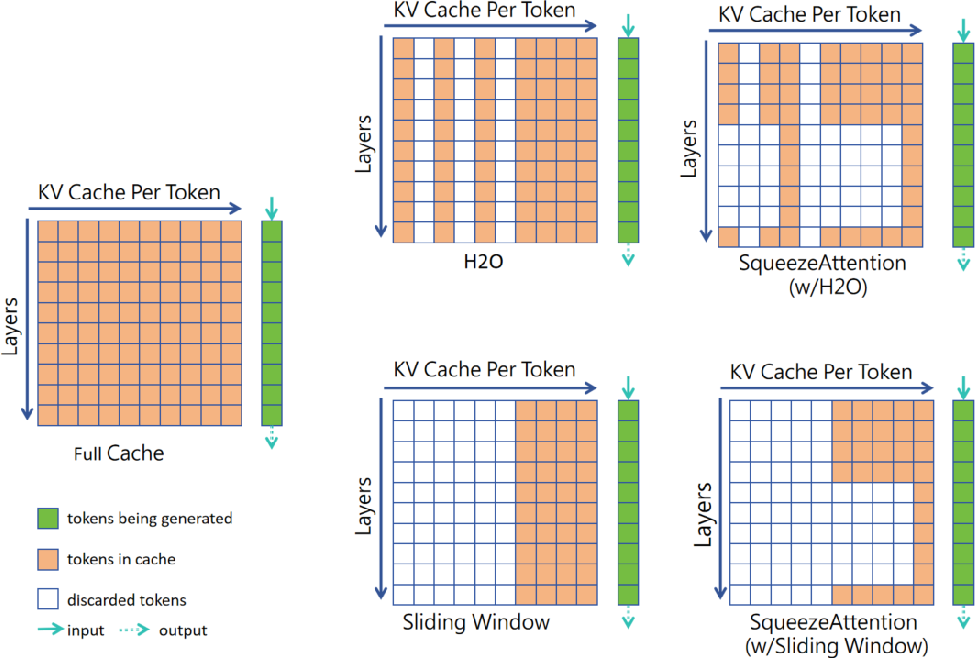
Figure 1 from SqueezeAttention: 2D Management of KV-Cache in LLM ...
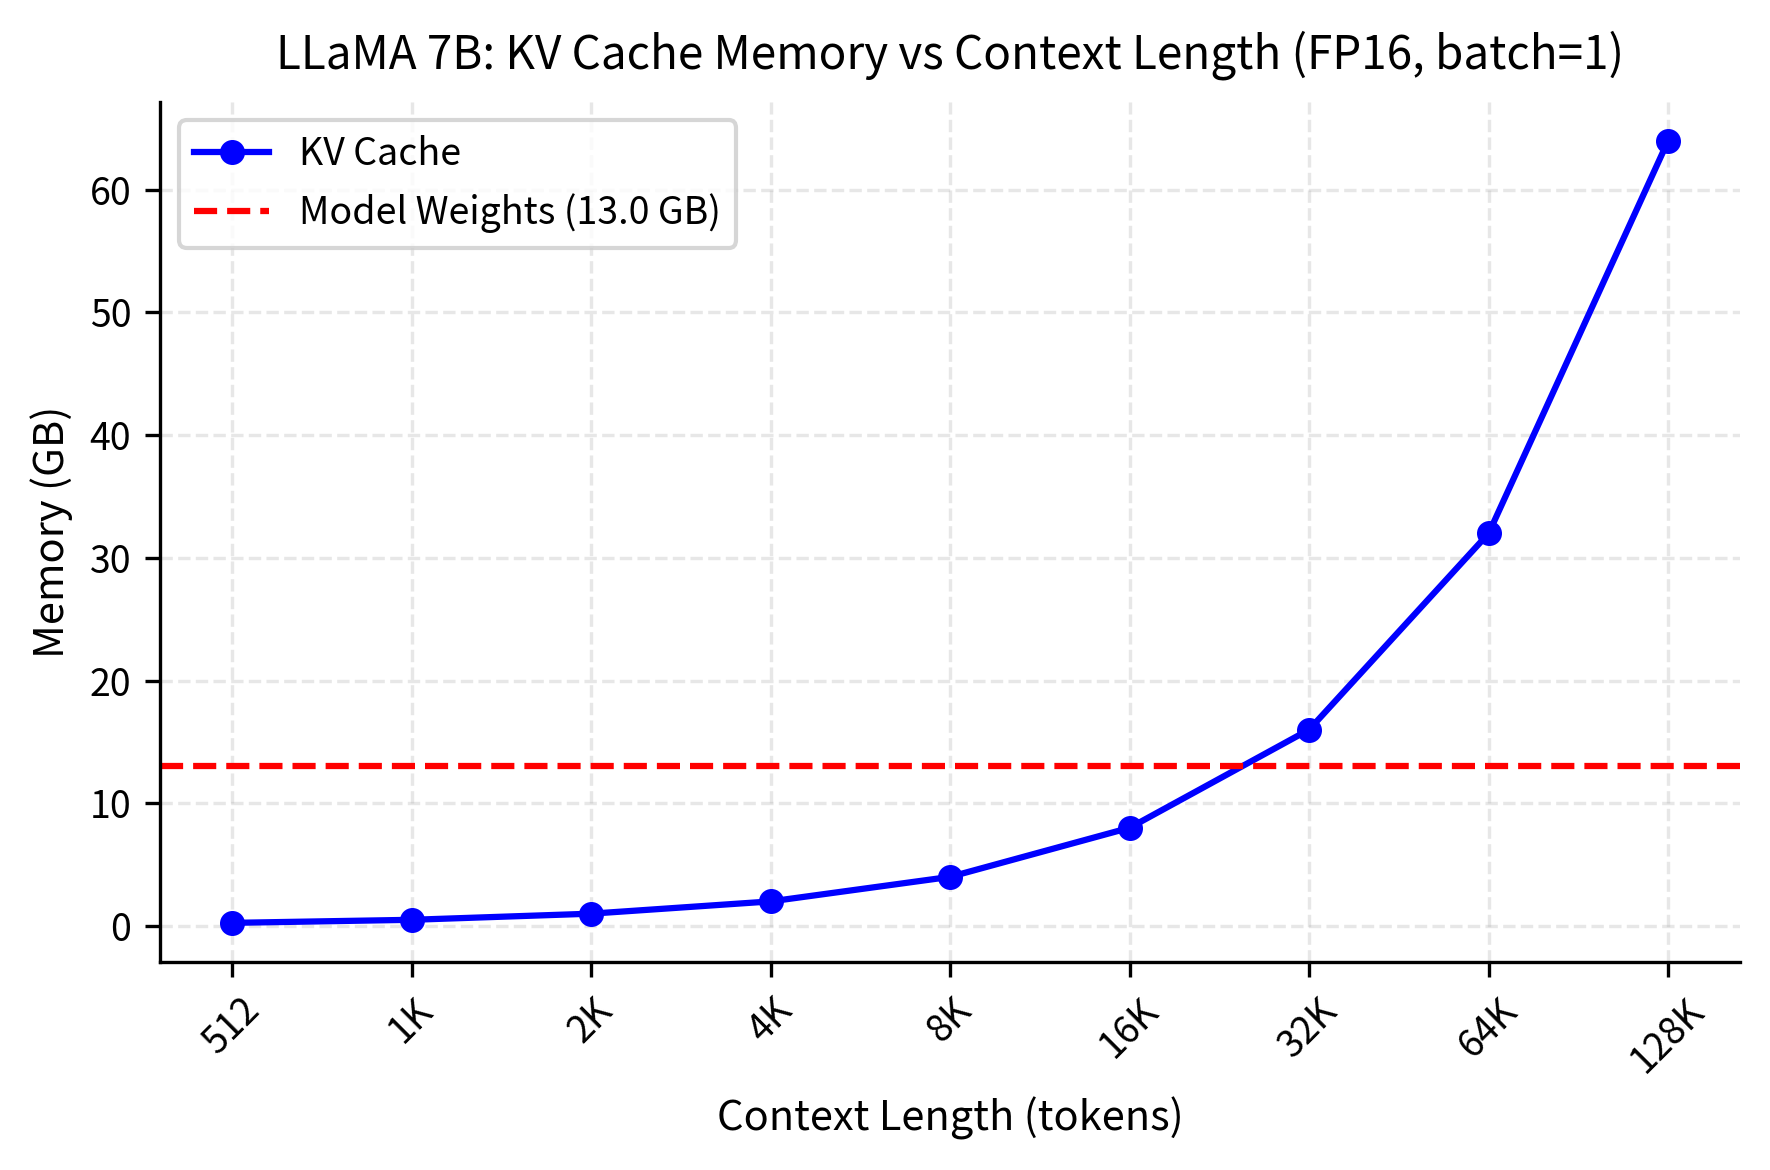
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...
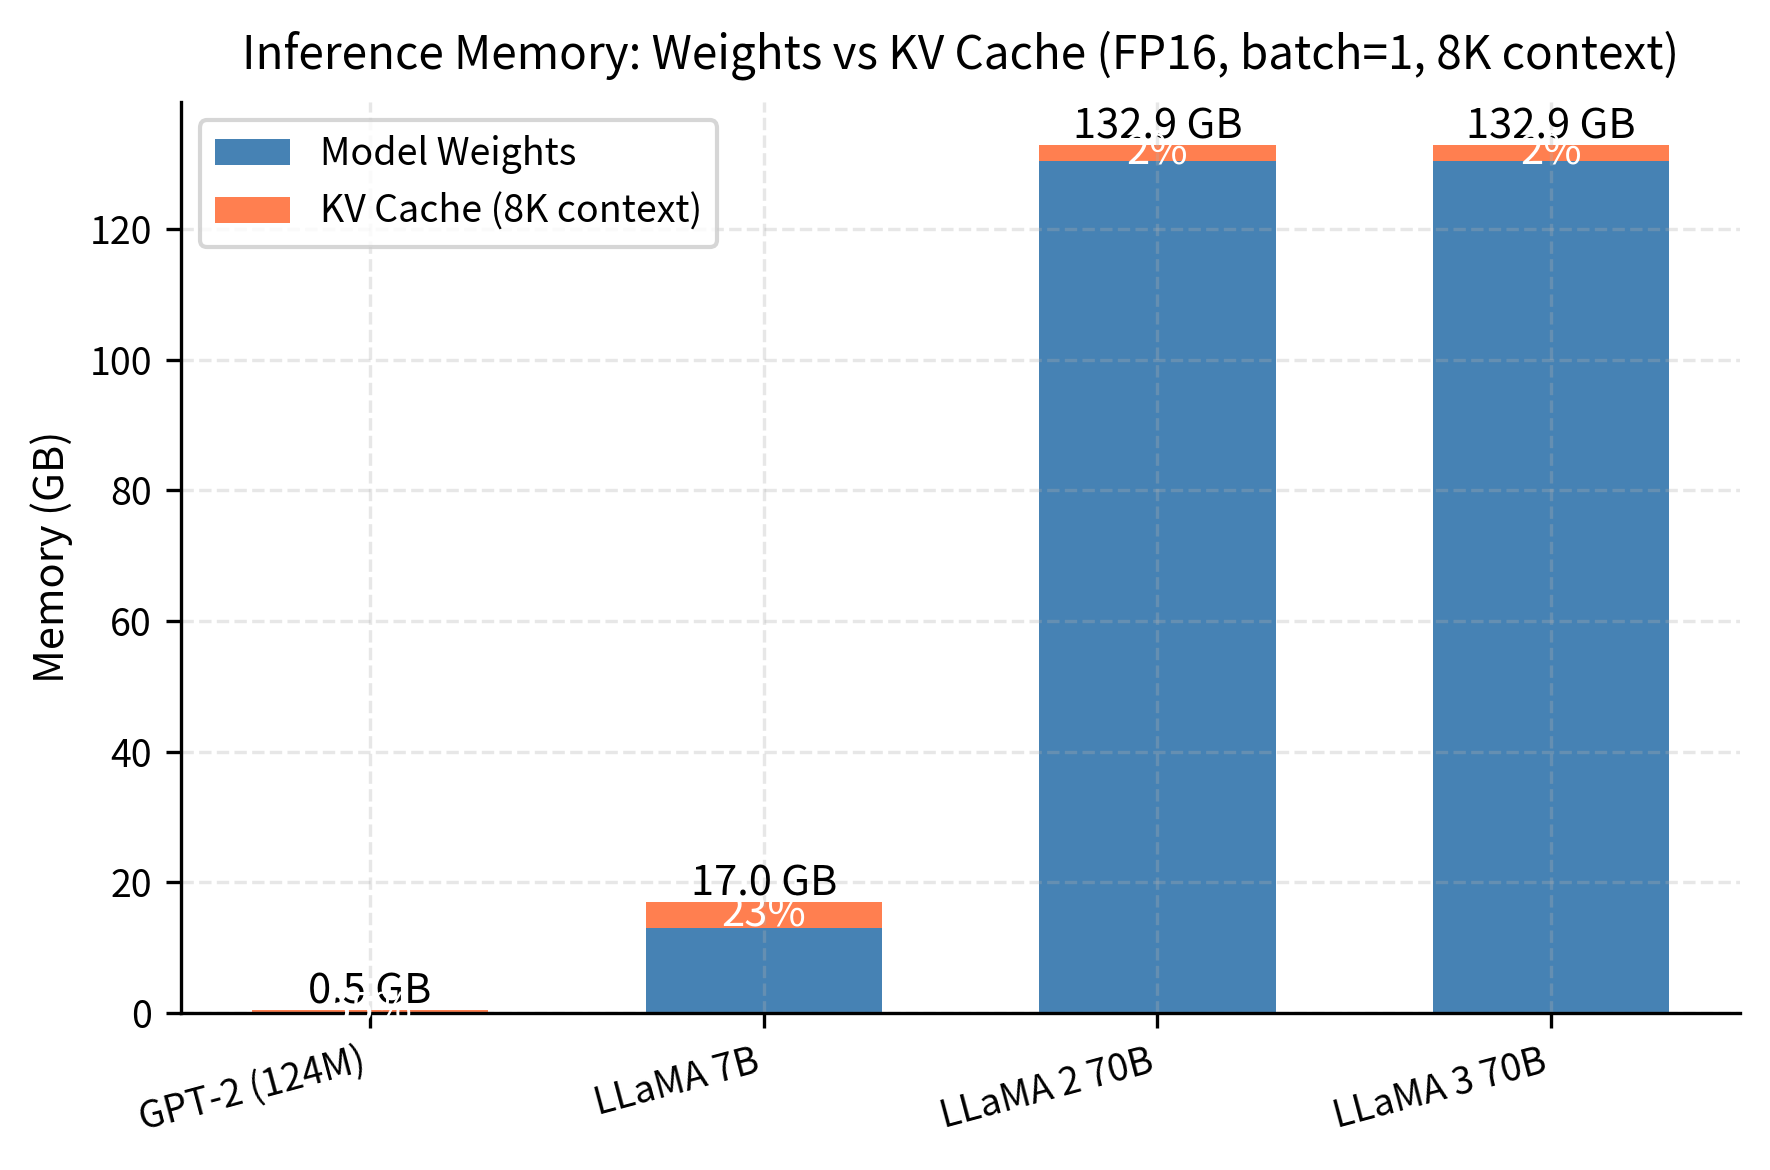
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...
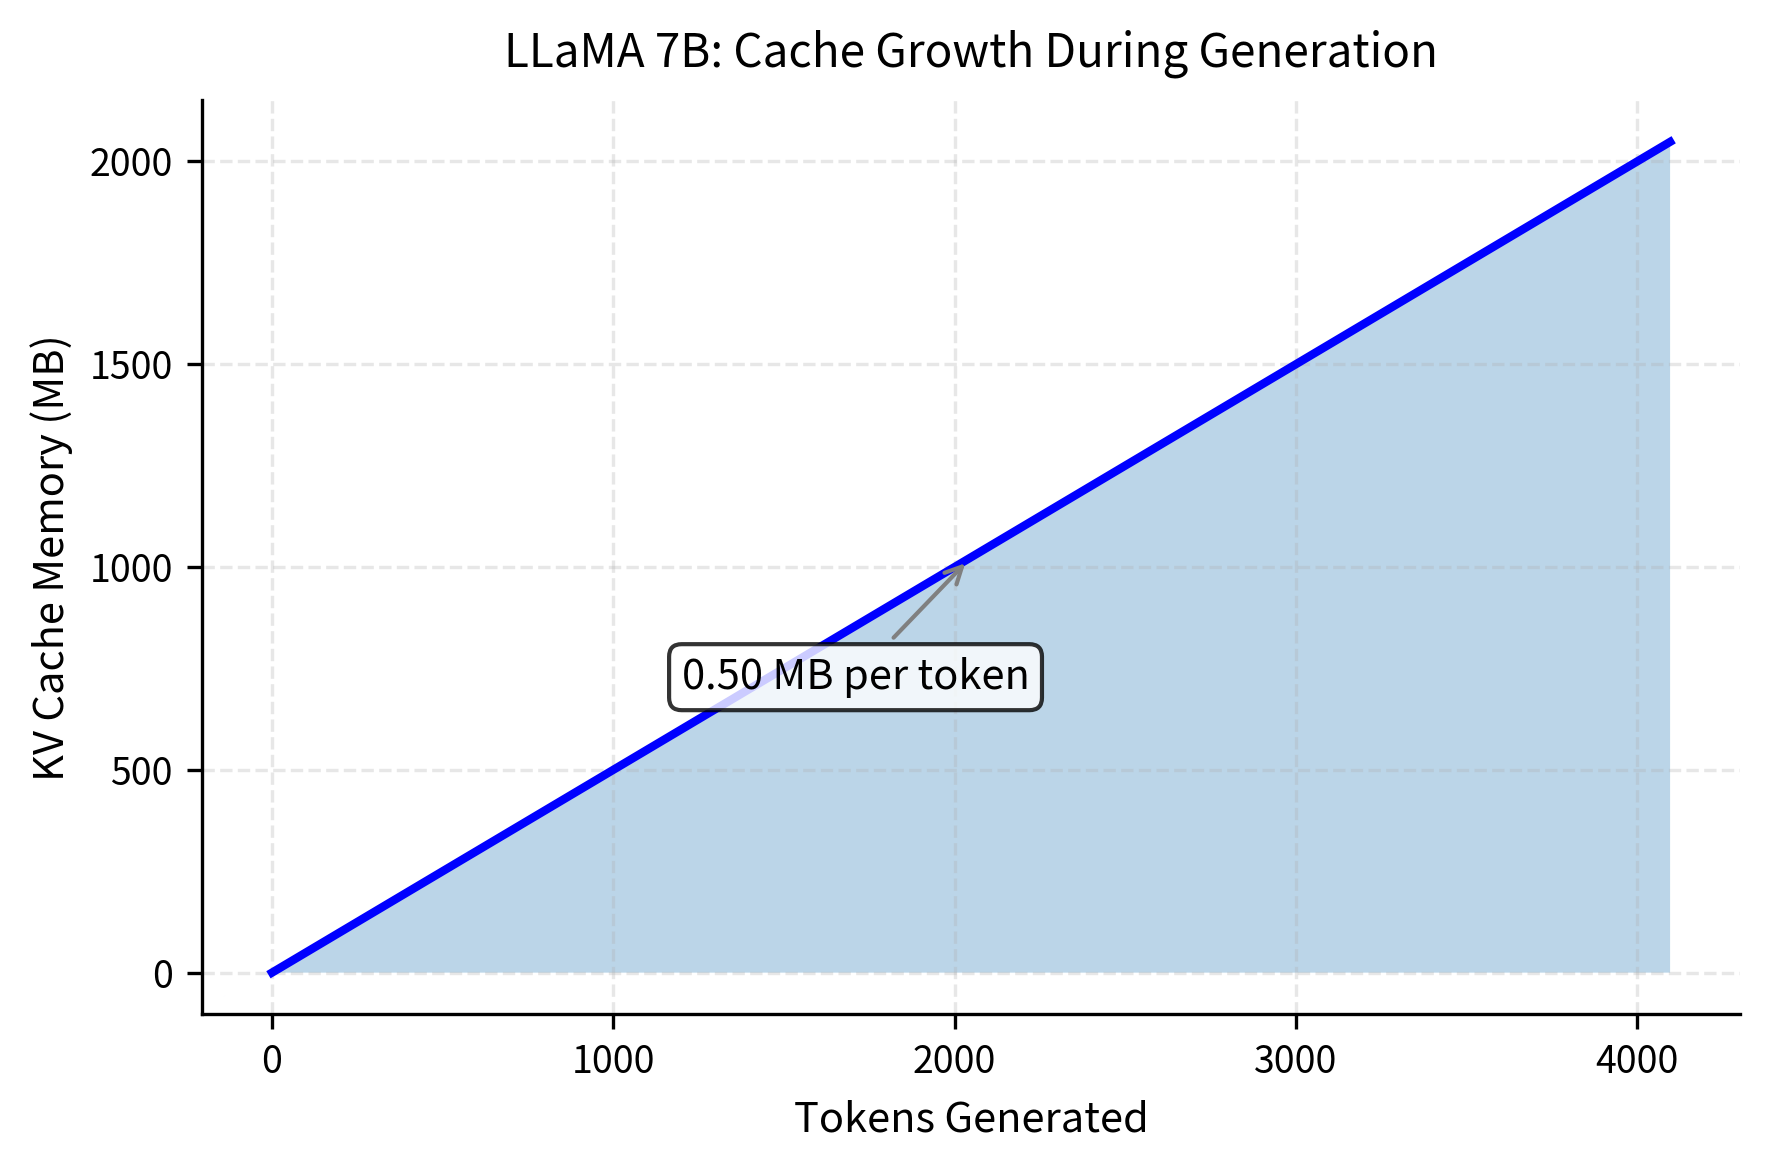
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...
PagedAttention — Virtual Memory for KV Caches | tutorialQ
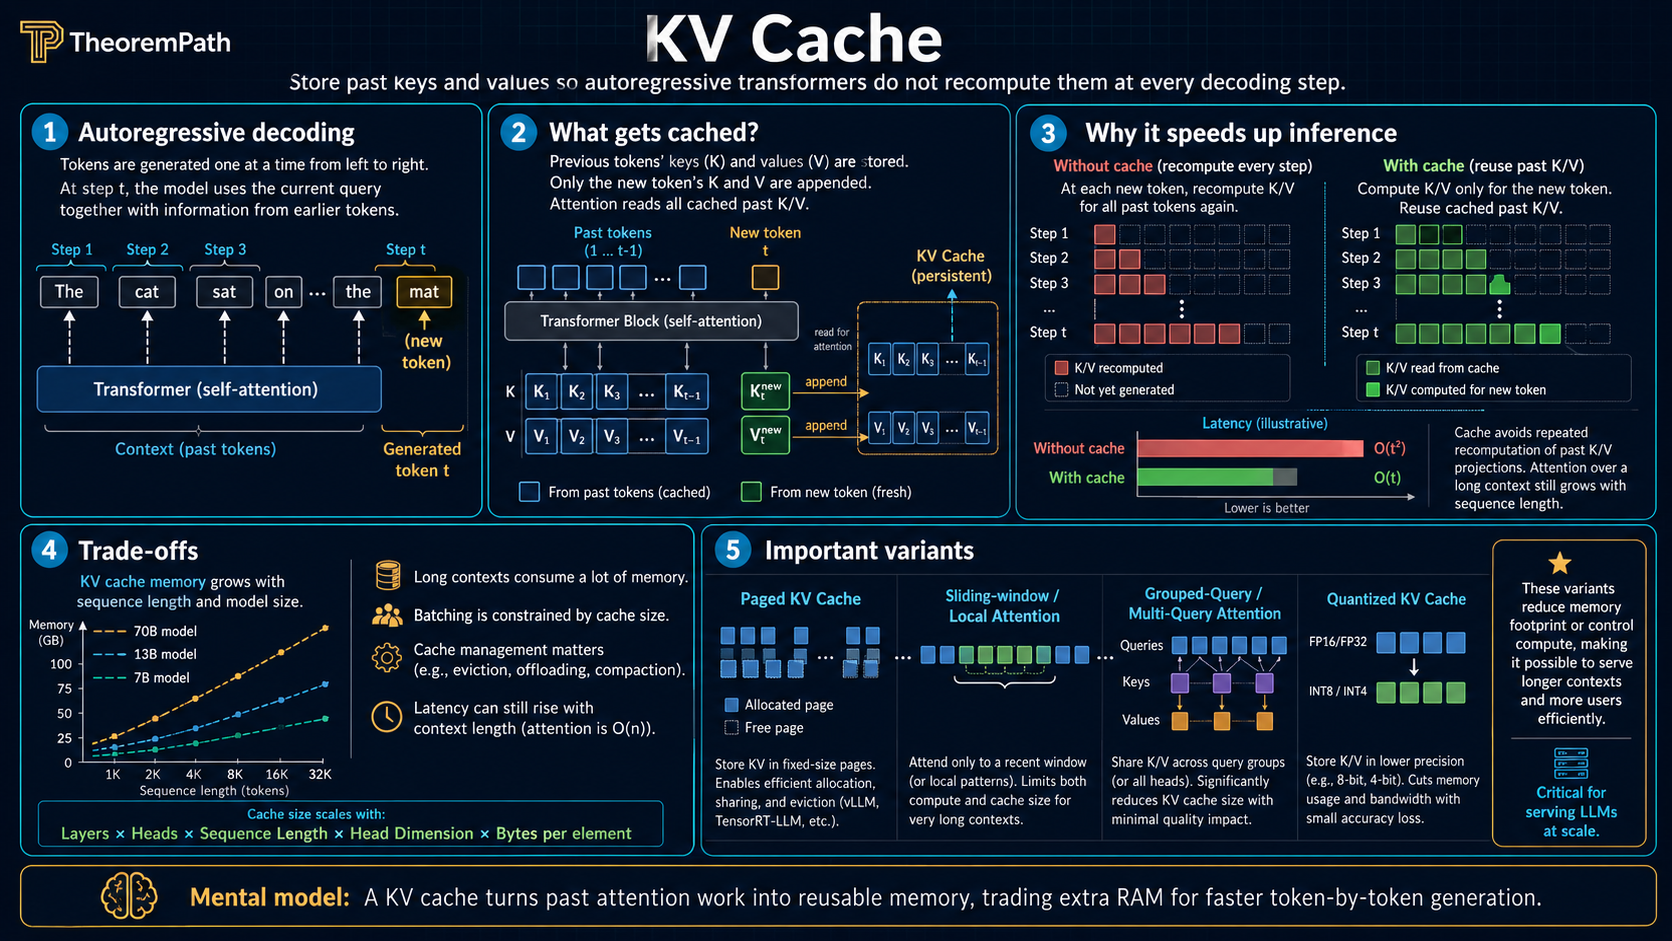
KV Cache. Inference Memory Bottleneck. LLM Construction | TheoremPath
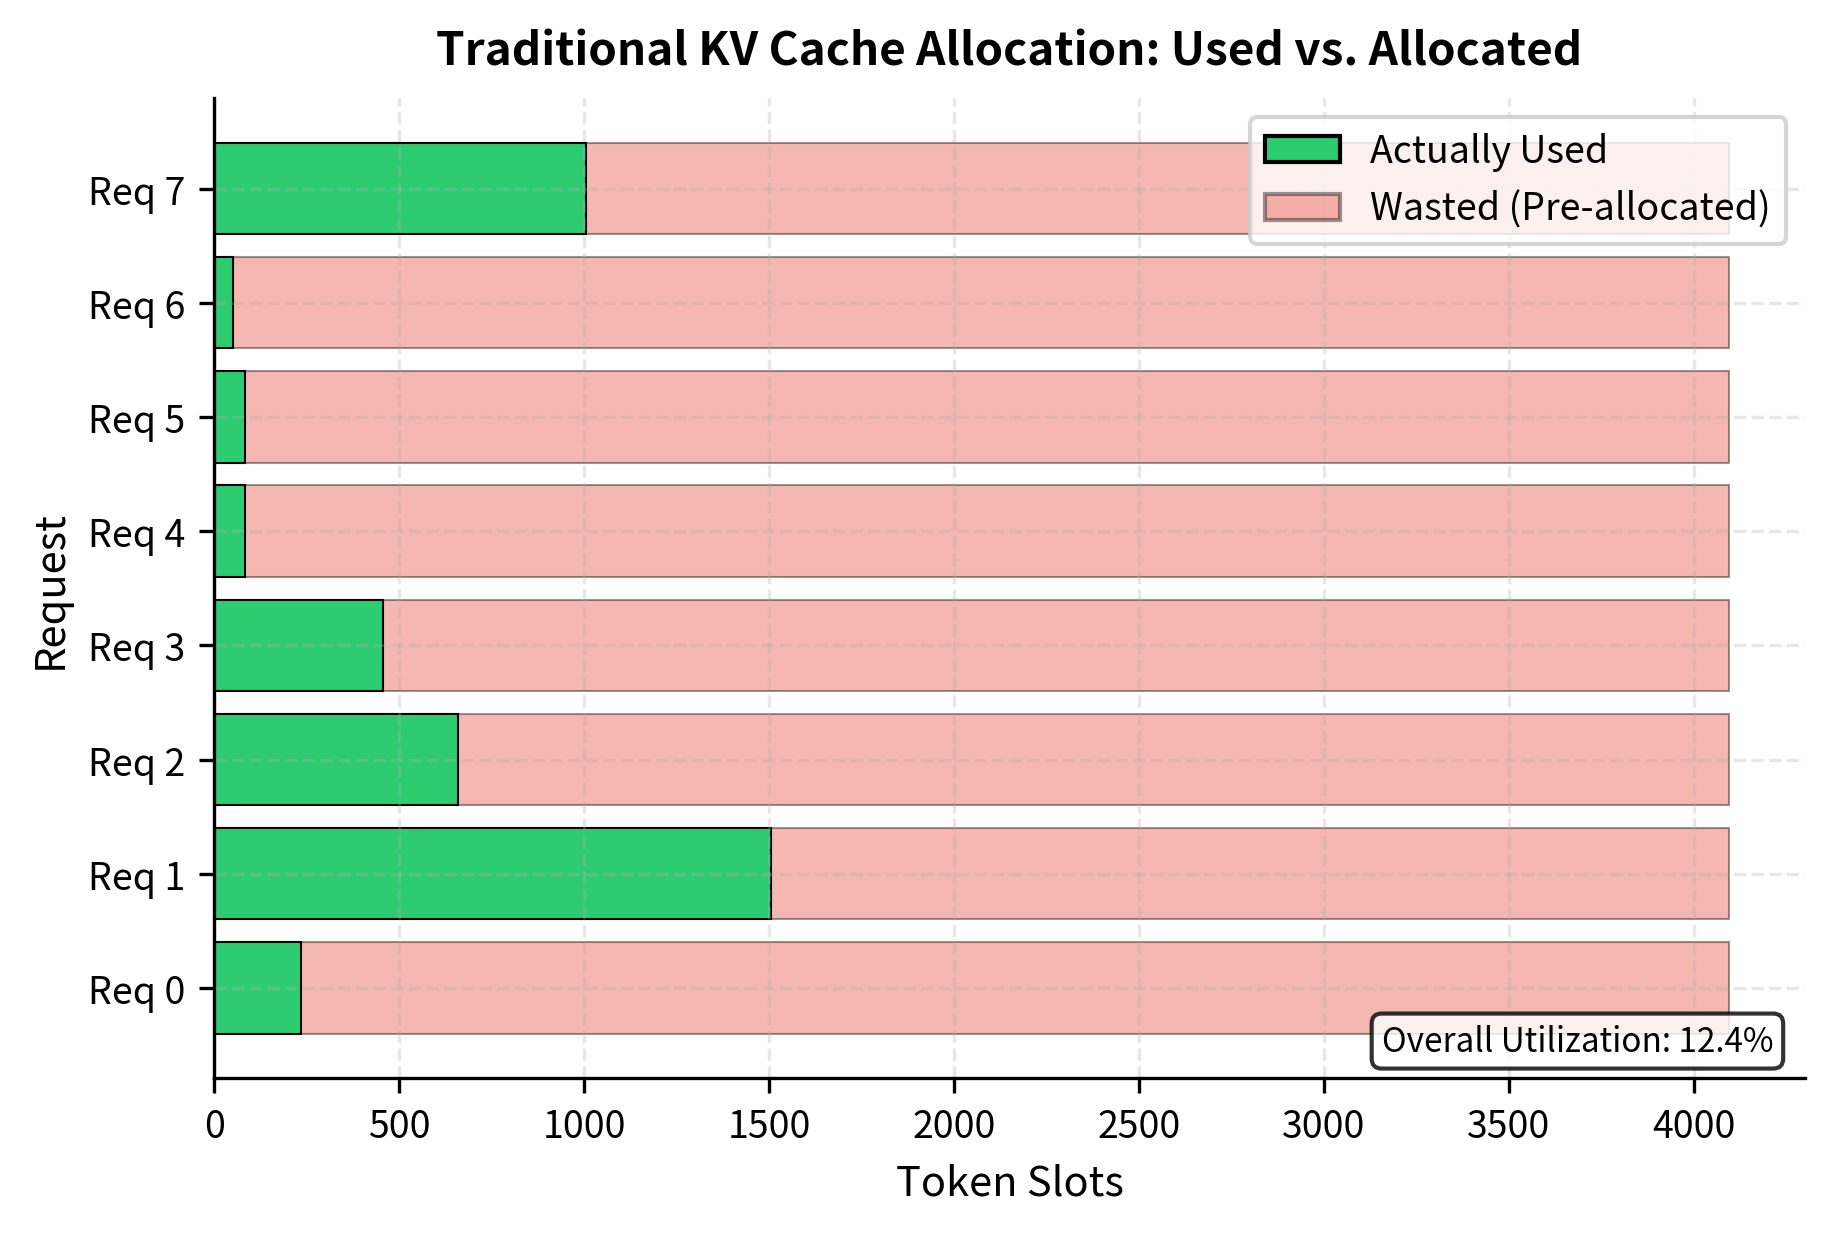
PagedAttention: Solving LLM KV Cache Memory Fragmentation - Interactive ...

Entropy-Guided KV Caching for Efficient LLM Inference
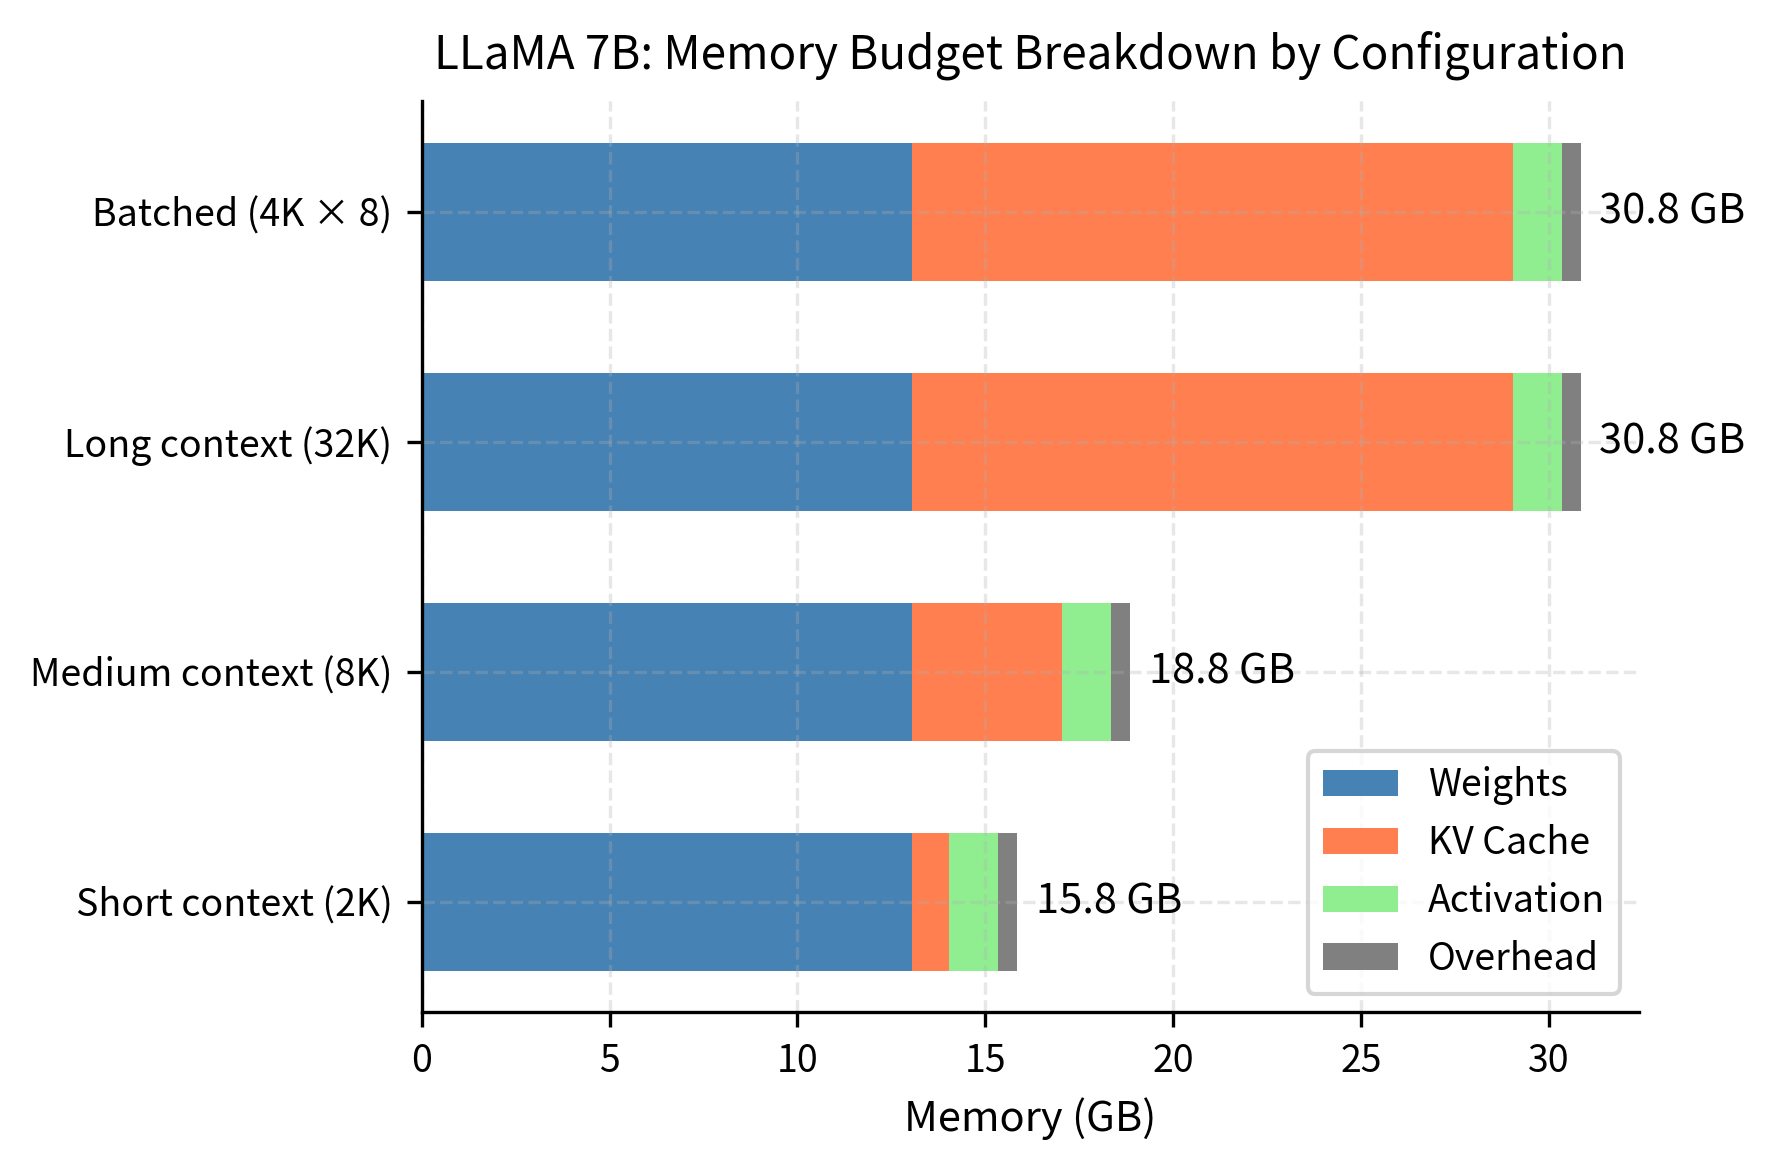
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...

KV Caching and LLM Optimization Techniques | by Ayushi Gupta | Medium
Advertisement Space (336x280)

LMCache: Accelerating LLM Inference with Smart KV Caching (Part 1 of 2 ...
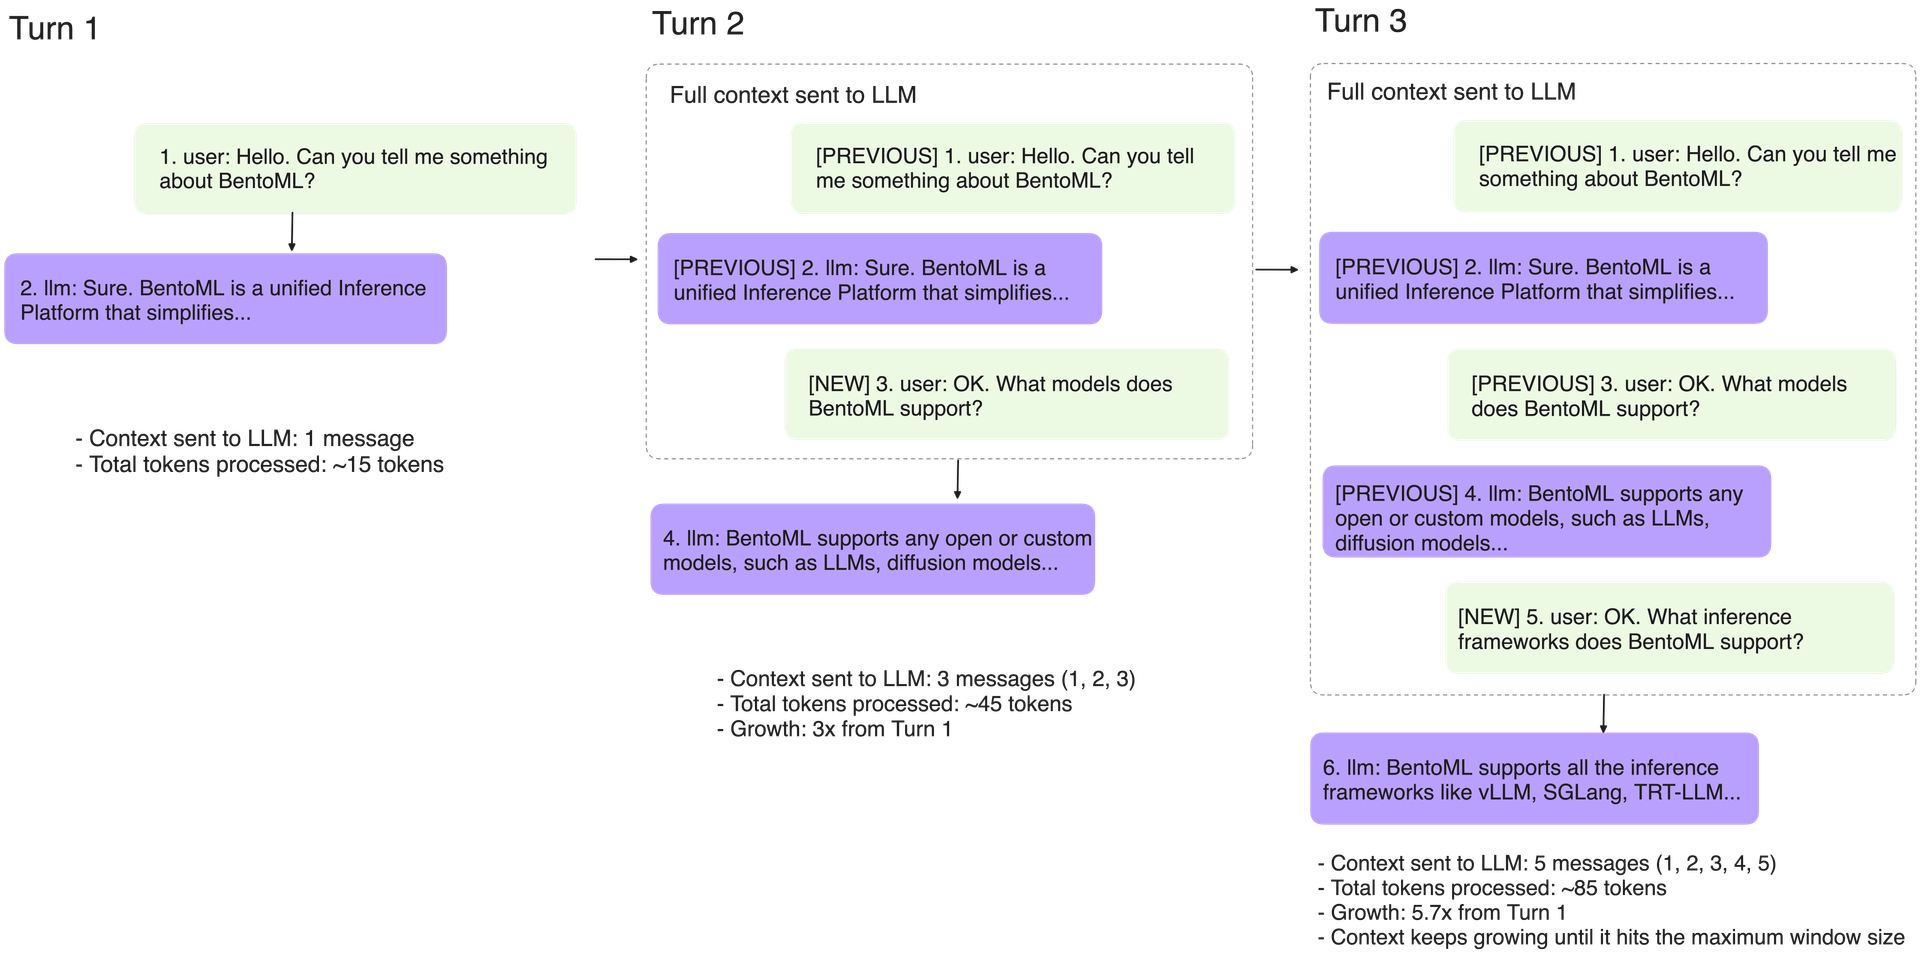
What is GPU Memory and Why it Matters for LLM Inference
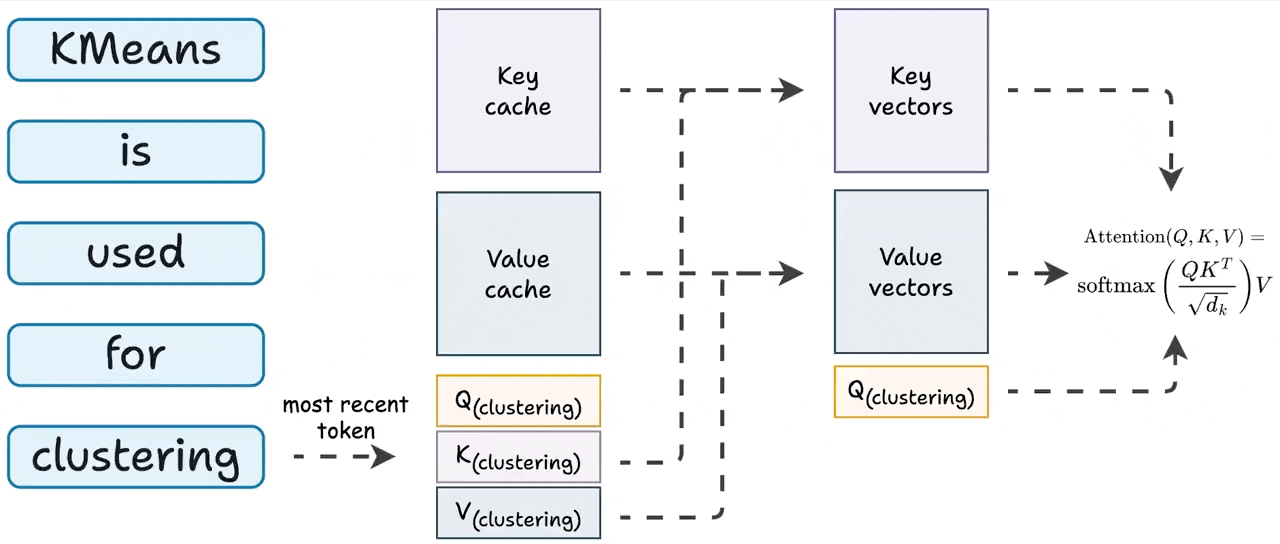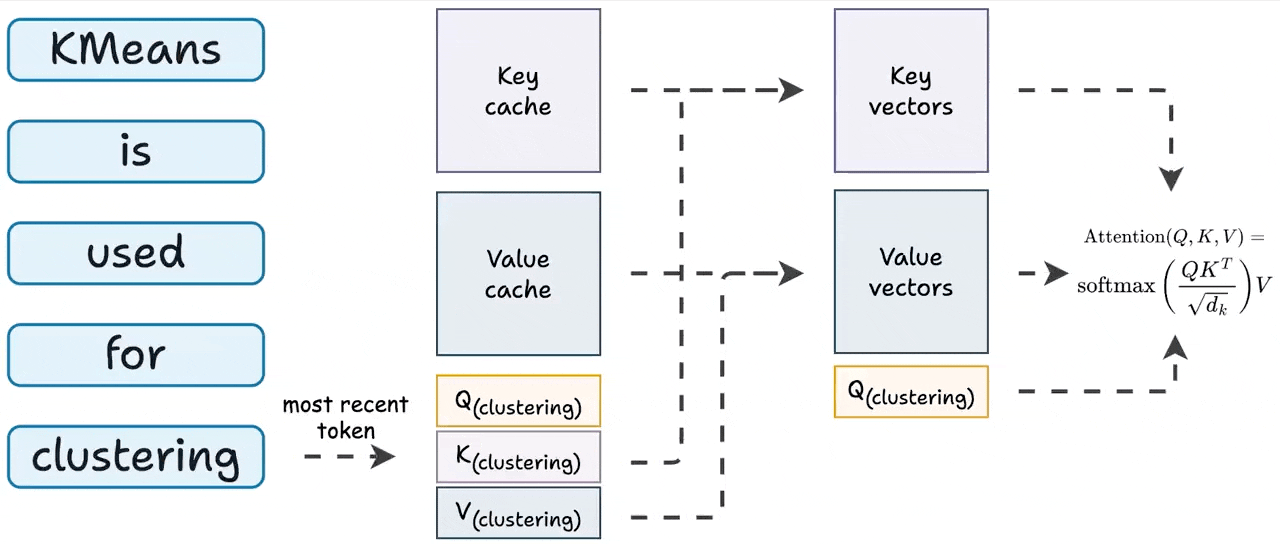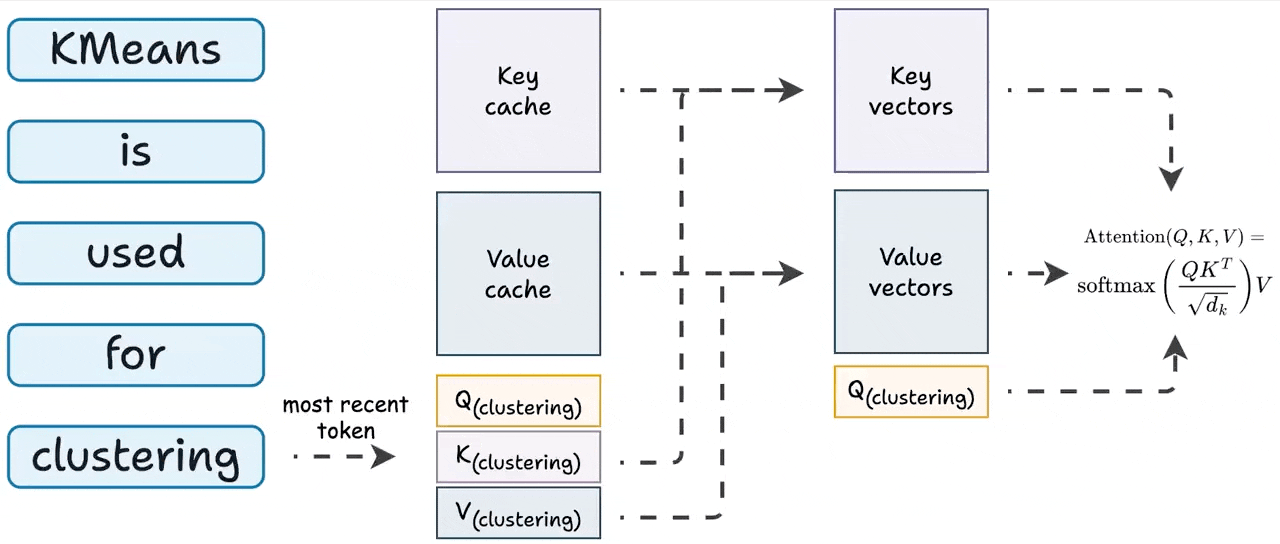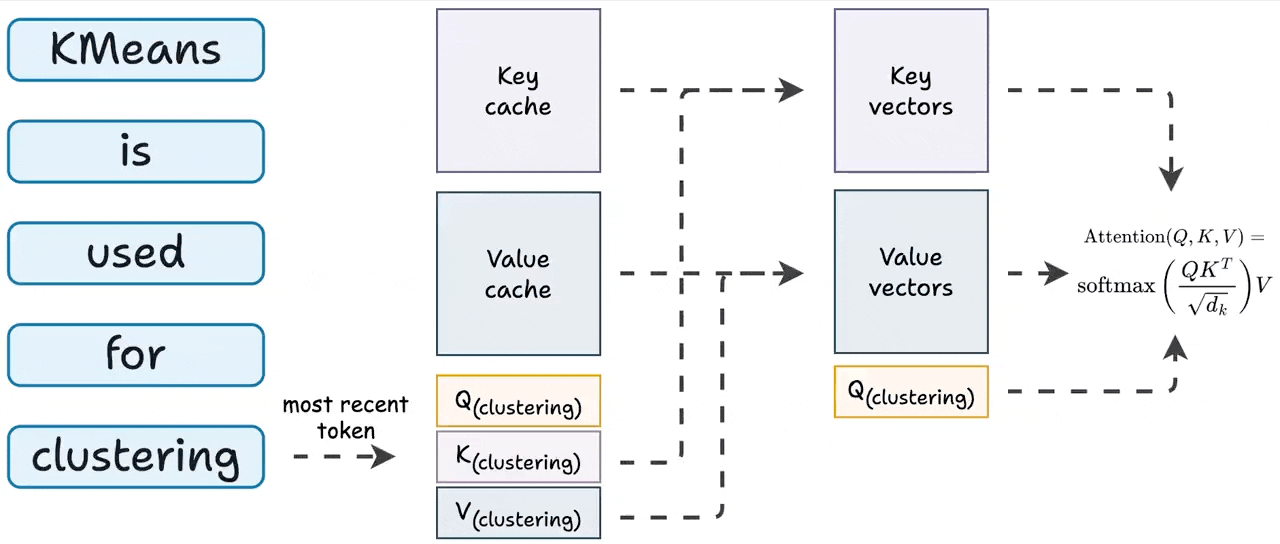
KV Caching in LLMs, explained visually

GPU Memory Tetris: KV Cache & Paged Attention | by Nikulsinh Rajput ...
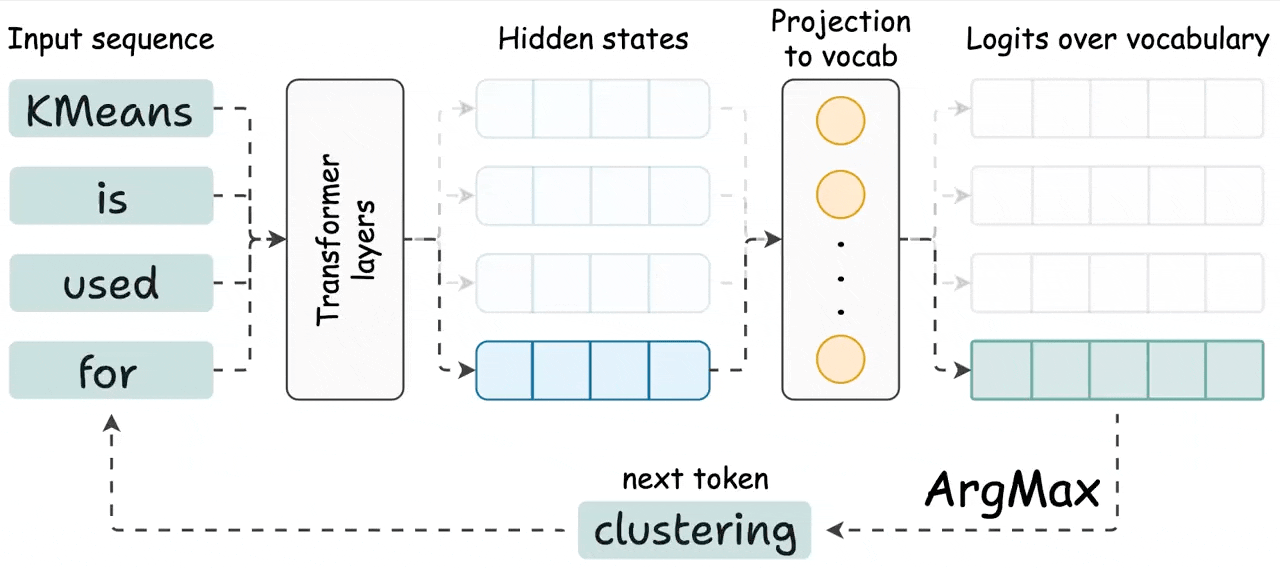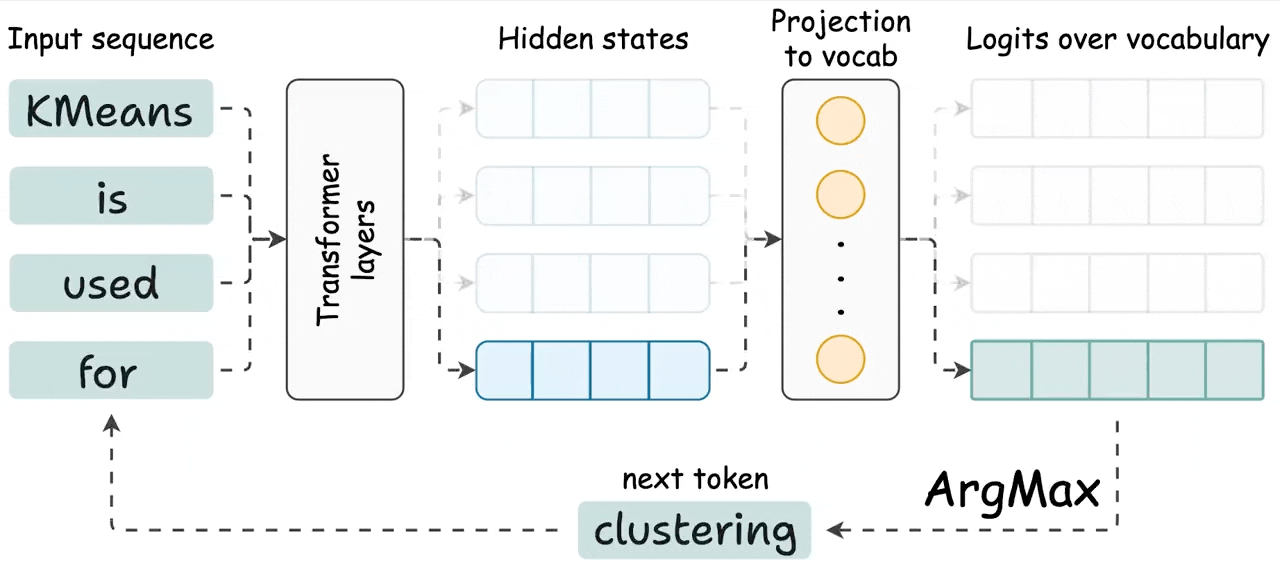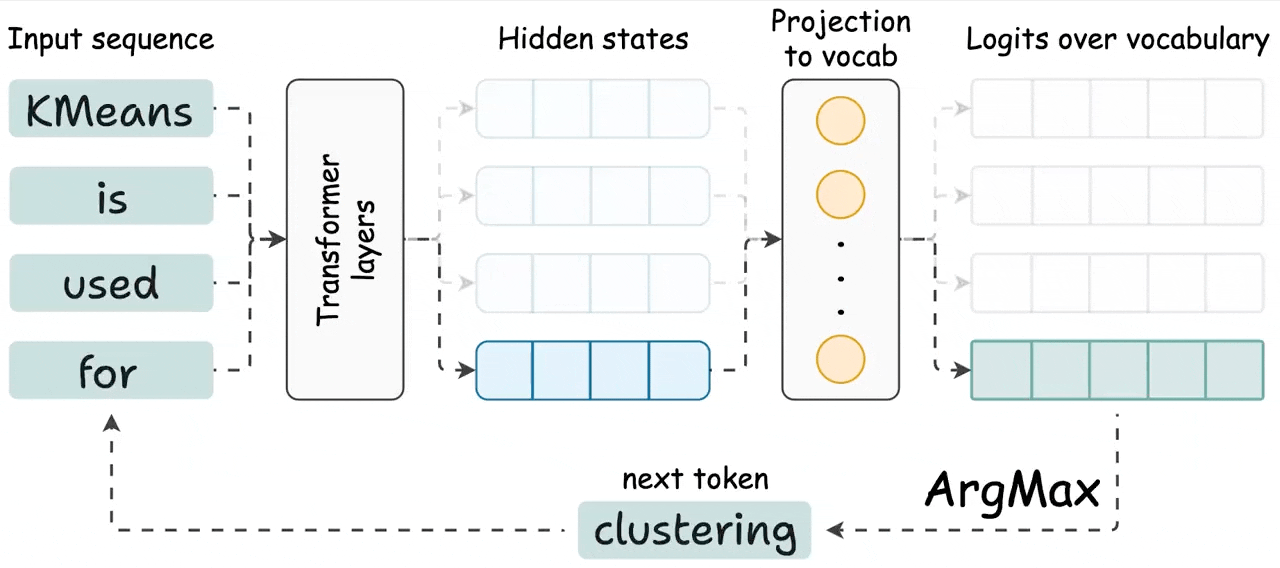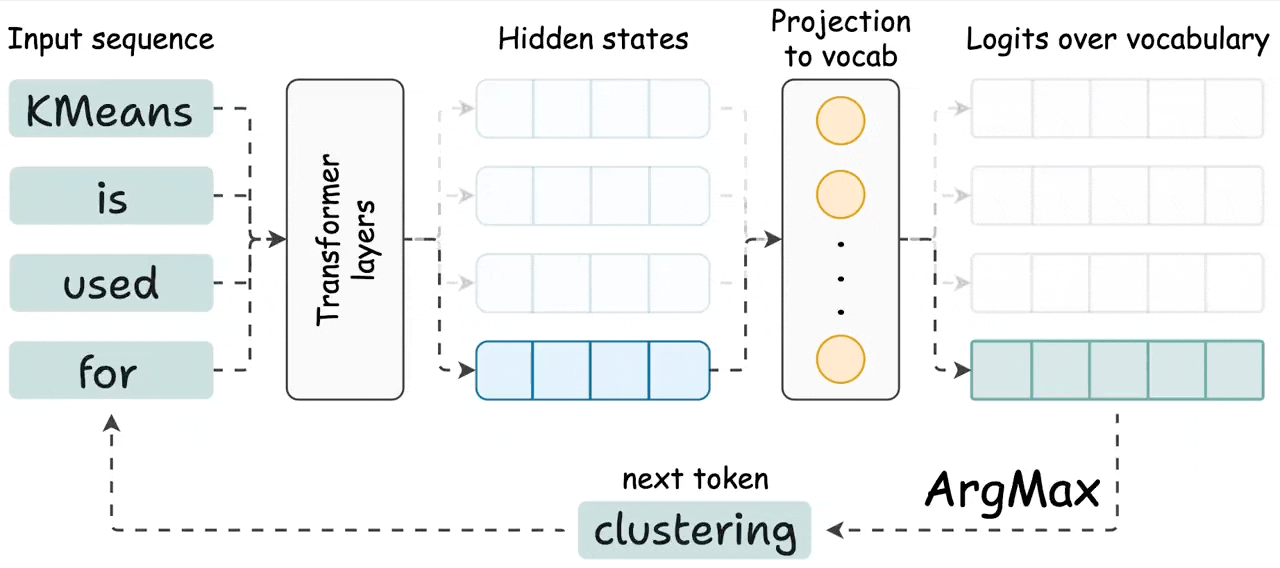
KV Caching in LLMs, Explained Visually. - by Avi Chawla
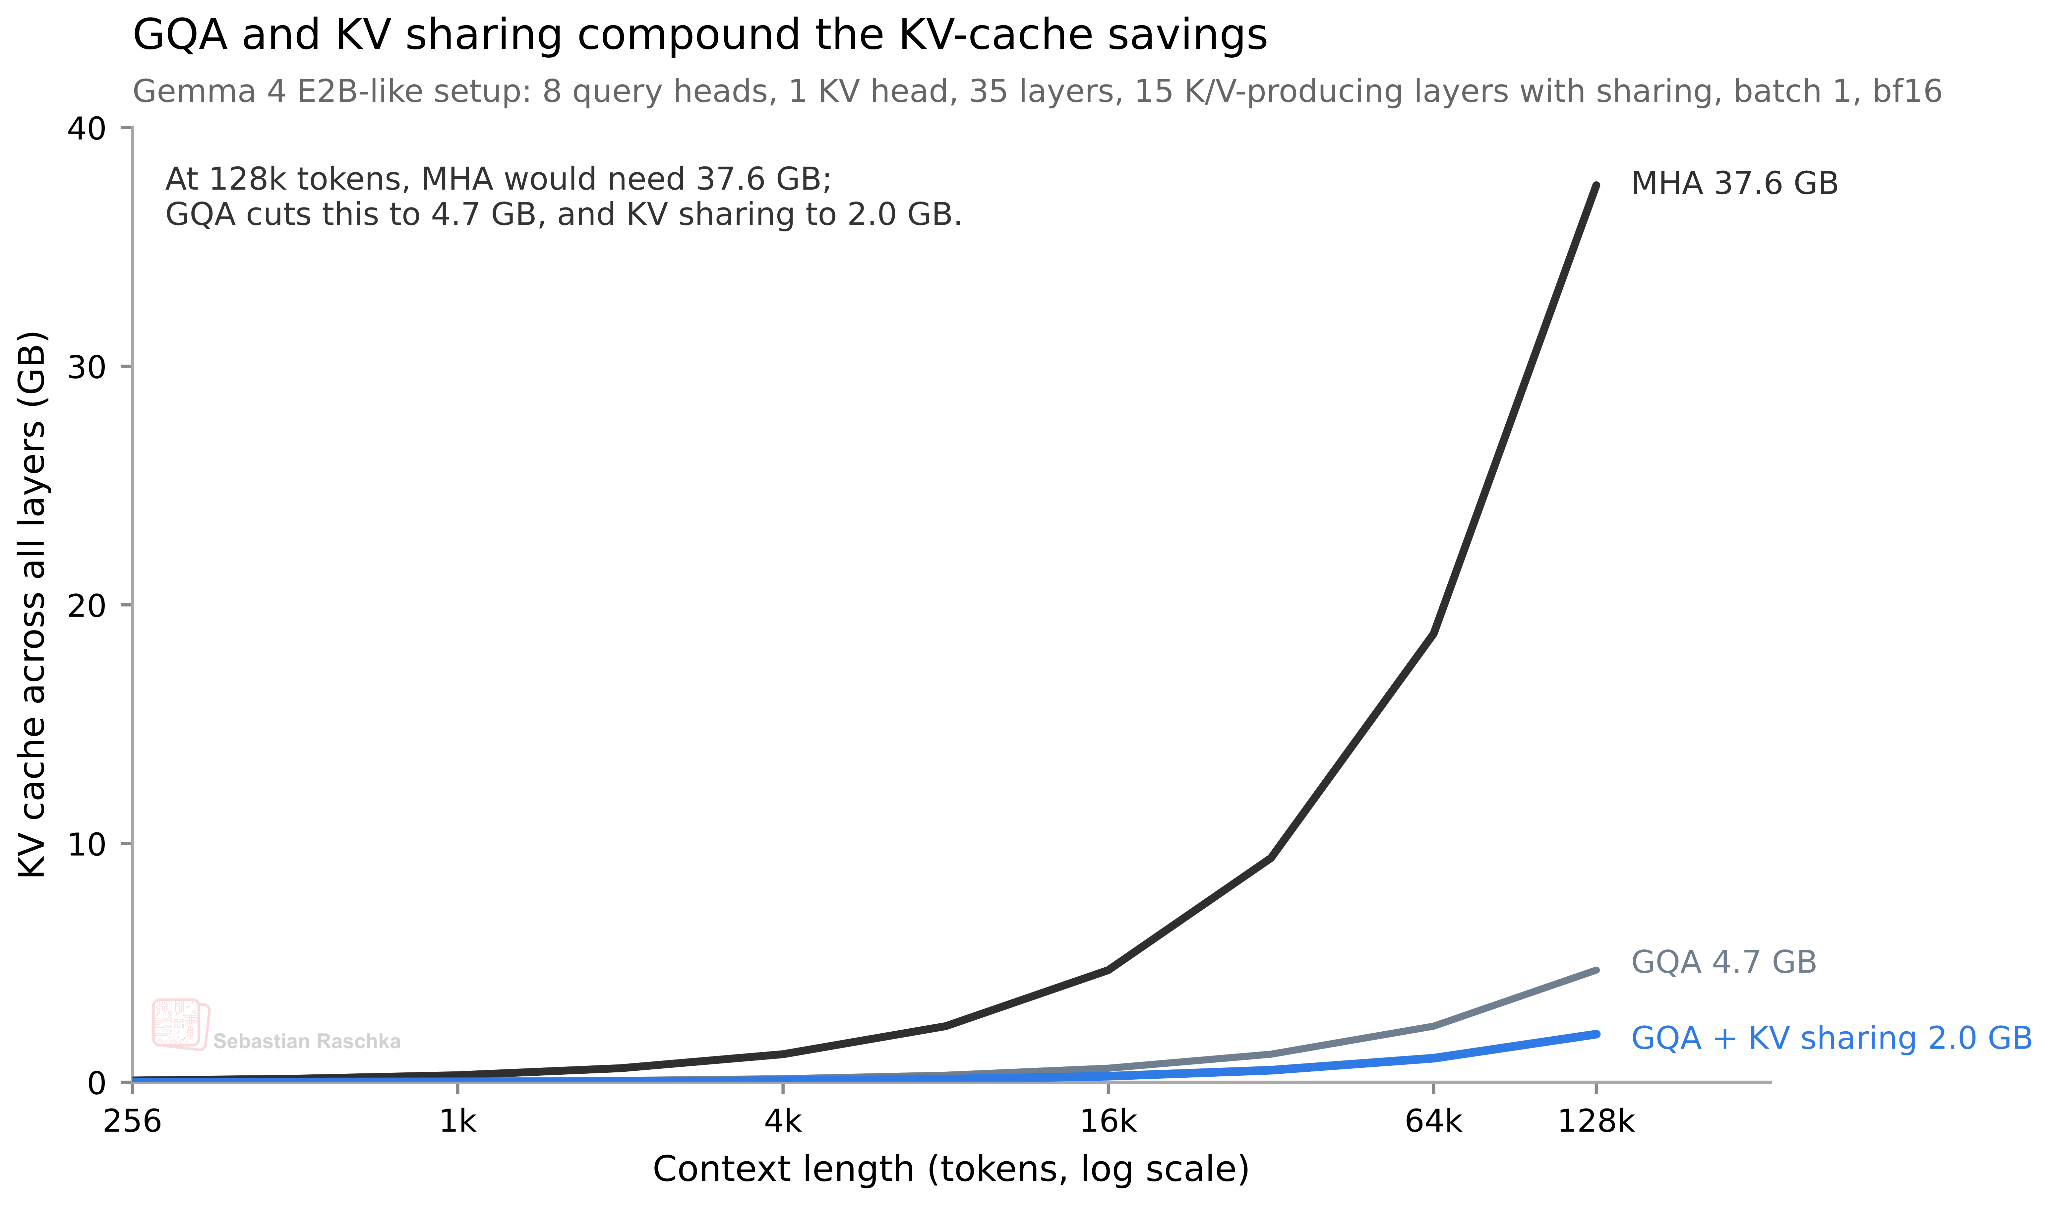
Recent Developments in LLM Architectures: KV Sharing, mHC, and ...
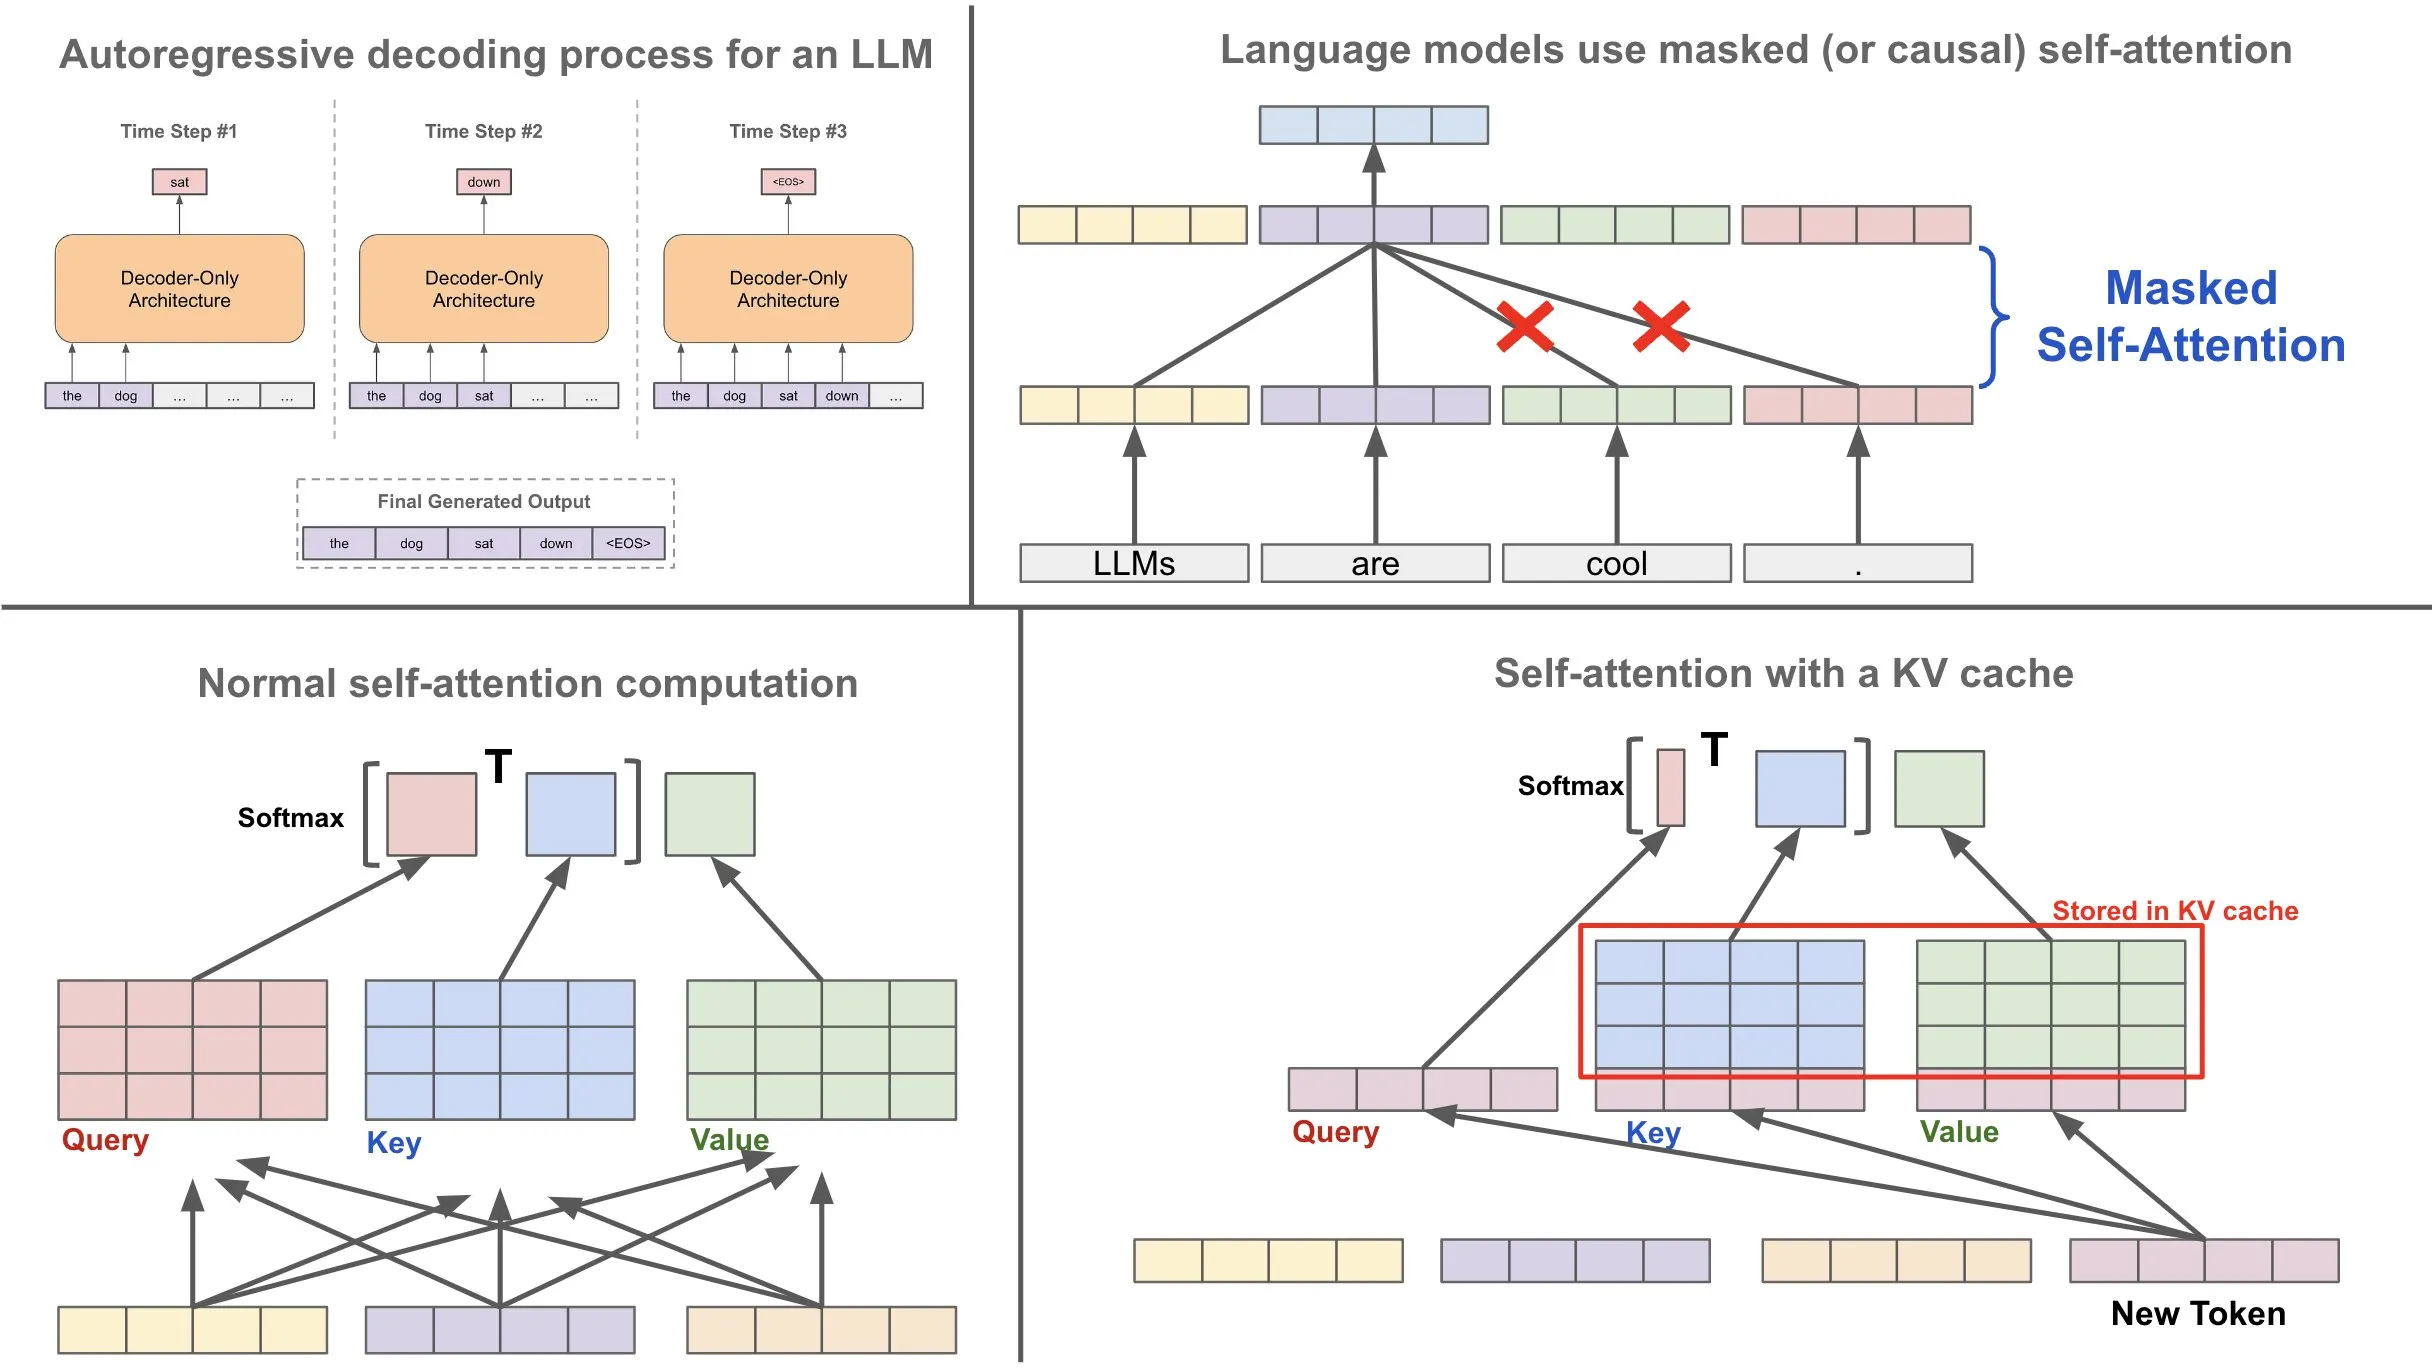
Dive Into Tokenization, Attention, and Key-Value Caching

Efficient GPU Memory Management for LLMs with PagedAttention | Ayush ...
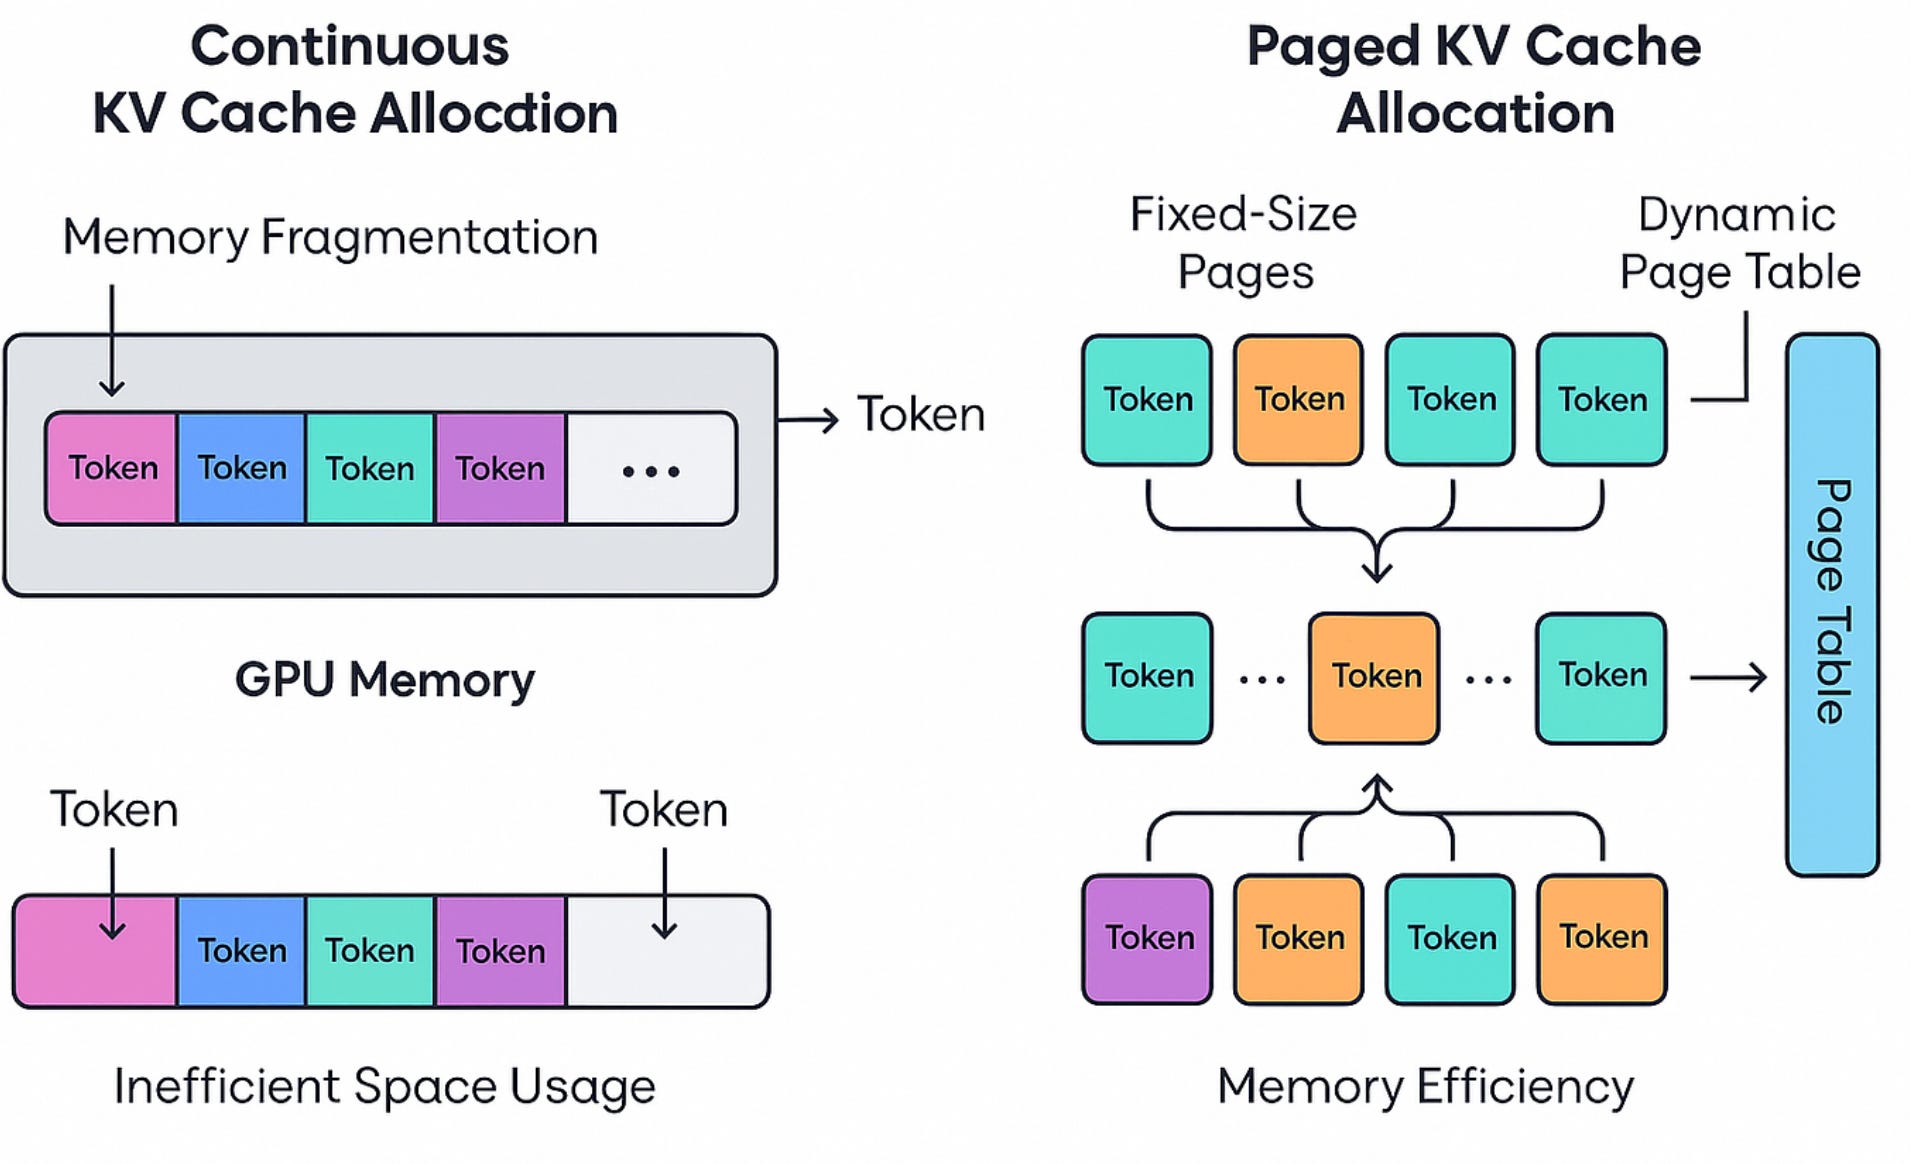
The Hidden Cost of LLM Infrastructure: How MLOps Mistakes Waste GPU ...

Meet 'kvcached': A Machine Learning Library to Enable Virtualized ...
Advertisement Space (336x280)

GPU memory requirements for serving Large Language Models | UnfoldAI

How to Reduce KV Cache Bottlenecks with NVIDIA Dynamo | NVIDIA ...
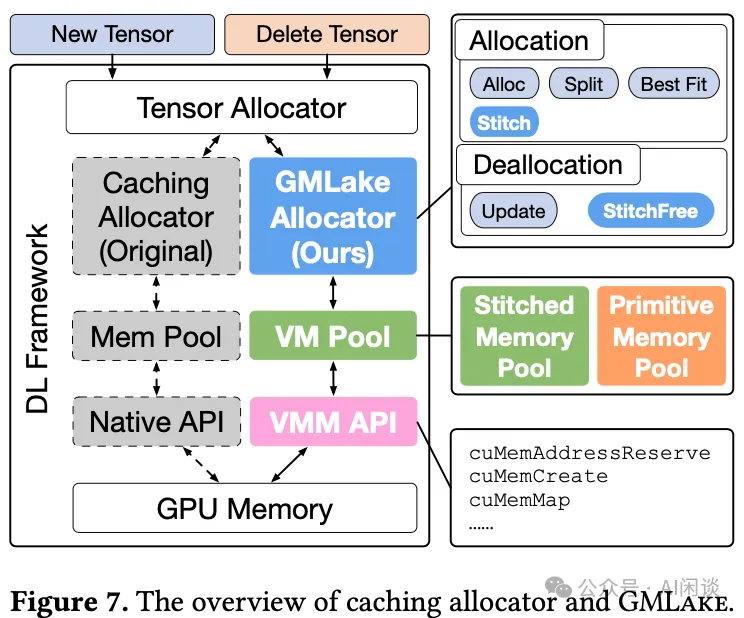
LLM 推理的 Attention 计算和 KV Cache 优化:PagedAttention、vAttention 等-AI.x-AIGC ...
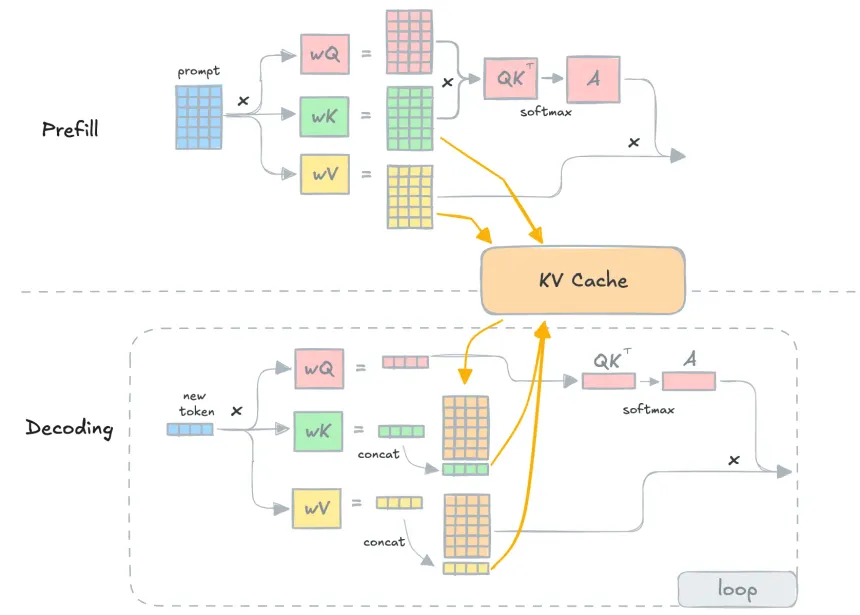
How KV Caching Makes Modern LLMs Fast?

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference
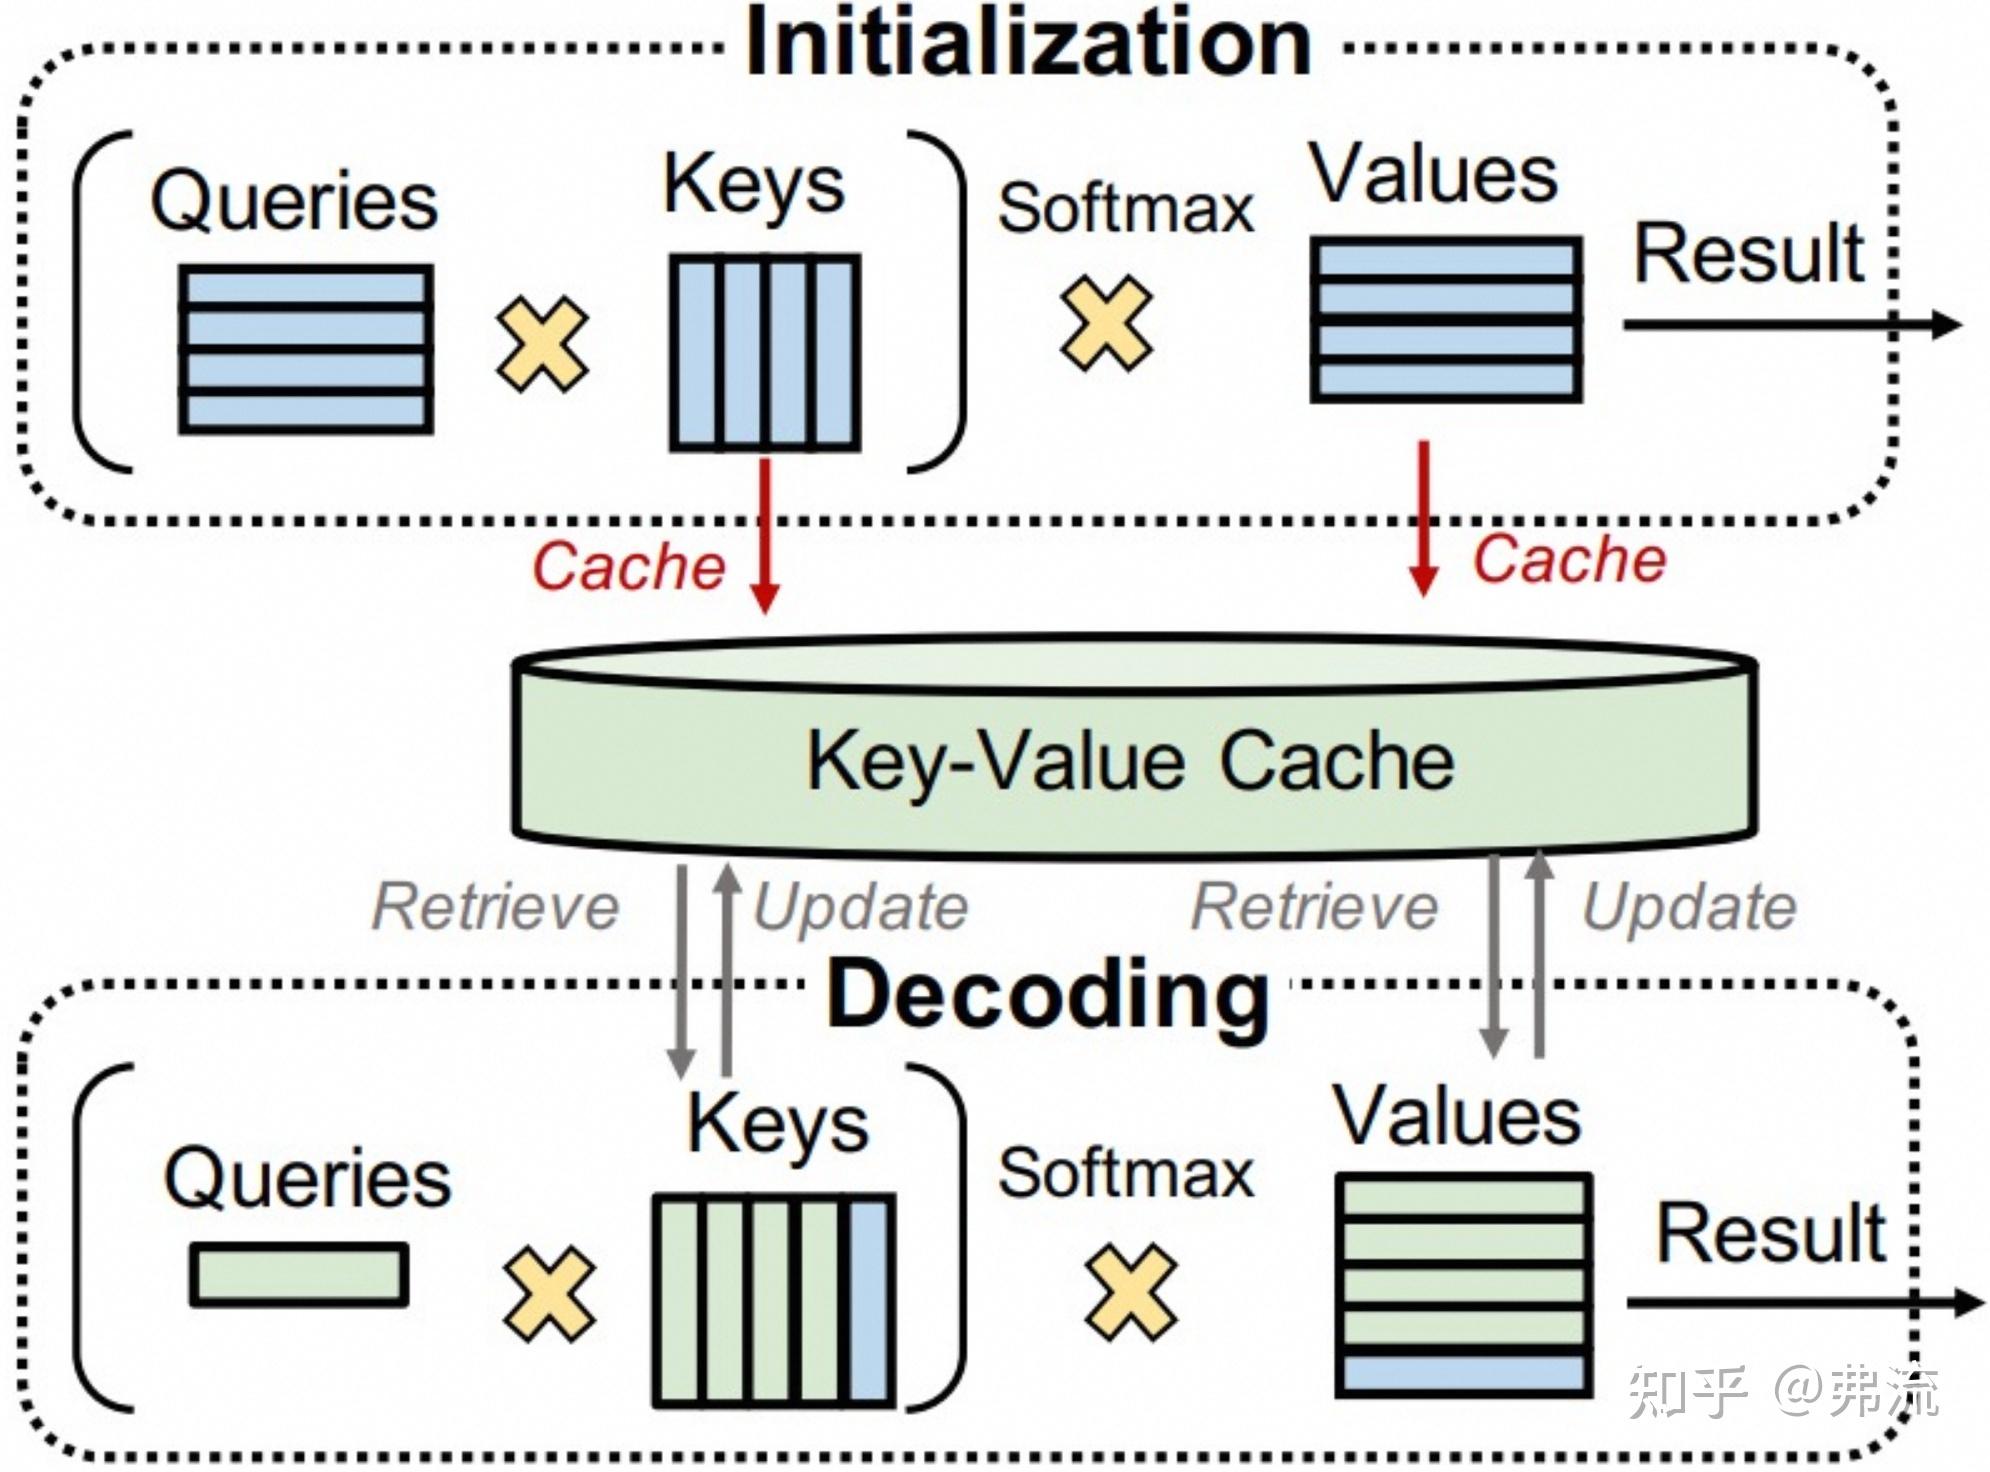
vLLM V1 源码解读(二):PagedAttention——用操作系统的思想管 GPU 的 KV Cache - 知乎