
Github Aibrixpriskv High Performance Kv Cache Store For Llm Github
GitHub - aibrix/PrisKV: High Performance KV Cache Store for LLM · GitHub
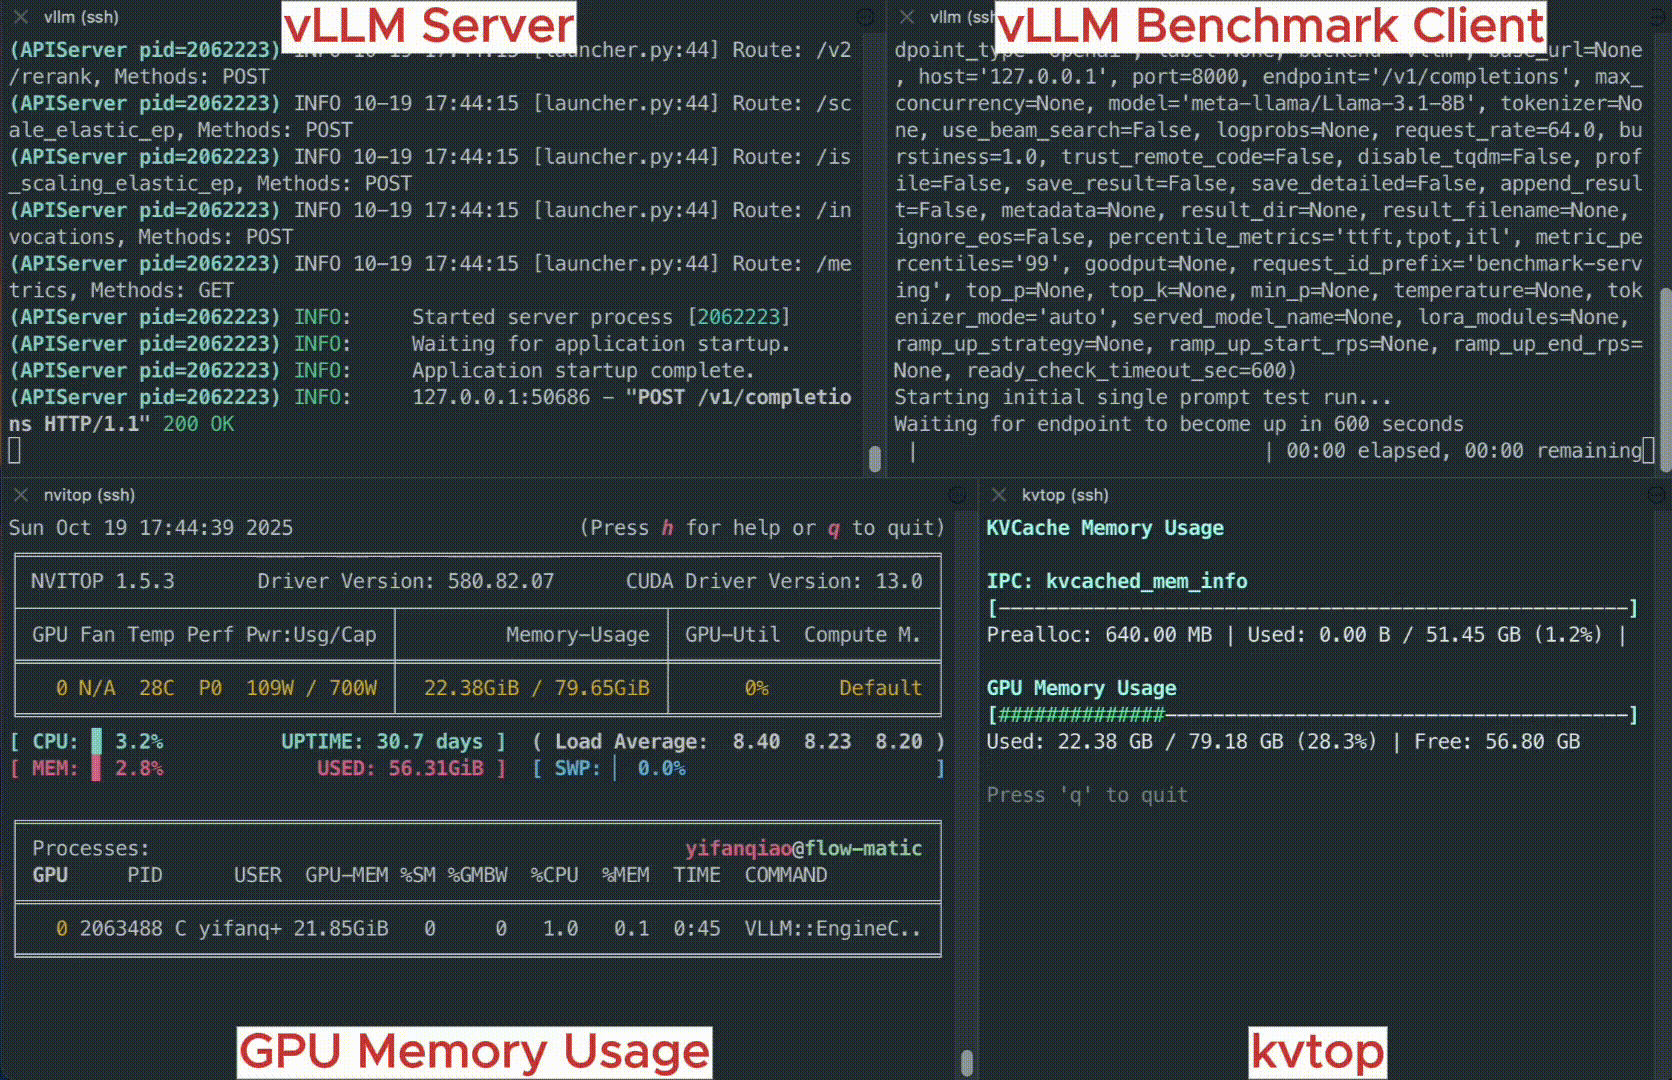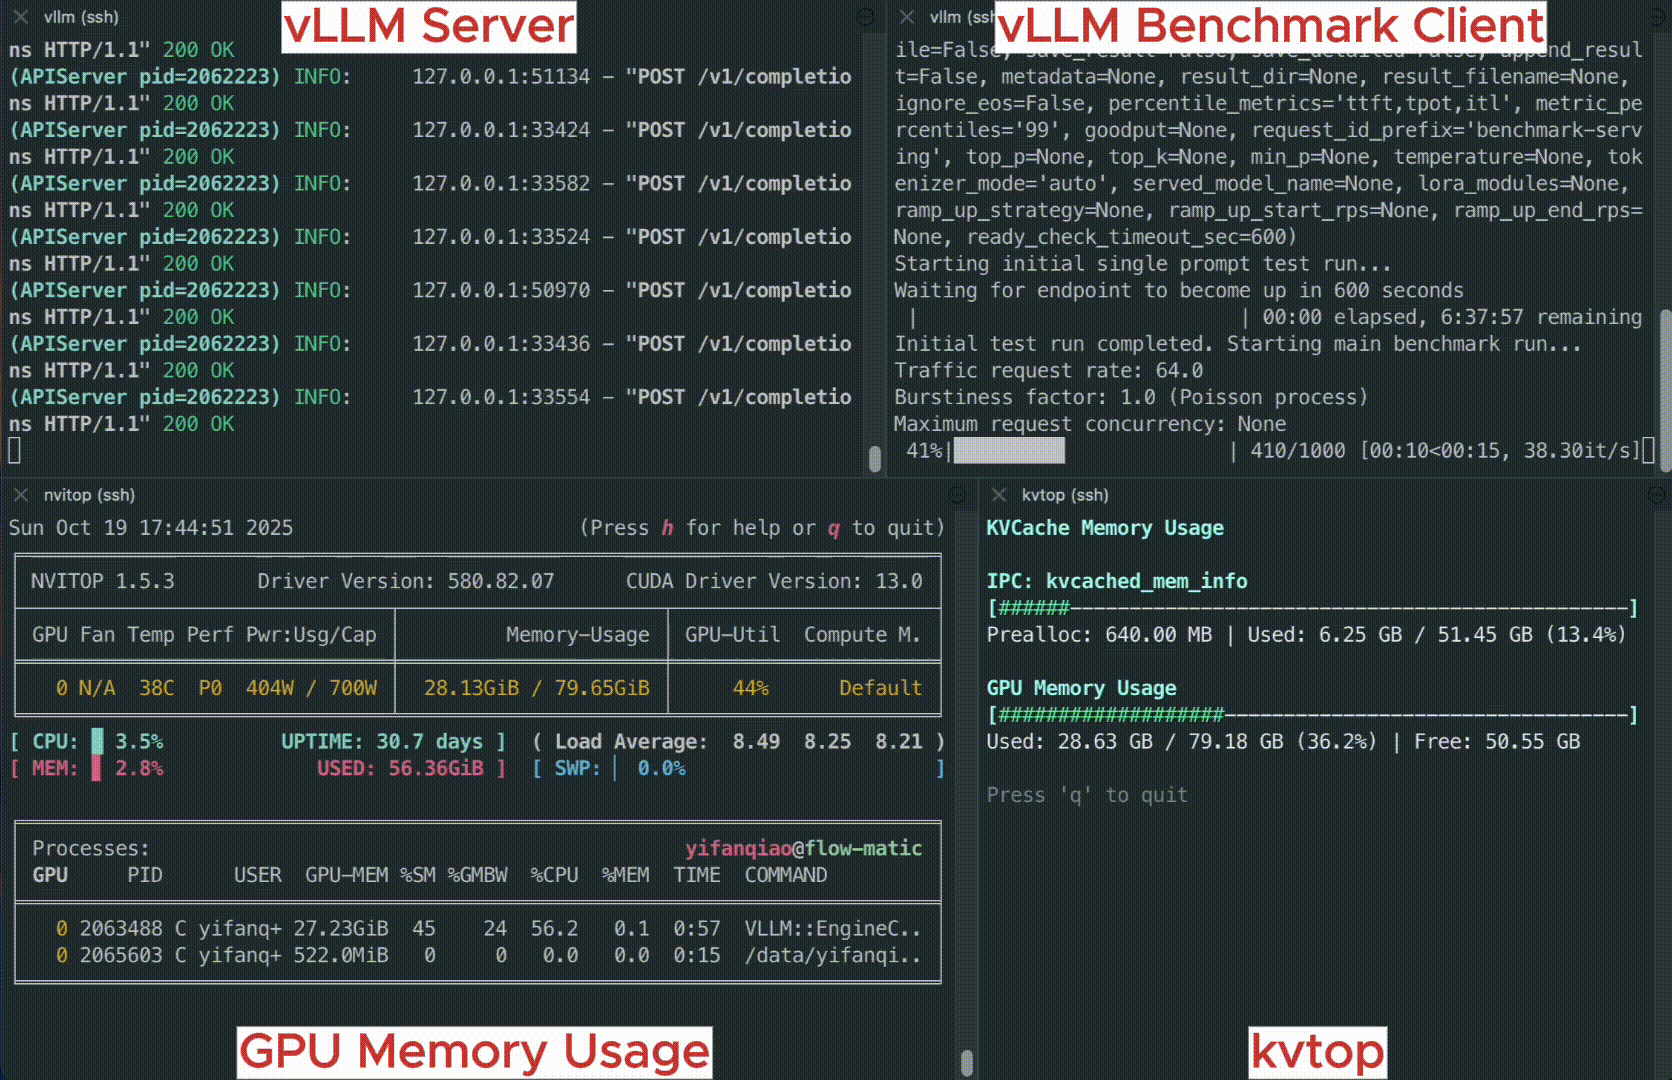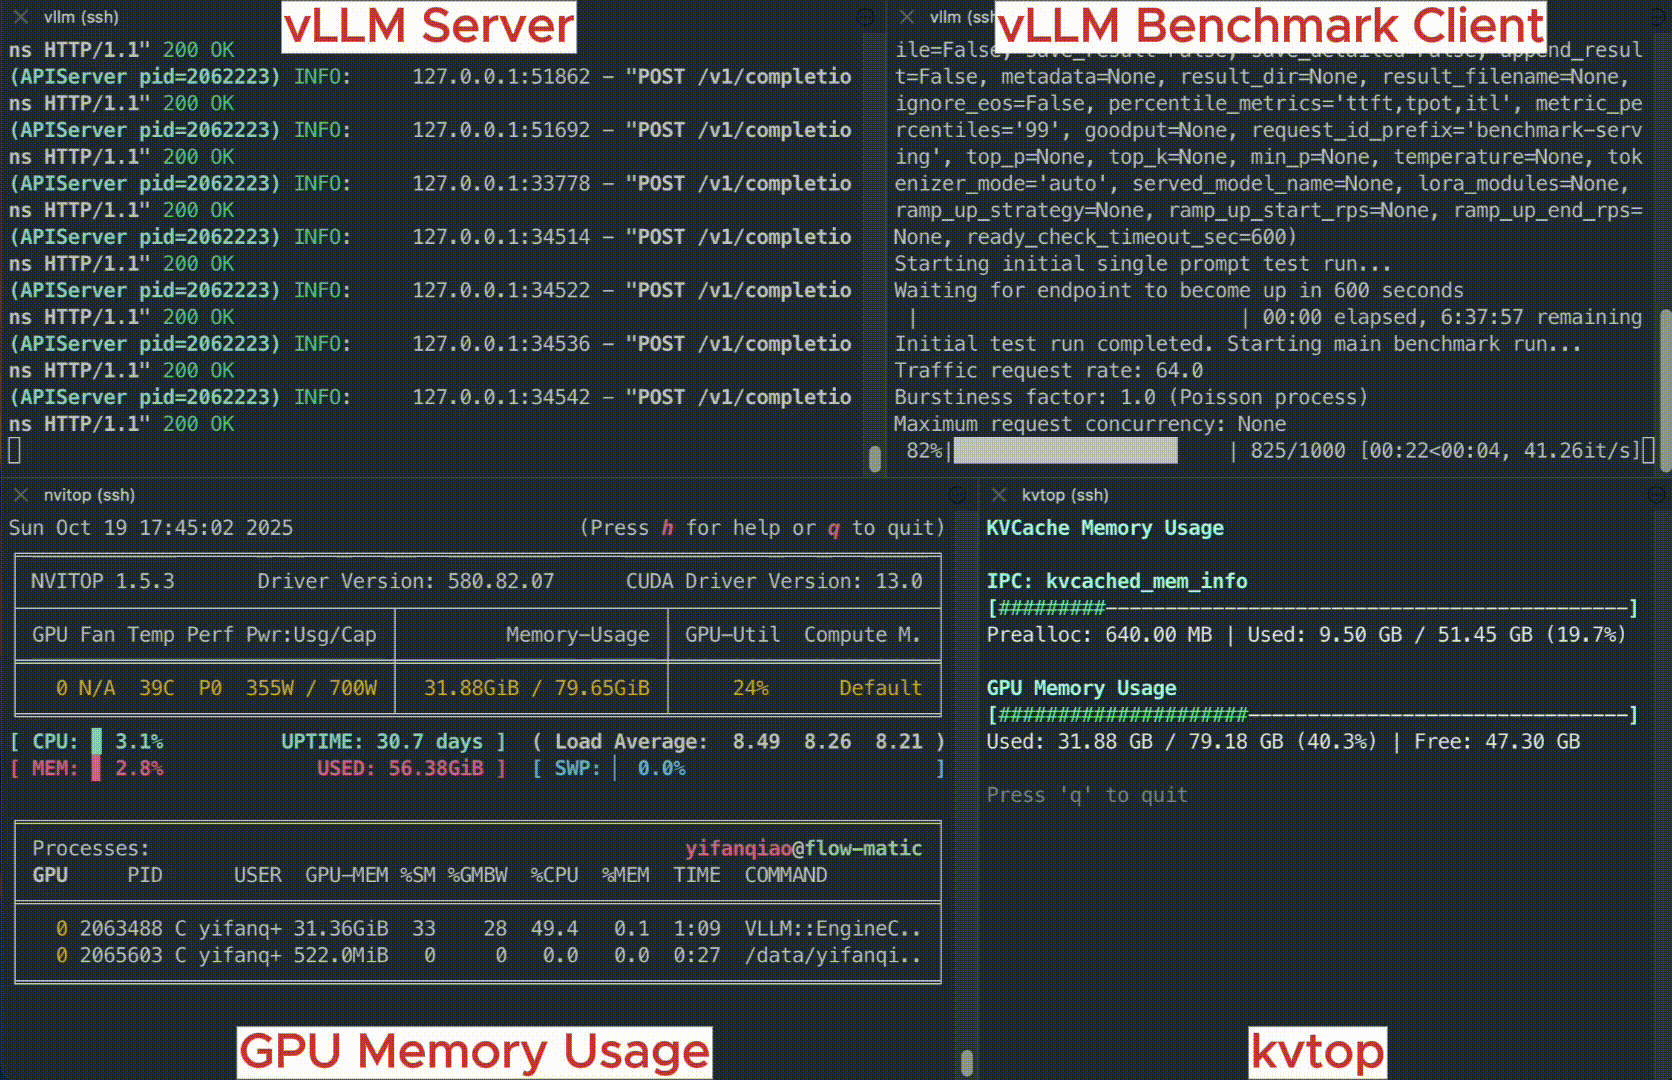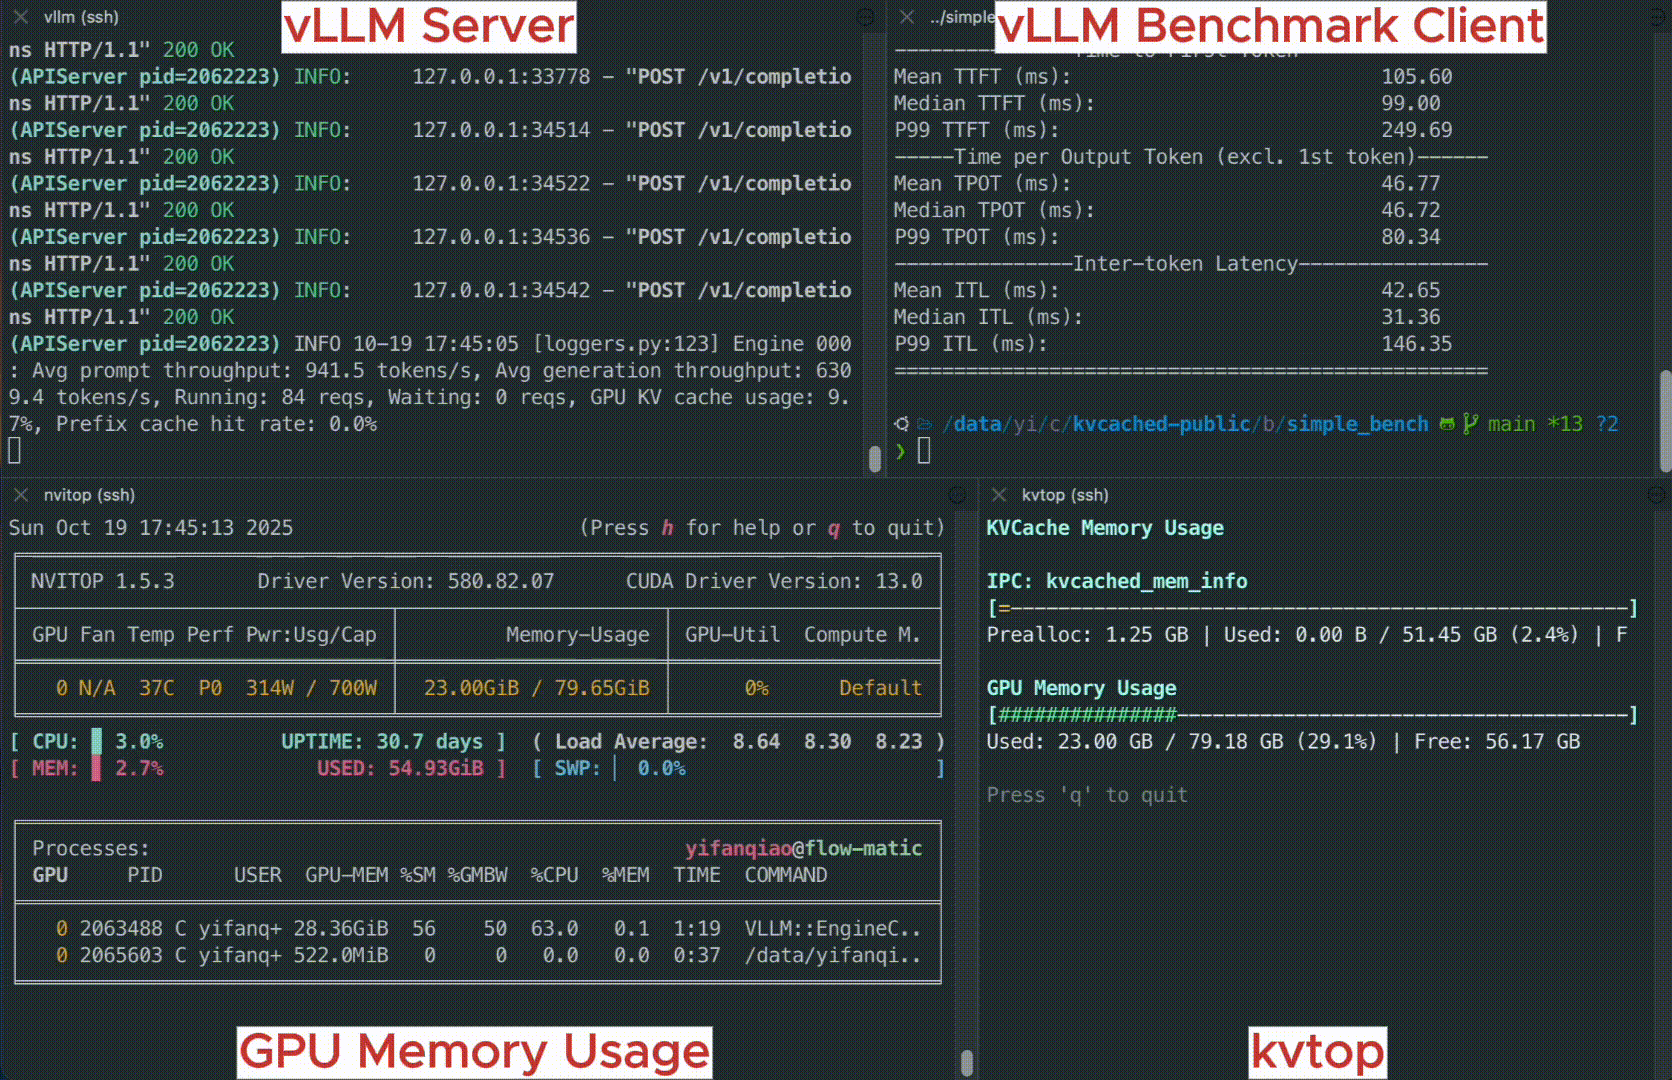
GitHub - ovg-project/kvcached: Virtualized Elastic KV Cache for Dynamic ...
GitHub - apguan/lmcache: Supercharge Your LLM with the Fastest KV Cache ...
GitHub - sjtu-zhao-lab/ClusterKV: ClusterKV: Manipulating LLM KV Cache ...
GitHub - NVIDIA/kvpress: LLM KV cache compression made easy · GitHub

ClusterKV: Manipulating LLM KV Cache in Semantic Space for Recallable ...
GitHub - LMCache/LMCache: Supercharge Your LLM with the Fastest KV ...

LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference ...

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference
Advertisement Space (300x250)
How to disable KV cache for LLM · Issue #1976 · NVIDIA/TensorRT-LLM ...
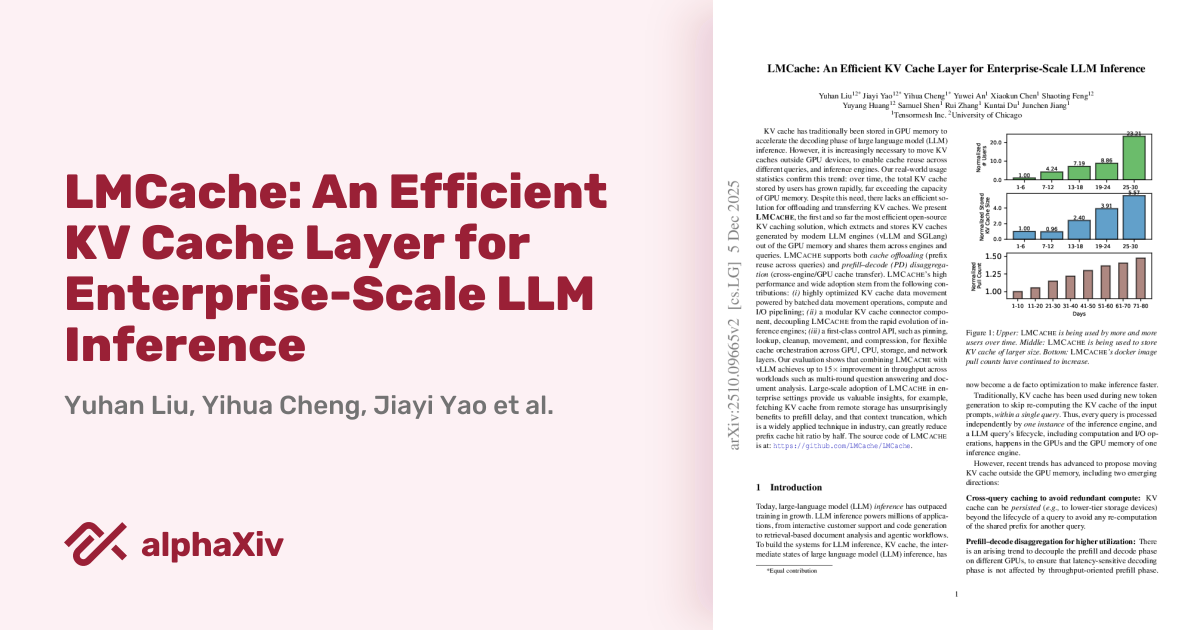
LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference ...
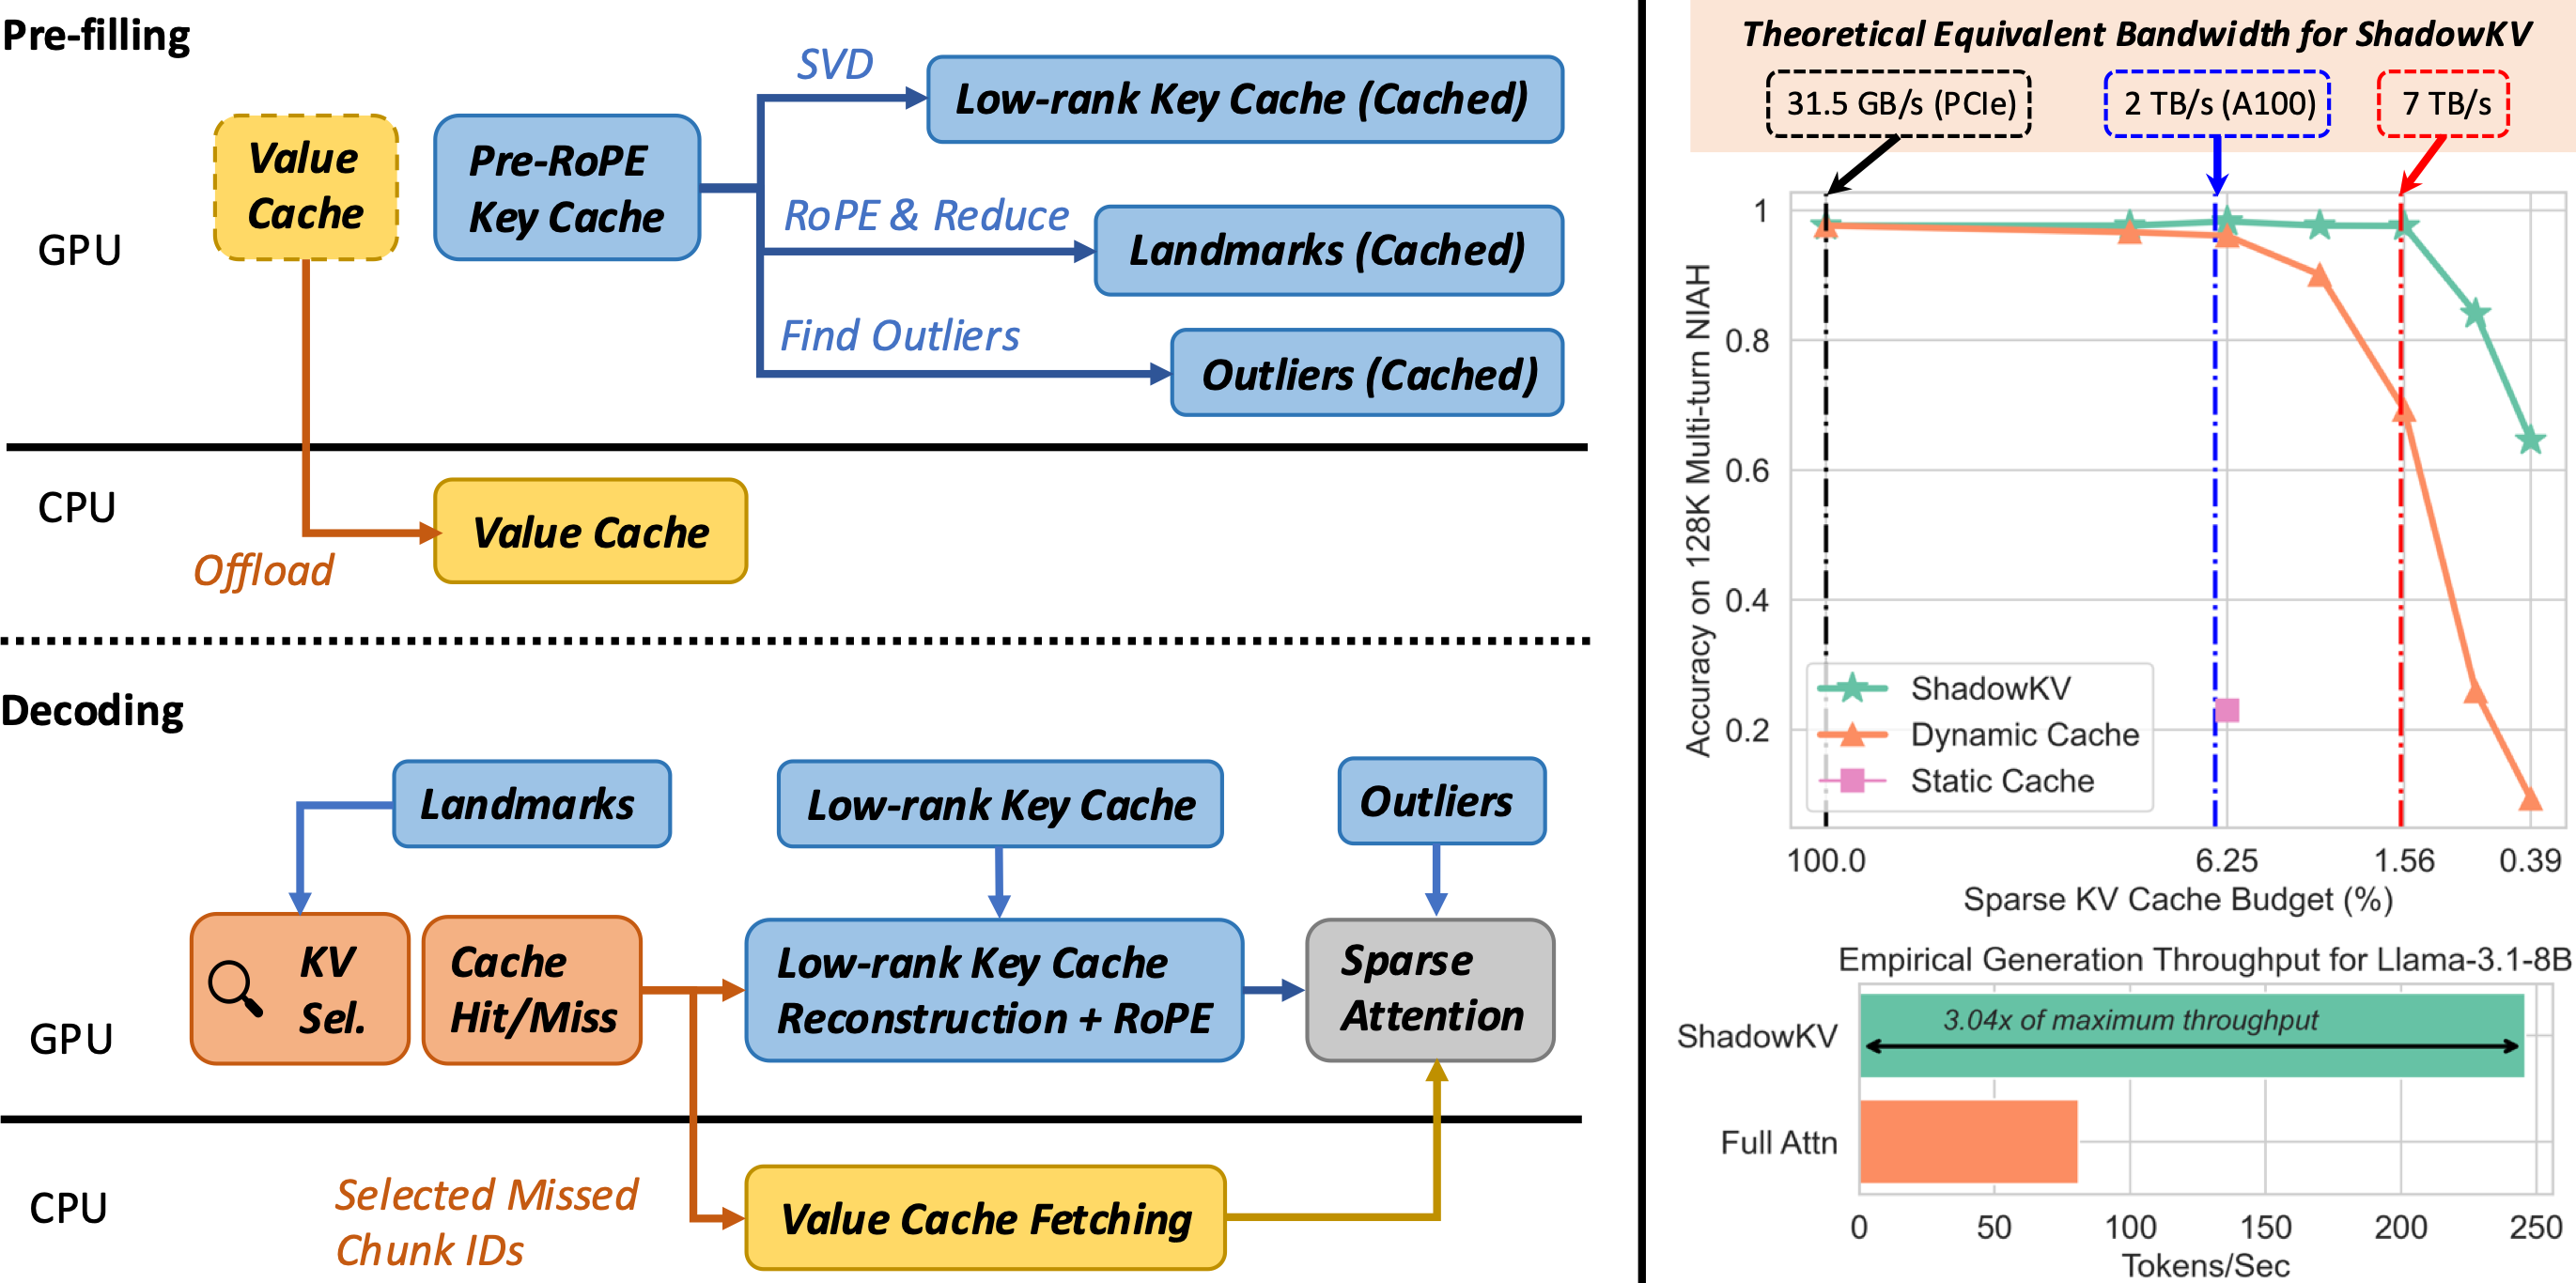
ShadowKV: KV Cache in Shadows for High-Throughput Long-Context LLM ...
GPU KV cache usage: 100.0%以后就卡住 · Issue #1206 · vllm-project/vllm · GitHub
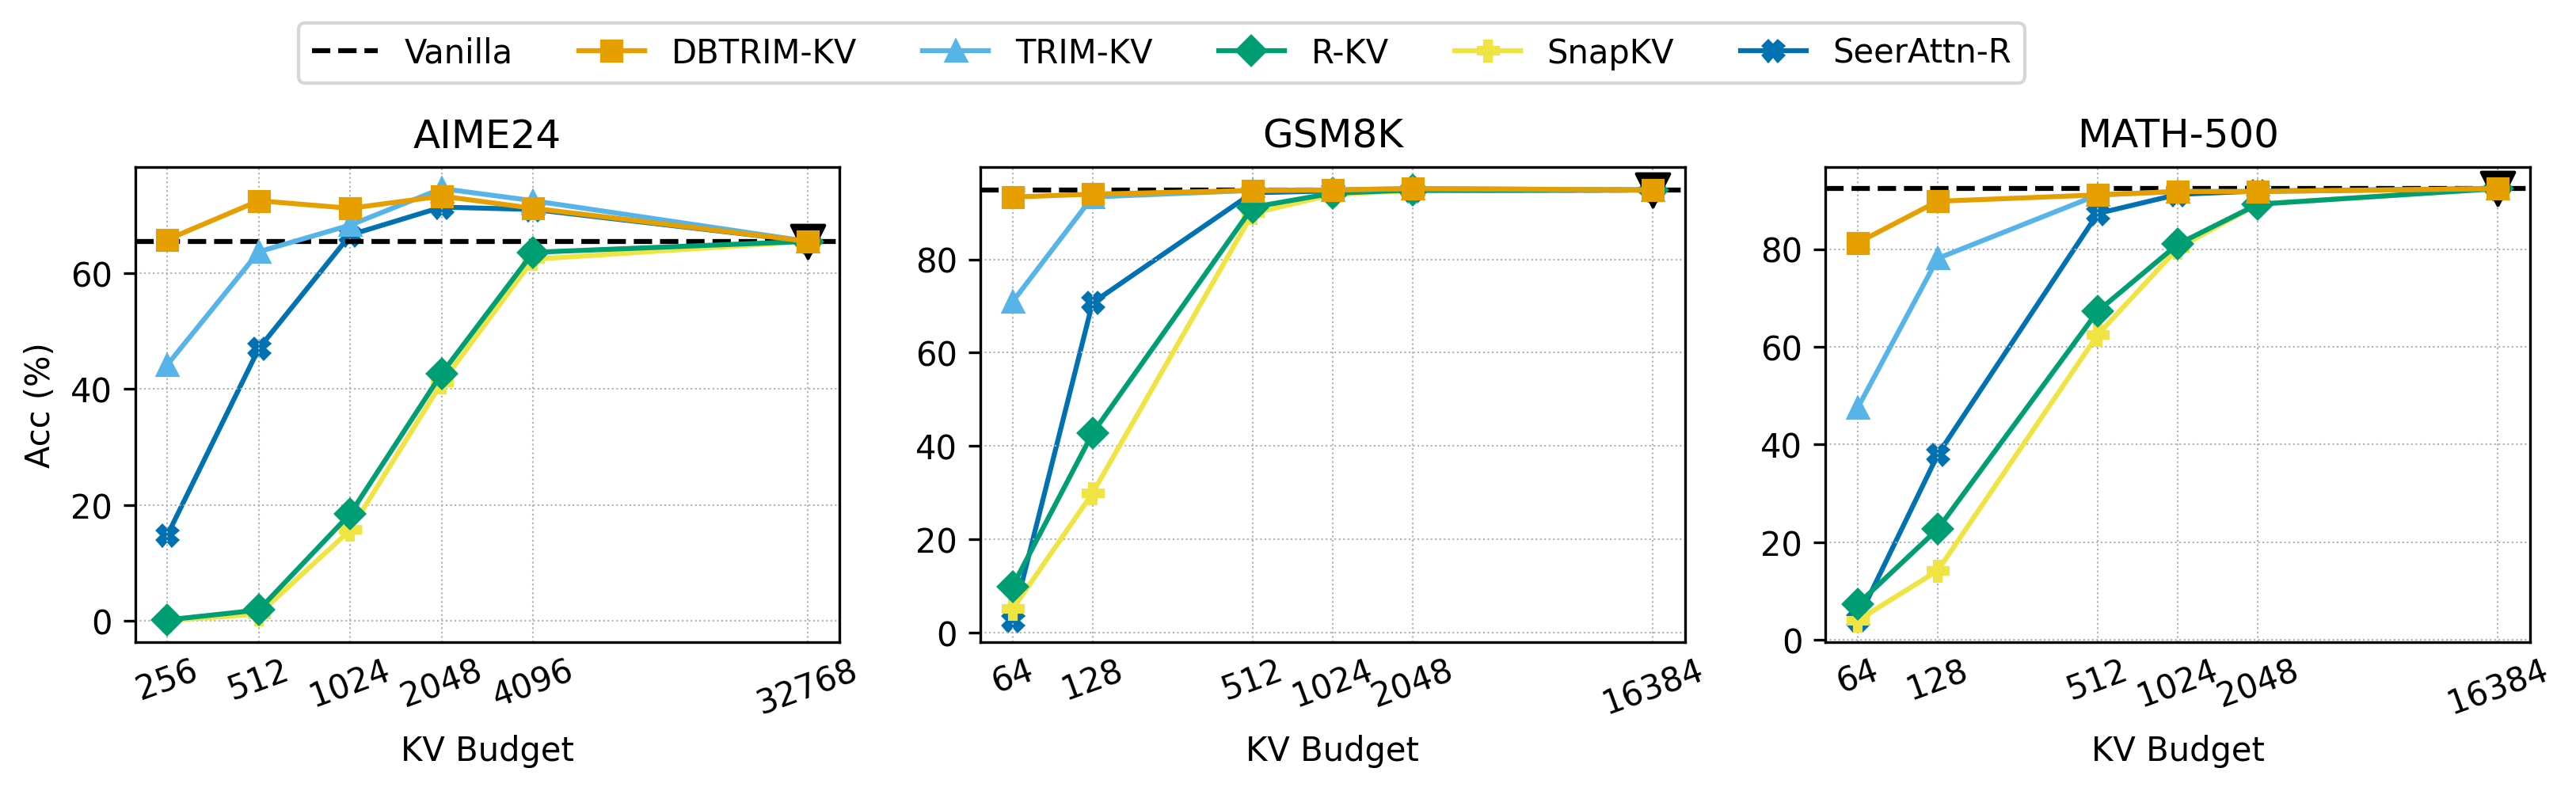
GitHub - ngocbh/trimkv: [TrimKV] Cache What Lasts: Token Retention for ...
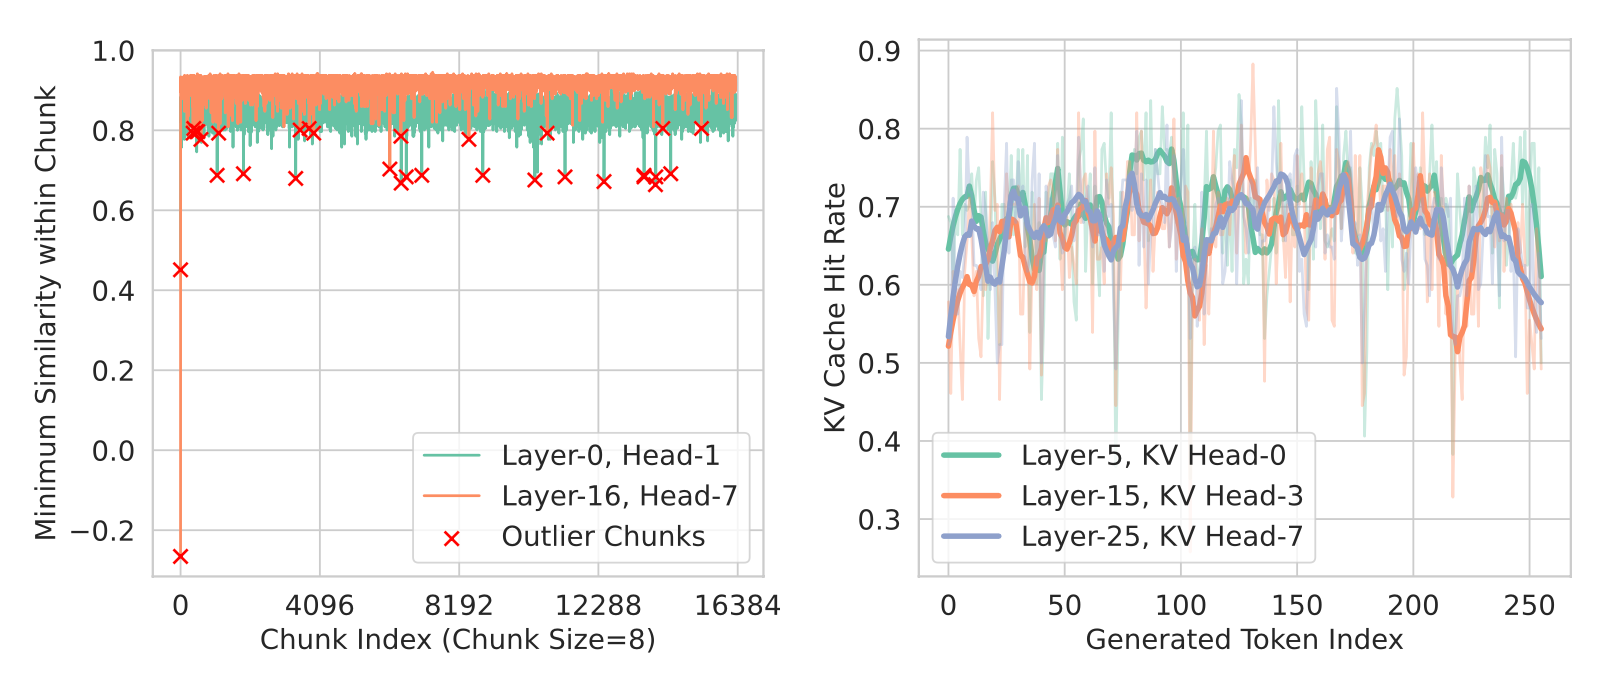
ShadowKV: KV Cache in Shadows for High-Throughput Long-Context LLM ...
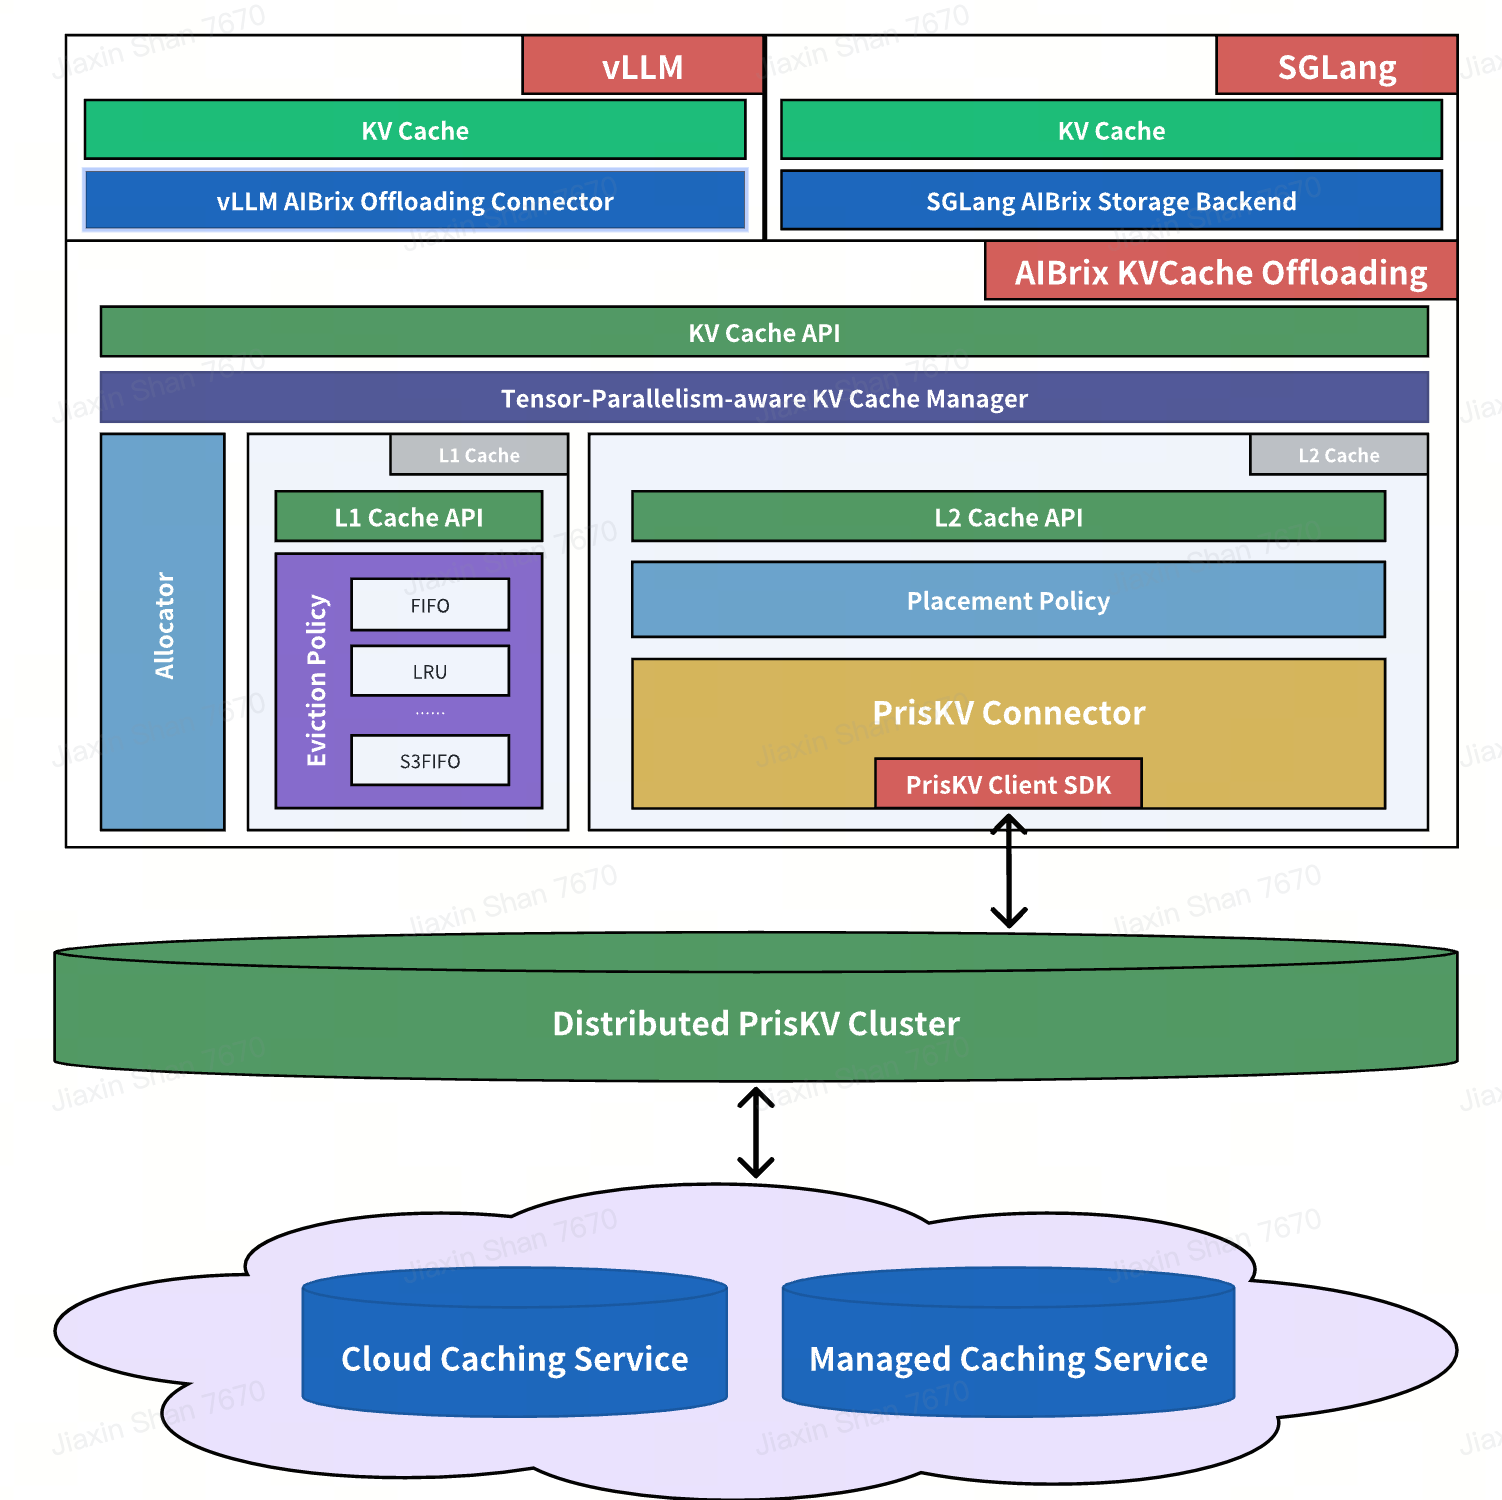
PrisKV: A Colocated Tiered KVCache Store for LLM Serving | AIBrix Blogs
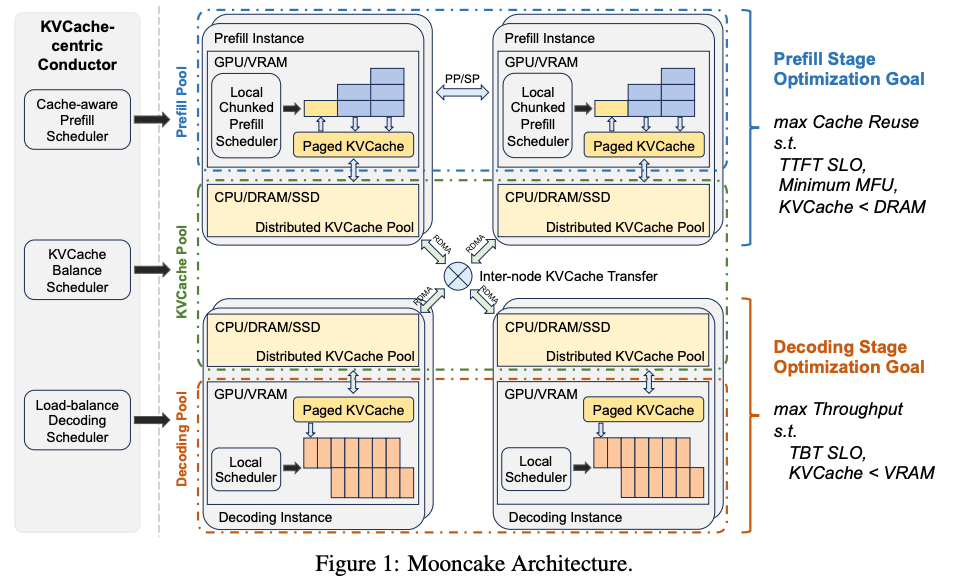
PrisKV: A Colocated Tiered KVCache Store for LLM Serving | AIBrix Blogs
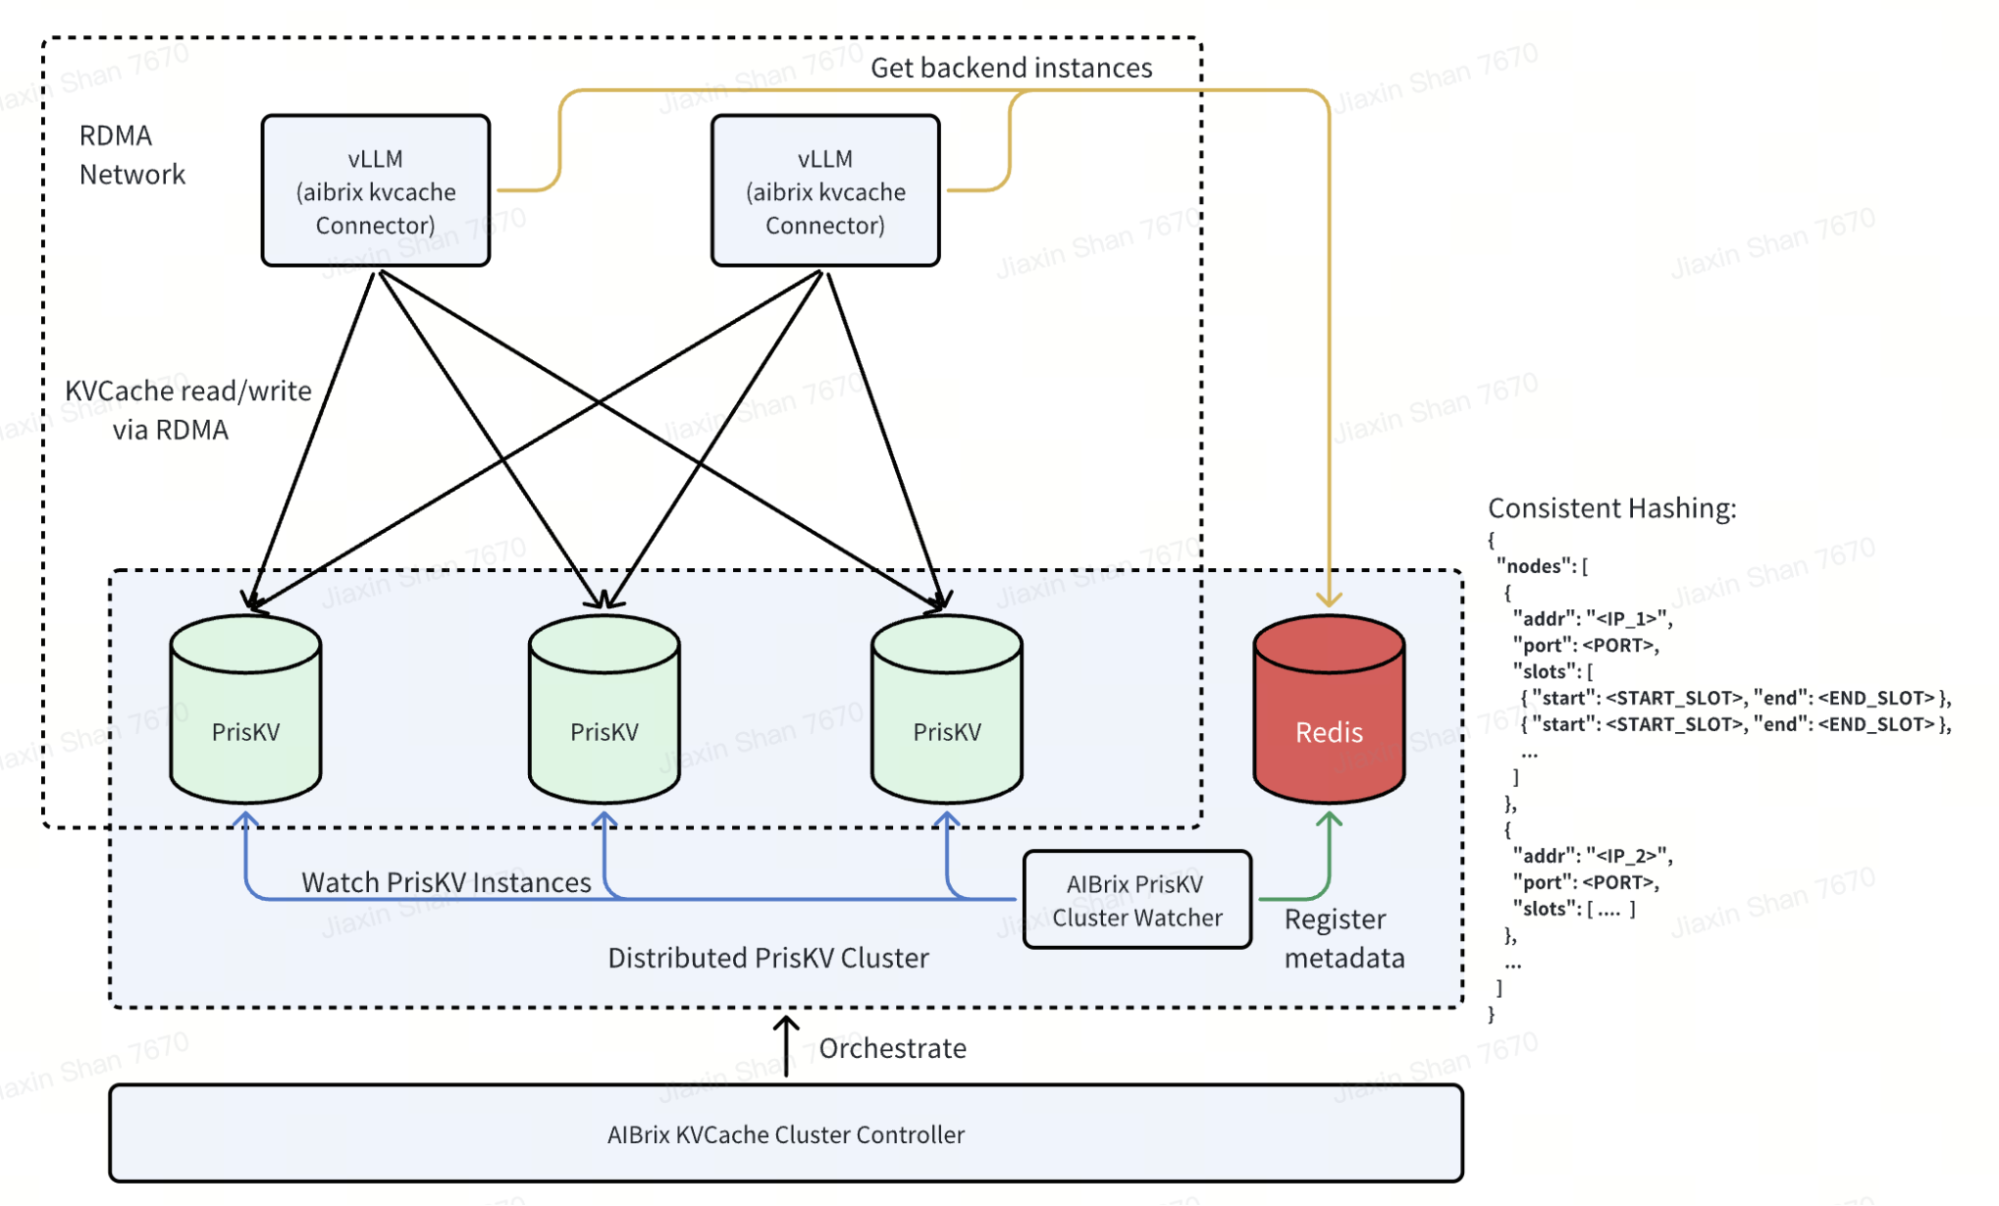
PrisKV: A Colocated Tiered KVCache Store for LLM Serving | AIBrix Blogs
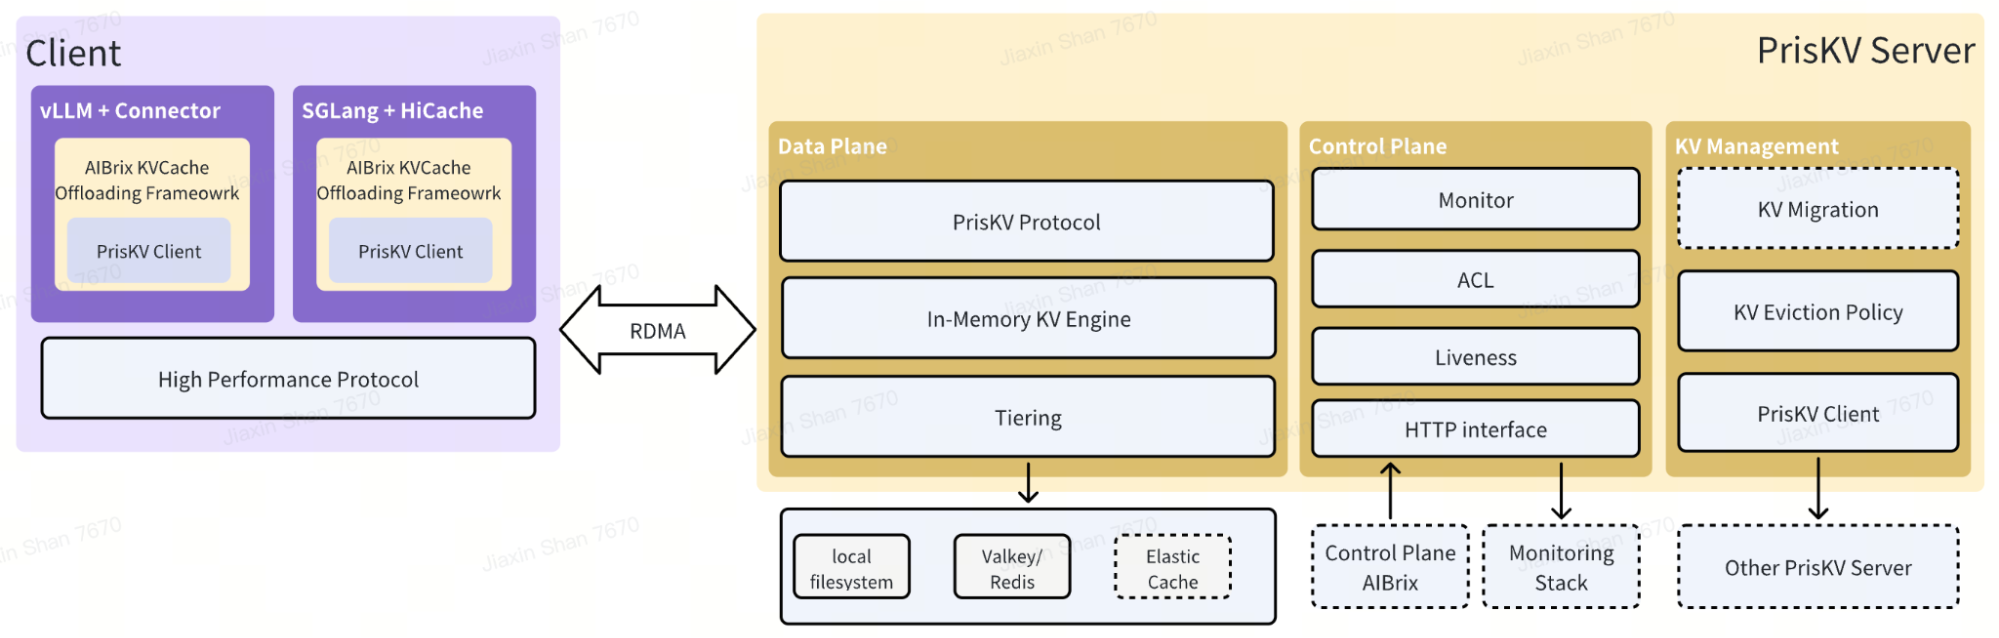
PrisKV: A Colocated Tiered KVCache Store for LLM Serving | AIBrix Blogs
Advertisement Space (336x280)

LLM Inference: Accelerating Long Context Generation with KV Cache ...
基于全局 KV Cache 存储系统的高效 LLM 推理加速方案 Efficient LLM Inference Acceleration ...

GitHub - kvcache-ai/Mooncake: Mooncake is the serving platform for Kimi ...
LMCache:加速 LLM 推理的 KV Cache 管理层开源项目 | Ai导航台

KV Cache Offload Accelerates LLM Inference - NADDOD Blog
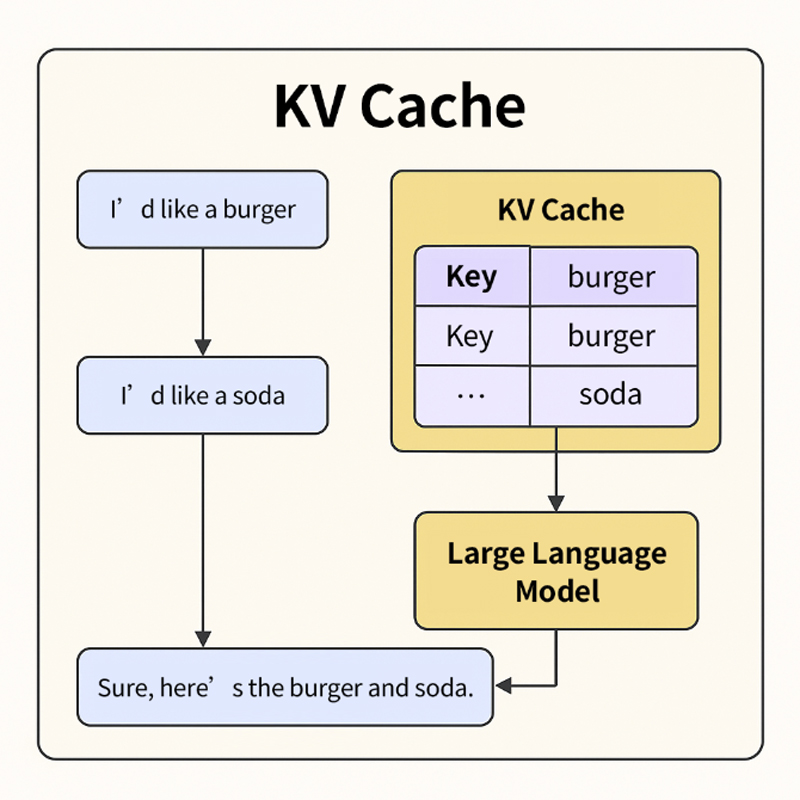
KV Cache Meets NVMe: The Key to Accelerating LLM Inference
LLM KV Cache Optimization: From 300KB to 69KB per Token | SimpleNews.ai
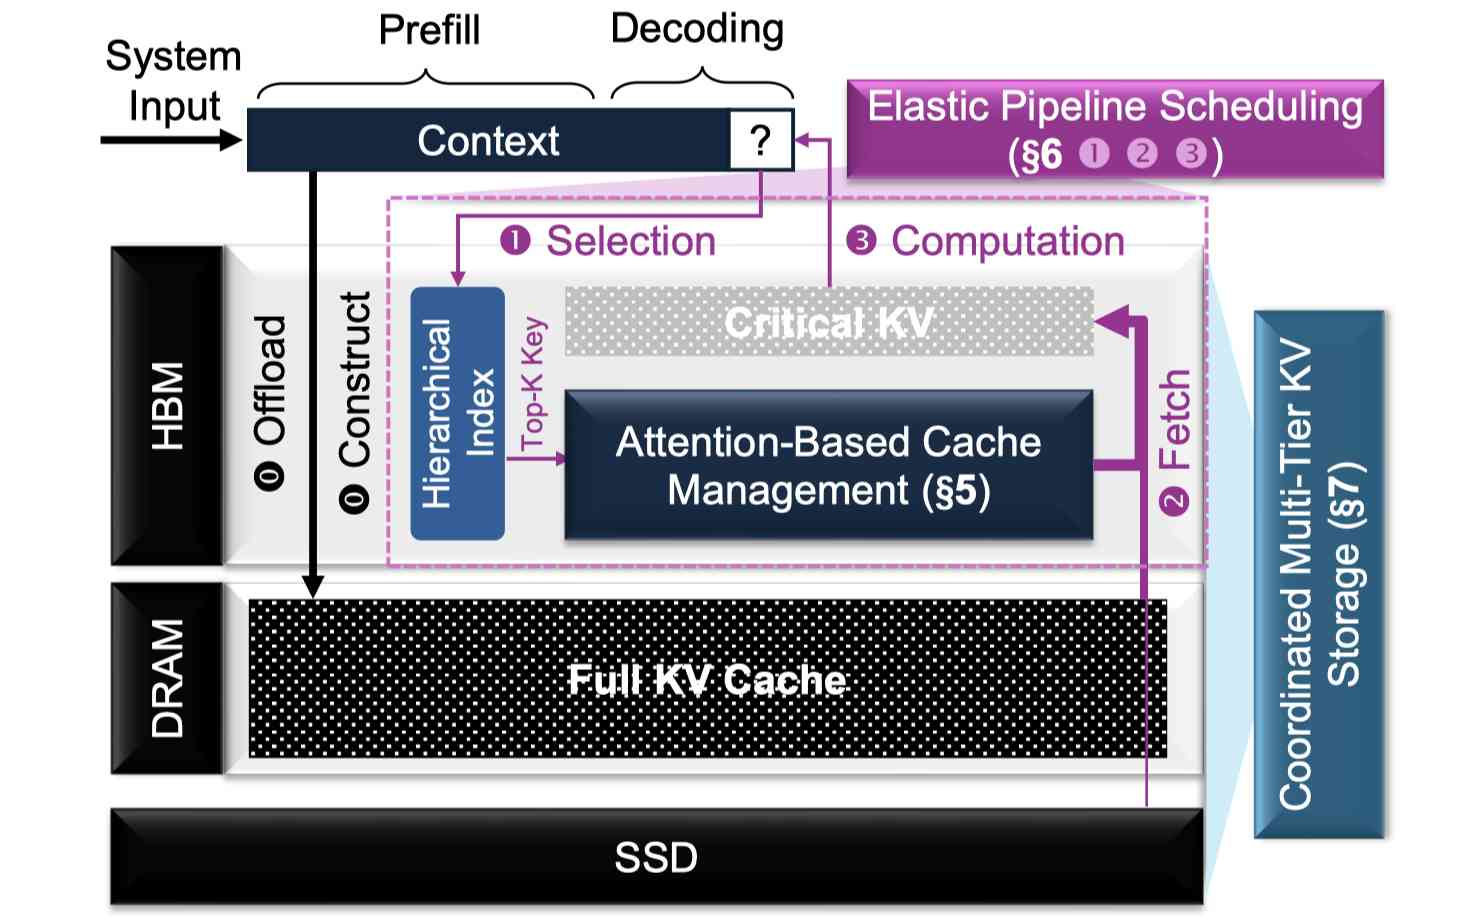
KVDrive: A Holistic Multi-Tier KV Cache Management System for Long ...

KV Cache Compression for Inference Efficiency in LLMs: A Review | AI ...
KV Cache Explained — Why LLM Inference Is Fast
Advertisement Space (336x280)

GEAR: An Efficient KV Cache Compression Recipe for Near-Lossless ...

KV Cache Reuse Is Quietly Reshaping LLM Inference Architecture | by ...

[논문 리뷰] Accelerating LLM Inference Throughput via Asynchronous KV Cache ...
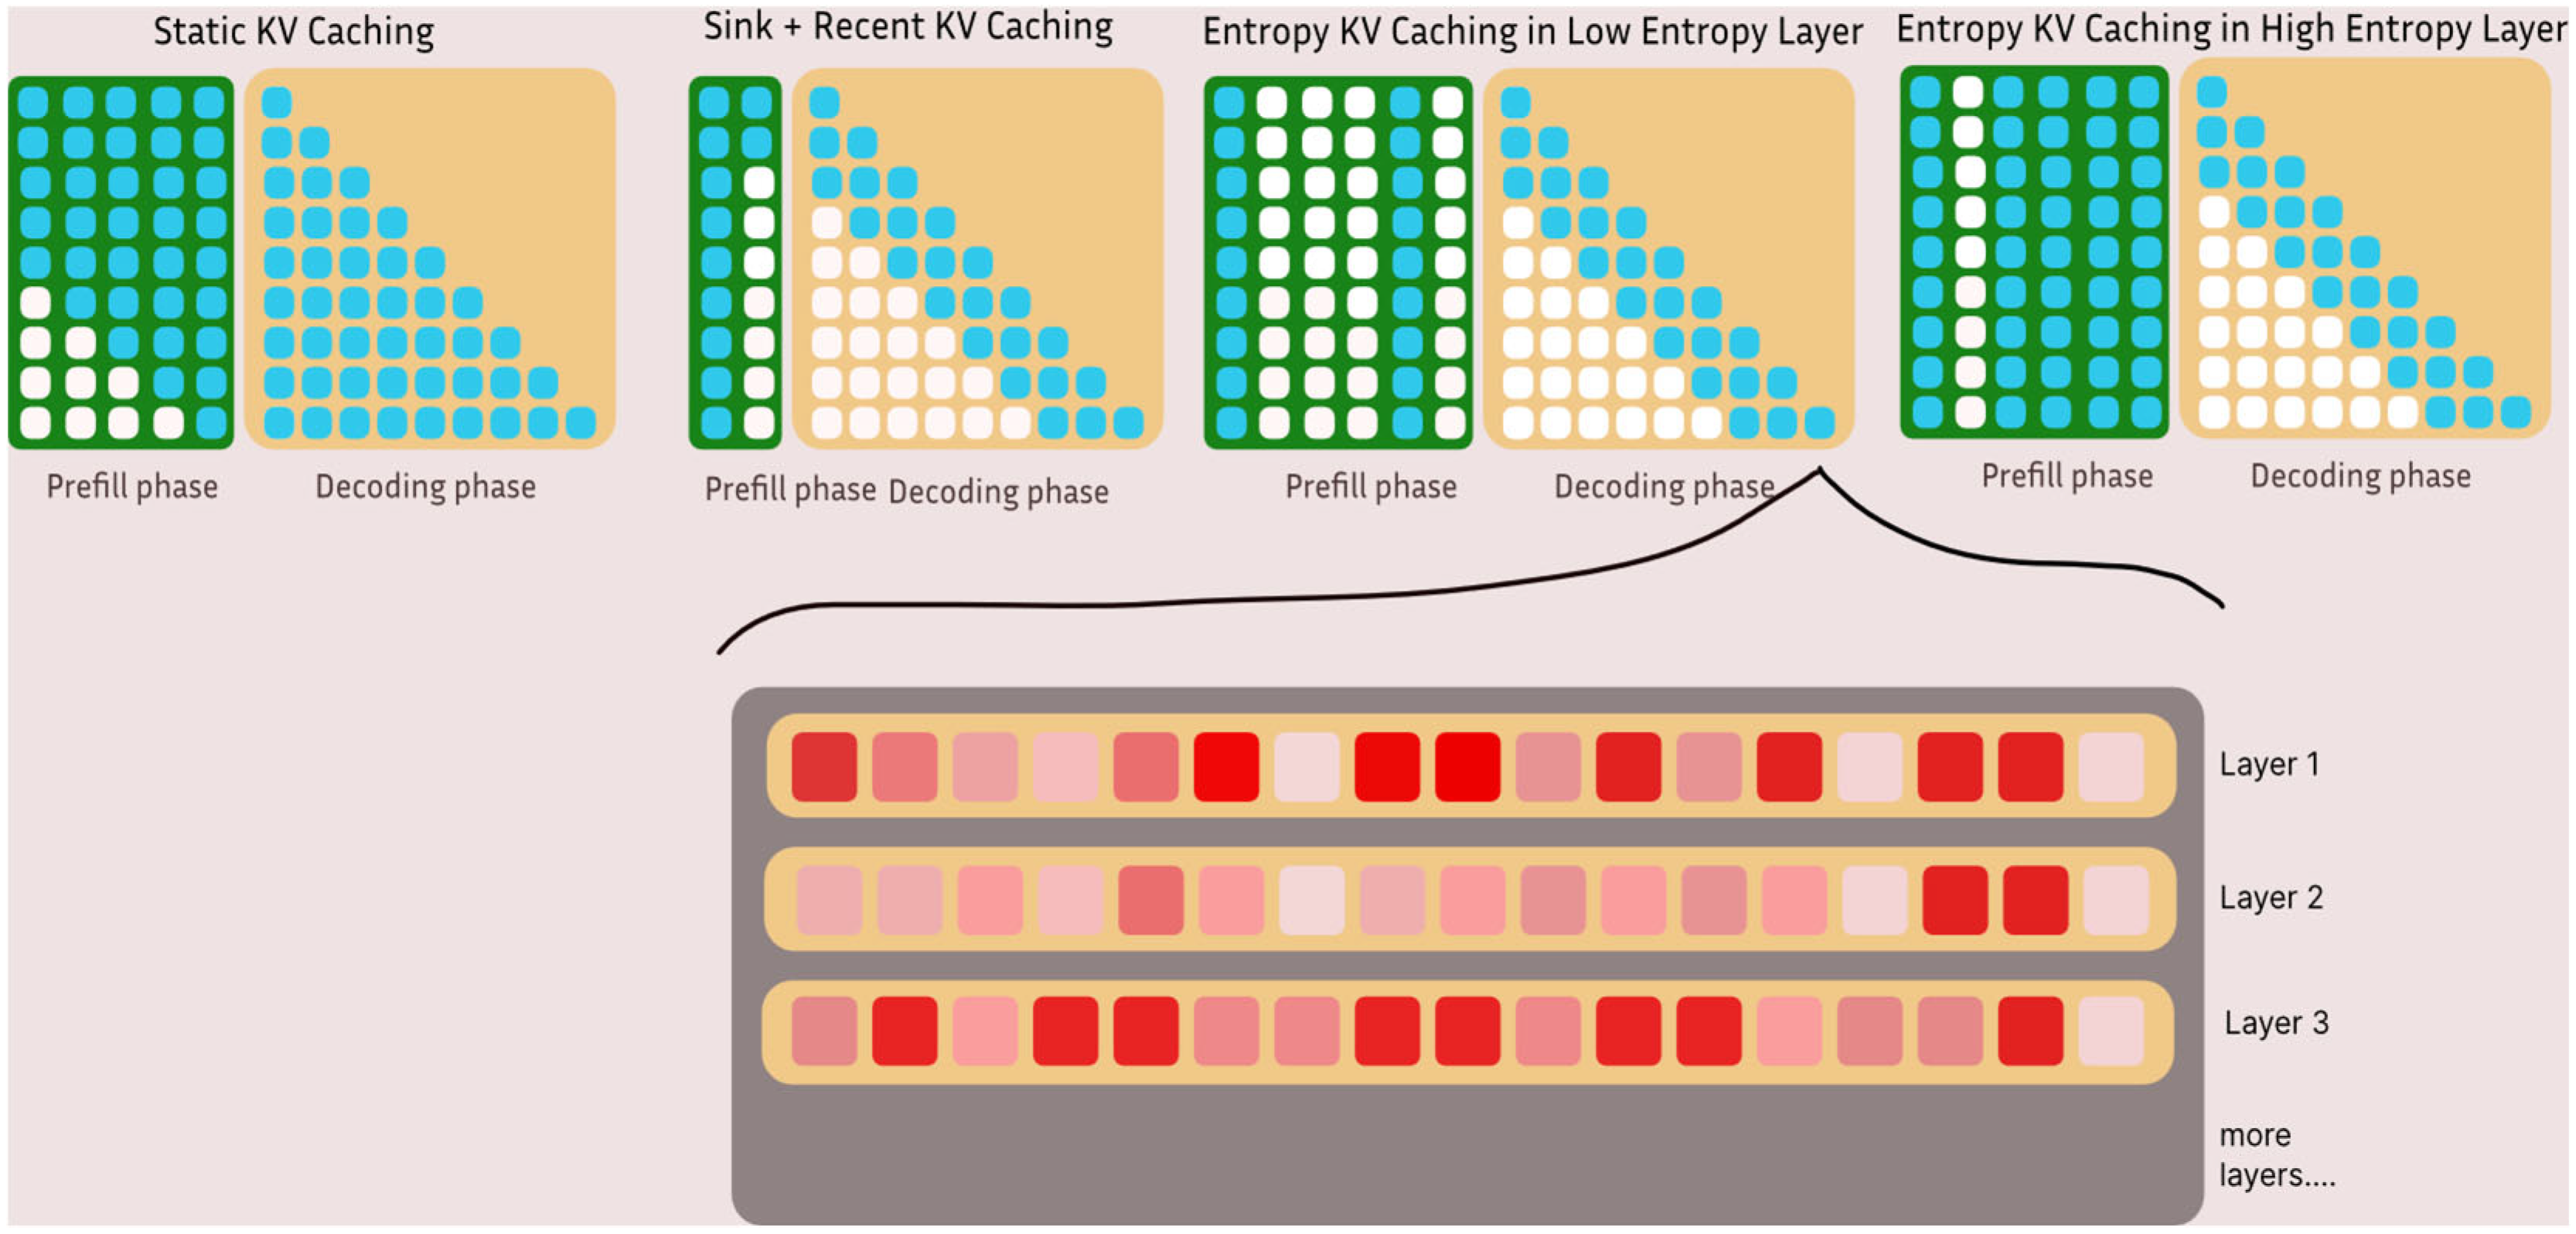
Entropy-Guided KV Caching for Efficient LLM Inference
GitHub - libriscv/kvmserver: Fast per-request isolation for Linux ...
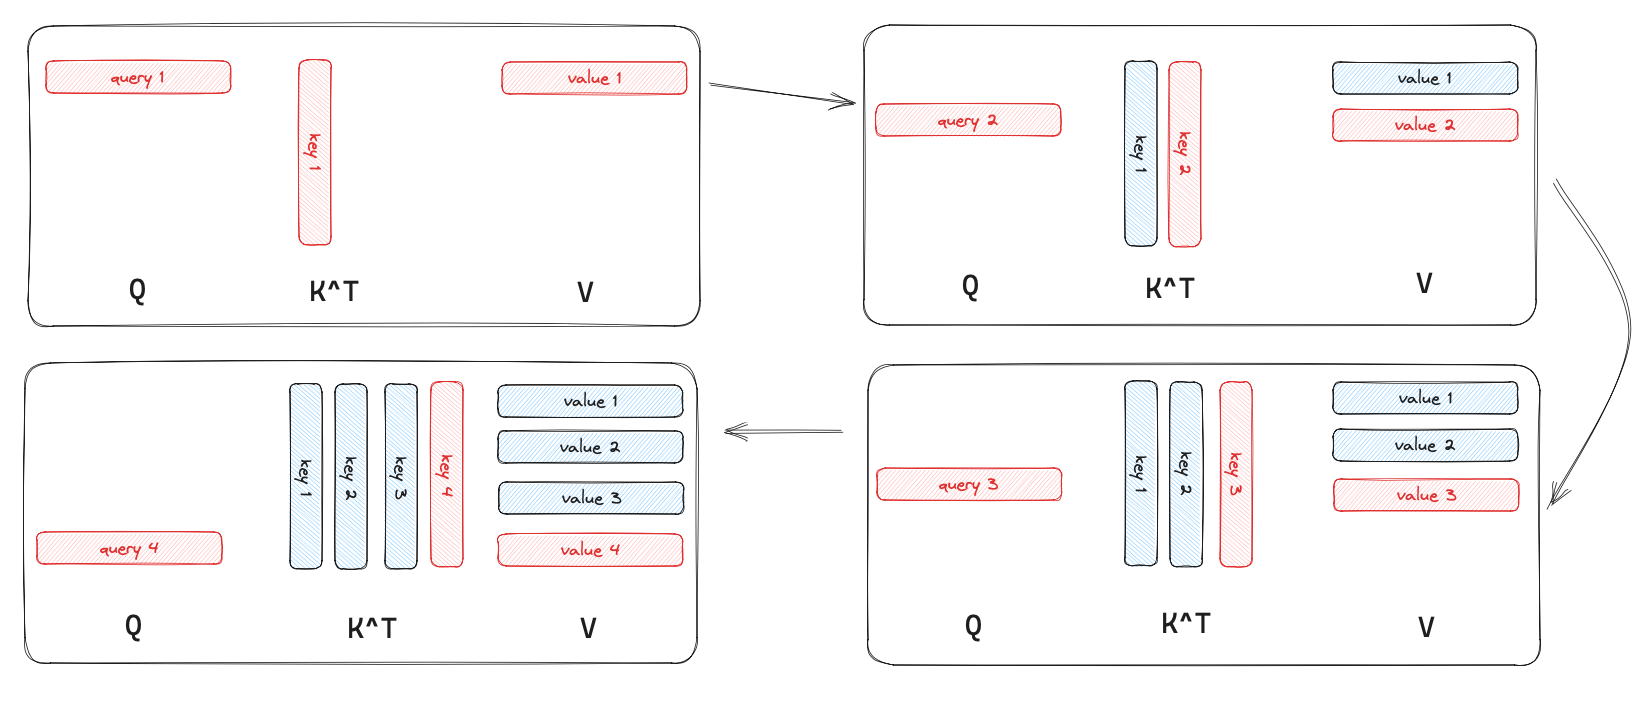
LLM inference optimization (1): KV Cache - MartinLwx's Blog