
Github Skyironlemonadellmserverai Local Llm Server With Gpu And Npu

GitHub - skyiron/lemonadeLLMserverAI: Local LLM Server with GPU and NPU ...

GitHub - skyiron/lemonadeLLMserverAI: Local LLM Server with GPU and NPU ...
GitHub - rebots-online/lemonade-npu: Local LLM Server with NPU ...

🍋 Local LLM Serving with GPU & NPU Acceleration – A Deep Dive into the ...
AMD's Lemonade: Open-Source Local AI Server Runs on GPU and NPU — Agent ...

Scale your Llm apps via cpu, gpu and npu with Lemonade! | Hisham Chowdhury
AMD Launches Lemonade: Open-Source Local LLM Server with GPU/NPU ...

Your AI, Your Rules: Running a Local LLM with GPU Acceleration on ...

AMD Lemonade Local LLM Server: GPU + NPU Inference on Consumer Hardware ...

Your AI, Your Rules: Running a Local LLM with GPU Acceleration on ...
Advertisement Space (300x250)
Lemonade vs Ollama — AMD-Optimized NPU Server vs Universal Local LLM ...

Lemonade by AMD: Open Source Local LLM Server with GPU/NPU Support | AI ...
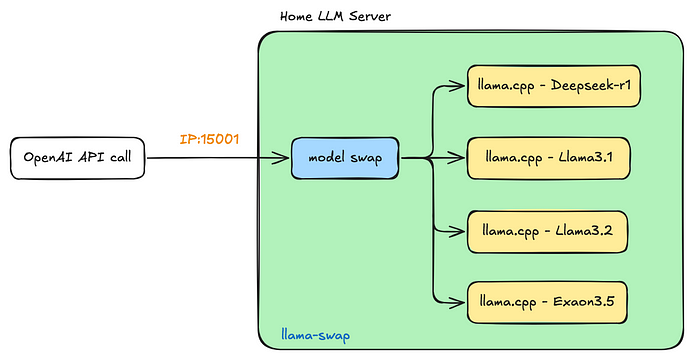
Efficient LLM Processing with Ollama on Local Multi-GPU Server ...
GitHub - gaztrabisme/llm-server: Local LLM inference server using llama ...
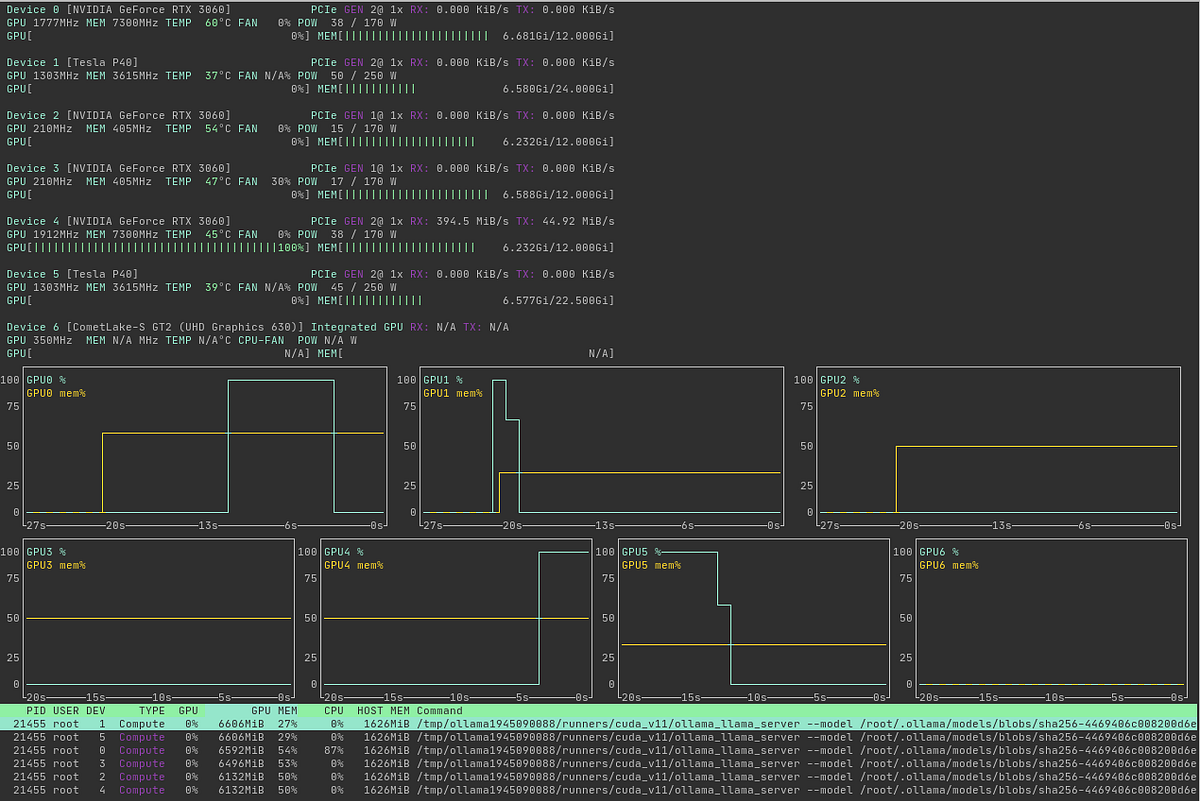
Tutorial: Build a Low-Cost Local LLM Server to Run 70B Models
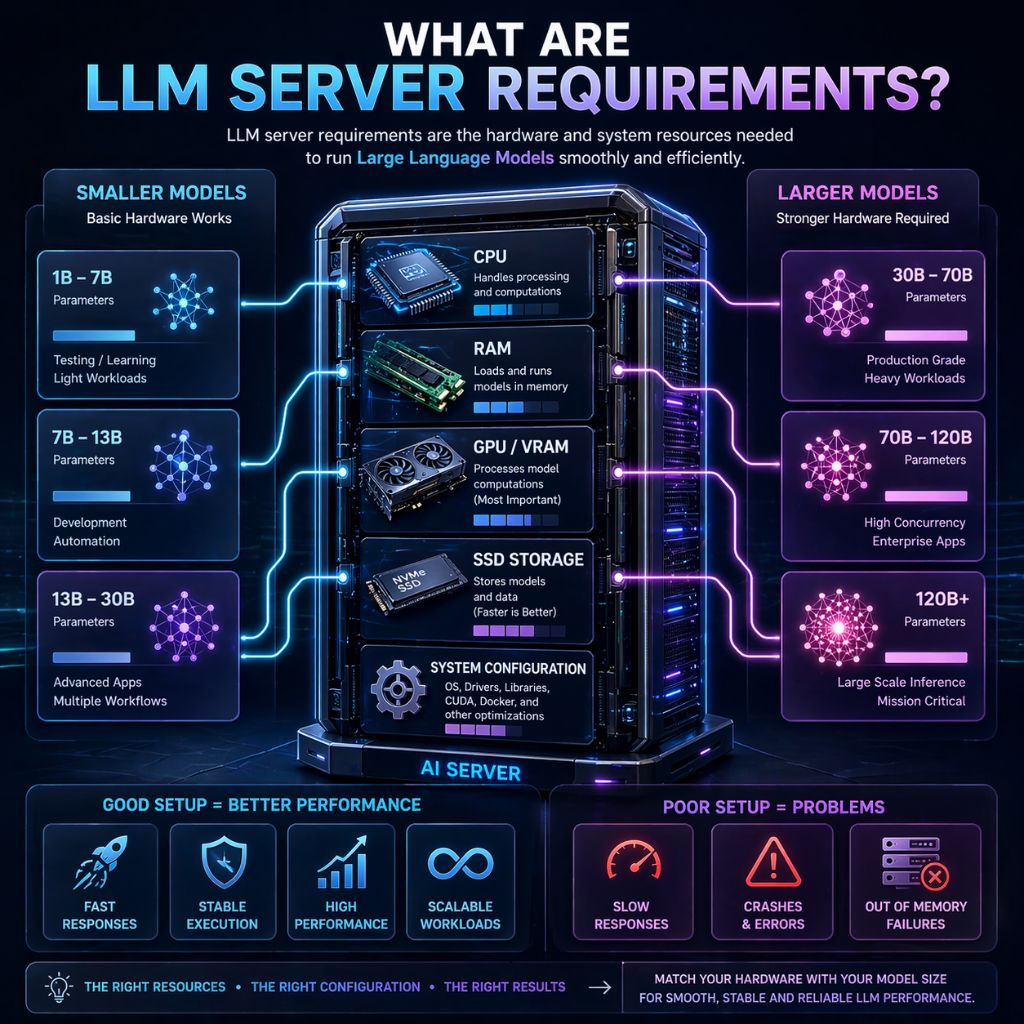
LLM Server Requirements: Hardware and Setup Guide
Local LLM vs Cloud GPU Cost: Paperspace, Lambda Labs, AWS Comparison 2026

Run Ollama with NVIDIA GPU in Proxmox VMs and LXC containers ...

GitHub - Universal-Invariant/AI-ipex-llm: Accelerate local LLM ...

Lemonade Server: How to Integrate with PEEL for Local LLM Support in ...
Advertisement Space (336x280)
Local LLM Server - Developer Tools App | MWM

LLM Deployment: A Guide to NVIDIA Triton Inference Server and TensorRT ...

Evaluating LLM Accuracy with lm-evaluation-harness for local server: A ...

Local LLM Server - Running LLMs Locally | LM Studio Docs

Private AI Assistant with Willow and a Local Large Language Model
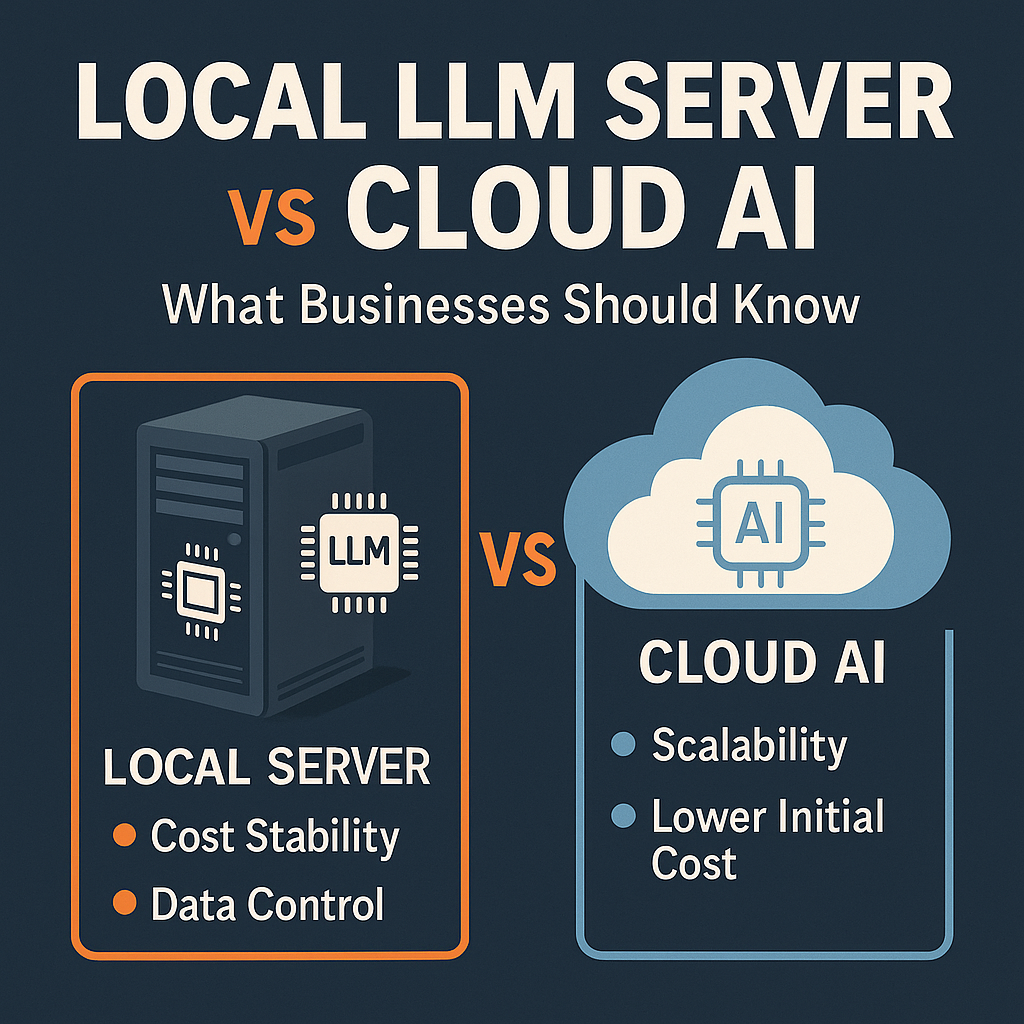
Local LLM Server vs Cloud AI: What Businesses Should Know

GitHub - thomas-steinberger-dev-ai/INTEL_ipex-llm: Accelerate local LLM ...

Lemonade v10.3: Run Local LLMs, Image Gen, and Speech on Your Own GPU ...

GitHub - Universal-Invariant/AI-ipex-llm: Accelerate local LLM ...

GitHub - Universal-Invariant/AI-ipex-llm: Accelerate local LLM ...
Advertisement Space (336x280)

Abusing an Unauthenticated Local Server to Overwrite LLM Wiki

Building Blue Fairy, our local LLM server - Japeto Labs
AMD's Lemonade: Local LLM Server That Actually Works on Radeon — Agent Wars

Automating Security Alerts with Local LLM Integration | by Manusiahiu ...

How to Run Open-Source LLMs on a Cloud Server with a GPU - MainWP ...

How to launch an LLM API server with minimal coding - TechTalks