
Local Llm Serving With Gpu Npu Acceleration A Deep Dive Into The

🍋 Local LLM Serving with GPU & NPU Acceleration – A Deep Dive into the ...

Your AI, Your Rules: Running a Local LLM with GPU Acceleration on ...

Introducing Lemonade Server: Local LLM Serving with GPU and NPU ...
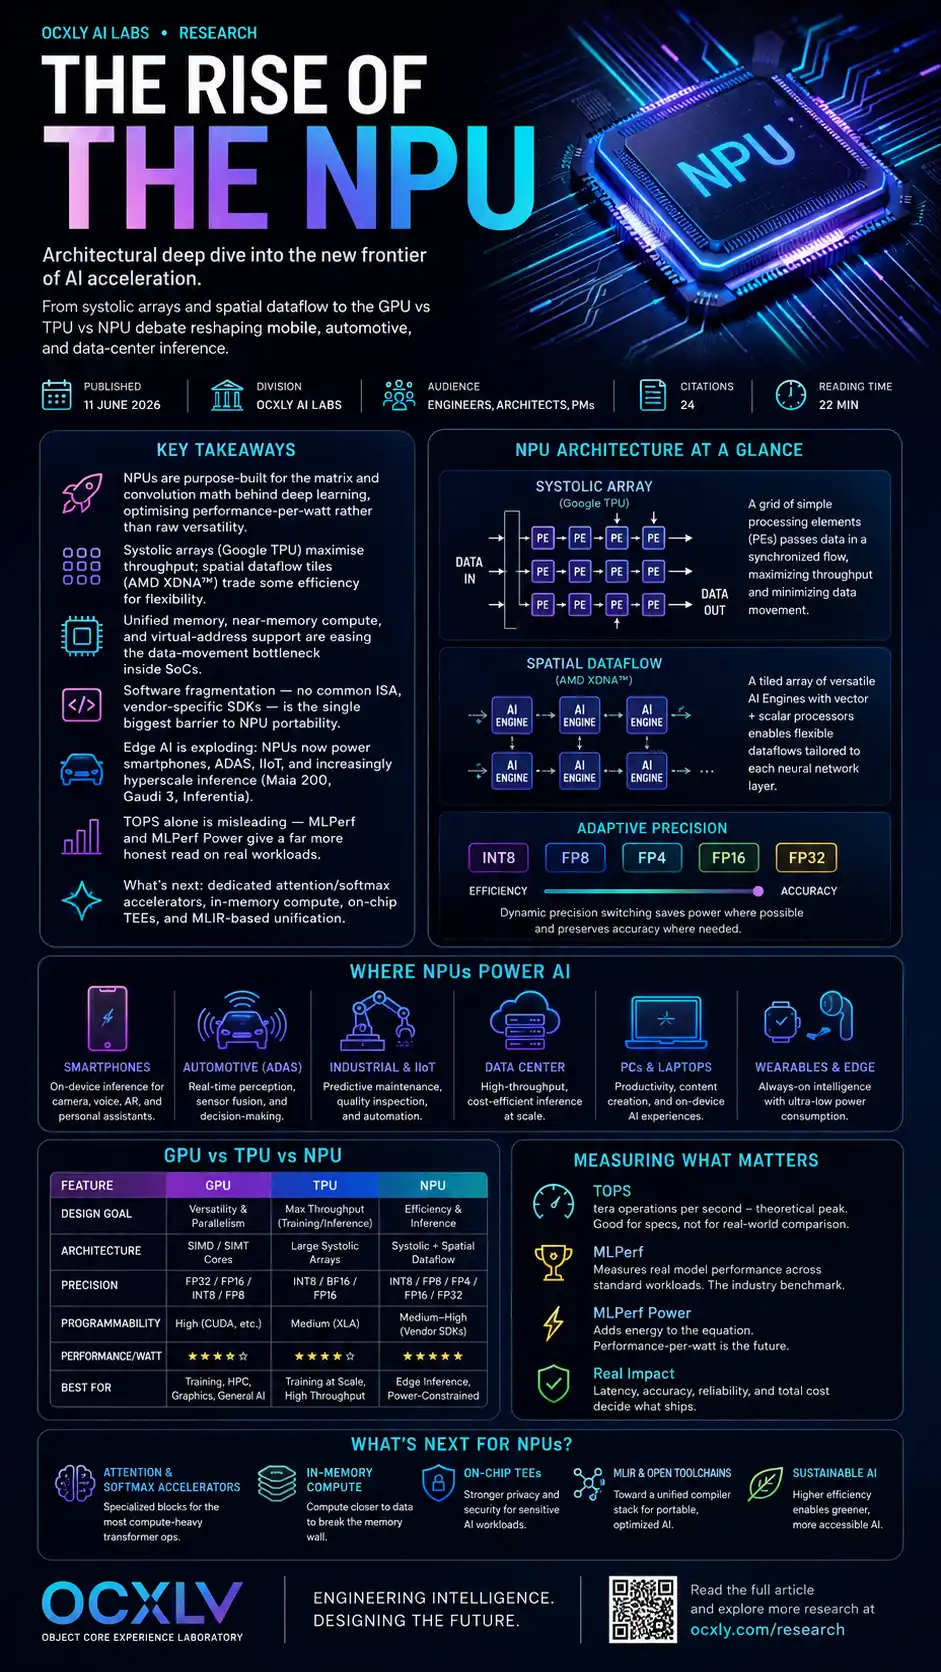
The Rise of the NPU — Architectural Deep Dive into AI Acceleration ...

From KV Caching to PagedAttention: A Deep Dive into GPU Memory in LLM ...

Your AI, Your Rules: Running a Local LLM with GPU Acceleration on ...

Optimizing NVIDIA GPU Utilization for LLM Inference: A Deep Dive for ...

GitHub - skyiron/lemonadeLLMserverAI: Local LLM Server with GPU and NPU ...
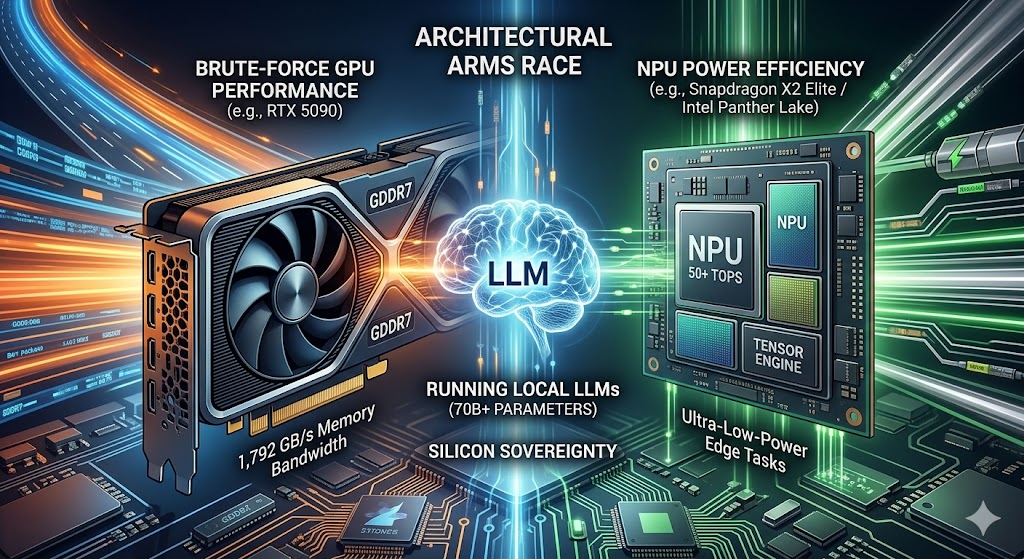
NPU vs GPU Local LLM Benchmarking (2026)
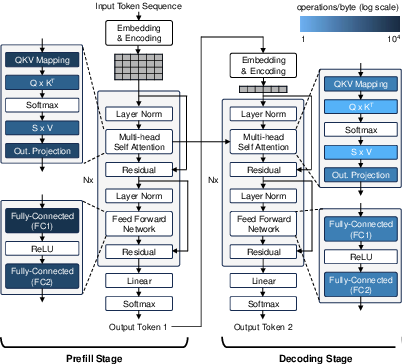
Figure 1 from LIA: A Single-GPU LLM Inference Acceleration with ...
Advertisement Space (300x250)
GPU and VRAM for Local LLM Acceleration
NPU support for LLM acceleration without gpu · nomic-ai gpt4all ...

LIA: A Single-GPU LLM Inference Acceleration with Cooperative AMX ...

Evaluating LLM Accuracy with lm-evaluation-harness for local server: A ...
Lemonade by AMD: a fast and open source local LLM server using GPU ...

AMD Lemonade Local LLM Server: GPU + NPU Inference on Consumer Hardware ...

Local LLM on NVIDIA GPU vs Cloud API: A Real Cost Analysis - DEV Community

Efficiently Scale LLM Training Across a Large GPU Cluster with Alpa and ...
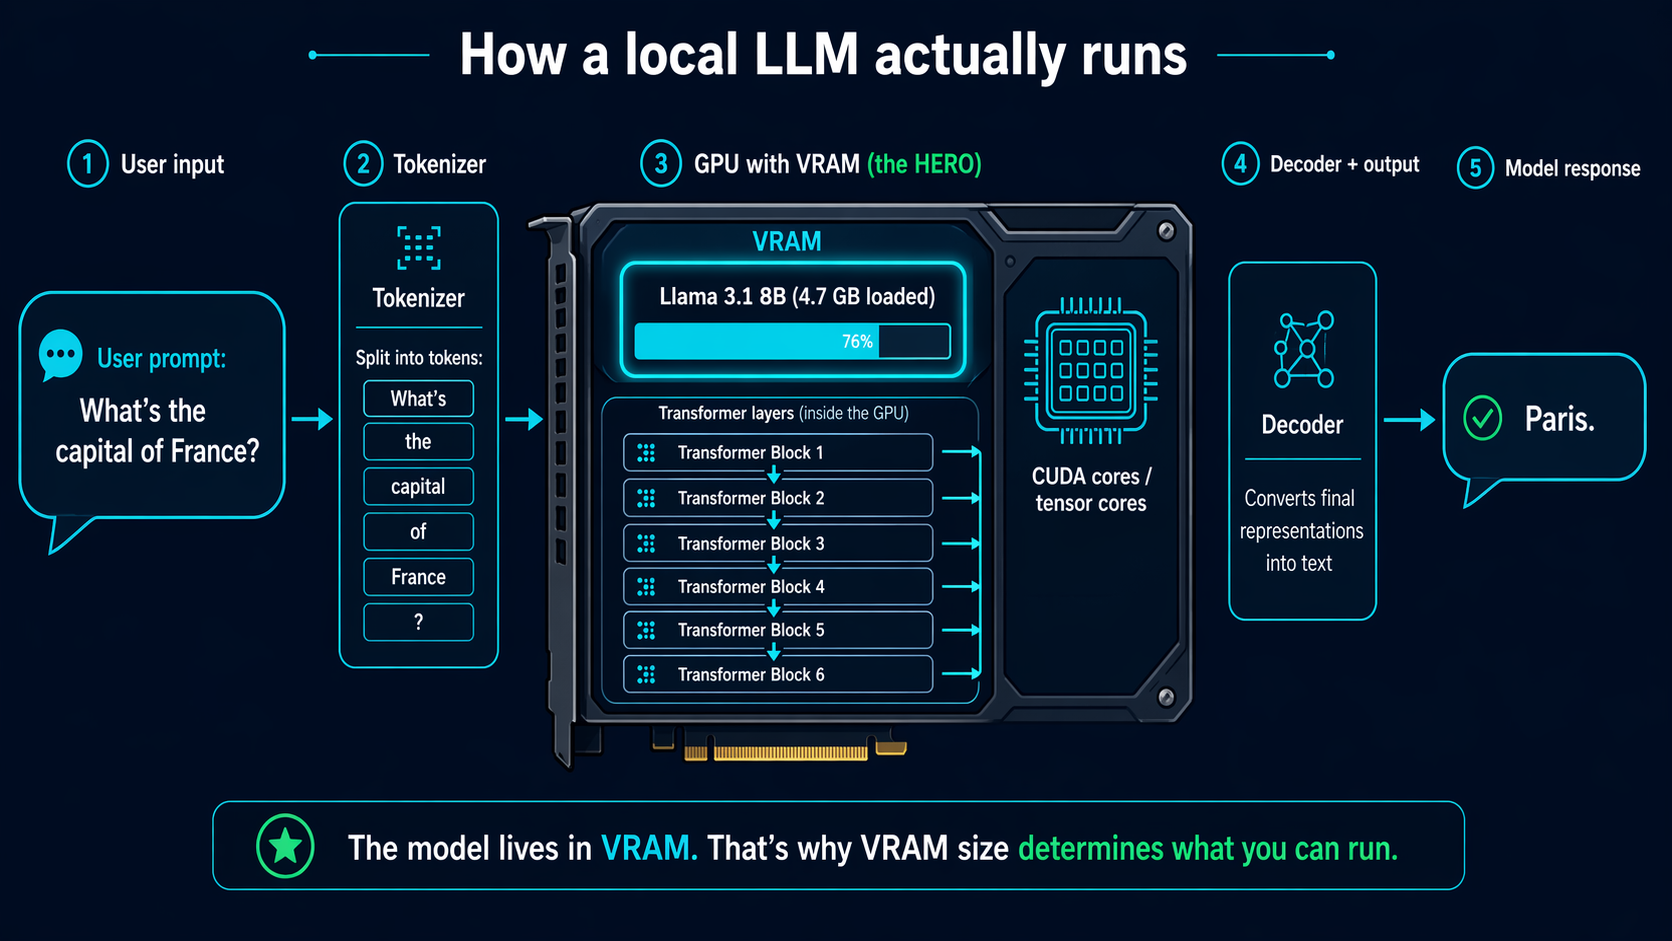
Can Your PC Run a Local LLM? Free Hardware Checker — GPU + RAM (2026 ...

Predictable LLM Serving on GPU Clusters | AI Research Paper Details
Advertisement Space (336x280)
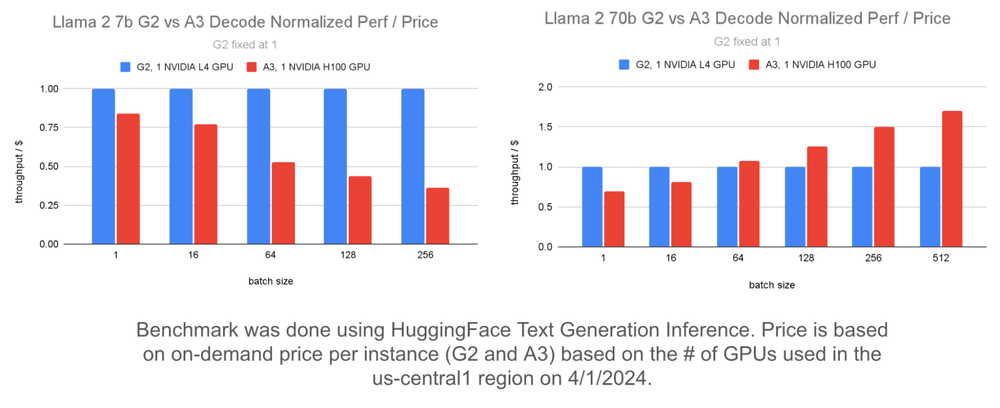
Maximize your LLM serving throughput for GPUs on GKE — a practical ...
AMD Launches Lemonade: Open-Source Local LLM Server with GPU/NPU ...

GPU vs NPU on Deep learning – Lechuck Park

LLM Serving with NPU: Re-engineered, Built for Scale and Efficiency ...

Intel Meteor Lake Technical Deep Dive - Intel AI Boost & NPU | TechPowerUp
LLM Local vs GPU na Nuvem: Comparativo de Custos Paperspace, Lambda ...
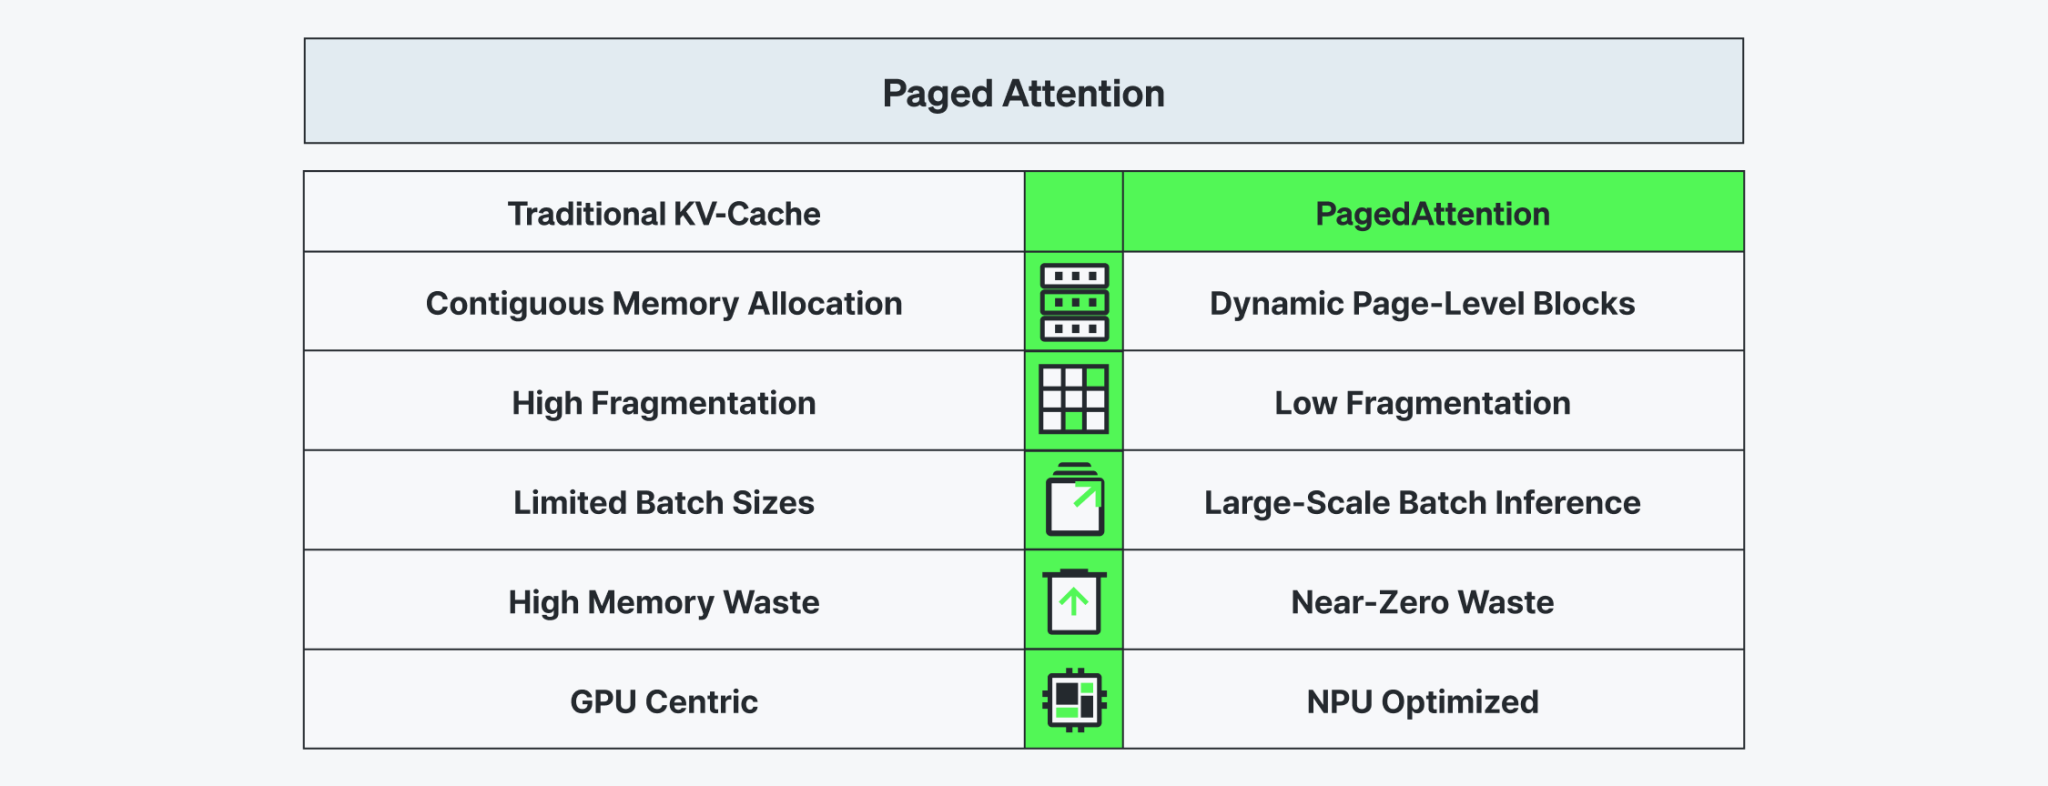
LLM Serving with NPU: Re-engineered, Built for Scale and Efficiency ...

The Imperative: Why LLM Serving Engine Choice Defines Performance ...

NEO: Saving GPU Memory Crisis with CPU Offloading for Online LLM Inference
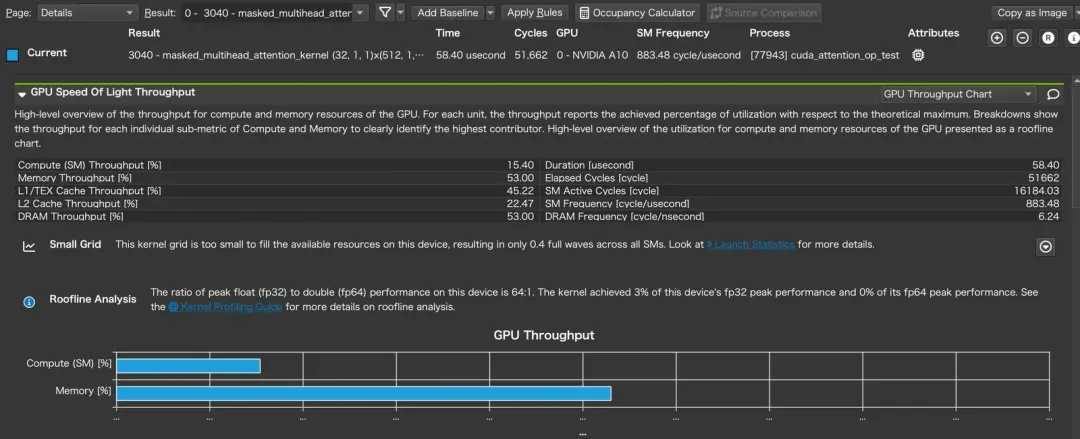
LLM Inference Acceleration: GPU Optimization for Attention in the ...
Advertisement Space (336x280)
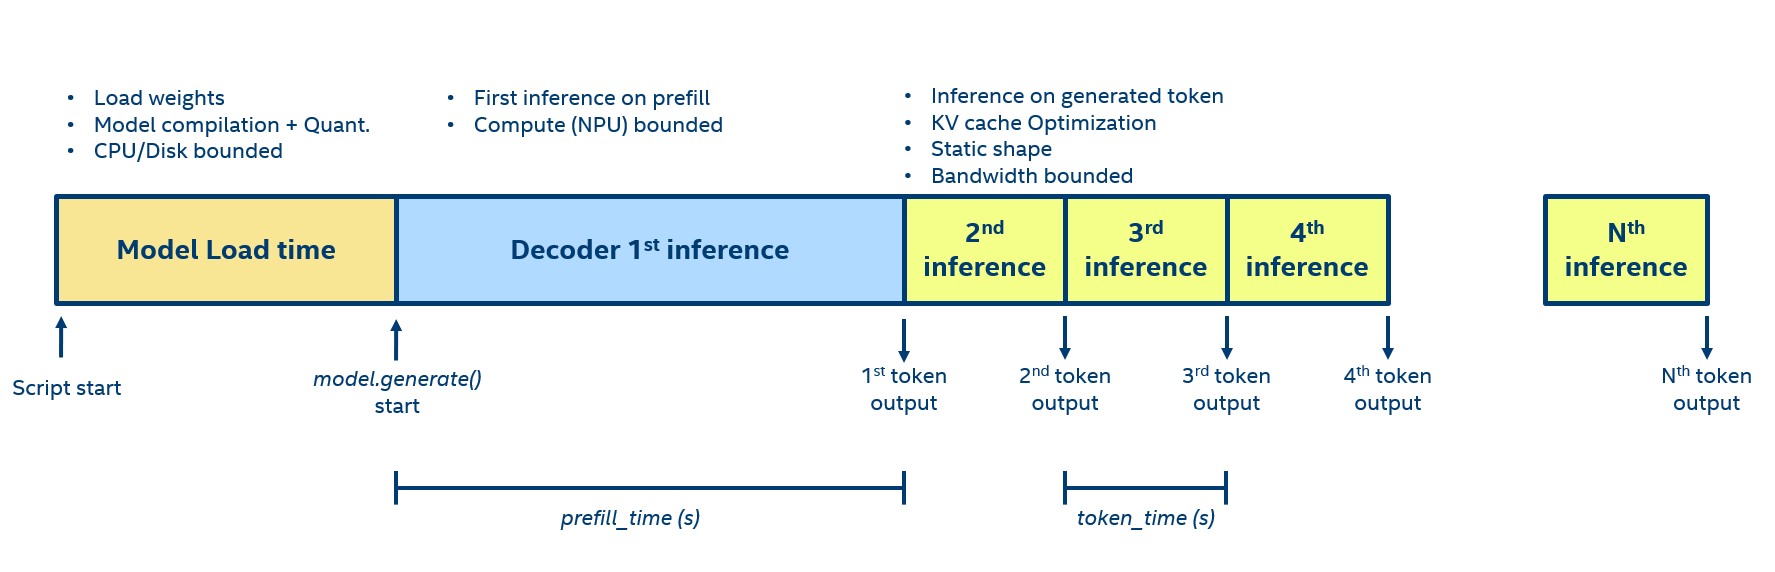
Decoding LLM performance — Intel® NPU Acceleration Library documentation

Announcing GPU and LLM Model Serving | Databricks Blog

Power of GPU Acceleration in Deep Learning: Elevating Model Training ...
Lemonade Review: AMD's Answer to Local AI Serving Brings NPU ...

Intel Meteor Lake Technical Deep Dive - Intel AI Boost & NPU | TechPowerUp

Lemonade by AMD: Open Source Local LLM Server with GPU/NPU Support | AI ...