
Github Tensorsenseinferenceengine Efficient Vlm Inference
GitHub - tensorsense/inference_engine: Efficient VLM inference

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...
Advertisement Space (300x250)
GitHub - intel/ai-visual-inference-samples: Intel® AI Visual Inference ...
inference code and inference weight · Issue #19 · om-ai-lab/VLM-R1 · GitHub

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Efficient Large Language Model Inference · @toytag.net
GitHub - shishishu/LLM-Inference-Acceleration: LLM Inference with Deep ...
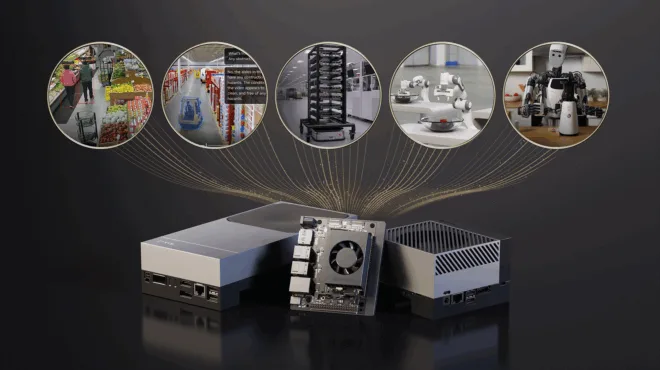
Accelerating LLM and VLM Inference for Automotive and Robotics with ...
Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

GitHub - Theia-4869/FasterVLM: Official code for paper: [CLS] Attention ...
Advertisement Space (336x280)
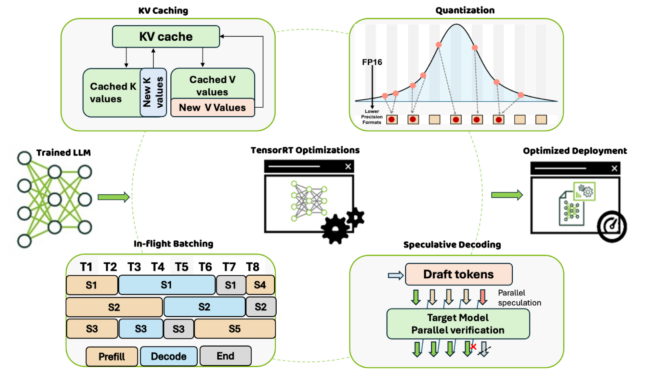
Boost Llama 3.3 70B Inference Throughput 3x with NVIDIA TensorRT-LLM ...

NVIDIA TensorRT Edge-LLM 加速汽车与机器人领域的 LLM 和 VLM 推理 - NVIDIA 技术博客
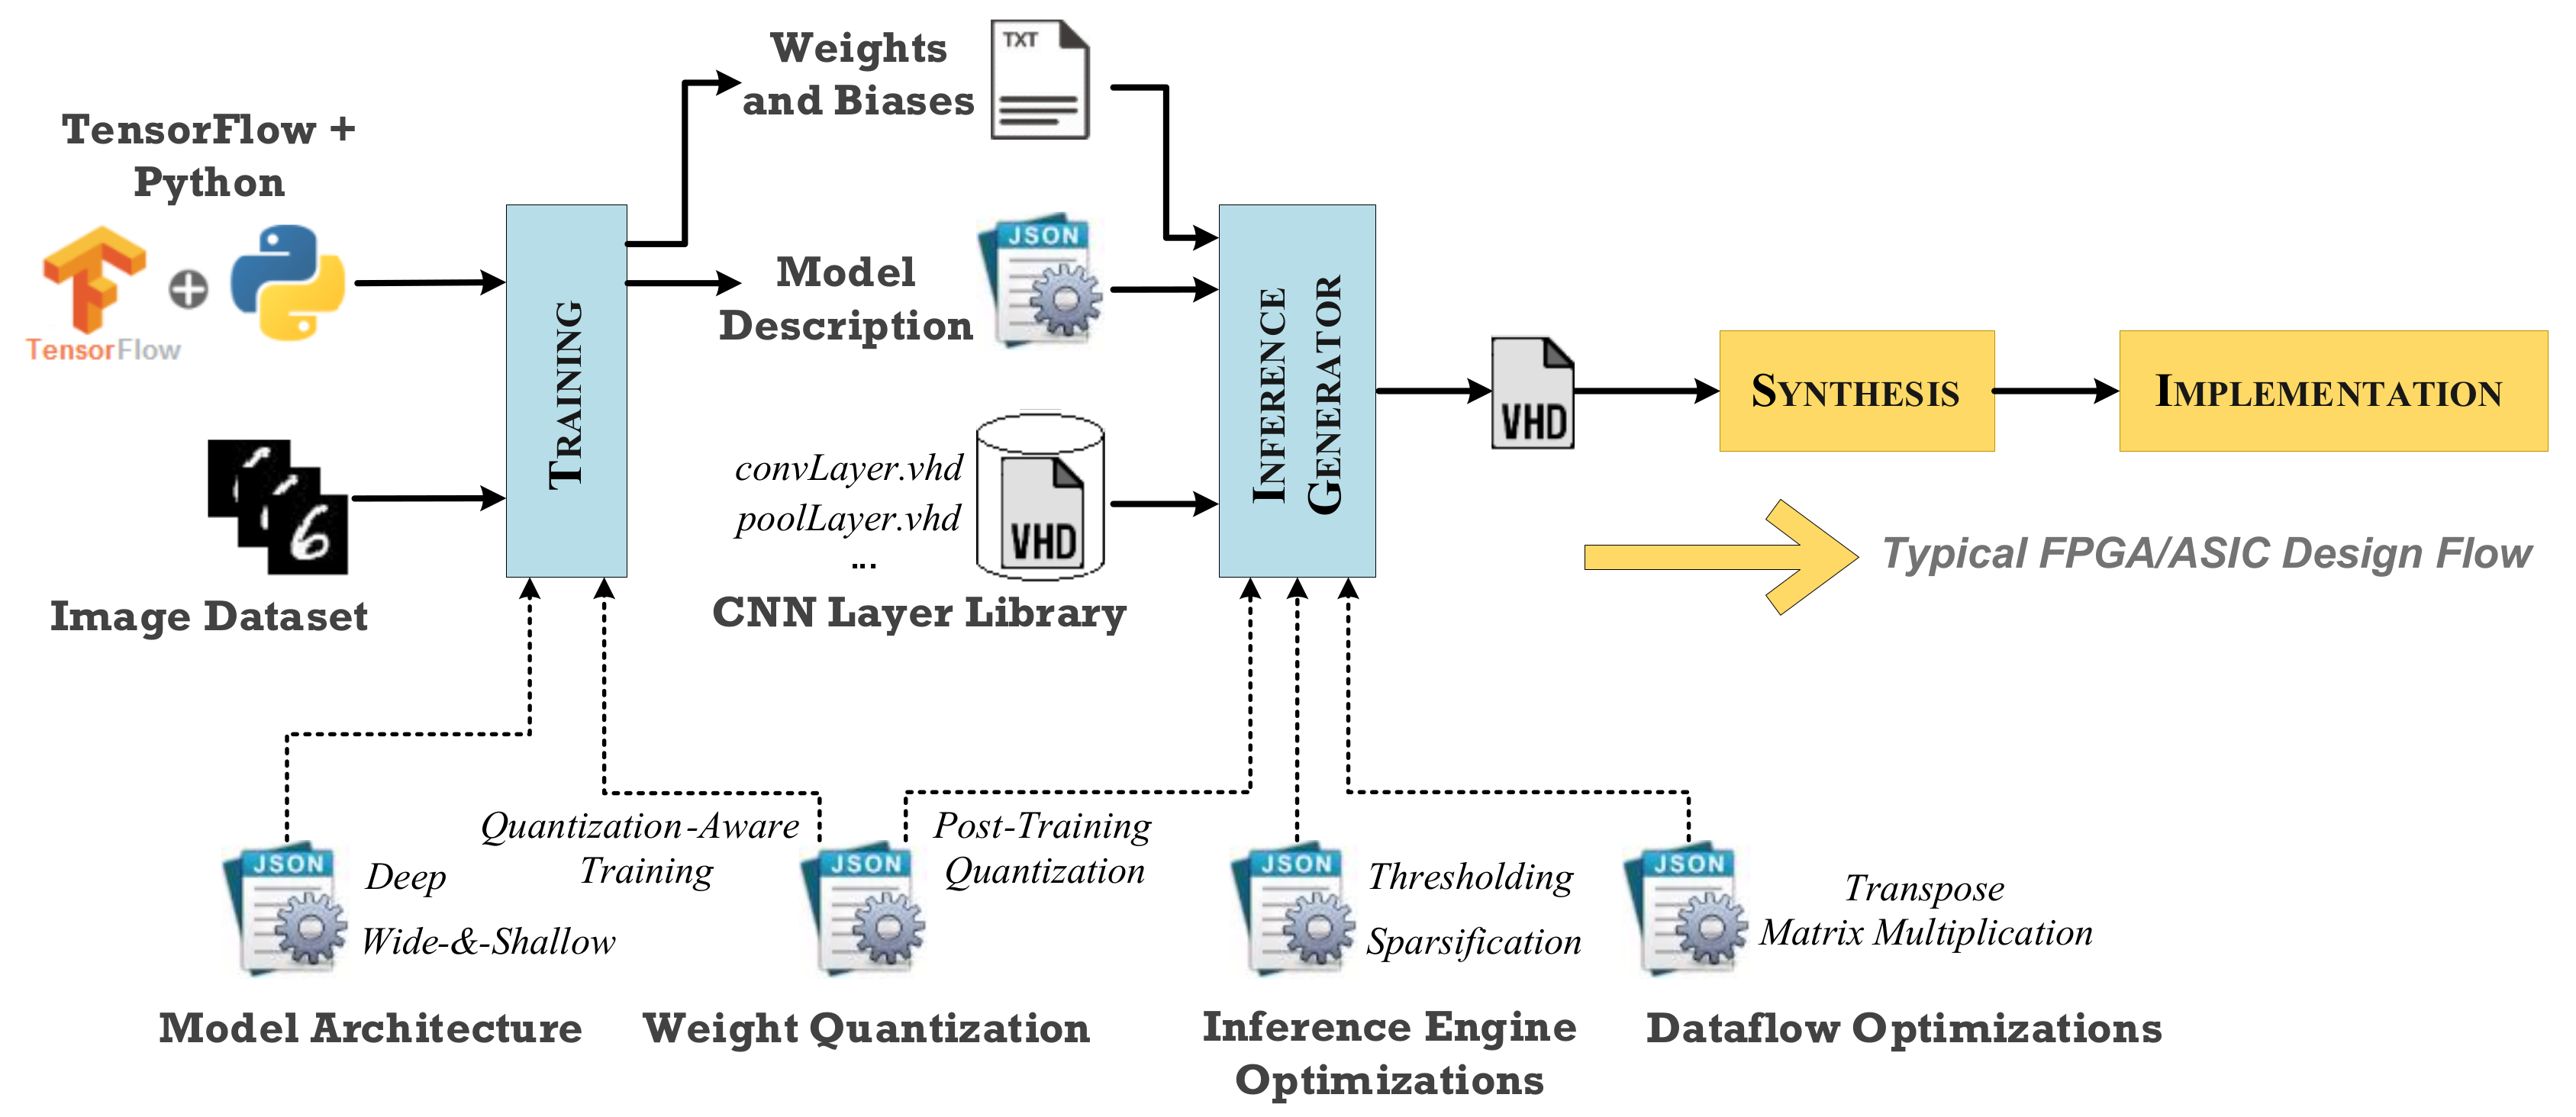
Tensorflow Deep Learning Inference – DGAM
Optimizing Inference on Large Language Models with NVIDIA TensorRT-LLM ...
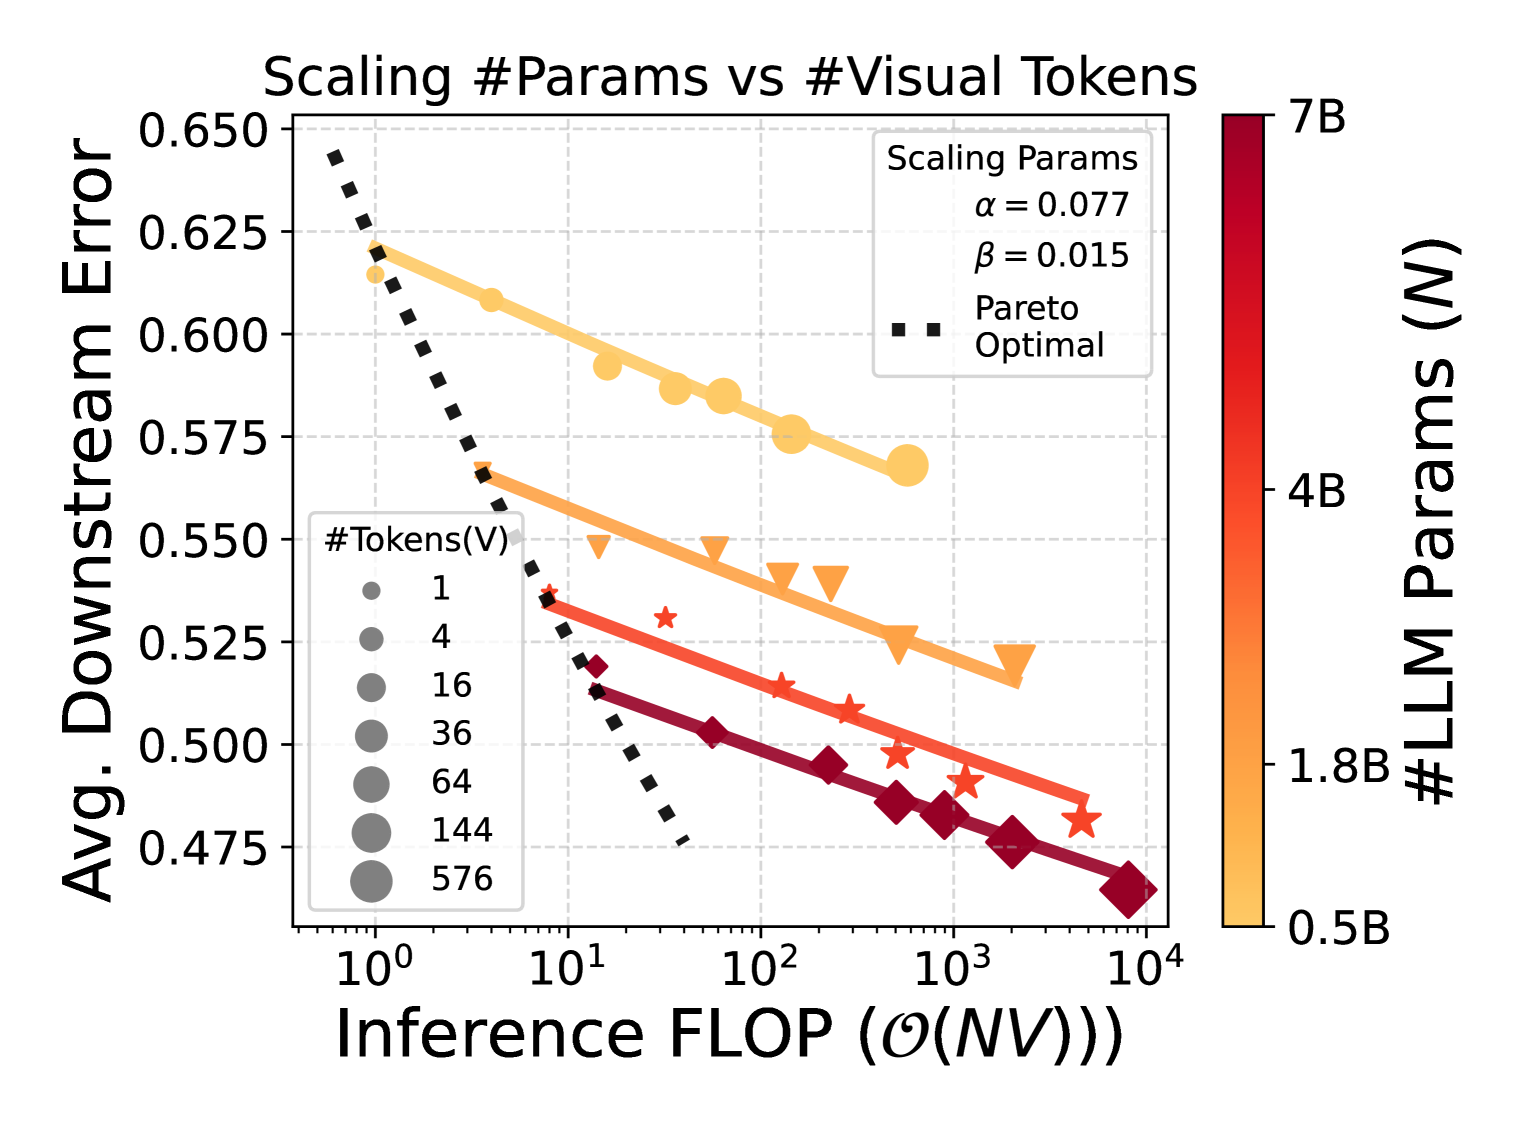
Inference Optimal VLMs Need Only One Visual Token but Larger Models ...
GitHub - process-cxr/vllm-inference: A high-throughput and memory ...
GitHub - rhythm98/vllm-inference: A high-throughput and memory ...
Best LLM Inference Engines (2026): vLLM, SGLang & TensorRT-LLM | Yotta Labs
GitHub - os01/ai-vllm-fast-inference: A high-throughput and memory ...
LLM Inference Benchmarking: Performance Tuning with TensorRT-LLM ...
Advertisement Space (336x280)
GitHub - llm-d/llm-d-inference-sim: A lightweight, configurable, and ...

Streamlining AI Inference Performance and Deployment with NVIDIA ...
GitHub - modelize-ai/LLM-Inference-Deployment-Tutorial: Tutorial for ...
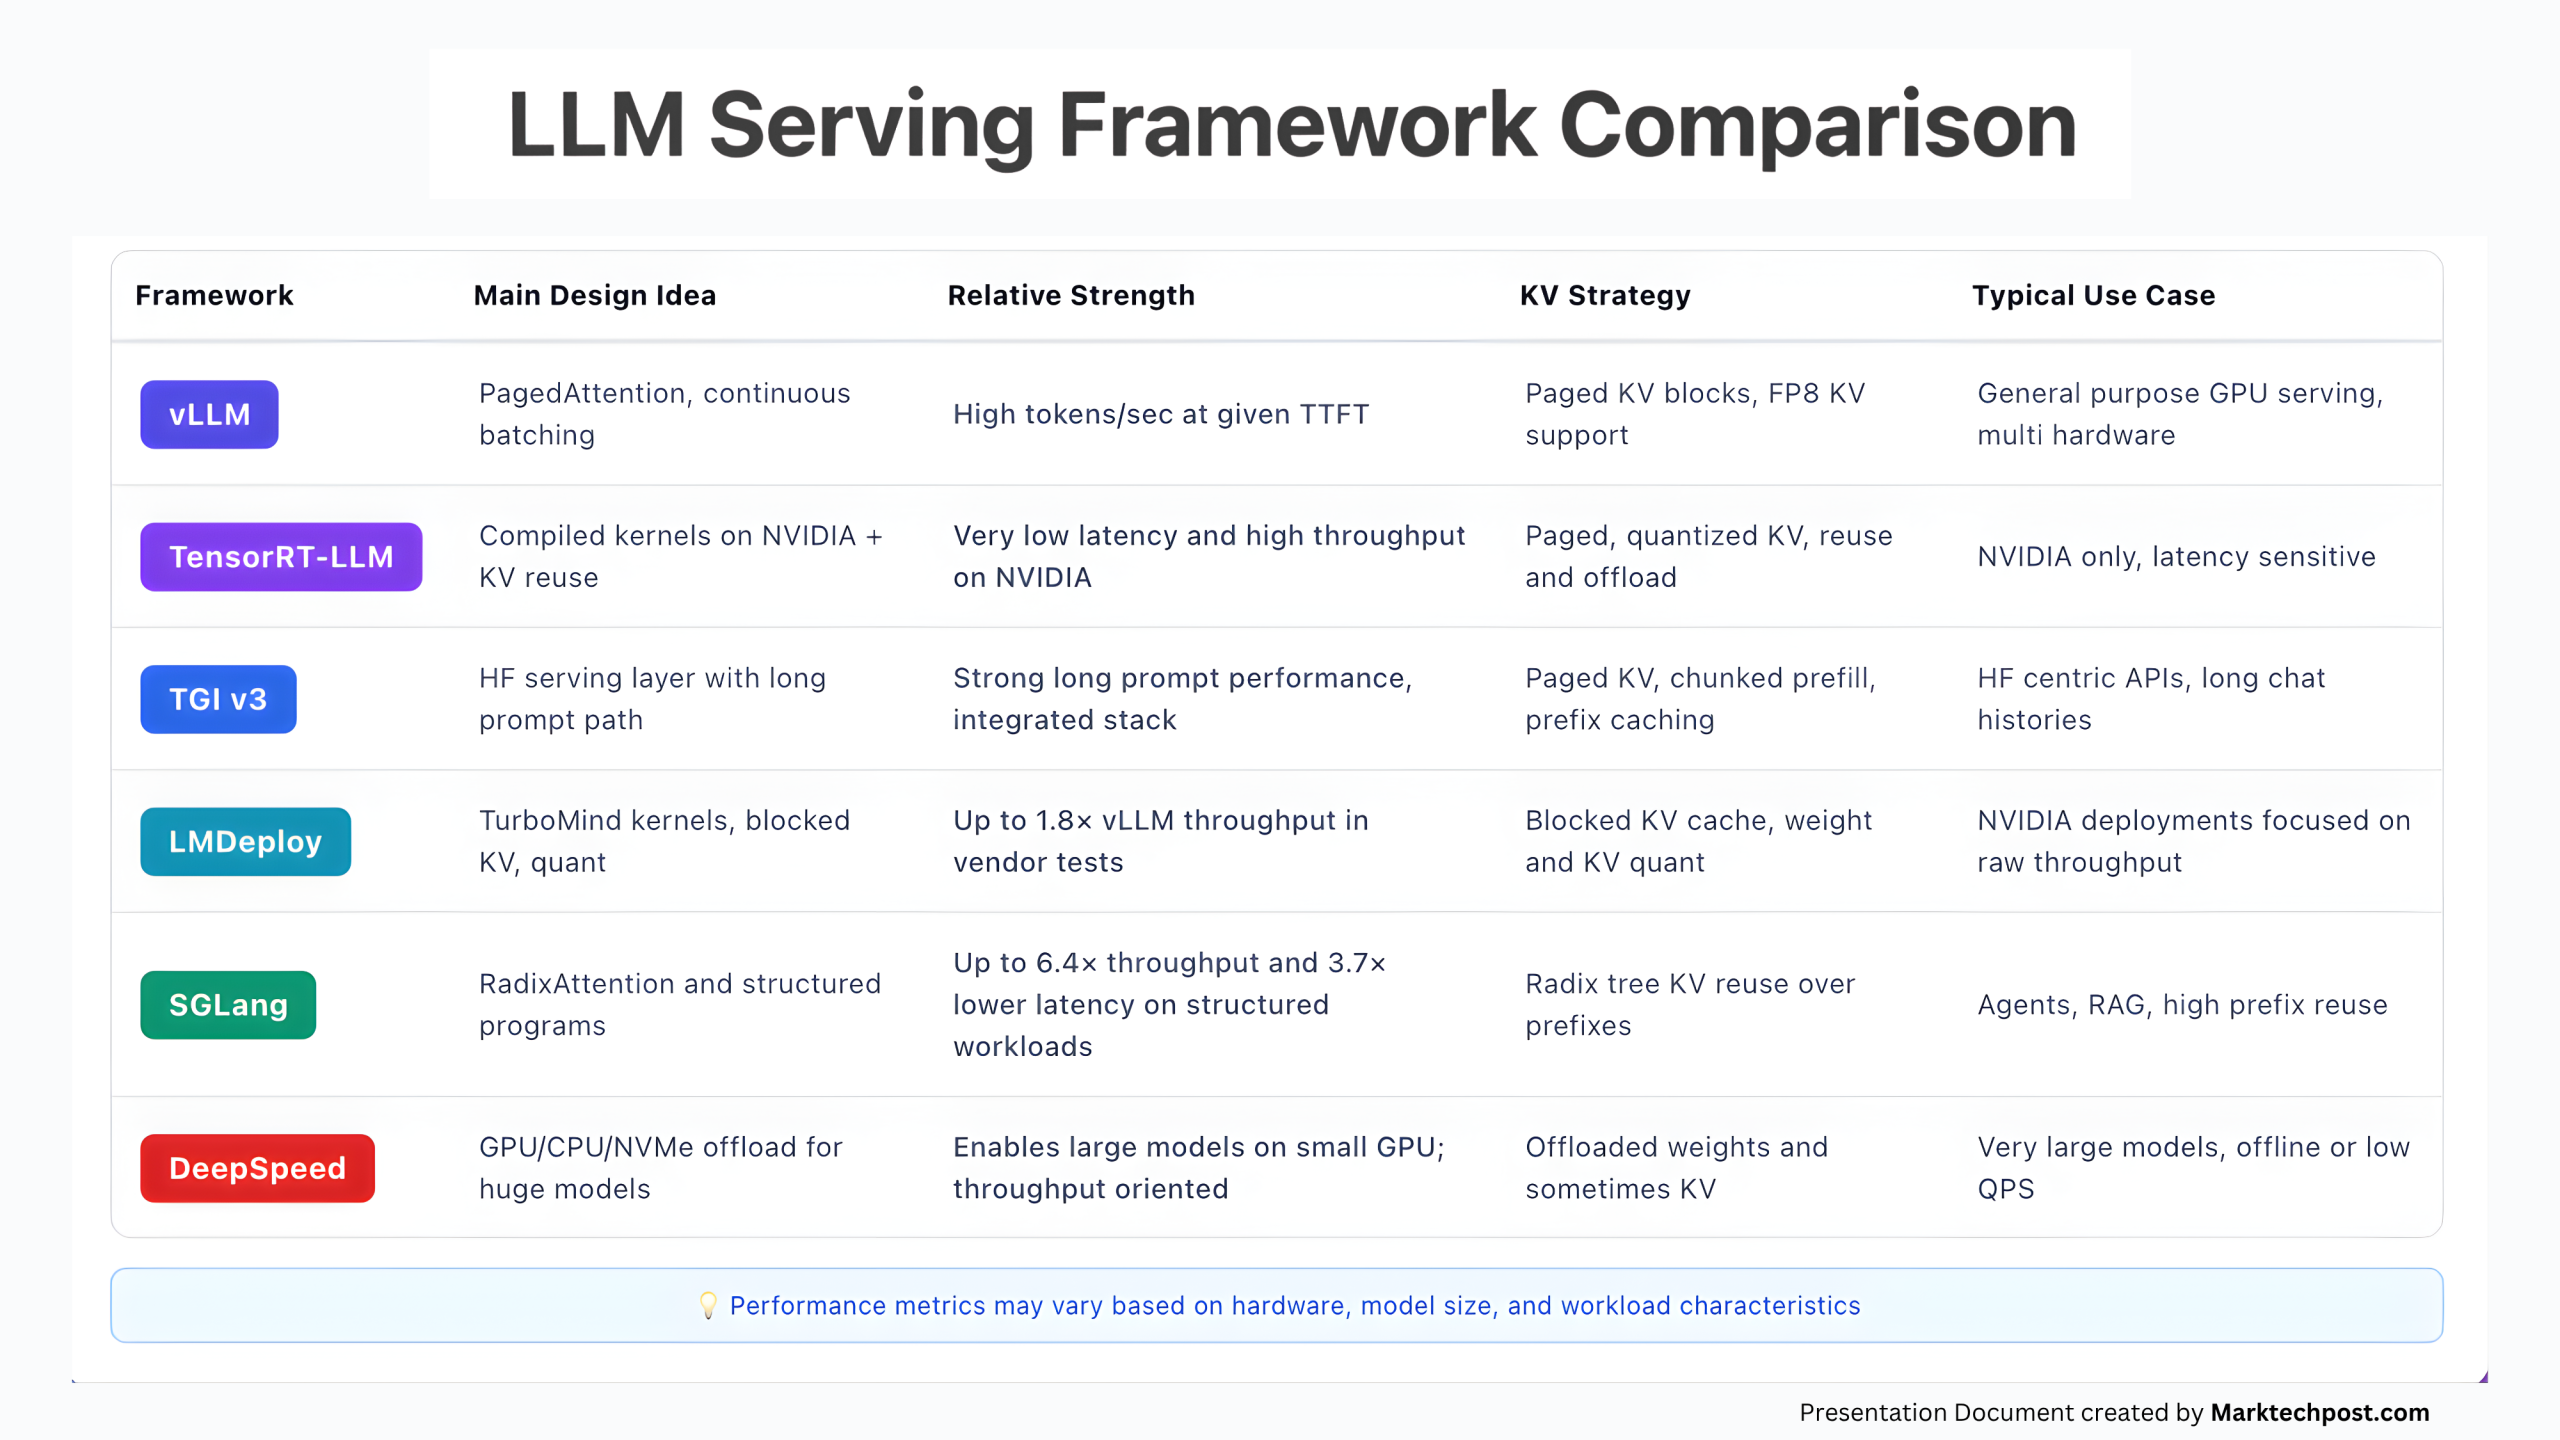
Comparing the Top 6 Inference Runtimes for LLM Serving in 2025 ...
GitHub - hejunhao2024/Efficient-LLM-Inference · GitHub
GitHub - HexaForge-1/highperf-ai-ml-inference: High-perf C++ AI/ML ...