
Accelerating Llm And Vlm Inference For Automotive And Robotics With

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...
Advertisement Space (300x250)

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...
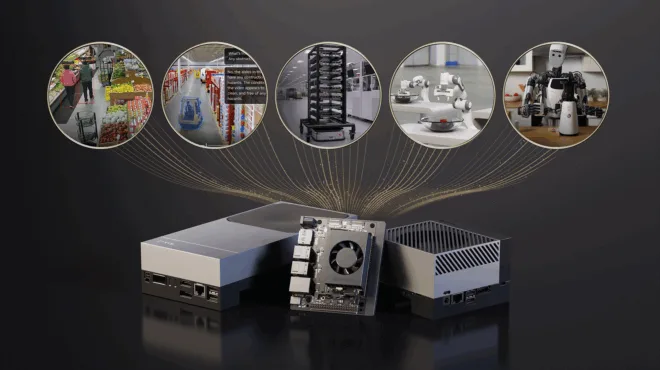
Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerate AI Inference for Edge and Robotics with NVIDIA Jetson T4000 ...
Accelerating LLM inference with post-training weight and activation...
Accelerating Laguna XS.2 Inference with vLLM, Speculators, and LLM ...
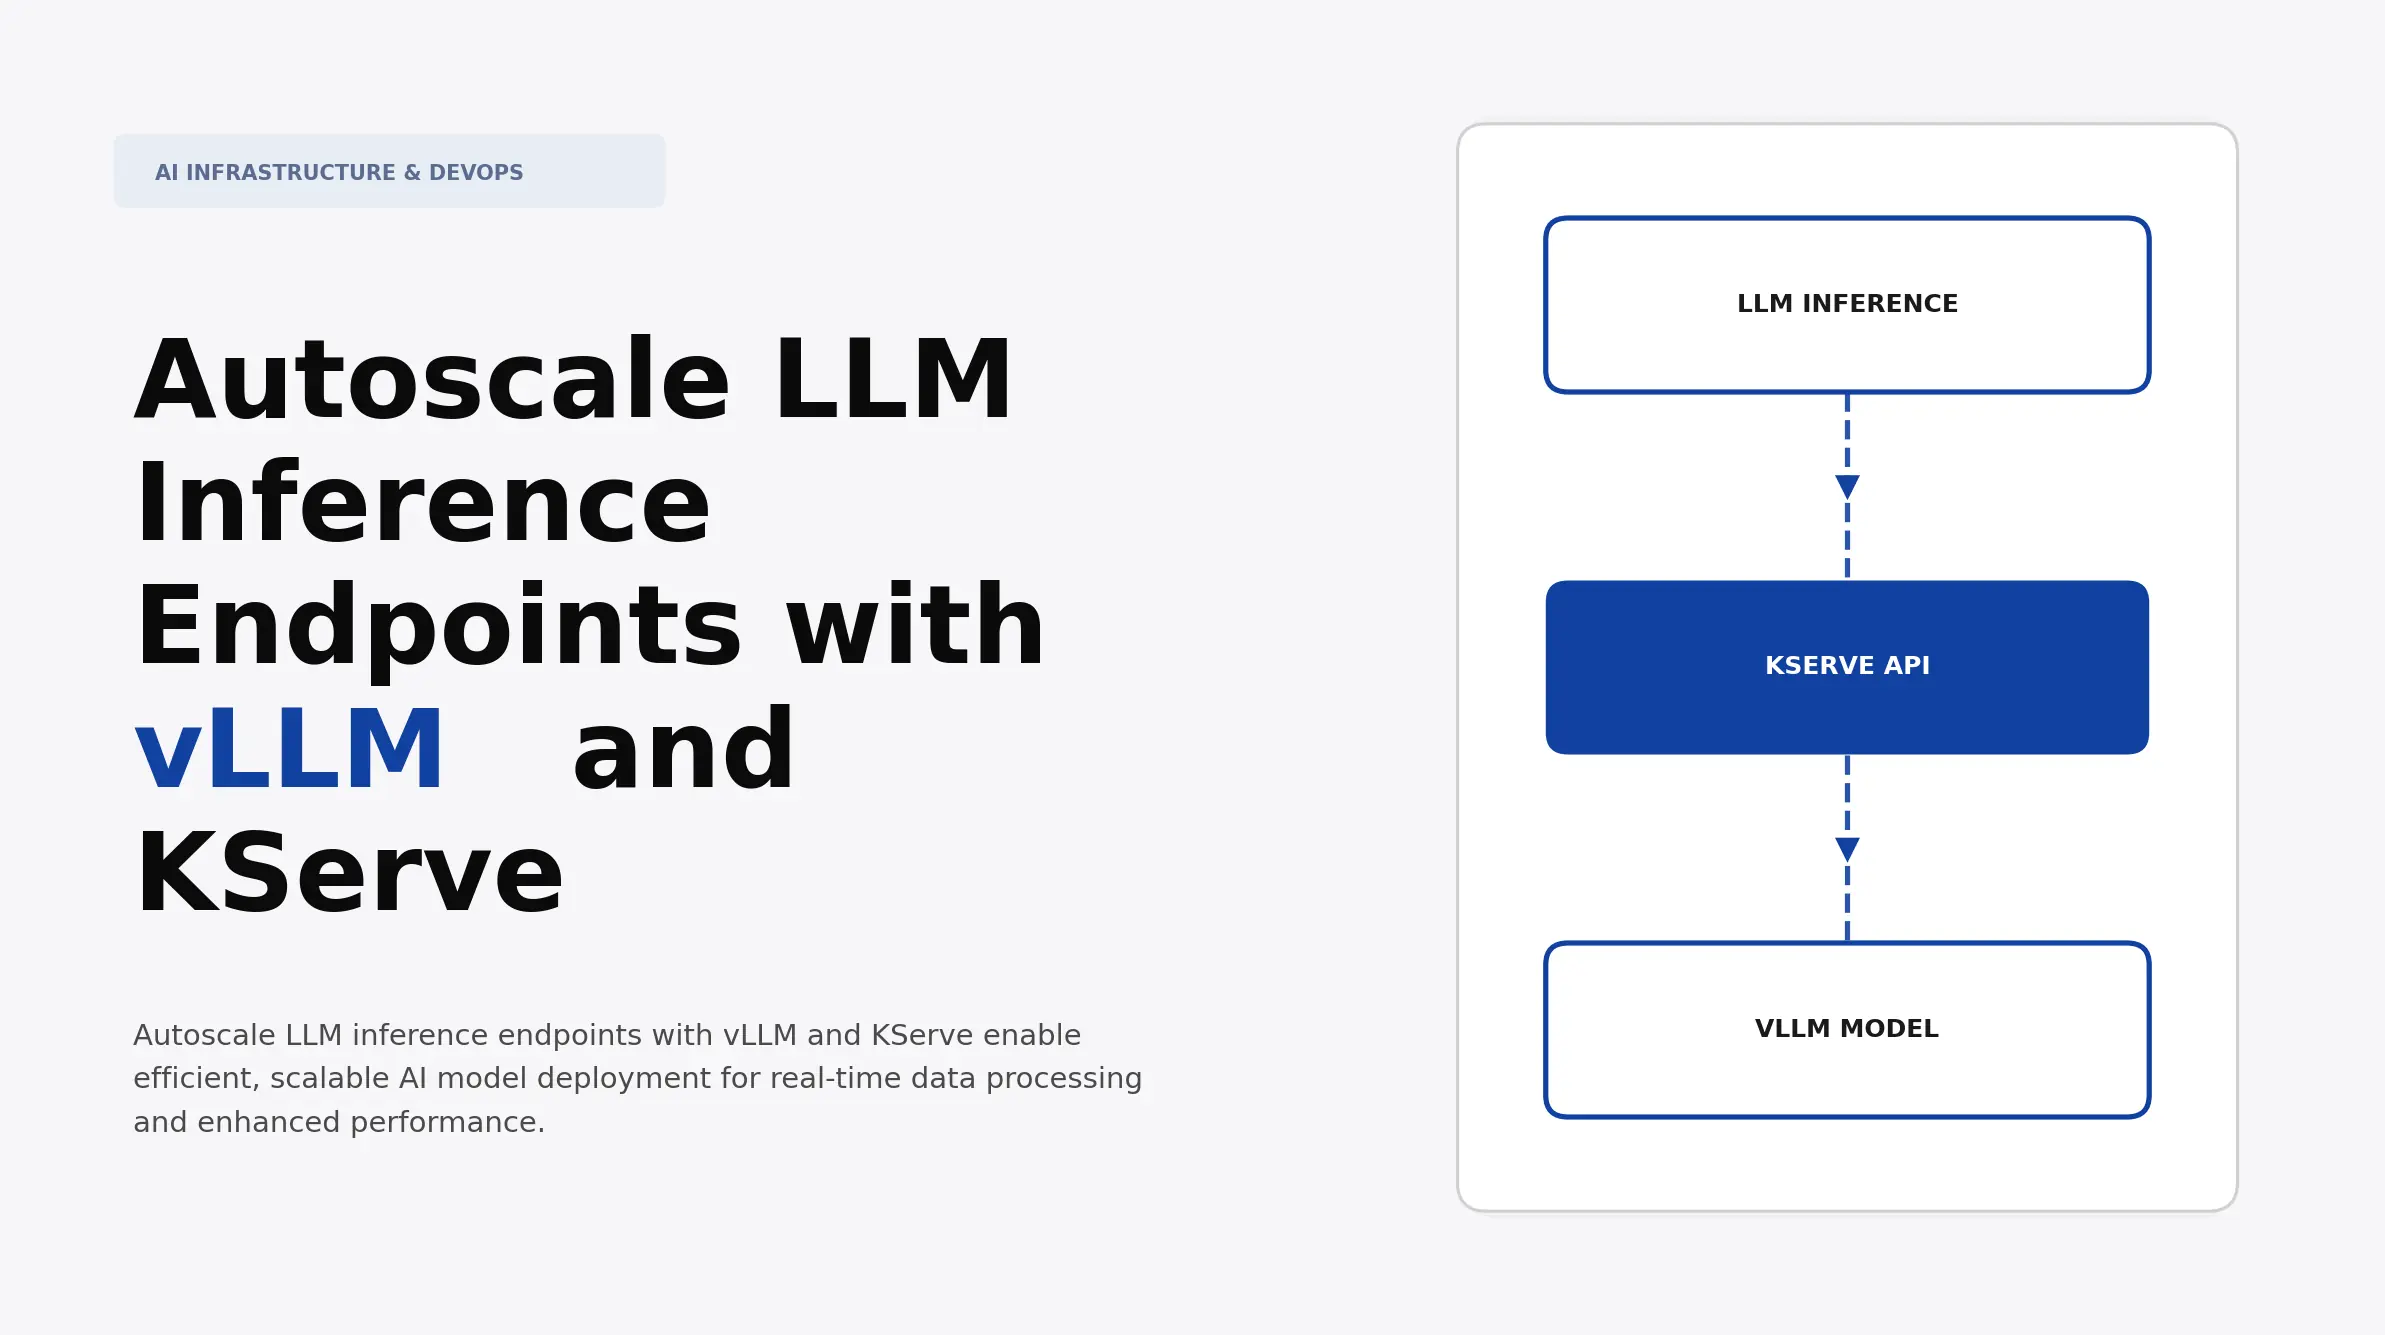
Autoscale LLM Inference Endpoints with vLLM and KServe | Atomic Loops
Advertisement Space (336x280)
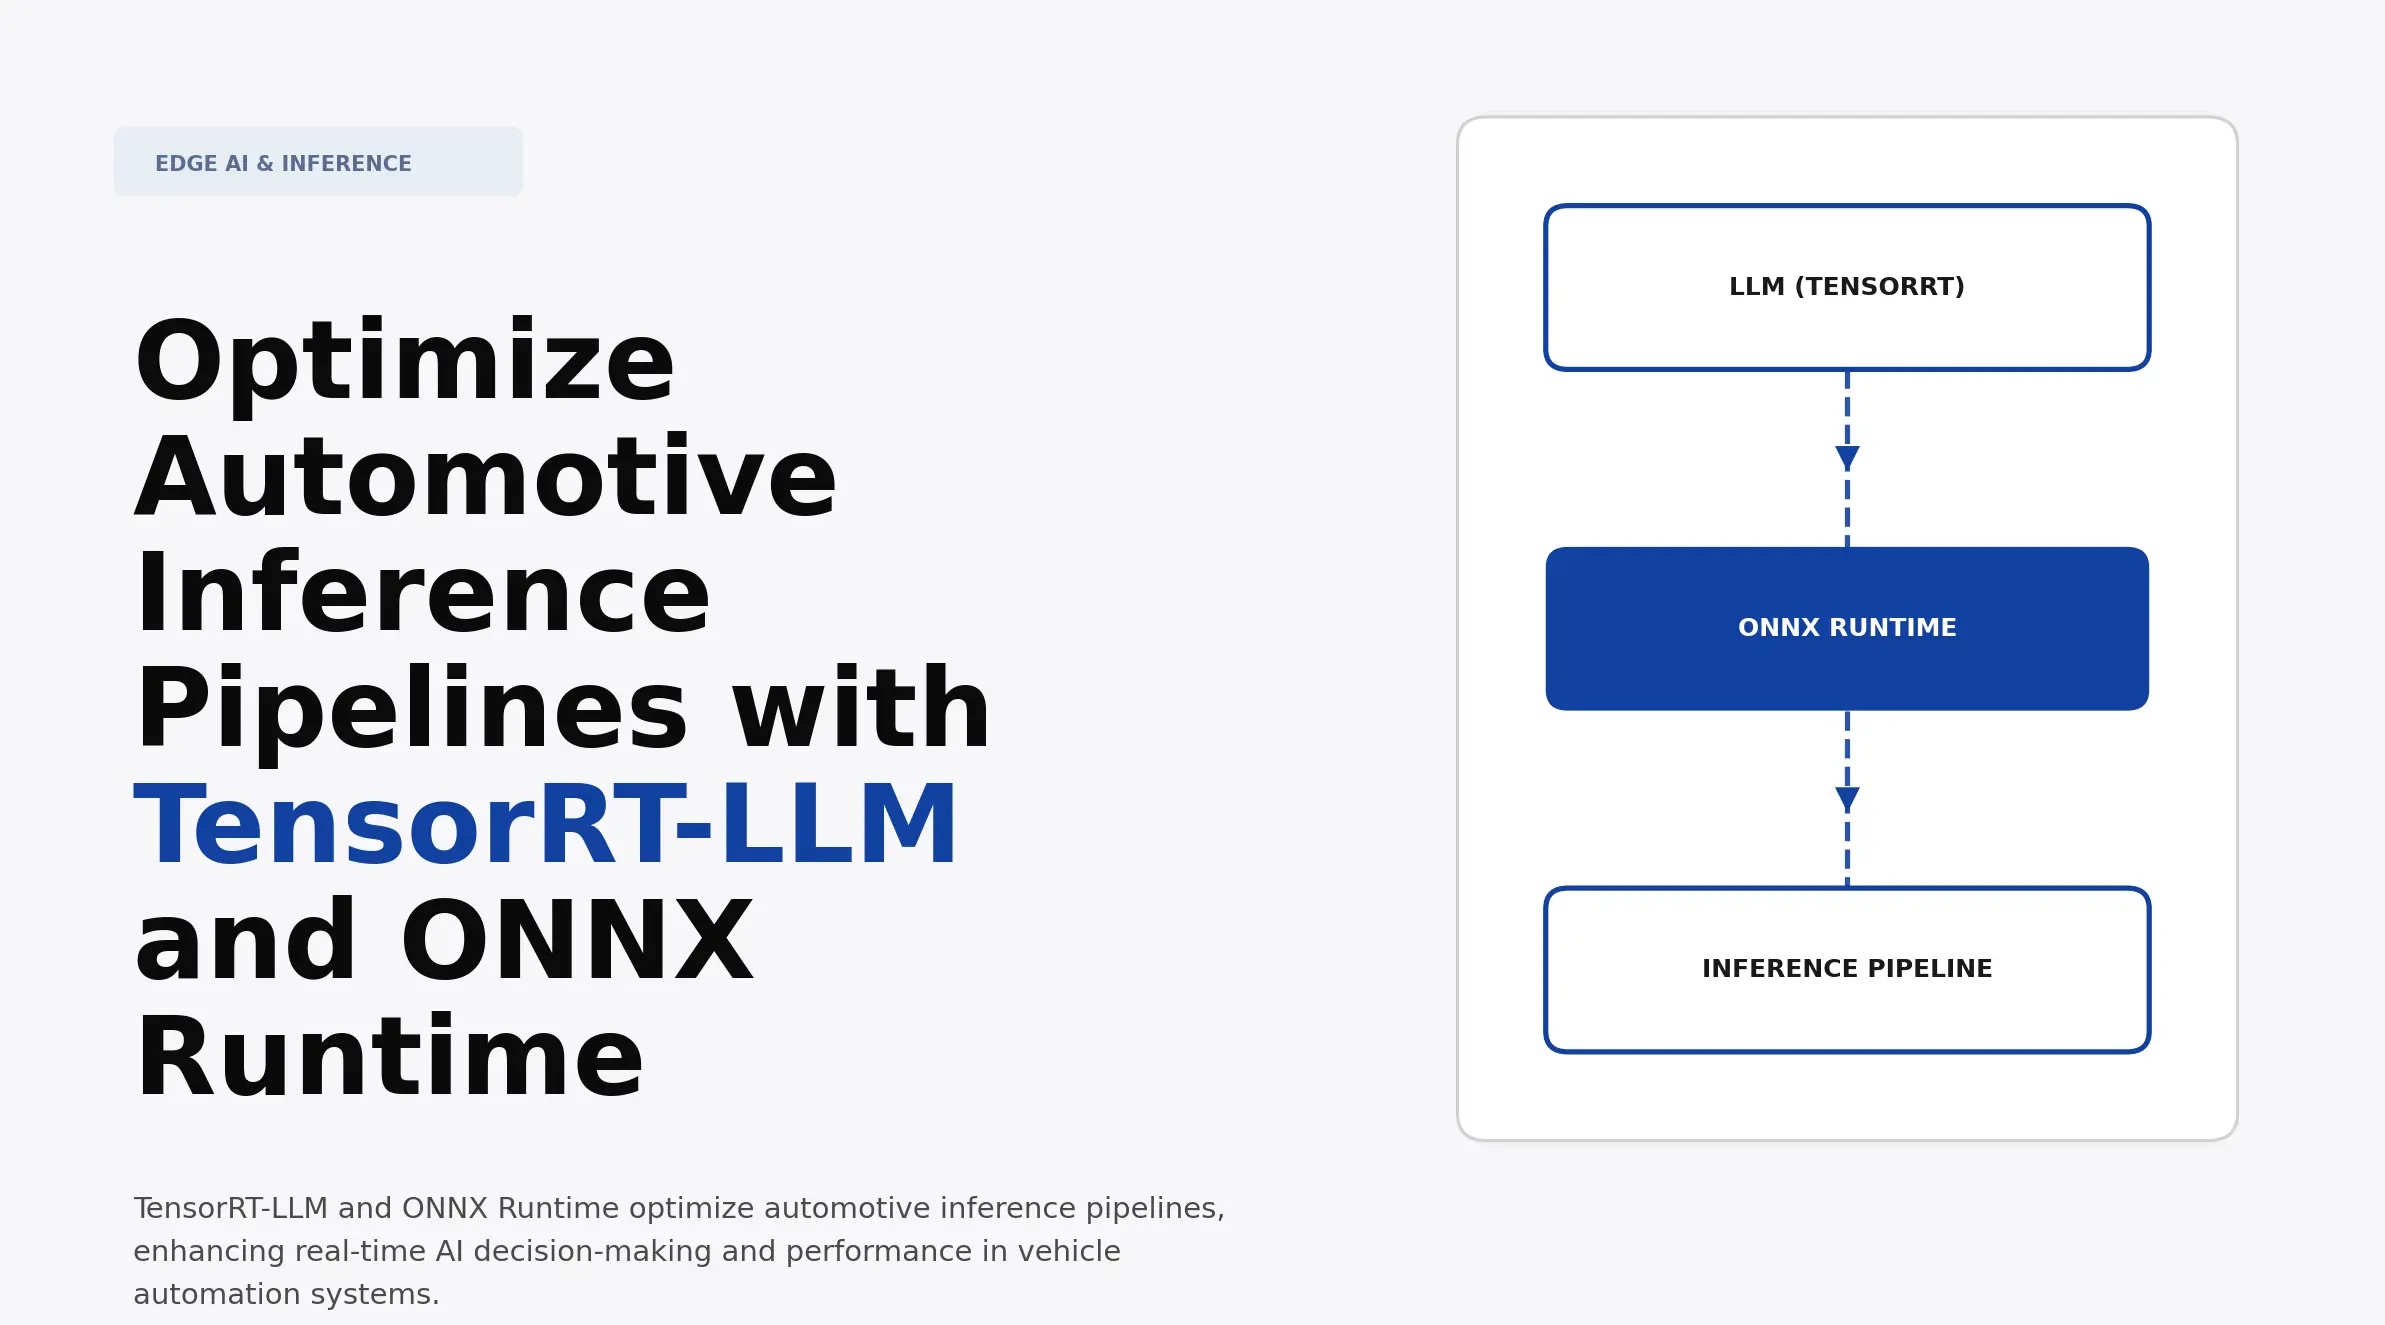
Optimize Automotive Inference Pipelines with TensorRT-LLM and ONNX ...

Accelerating LLM Inference - Tradeoffs, Design, and New Ideas

FastMTP: Accelerating LLM Inference with Enhanced Multi-Token ...

Accelerating LLM Inference with vLLM - YouTube

AcceLLM: Accelerating LLM Inference using Redundancy for Load Balancing ...

[2505.02123] DriveAgent: Multi-Agent Structured Reasoning with LLM and ...

GemFilter: A Novel AI Approach to Accelerate LLM Inference and Reduce ...

Accelerate LLM fine-tuning and deployment with Domino and NVIDIA NIM

Accelerating LLM Inference with Speculative Decoding using LMStudio ...

Driving by Conversation: Personalized Autonomous Driving with LLMs and ...
Advertisement Space (336x280)

LLM Inference: Accelerating Long Context Generation with KV Cache ...

Paper page - AccLLM: Accelerating Long-Context LLM Inference Via ...
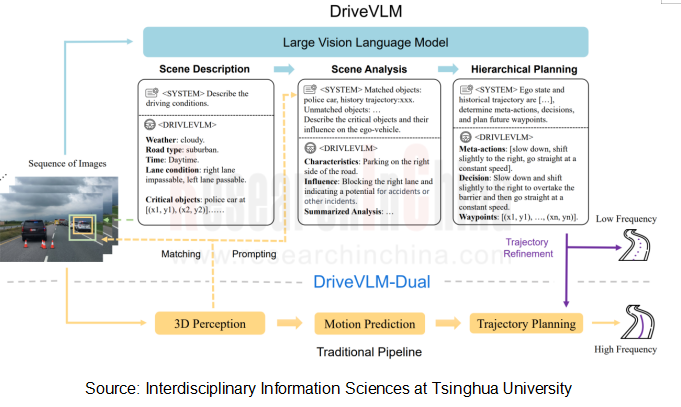
Automotive AI Foundation Model Technology and Application Trends Report ...

Amphista: Accelerate LLM Inference with Bi-directional Multiple ...

Driving by Conversation: Personalized Autonomous Driving with LLMs and ...
Streamline LLM Deployment for Autonomous Vehicle Applications with ...