
How Do You Actually Scale High Throughput Llm Serving In Production

How Do You Actually Scale High-Throughput LLM Serving in Production ...

How Do You Actually Scale High-Throughput LLM Serving in Production ...

Throughput is Not All You Need: Maximizing Goodput in LLM Serving using ...

Throughput is Not All You Need: Maximizing Goodput in LLM Serving using ...

Throughput is Not All You Need: Maximizing Goodput in LLM Serving using ...
Latency vs Throughput — The Fundamental Trade-Off in LLM Serving ...
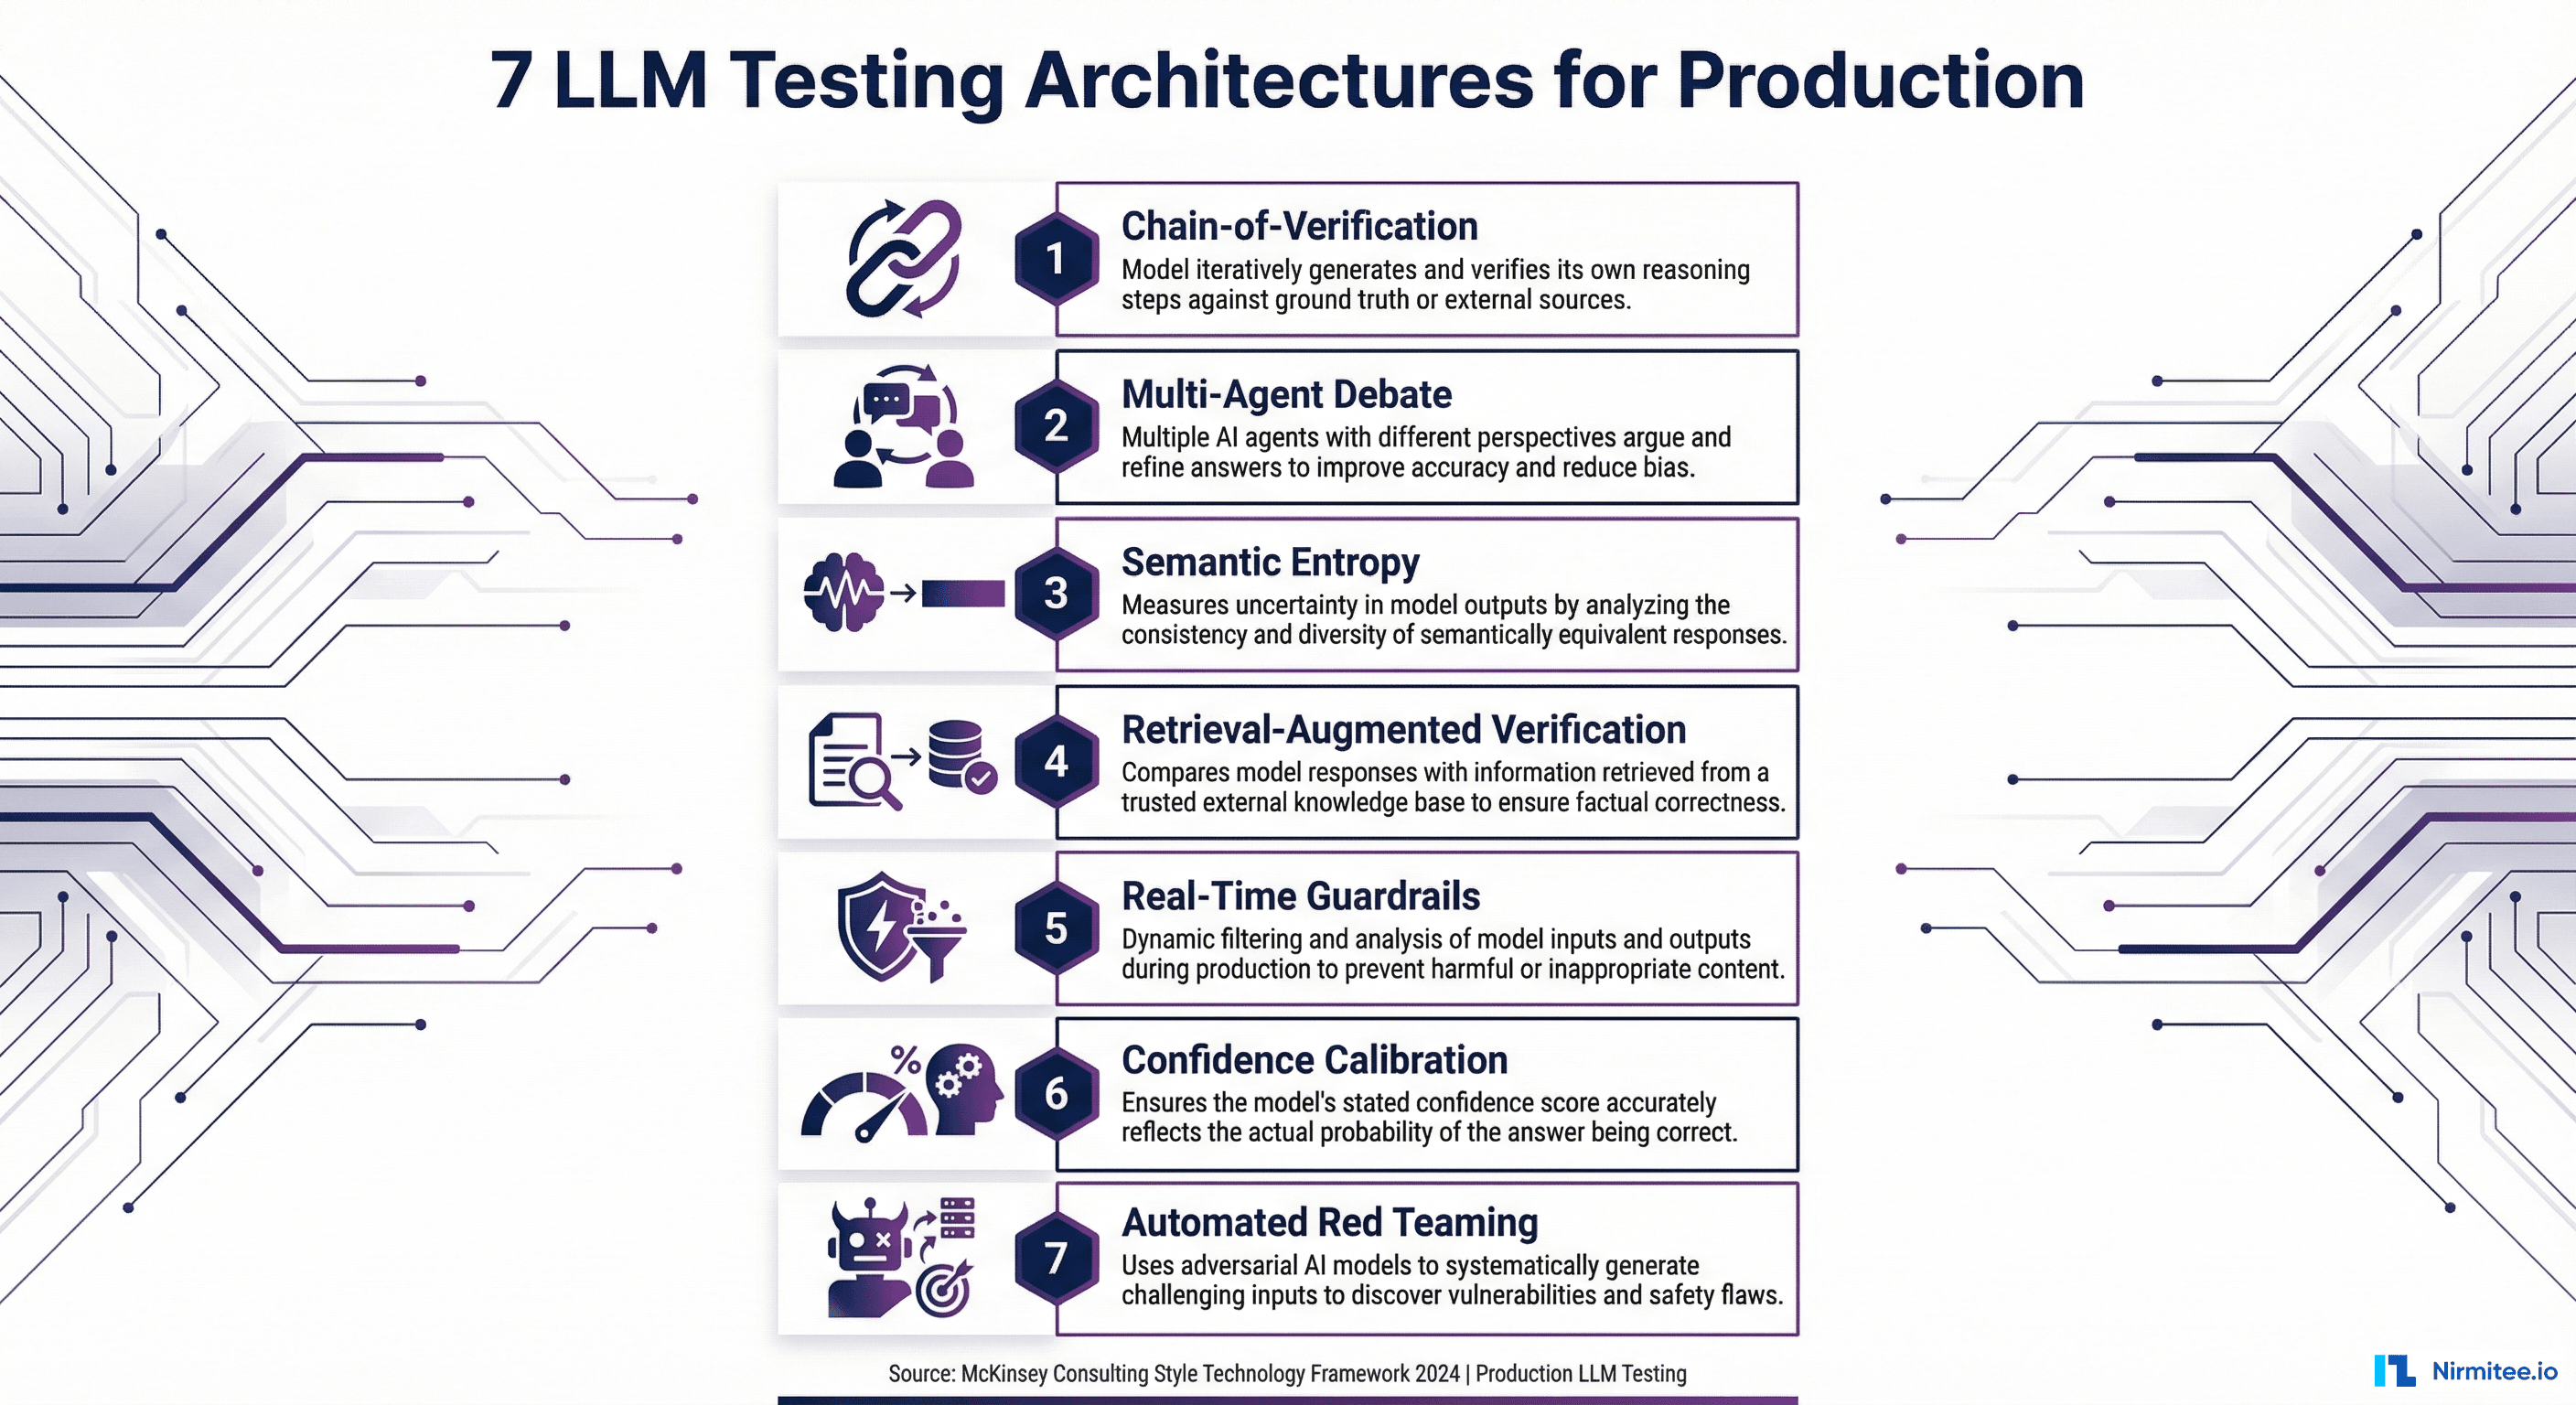
7 LLM Testing Architectures That Actually Work in Production

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...
Advertisement Space (300x250)

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...

Scaling AI in production: A practical guide to LLM Serving - Fractal ...

Scaling AI in production: A practical guide to LLM Serving - Fractal ...
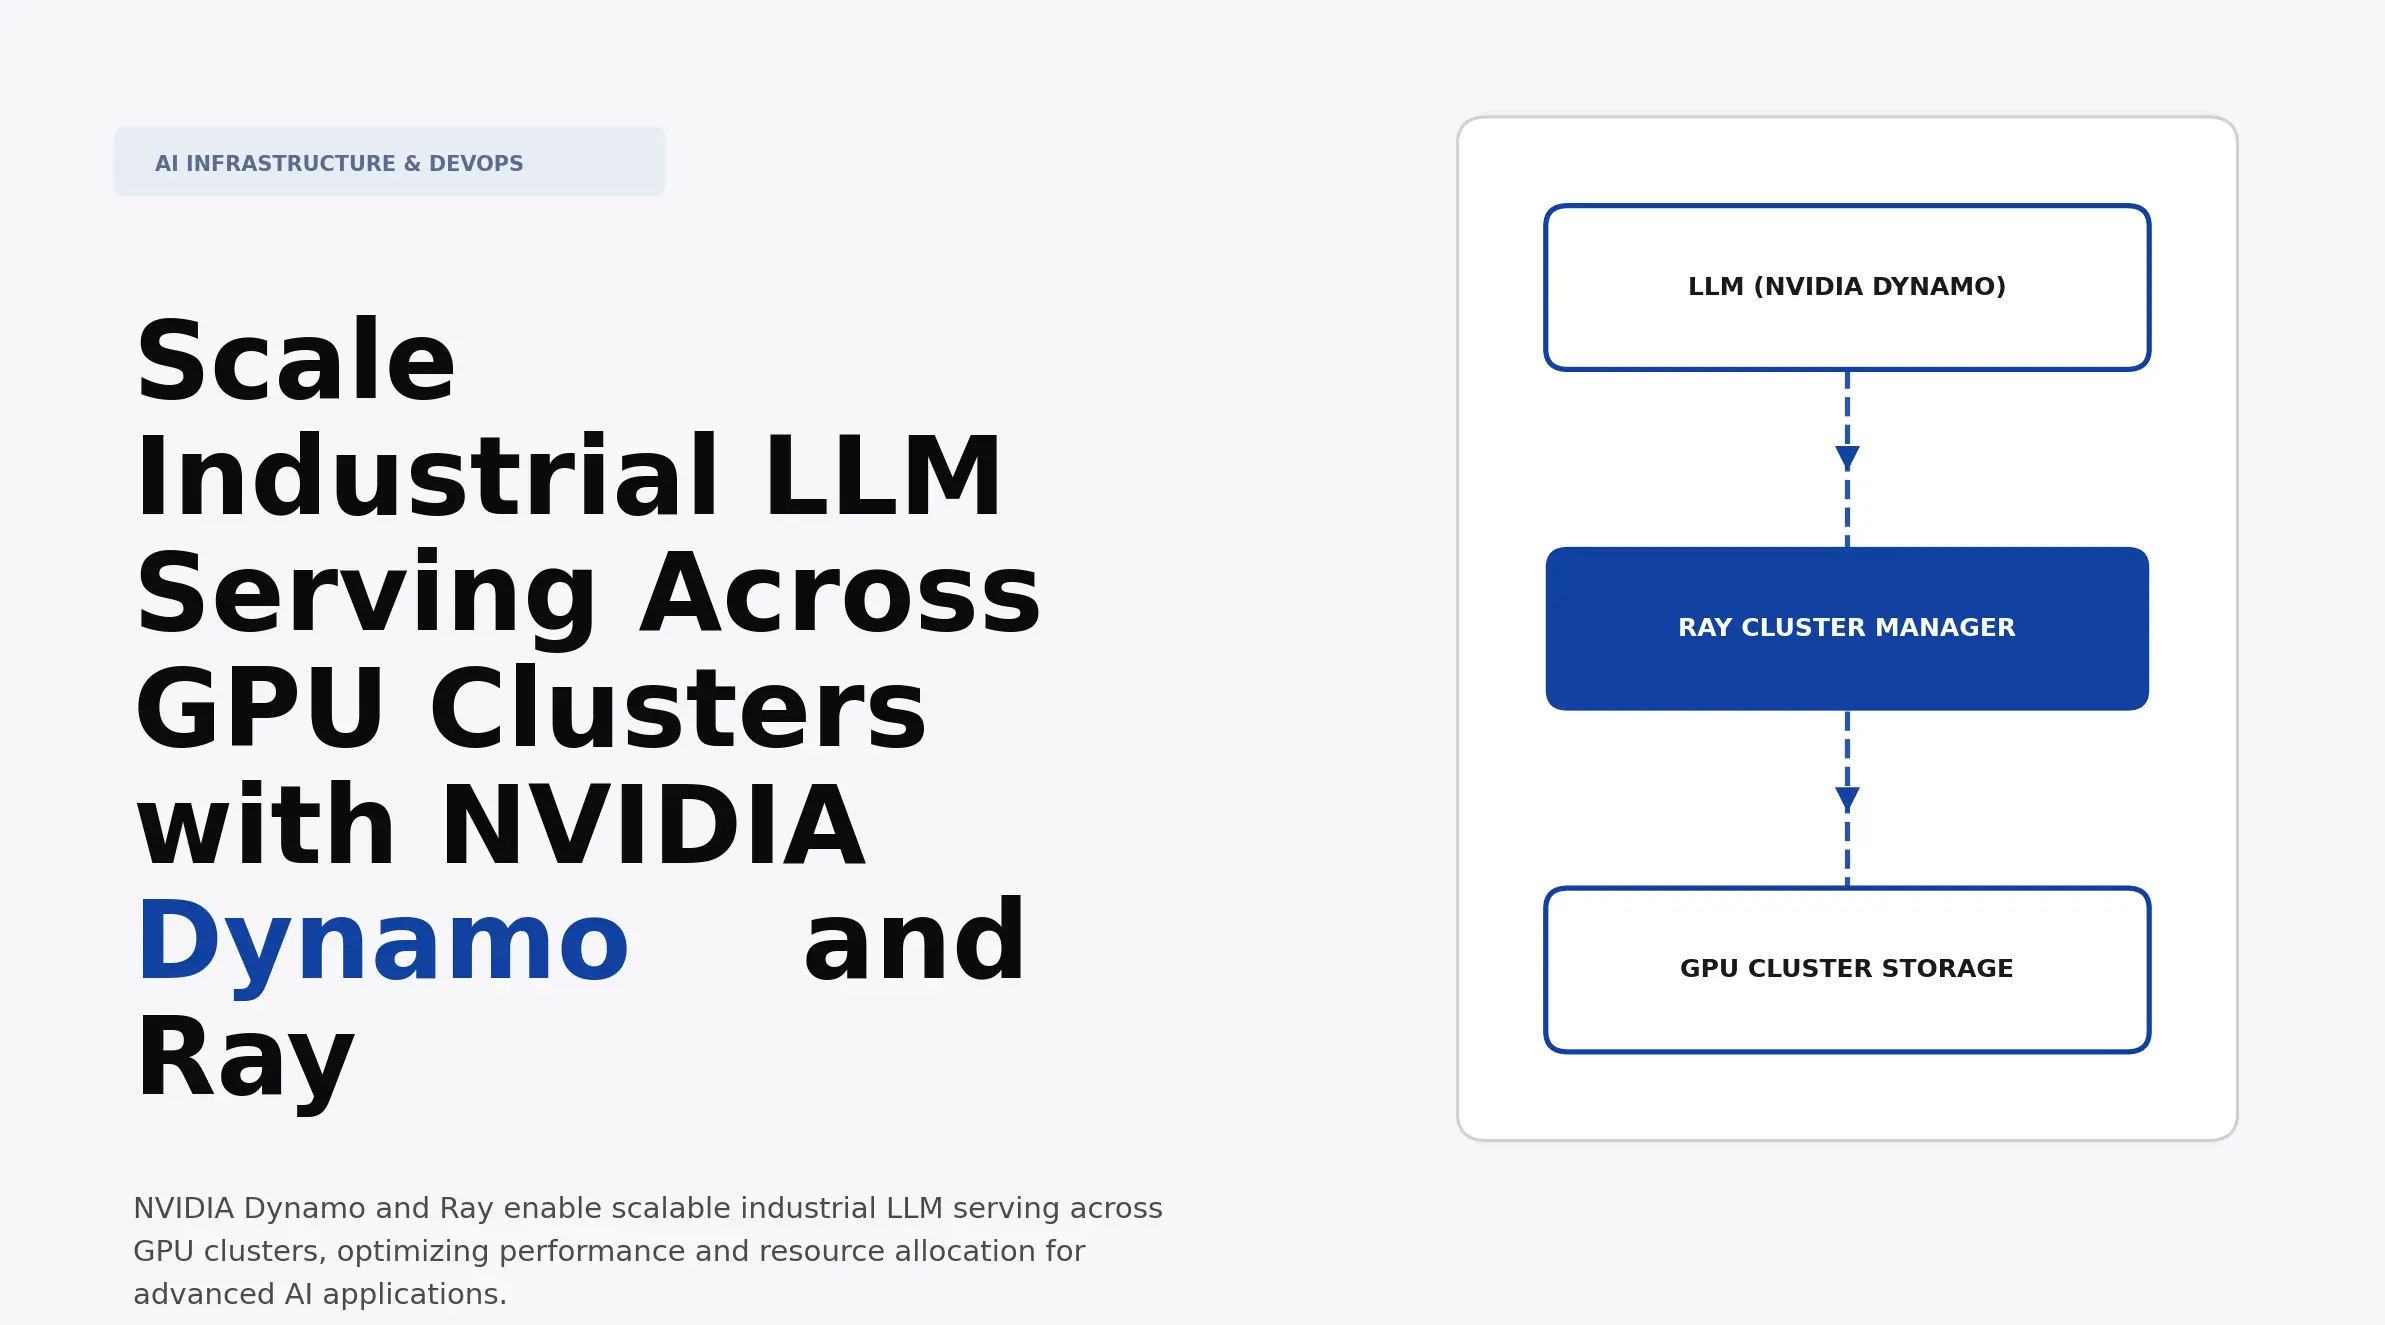
Scale Industrial LLM Serving Across GPU Clusters with NVIDIA Dynamo and ...
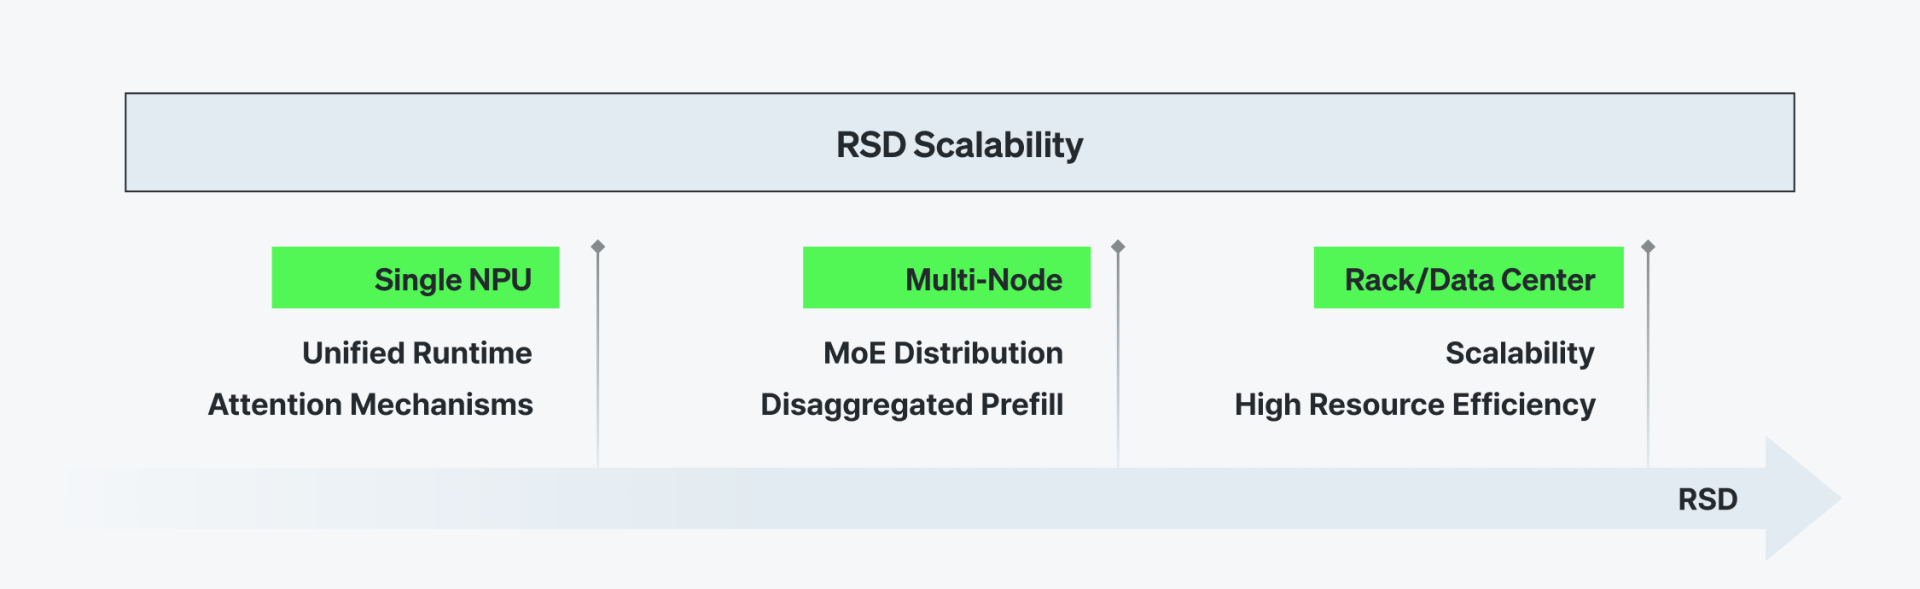
LLM Serving with NPU: Re-engineered, Built for Scale and Efficiency ...

Identifying and Mitigating Systemic Measurement Bias in Production LLM ...
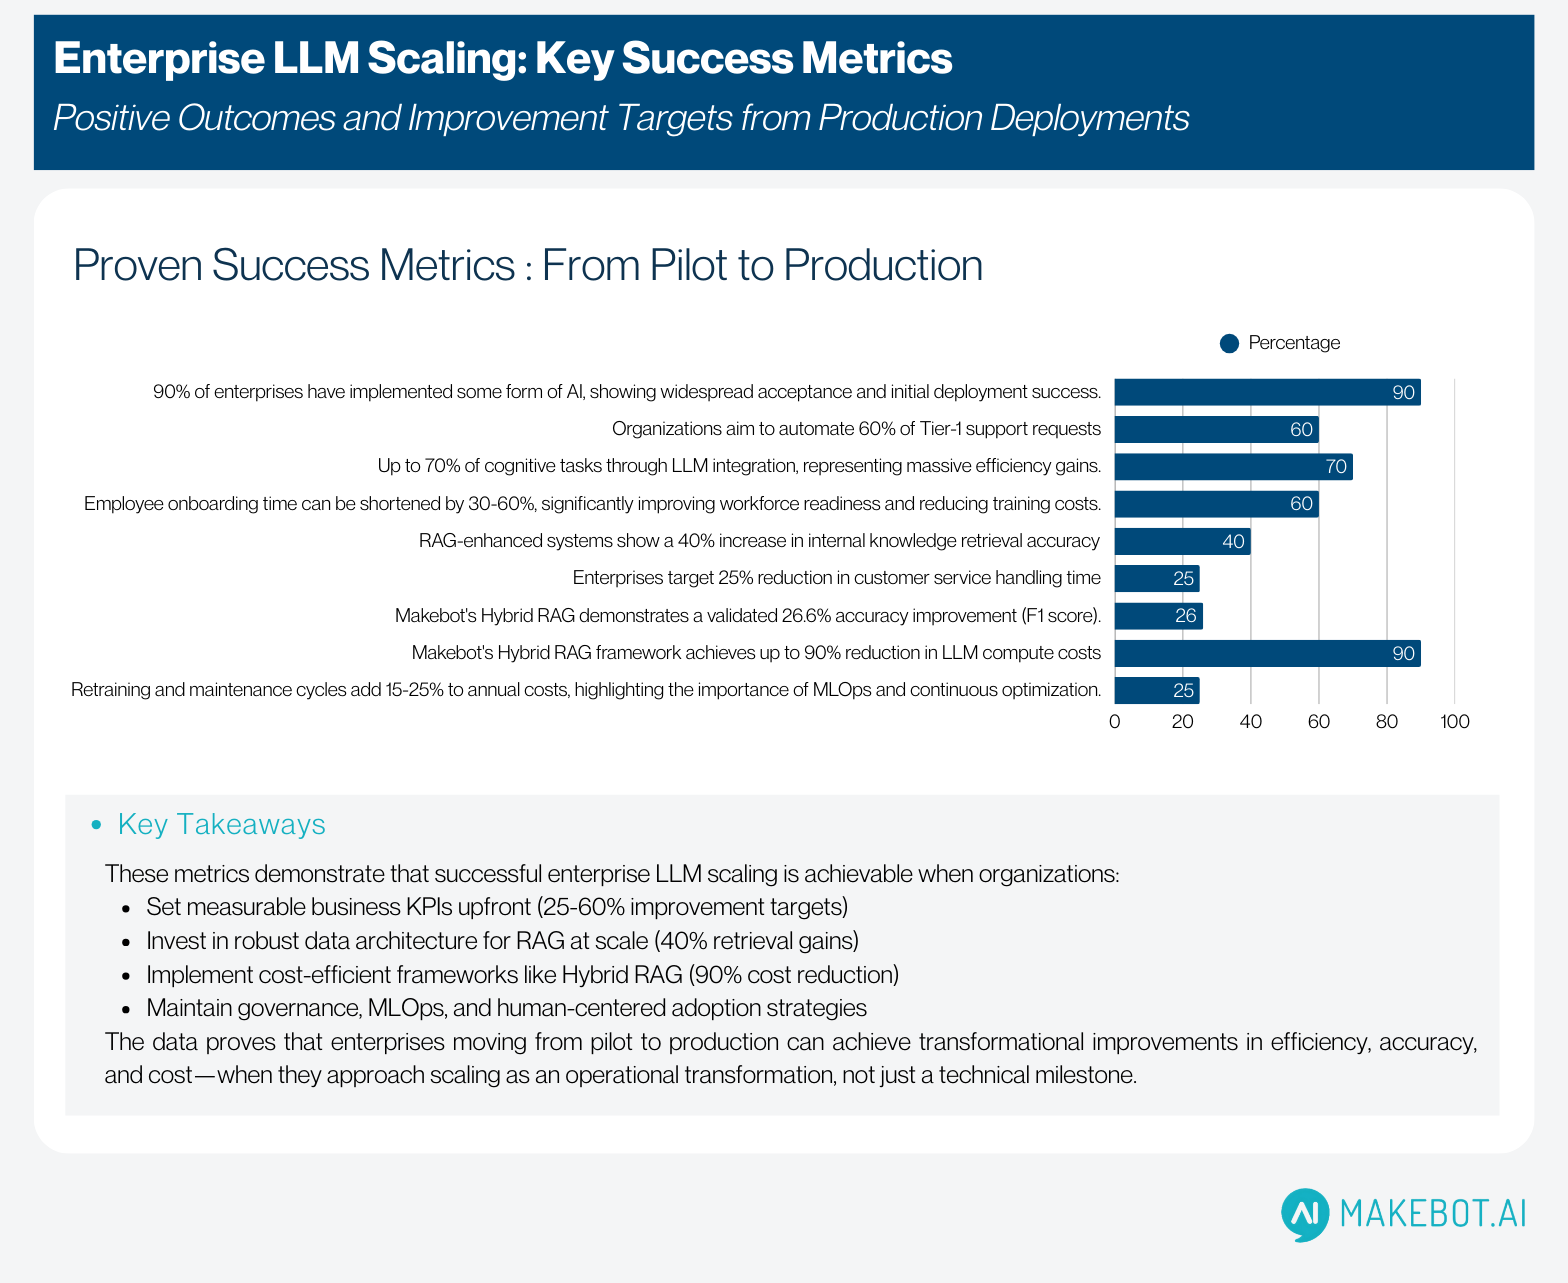
From Pilot to Production: How Enterprises Can Successfully Scale LLM ...

LLM Serving with NPU: Re-engineered, Built for Scale and Efficiency ...
Advertisement Space (336x280)

Identifying and Mitigating Systemic Measurement Bias in Production LLM ...
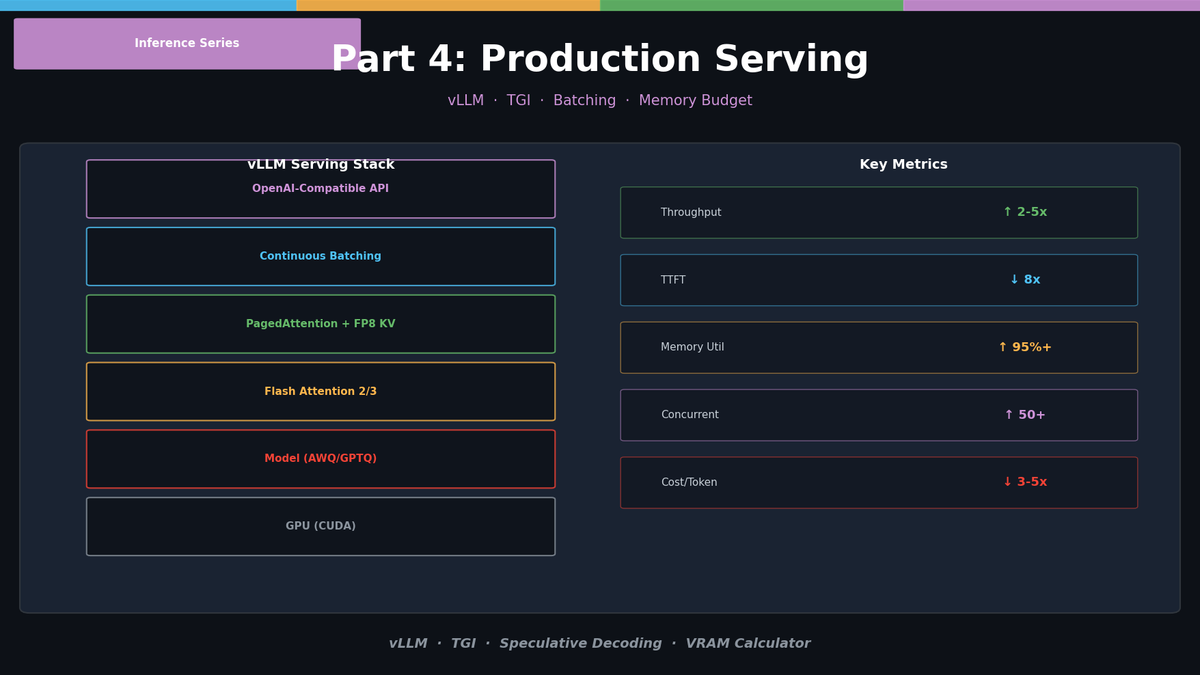
LLM Inference Optimization Part 4 — Production Serving | SOTAAZ Blog

Top 5 LLM Gateways for Production in 2026 (A Deep, Practical Comparison ...
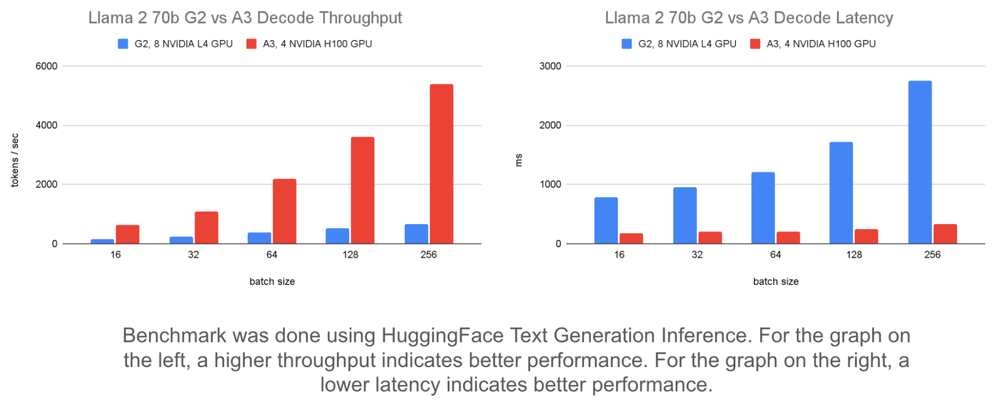
Maximize your LLM serving throughput for GPUs on GKE — a practical ...
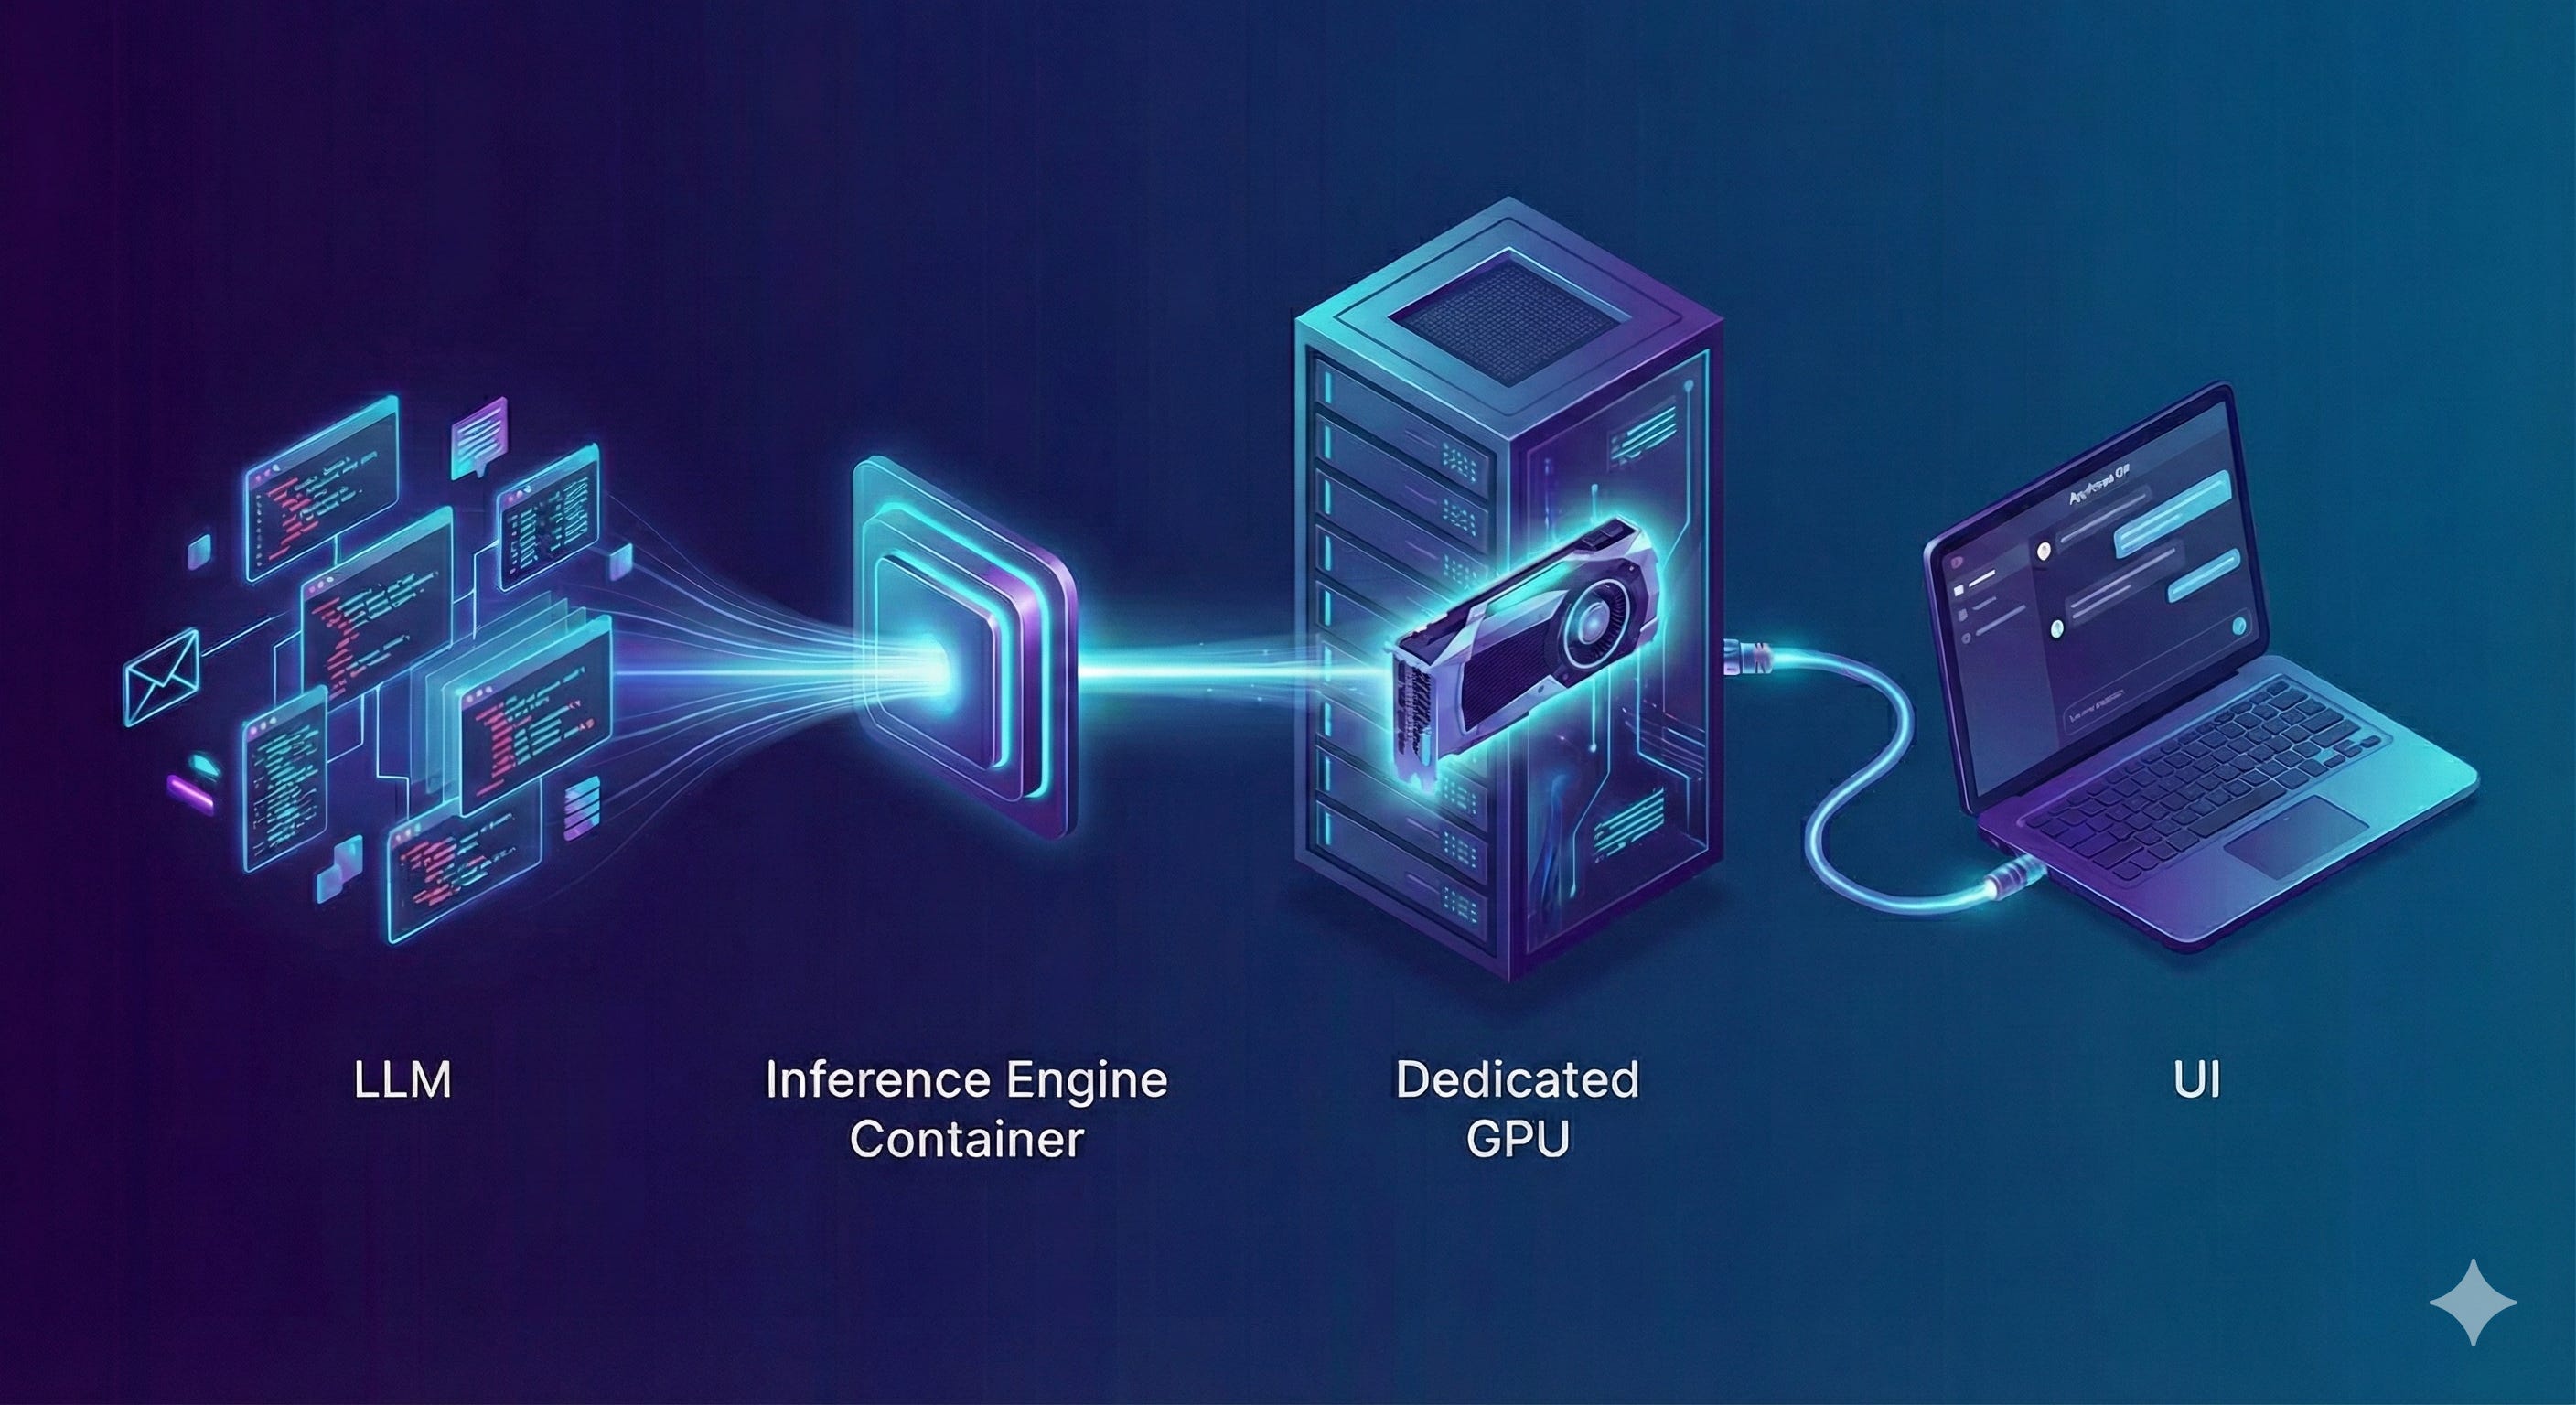
How to Deploy Your LLM in the Cloud - by Benjamin Marie

How to Scale LLM Applications With Continuous Batching!

How to Scale LLM Applications With Continuous Batching!
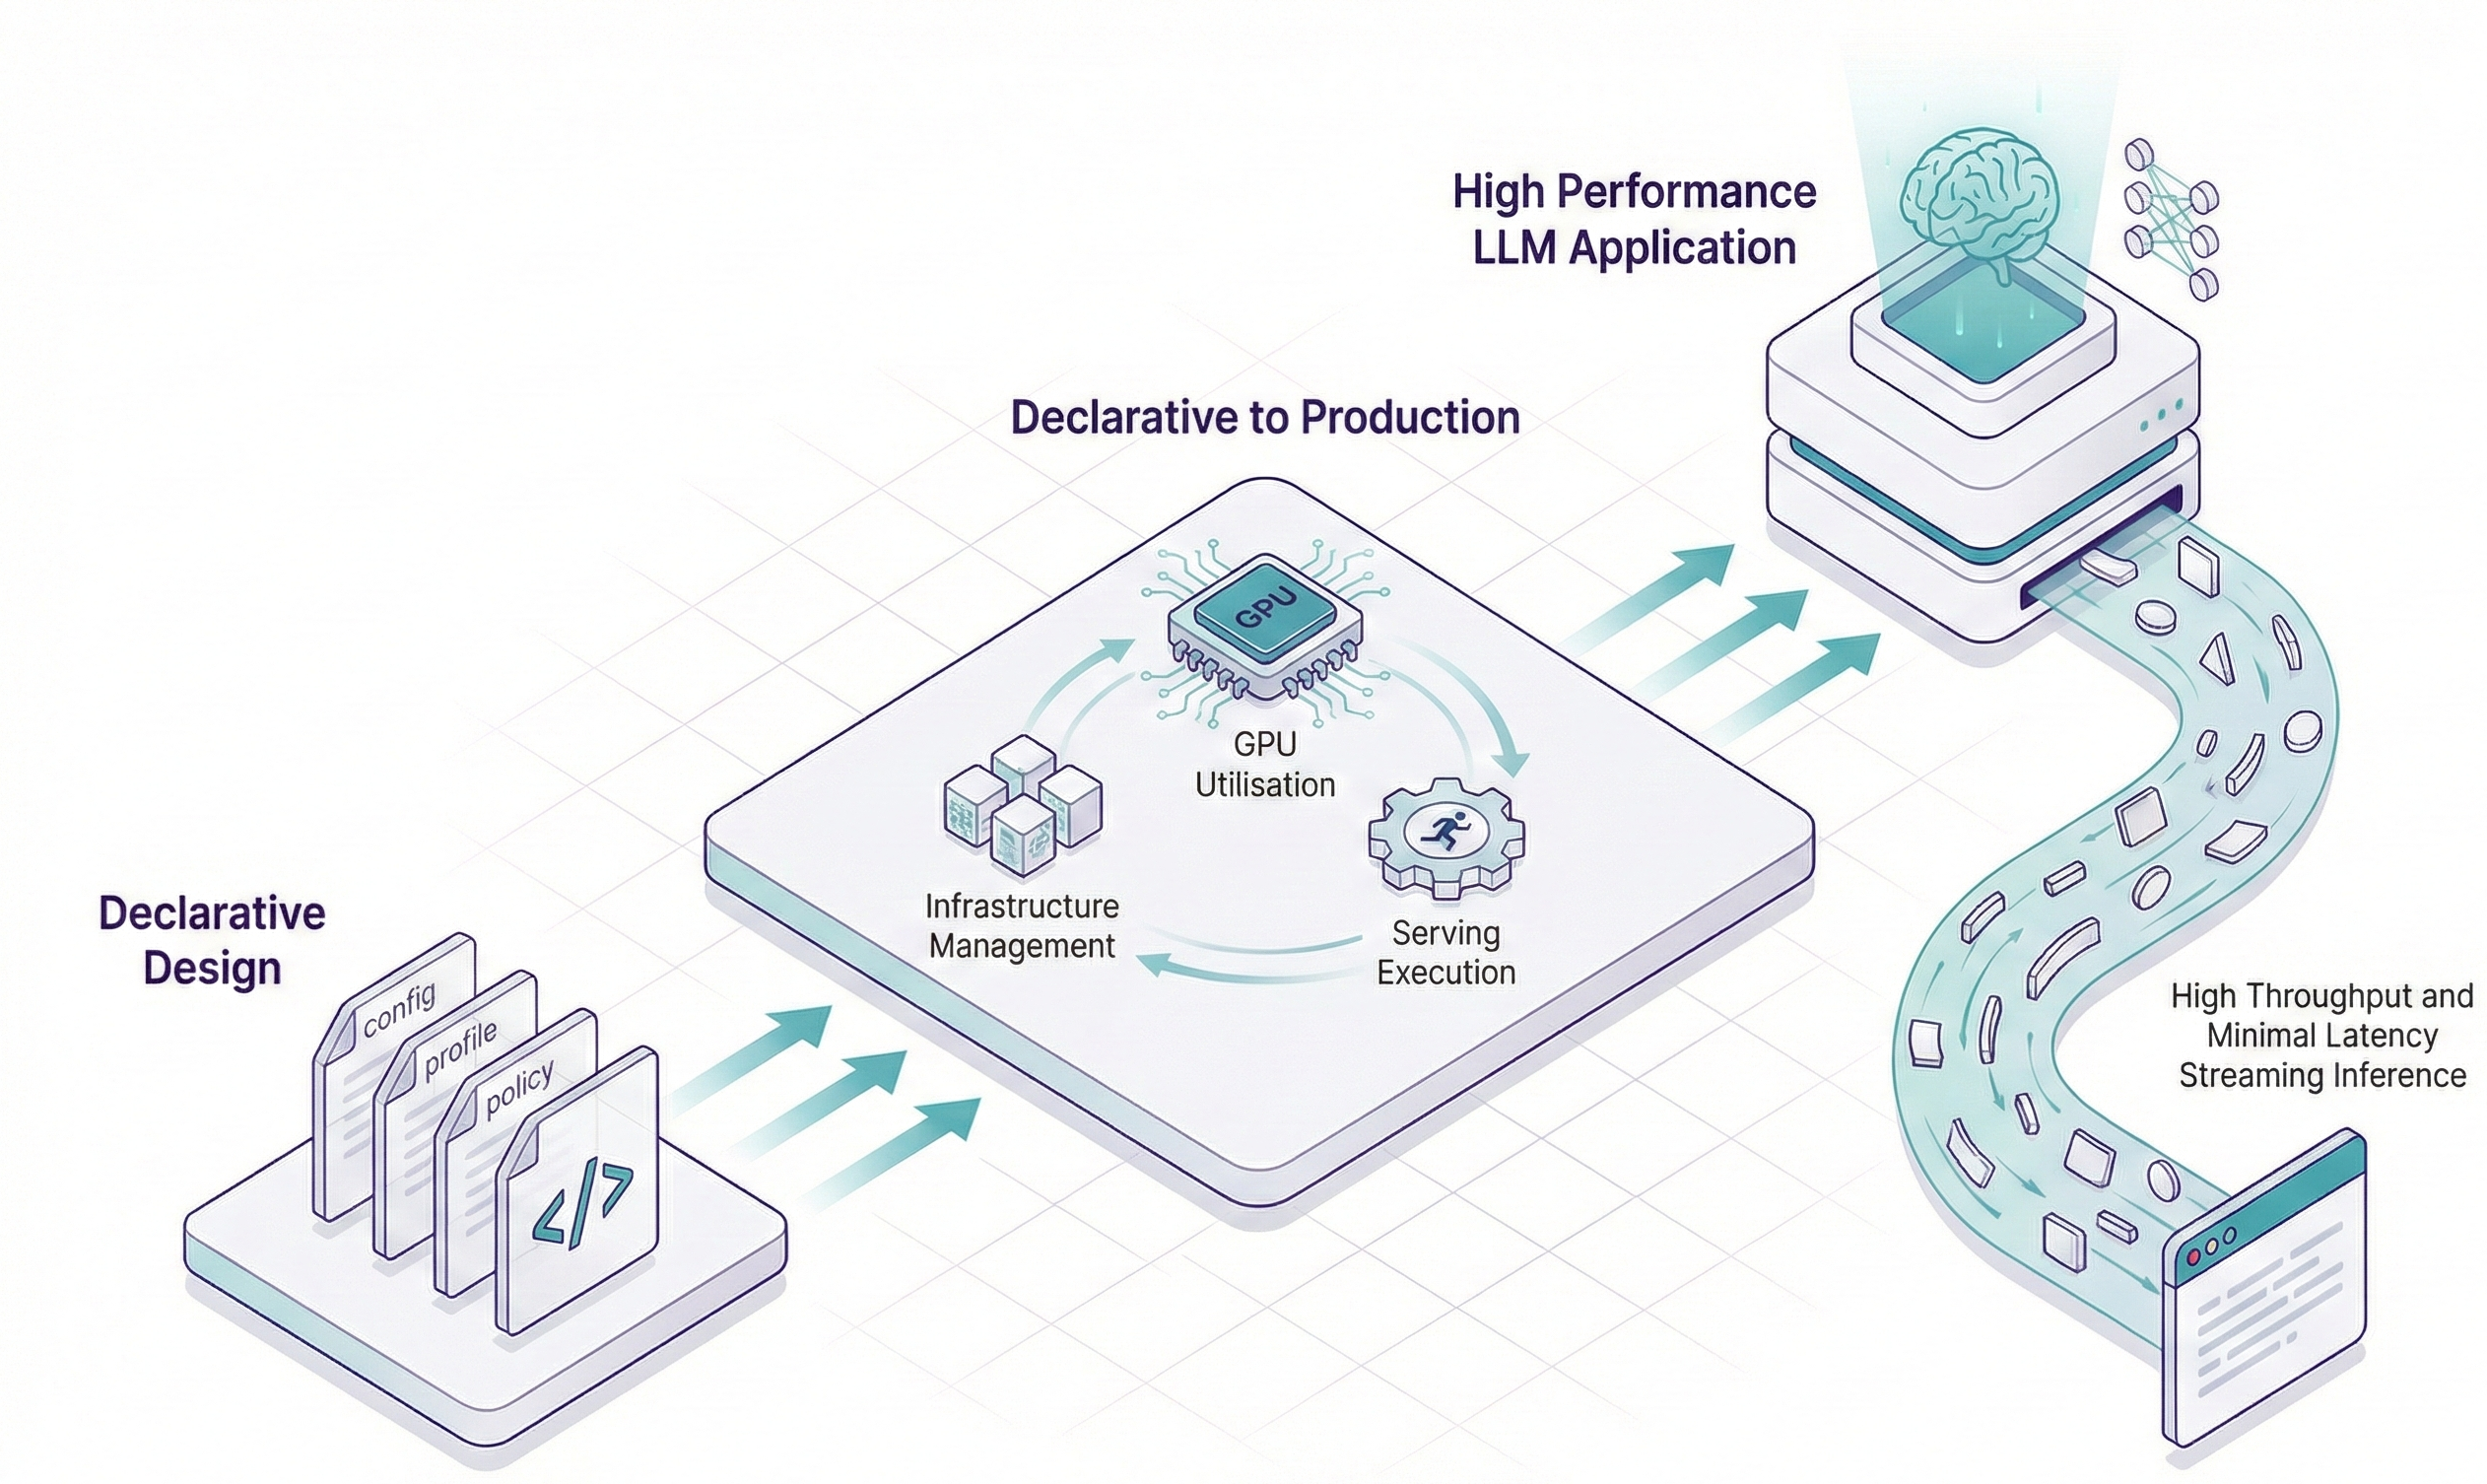
Model Serving - The Enterprise LLM Operating Layer

Scale Open LLMs with vLLM Production Stack | by Shahrukh khan | Medium

Free Course: Build a Production-Ready LLM System That Writes Like You
Advertisement Space (336x280)

Scaling LLM Inference on GKE: Serving with vLLM or llm-d | by Don ...
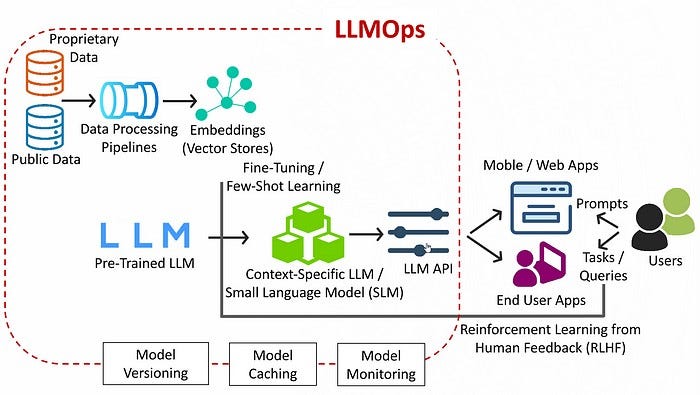
Deploying LLMs Into Production Using TensorRT LLM | by Het Trivedi ...

ML Serving Pipelines That Actually Scale: Triton, TensorRT-LLM, KV ...

#65 | How to Serve LLMs in Production: Tools, Architecture & Strategic ...

Continuous Batching: Optimizing LLM Inference Throughput - Interactive ...

Operationalize LLM Evaluation at Scale using Amazon SageMaker Clarify ...