
Llm Serving With Npu Re Engineered Built For Scale And Efficiency
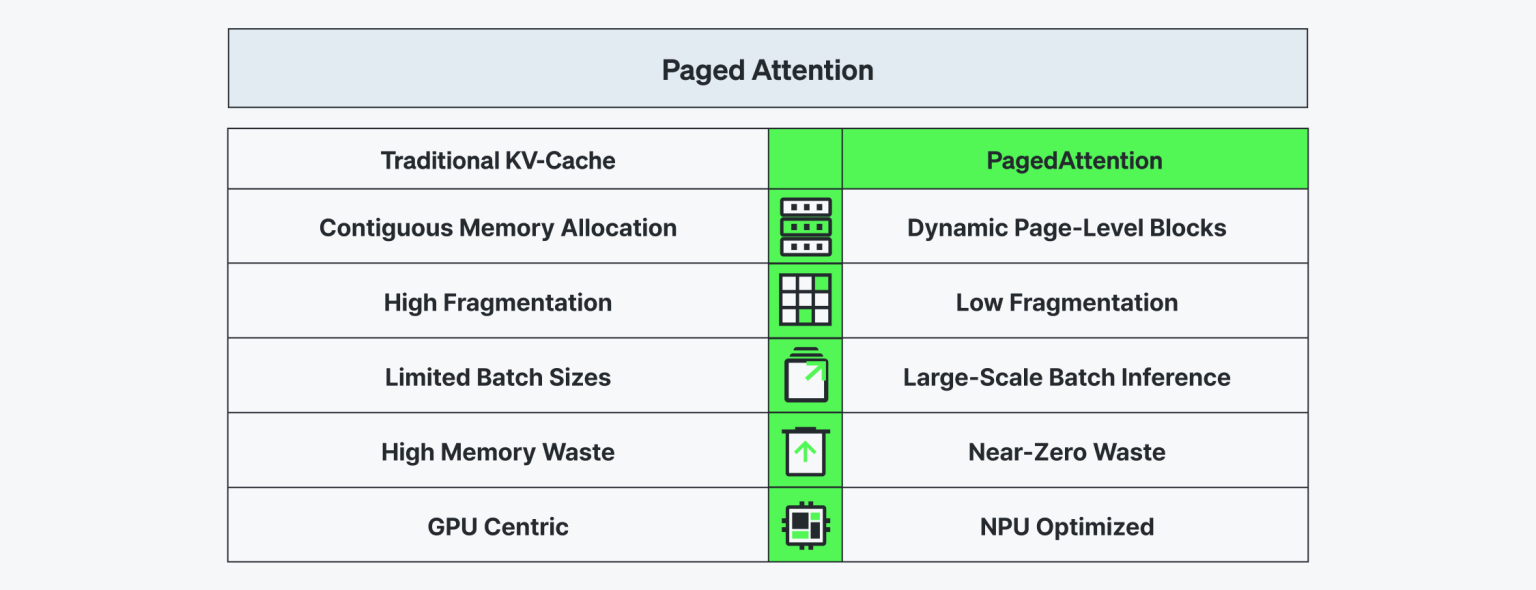
LLM Serving with NPU: Re-engineered, Built for Scale and Efficiency ...

LLM Serving with NPU: Re-engineered, Built for Scale and Efficiency ...
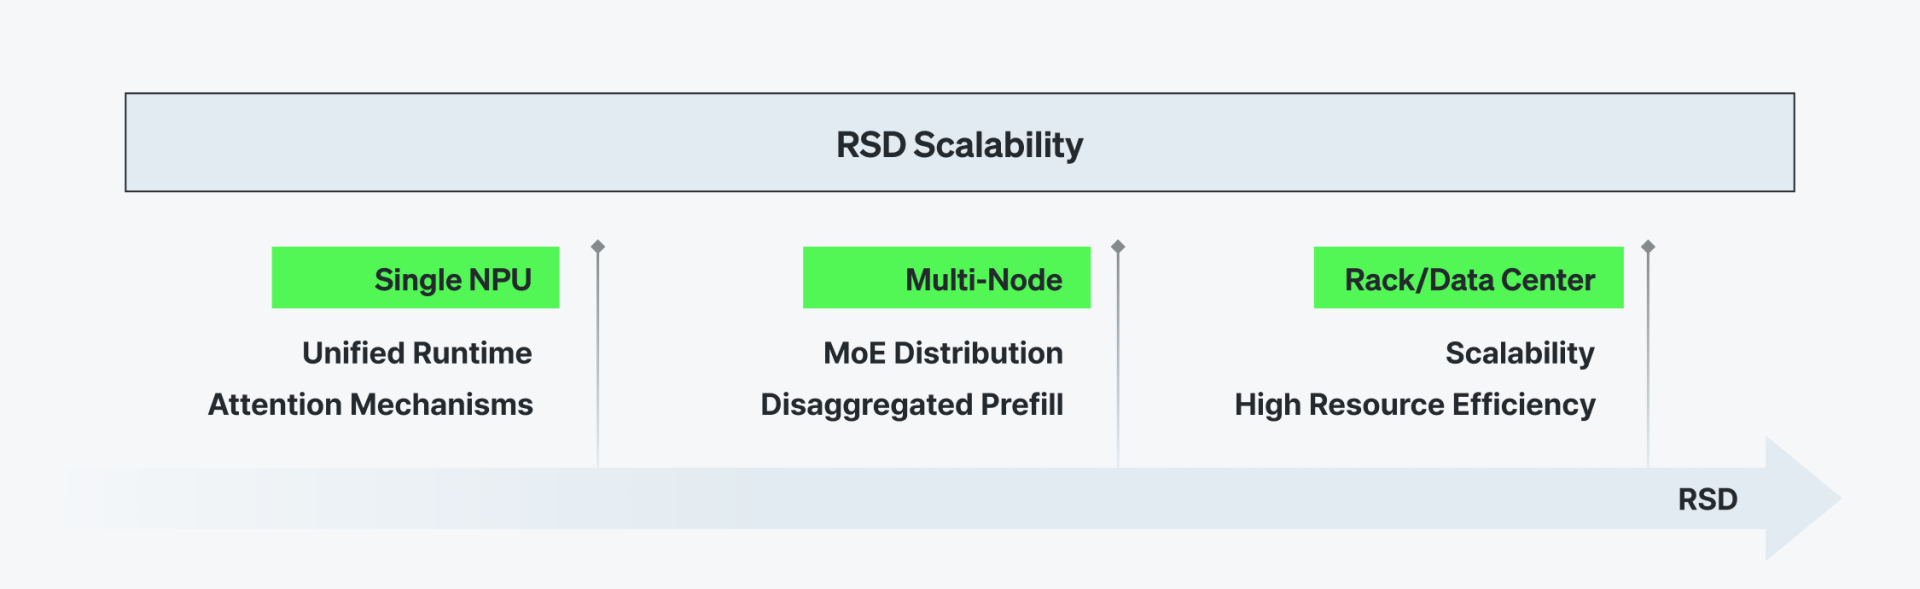
LLM Serving with NPU: Re-engineered, Built for Scale and Efficiency ...
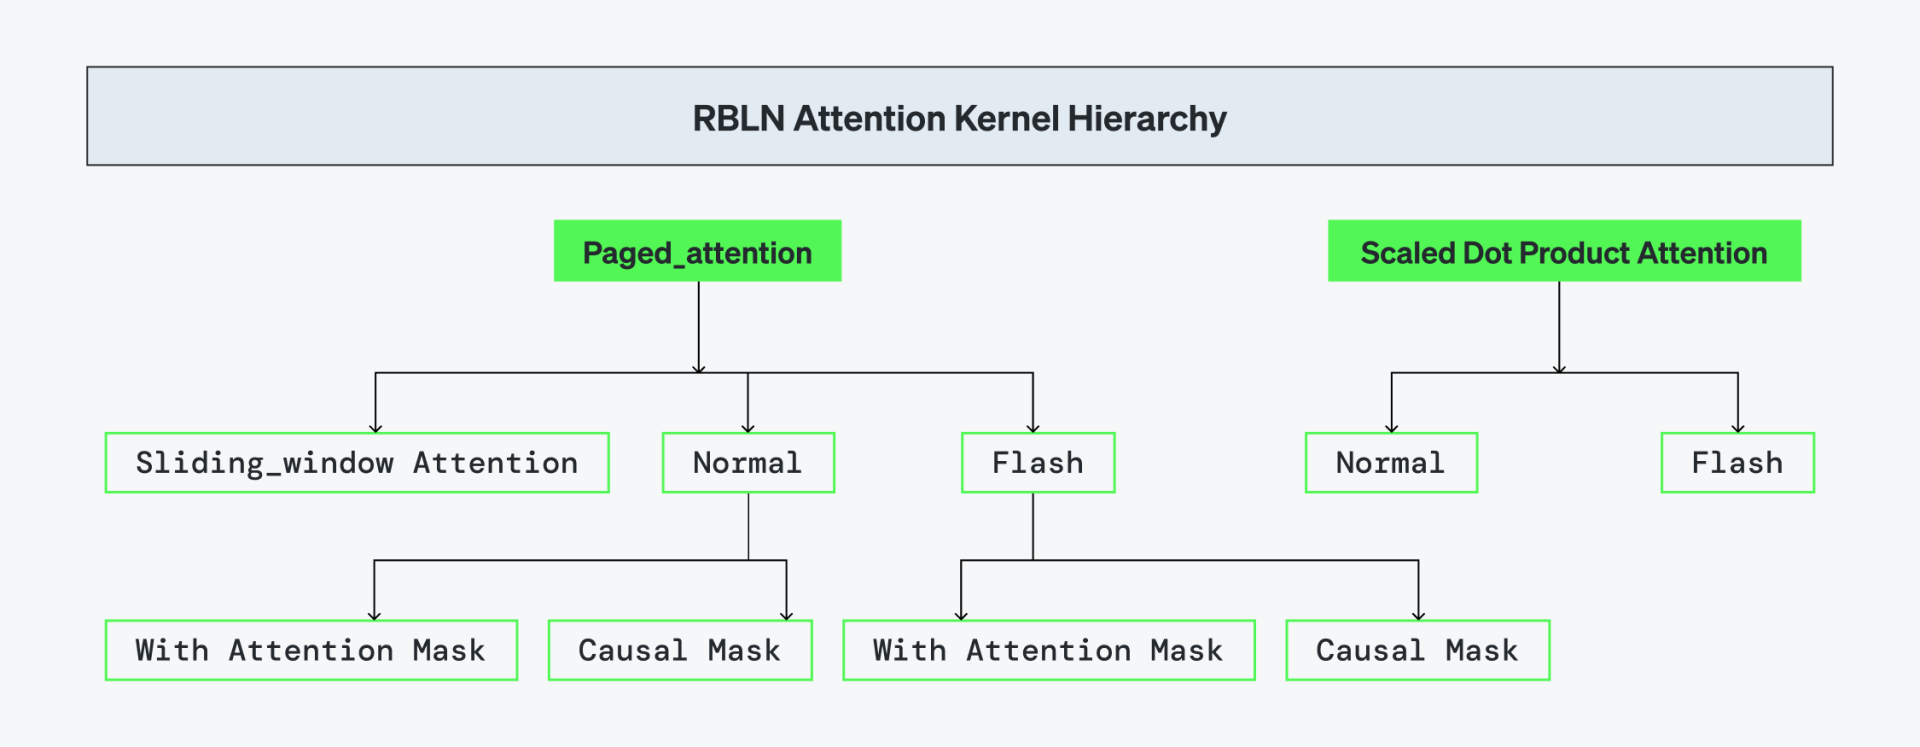
LLM Serving with NPU: Re-engineered, Built for Scale and Efficiency ...
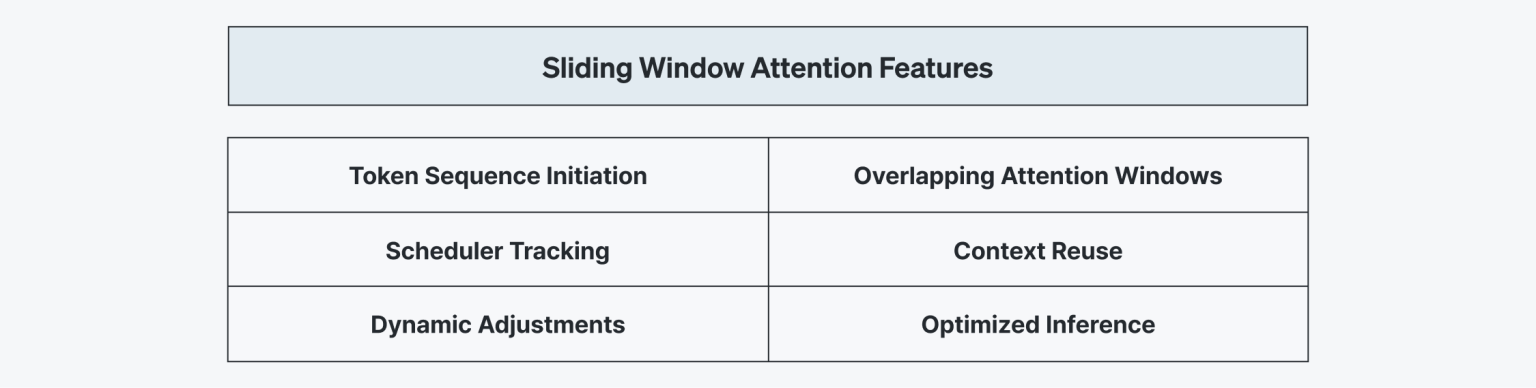
LLM Serving with NPU: Re-engineered, Built for Scale and Efficiency ...
LLM Serving with NPU: Re-engineered, Built for Scale and Efficiency ...

LLM Serving with NPU: Re-engineered, Built for Scale and Efficiency ...
LLM Serving with NPU: Re-engineered, Built for Scale and Efficiency ...
LLM Serving with NPU: Re-engineered, Built for Scale and Efficiency ...

Introducing Lemonade Server: Local LLM Serving with GPU and NPU ...
Advertisement Space (300x250)

Scale your Llm apps via cpu, gpu and npu with Lemonade! | Hisham Chowdhury

LLM Architecture for Massive Scale and Low Latency | Prakash Pujari ...

GitHub - skyiron/lemonadeLLMserverAI: Local LLM Server with GPU and NPU ...

🍋 Local LLM Serving with GPU & NPU Acceleration – A Deep Dive into the ...

NPUEval: the First LLM Benchmark for NPU Kernel Code Generation ...

How will next-gen NPU architectures scale local language models for ...

Hardware-Software Co-design for 3D-DRAM-based LLM Serving Accelerator

RaiderChip NPU leads edge LLM benchmarks against GPUs and CPUs in ...

RaiderChip NPU leads edge LLM benchmarks against GPUs and CPUs in ...
vLLM Review: Production-Grade Open-Source LLM Serving Built Around ...
Advertisement Space (336x280)

NXP Debuts i.MX 95 Armed with 3D Graphics and NPU Improvements - News
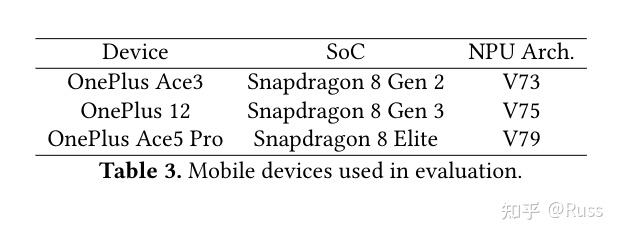
硬核端侧推理:《Scaling LLM Test-Time Compute with Mobile NPU on Smartphones》 - 知乎

Performance and Efficiency Gains of NPU-Based Servers over GPUs for AI ...

How We Built LLM Infrastructure That Actually Works — And What We ...

Efficient Mixture-of-Experts LLM Inference with Apple Silicon NPUs

[논문리뷰] NeuPIMs: NPU-PIM HeterogeneousAcceleration for Batched LLM ...

What's an NPU and Why Is Big Tech Suddenly Obsessed?

P3-LLM: An Integrated NPU-PIM Accelerator for LLM Inference Using ...
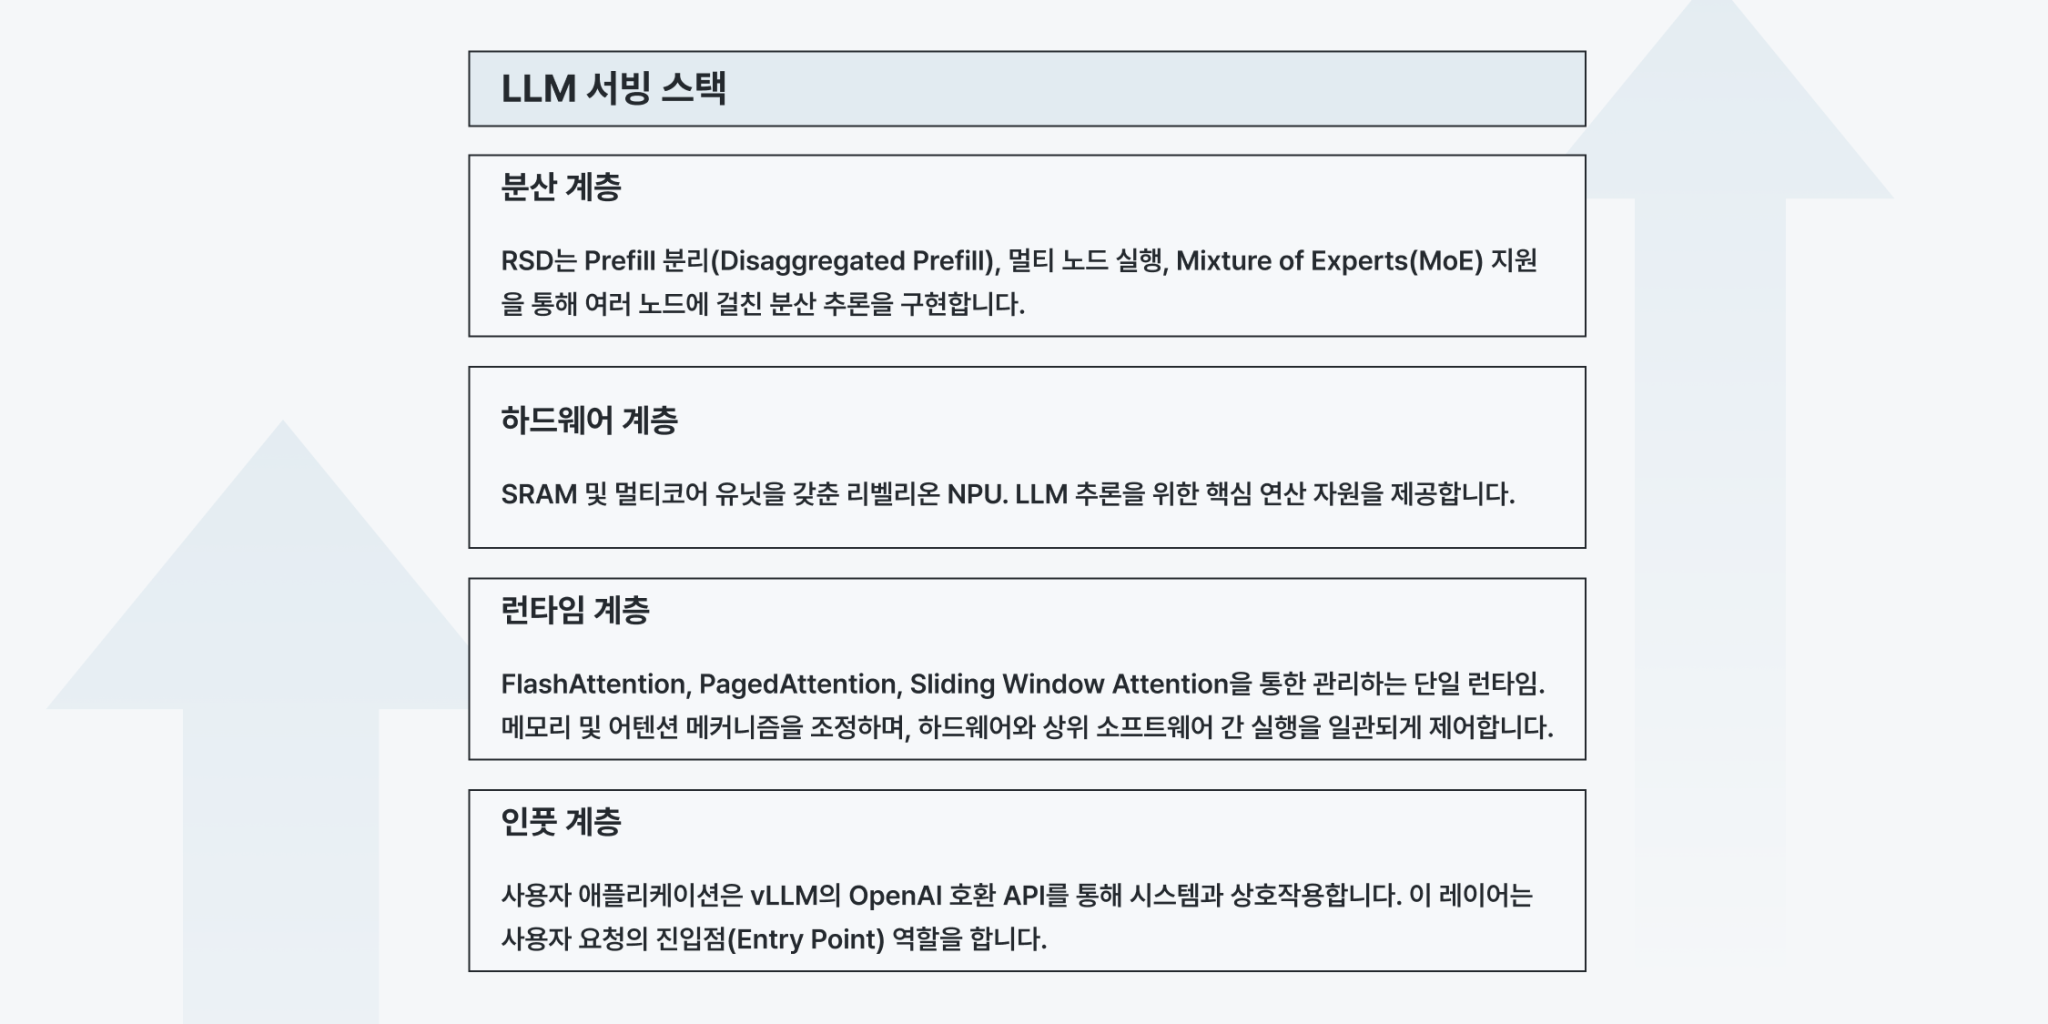
NPU 기반 LLM 서빙: 성능과 효율을 위한 새로운 시스템 - Rebellions
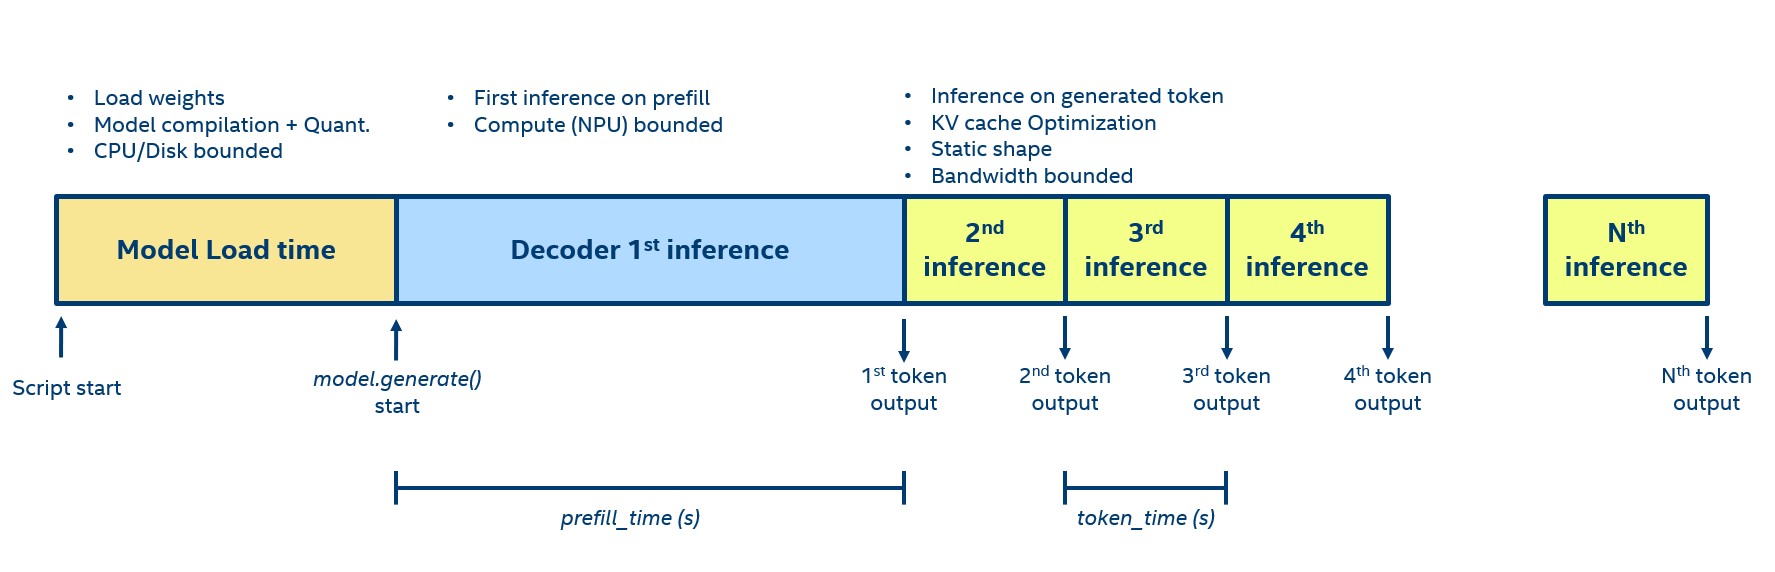
Decoding LLM performance — Intel® NPU Acceleration Library documentation
Advertisement Space (336x280)

LLM Serving — npu-sim

Rethinking Compute Substrates for 3D-Stacked Near-Memory LLM Decoding ...

New Arrivals: LLM Offline Model for AI Tasks | TikTok
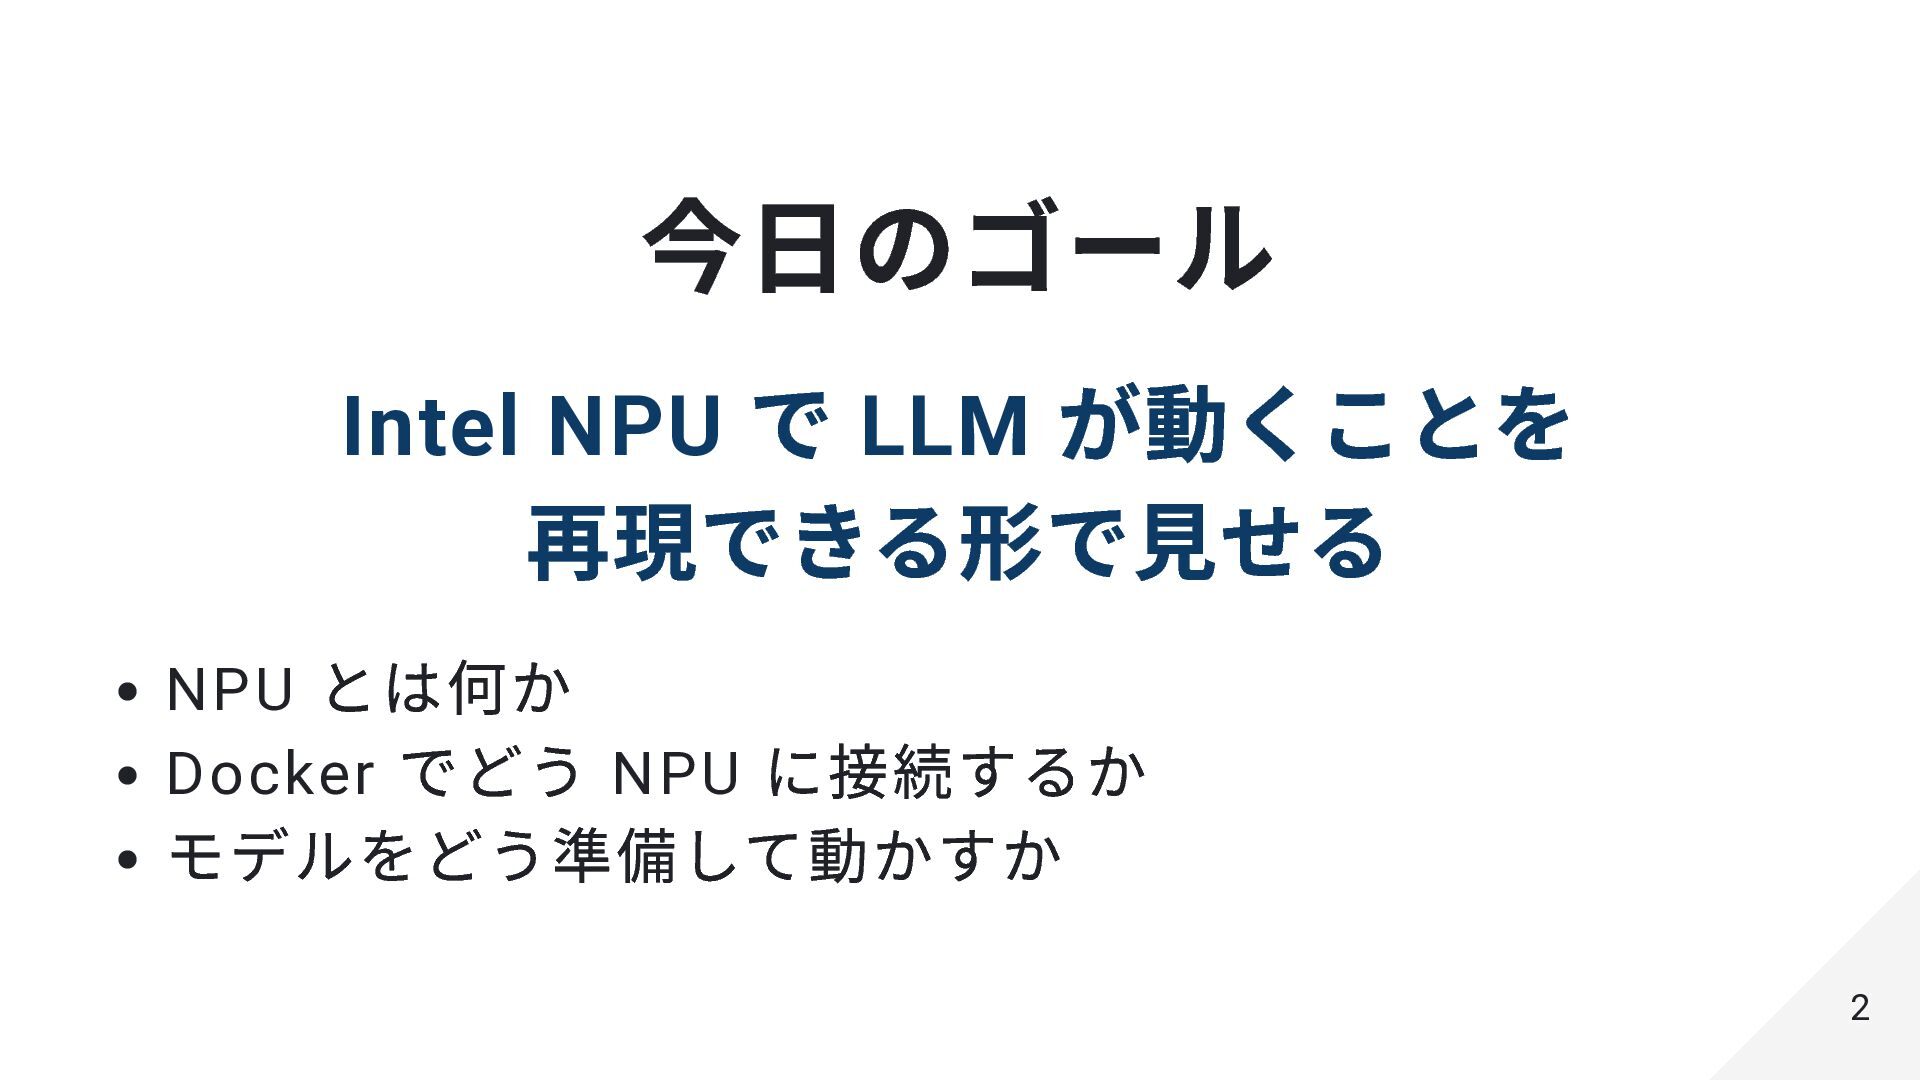
Inetl NPU でローカル LLM - Speaker Deck

(PDF) P3-LLM: An Integrated NPU-PIM Accelerator for LLM Inference Using ...

Scaling AI in production: A practical guide to LLM Serving - Fractal ...