How Does Tensorrt Implement Specific Layers Using Fp16 Precision
How does Tensorrt implement specific layers using FP16 precision ...
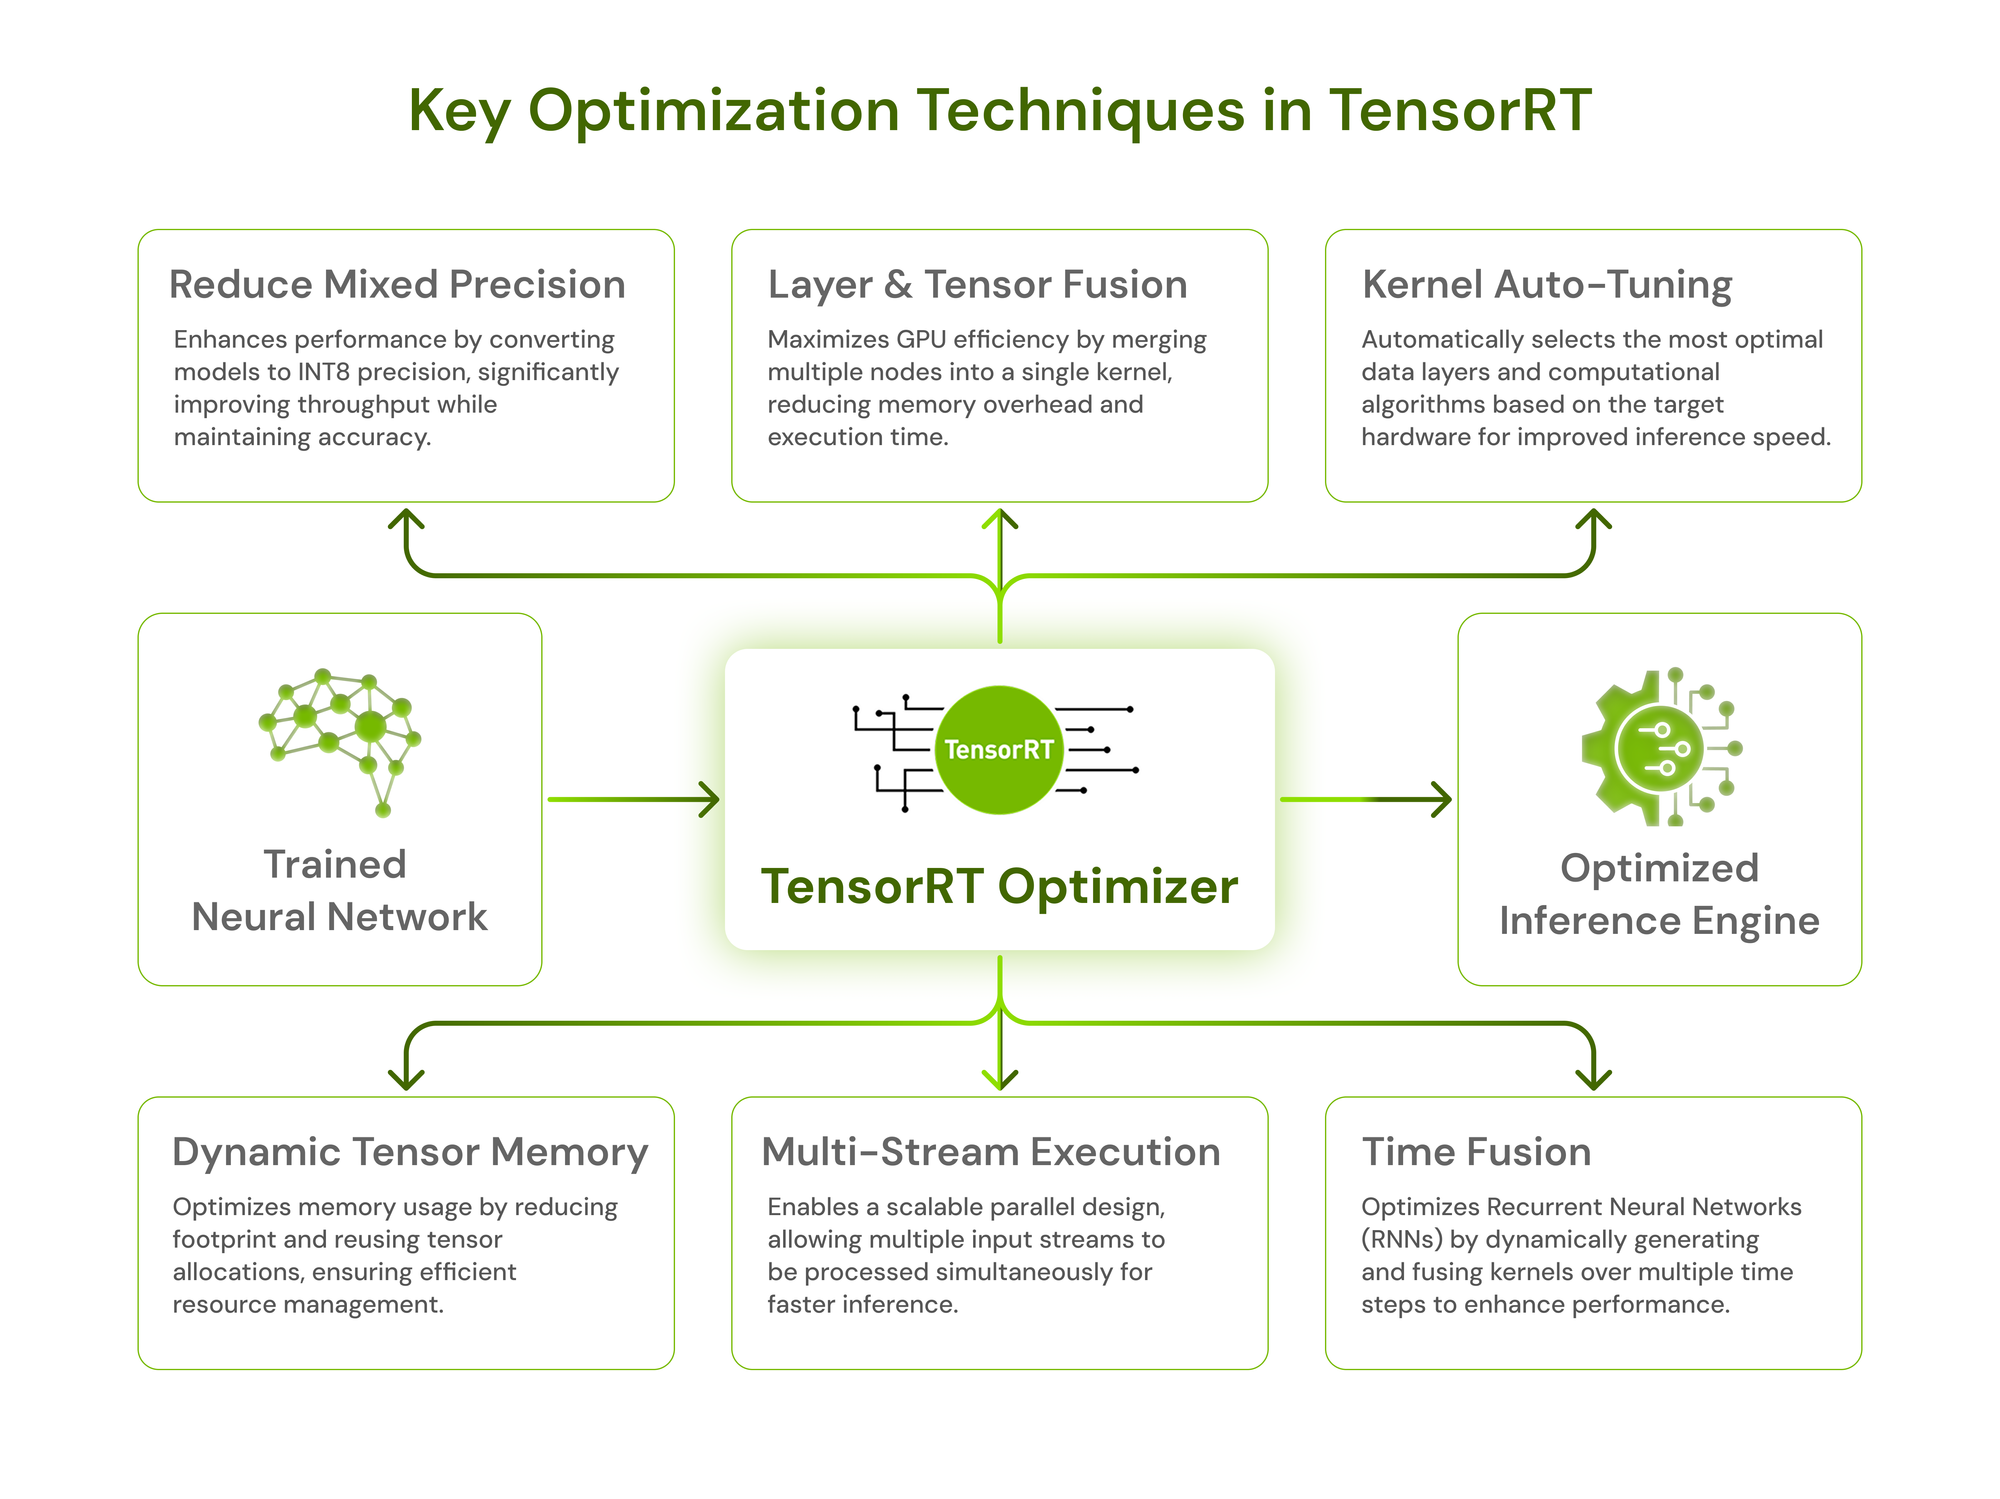
How to optimize inference using TensorRT on Jetson AGX Orin
How to use FP16 precision in C++ · Issue #1754 · NVIDIA/TensorRT · GitHub

Model does not get Int8 layers - TensorRT - NVIDIA Developer Forums

Quantization FP16 model using pytorch_quantization and TensorRT · Issue ...

Jetson Edge Cihazlarında YOLOv9 Model Optimizasyonu: TensorRT ile FP16 ...

Using TensorRT to Accelerate Inference · microsoft/MMdnn Wiki · GitHub
"Fp16 precision has been set for a layer or layer output, but fp16 is ...

Using TensorRT to Accelerate Inference · microsoft/MMdnn Wiki · GitHub

Mixed precision training. Red and green paths represent FP32 and FP16 ...
Advertisement Space (300x250)
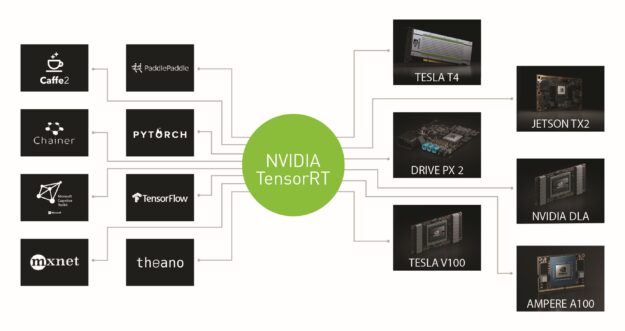
Estimating Depth with ONNX Models and Custom Layers Using NVIDIA ...

TensorRT int8 slower than FP16 due to reformat layer - TensorRT ...

TensorRT int8 slower than FP16 due to reformat layer - TensorRT ...

Estimating Depth with ONNX Models and Custom Layers Using NVIDIA ...
How to specify some not all layer precision in tensorrt? · Issue #3118 ...

Does tensorRT inference app eat cuda resources? - TensorRT - NVIDIA ...
Using TensorRT to Accelerate Inference · microsoft/MMdnn Wiki · GitHub

Speed up TensorFlow Inference on GPUs with TensorRT — The TensorFlow Blog

TensorRT survey | PPTX
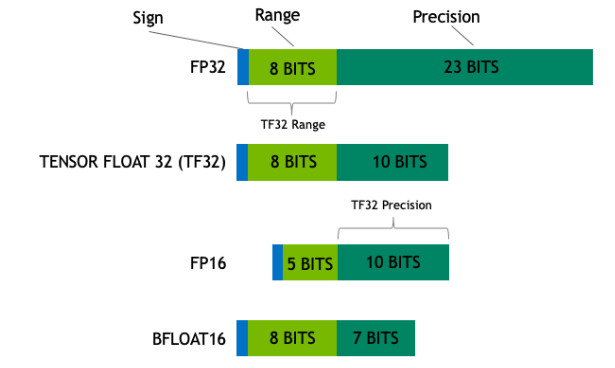
Accuracy Considerations — NVIDIA TensorRT
Advertisement Space (336x280)

Recovering single precision accuracy from Tensor Cores while surpassing ...

Tag: FP16 | NVIDIA Technical Blog

NVIDIA TensorRT for RTX Introduces an Optimized Inference AI Library on ...

NVIDIA TensorRT Accelerates Stable Diffusion Nearly 2x Faster with 8 ...

Achieving FP32 Accuracy for INT8 Inference Using Quantization Aware ...
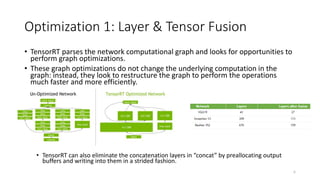
TensorRT survey | PPTX

TensorRT survey | PPTX

TensorRT survey | PPTX
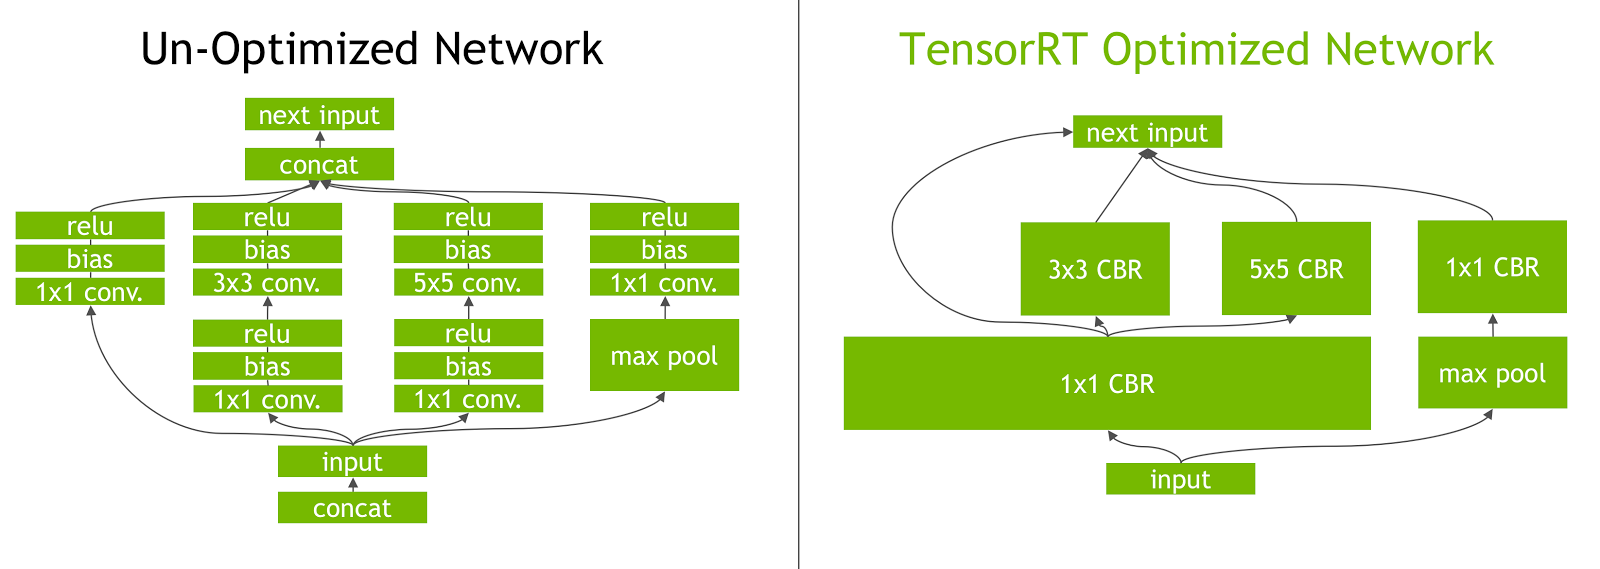
TensorRT - Ultralytics YOLO Docs
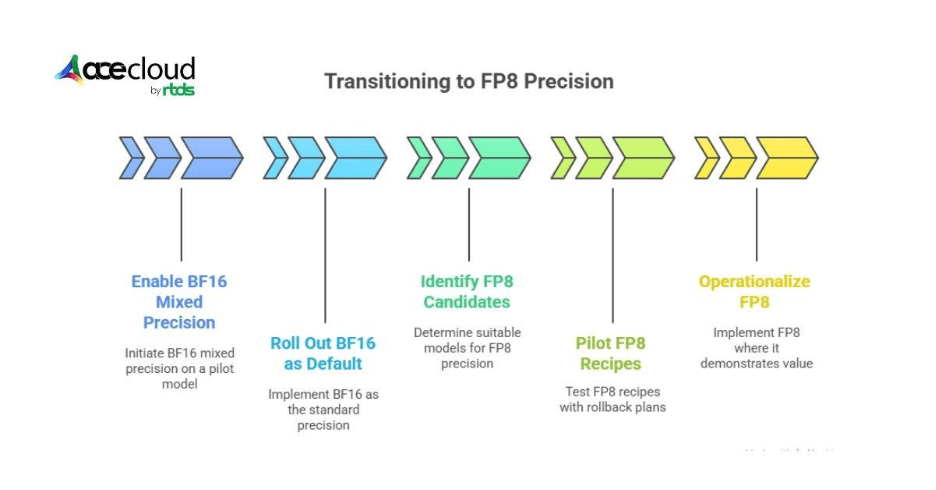
FP8 Vs BF16: Choosing Mixed Precision On NVIDIA Tensor Cores
Advertisement Space (336x280)
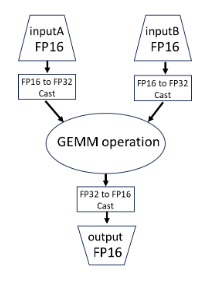
Advanced Topics — NVIDIA TensorRT

GitHub - LSH9832/pysot-tensorrt: convert most of pysot network layers ...

TensorRT部署系列 | 如何将模型从 PyTorch 转换为 TensorRT 并加速推理?-阿里云开发者社区
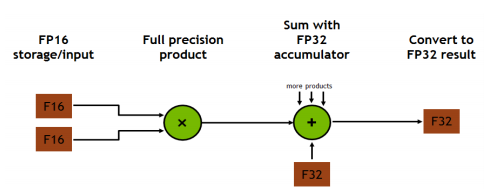
Mixed Precision Training for NLP and Speech Recognition with ...
Layer-wise precision in bf16, and fp8 · Issue #3735 · NVIDIA/TensorRT ...
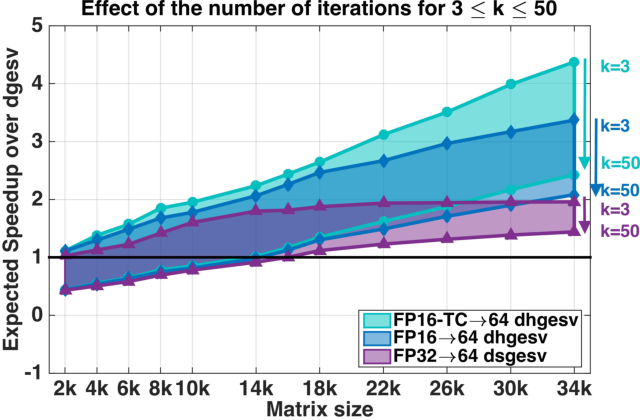
Figure 4 from Harnessing GPU Tensor Cores for Fast FP16 Arithmetic to ...