
How To Configure Vllm For Llm Serving
How to Configure vLLM for LLM Serving
How to Install and Configure vLLM on Ubuntu for Fast LLM Inference and ...

How vLLM solves LLM serving issues for AI apps | Aaroh Bhardwaj posted ...
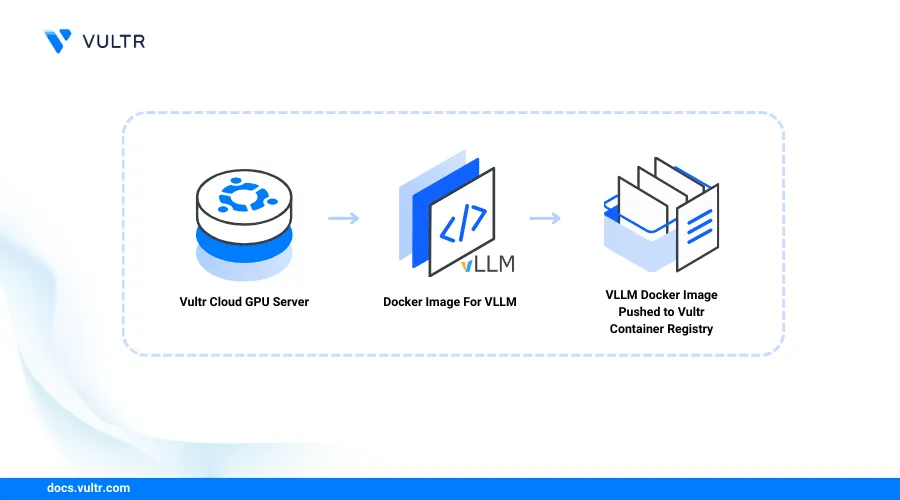
How to Build a vLLM Container Image for LLM Deployment | Vultr Docs

How to easily migrate LLM inference serving from vLLM to Friendli ...

Install vLLM on Linux for Production LLM Serving (2026 Guide)

Install vLLM on Linux for Production LLM Serving (2026 Guide)

A Gentle Introduction to vLLM for Serving - KDnuggets

Install vLLM on Linux for Production LLM Serving (2026 Guide)

Install vLLM on Linux for Production LLM Serving (2026 Guide)
Advertisement Space (300x250)
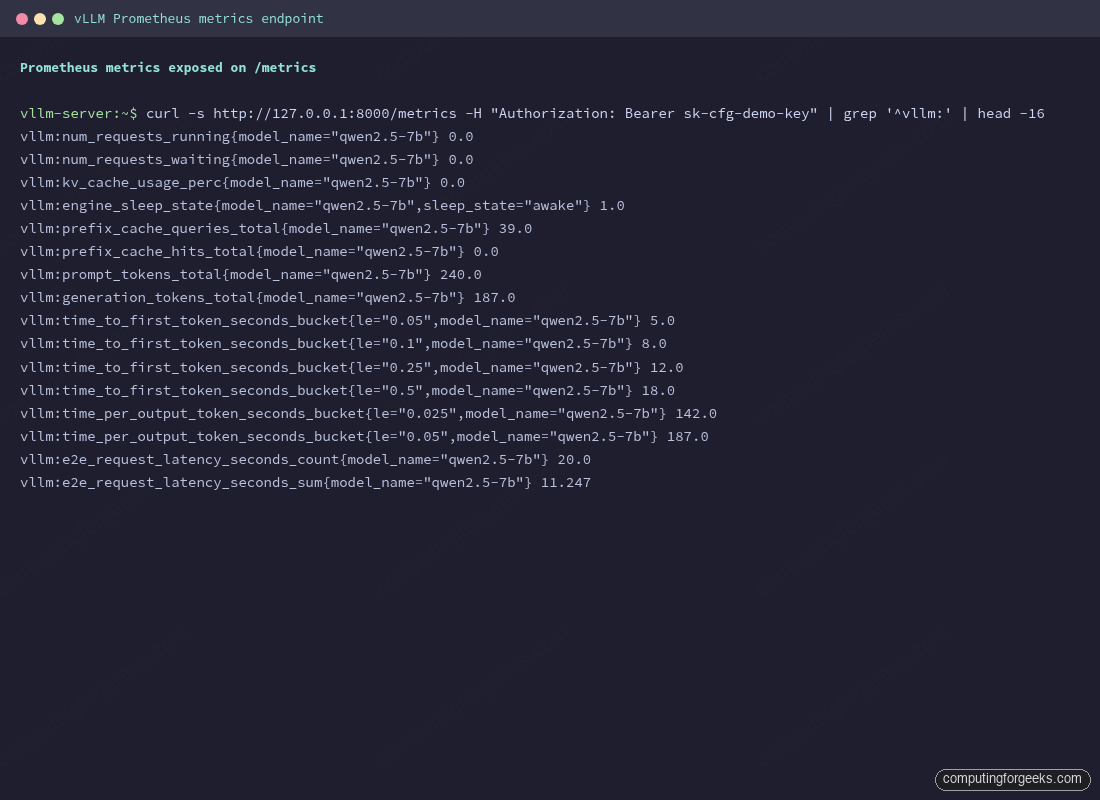
Install vLLM on Linux for Production LLM Serving (2026 Guide)

Install vLLM on Linux for Production LLM Serving (2026 Guide)
🚀 The Ultimate Guide to LLM Serving Frameworks for On-Premises ...
Ray Serve LLM on Anyscale: Wide-EP and Disaggregated Serving with vLLM
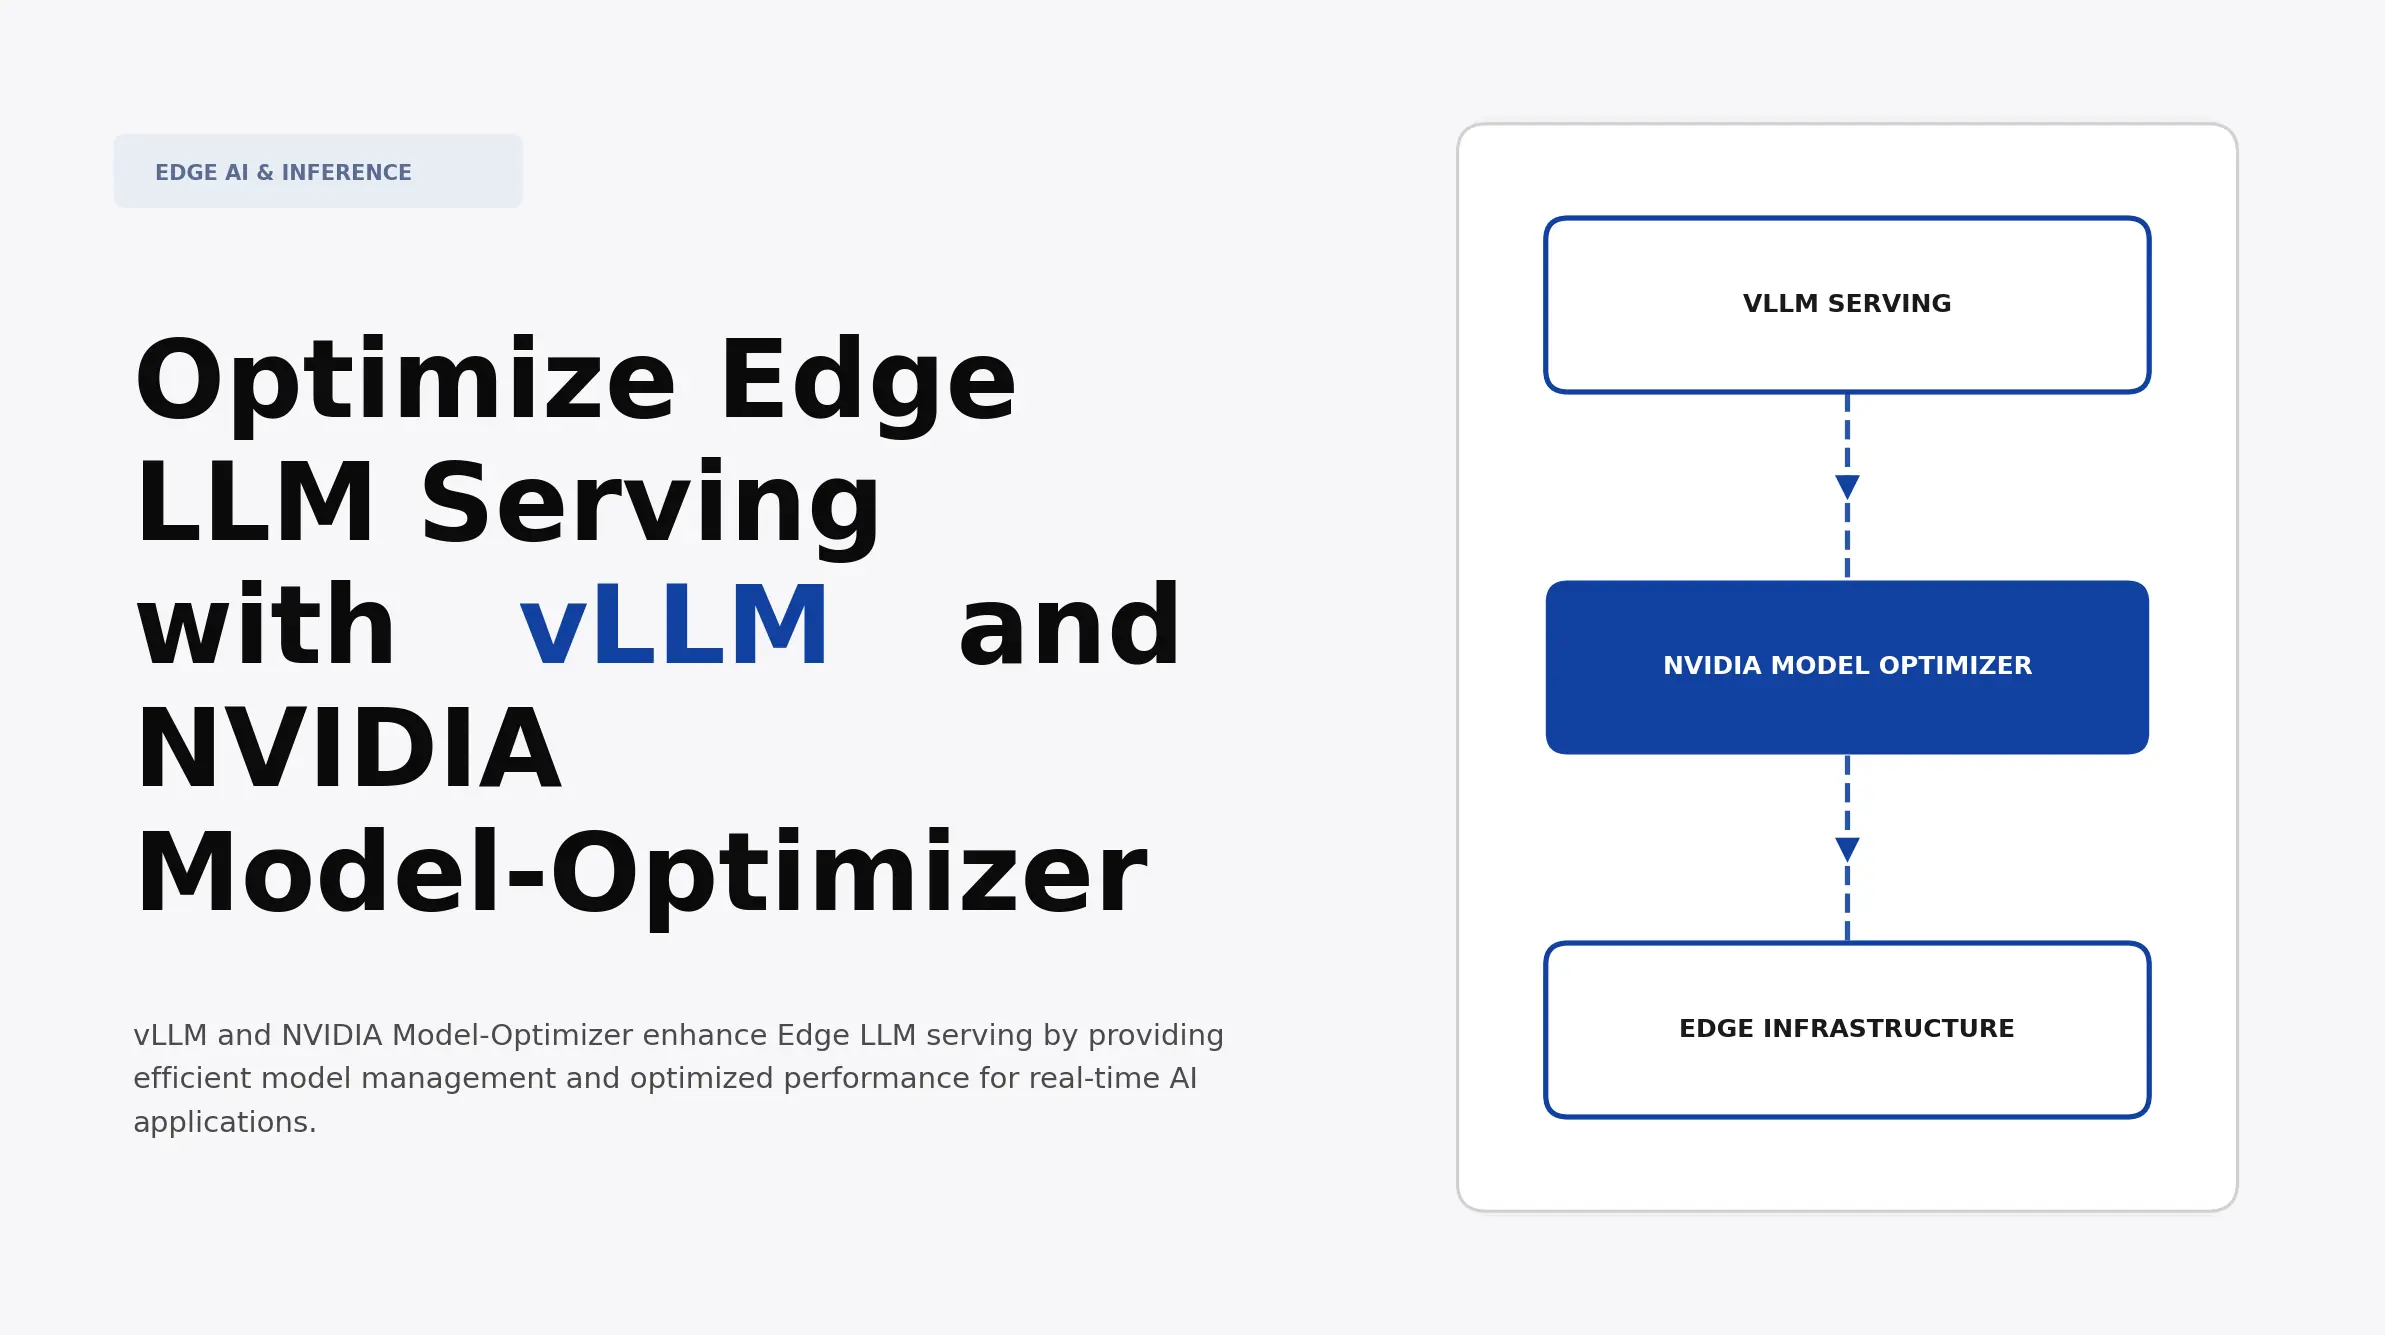
Optimize Edge LLM Serving with vLLM and NVIDIA Model-Optimizer | Atomic ...
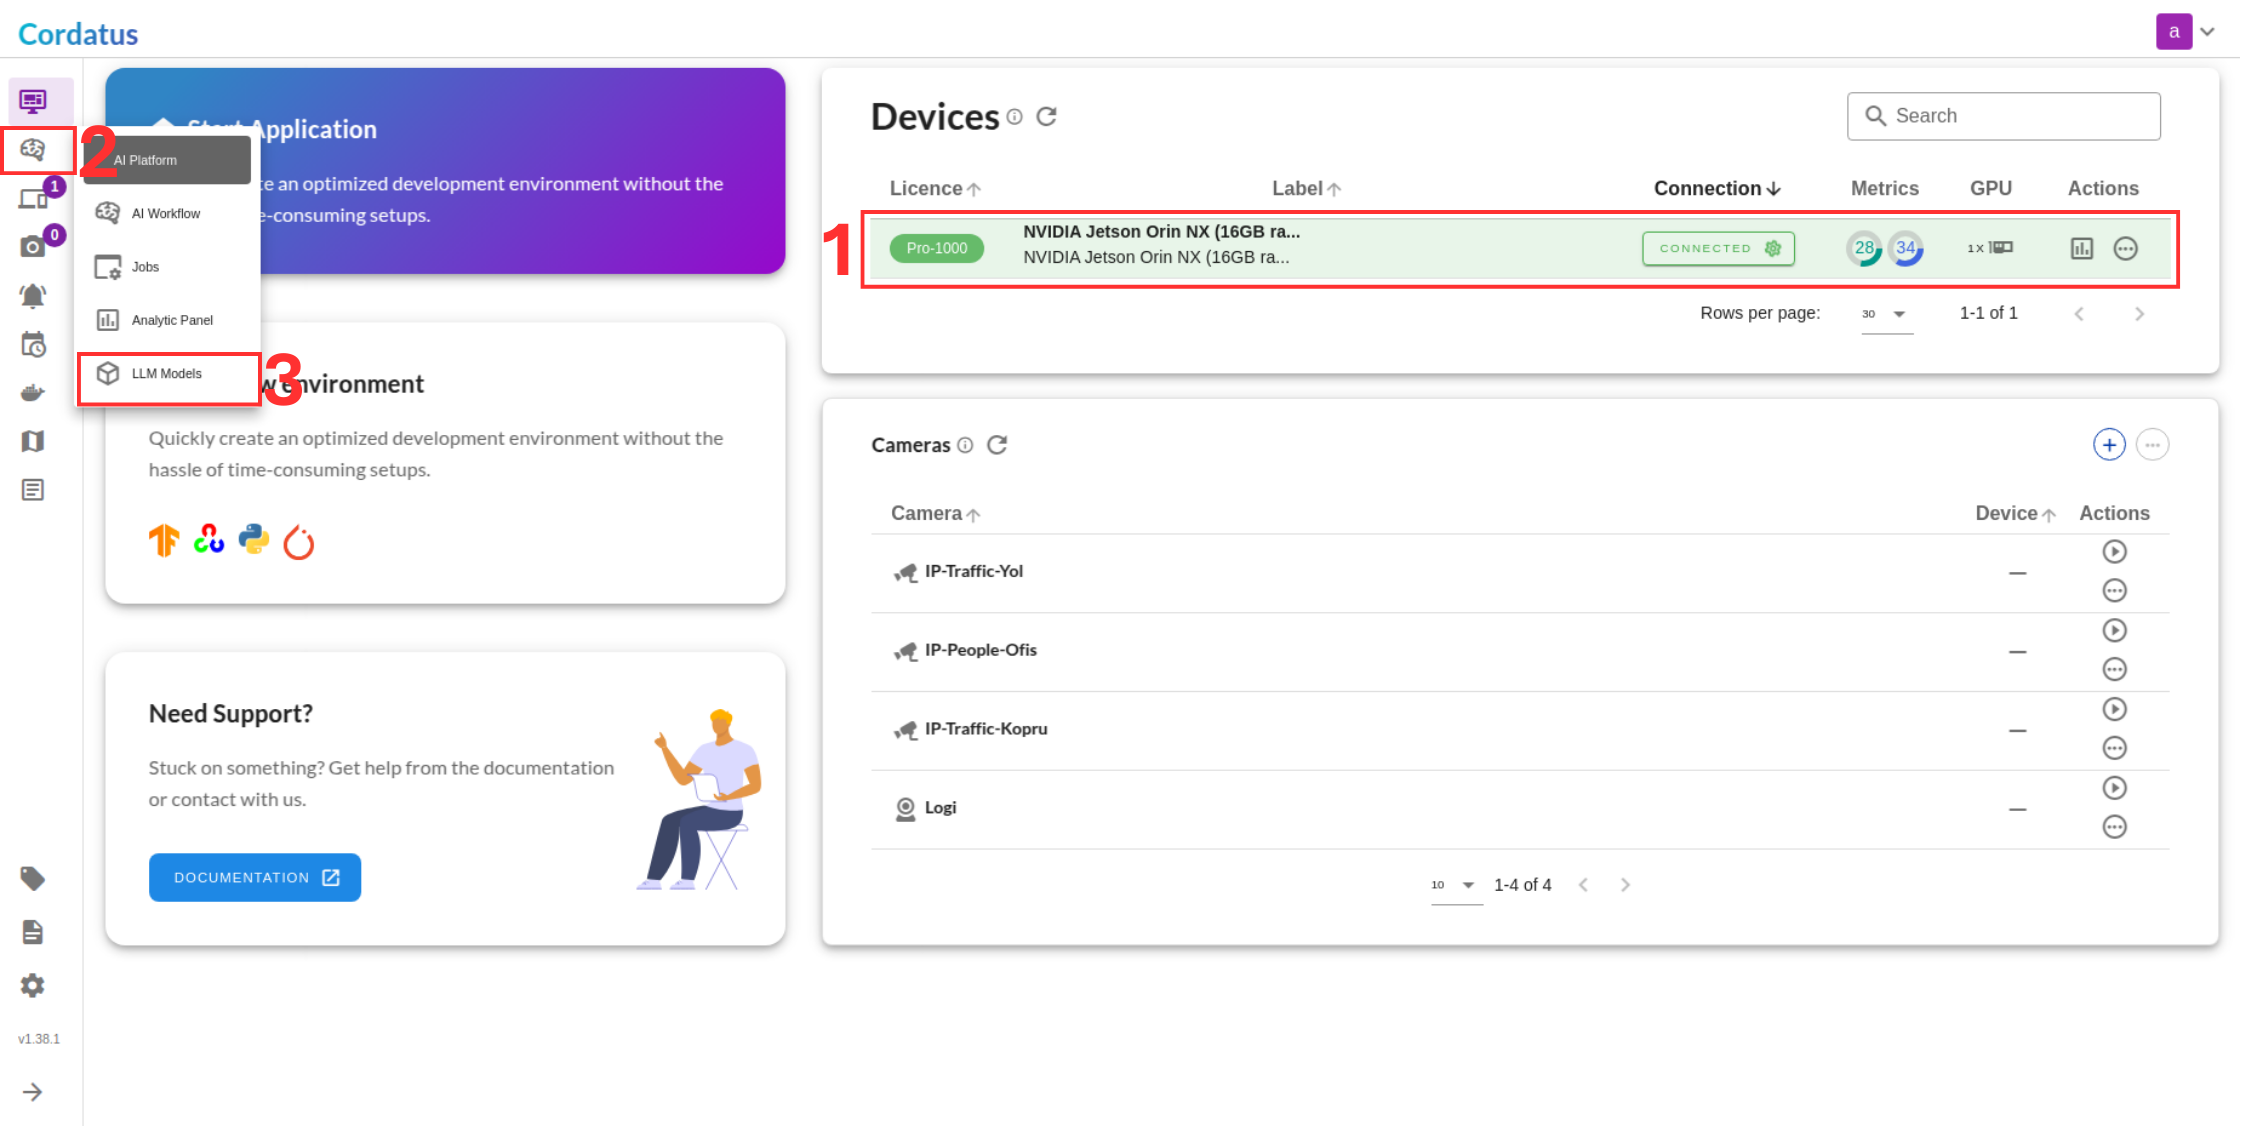
vLLM: Easy, Fast & Cost‑Effective LLM Serving for Everyone
vLLM Tutorial: Fast, OpenAI‑Compatible LLM Serving Guide

vLLM Tutorial: Fast, OpenAI‑Compatible LLM Serving Guide

[vLLM vs TensorRT-LLM] #2. Towards Optimal Batching for LLM Serving ...
Deploying local LLM hosting for free with vLLM
Advertisement Space (336x280)
vLLM Tutorial: Fast, OpenAI‑Compatible LLM Serving Guide

How to setup an LLM on PC examples
Efficient LLM Inference and Serving with vLLM
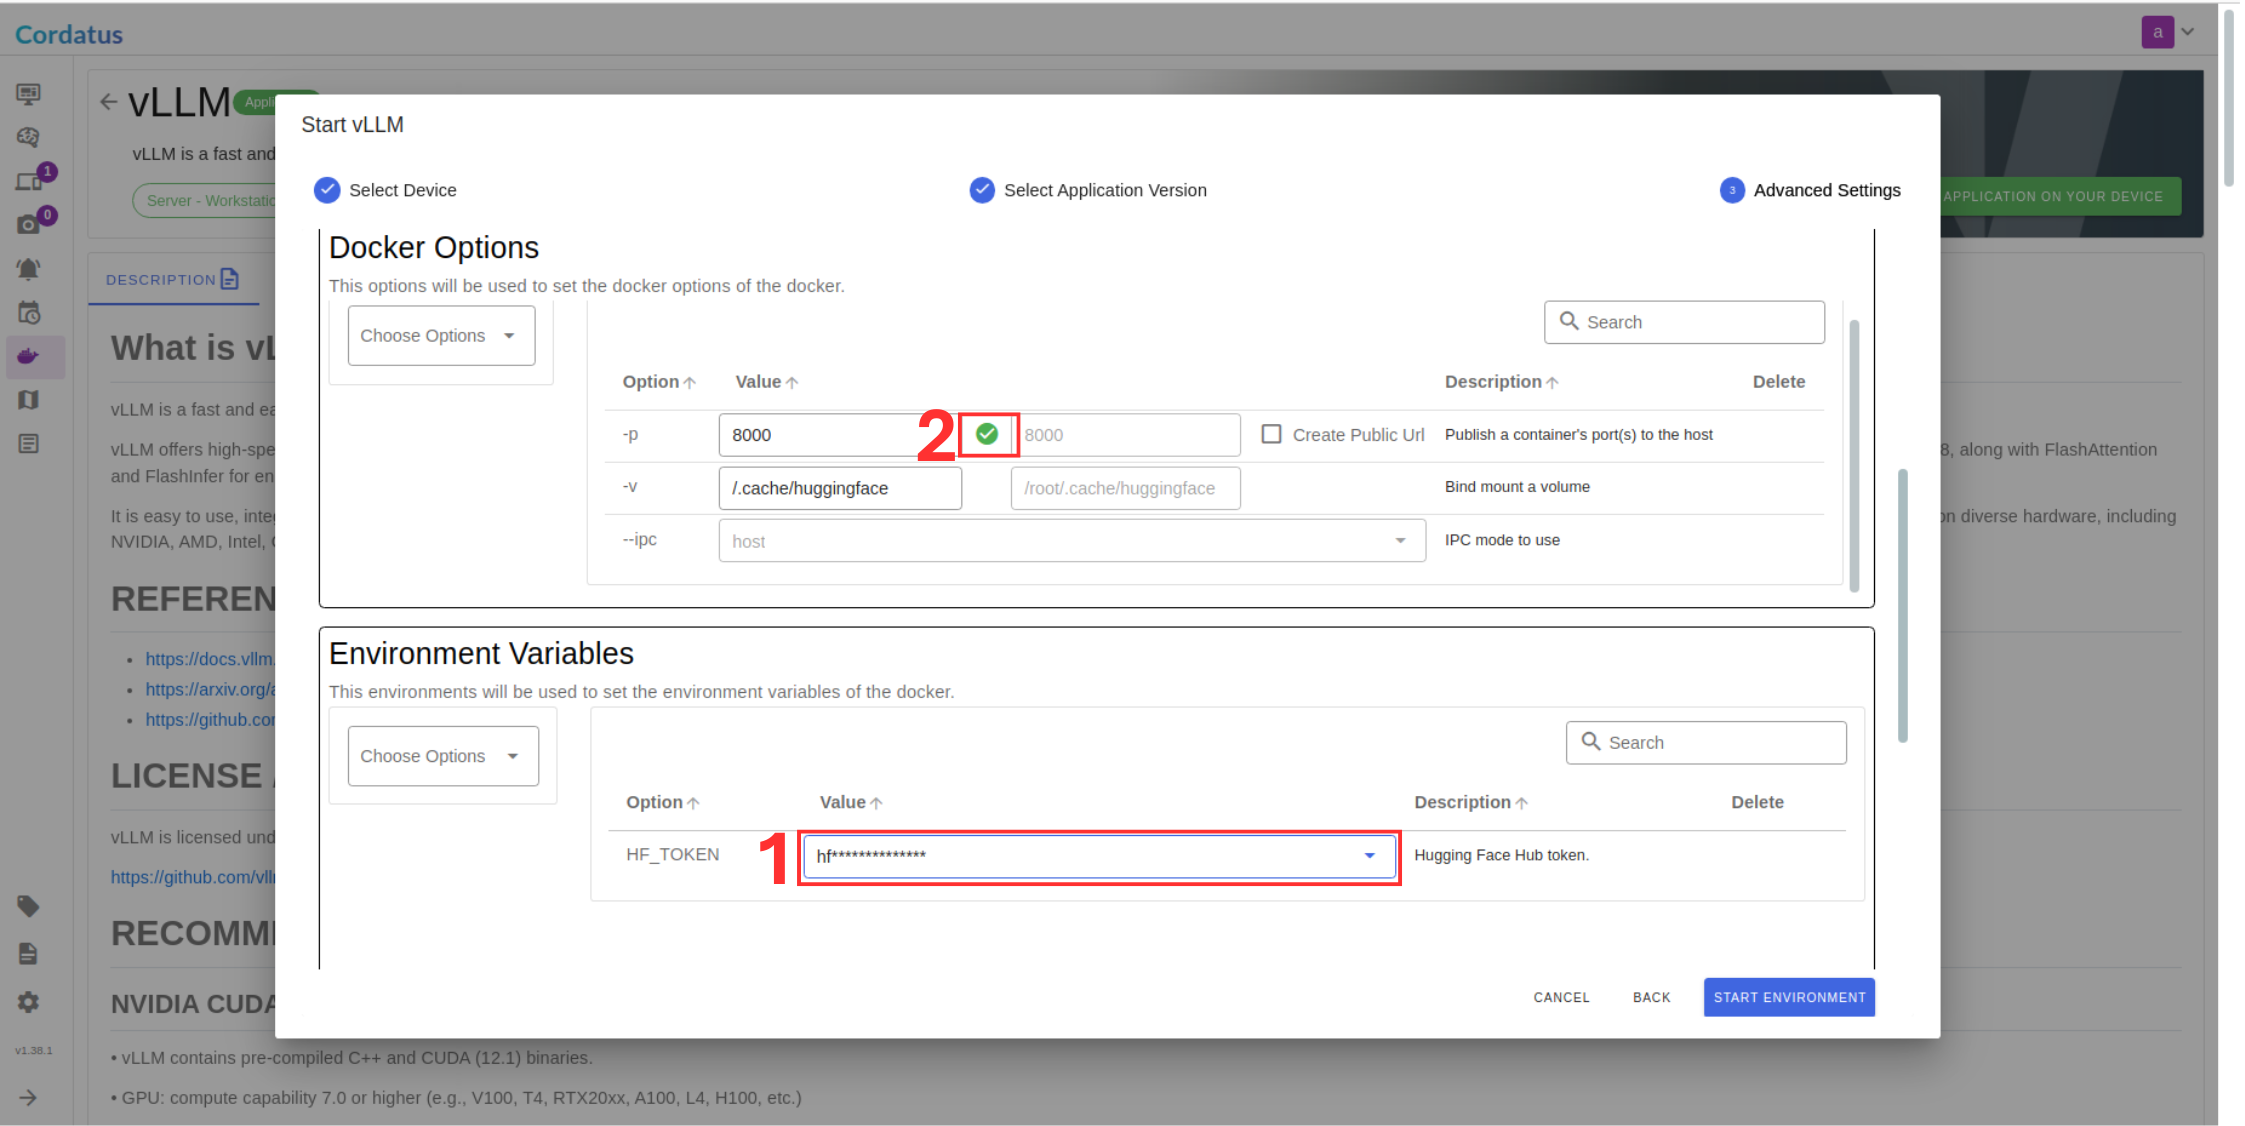
vLLM: Easy, Fast & Cost‑Effective LLM Serving for Everyone
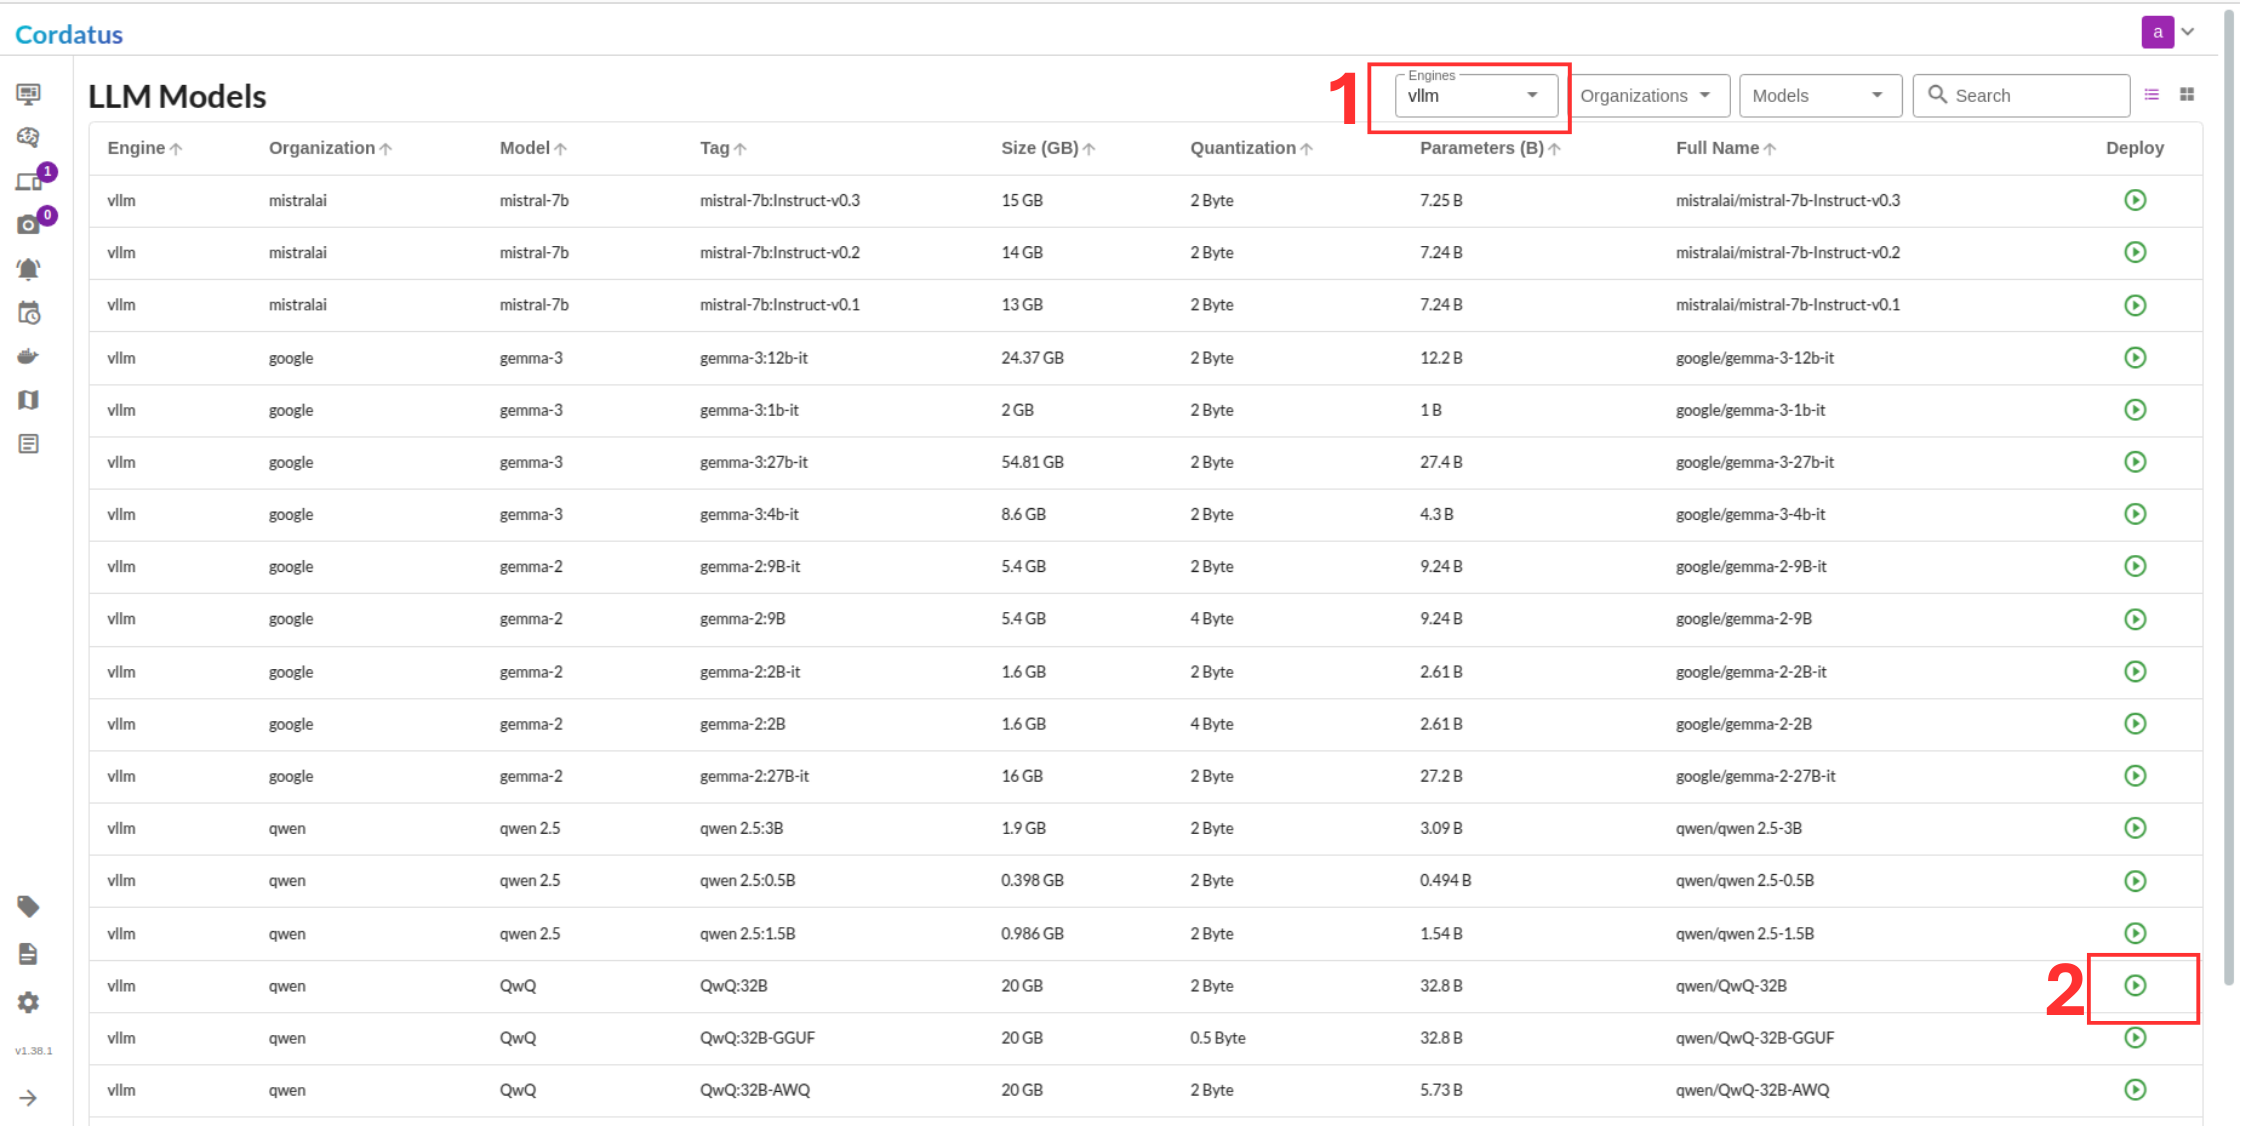
vLLM: Easy, Fast & Cost‑Effective LLM Serving for Everyone
vLLM Guide 2026 | High-Throughput LLM Serving
Ollama vs vLLM: A Performance-Focused Guide to LLM Serving

Fast LLM Serving with vLLM and PagedAttention - YouTube
vLLM Tutorial: Fast, OpenAI‑Compatible LLM Serving Guide
vLLM: Easy, Fast & Cost‑Effective LLM Serving for Everyone
Advertisement Space (336x280)

Free Video: Scalable and Efficient LLM Serving With the VLLM Production ...

VLLM: Using PagedAttention To Optimize LLM Inference and Serving | PDF ...

vLLM Tutorial: Fast, OpenAI‑Compatible LLM Serving Guide

Meet vLLM: For faster, more efficient LLM inference and serving

Multi-Node LLM Serving Using sig LWS and vLLM - CECG