
A Gentle Introduction To Vllm For Serving Kdnuggets

A Gentle Introduction to vLLM for Serving - KDnuggets
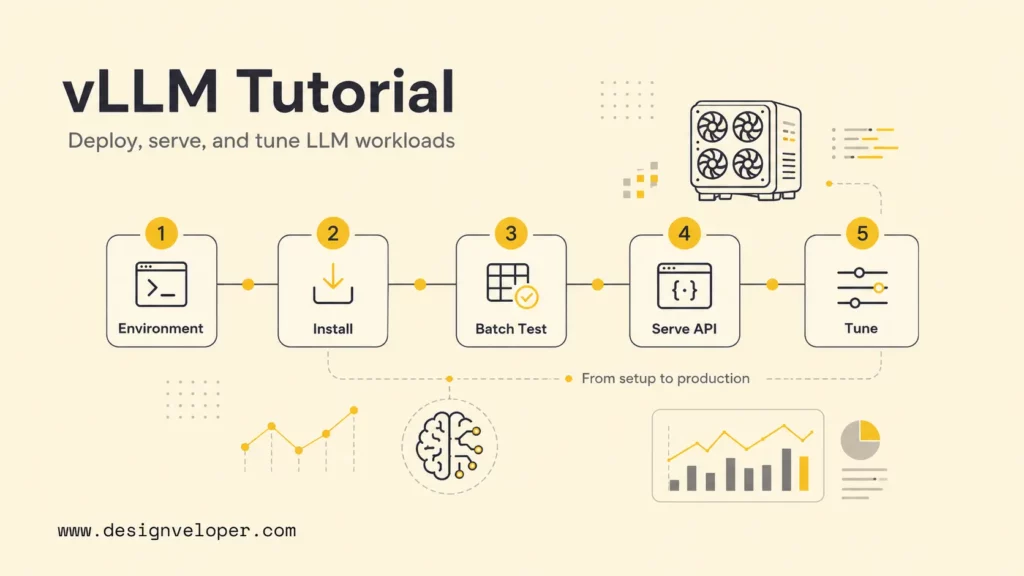
vLLM Tutorial: A Step-By-Step Guide To Deploying And Serving LLMs ...
Structured Decoding in vLLM: a gentle introduction | vLLM Blog

A Brief Introduction to Optimized Batched Inference with vLLM | by ...

Structured Decoding in vLLM: a gentle introduction | vLLM Blog
How to Configure vLLM for LLM Serving
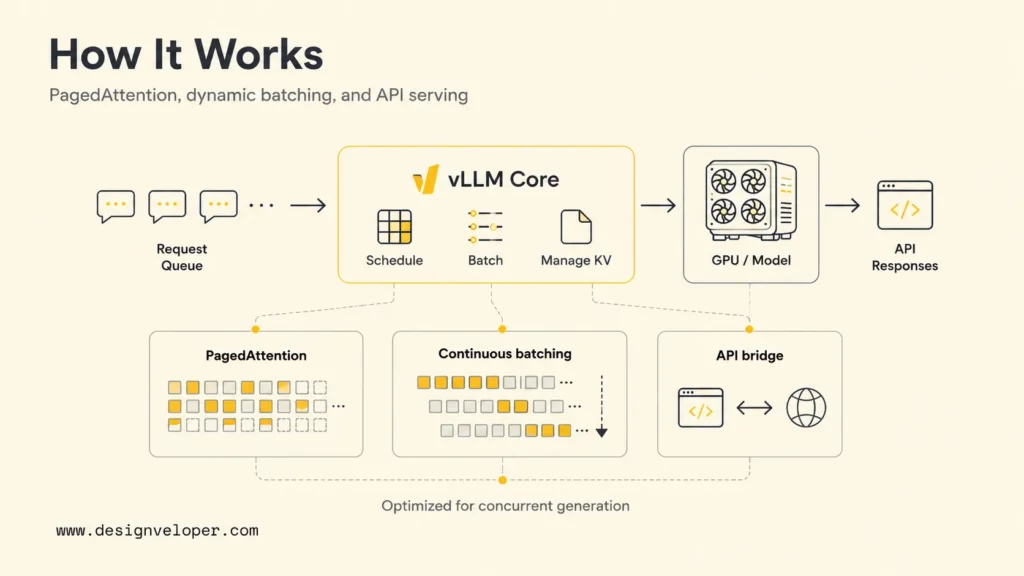
vLLM Tutorial: A Step-By-Step Guide To Deploying And Serving LLMs ...
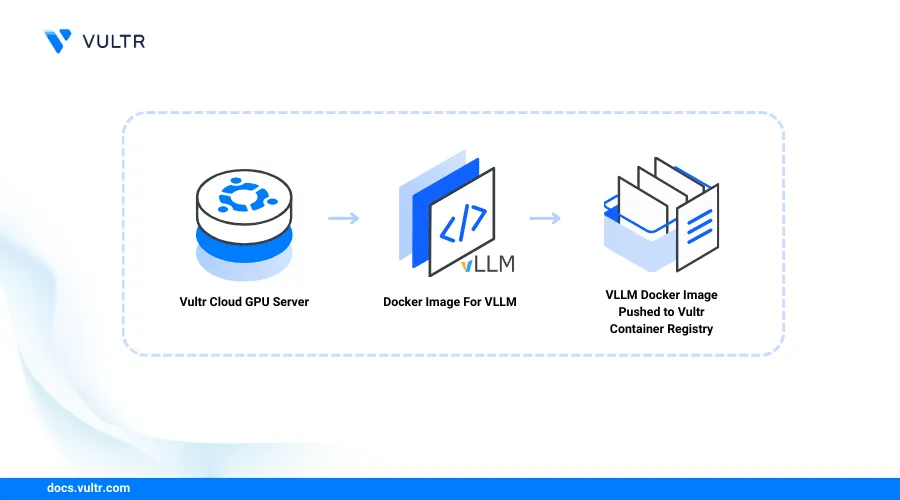
How to Build a vLLM Container Image for LLM Deployment | Vultr Docs

Introduction to vLLM: A High-Performance LLM Serving Engine - The New Stack
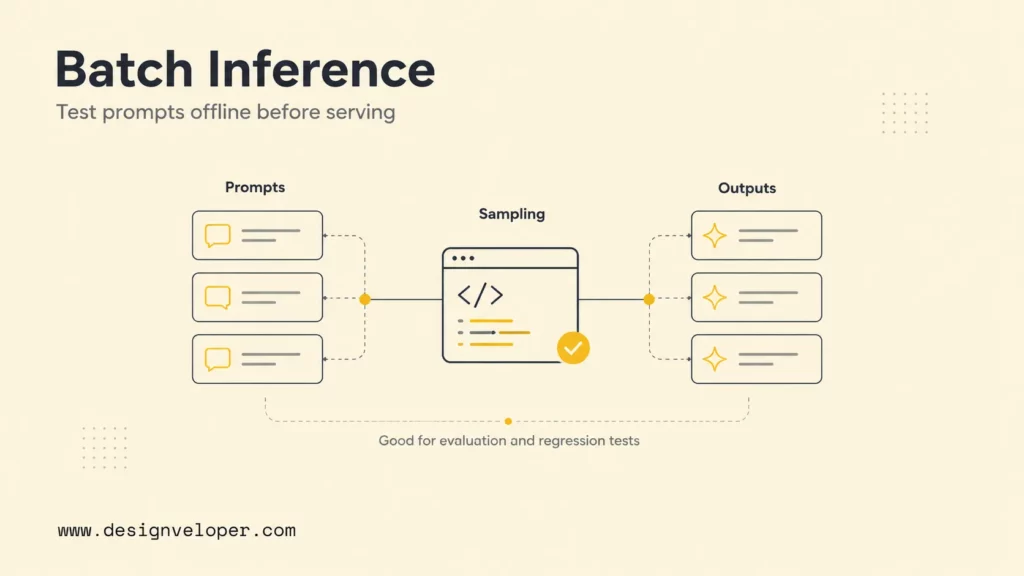
vLLM Tutorial: A Step-By-Step Guide To Deploying And Serving LLMs ...
Advertisement Space (300x250)
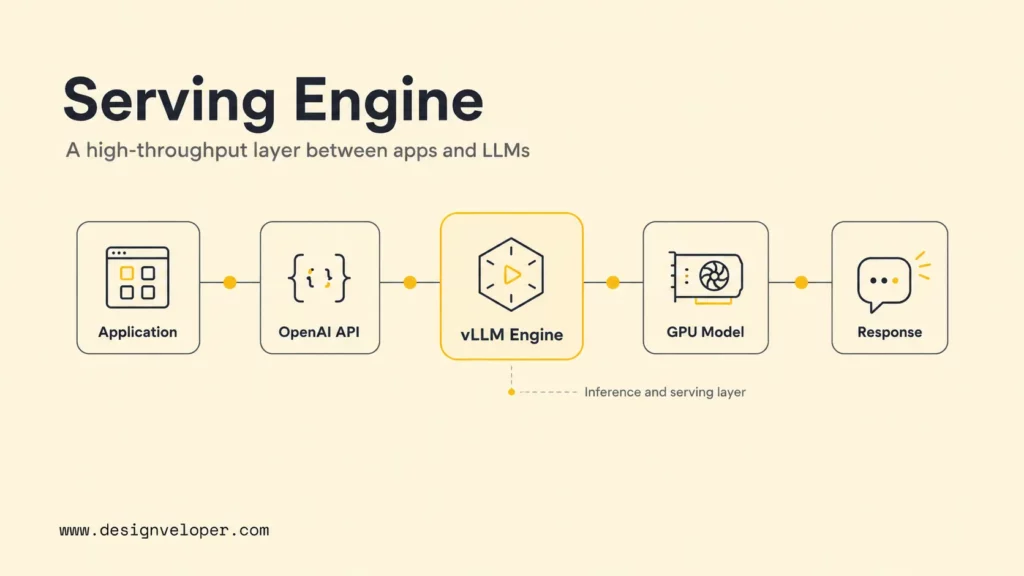
vLLM Tutorial: A Step-By-Step Guide To Deploying And Serving LLMs ...
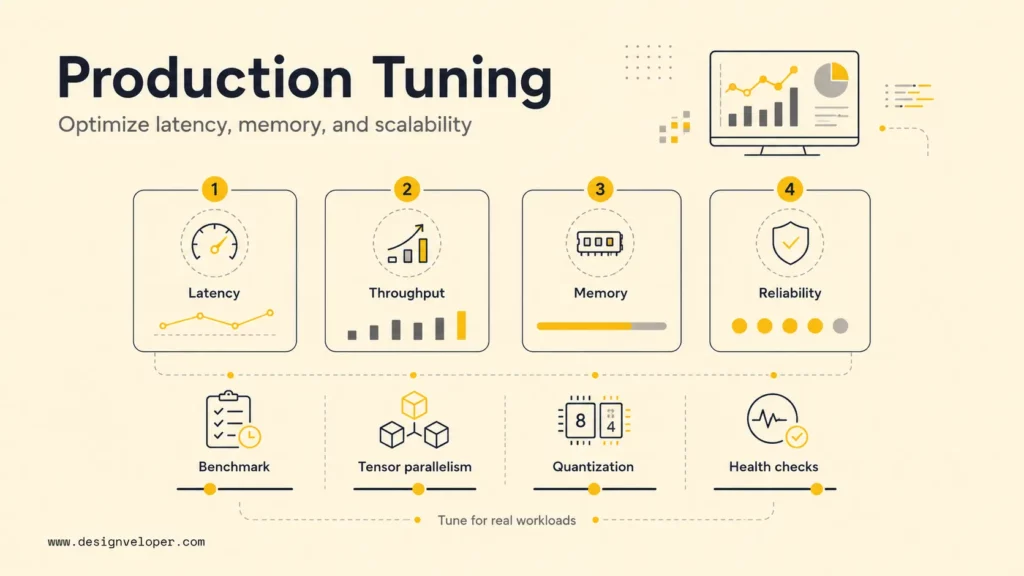
vLLM Tutorial: A Step-By-Step Guide To Deploying And Serving LLMs ...
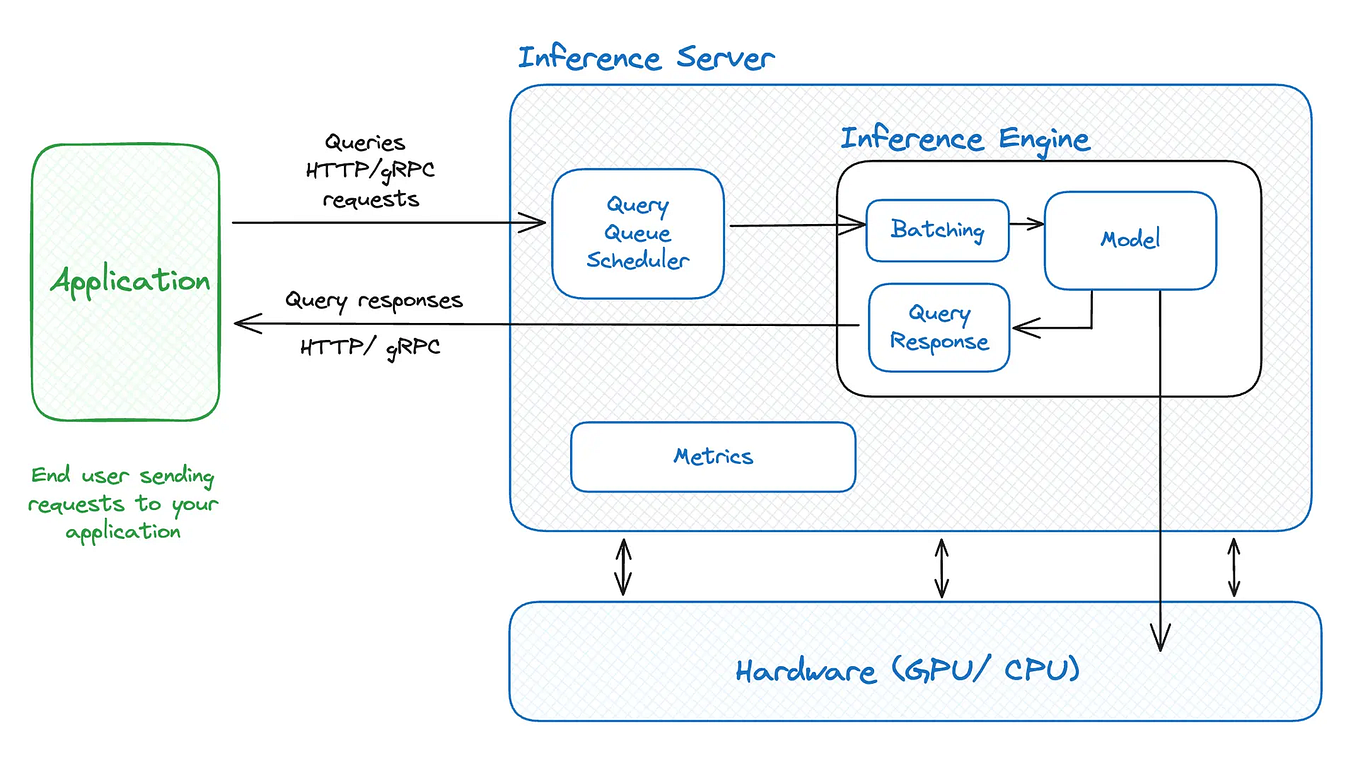
A Brief Introduction to Optimized Batched Inference with vLLM | by ...
Introduction to vLLM | lowtouch.ai

Structured Decoding in vLLM: A Gentle Introduction

How vLLM solves LLM serving issues for AI apps | Aaroh Bhardwaj posted ...
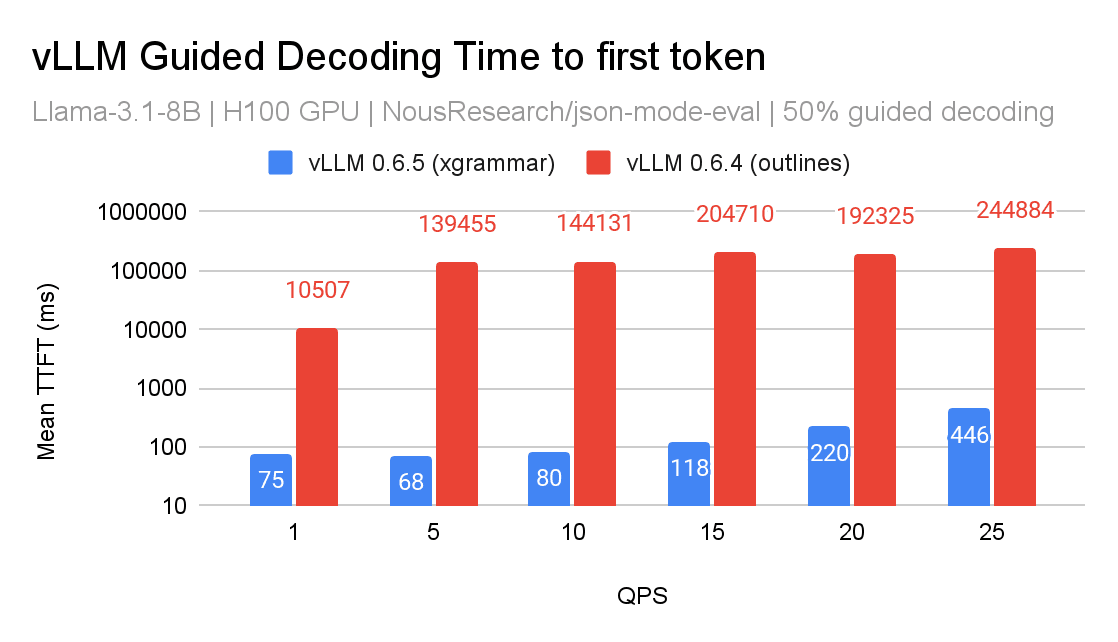
Structured Decoding in vLLM: A Gentle Introduction

Structured Decoding in vLLM: A Gentle Introduction

Install vLLM on Linux for Production LLM Serving (2026 Guide)

Introduction to vLLM and PagedAttention | Runpod Blog
Advertisement Space (336x280)

Serving Large Language Models with vLLM on AMD ROCm GPUs | by Trade ...
vLLM Tutorial: Fast, OpenAI‑Compatible LLM Serving Guide
Ray Serve LLM on Anyscale: Wide-EP and Disaggregated Serving with vLLM

vLLM in Practice: A Developer’s Guide to... book by Kairo Corvin
Self-Hosting LLMs on Kubernetes: Serving LLMs using vLLM
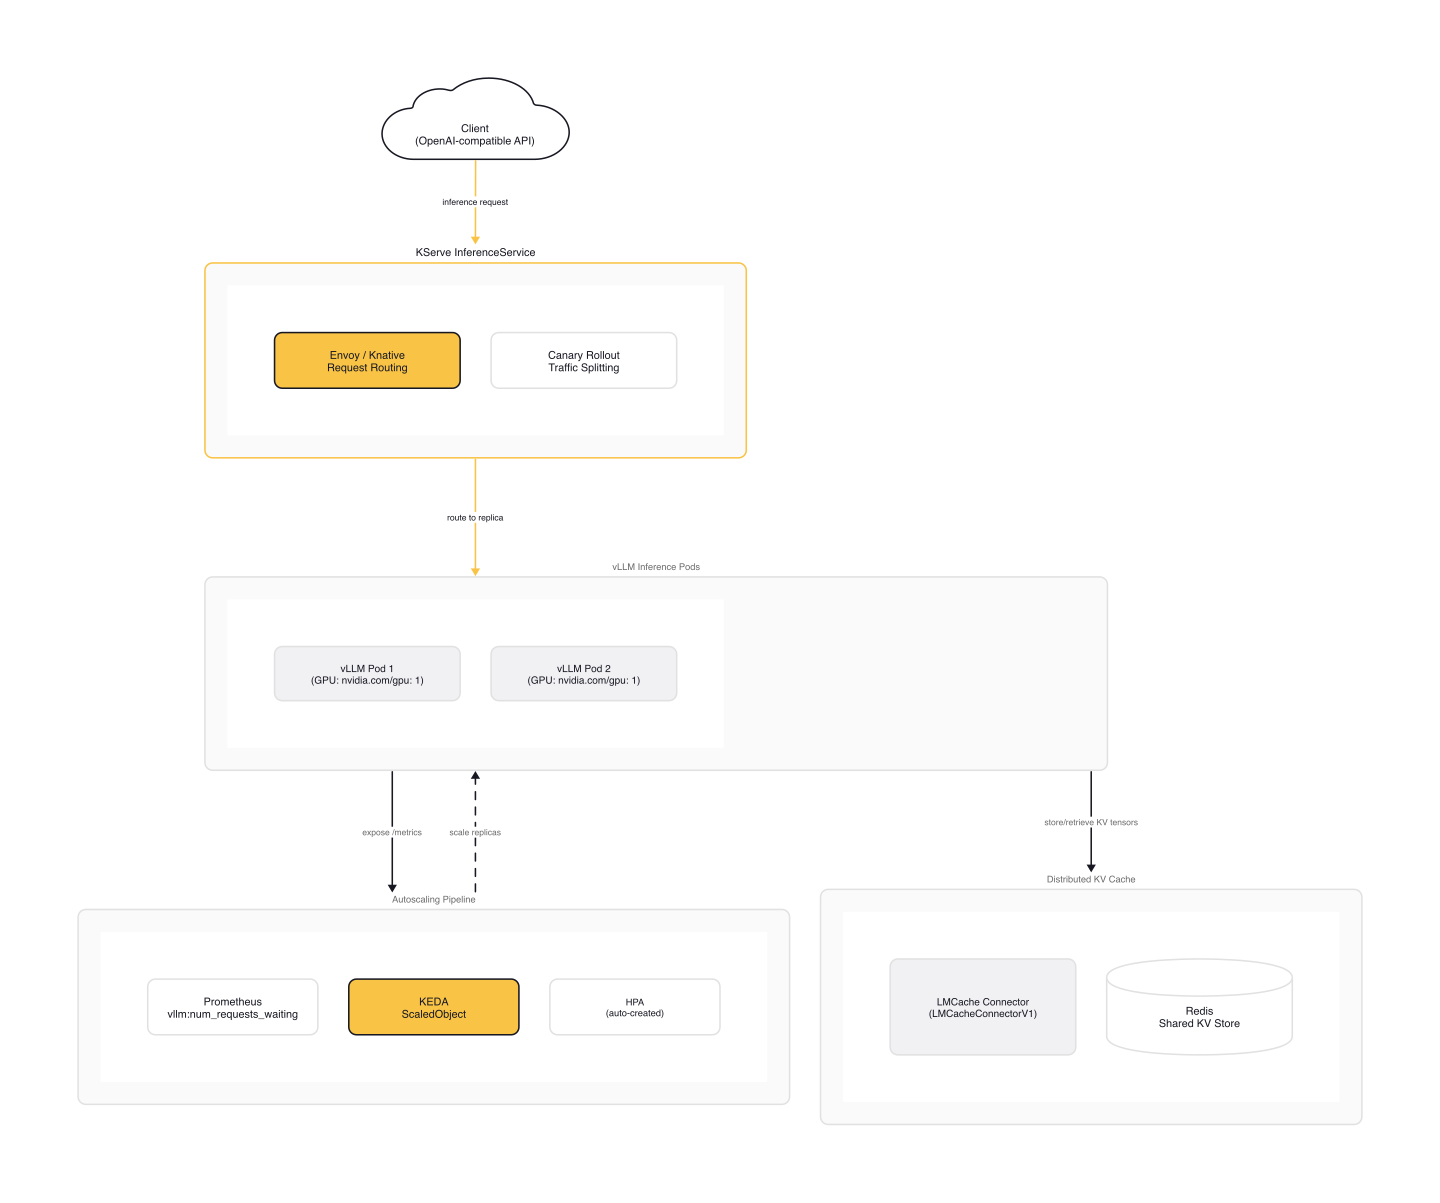
Production LLM Serving on Kubernetes: vLLM + KServe Stack — KubeDojo

Free Video: Fast LLM Serving with vLLM and PagedAttention from Anyscale ...
vLLM Tutorial: Fast, OpenAI‑Compatible LLM Serving Guide
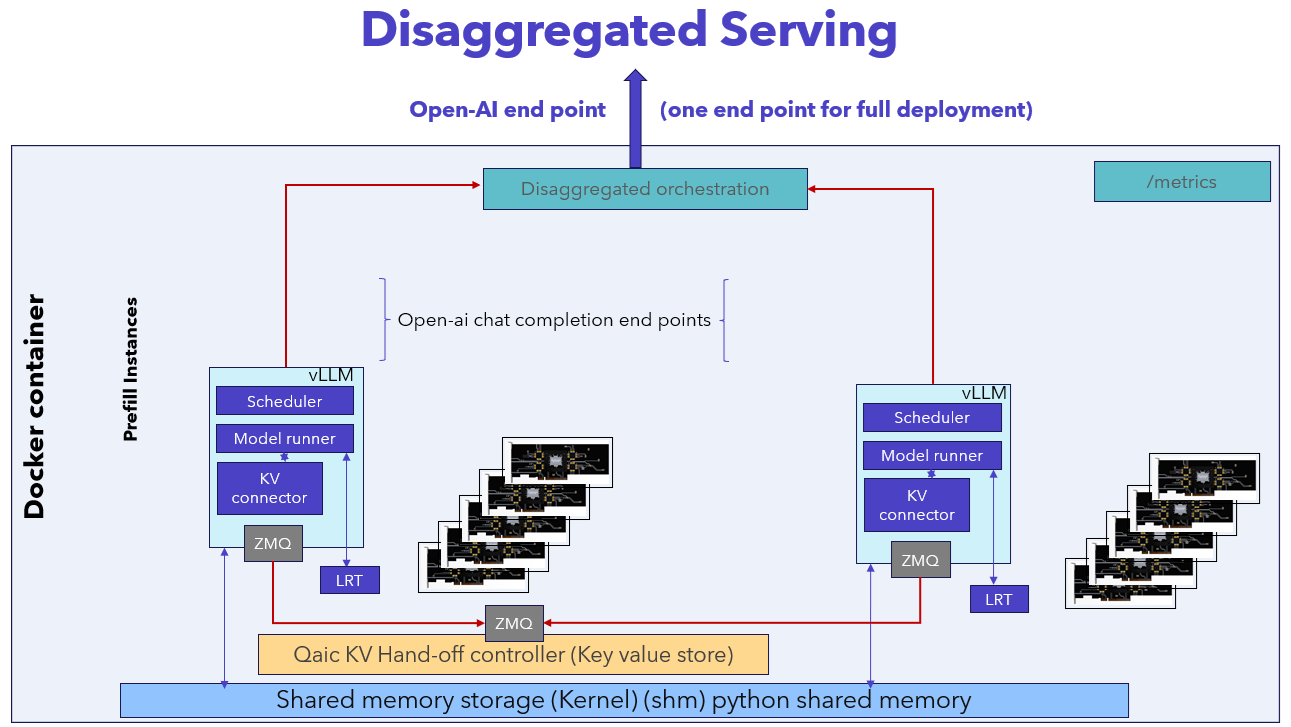
Disaggregated Serving Support with vLLM - Qualcomm Cloud AI Documentation
How to Serve LLMs with vLLM — Production Deployment Guide
Advertisement Space (336x280)

Serving vLLM Embeddings on Vast.ai
vLLM Guide 2026 | High-Throughput LLM Serving
Serving Models with vLLM | vllm-project/speculators | DeepWiki
vLLM Tutorial: Fast, OpenAI‑Compatible LLM Serving Guide
Optimize Edge LLM Serving with vLLM and NVIDIA Model-Optimizer | Atomic ...