
How To Implement Attention Distillation For Transformer Models
How to Implement Attention Distillation for Transformer Models ...
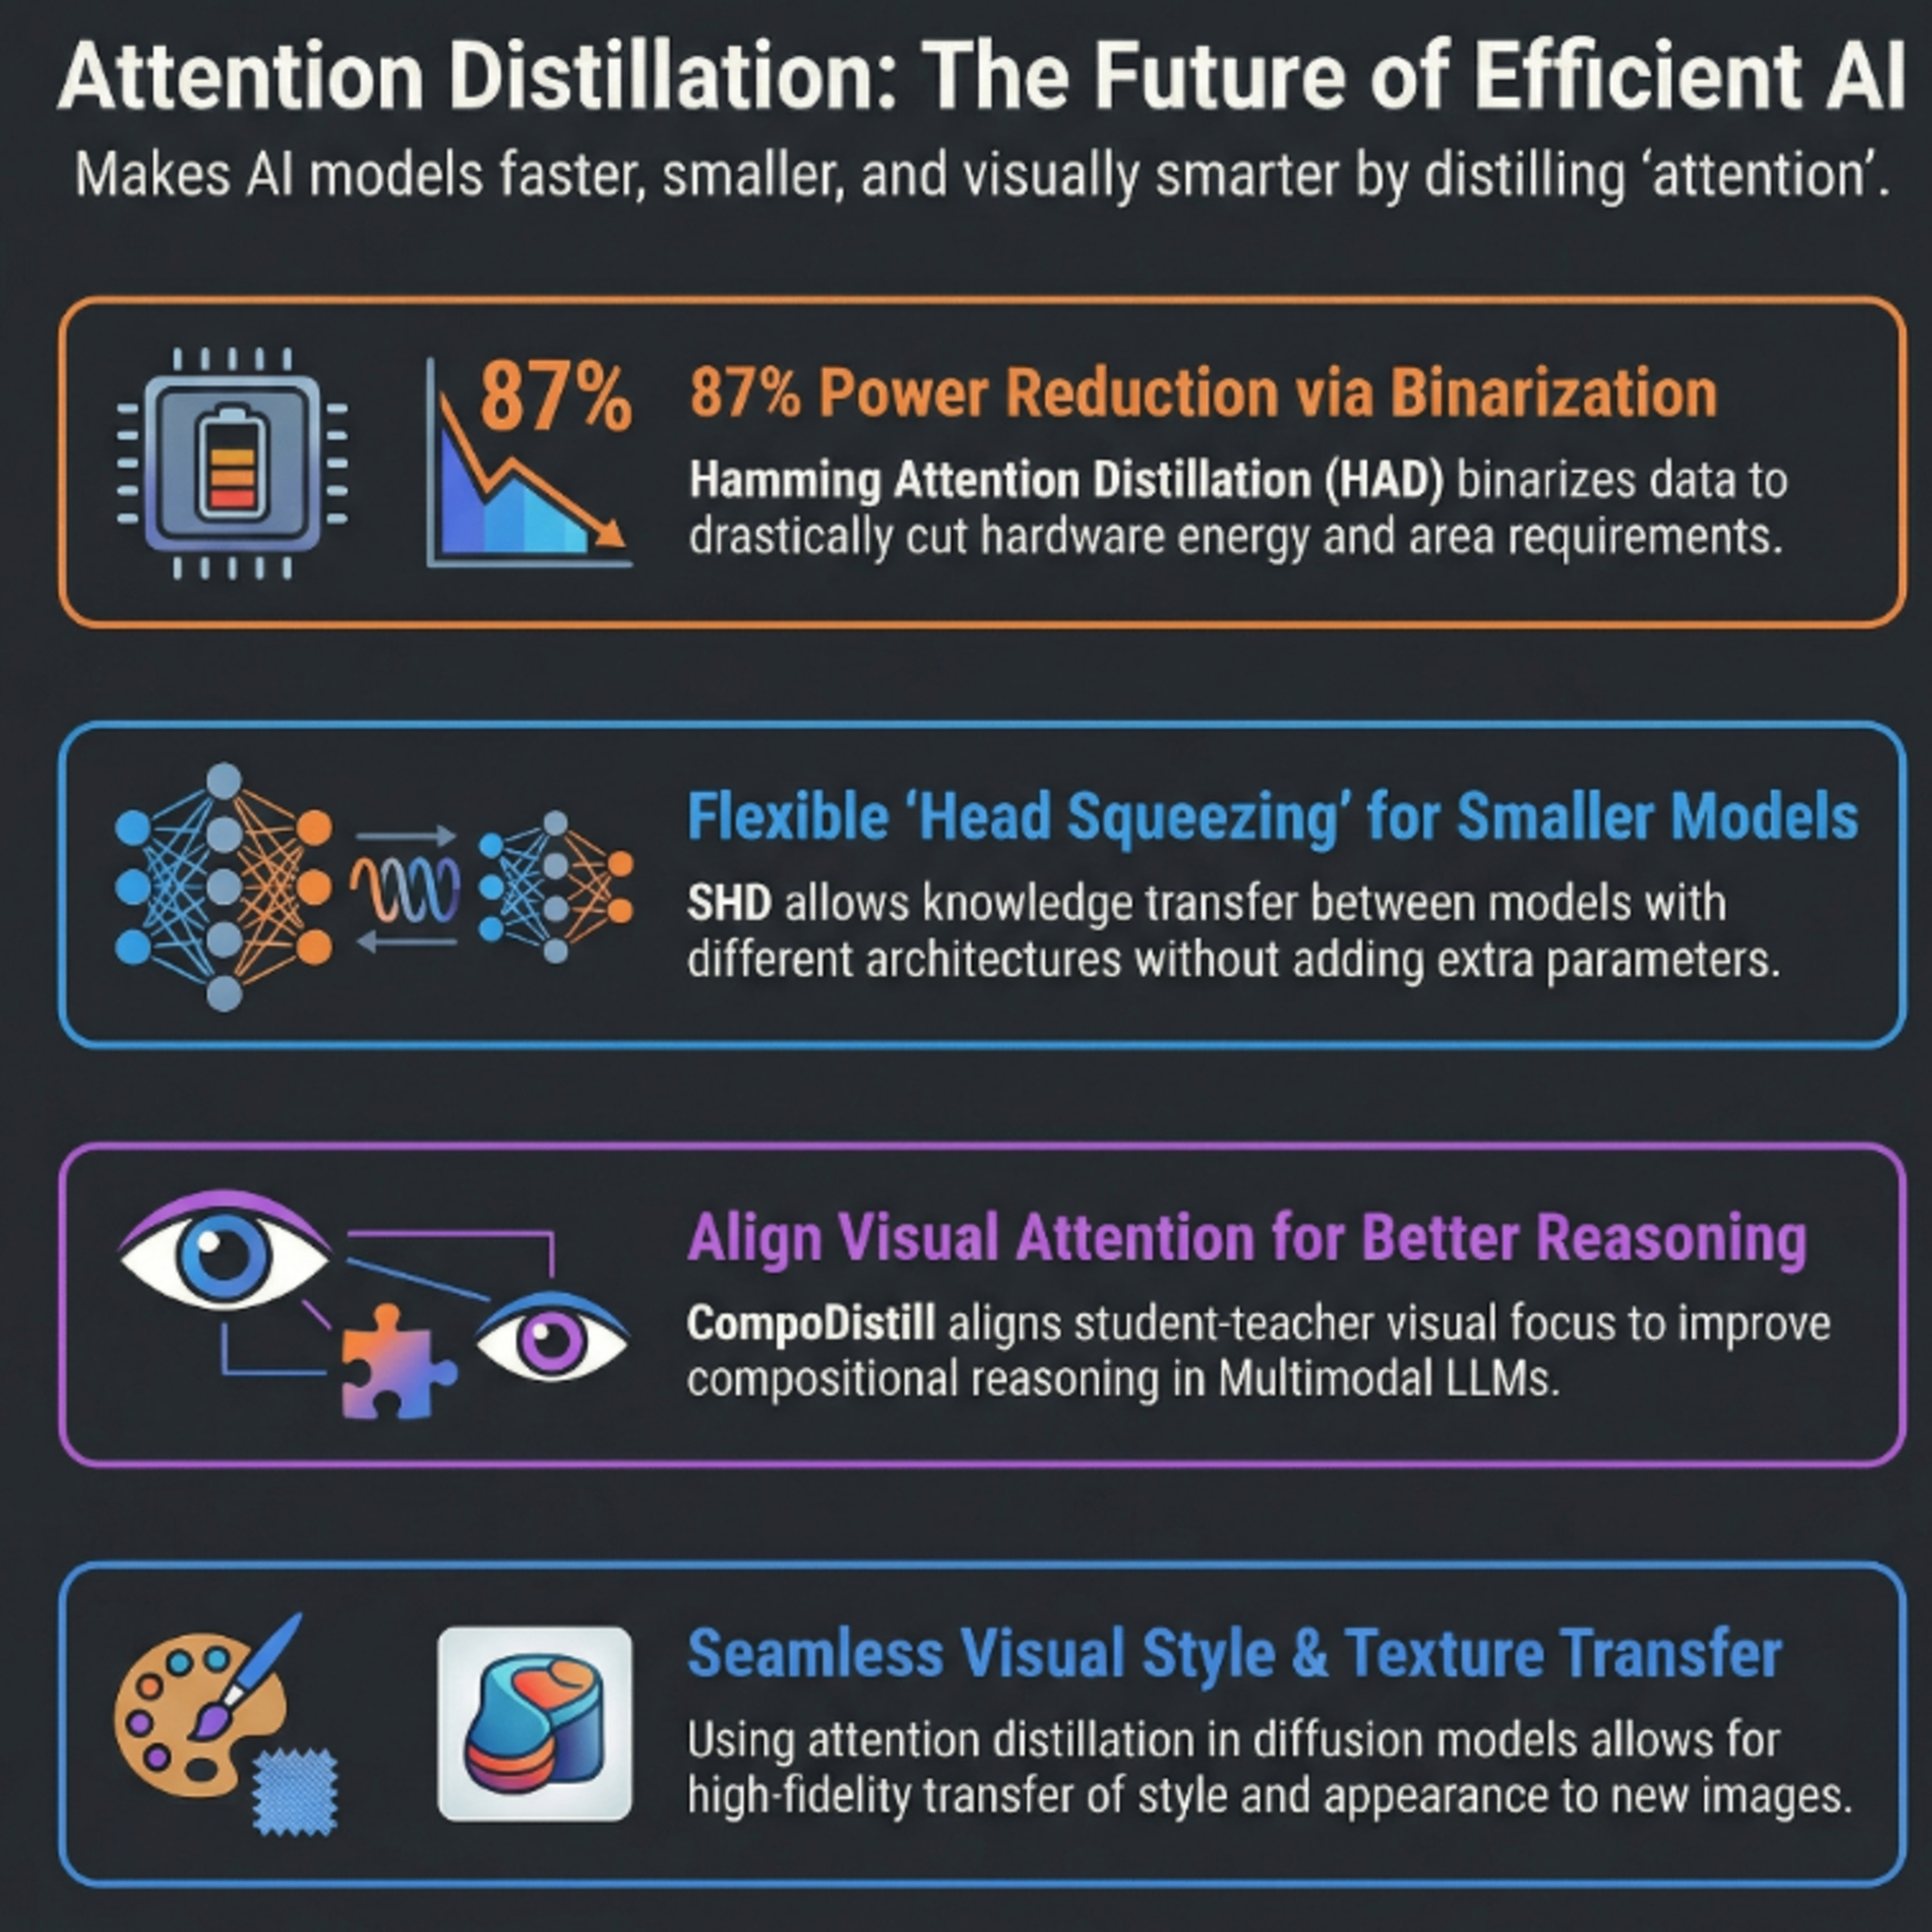
Advances in Attention Distillation for Efficient Transformer Models ...
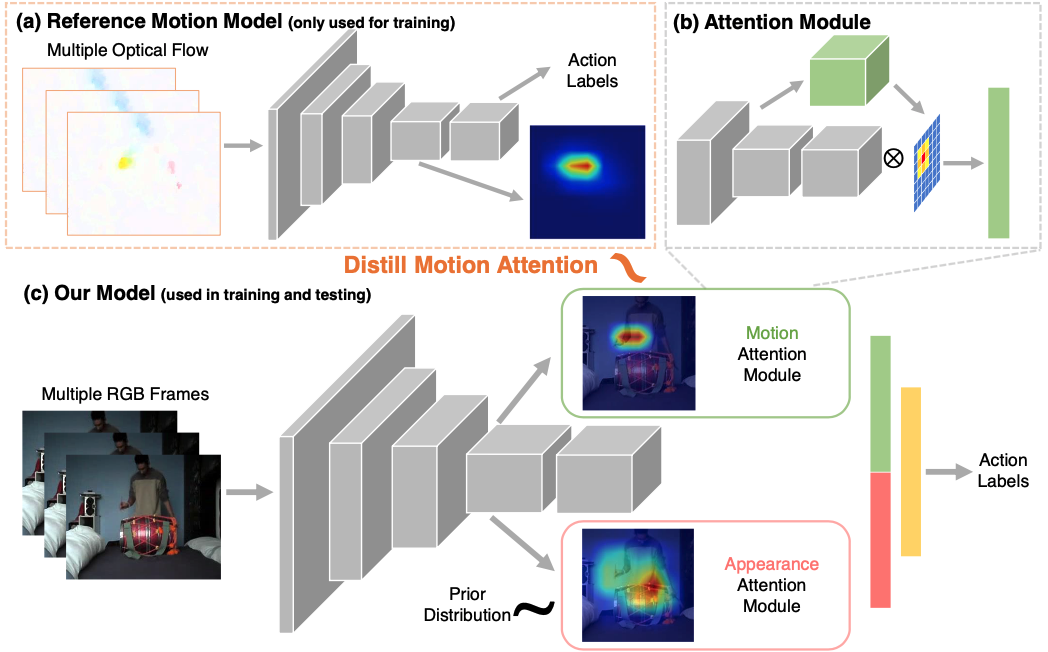
Attention Distillation for Learning Video Representations
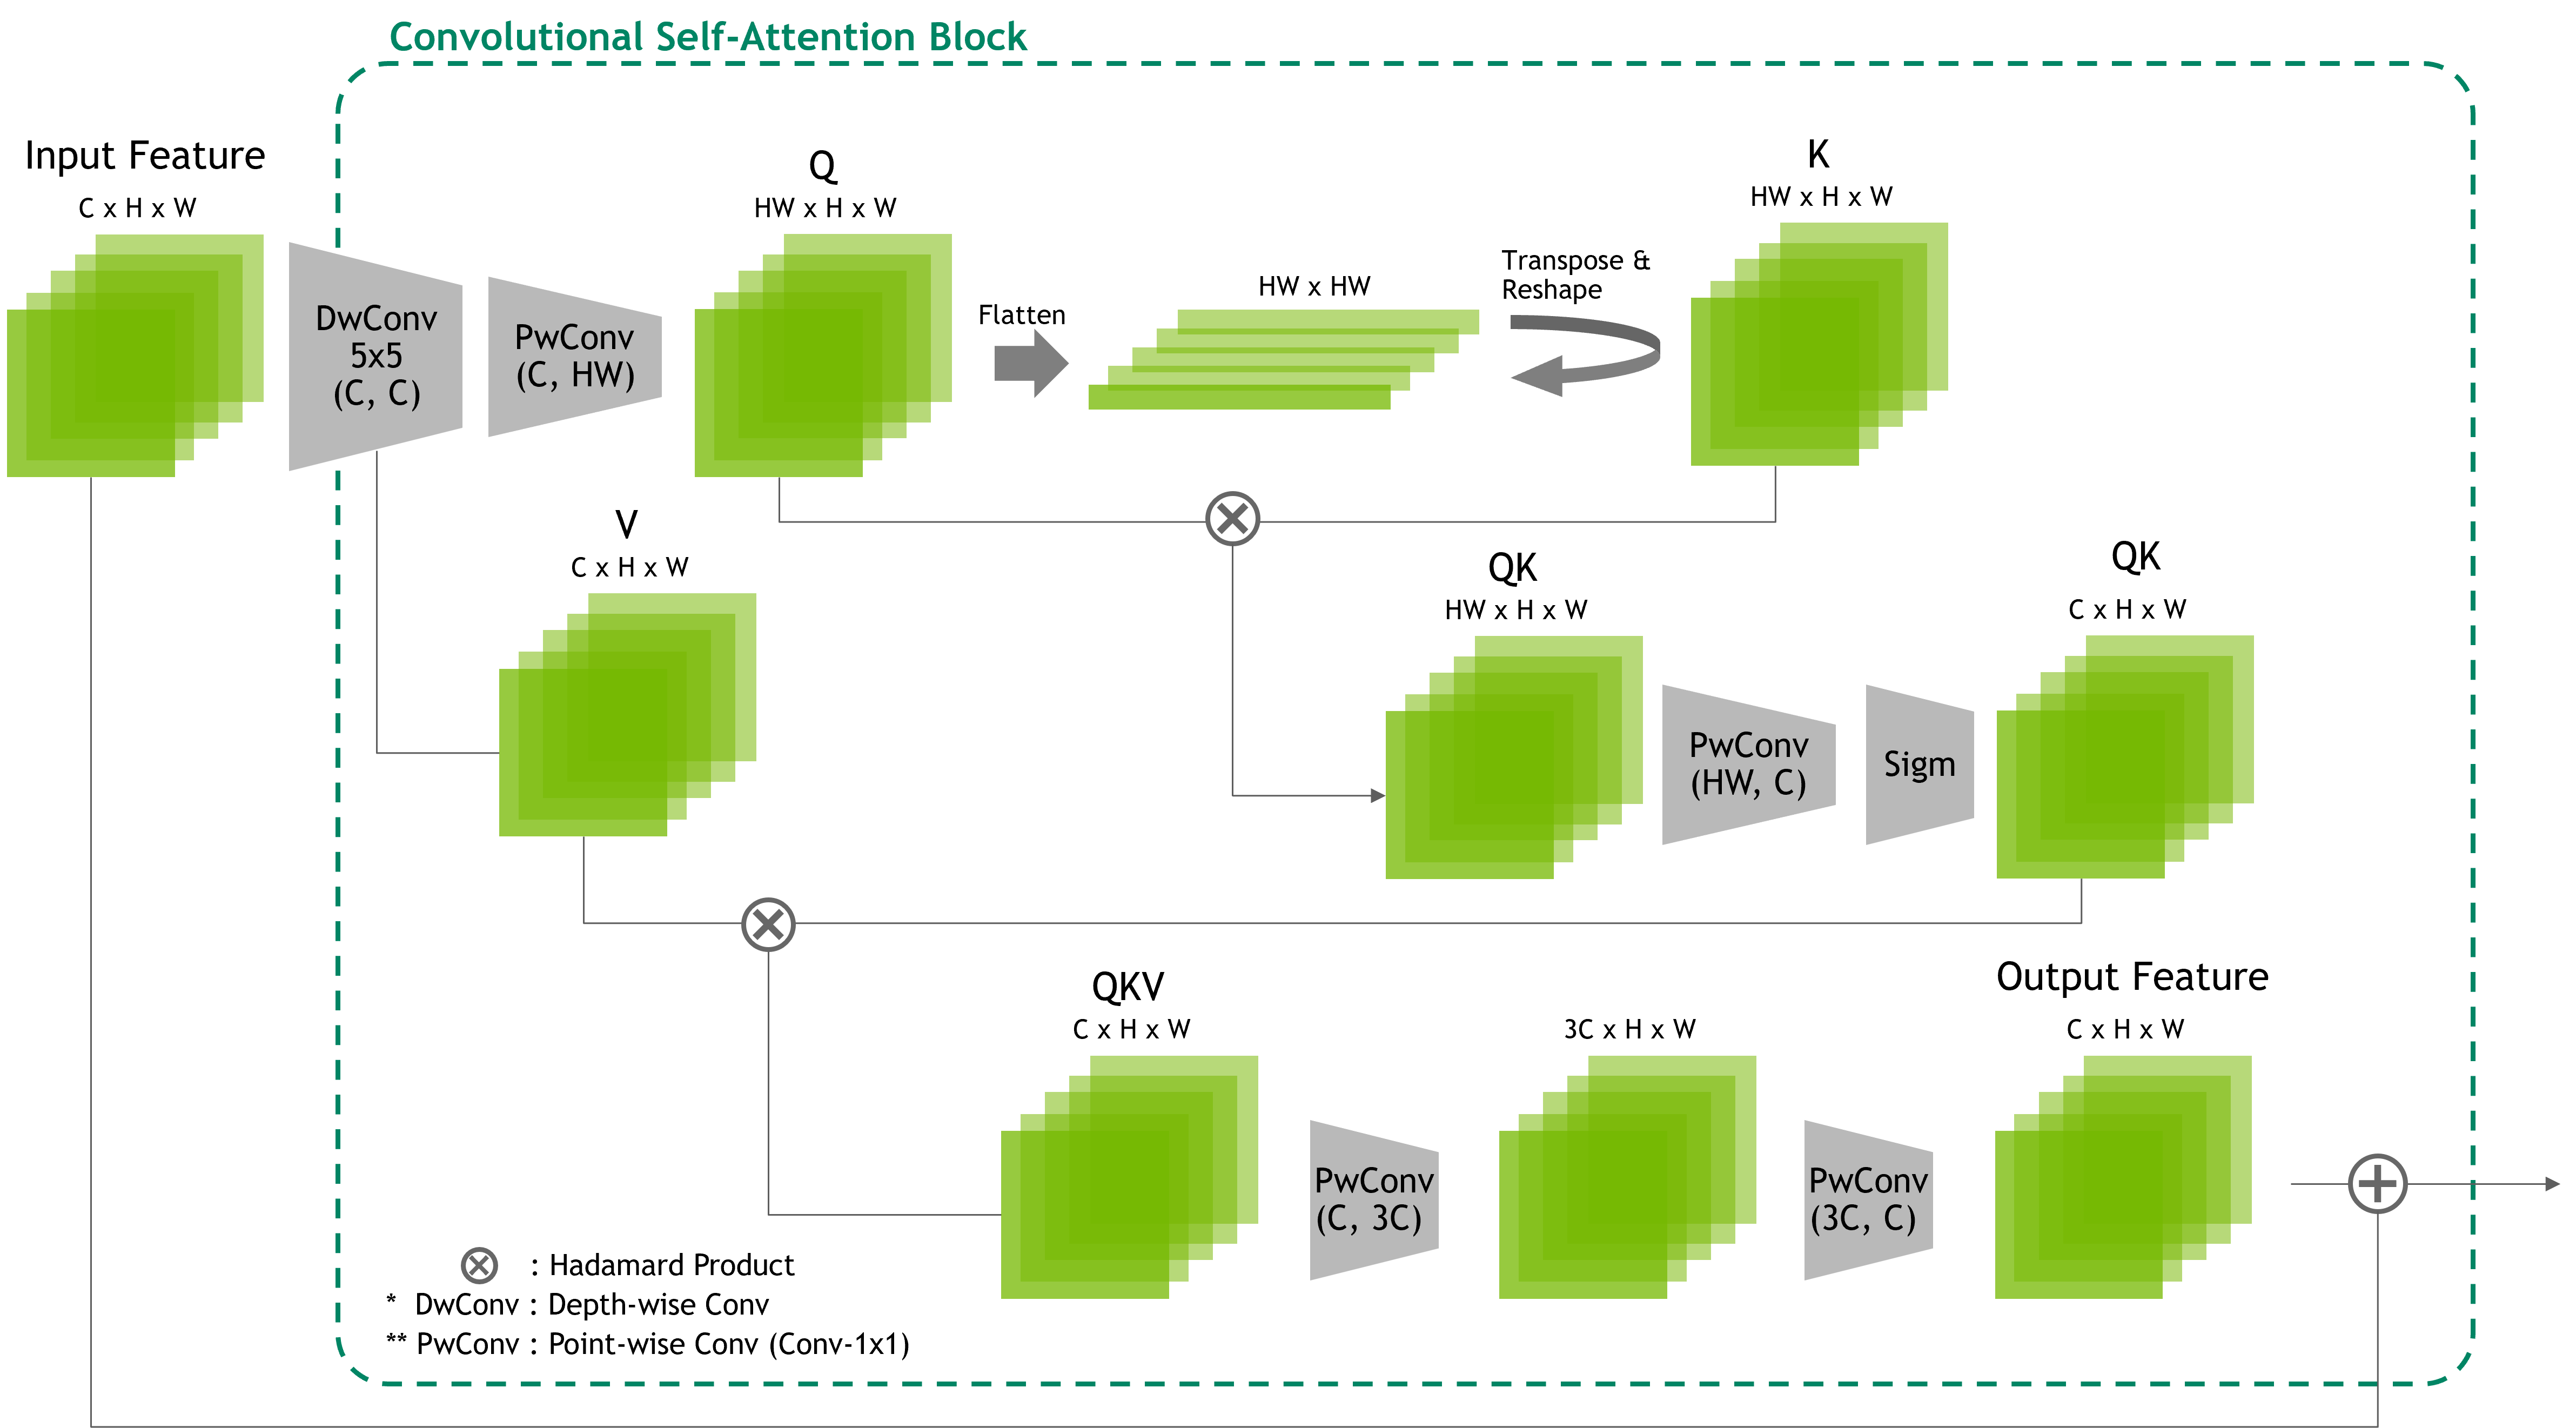
Emulating the Attention Mechanism in Transformer Models with a Fully ...

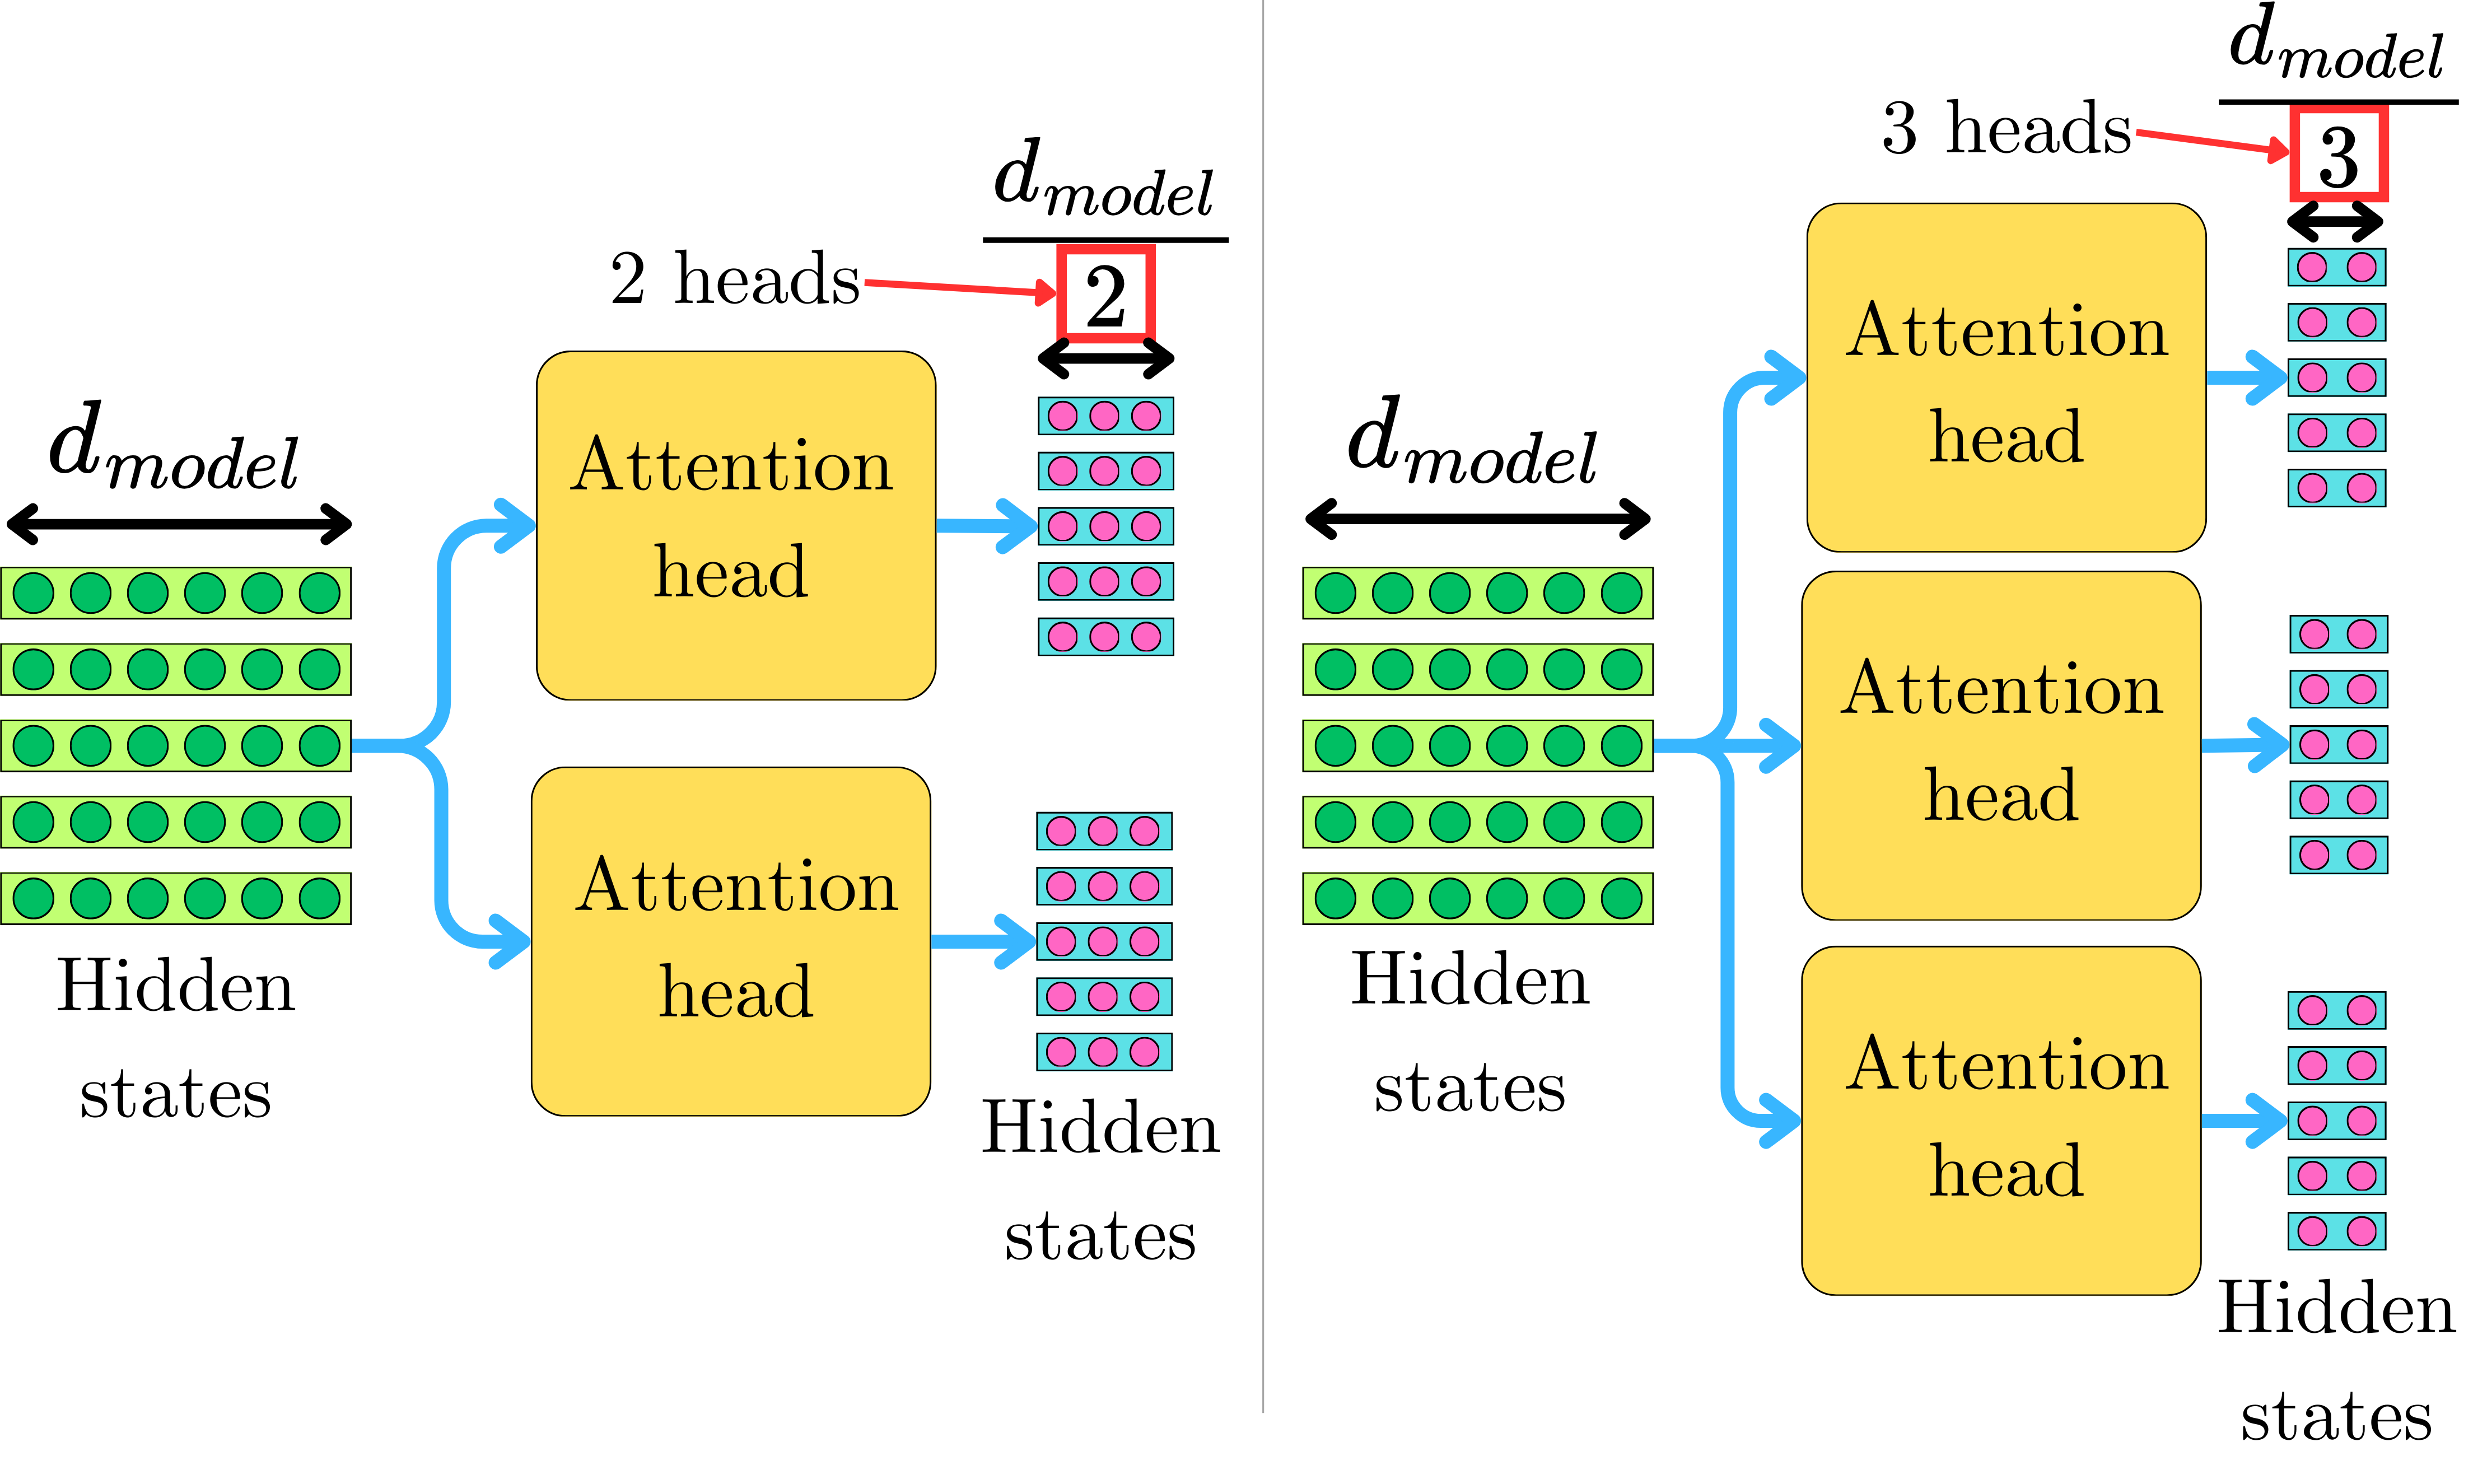
Matters of Attention: What is Attention and How to Compute Attention in ...

Attention → Mamba cross-architecture distillation is real Transformer ...
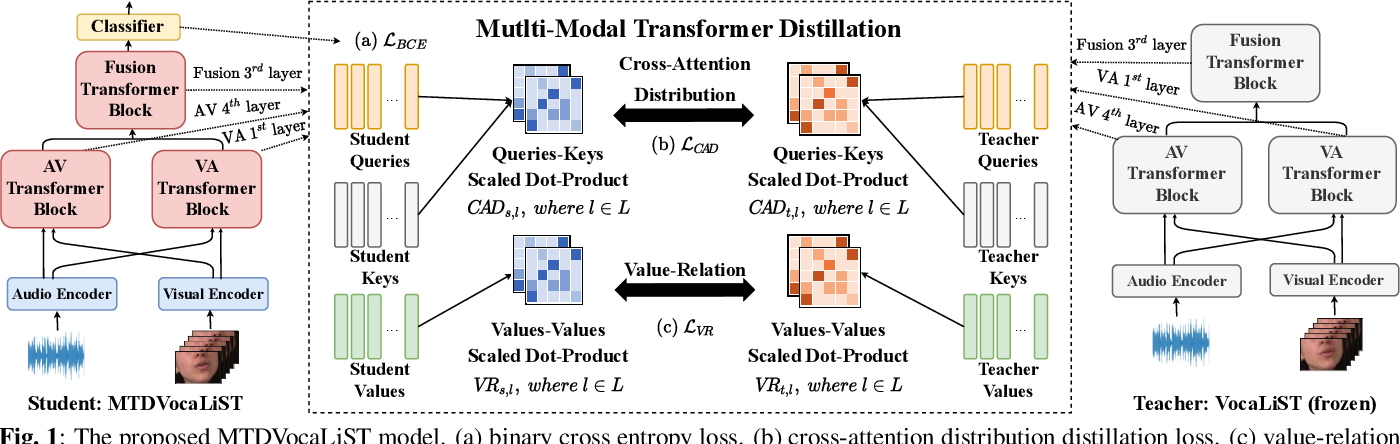
Figure 1 from Multimodal Transformer Distillation for Audio-Visual ...

Loop and distillation: Attention weights fusion transformer for fine ...
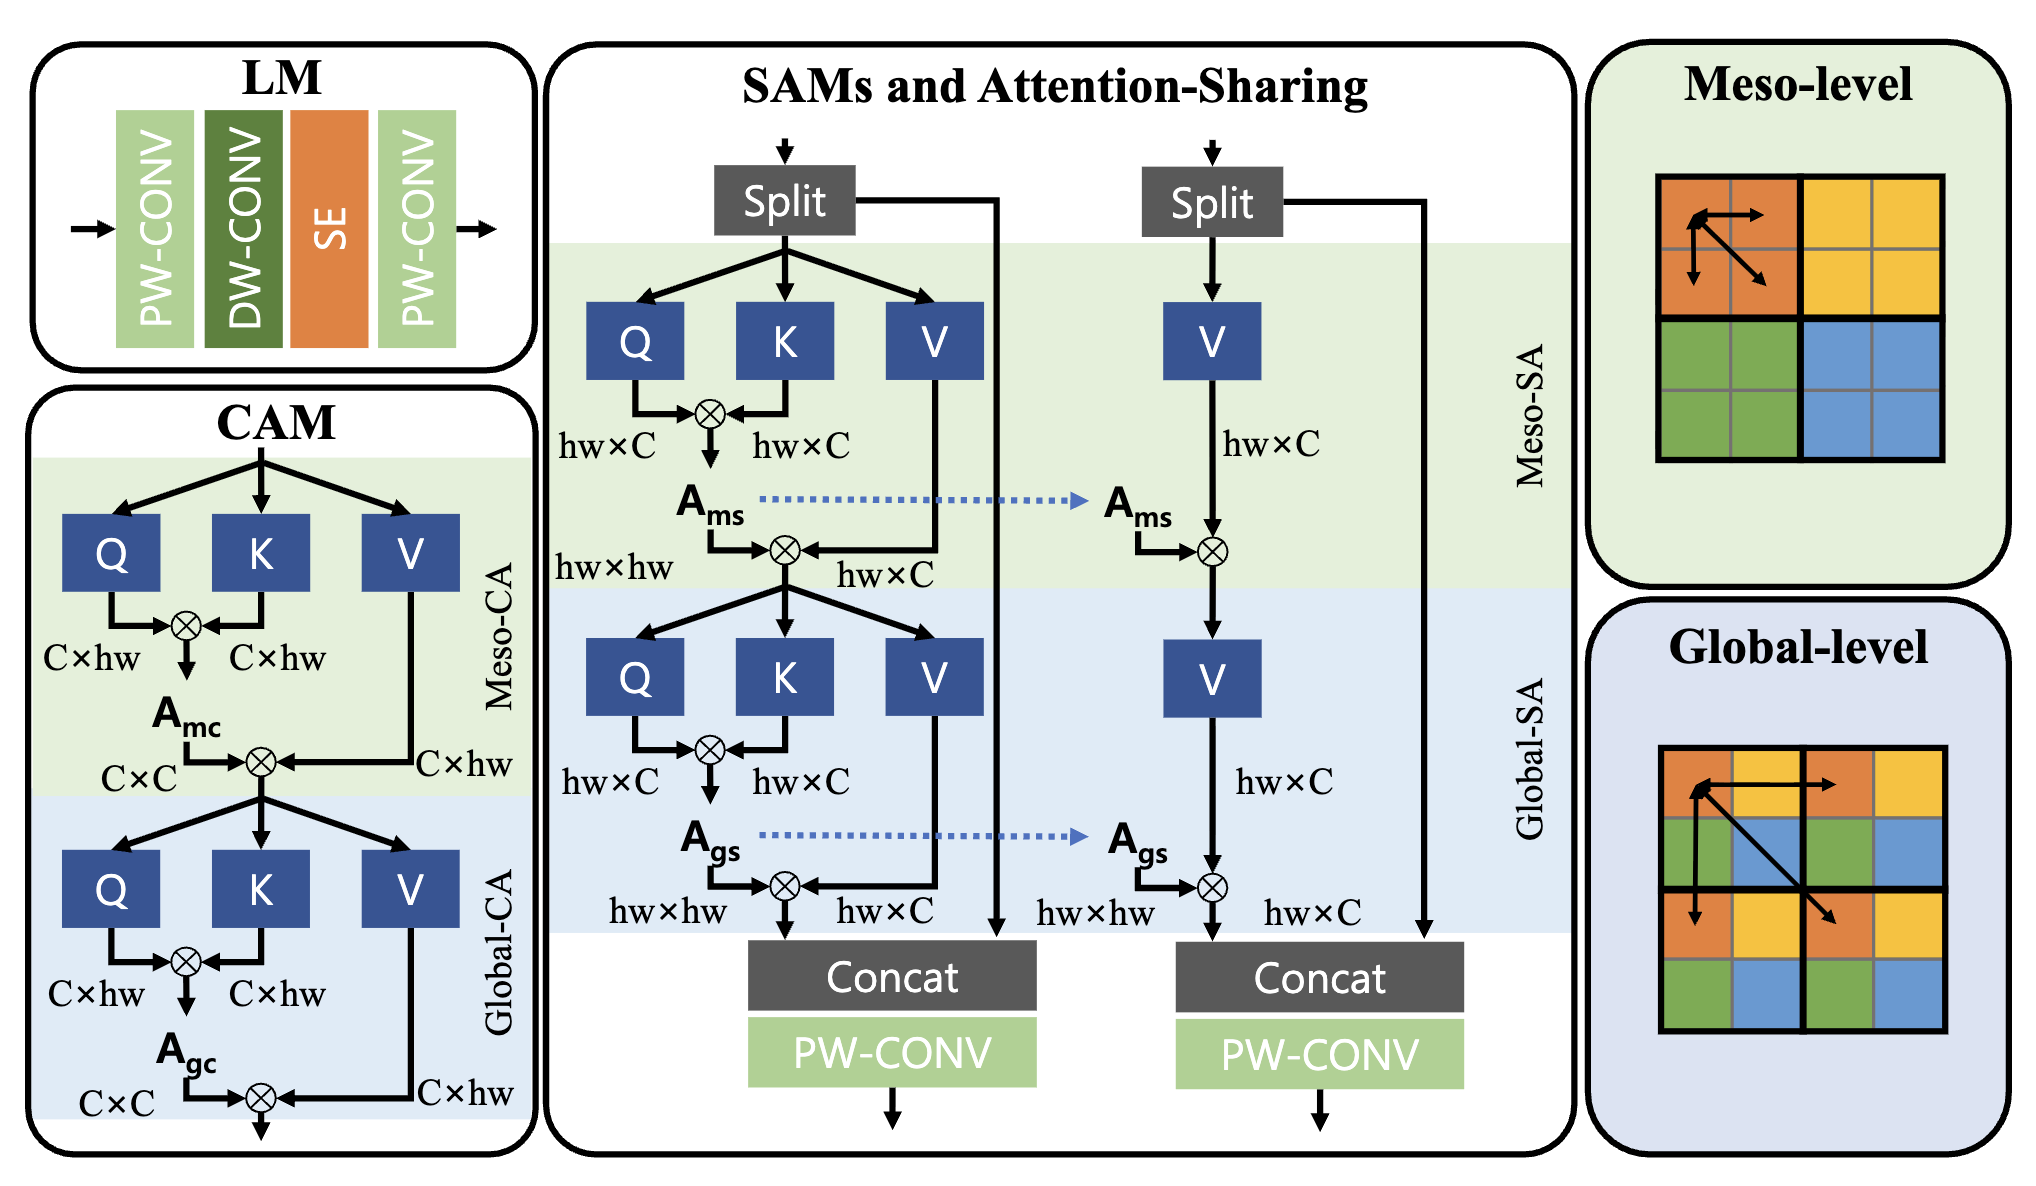
Efficient Attention-Sharing Information Distillation Transformer for ...

[논문 리뷰] RADLADS: Rapid Attention Distillation to Linear Attention ...
Advertisement Space (300x250)

Emulating the Attention Mechanism in Transformer Models with a Fully ...

Distillation of Transformer Models - YouTube
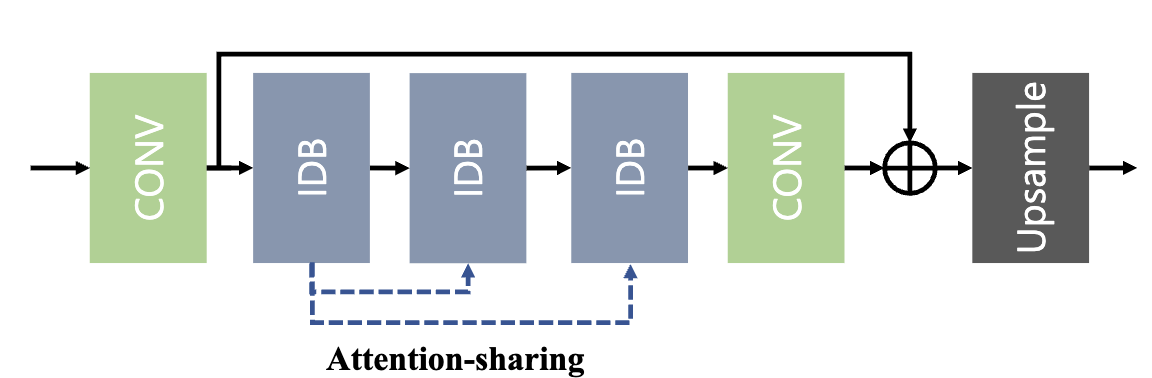
Efficient Attention-Sharing Information Distillation Transformer for ...
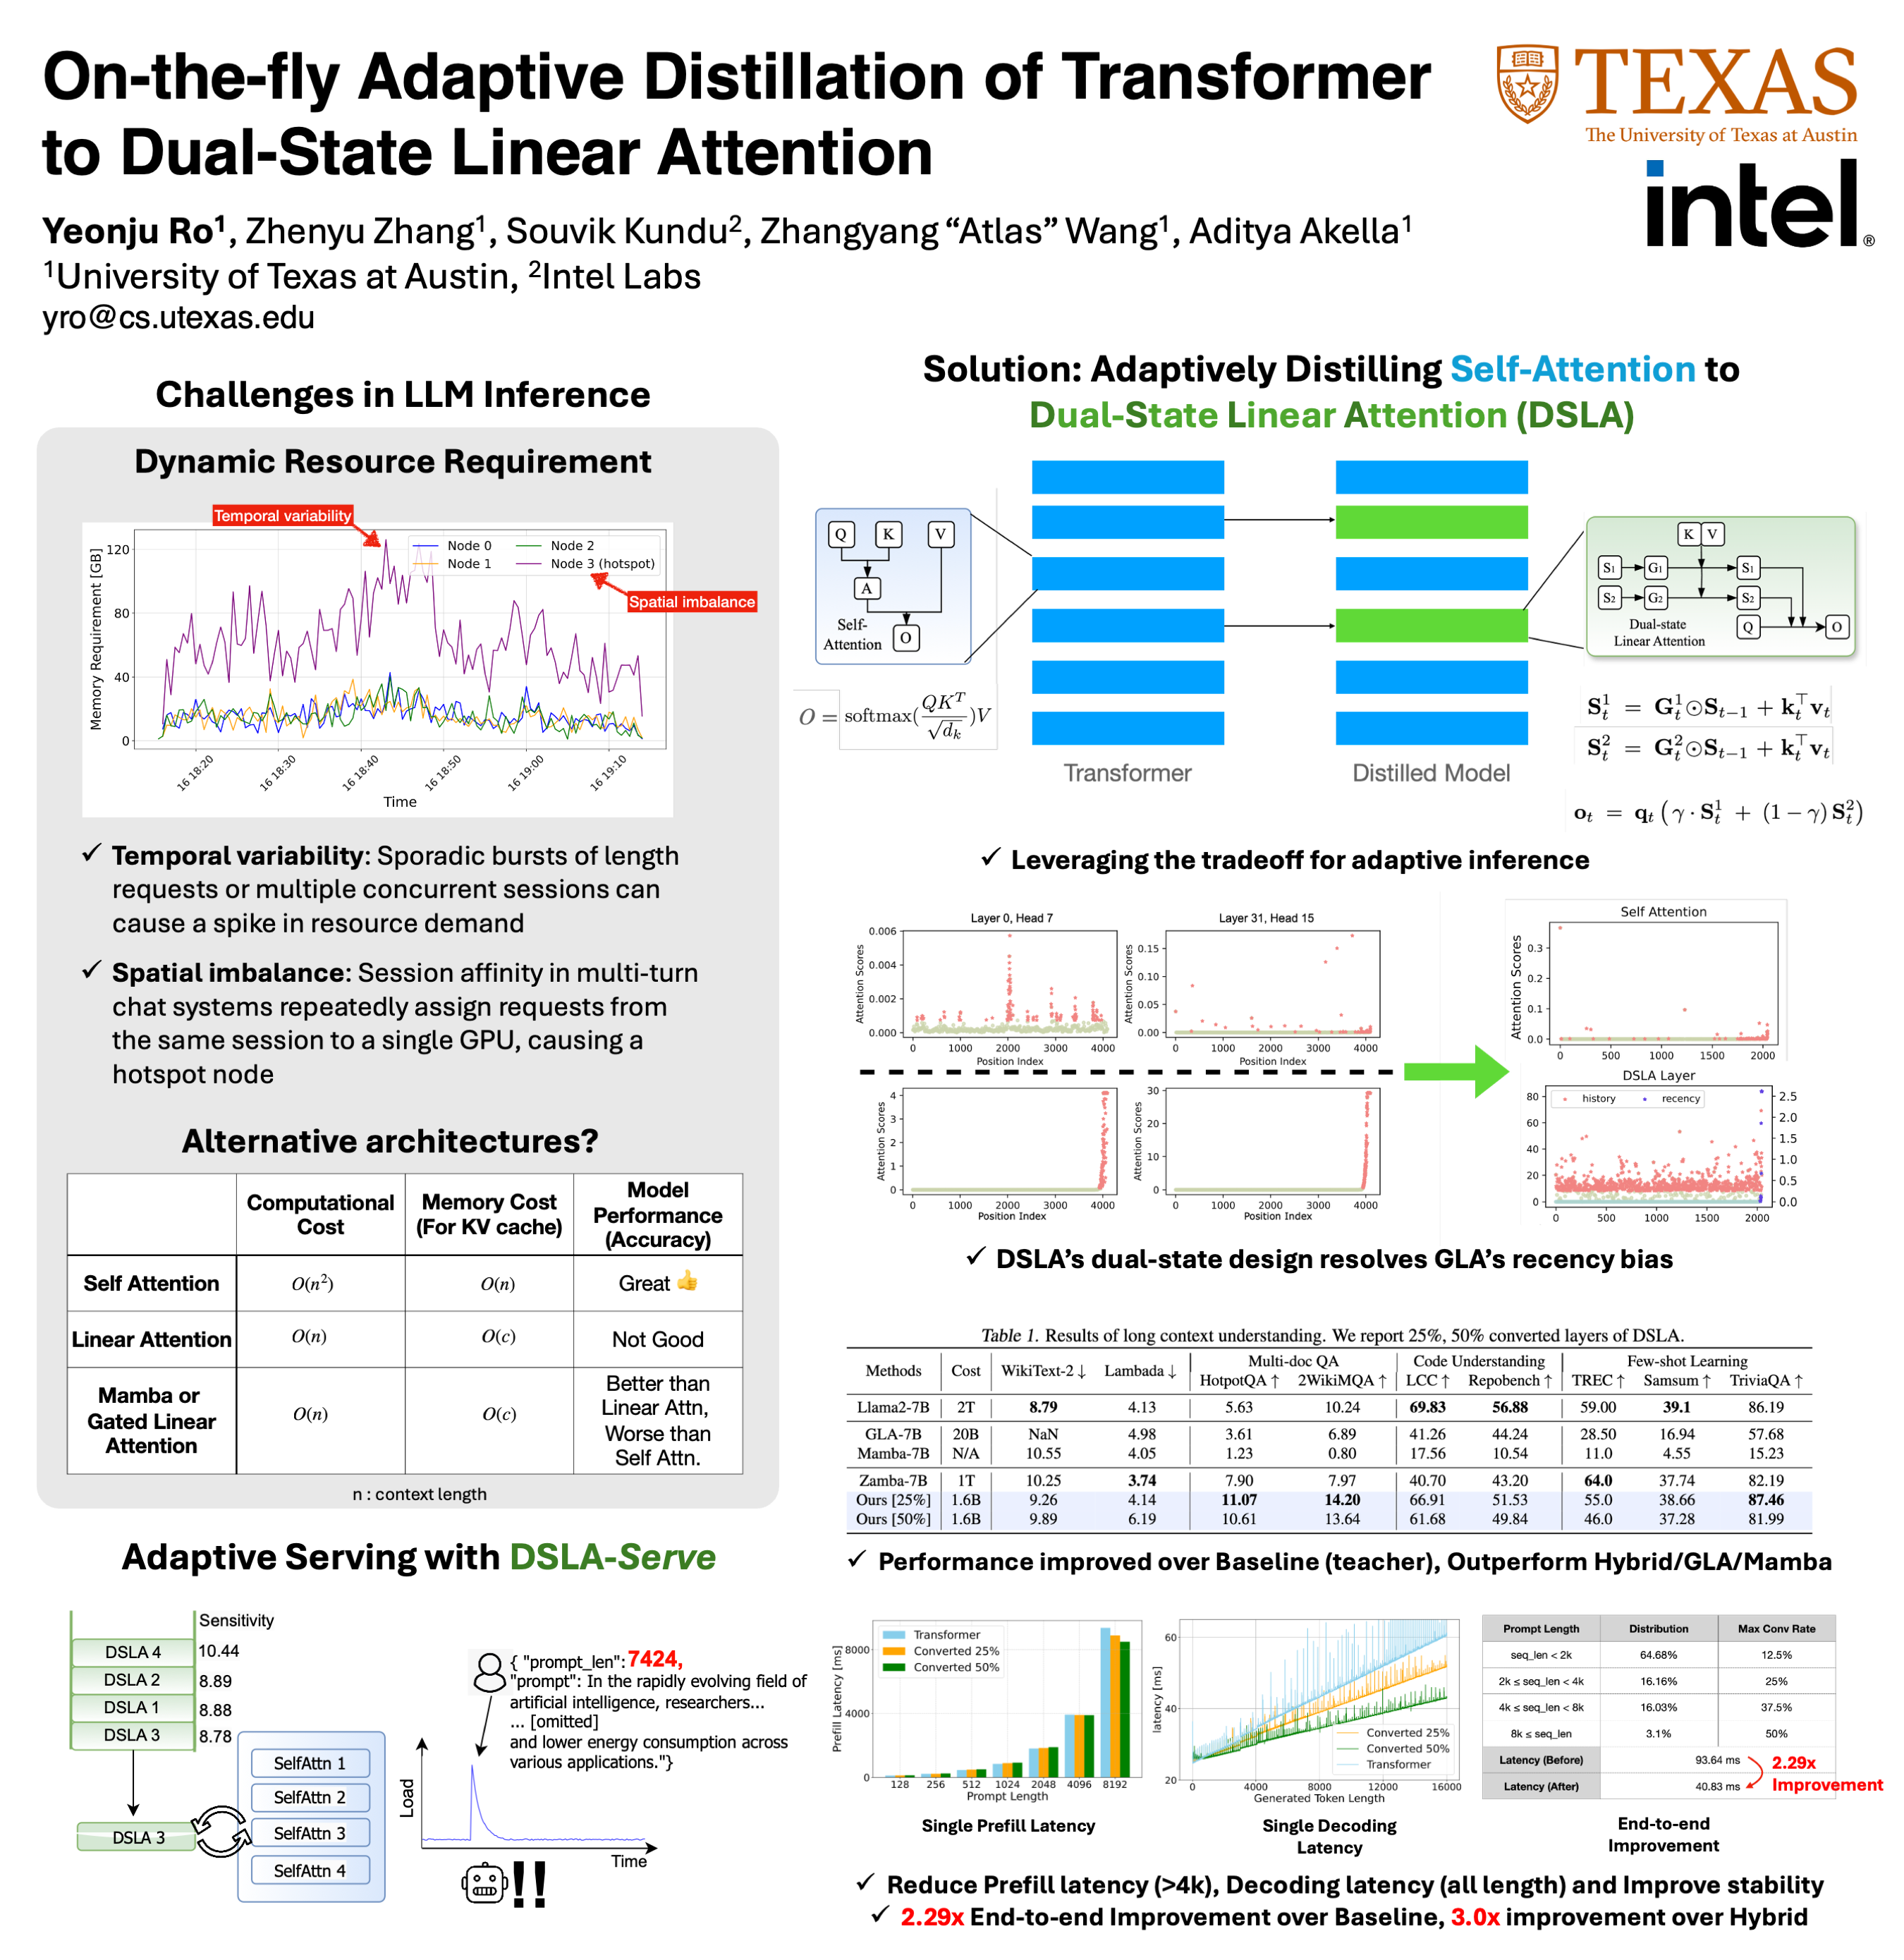
ICML Poster On-the-Fly Adaptive Distillation of Transformer to Dual ...

Loop and distillation: Attention weights fusion transformer for fine ...

Understanding Attention Mechanisms: The Key to Transformer Model ...
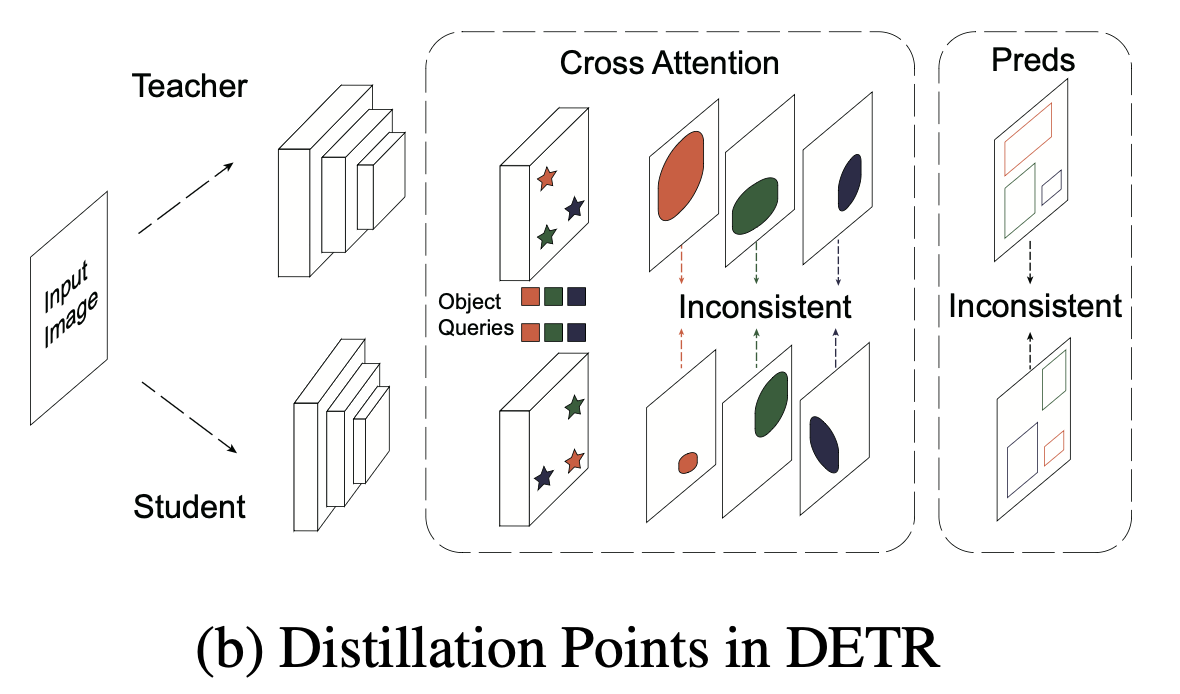
KD-DETR: Knowledge Distillation for Detection Transformer with ...

Figure 1 from Knowledge Distillation in RNN-Attention Models for Early ...
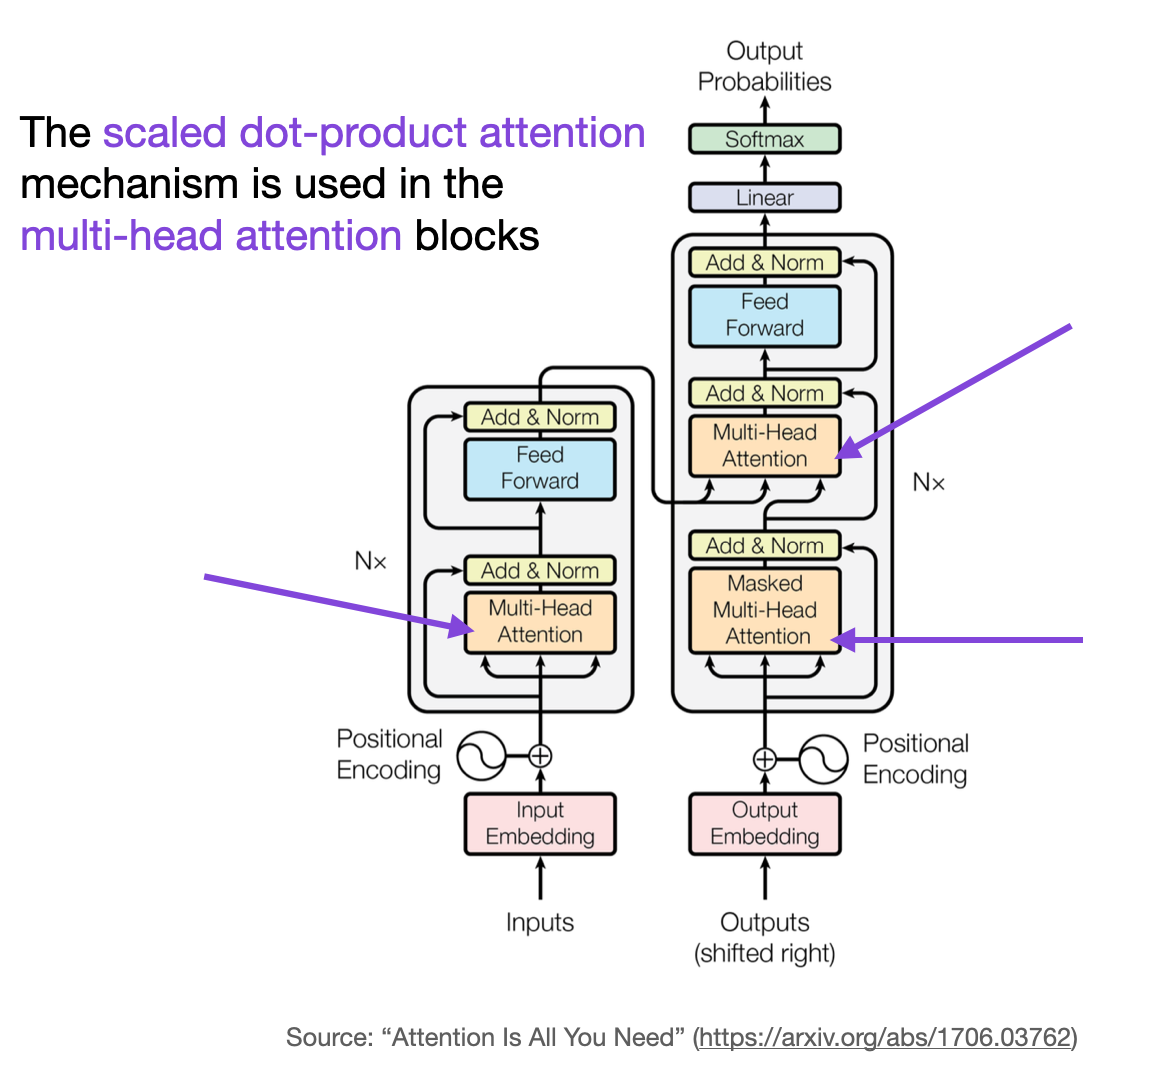
Attention Is All You Need: The Original Transformer Architecture
Attention Block Vs Transformer _ Transformer Architecture – SRYSF
Advertisement Space (336x280)
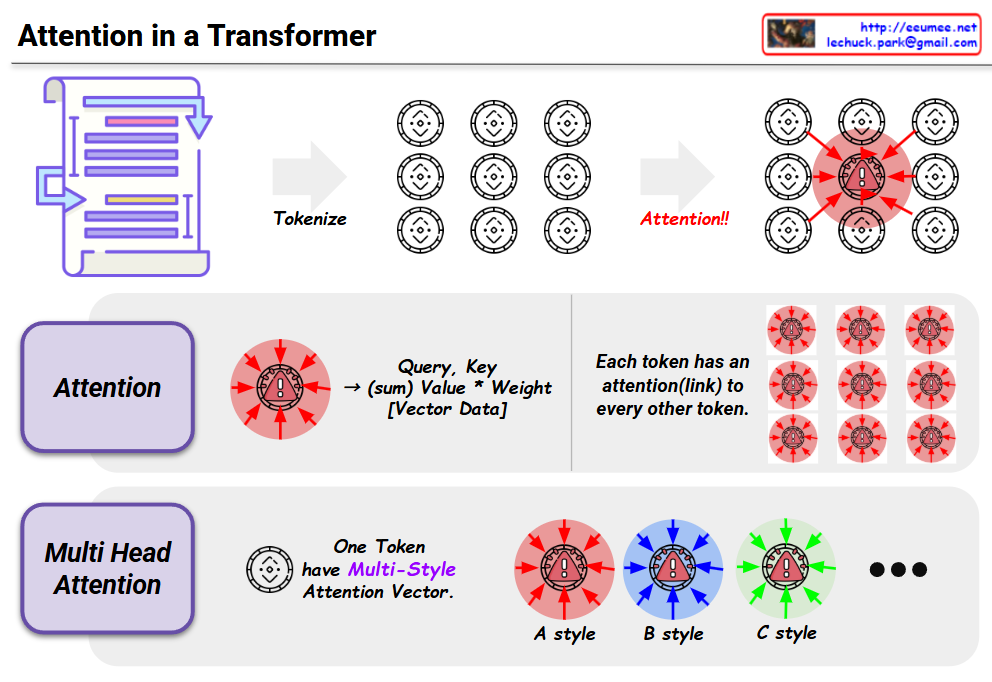
Attention in a Transformer – Lechuck Park

Hierarchical and Step-Layer-Wise Tuning of Attention Specialty for ...
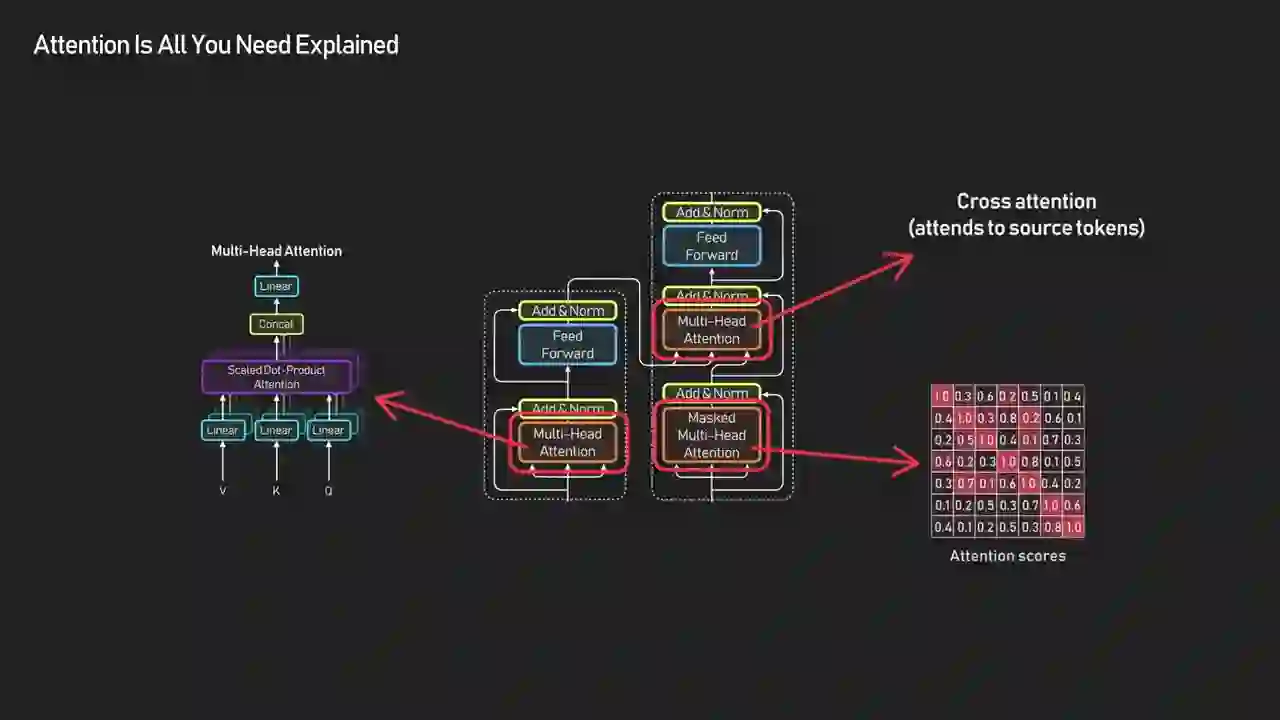
How Transformers Work: Attention Is All You Need, Explained Step by Step

Teacher student learning with hidden state and attention distillation ...
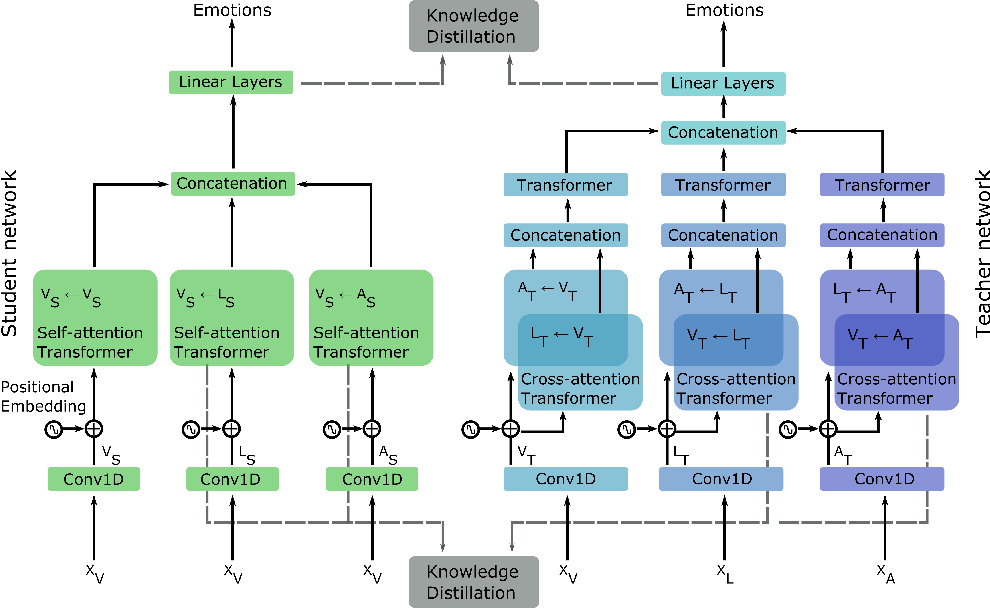
Figure 1 from From Multimodal to Unimodal Attention in Transformers ...
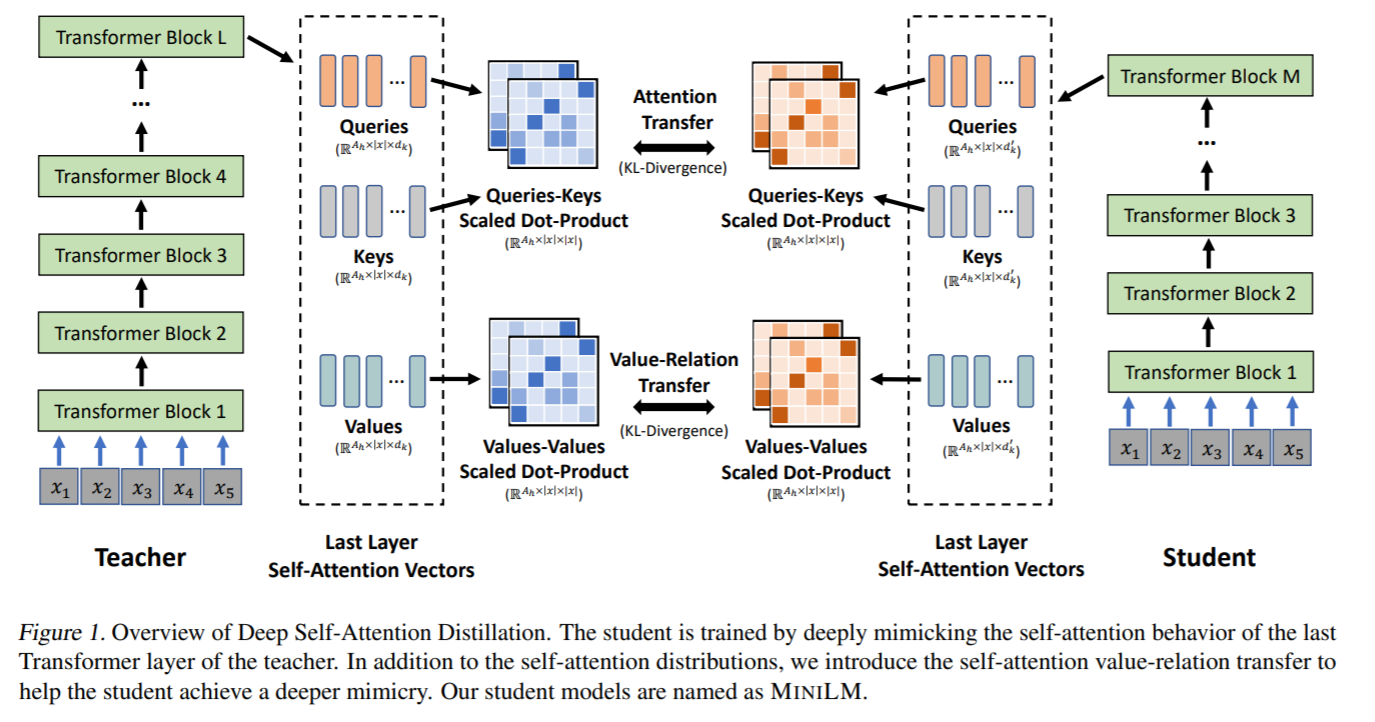
MiniLM - Deep Self-Attention Distillation for Task-Agnostic Compression ...
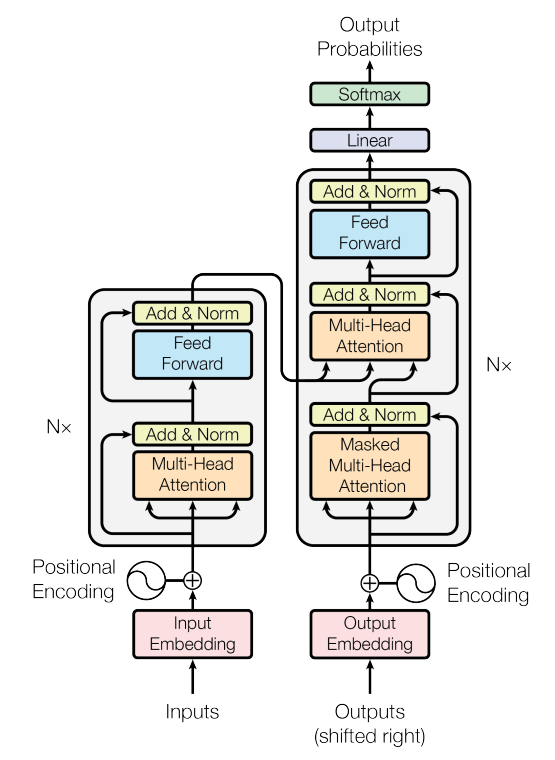
"Attention, Please!": A Visual Guide To The Attention Mechanism ...

Teacher student learning with hidden state and attention distillation ...
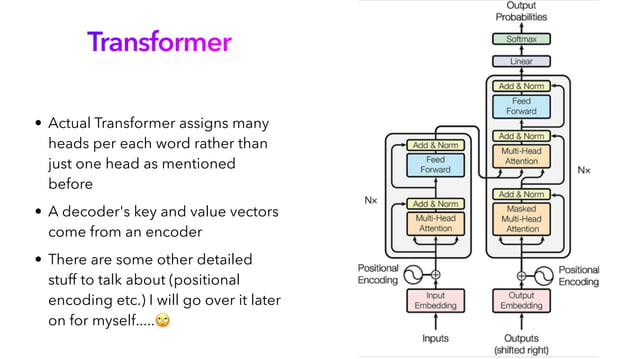
Transformer Attention Visualization – KFAI
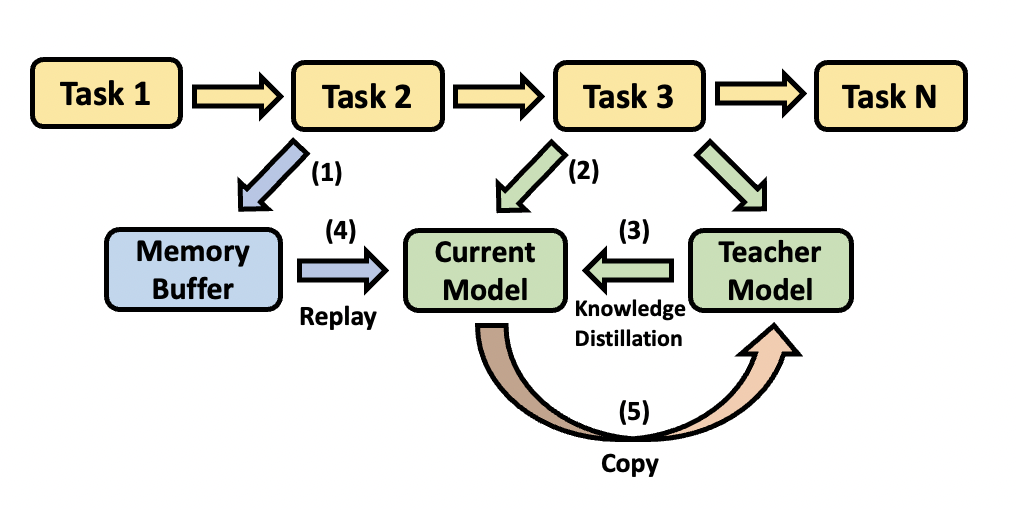
[2303.14423] Task-Attentive Transformer Architecture for Continual ...
Advertisement Space (336x280)

(PDF) A Transformer-based Knowledge Distillation Network for Cortical ...

Transformer Model Fig. 2: Attention mechanism (a) shows complete ...

[2210.00944] Attention Distillation: self-supervised vision transformer ...
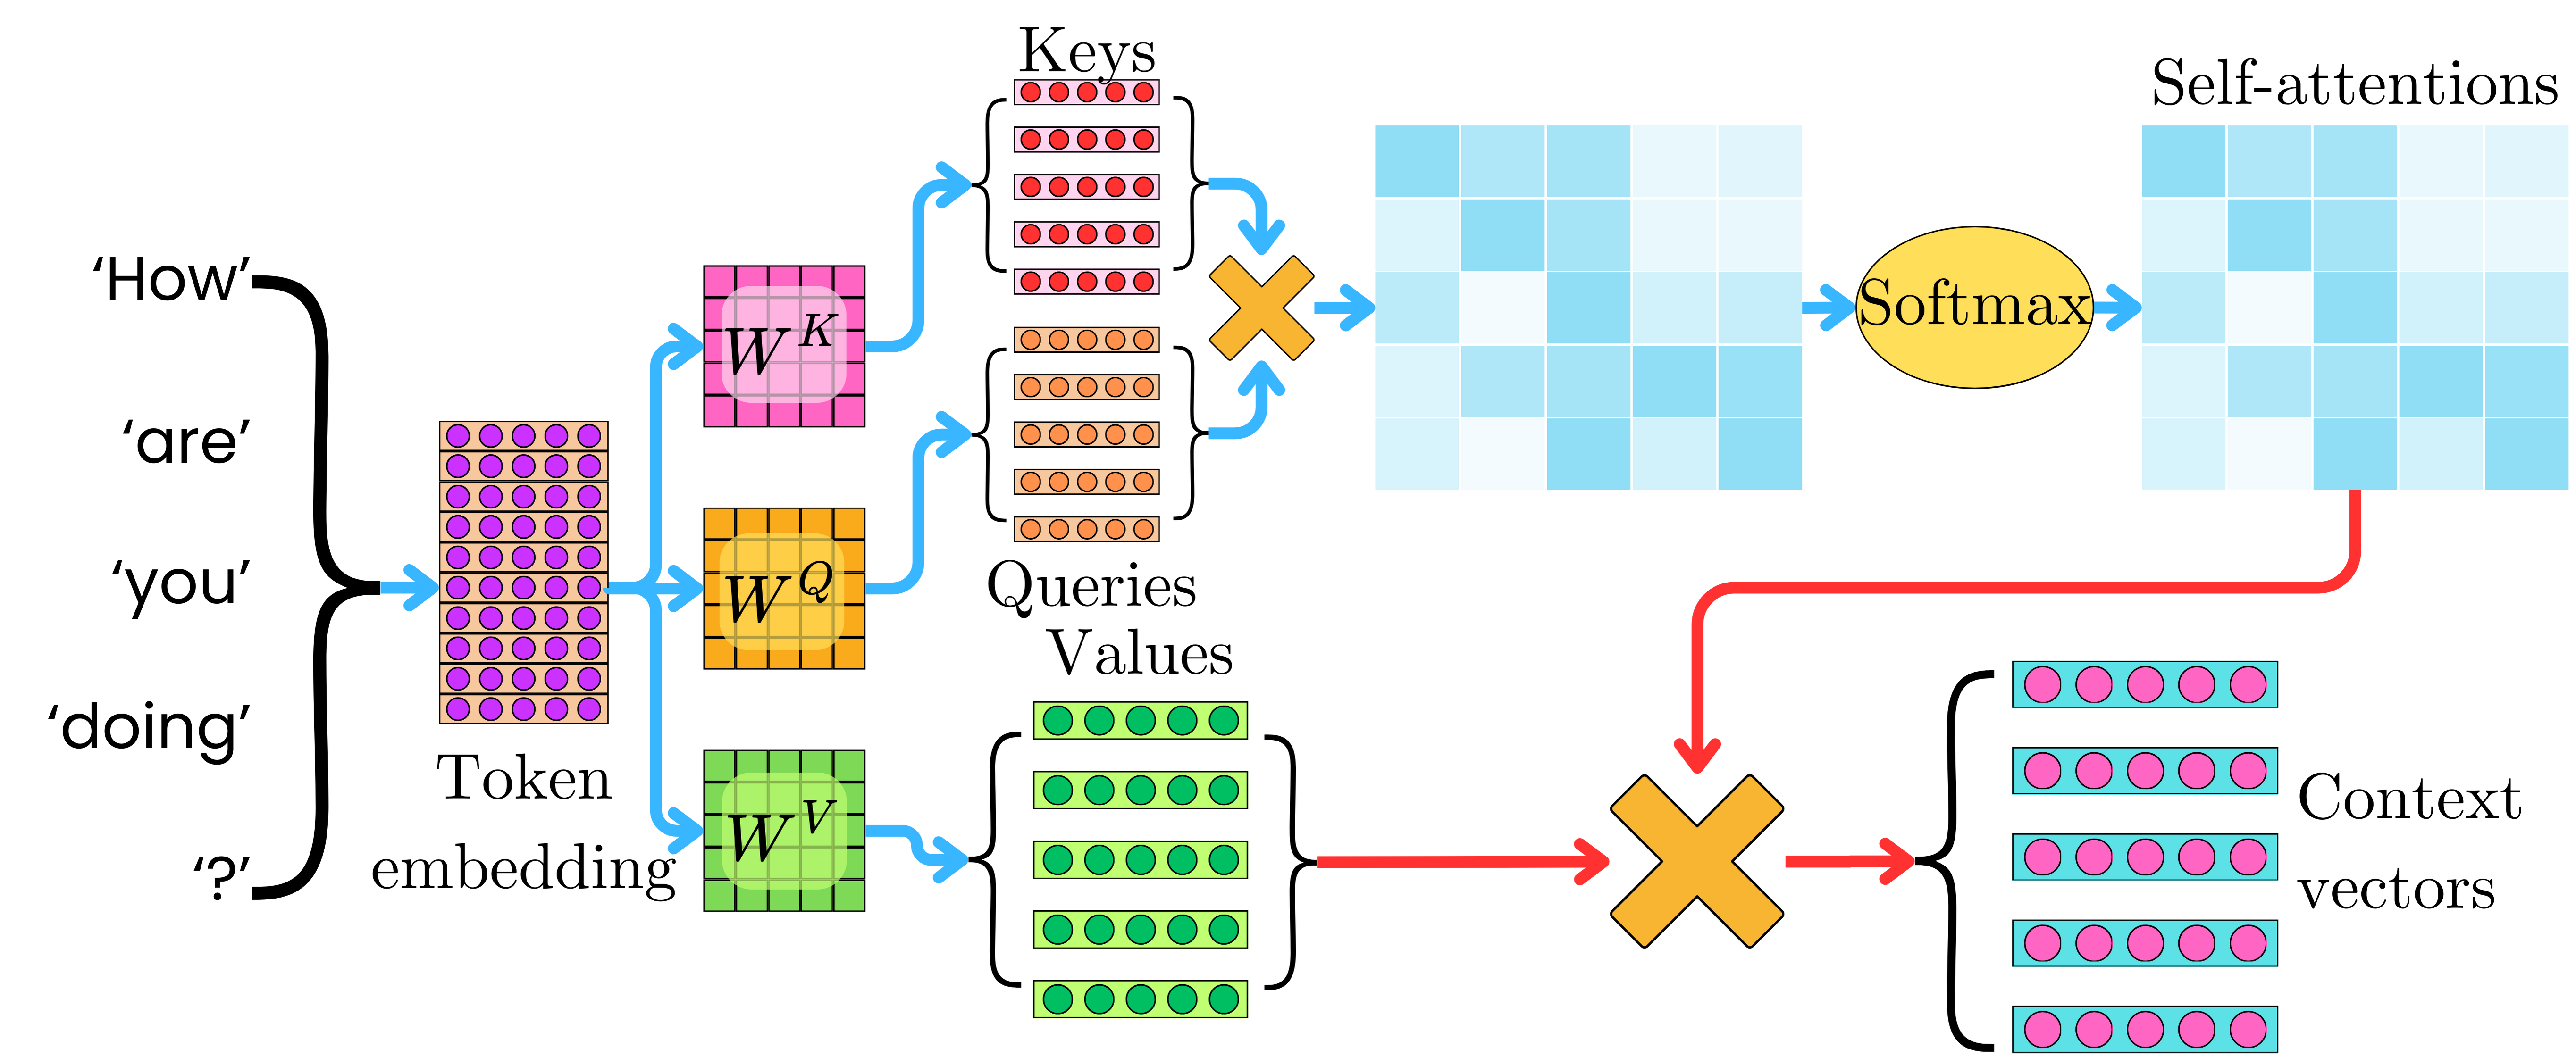
Attention Is All You Need: The Original Transformer Architecture
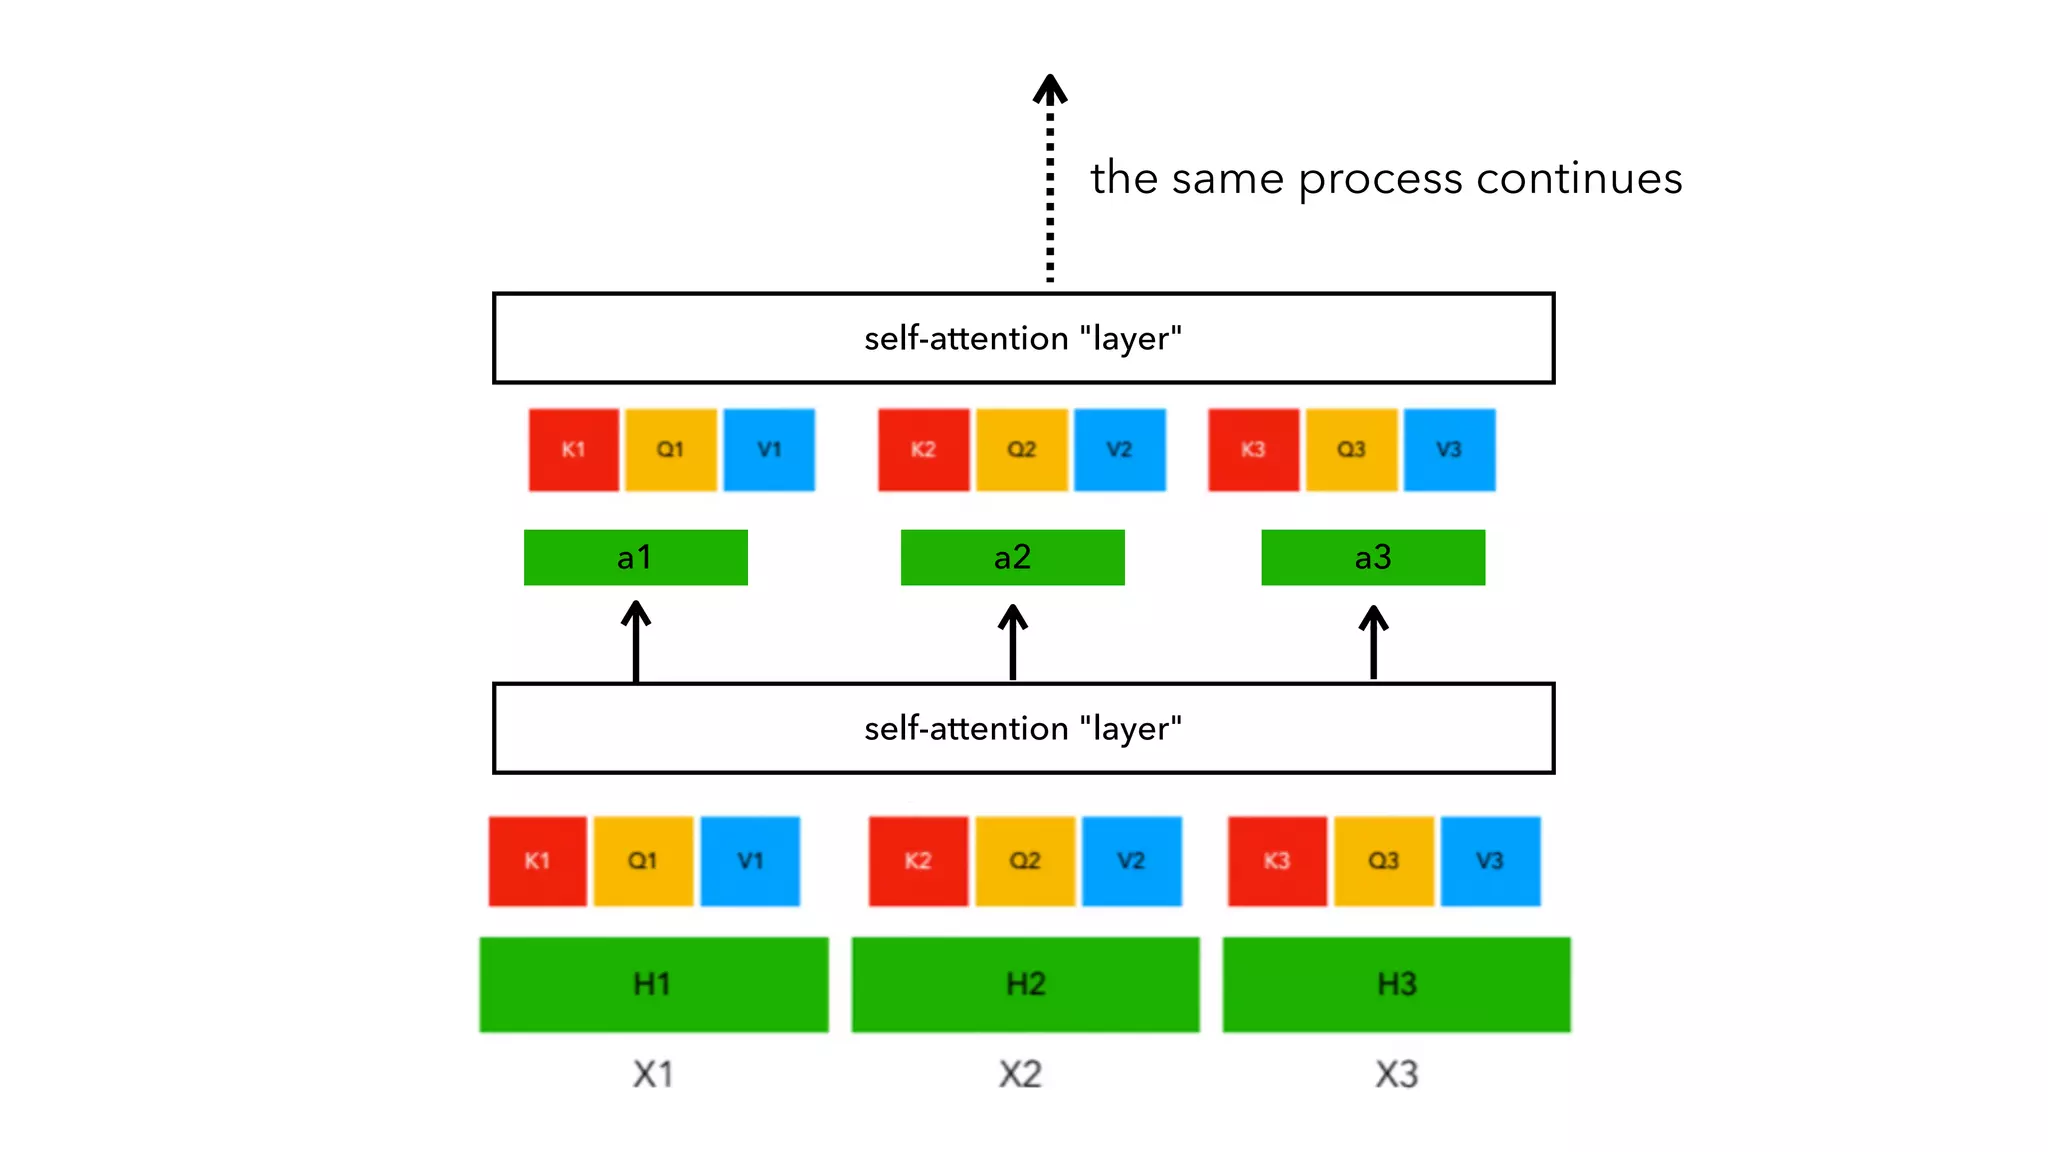
A Multiscale Visualization of Attention in the Transformer Model | PPT
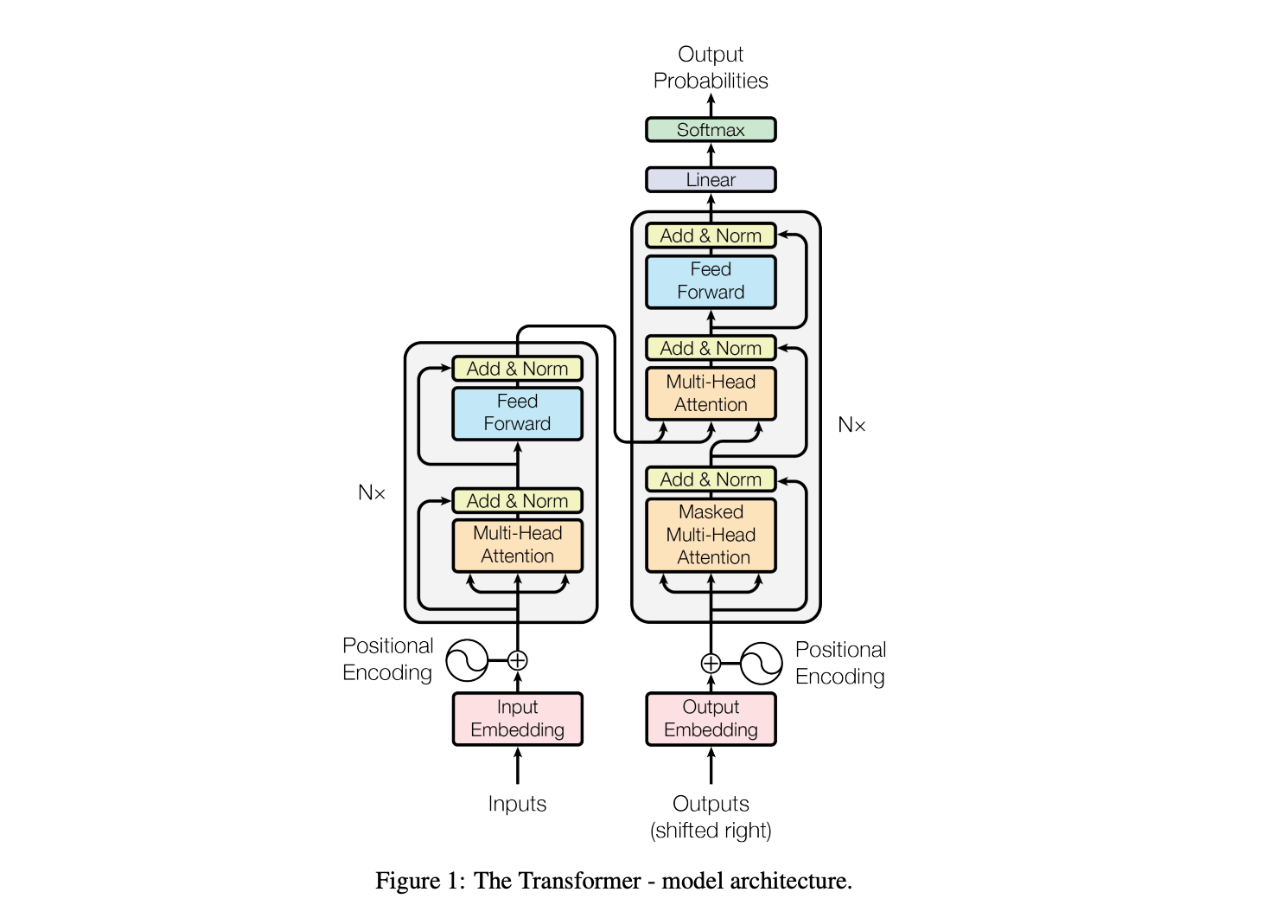
[basic] Attention and Transformer