
Advances In Attention Distillation For Efficient Transformer Models
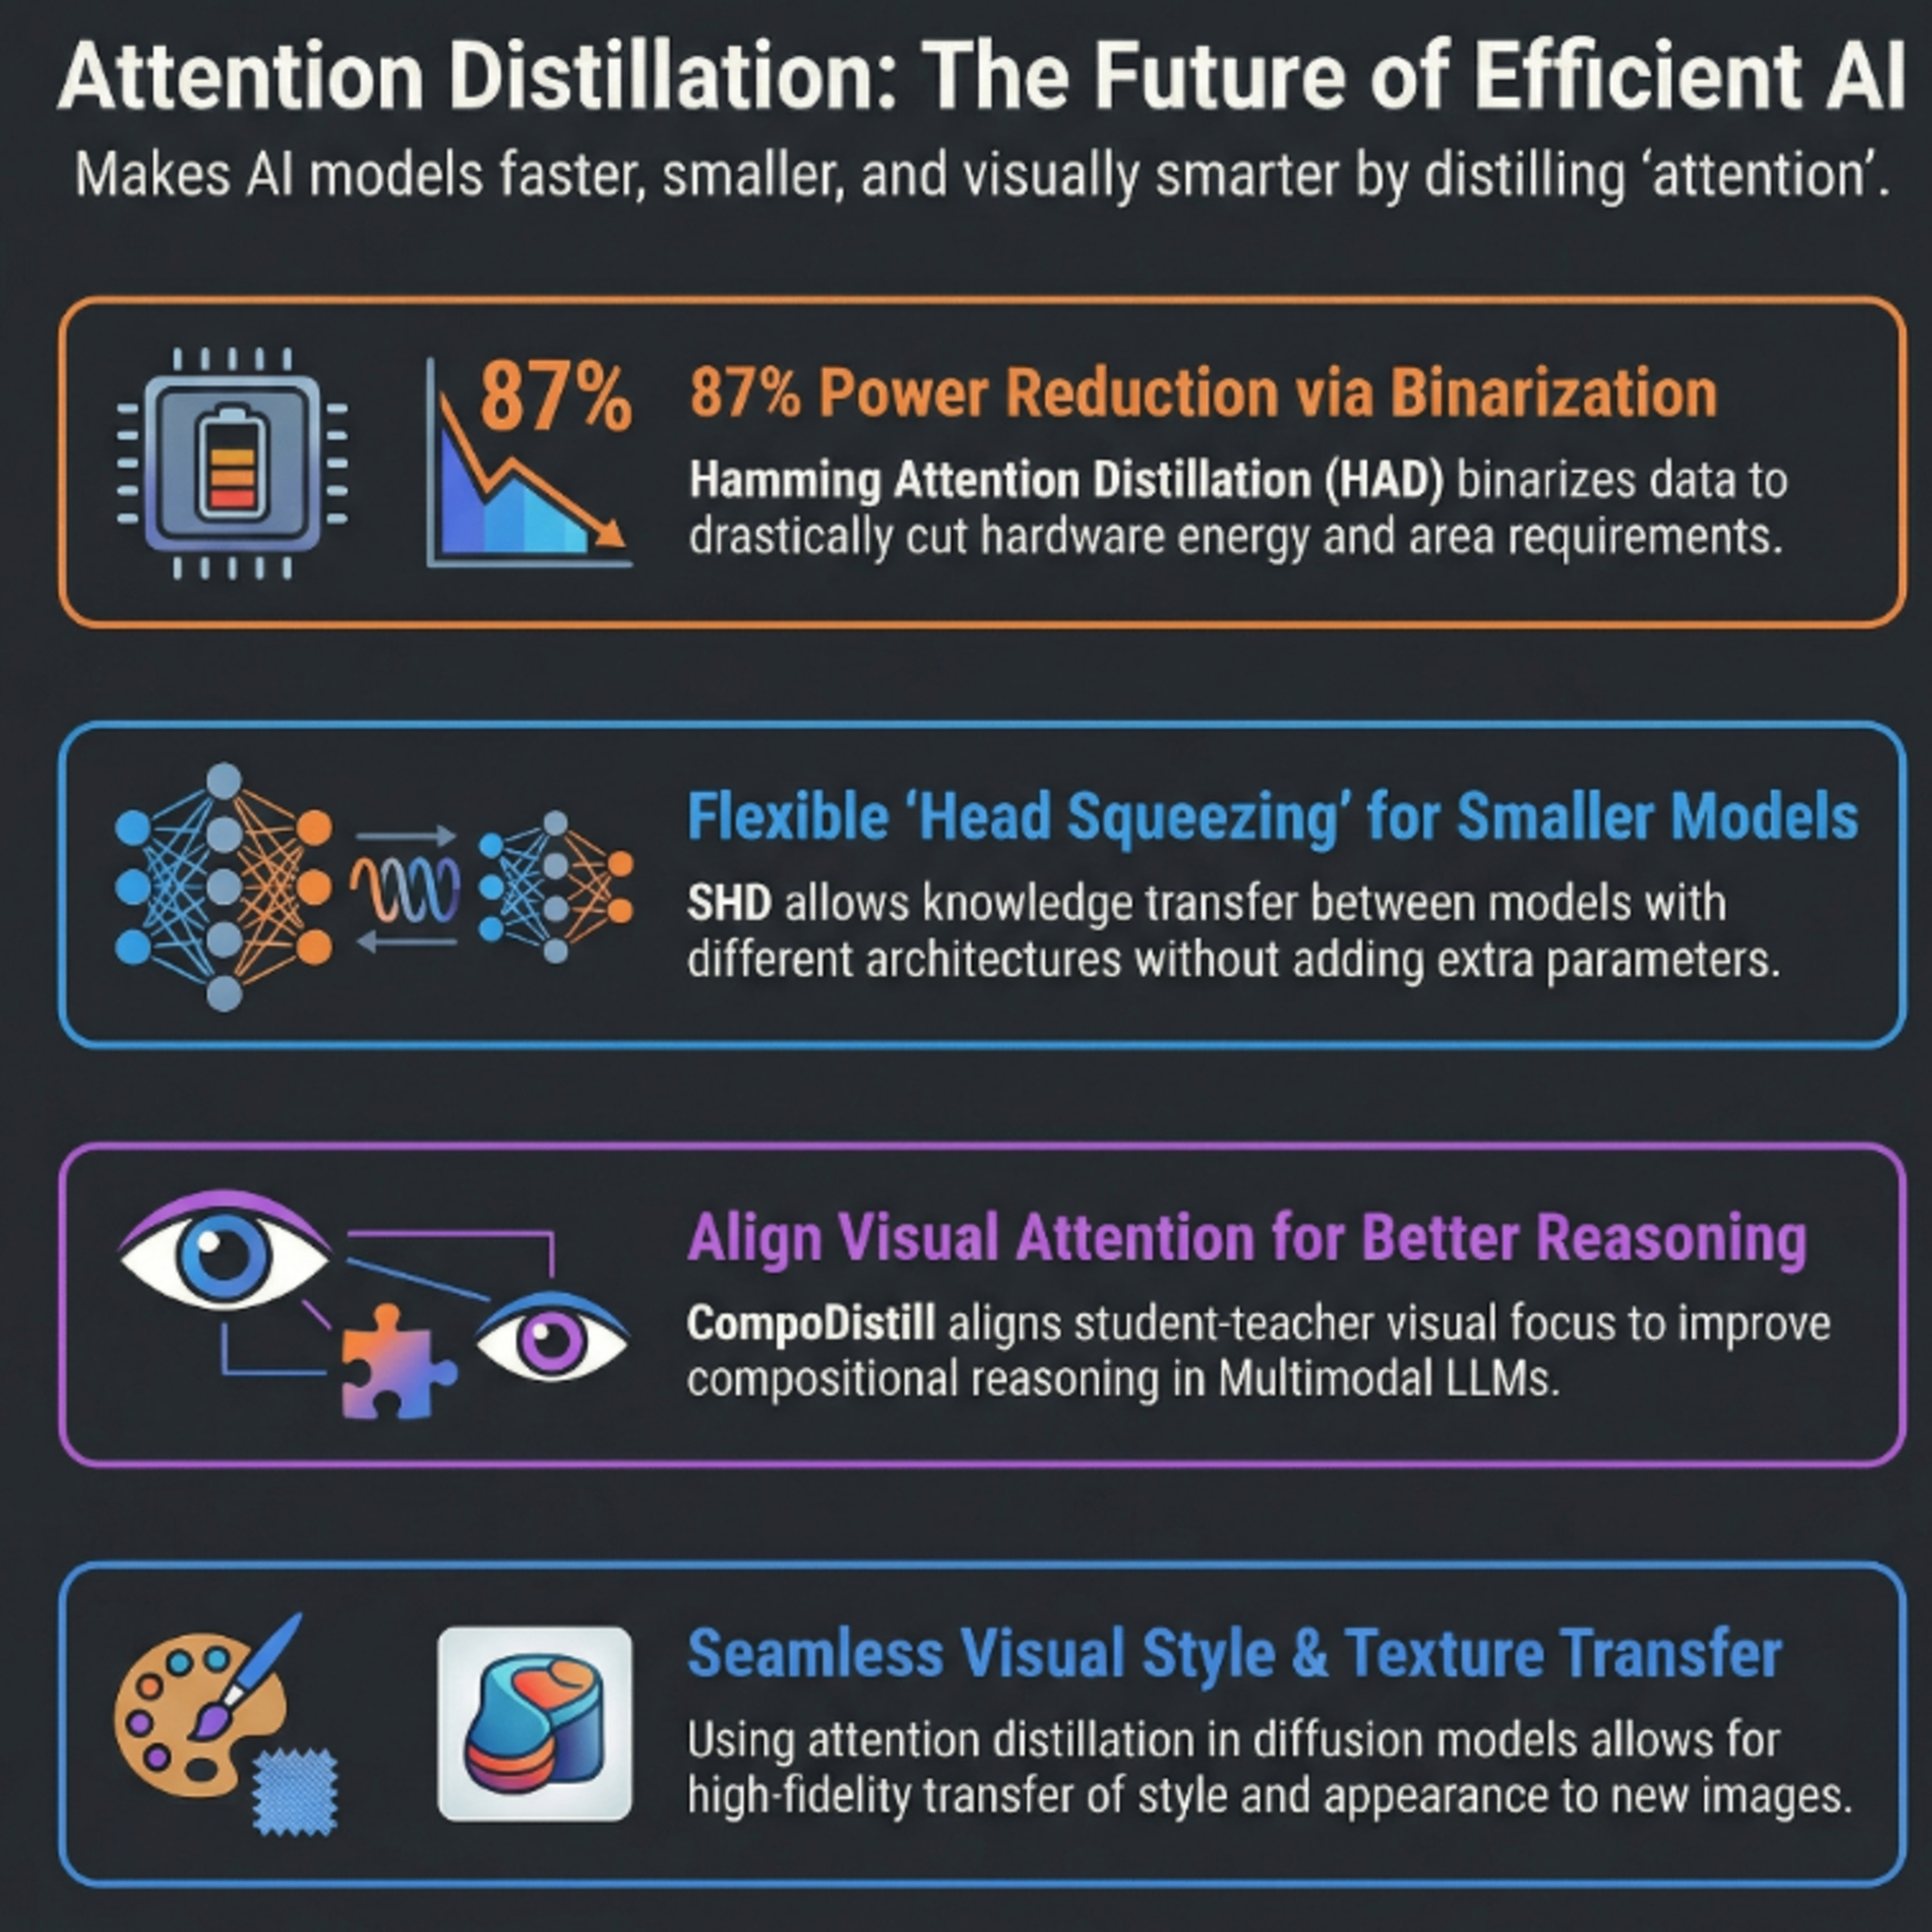
Advances in Attention Distillation for Efficient Transformer Models ...
How to Implement Attention Distillation for Transformer Models ...
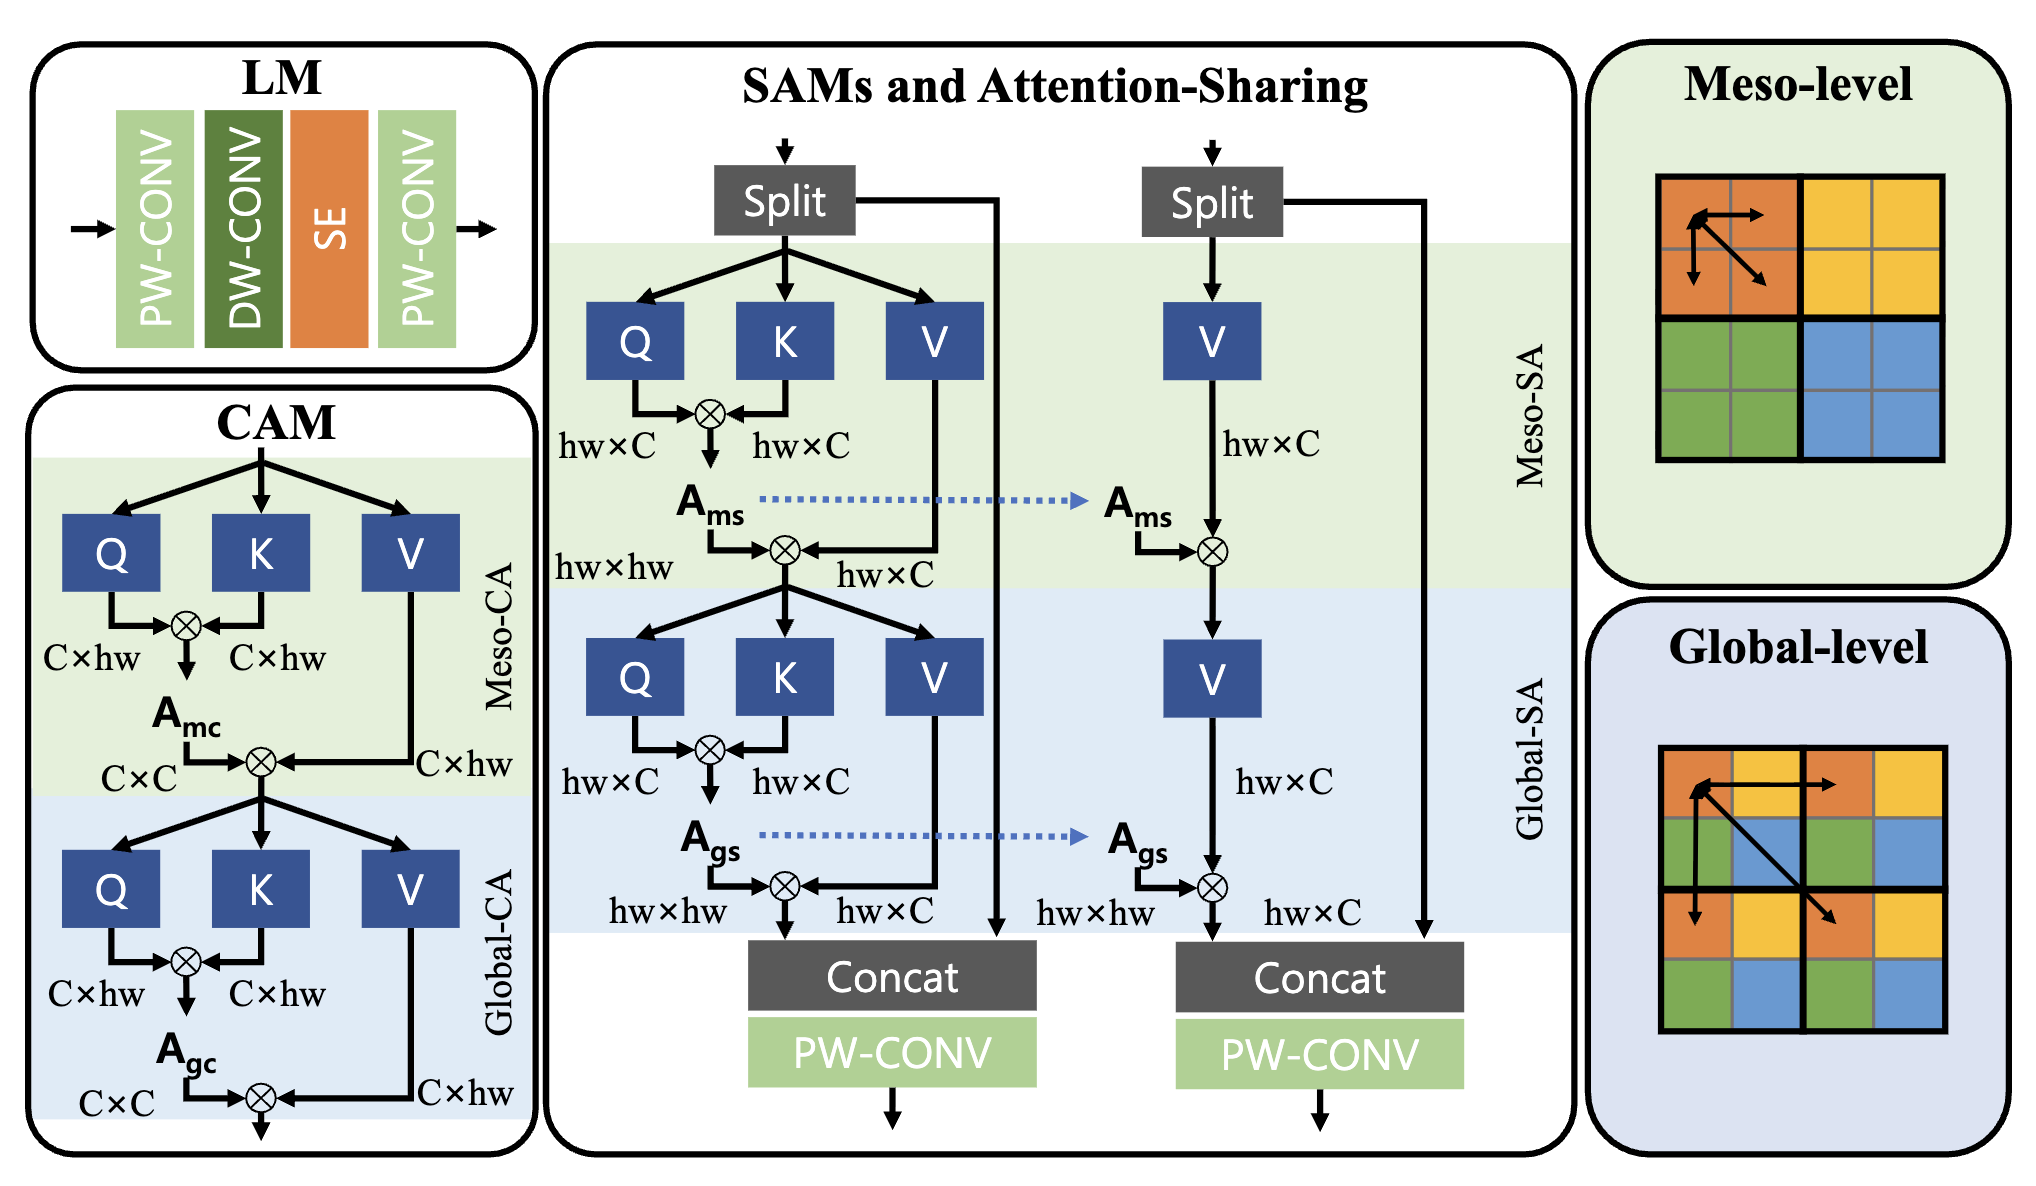
Efficient Attention-Sharing Information Distillation Transformer for ...

(PDF) Pruning‐guided feature distillation for an efficient transformer ...
(PDF) TransKD: Transformer Knowledge Distillation for Efficient ...

Loop and distillation: Attention weights fusion transformer for fine ...

3. Comparison of the attention mechanism in original transformer model ...

Attention → Mamba cross-architecture distillation is real Transformer ...

A Historical Survey of Advances in Transformer Architectures

Loop and distillation: Attention weights fusion transformer for fine ...
Advertisement Space (300x250)
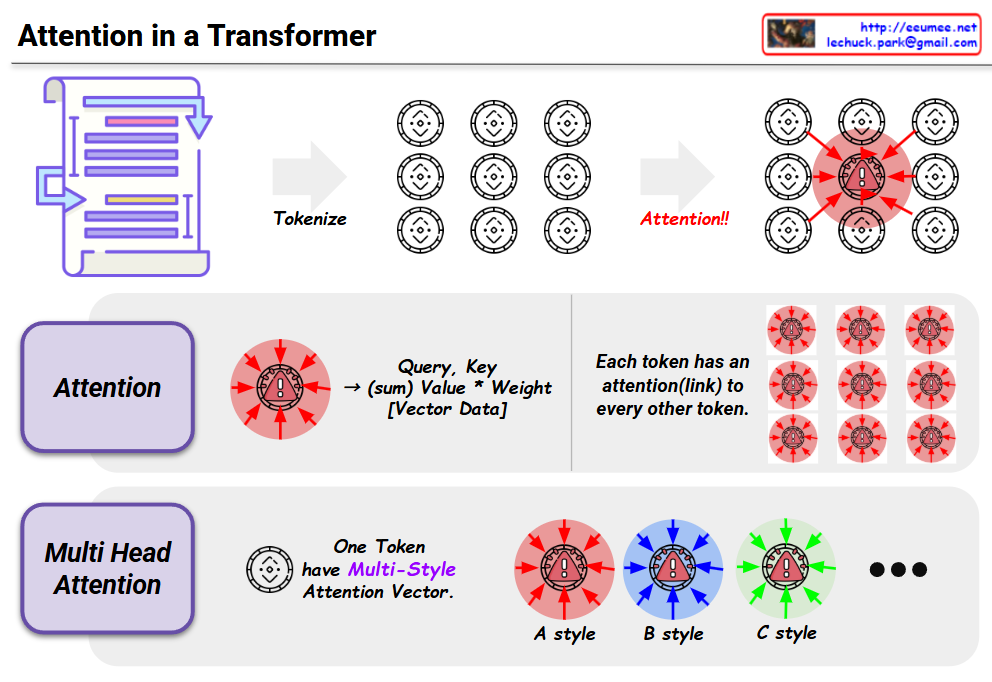
Attention in a Transformer – Lechuck Park
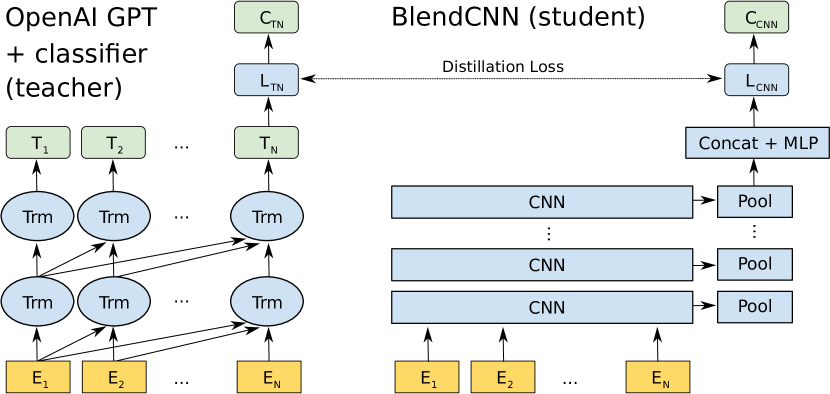
[1909.03508] Transformer to CNN: Label-scarce distillation for ...

(PDF) Advances in Text-to-Image Generation: Integrating Transformer ...

Knowledge Distillation for Efficient Transformer-Based Reinforcement ...
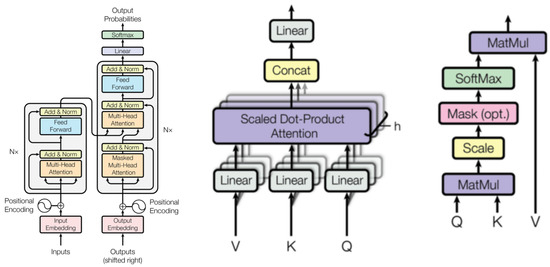
Leveraging Transformer Models for Enhanced Pharmacovigilance: A ...
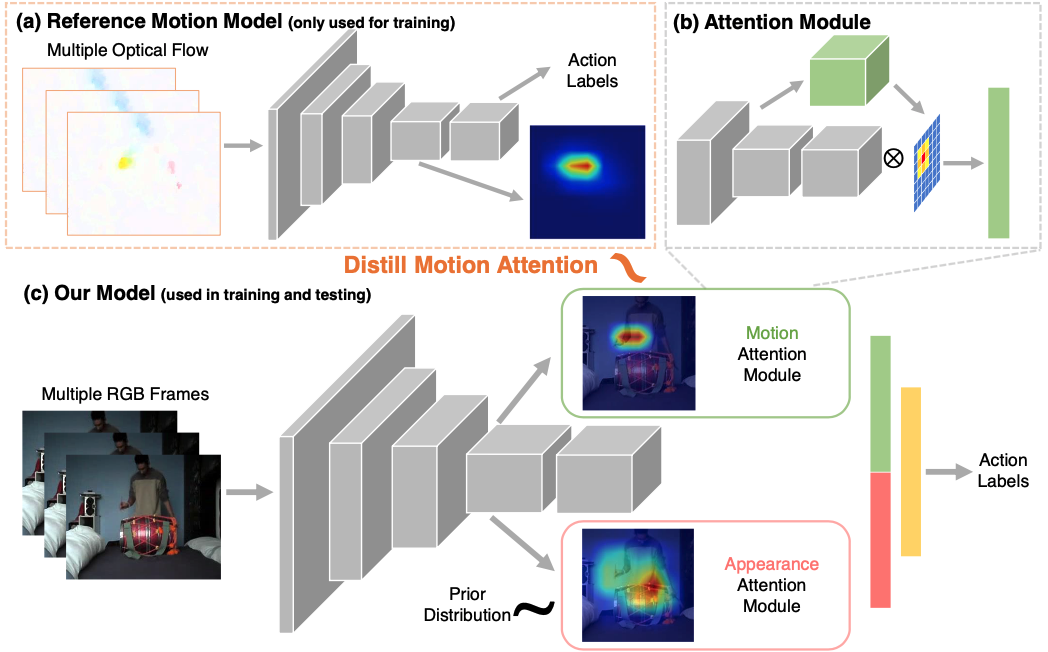
Attention Distillation for Learning Video Representations
Distillation of Transformer Models - Trelis Research
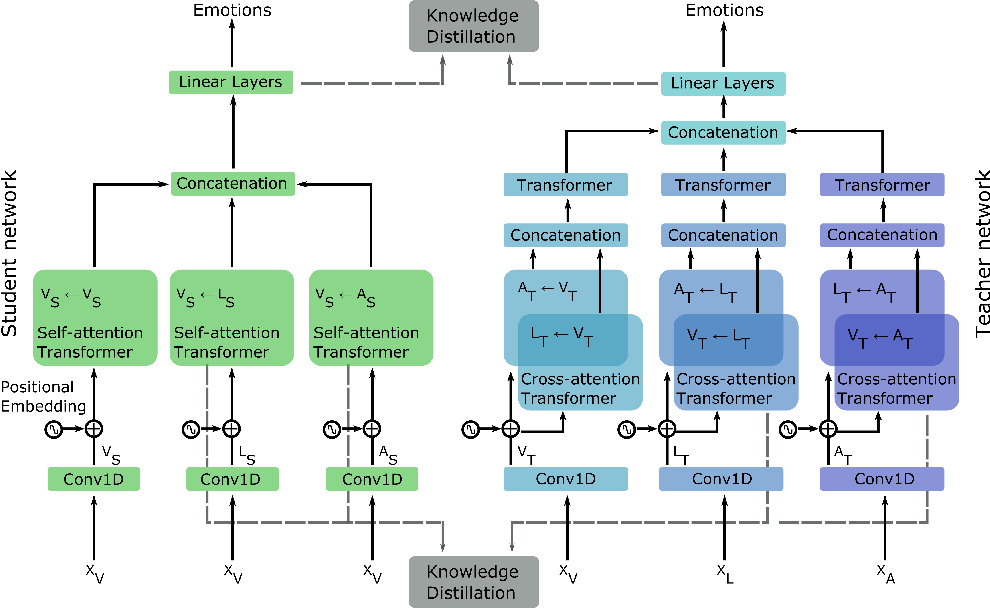
Figure 1 from From Multimodal to Unimodal Attention in Transformers ...
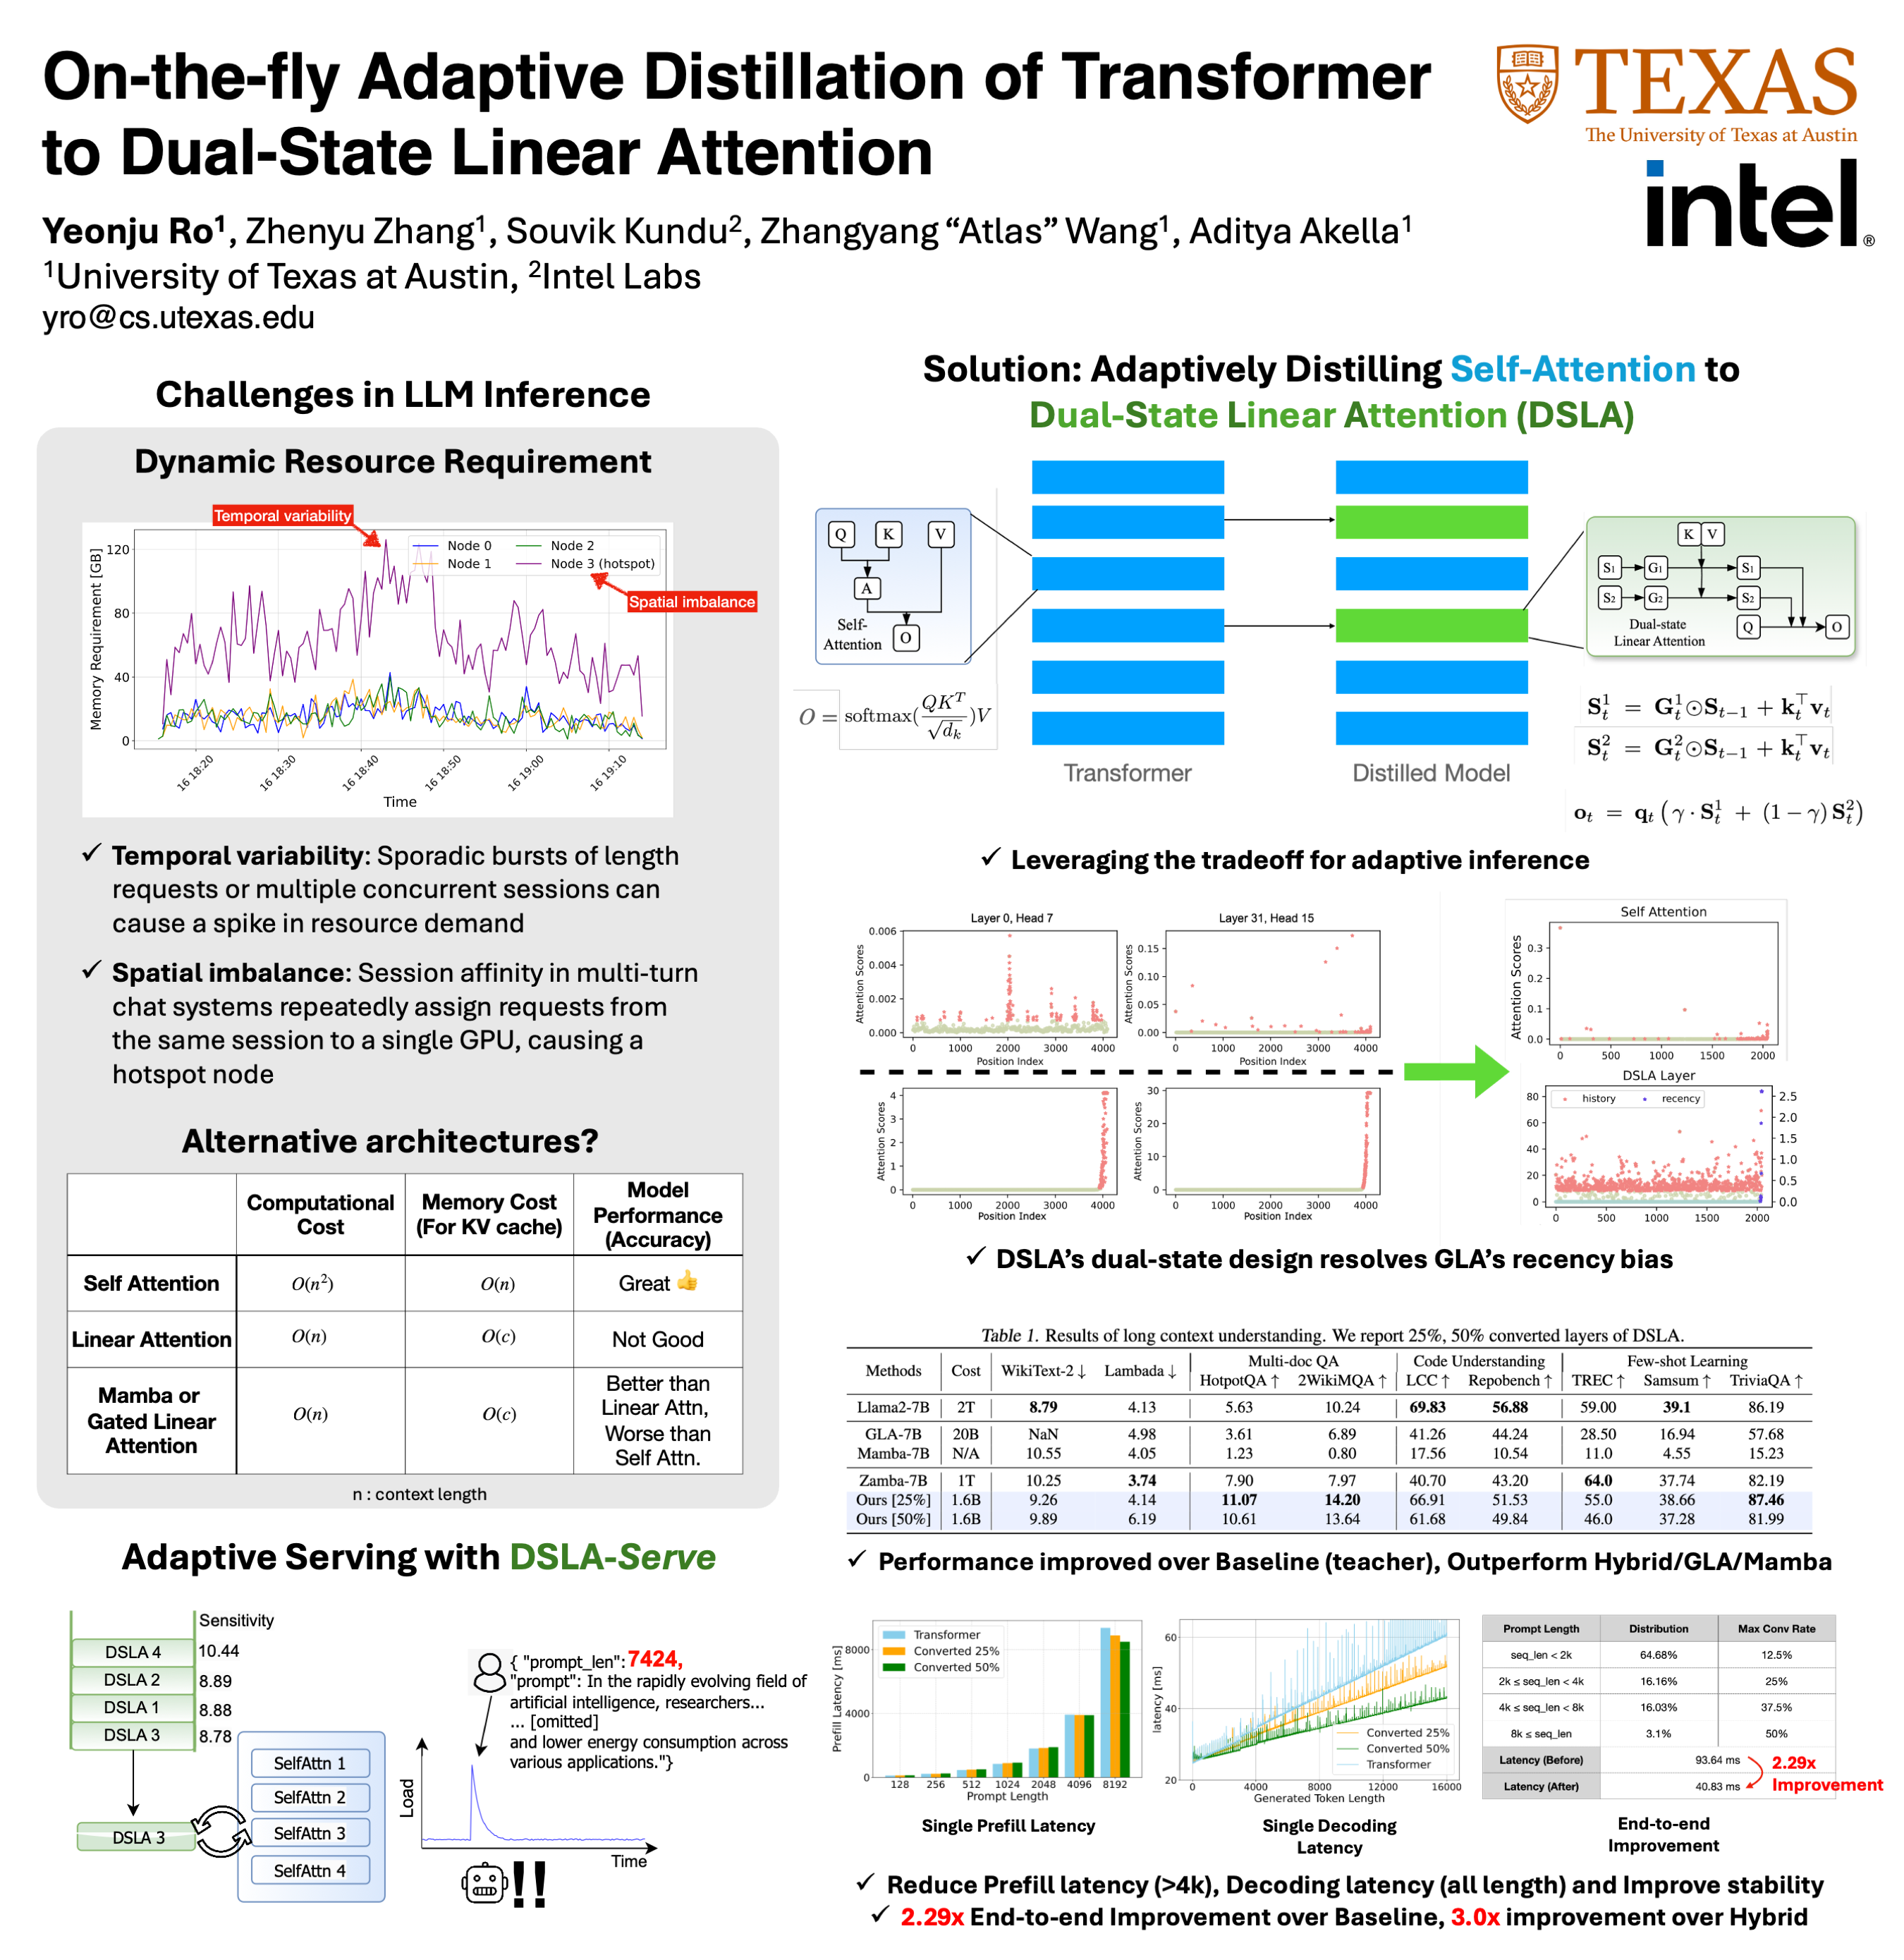
ICML Poster On-the-Fly Adaptive Distillation of Transformer to Dual ...

Attention Mechanisms in Transformers
Advertisement Space (336x280)
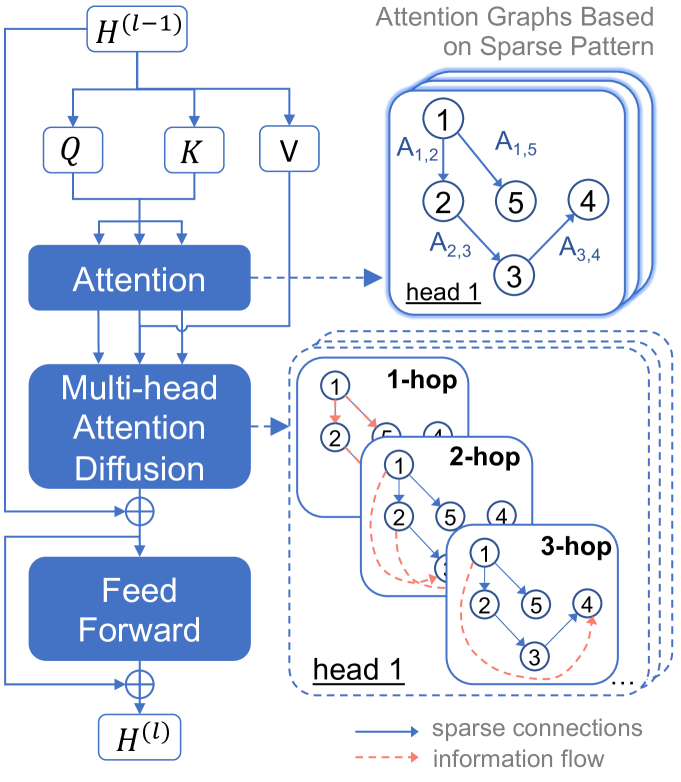
[2210.11794] Diffuser: Efficient Transformers with Multi-hop Attention ...
Transformer Model Fig. 2: Attention mechanism (a) shows complete ...

Matters of Attention: What is Attention and How to Compute Attention in ...
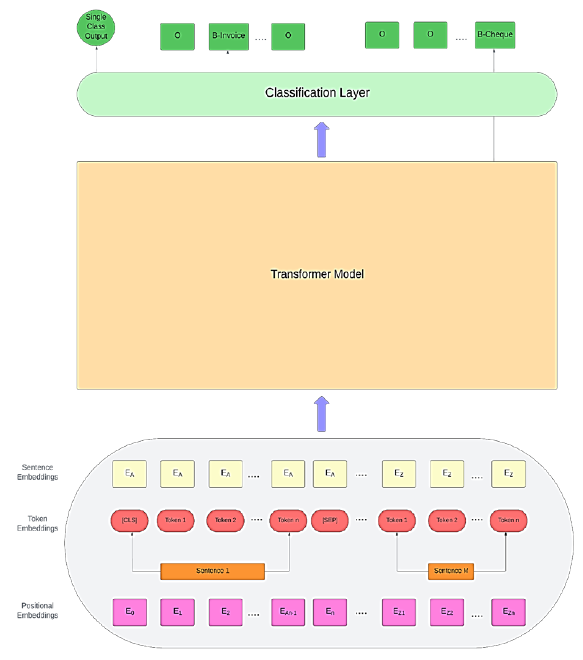
Multi-label multi-class text classification-enhanced attention in ...

(PDF) A Transformer-based Knowledge Distillation Network for Cortical ...

What is Transformer Model in AI? Features and Examples

Teacher student learning with hidden state and attention distillation ...
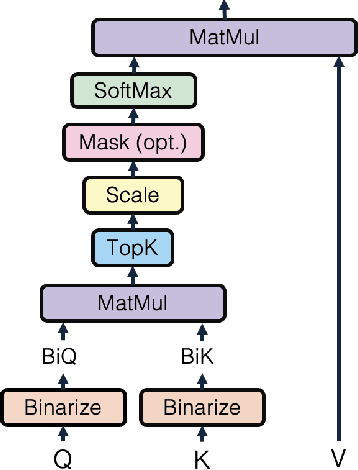
Hamming Attention Distillation: Binarizing Keys and Queries for ...
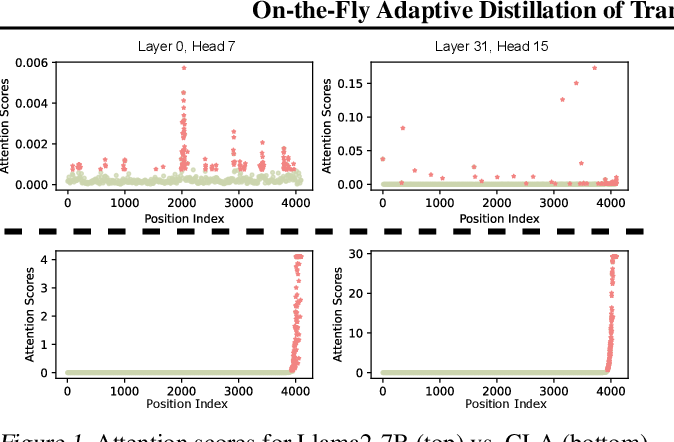
Figure 1 from On-the-Fly Adaptive Distillation of Transformer to Dual ...

Understanding The Attention Mechanism in Transformers with Code | by ...
Advertisement Space (336x280)

Transformer Model Fig. 2: Attention mechanism (a) shows complete ...

Hamming Attention Distillation: Binarizing Keys and Queries for ...

Training data-efficient image transformers & distillation through attention
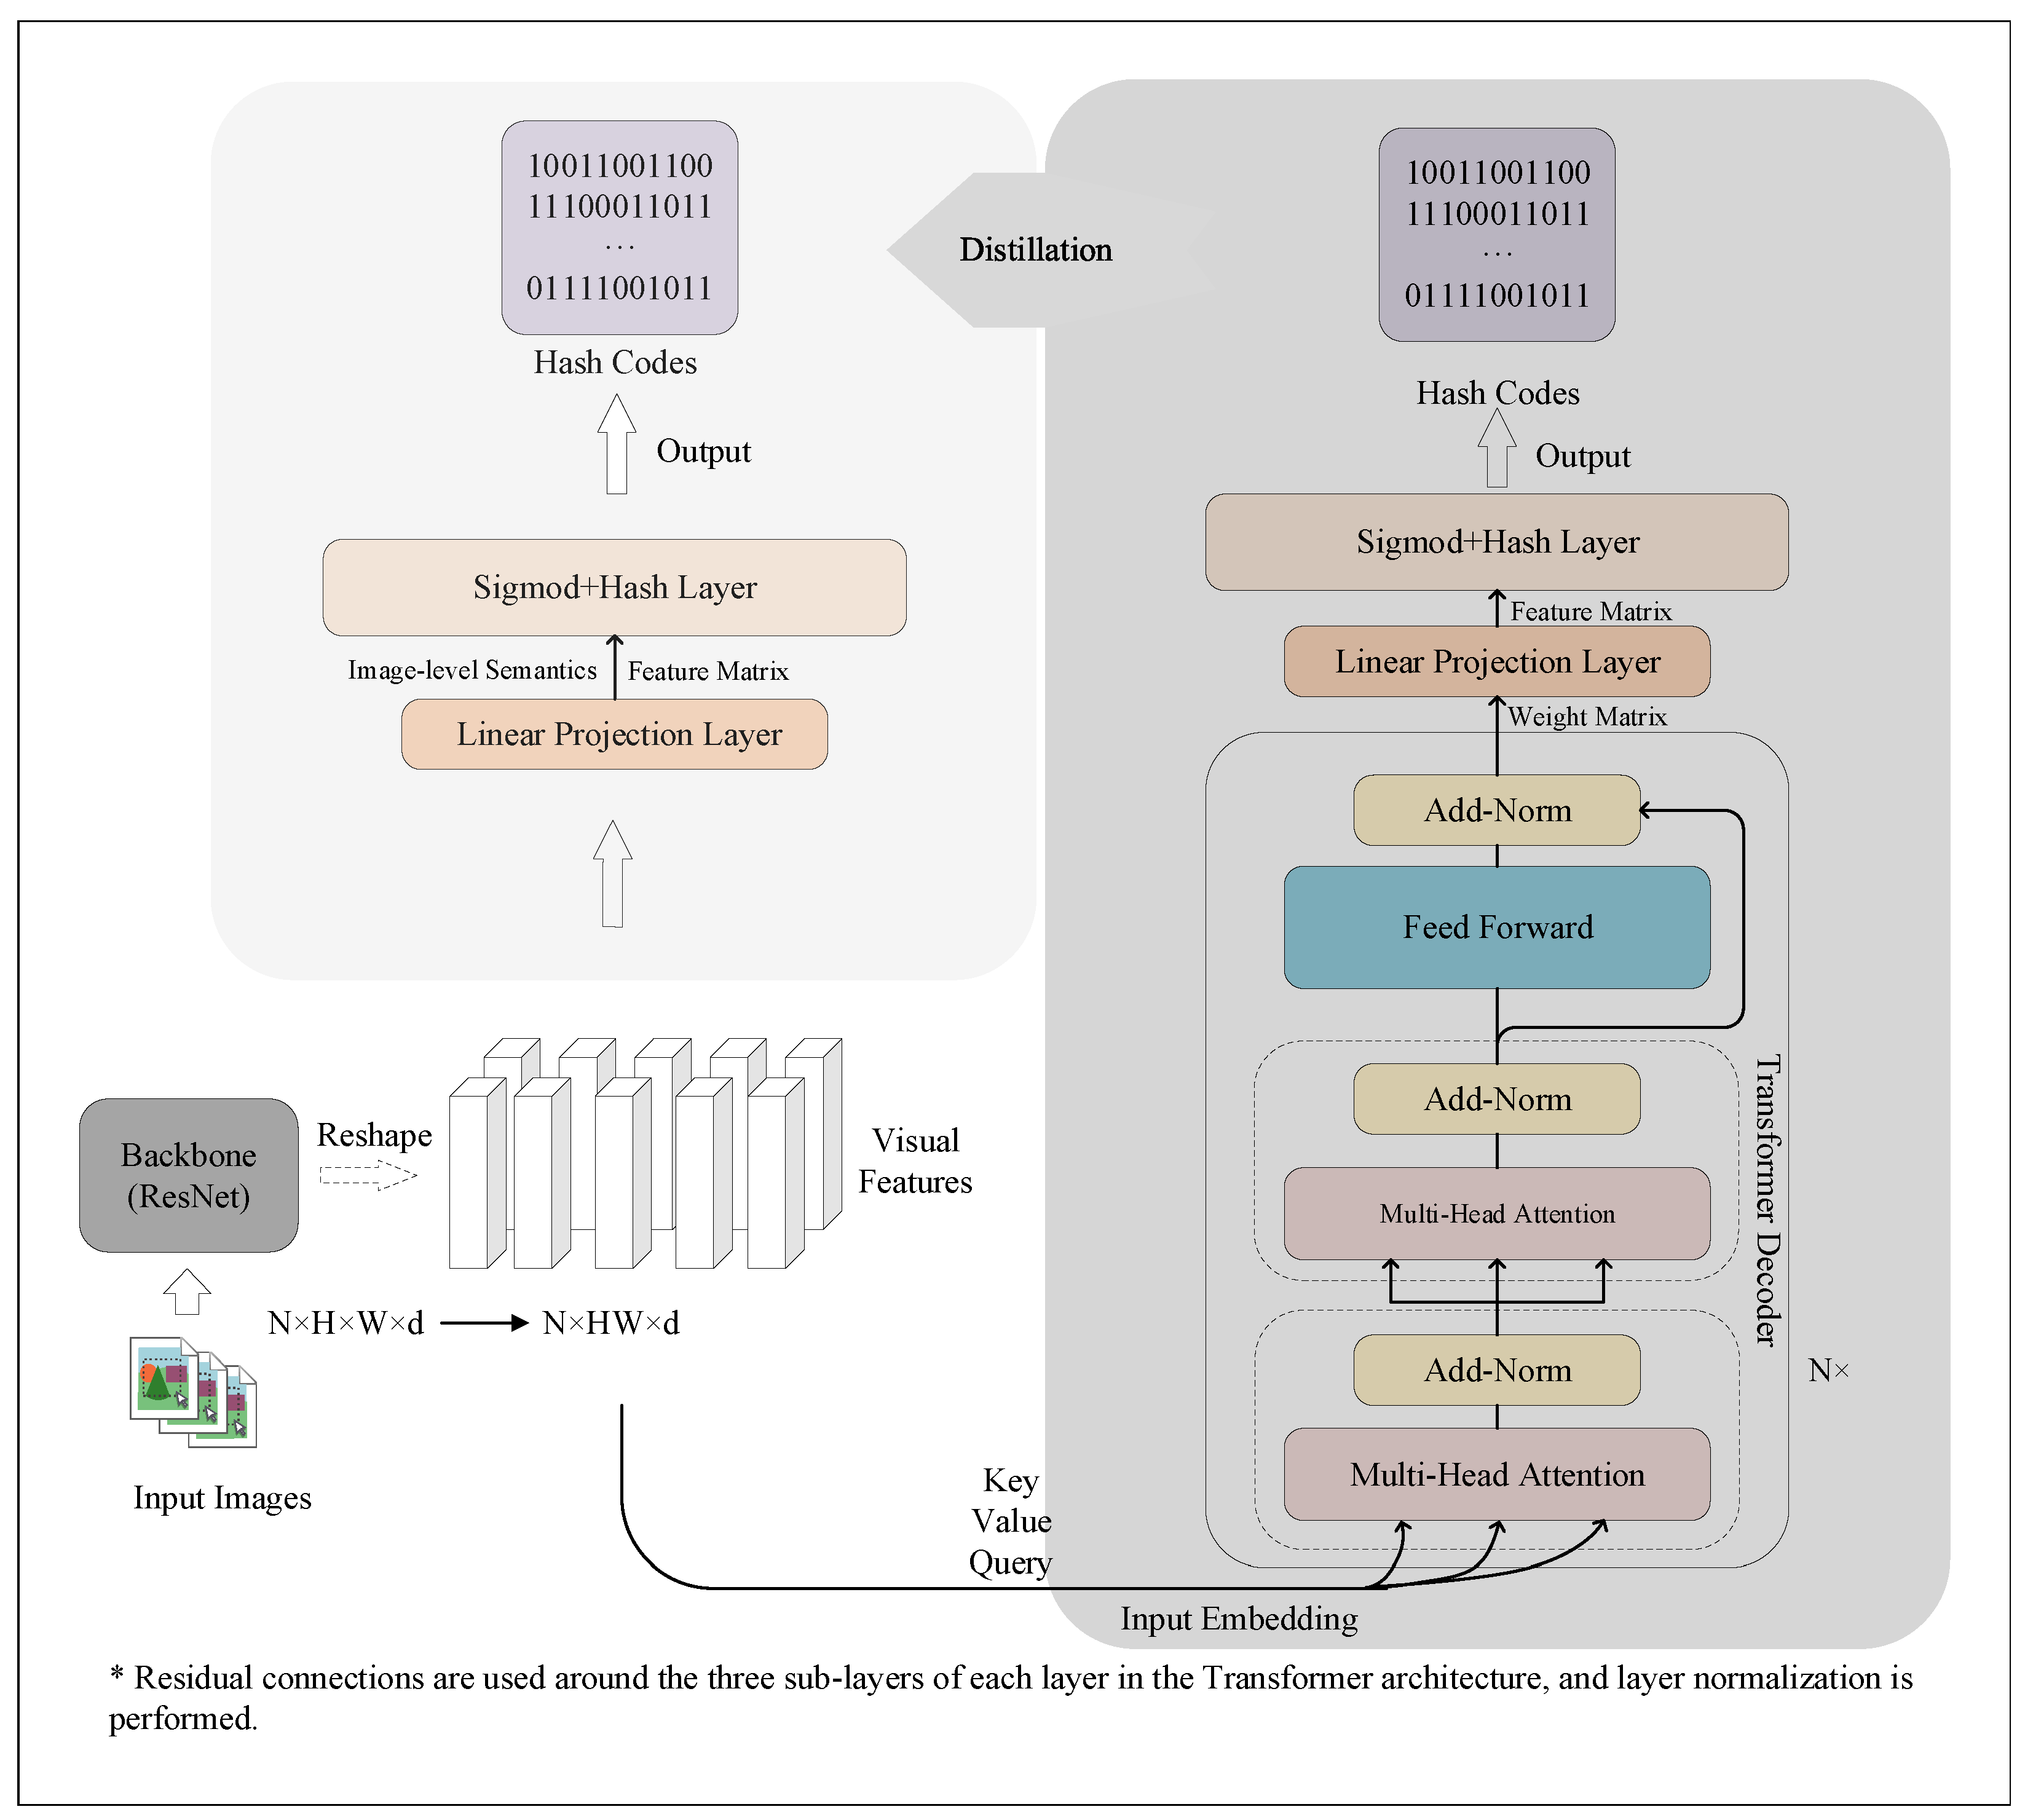
Transformer-Based Distillation Hash Learning for Image Retrieval

Agent Attention: Efficient Transformer Integration | PDF | Image ...

(PDF) Knowledge Distillation in Vision Transformers: A Critical Review