
How To Run Quantized Gguf Llms Locally On Gpu With Llamacpp No Cloud
How to Run Quantized GGUF LLMs Locally on GPU with llama.cpp (No Cloud ...

How to Run Quantized GGUF LLMs Locally on GPU with llama.cpp (No Cloud ...

How to Run Quantized GGUF LLMs Locally on GPU with llama.cpp (No Cloud ...

Run GGUF Quantized 7B LLMs with no GPU on your laptop | Virendra Singh
How to Run LLMs Locally Using Ollama and LlamaCPP

How to Run LLMs Locally with Ollama: GPU-Accelerated Setup Guide ...

How to Run LLMs Locally With llama.cpp and GGML | LLMs – Weights & Biases

How to Run LLaMA Locally on CPU or GPU | Python & Langchain ...

The easiest way to run LLMs locally on your GPU - llama.cpp Vulkan ...

Run LLMs Locally on Your GPU with vLLM (No APIs) | Top Python Libraries
Advertisement Space (300x250)

How to Run LLM Locally on Your Computer with LM Studio - Hongkiat
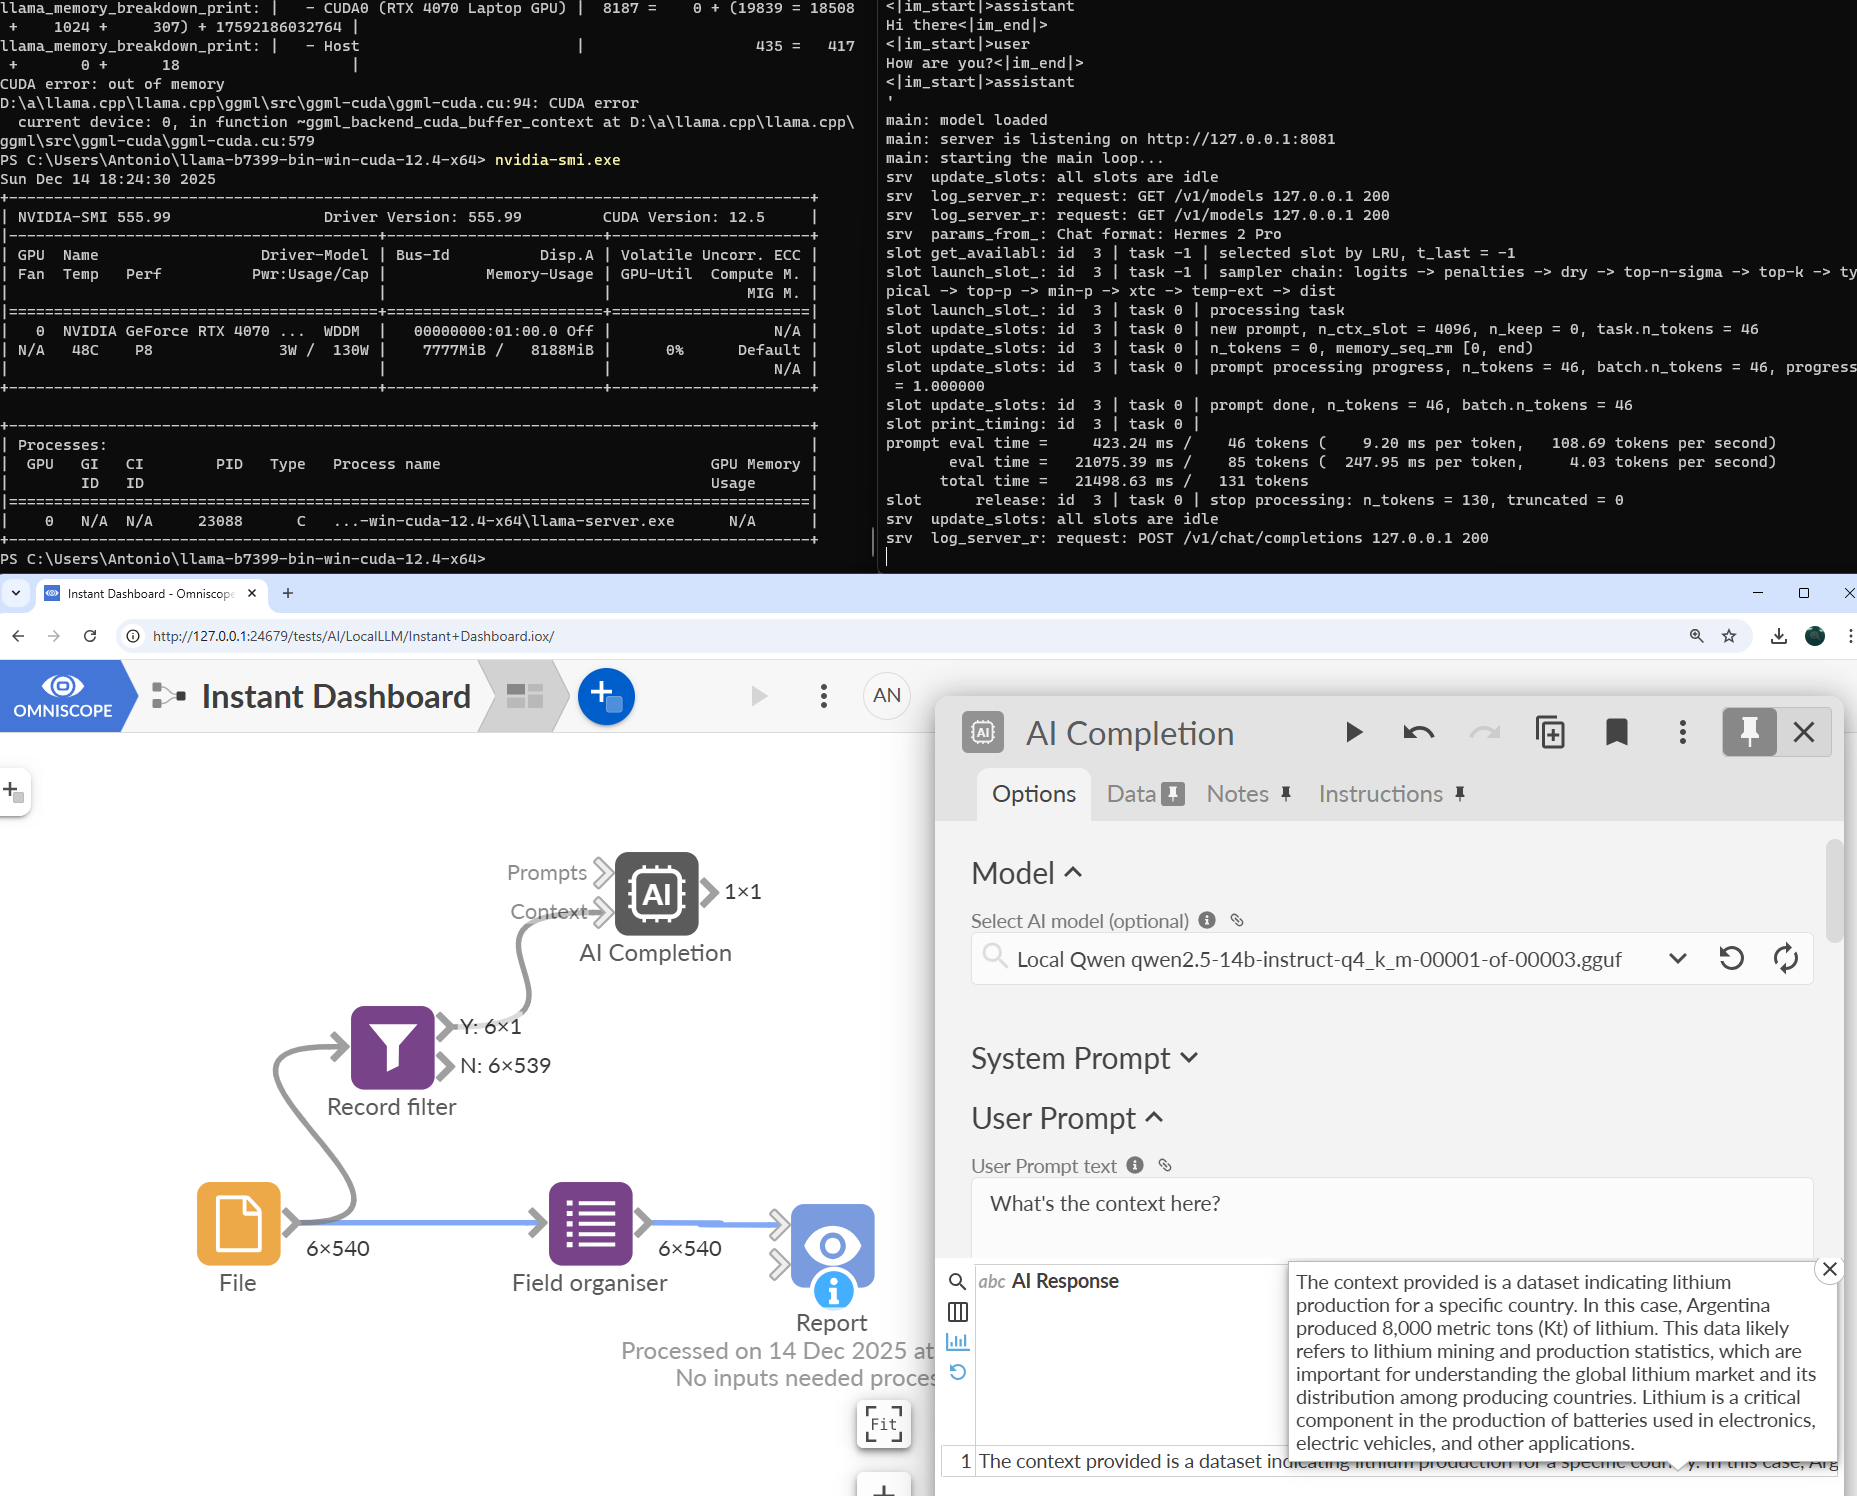
How to run Local LLMs on Windows with NVIDIA (llama.cpp + CUDA ...
Run Quantized GGUF Models at High Speed with llama.cpp on CPU and GPU ...

How to Run LLMs locally with WEB-UI like ChatGPT | Ollama Web-UI ...
How to Install and Run LLMs Locally on Android Phones - KDnuggets

Large Language Models: How to Run LLMs on a Single GPU - hyperight.com
GGUF Dynamic Quantization on GPU Cloud: Deploy LLMs 50% Cheaper with ...

How to Deploy GPU-Powered AI Model LLM on Google Cloud Run - Geeky Gadgets
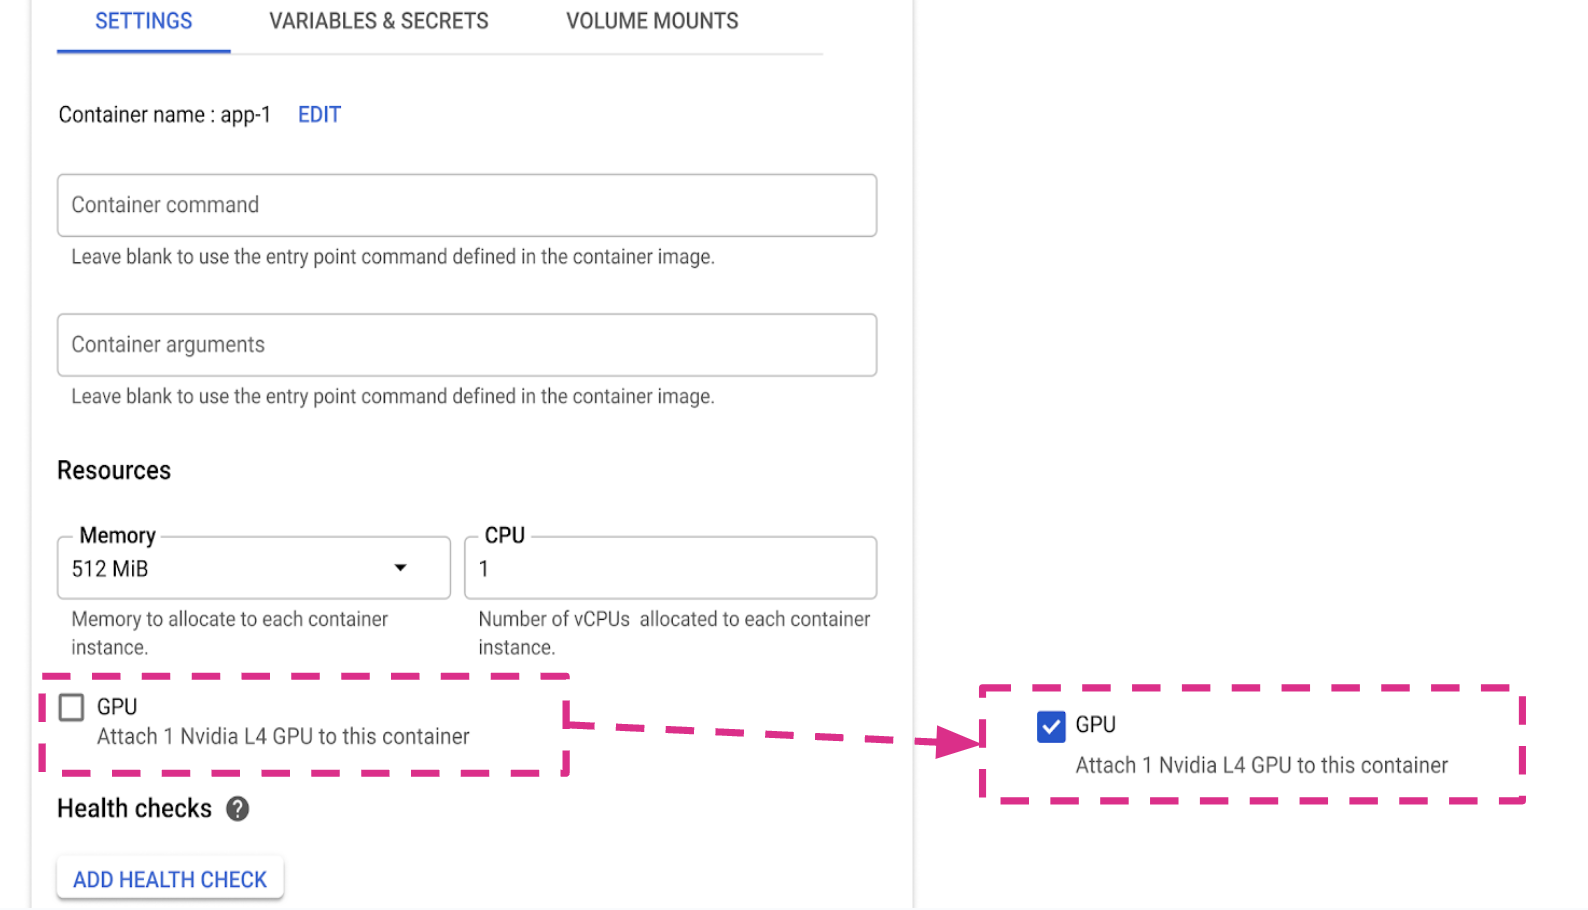
Run LLMs on Cloud Run with GPUs | Amulya Bhatia

How to Run LLMs Locally — A Deep Dive – SKR TEK
Advertisement Space (336x280)

How To Run LLMs Locally - Deployment And Benchmark

AMD GPU 6700XT run a 13 Billion LLM Model - how to run LLaMA 4bit mode ...

LLMs with No GPUs - Use Custom GGUF Models with LLMWare - YouTube
How to Use llama.cpp to Run LLaMA Models Locally in 2026

Meet GGUF Loader: Run Local LLMs with Zero Hassle - DEV Community

How to Use llama.cpp to Run GGUF Language Models in iOS Apps

How To Run LLMs Locally?
Can You Run LLMs Locally Without a GPU? I Tested 8 Models on Linux

Local LLMs: How To Run gguf-bassed Models With Gradio - YouTube

⚙️ Tools to Run Open LLMs Locally Llama, Phi, Mistral, Gemma etc are ...
Advertisement Space (336x280)
What LLM Can I Run Locally on My GPU or Mac? (2026 Calculator + Guide ...

Install and run LLM's Locally with text generation webui on AMD gpu's ...

Meet GGUF Loader: Run Local LLMs with Zero Hassle - DEV Community

Run Any GGUF Model Locally with Ollama | by Manish Singh | Medium
Run LLMs on Any GPU: GPT4All Universal GPU Support | Vuink.com

Run LLMs Locally with Local Server (Llama 3 + LM Studio) - YouTube