
Run Gguf Quantized 7b Llms With No Gpu On Your Laptop Virendra Singh

Run GGUF Quantized 7B LLMs with no GPU on your laptop - YouTube

How to Run Quantized GGUF LLMs Locally on GPU with llama.cpp (No Cloud ...
How to Run Quantized GGUF LLMs Locally on GPU with llama.cpp (No Cloud ...

GGUF Quantization with Imatrix and K-Quantization to Run LLMs on Your CPU

Run LLMs Locally on Your GPU with vLLM (No APIs) | Top Python Libraries

Run Al Models on Your Laptop with Open-Source LLMs | Mistral-7B ...

GPT4All: Run Local LLMs on Your Laptop Without GPU
Microsoft BitNet: Run 100B Parameter LLMs on Your CPU, No GPU Required
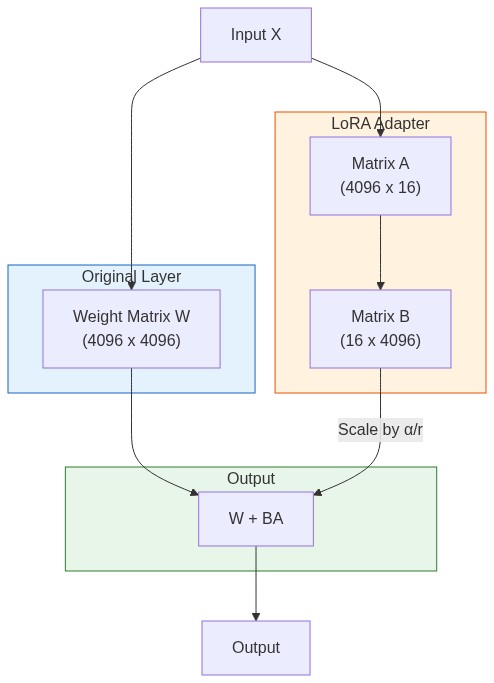
Fine-Tuning LLMs with QLoRA: Run a 7B Model on a Single GPU | OneRuby.dev

How to run LLMs on your laptop with quantization | Maxym Muzychenko ...
Advertisement Space (300x250)
Run Quantized GGUF Models at High Speed with llama.cpp on CPU and GPU ...

GGUF Quantization with Imatrix and K-Quantization to Run LLMs on Your CPU
Run LLMs on Your CPU’s NPU (NO GPU Needed) – Full Setup Guide - YouTube
GGUF Dynamic Quantization on GPU Cloud: Deploy LLMs 50% Cheaper with ...

How to run Llama-7B on a laptop with 4GB GPU - YouTube

How to Run Open-Source LLMs on a Cloud Server with a GPU - MainWP ...

Run LLMs on a 6 GB Laptop GPU & CPU — SmolLM-3 Quantization + Nim ...
How to run LLMs locally on your laptop for free, a beginner’s guide ...

Run GGUF Quantized Models Easily with KoboldCPP on Runpod | Runpod Blog

BitNet: How Microsoft Made 100B LLMs Run on Your Laptop CPU | YUV.AI Blog
Advertisement Space (336x280)

Why Run LLMs on Your Own GPU for Agentic Workflow

LLMs with No GPUs - Use Custom GGUF Models with LLMWare - YouTube

Large Language Models: How to Run LLMs on a Single GPU - hyperight.com

Meet GGUF Loader: Run Local LLMs with Zero Hassle - DEV Community

How To Run LLMs On Your RTX PC - Part 1 (Hugging Face) - NUA Dev

How to Use Intel and AMD GPUs to run LLMs on Your PC - YouTube

Run Google Gemma 2B 7B Locally on the CPU & GPU - YouTube
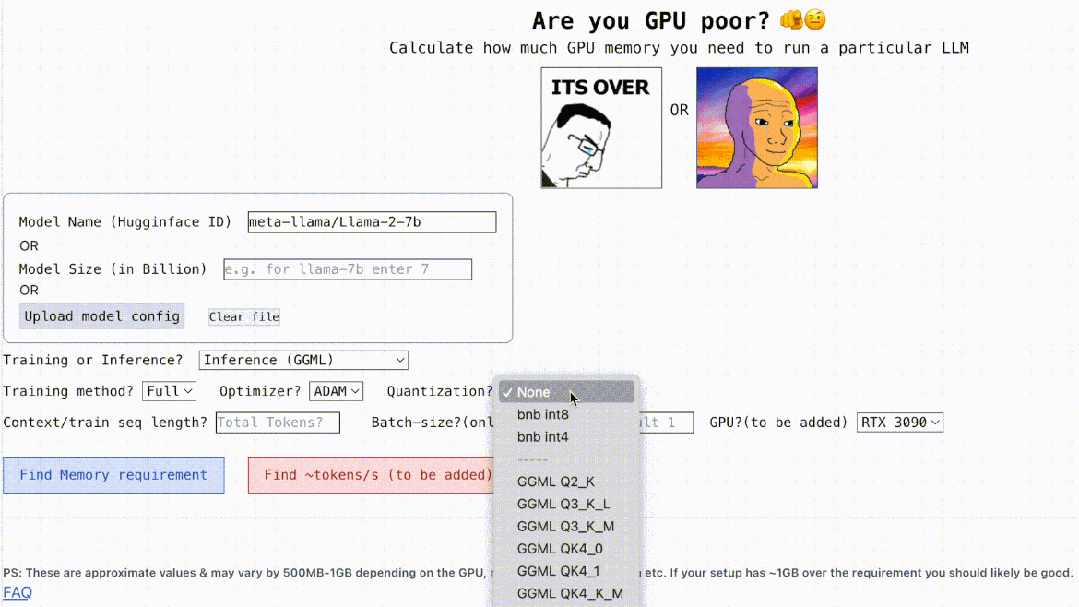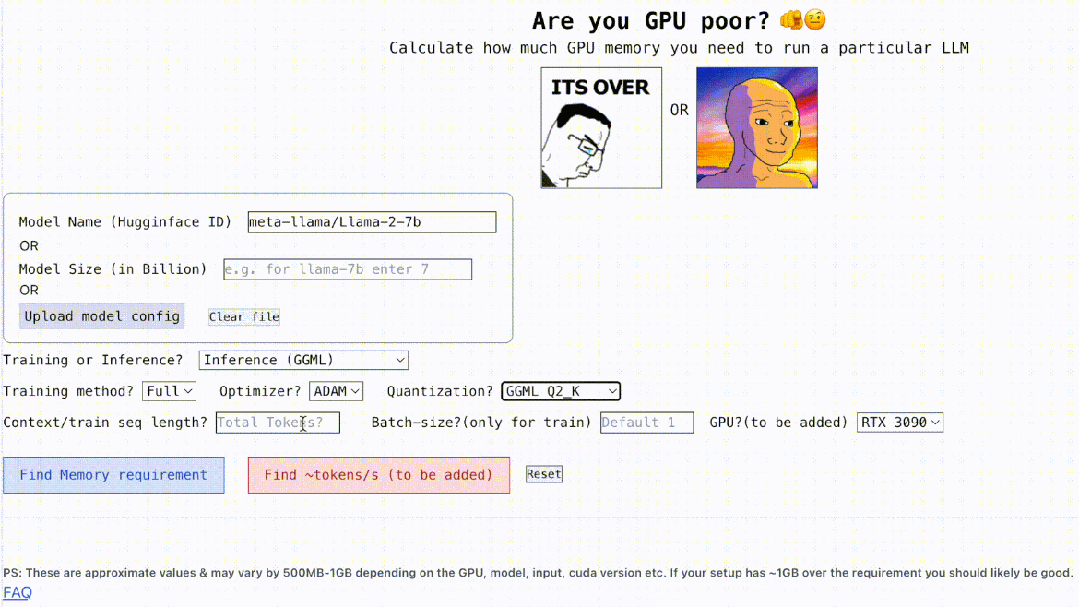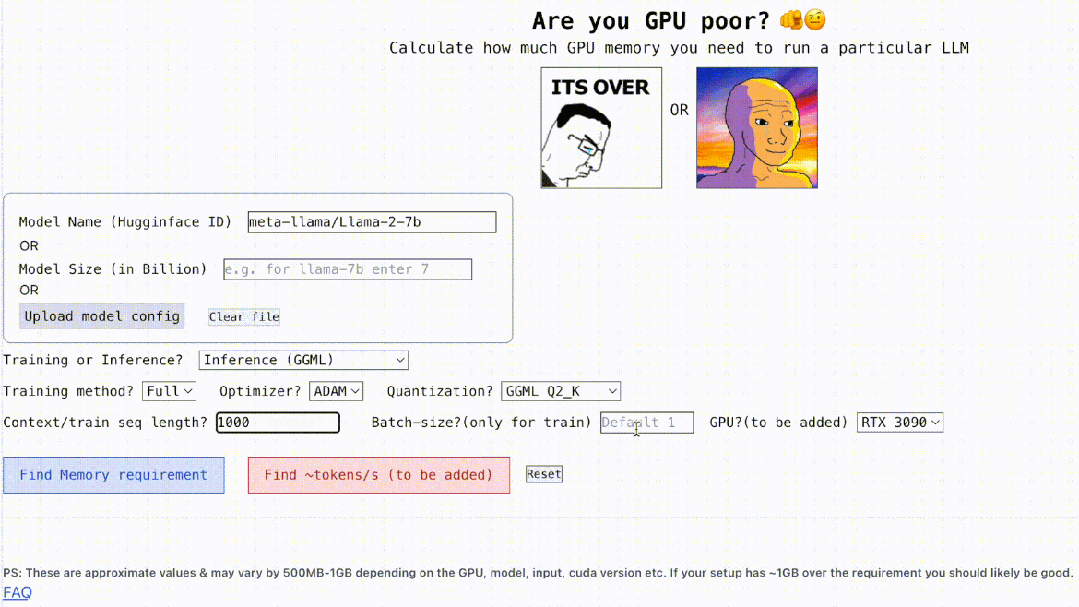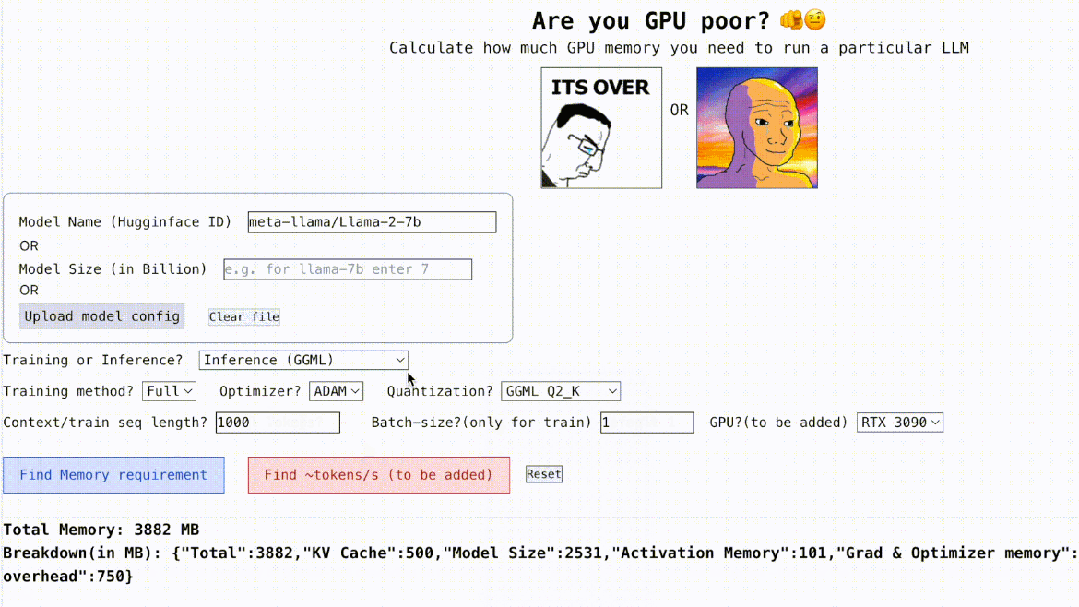
How To Run LLMs On Your RTX PC - Part 1 (Hugging Face) - NUA Dev
How to Get Started with Merlinite 7b - GGUF 4-bit Quantized Version fxis.ai
Run 70B LLMs on Consumer GPU - VRAM and Quantization Guide (2026)
Advertisement Space (336x280)
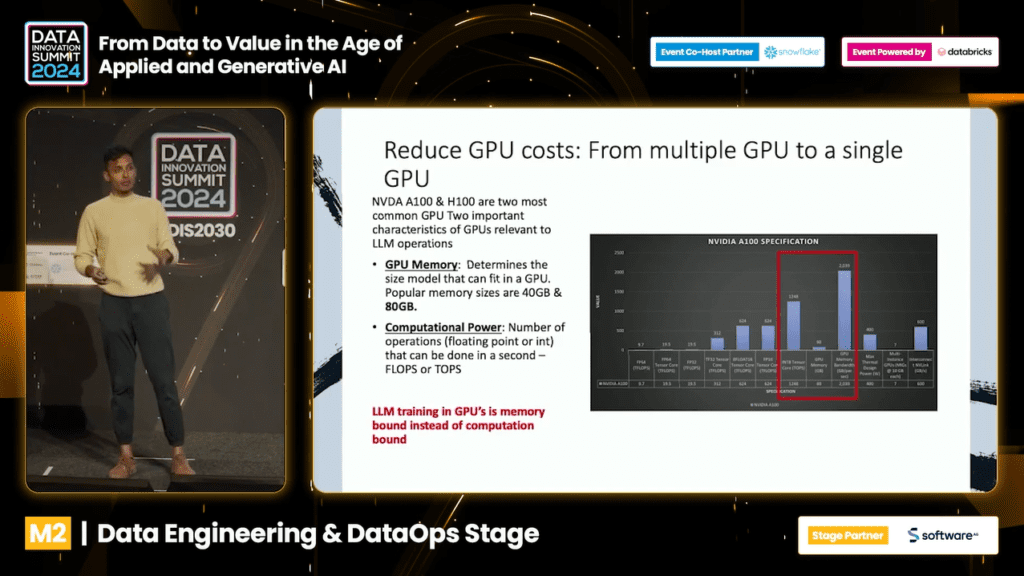
Large Language Models: How to Run LLMs on a Single GPU - hyperight.com

Unbelievable! Run 70B LLM Inference on a Single 4GB GPU with This NEW ...
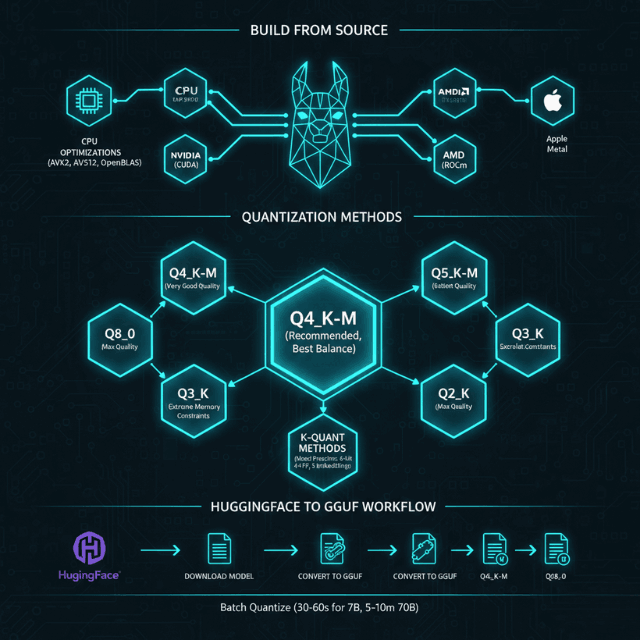
Run 70B LLMs on Consumer GPU - VRAM and Quantization Guide (2026)

Meet GGUF Loader: Run Local LLMs with Zero Hassle - DEV Community

RUN LLMs on CPU x4 the speed (No GPU Needed) - YouTube

easily run LLMs on your laptop... really cool | Dinis Cruz