
Humaneval A Benchmark For Evaluating Llm Code Generation Capabilities
HumanEval: A Benchmark for Evaluating LLM Code Generation Capabilities ...
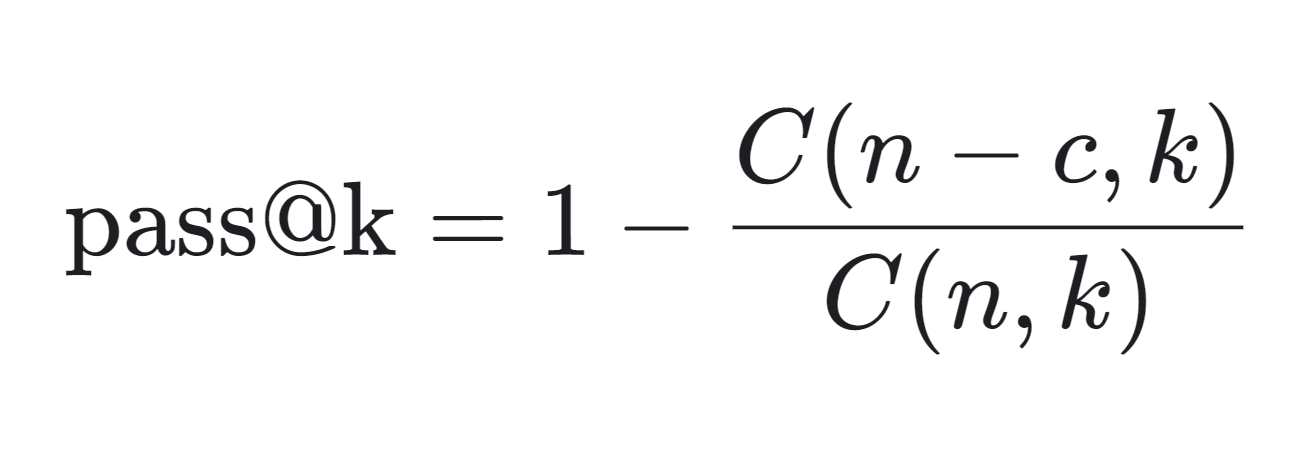
HumanEval: A Benchmark for Evaluating LLM Code Generation Capabilities ...

HumanEval - The Most Inhuman Benchmark For LLM Code Generation - DEV ...

HumanEval - The Most Inhuman Benchmark For LLM Code Generation - DEV ...

(PDF) Tests as Prompt: A Test-Driven-Development Benchmark for LLM Code ...
HumanEval Benchmark: Evaluating LLM Code Generation Capability

A new promising benchmark for code generation models : r/llm_updated

[논문 리뷰] KG-LLM-Bench: A Scalable Benchmark for Evaluating LLM Reasoning ...
HumanEval-XL: A Multilingual Code Generation Benchmark for Cross ...
Evaluating LLM Accuracy with lm-evaluation-harness for local server: A ...
Advertisement Space (300x250)
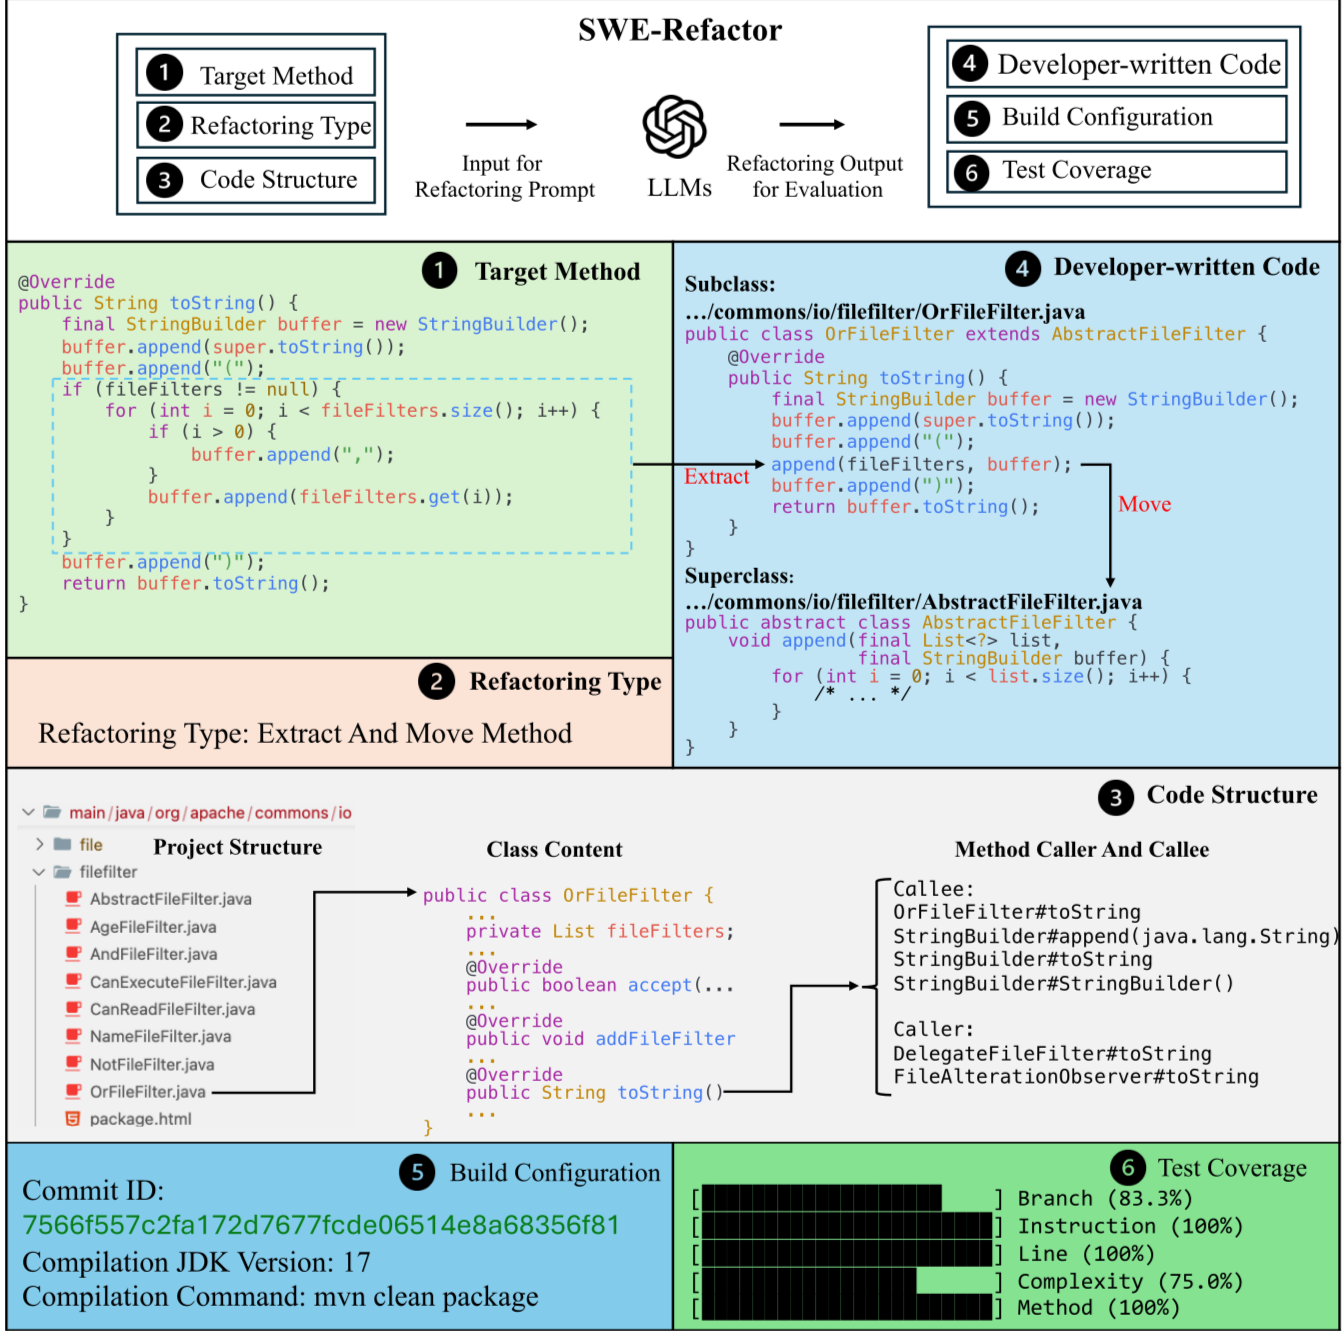
[논문 리뷰] SWE-Refactor: A Repository-Level Benchmark for Real-World LLM ...

Benchmark Agreement Testing Done Right: A Guide for LLM Benchmark ...

WTU-Eval: A New Standard Benchmark Tool for Evaluating Large Language ...

WTU-Eval: A New Standard Benchmark Tool for Evaluating Large Language ...

[论文评述] An evaluation of LLM code generation capabilities through graded ...

[논문 리뷰] Web-Bench: A LLM Code Benchmark Based on Web Standards and ...
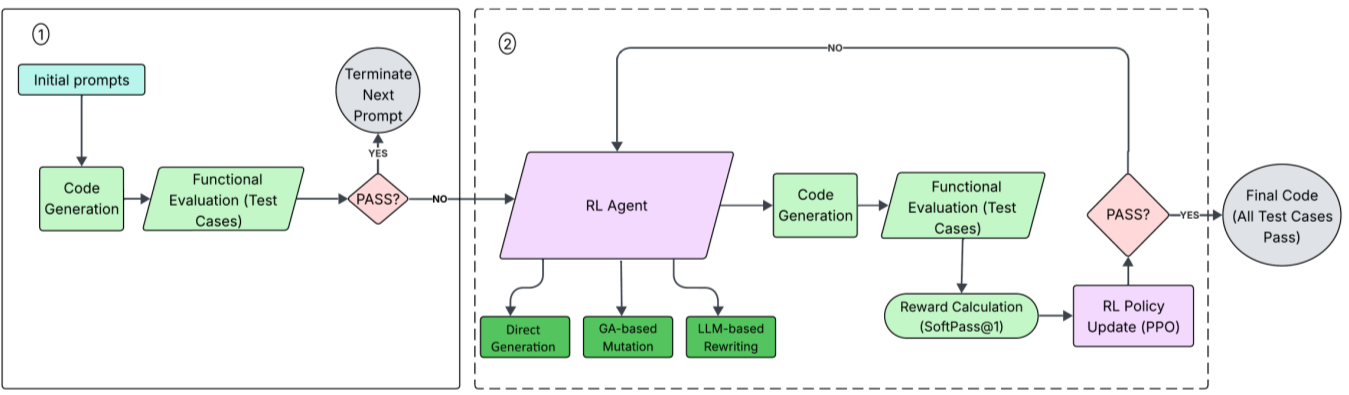
[論文レビュー] Prompt Optimization for LLM Code Generation via Reinforcement ...
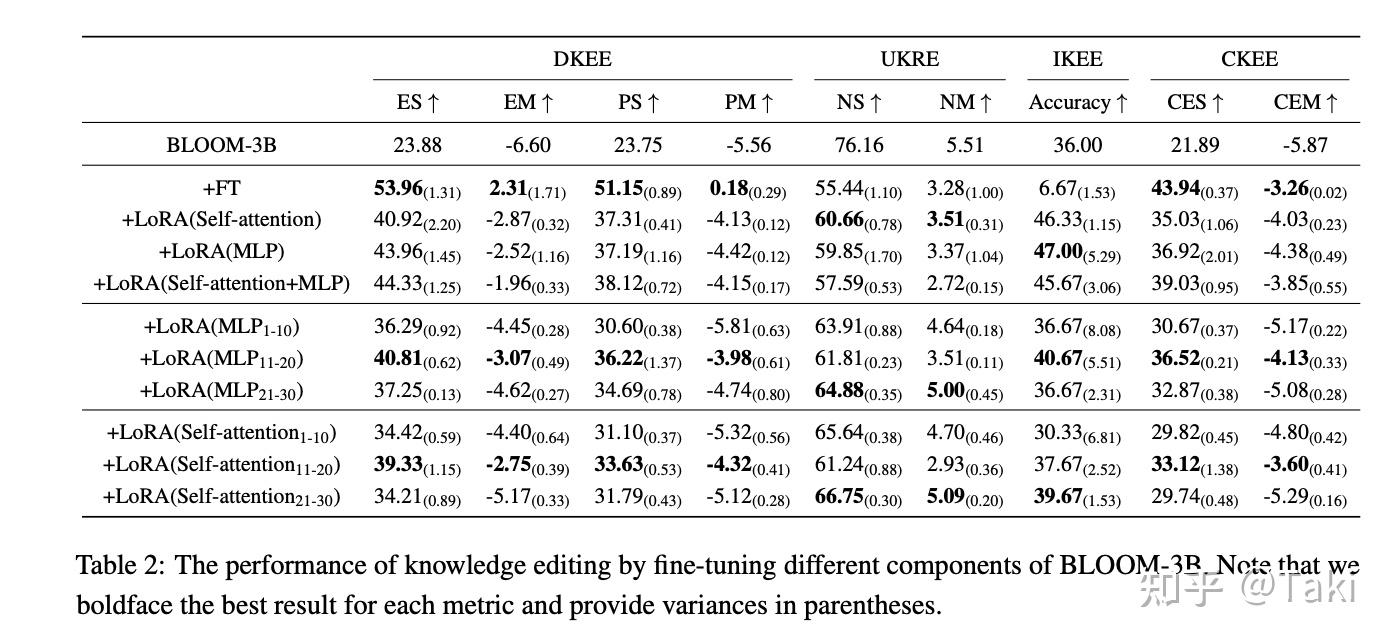
Eva-KELLM: A New Benchmark for Evaluating Knowledge Editing of LLMs - 知乎

How to Perform Code Generation with LLM Models - Novita
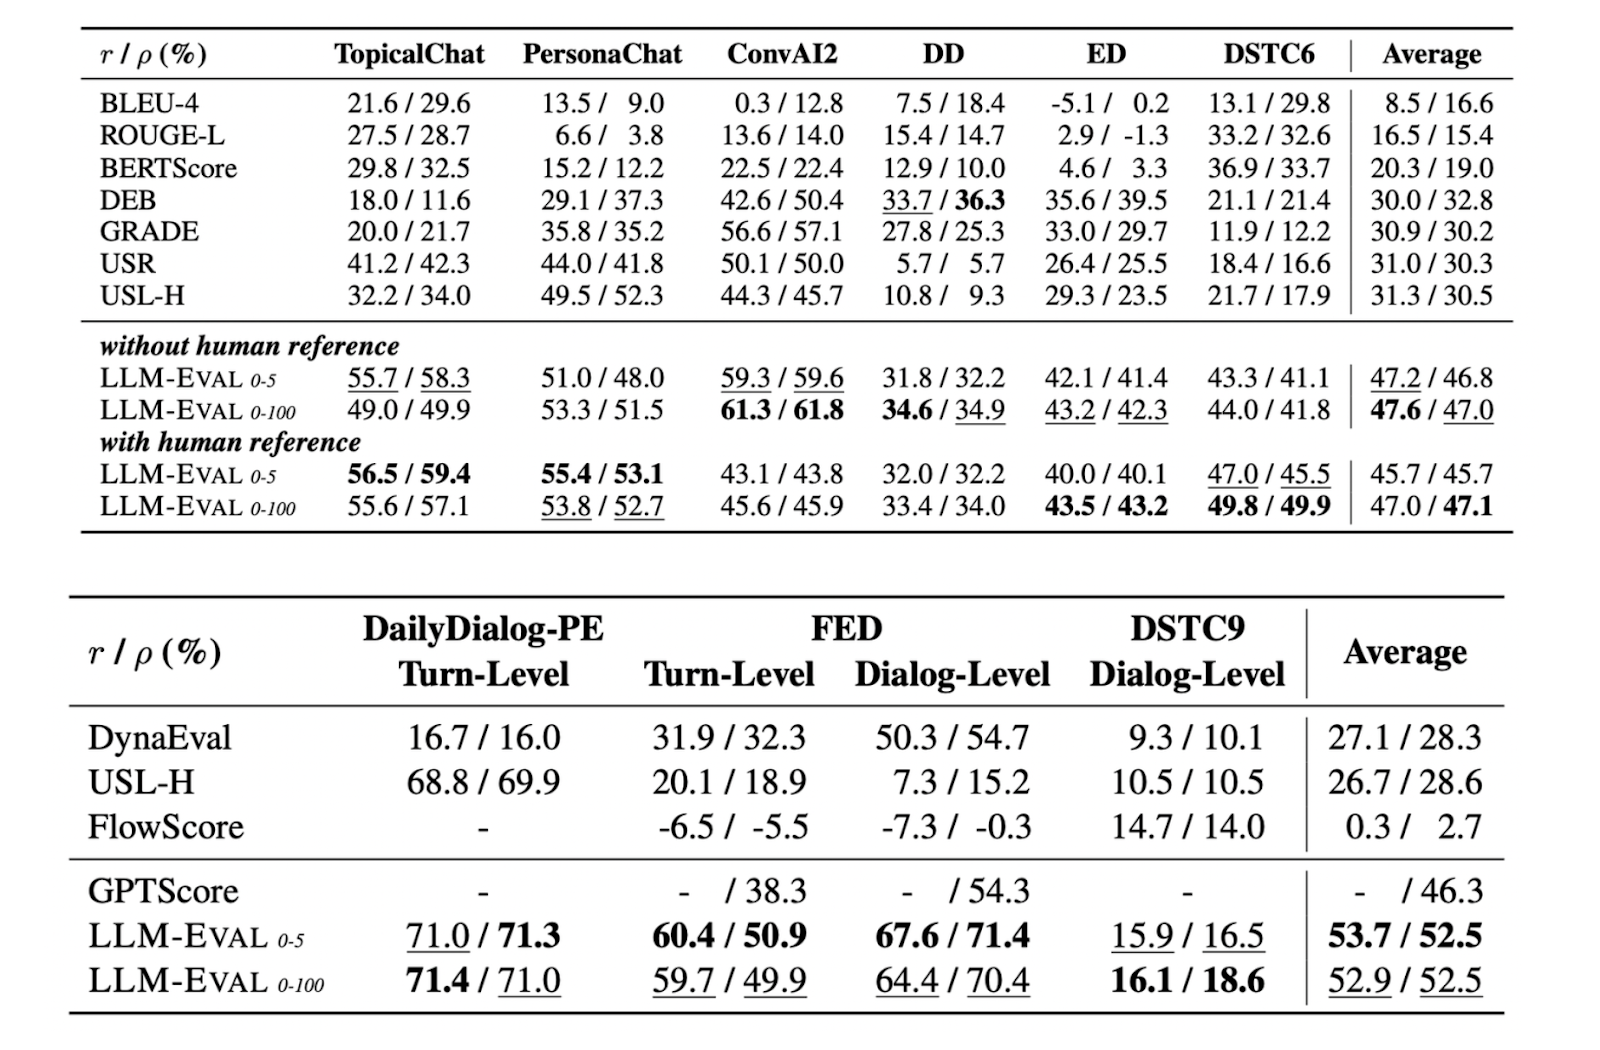
LLM-Eval: A Simplified Approach to Evaluating LLM Conversations ...
Advertisement Space (336x280)

LLM Code Generation: Evaluating Boundary Examples | Kelvin Meeks posted ...

Improving LLM Code Generation with Grammar Augmentation
HumanEval and Code Benchmarks: How to Test LLM Programming Ability in 2026
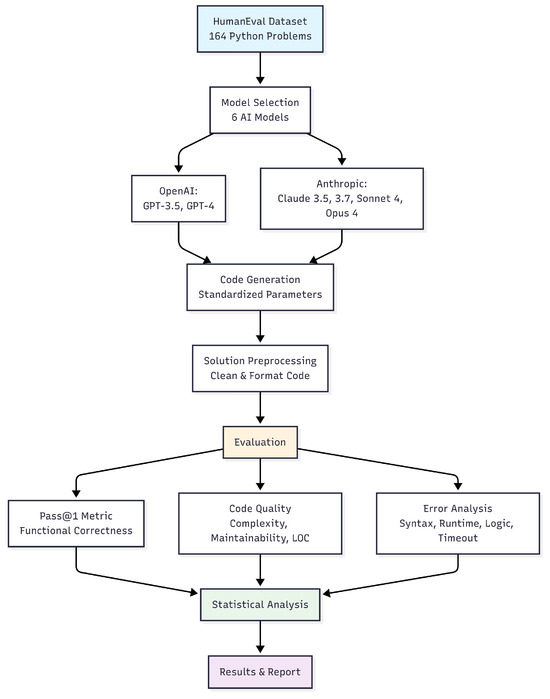
Comparative Analysis of AI Models for Python Code Generation: A ...

Evaluate LLM code generation with LLM-as-judge evaluators - DEV Community
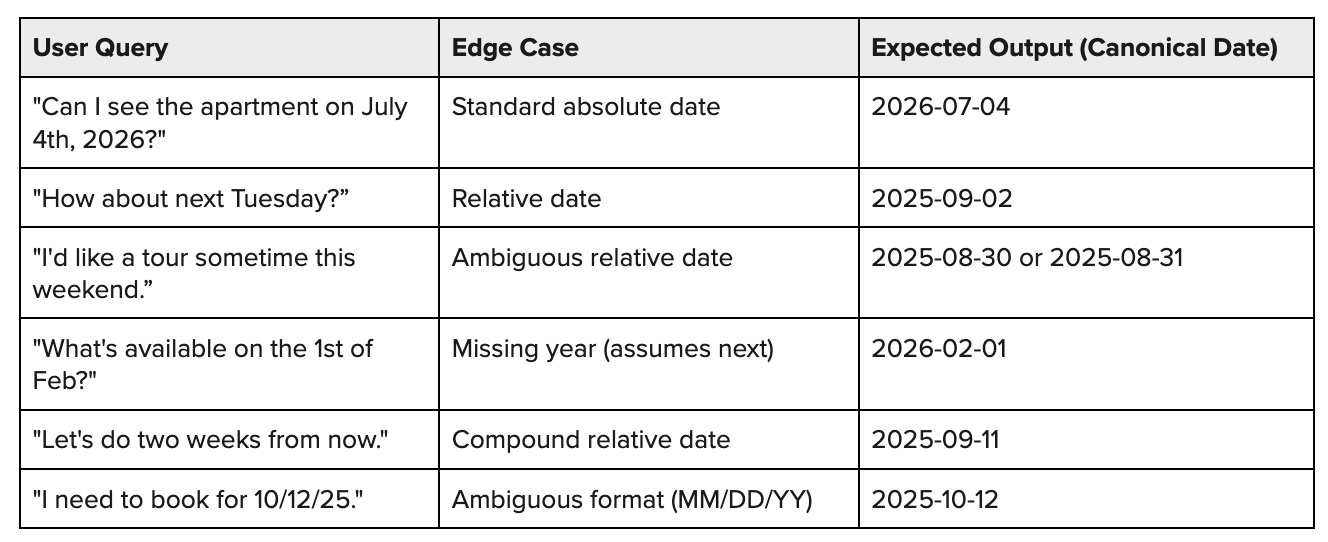
A pragmatic guide to LLM evals for devs
HumanEval and Code Benchmarks: Testing LLM Programming Ability

Evaluating LLM Performance - Best Generative AI & Machine Learning ...
GitHub - brandaobrandisborges/openai-human-eval: Code for the paper ...
LLM Comparison Through TGI Benchmark Using SaladCloud - SaladCloud Blog
Advertisement Space (336x280)

Evaluating LLM-Based Test Generation Under Software Evolution
G-Eval for LLM Evaluation
Human LLM Evaluation 2026: Practical Guide for AI Teams
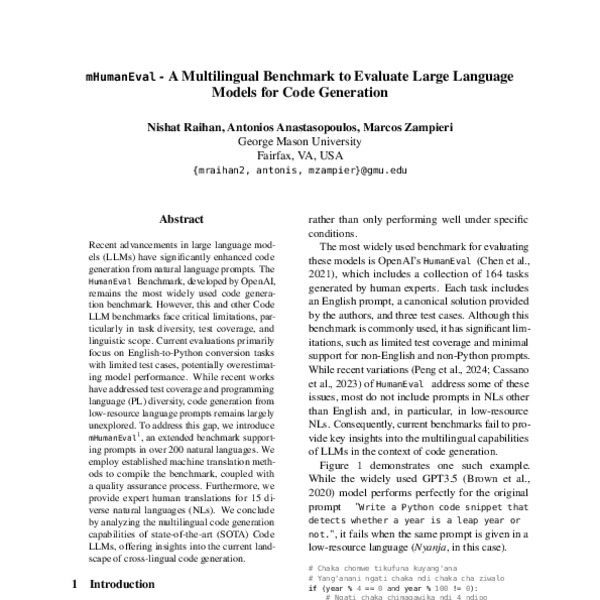
mHumanEval - A Multilingual Benchmark to Evaluate Large Language Models ...

(PDF) Re-Evaluating Code LLM Benchmarks Under Semantic Mutation

HumanEval Pro and MBPP Pro: Evaluating Large Language Models on Self ...