
Inferencing Llms At Scale With Kubernetes And Vllm By Welzin

Inferencing LLMs at Scale with Kubernetes and vLLM | by Welzin ...
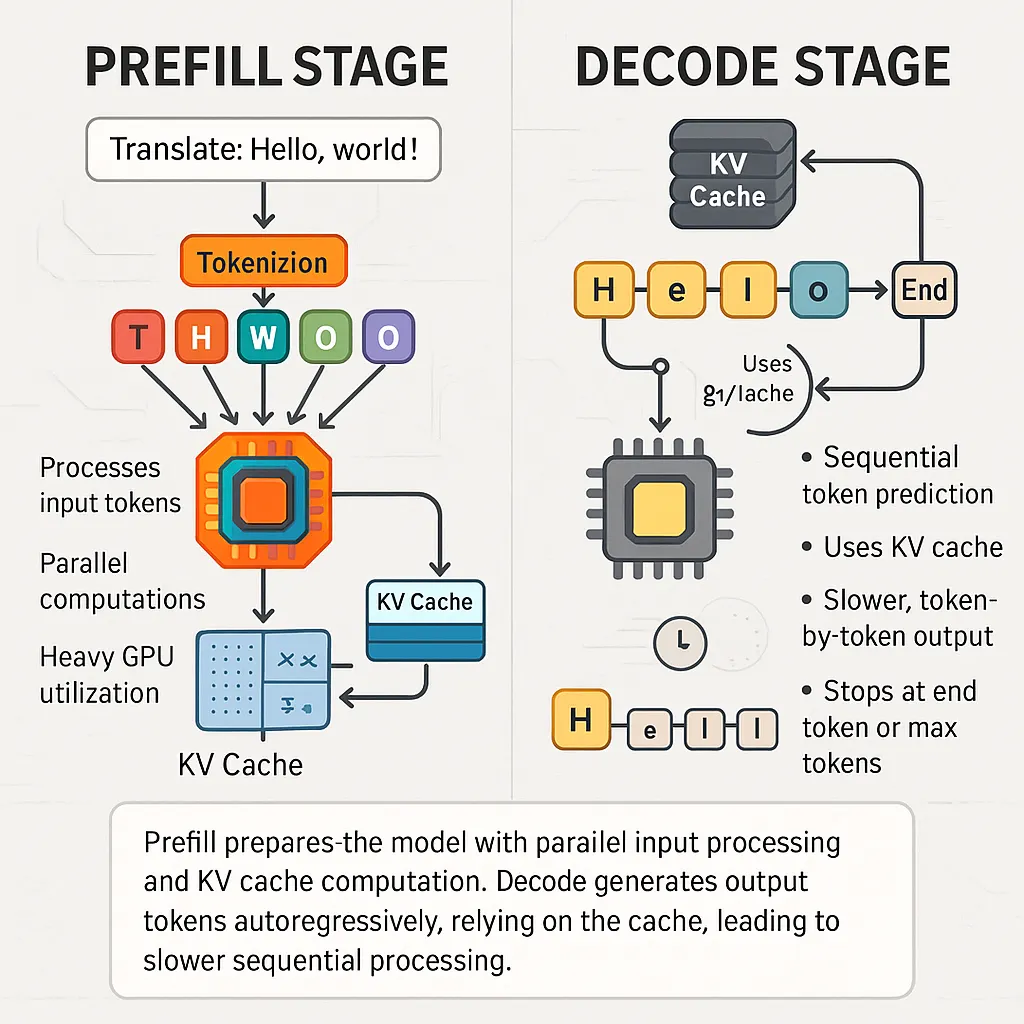
Inferencing LLMs at Scale with Kubernetes and vLLM | by Welzin ...

Optimizing LLM Inference with Kubernetes and vLLM | by EzgiTastan | Medium
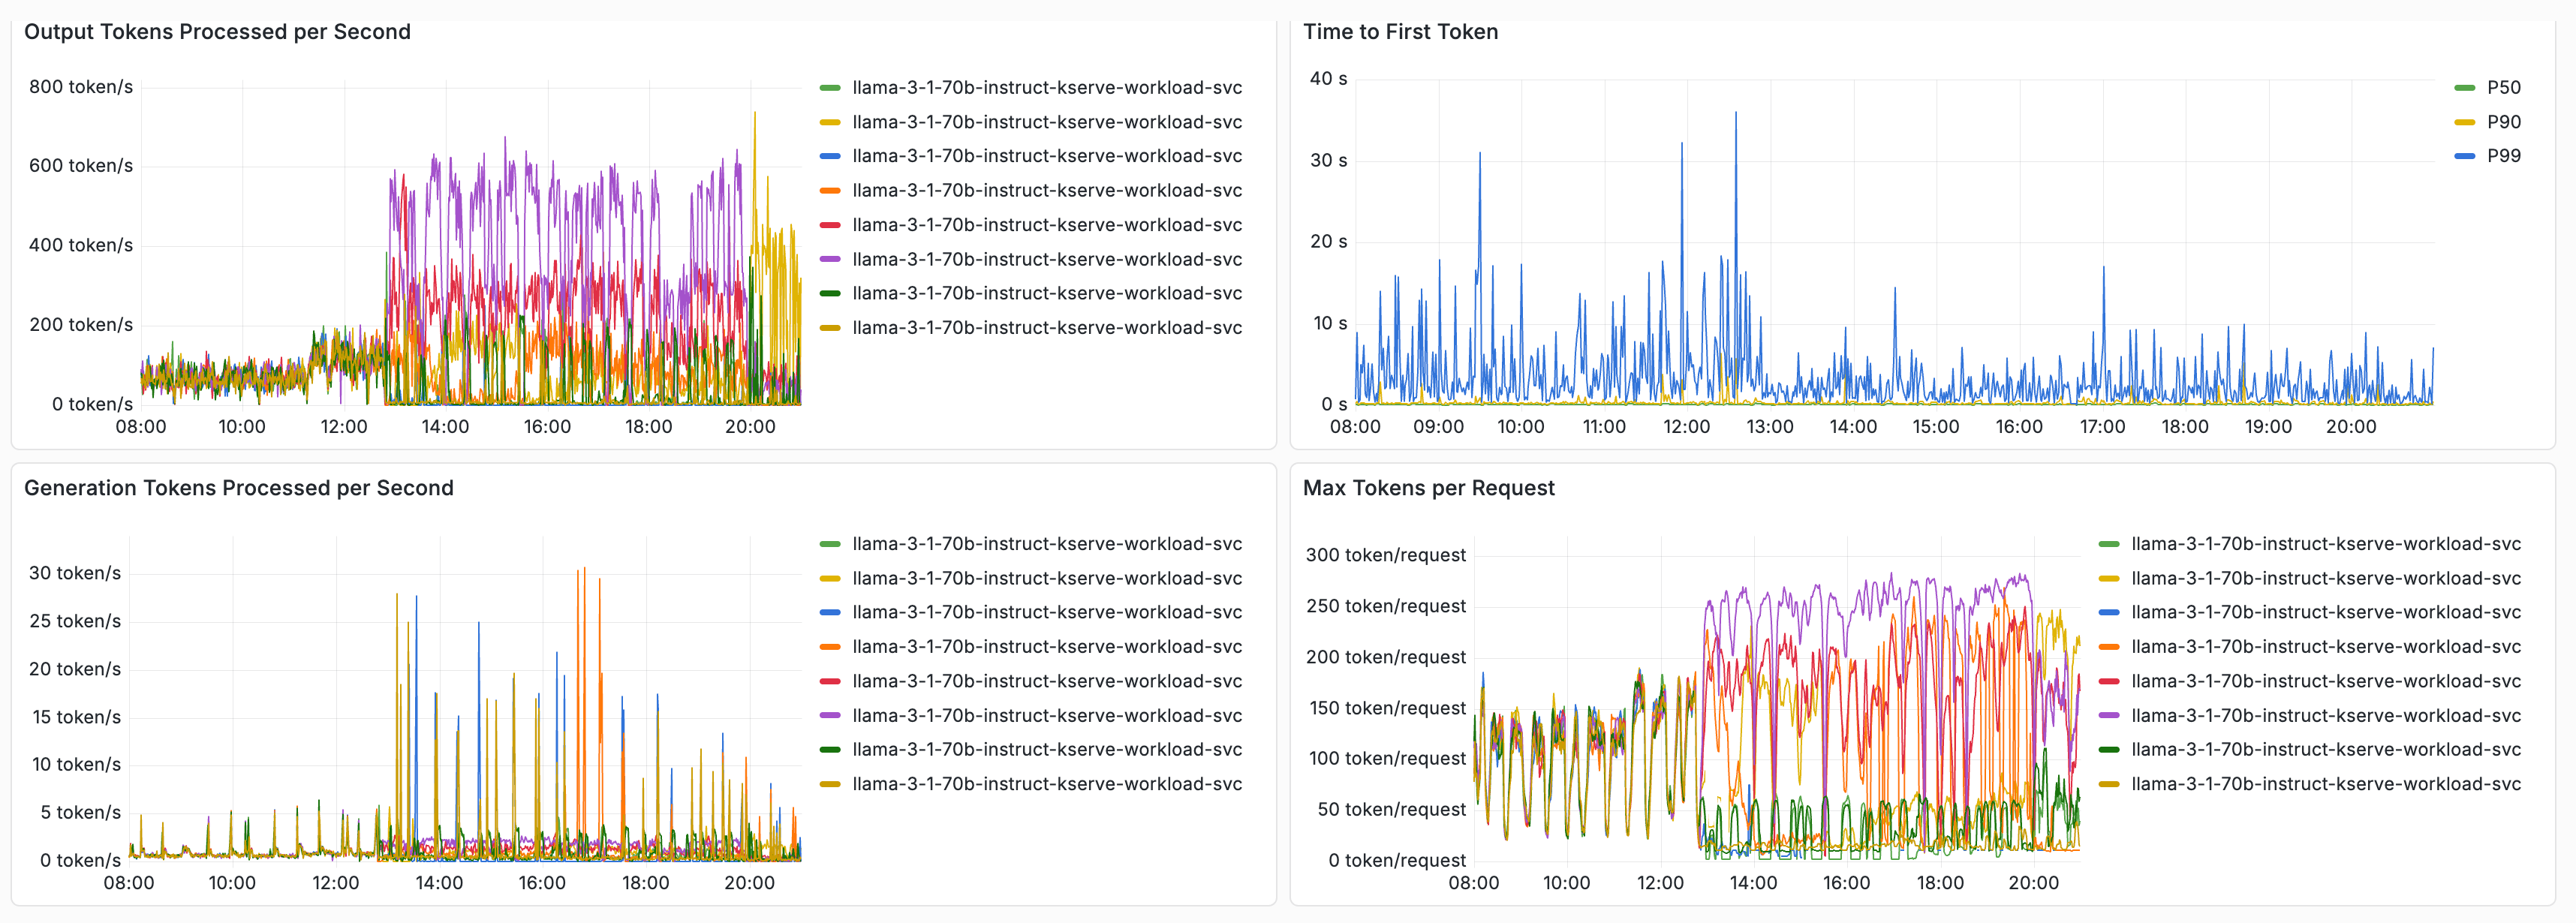
Production-Grade LLM Inference at Scale with KServe, llm-d, and vLLM ...

Optimizing LLM Inference with Kubernetes and vLLM | by EzgiTastan | Medium
Scale Open LLMs with vLLM Production Stack | by Shahrukh khan | Medium
High-Performance LLM Infrastructure with Kubernetes and vLLM on Private ...

Kubernetes for Generative AI: Deploy LLMs at Scale
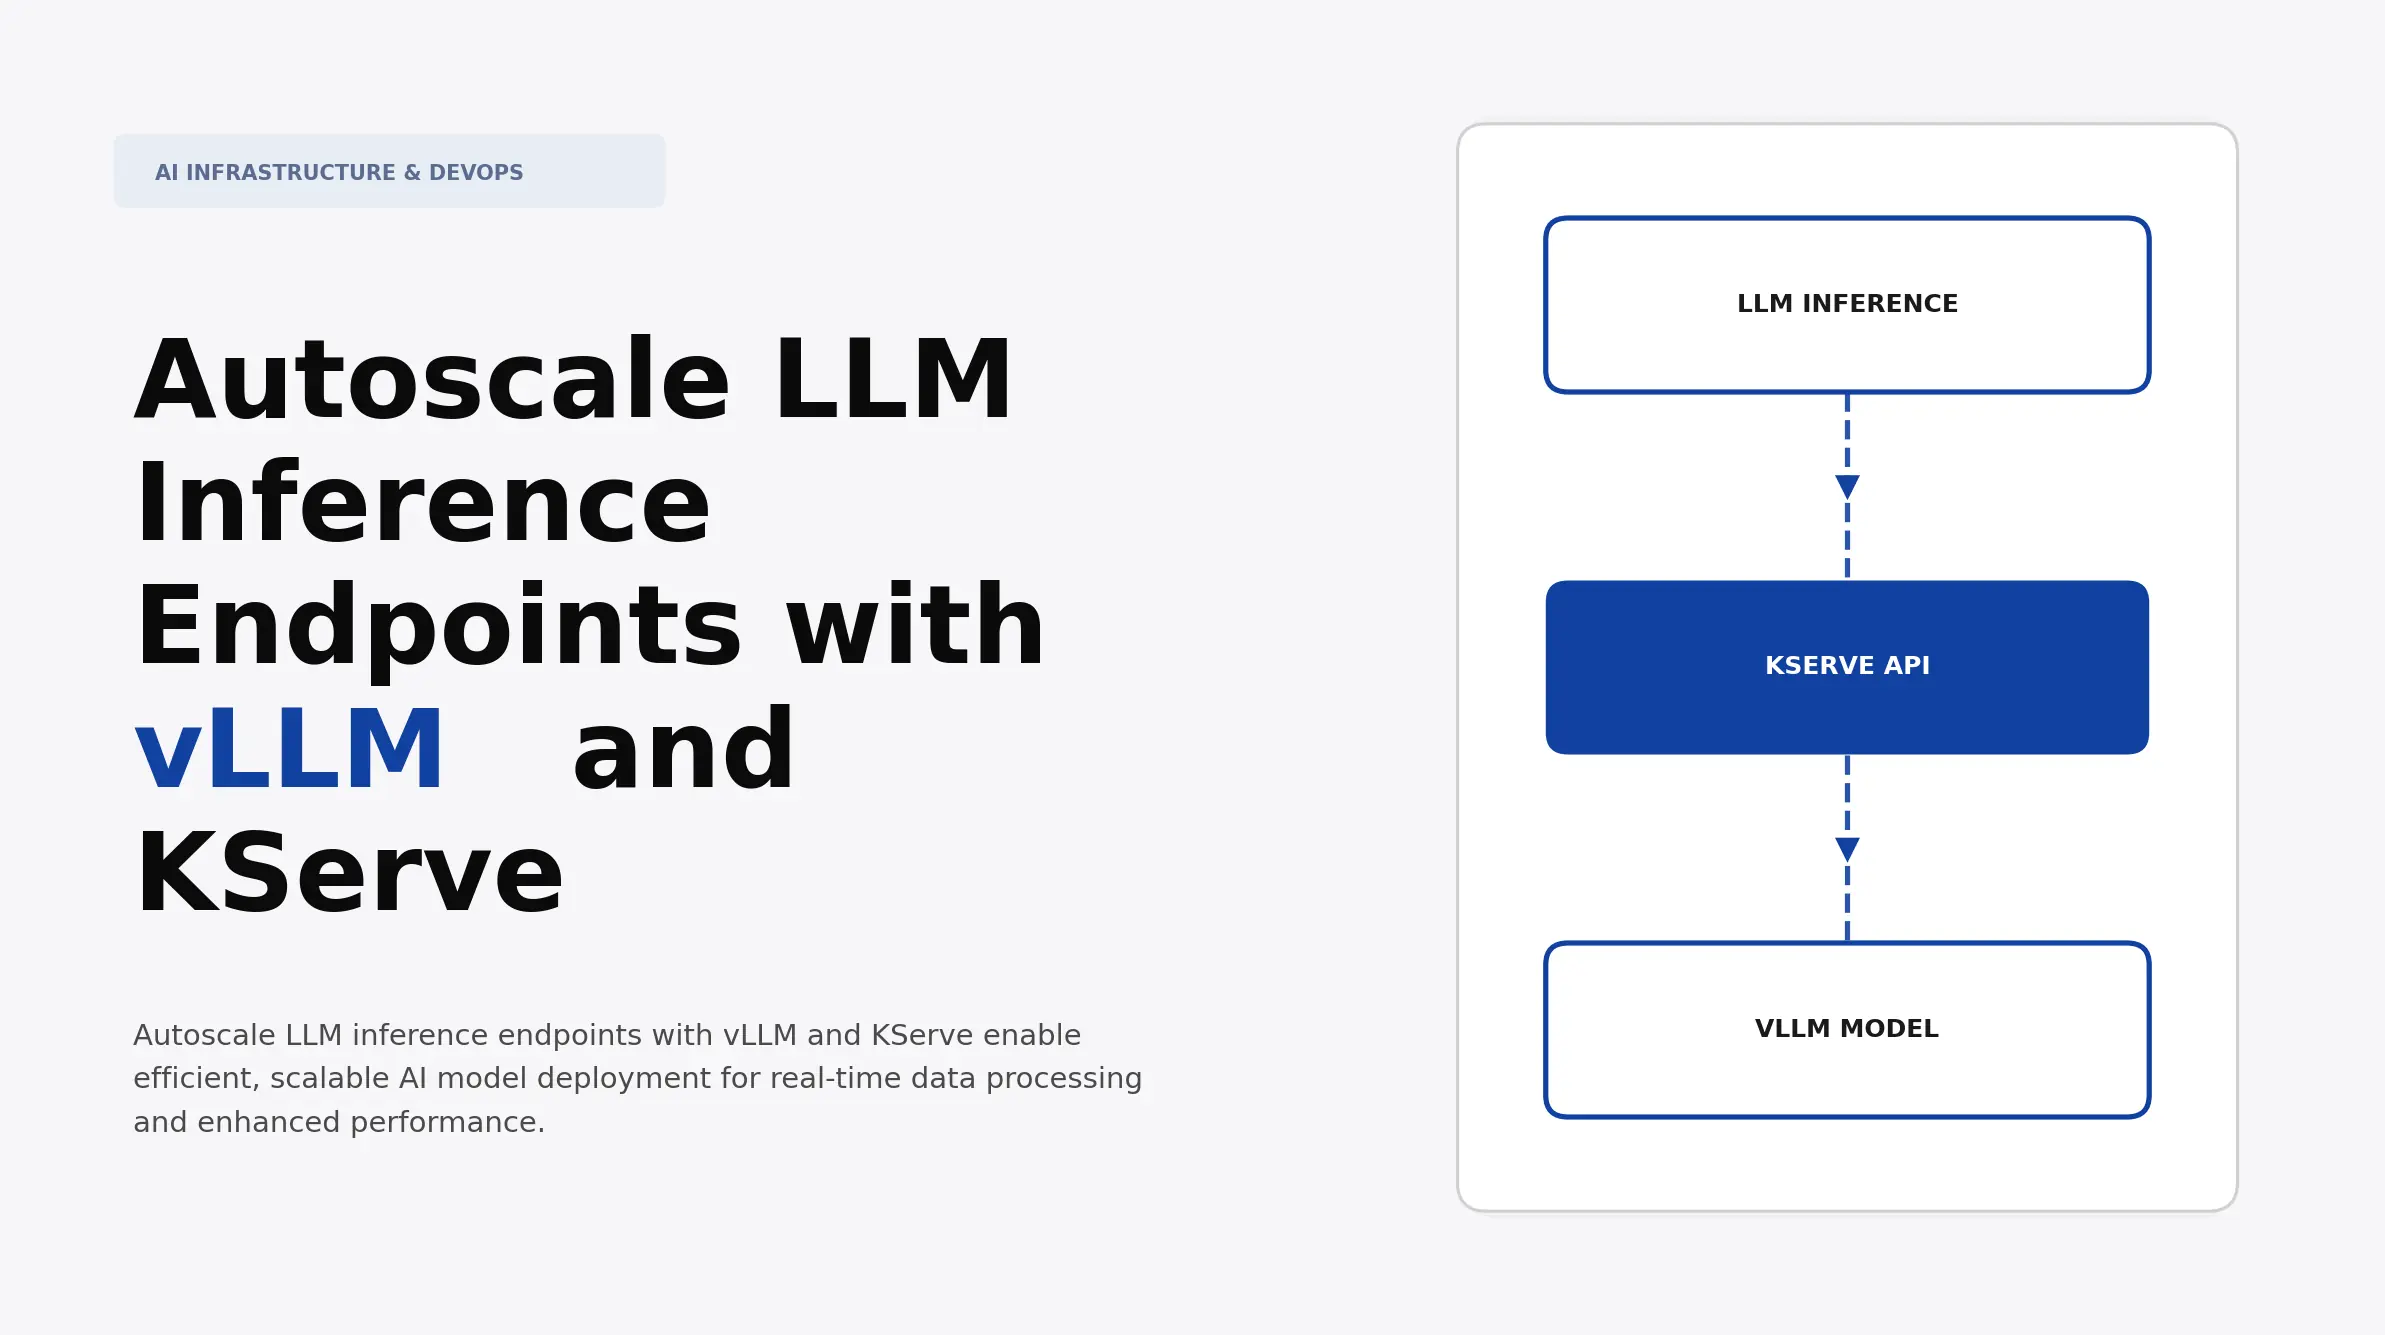
Autoscale LLM Inference Endpoints with vLLM and KServe | Atomic Loops

Scaling LLM Inference on GKE: Serving with vLLM or llm-d | by Don ...
Advertisement Space (300x250)
stackconf 2026: Combining Kubernetes and vLLM to Deliver Scalable ...
Monitor LLM Routing with the Kubernetes Inference Extension and Datadog

Enterprise-Ready LLM Inferencing with the vLLM Production Stack on Dell ...
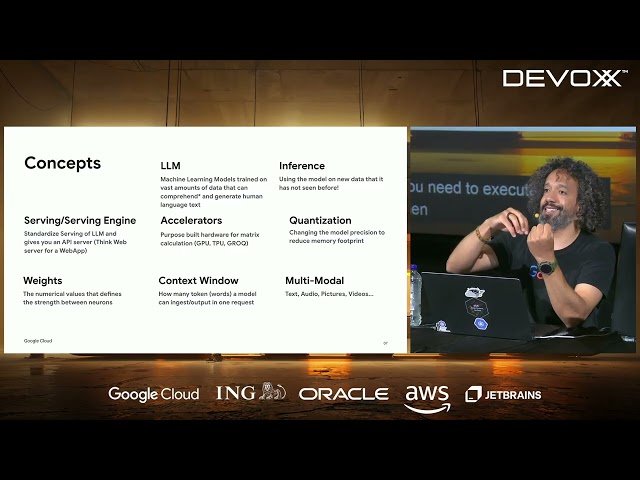
Free Video: Large Scale Distributed LLM Inference with LLM-D and ...

A Brief Introduction to Optimized Batched Inference with vLLM | by ...
vLLM: Deploying LLMs at Scale Like OpenAI

Combining Kubernetes and vLLM to Deliver Scalable, Distributed ...

vLLM Explained: How PagedAttention Makes LLMs Faster and Cheaper - DEV ...

Open‑Source LLM Inferencing at Scale: vLLM Production Stack on Dell AI ...
Efficient LLM Inference and Serving with vLLM
Advertisement Space (336x280)

vLLM: Deploying LLMs at Scale - Fractal Analytics
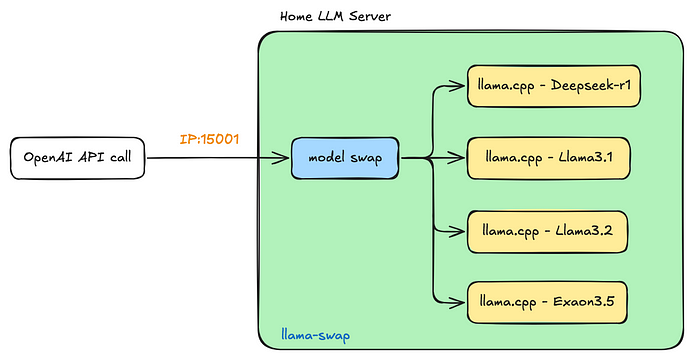
Deploy Large Language Model (LLM) with vLLM on K8s | by FiftyFive ...

Model Routing | Open‑Source LLM Inferencing at Scale: vLLM Production ...

High Availability | Open‑Source LLM Inferencing at Scale: vLLM ...

Core Components | Open‑Source LLM Inferencing at Scale: vLLM Production ...

Performance Optimization | Open‑Source LLM Inferencing at Scale: vLLM ...
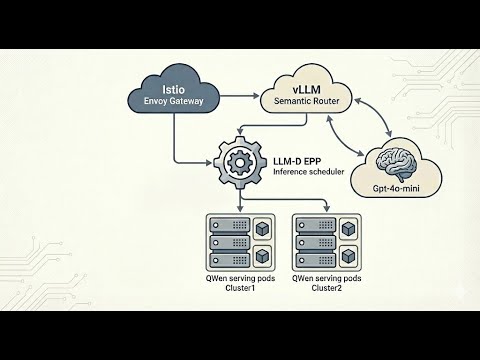
Intelligent LLM inferencing via vLLM Semantic Router, LLM-D with local ...

Getting Started with vLLM: Fast and Efficient LLM Inference | by Wenyi ...

System-level Architecture | Open‑Source LLM Inferencing at Scale: vLLM ...

Architecture | Open‑Source LLM Inferencing at Scale: vLLM Production ...
Advertisement Space (336x280)

Model Verification | Open‑Source LLM Inferencing at Scale: vLLM ...
Scaling LLMs with NVIDIA Triton and NVIDIA TensorRT-LLM Using ...

Deploy Large Language Model (LLM) with vLLM on K8s | by FiftyFive ...

Run LLMs at Scale - Self-Hosted AI Infrastructure - Cast AI
vLLM - High-throughput LLM inference engine with PagedAttention ... at ...
stackconf 2026: Combining Kubernetes and vLLM to Deliver Scalable ...