
Is It Possible To Run Multiple Tensorrt Model Inference On A Gpu

Is it possible to run multiple TensorRT model inference on a GPU ...

TensorRT model inference fully on DLA is slow due to abnormally slow ...

TensorRT is a C++ inference framework that can run on various NVIDIA ...

Model inference on multiple cuda streams with tensorrt api - Jetson AGX ...

Model inference on multiple cuda streams with tensorrt api - Jetson AGX ...

Model inference on multiple cuda streams with tensorrt api - Jetson AGX ...
How to run multiple TensorRT model in one inference? · Issue #1688 ...

Model inference on multiple cuda streams with tensorrt api - Jetson AGX ...

Model inference on multiple cuda streams with tensorrt api - Jetson AGX ...

Model inference on multiple cuda streams with tensorrt api - Jetson AGX ...
Advertisement Space (300x250)

scoring - Running Tensorflow model inference script on multiple GPU ...

Model inference on multiple cuda streams with tensorrt api - #2 by zhi ...

Model inference on multiple cuda streams with tensorrt api - Jetson AGX ...

High GPU usage during simple model inference on Tensorrt - TensorRT ...

NVIDIA TensorRT 4 to Boost GPU Inference - Engineering.com
How to perform multiple trt inferences on one GPU at the same time ...

Leadtek AI Forum - How to accelerate AI model Inference on GPU:A Hands ...
TensorRT GPU inference to support multi-model inference needs to push ...

Leadtek AI Forum - How to accelerate AI model Inference on GPU:A Hands ...
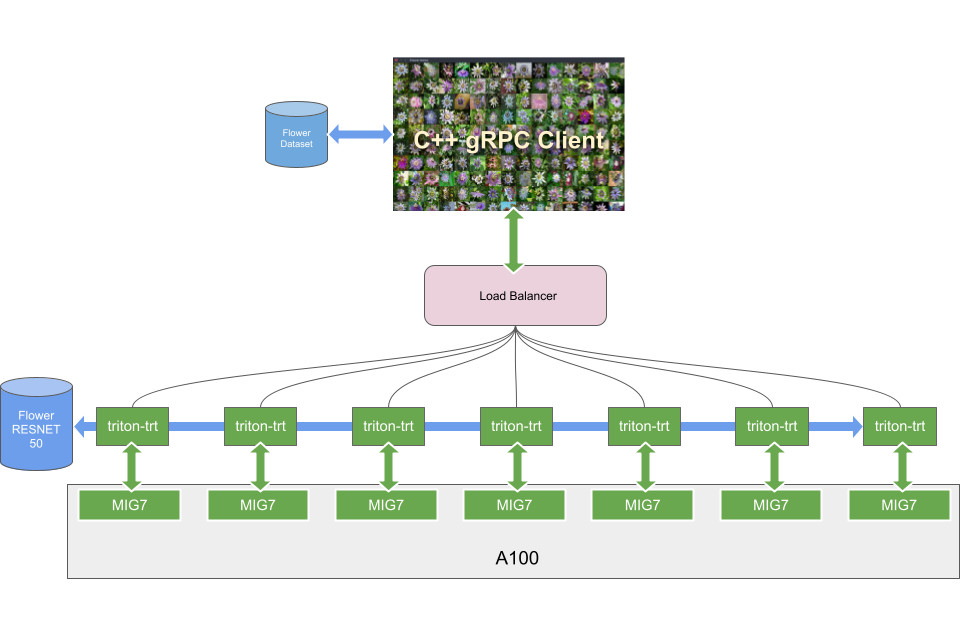
ISC20 Featured Demo: Running Multiple Workloads on a Single A100 GPU ...
Advertisement Space (336x280)

Leadtek AI Forum - How to accelerate AI model Inference on GPU:A Hands ...

How convert pytorch model that have mutiple parallel inputs to tensorrt ...

Running 2 models on the same GPU with TensorRT - TensorRT - NVIDIA ...

NVIDIA TensorRT for RTX Introduces an Optimized Inference AI Library on ...

NVIDIA AI Revolutionizes Inference: TensorRT Model Optimizer for GPU ...
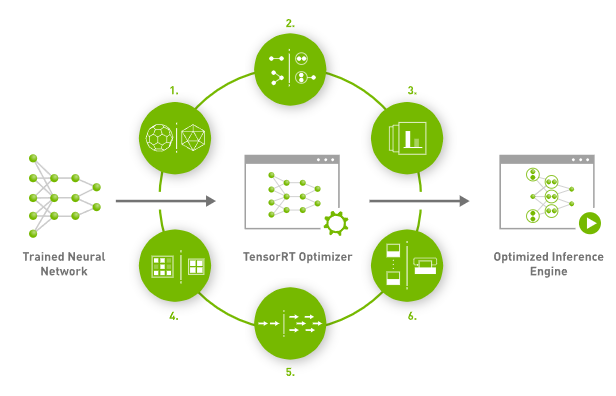
Faster YOLOv5 inference with TensorRT, Run YOLOv5 at 27 FPS on Jetson ...
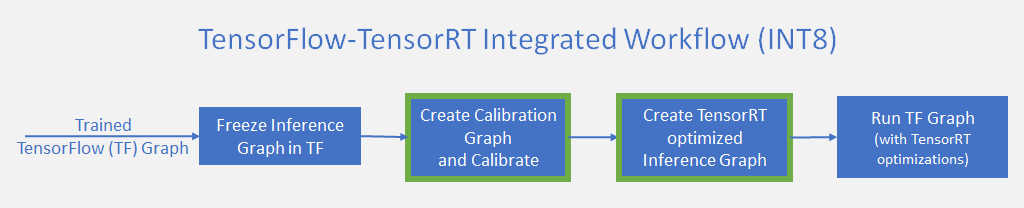
Speed up TensorFlow Inference on GPUs with TensorRT — The TensorFlow Blog

YOLO Model Optimization: Achieving 2x Faster Inference on Jetson Orin ...
Boost inference speeds with NVIDIA TensorRT on UbiOps - UbiOps - AI ...

NVIDIA TensorRT for RTX: Optimized AI Inference Now on Windows 11
Advertisement Space (336x280)
The issue of GPU usage in tensorrt dla inference models · Issue #2711 ...
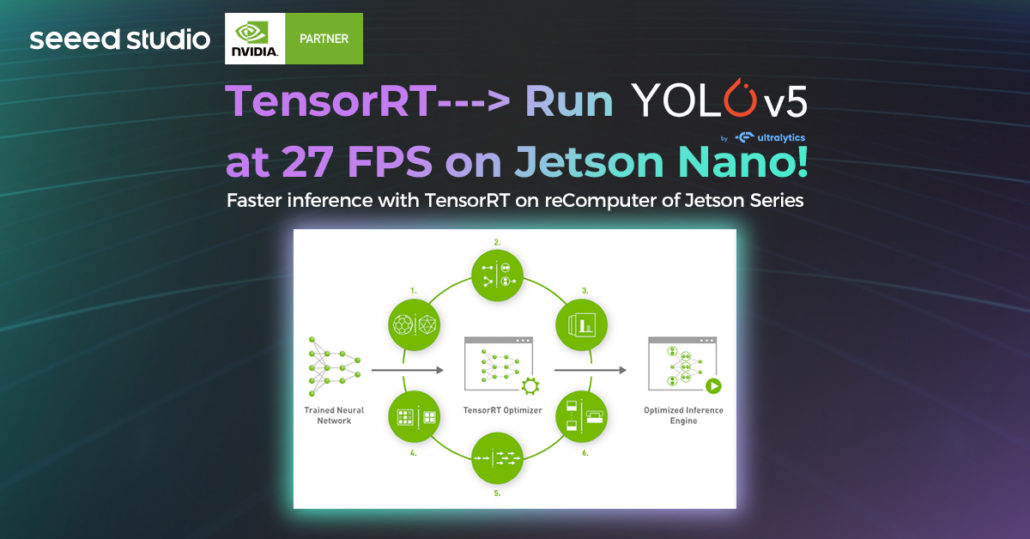
Faster YOLOv5 inference with TensorRT, Run YOLOv5 at 27 FPS on Jetson ...
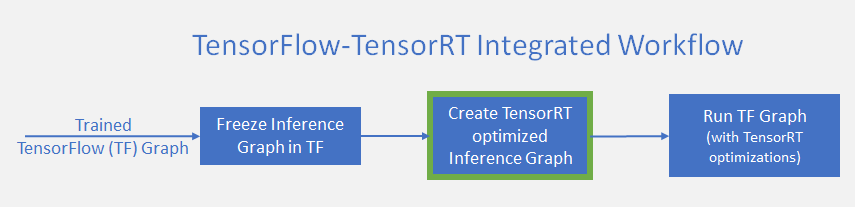
Speed up TensorFlow Inference on GPUs with TensorRT — The TensorFlow Blog
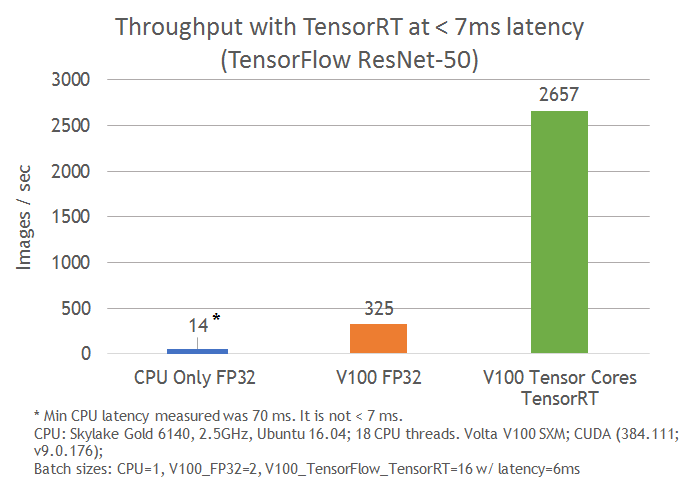
Speed up TensorFlow Inference on GPUs with TensorRT — The TensorFlow Blog

NVIDIA TensorRT-LLM Supercharges Large Language Model Inference on ...
New TensorRT model occupying more GPU-Memory as compared to the older ...