
Model Inference On Multiple Cuda Streams With Tensorrt Api Jetson Agx

Model inference on multiple cuda streams with tensorrt api - Jetson AGX ...

Model inference on multiple cuda streams with tensorrt api - Jetson AGX ...

Model inference on multiple cuda streams with tensorrt api - Jetson AGX ...

Model inference on multiple cuda streams with tensorrt api - Jetson AGX ...

Model inference on multiple cuda streams with tensorrt api - Jetson AGX ...

Model inference on multiple cuda streams with tensorrt api - #2 by zhi ...

Model inference on multiple cuda streams with tensorrt api - #2 by zhi ...

Model inference on multiple cuda streams with tensorrt api - #4 by zhi ...

No speed up in inference on jetson agx with tensorflow 2 and tensorRT ...
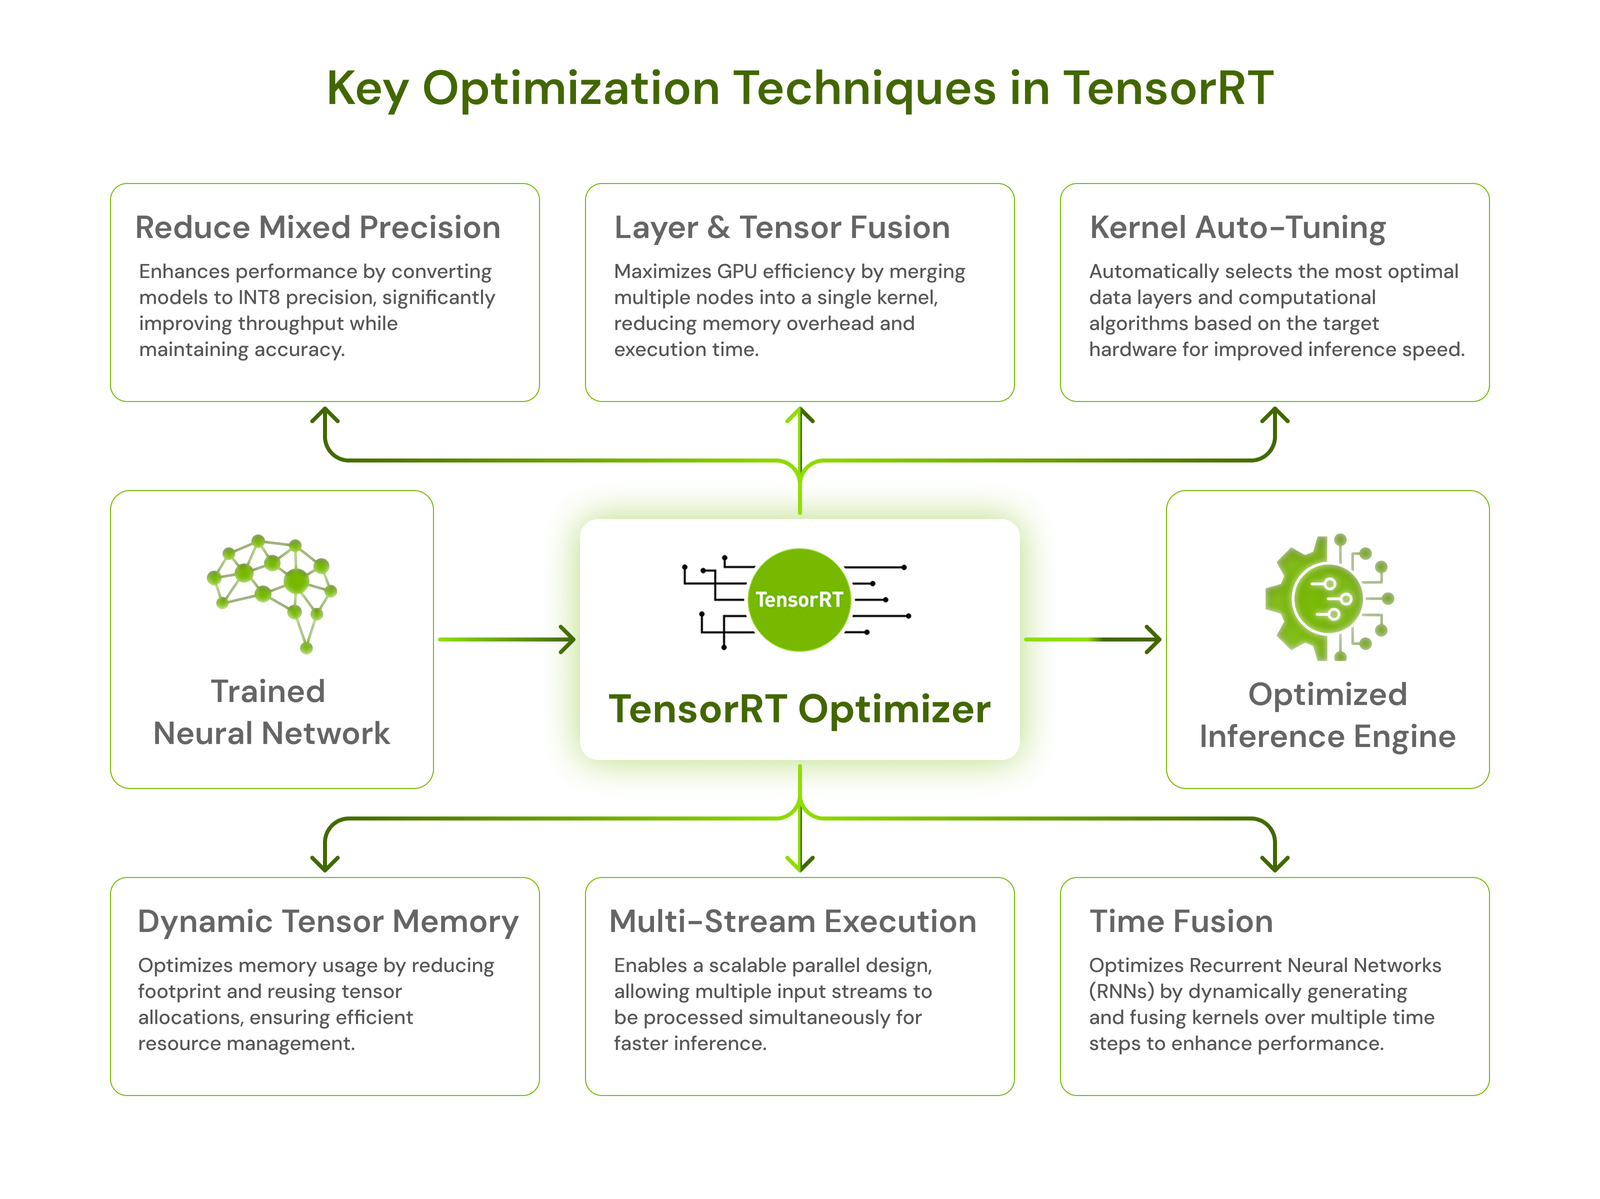
How to optimize inference using TensorRT on Jetson AGX Orin
Advertisement Space (300x250)
How to optimize inference using TensorRT on Jetson AGX Orin

TensorRT ( C++ ) inference strange behavior on Jetson AGX Xavier ...

Is it possible to run multiple TensorRT model inference on a GPU ...

Slow inference using CUDA and PyTorch on Jetson AGX - CUDA Programming ...

High RAM consumption with CUDA and TensorRT on Jetson Xavier NX ...

YOLO Model Optimization: Achieving 2x Faster Inference on Jetson Orin ...

YOLO Model Optimization: Achieving 2x Faster Inference on Jetson Orin ...

TensorRT model inference fully on DLA is slow due to abnormally slow ...

TensorRT model inference fully on DLA is slow due to abnormally slow ...
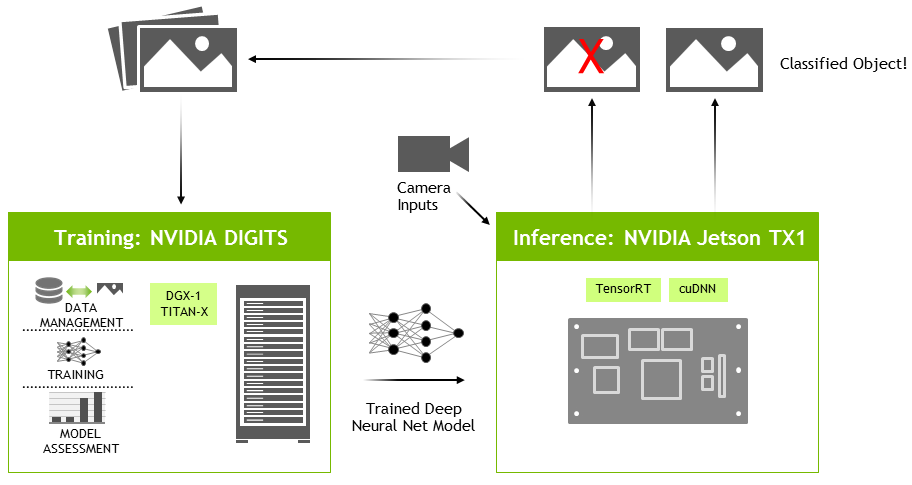
JetPack 2.3 with TensorRT Doubles Jetson TX1 Deep Learning Inference ...
Advertisement Space (336x280)

YOLO Model Optimization: Achieving 2x Faster Inference on Jetson Orin ...

YOLO Model Optimization: Achieving 2x Faster Inference on Jetson Orin ...

YOLO Model Optimization: Achieving 2x Faster Inference on Jetson Orin ...

TensorRT 5 Python API for Jetson AGX Xavier? - Jetson AGX Xavier ...
Using TensorRT with ONNX Models in Jetson Inference - Help Docs for ...

TensorRT Small Model High RAM Consumption During Inference on Nvidia ...

How to convert a trained model to TensorRT for inference? - Jetson AGX ...
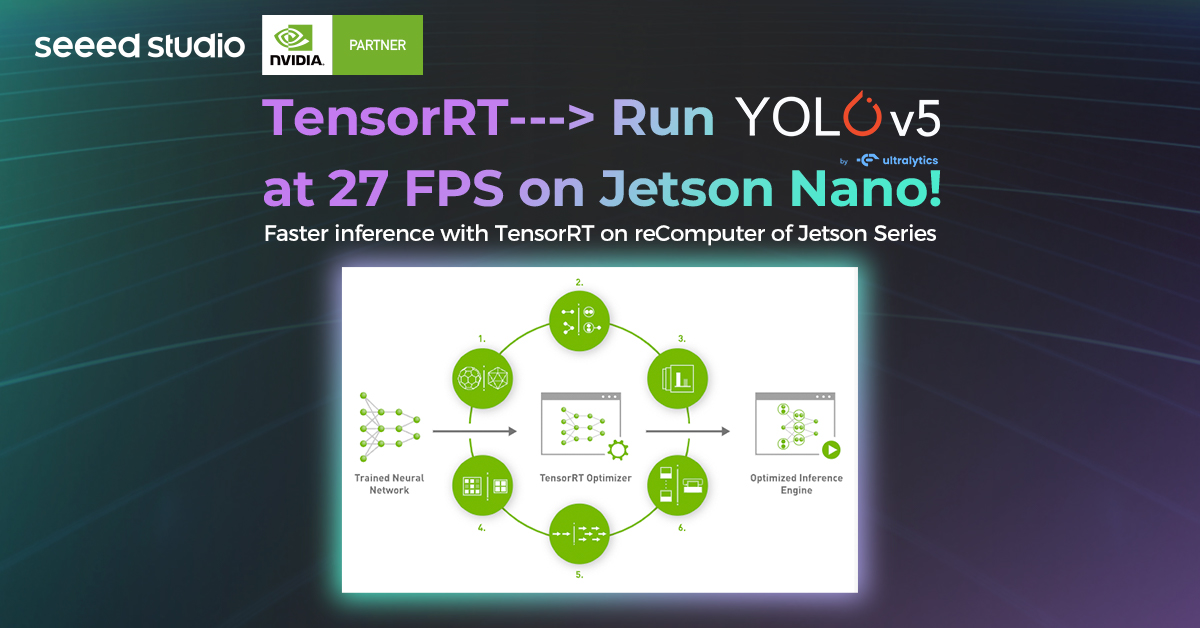
Faster YOLOv5 inference with TensorRT, Run YOLOv5 at 27 FPS on Jetson ...
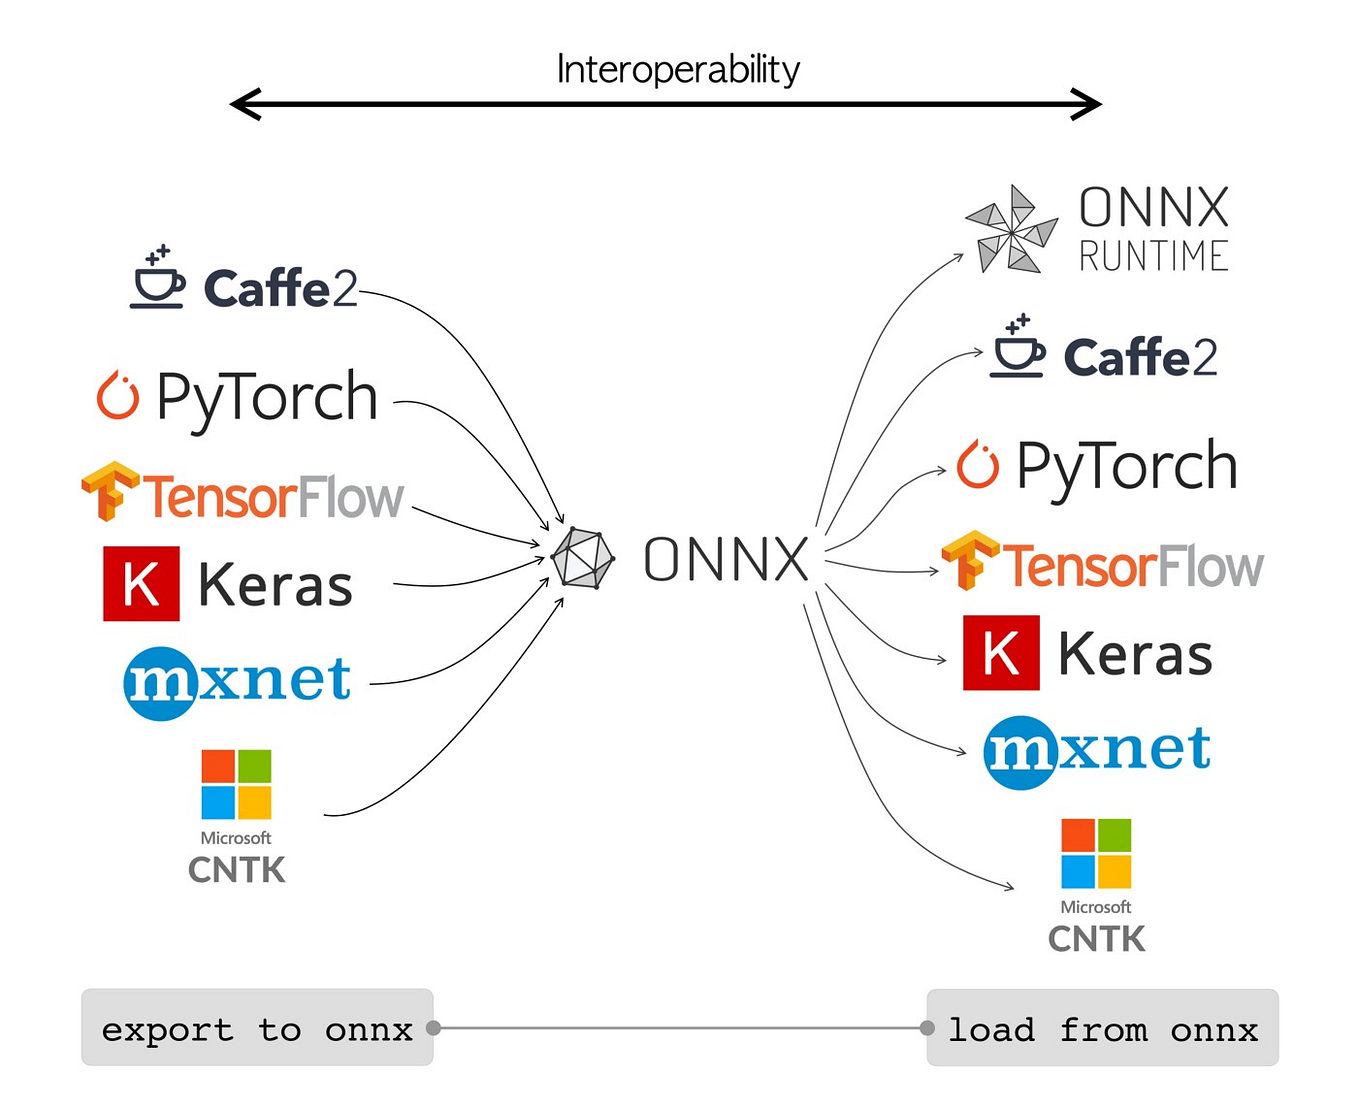
YOLOv7 with TensorRT on Jetson Nano (with Python script example) | by ...

CUDA Streams Usage in ORIN AGX - Jetson AGX Orin - NVIDIA Developer Forums
Advertisement Space (336x280)

[more] Deep learning model deployment based on NVIDIA Jetson AGX Orin ...

Jetson AGX tensorrt inference latency very high after upgrade the ...

Inference slow even using TensorRT - Jetson AGX Orin - NVIDIA Developer ...

Deploying to NVIDIA Jetson with TensorRT: Production-Grade Inference ...

TensorRT on Multiple CUDA-Streams - GPU-Accelerated Libraries - NVIDIA ...
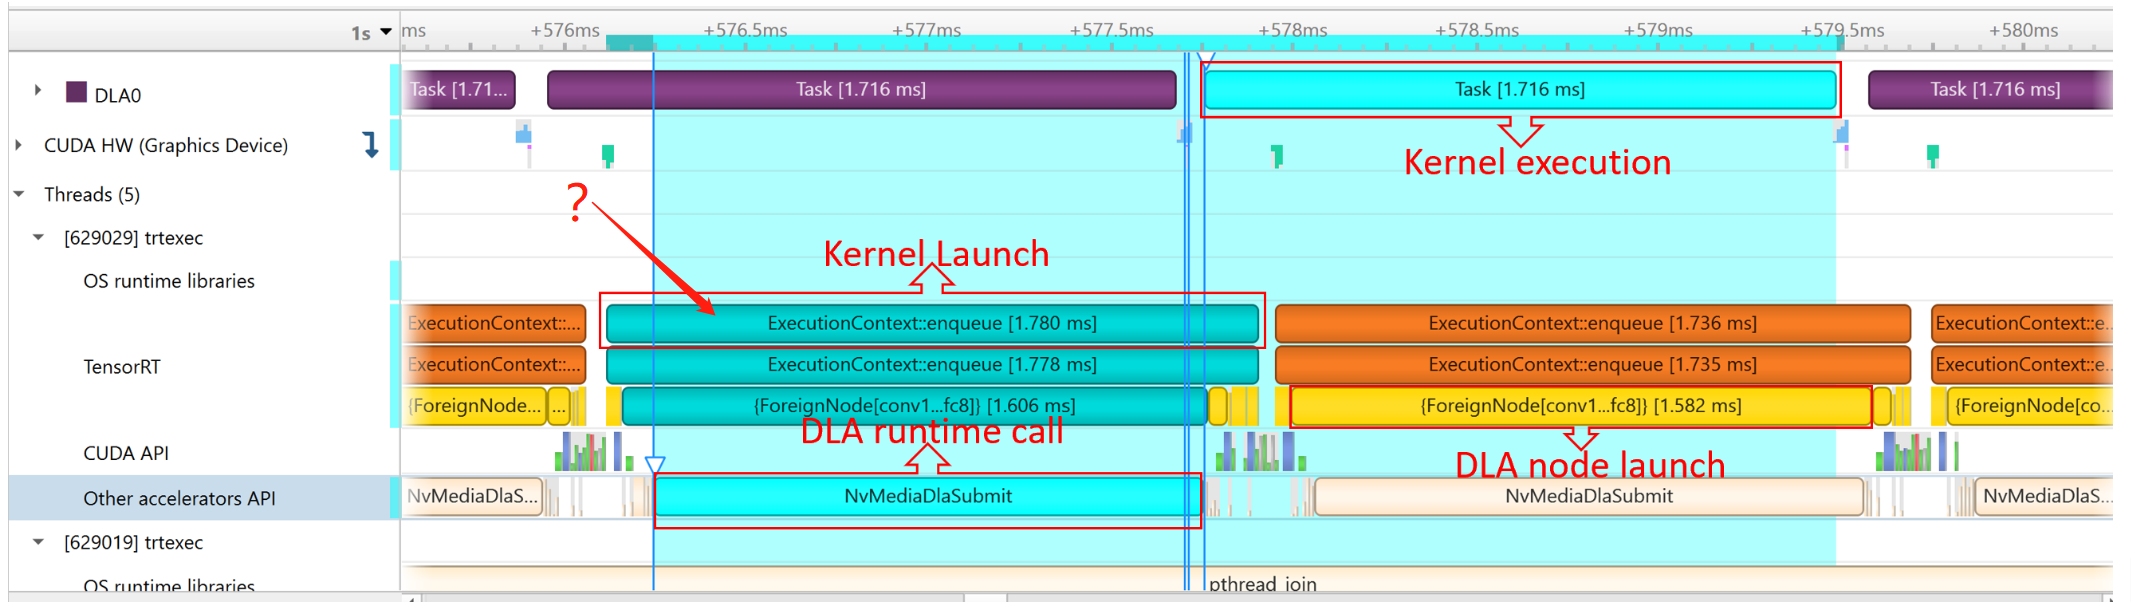
Tensorrt execute inferences with cuda multi-streams · Issue #485 ...