
Kv Cache Optimization Strategies For Scalable And Efficient Llm

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference

Figure 1 from KV Cache Optimization Strategies for Scalable and ...

[2603.20397] KV Cache Optimization Strategies for Scalable and ...
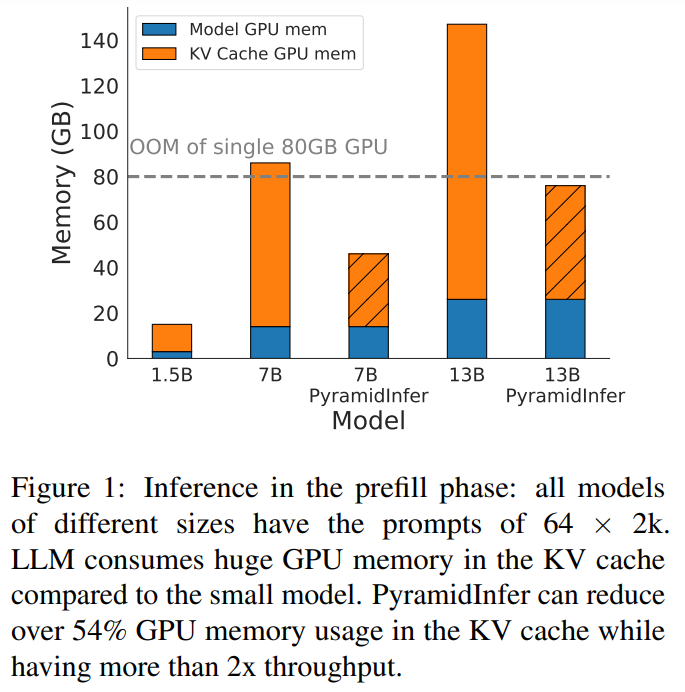
PyramidInfer: Allowing Efficient KV Cache Compression for Scalable LLM ...
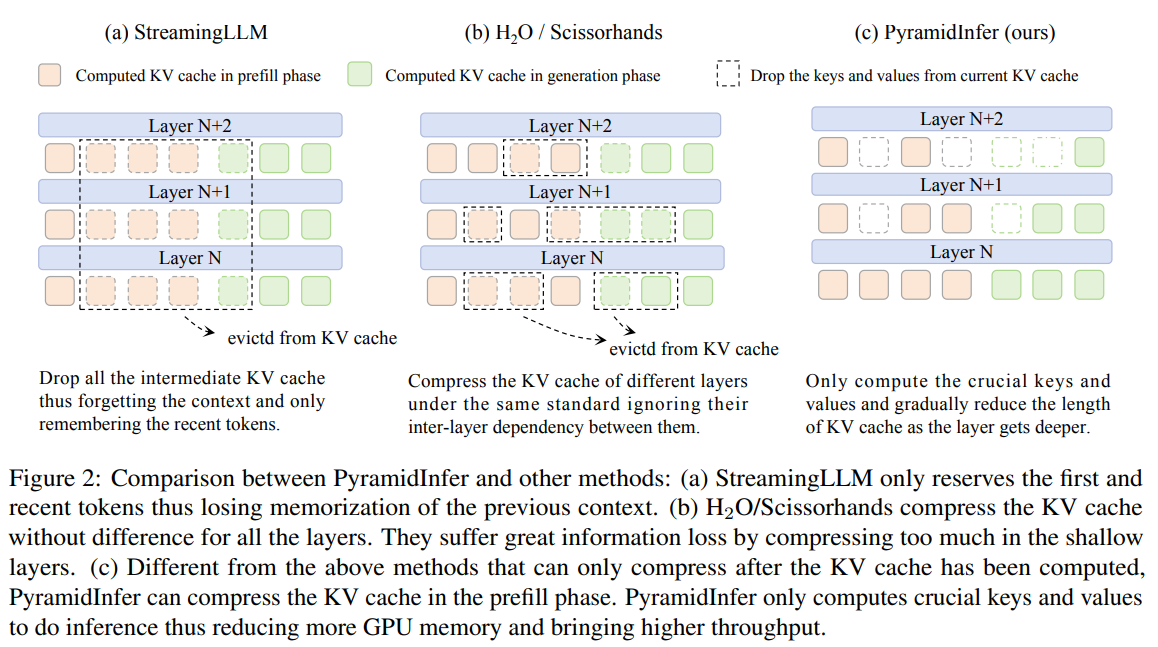
PyramidInfer: Allowing Efficient KV Cache Compression for Scalable LLM ...

PyramidInfer: Allowing Efficient KV Cache Compression for Scalable LLM ...

LOOK-M: Look-Once Optimization in KV Cache for Efficient Multimodal ...
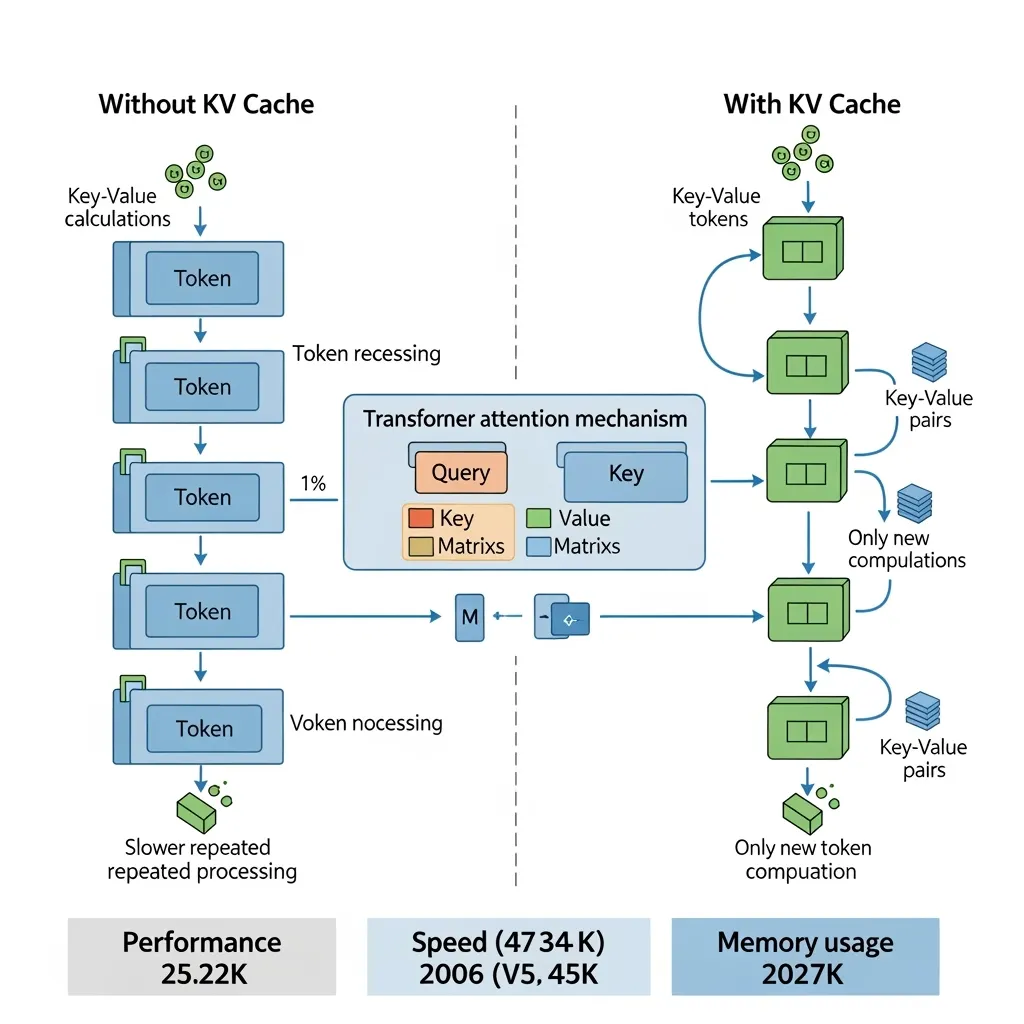
KV Cache Explained: Efficient Attention for LLM Generation ...
Advertisement Space (300x250)

KV Cache Optimization Techniques for LLM Serving | TURION.AI

LOOK-M: Look-Once Optimization in KV Cache for Efficient Multimodal ...

[PDF] LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM ...

[PDF] LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM ...
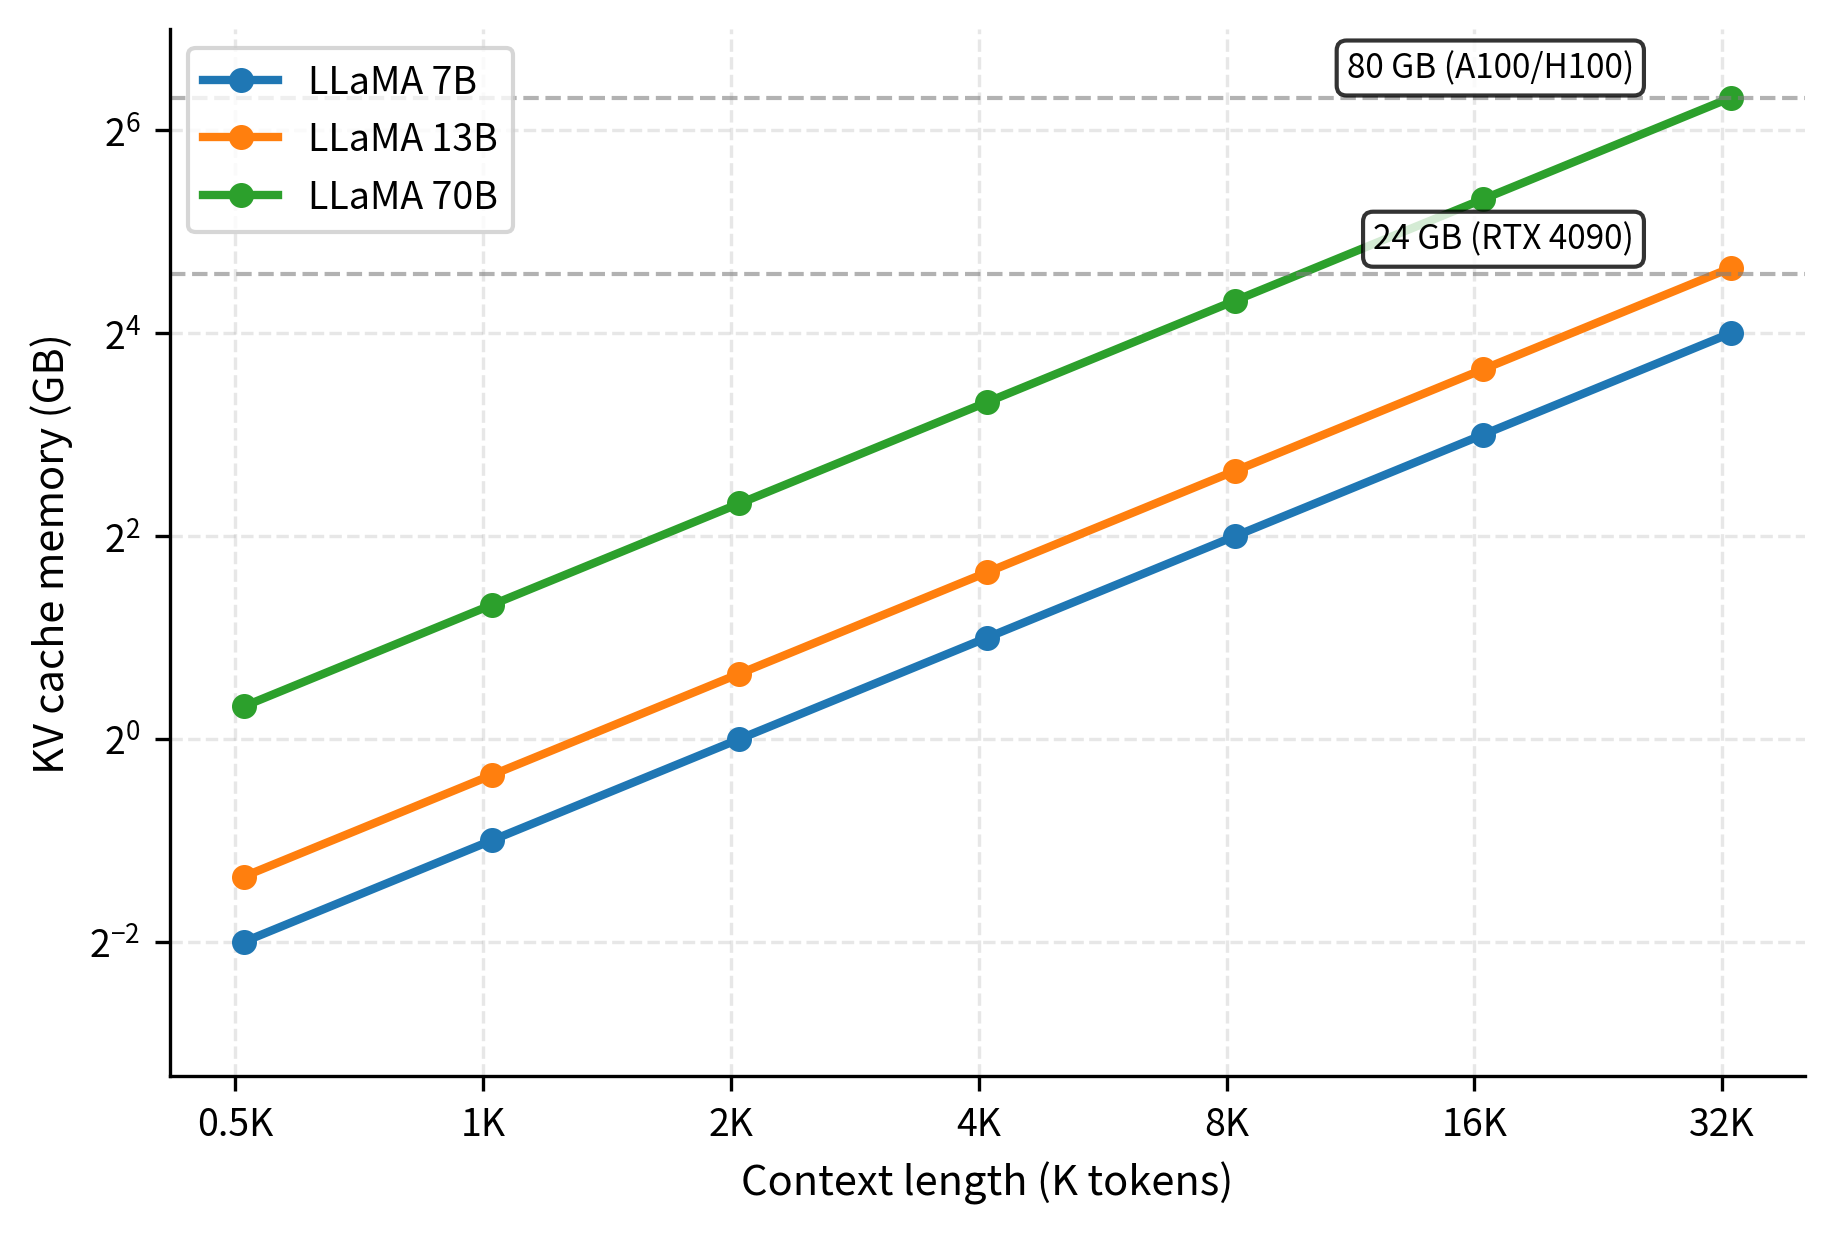
Memory Optimization in LLMs: Leveraging KV Cache Quantization for ...
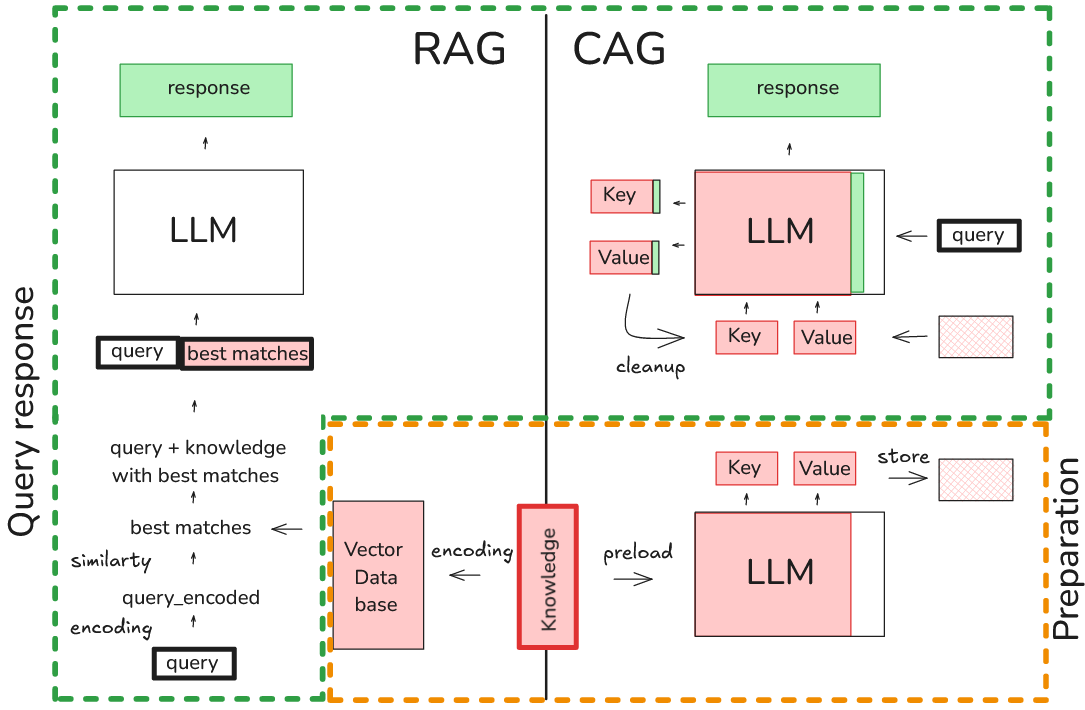
Memory Optimization in LLMs: Leveraging KV Cache Quantization for ...

Memory Optimization in LLMs: Leveraging KV Cache Quantization for ...
Memory Optimization in LLMs: Leveraging KV Cache Quantization for ...

Scaling Multi-Turn LLM Inference with KV Cache Storage Offload and Dell ...

Paper page - LMCache: An Efficient KV Cache Layer for Enterprise-Scale ...
Advertisement Space (336x280)
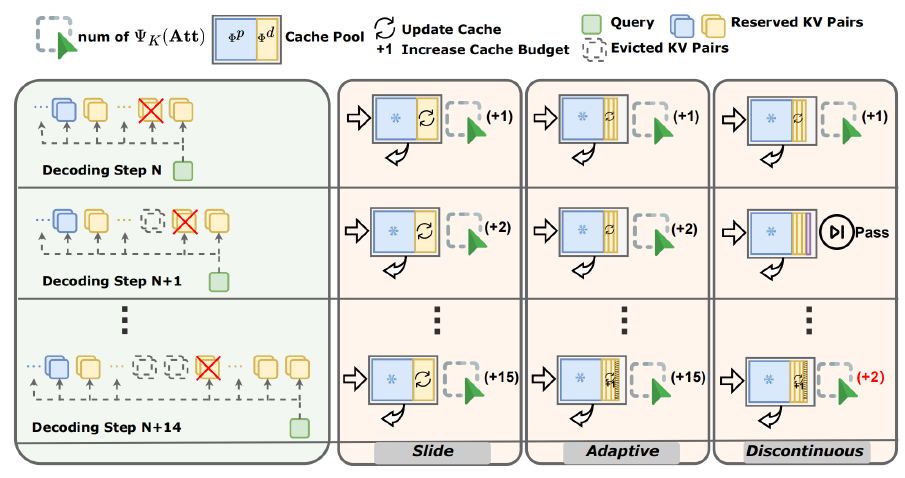
SCOPE: KV Cache optimization framework for long-context generation in ...

[논문 리뷰] KV Cache Transform Coding for Compact Storage in LLM Inference
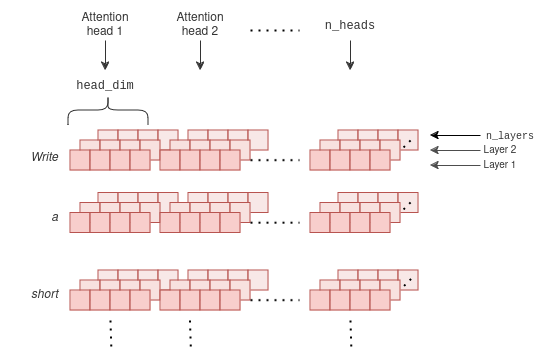
Techniques for KV Cache Optimization in Large Language Models
Memory Optimization in LLMs: Leveraging KV Cache Quantization for ...

Memory Optimization in LLMs: Leveraging KV Cache Quantization for ...
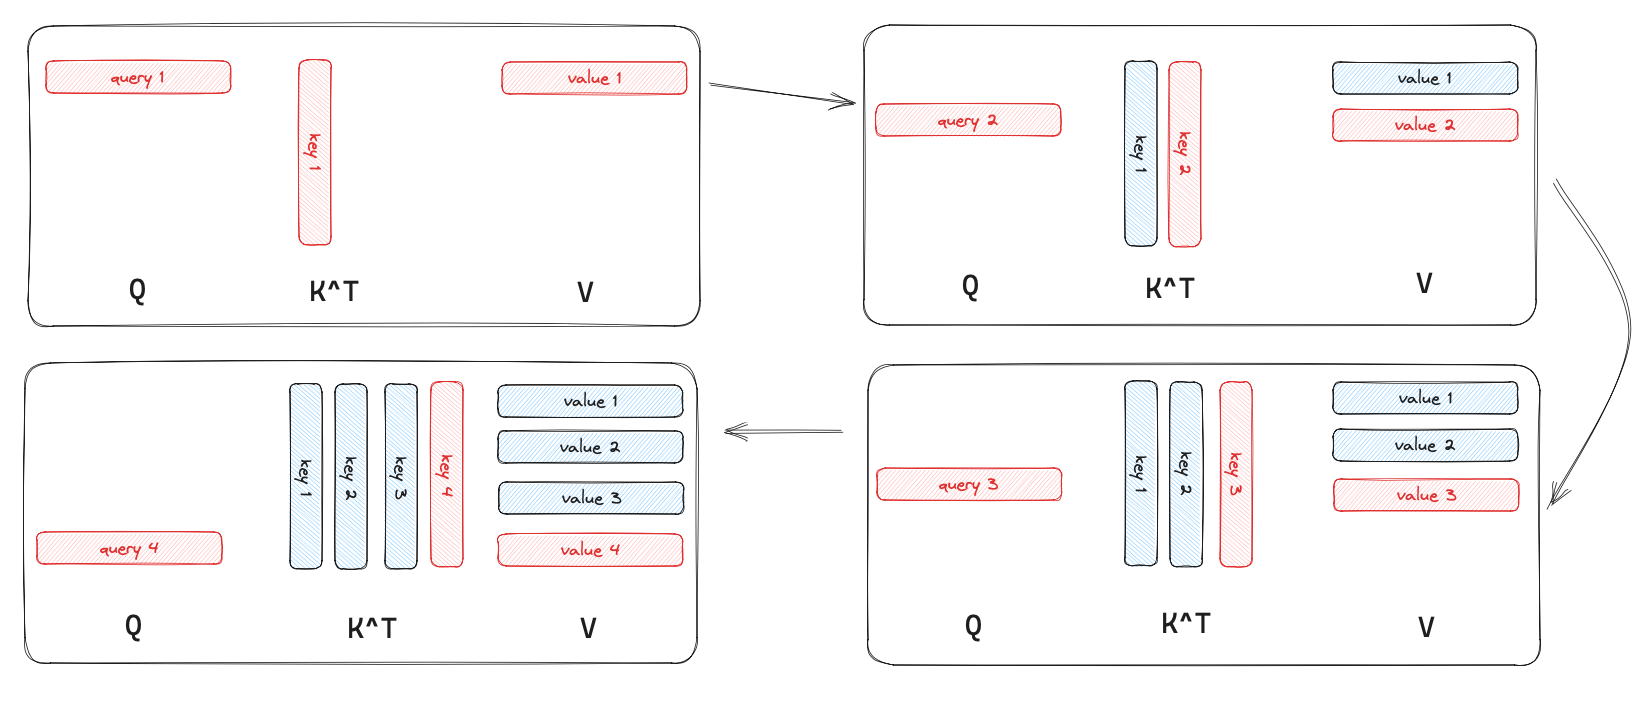
LLM inference optimization (1): KV Cache - MartinLwx's Blog

Memory Optimization in LLMs: Leveraging KV Cache Quantization for ...
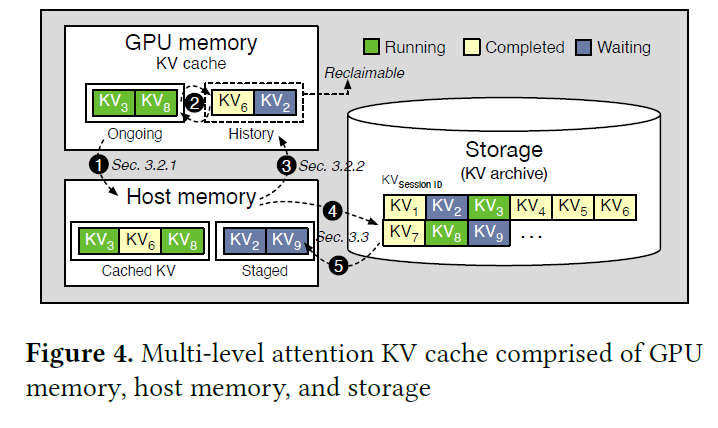
LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...
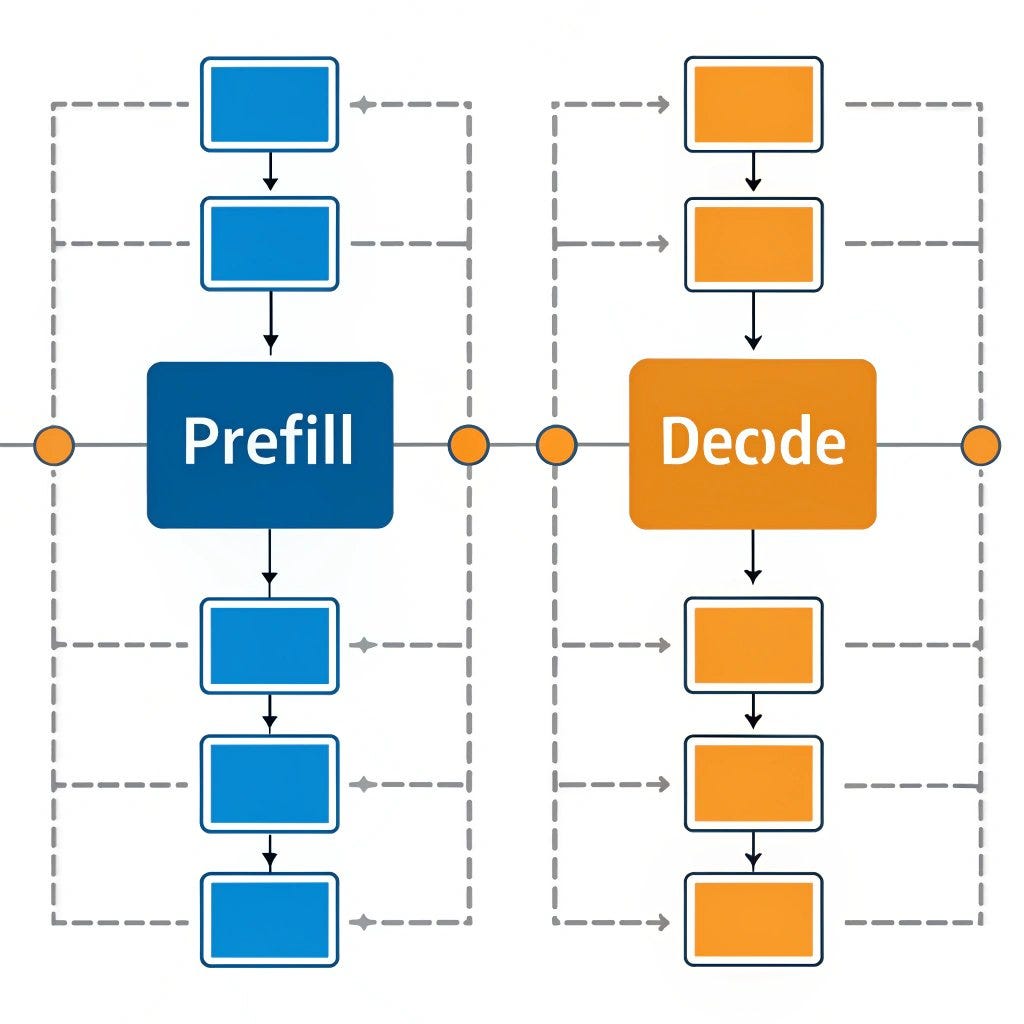
Memory Optimization in LLMs: Leveraging KV Cache Quantization for ...

LLM profiling guides KV cache optimization - Microsoft Research
Advertisement Space (336x280)

What Is KV Cache and Why It Affects LLM Speed - ML Journey

The Hidden Trick That Makes Every LLM Fast: Understanding the KV Cache ...

KV Cache in LLM: Boosting Efficiency and Reducing Latency | Ashish Patel 🇮🇳
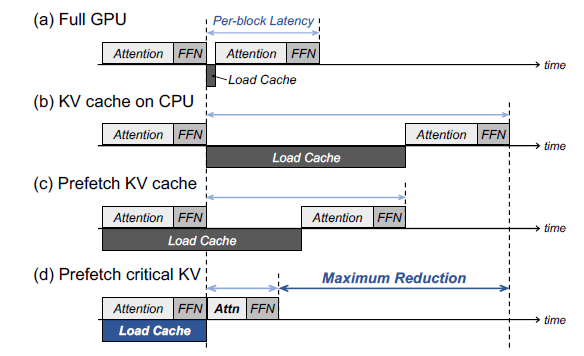
Optimizing LLM Inference: Managing the KV Cache | by Aalok Patwa | Medium
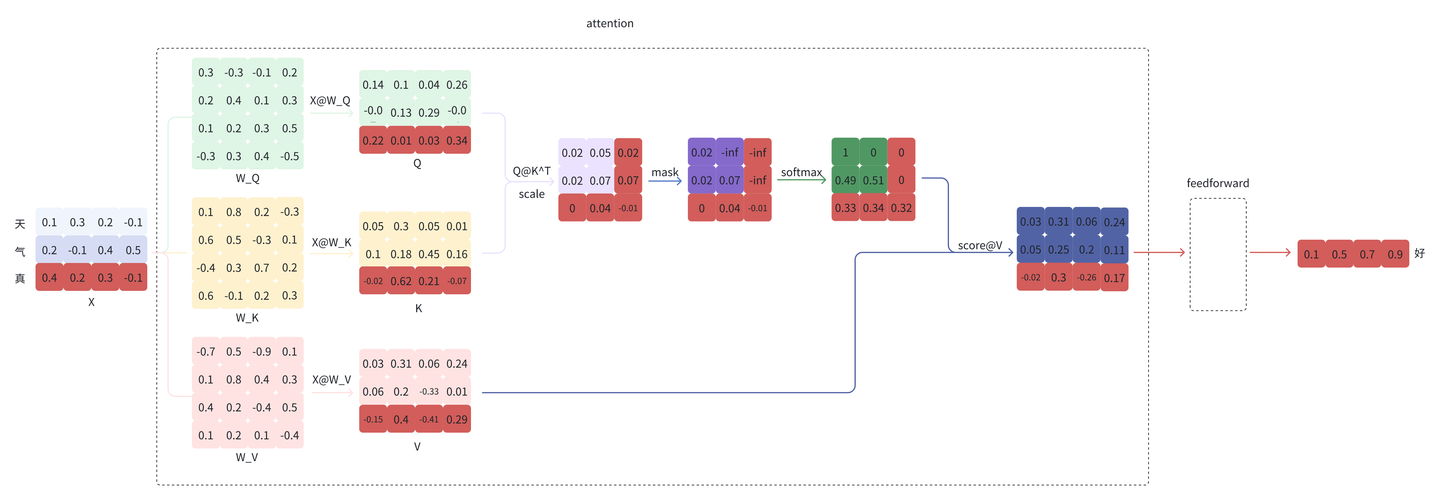
LLM 推理优化之 KV Cache - 知乎

Understanding and Coding the KV Cache in LLMs from Scratch