
Pdf Lmcache An Efficient Kv Cache Layer For Enterprise Scale Llm
LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference ...

LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference ...

LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference ...

LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference ...

[PDF] LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM ...

LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference ...

Paper page - LMCache: An Efficient KV Cache Layer for Enterprise-Scale ...

Paper page - LMCache: An Efficient KV Cache Layer for Enterprise-Scale ...

Paper page - LMCache: An Efficient KV Cache Layer for Enterprise-Scale ...

Paper page - LMCache: An Efficient KV Cache Layer for Enterprise-Scale ...
Advertisement Space (300x250)

Paper page - LMCache: An Efficient KV Cache Layer for Enterprise-Scale ...

Paper page - LMCache: An Efficient KV Cache Layer for Enterprise-Scale ...

PyramidInfer: Allowing Efficient KV Cache Compression for Scalable LLM ...

[论文评述] LRAgent: Efficient KV Cache Sharing for Multi-LoRA LLM Agents

Paper page - GEAR: An Efficient KV Cache Compression Recipefor Near ...

Caching Strategies for LLM Systems (Part 2): KV Cache and the ...
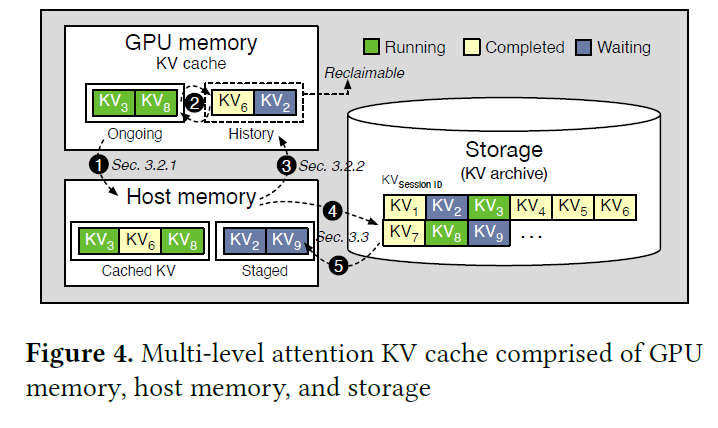
LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...

[논문 리뷰] KV Cache Transform Coding for Compact Storage in LLM Inference
amd - LMCache: Revolutionizing KV Cache for Faster LLM Inference - cuda

LMCache Lab powers up vLLM V1 with KV cache and NIXL support | LMCache ...
Advertisement Space (336x280)
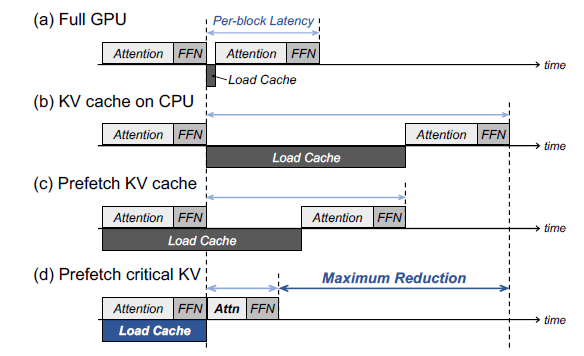
KV Cache compression with Inter-Layer Attention Similarity for ...

LLM Inference: Accelerating Long Context Generation with KV Cache ...

Scaling Multi-Turn LLM Inference with KV Cache Storage Offload and Dell ...
GitHub - apguan/lmcache: Supercharge Your LLM with the Fastest KV Cache ...
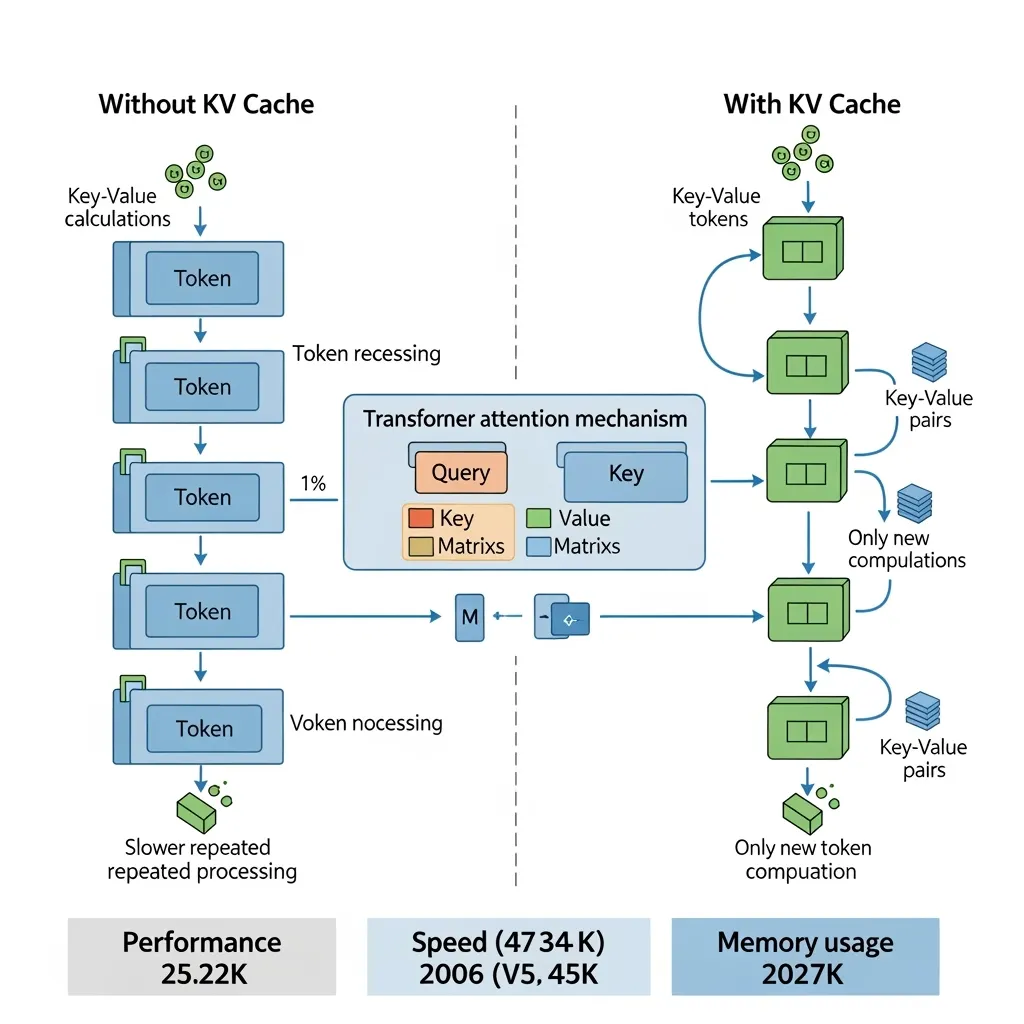
Memory Optimization in LLMs: Leveraging KV Cache Quantization for ...
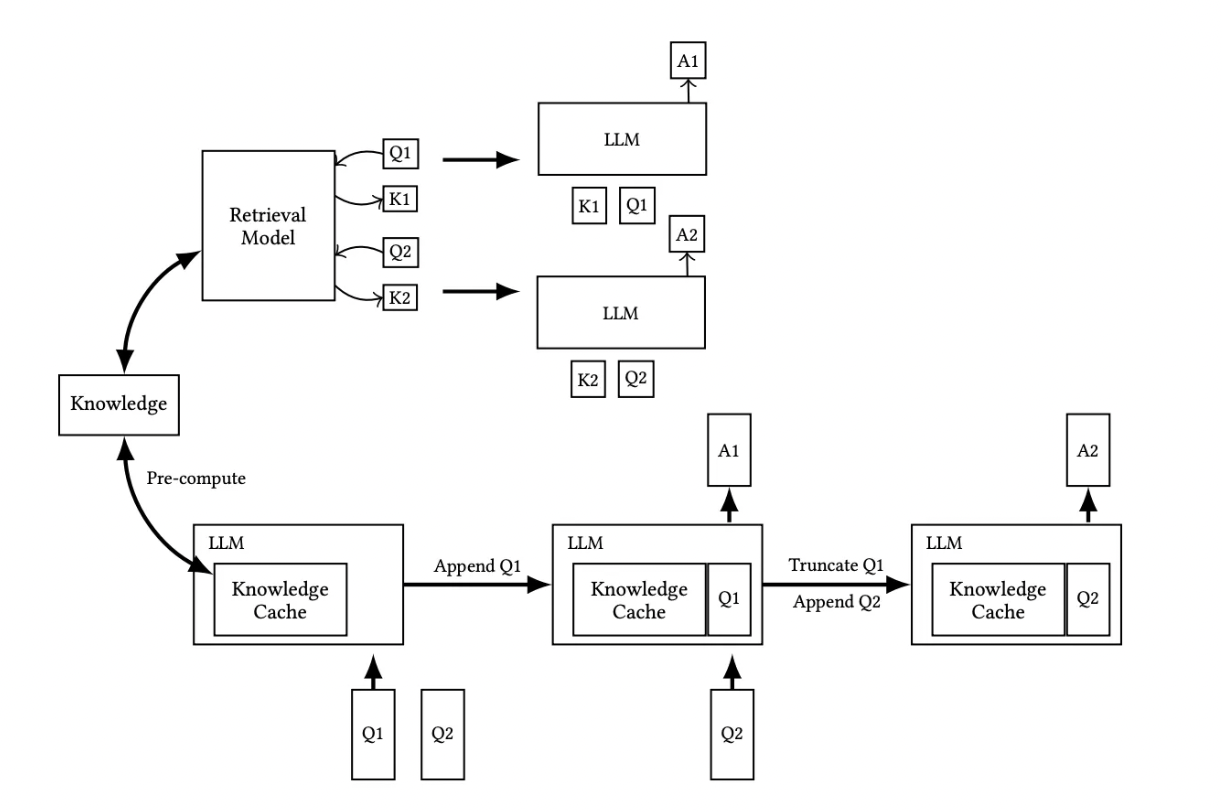
Optimizing LLM Inference: Managing the KV Cache | by Aalok Patwa | Medium

(PDF) Efficient and Workload-Aware LLM Serving via Runtime Layer ...

LLM Jargons Explained: Part 4 - KV Cache - YouTube
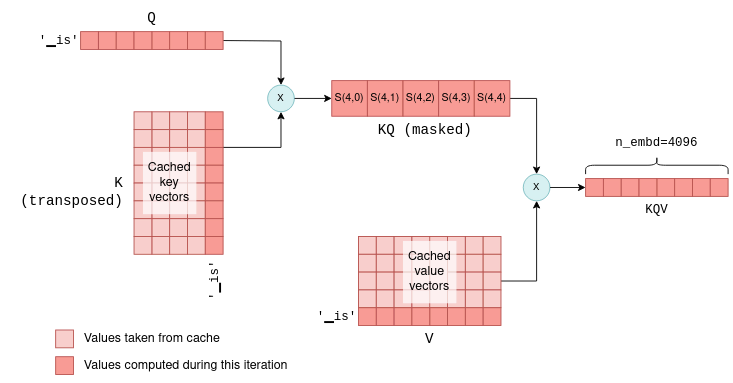
LLM 和 KV cache 详解 | Jasmine

Memory Optimization in LLMs: Leveraging KV Cache Quantization for ...
Advertisement Space (336x280)
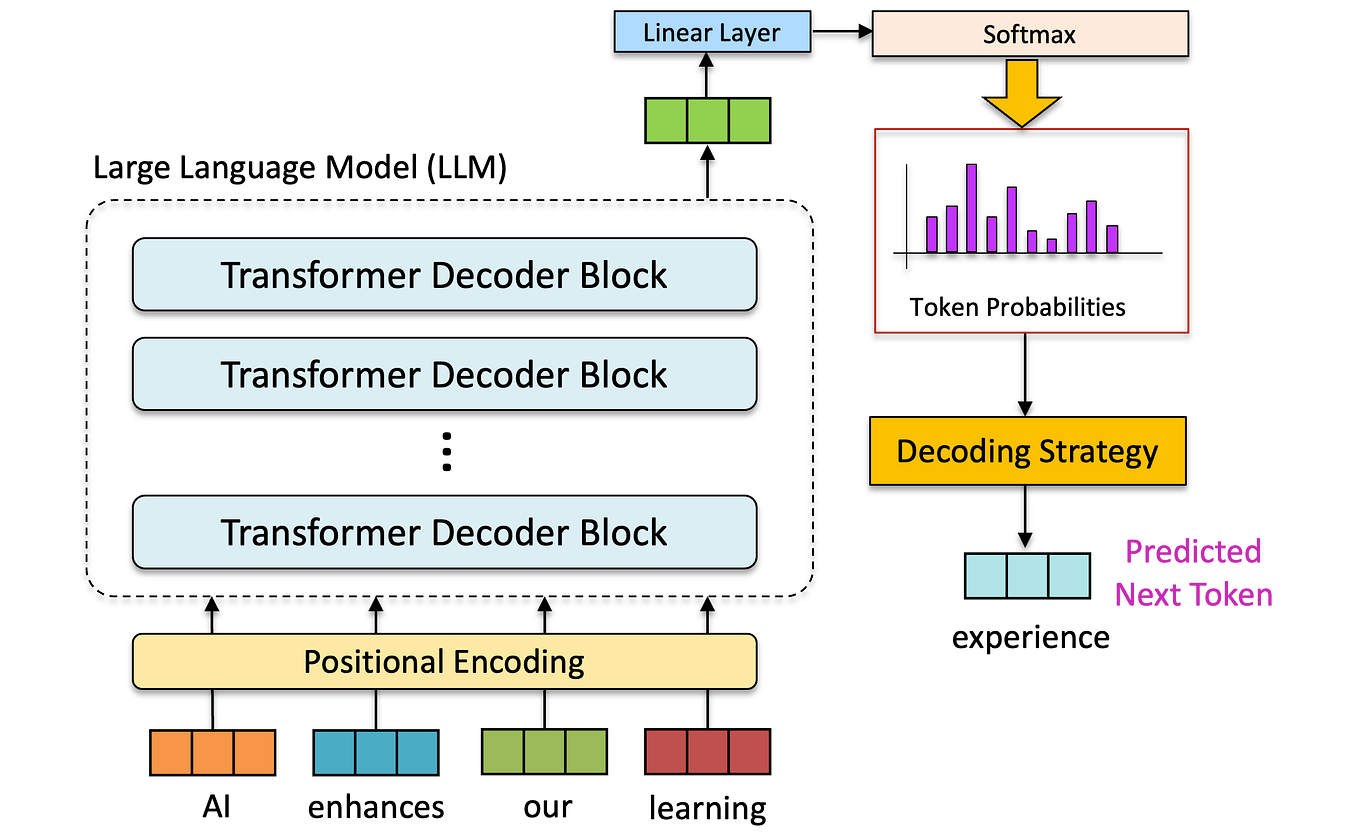
Optimizing LLM Inference: Managing the KV Cache | by Aalok Patwa | Medium

Paper page — Infinite-LLM: Efficient LLM Service for Long Context with ...

Oaken: Fast and Efficient LLM Serving with Online-Offline Hybrid KV ...
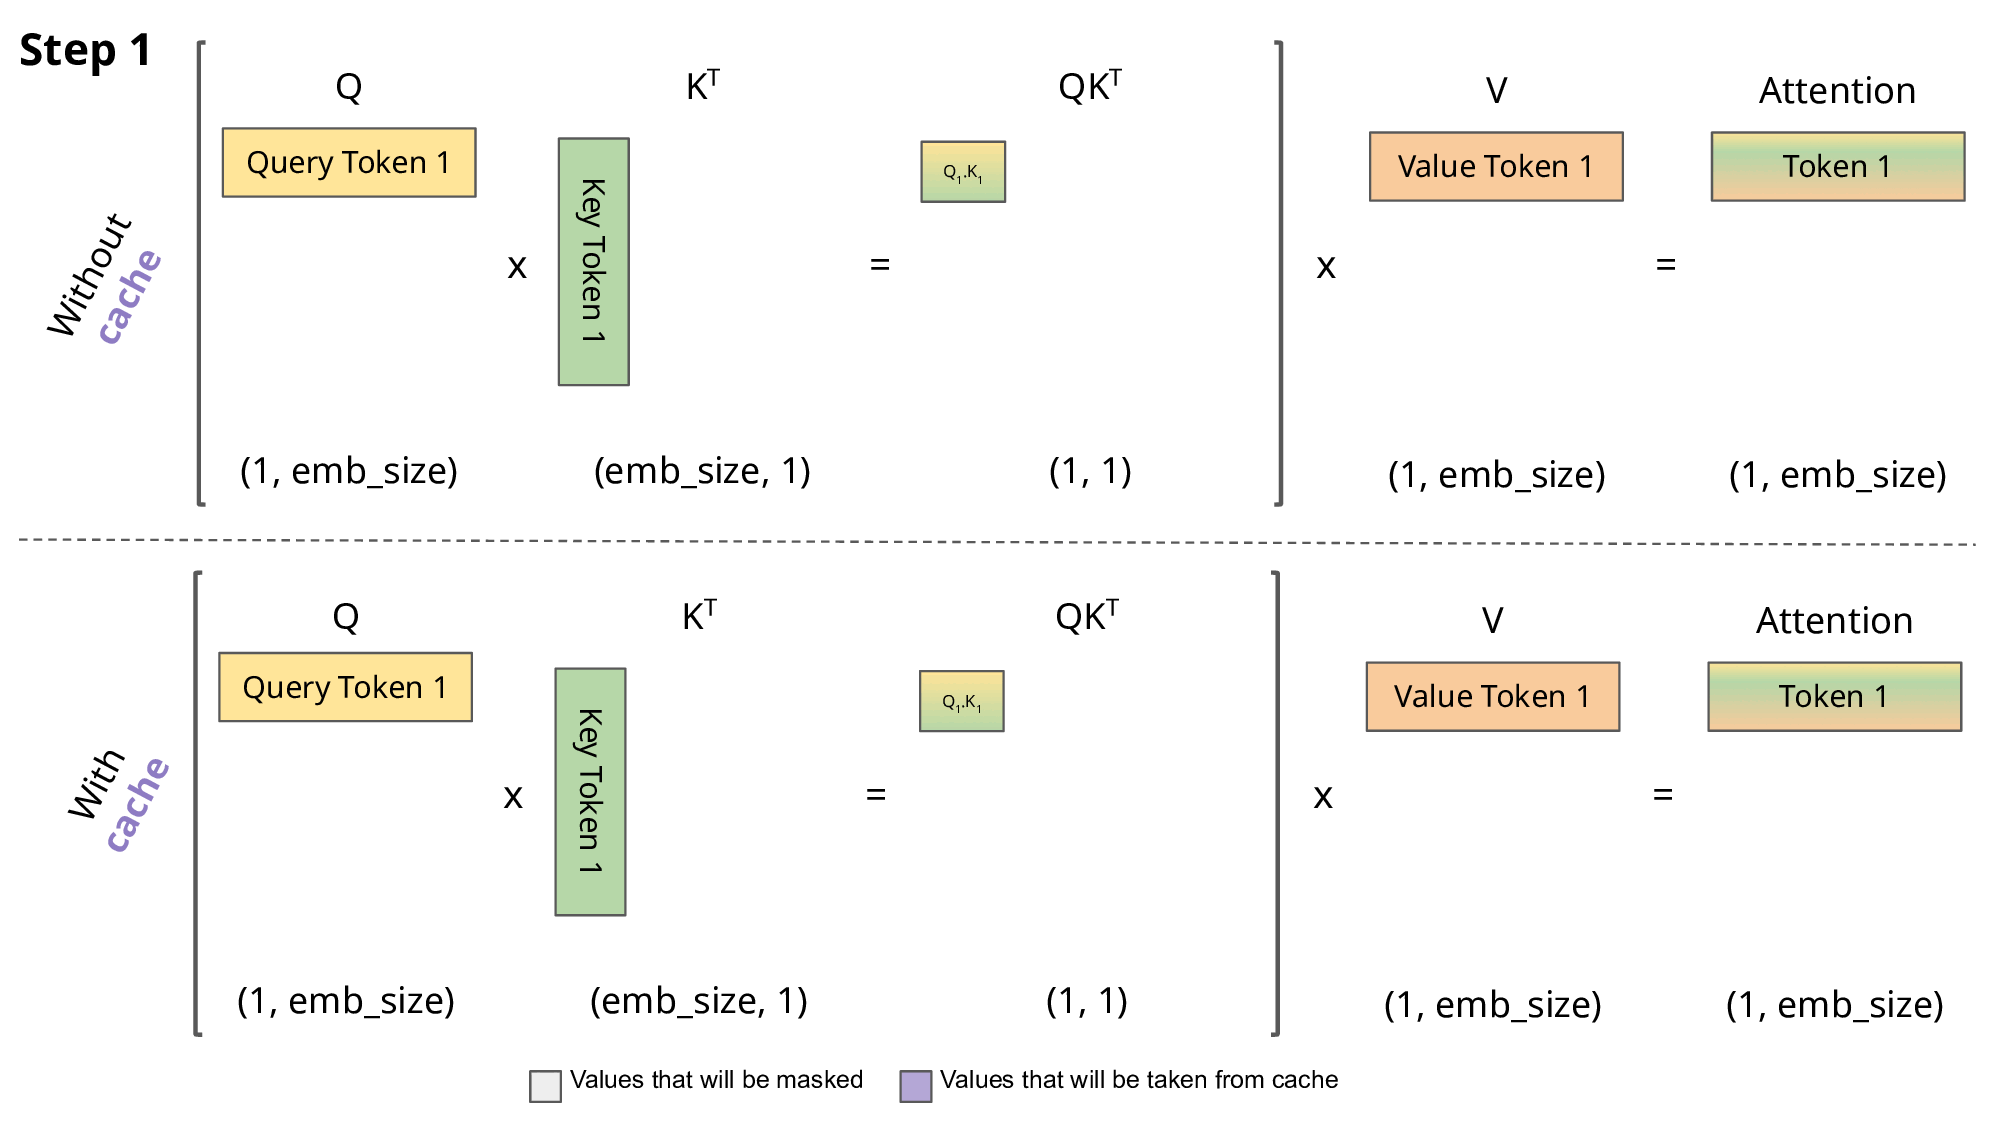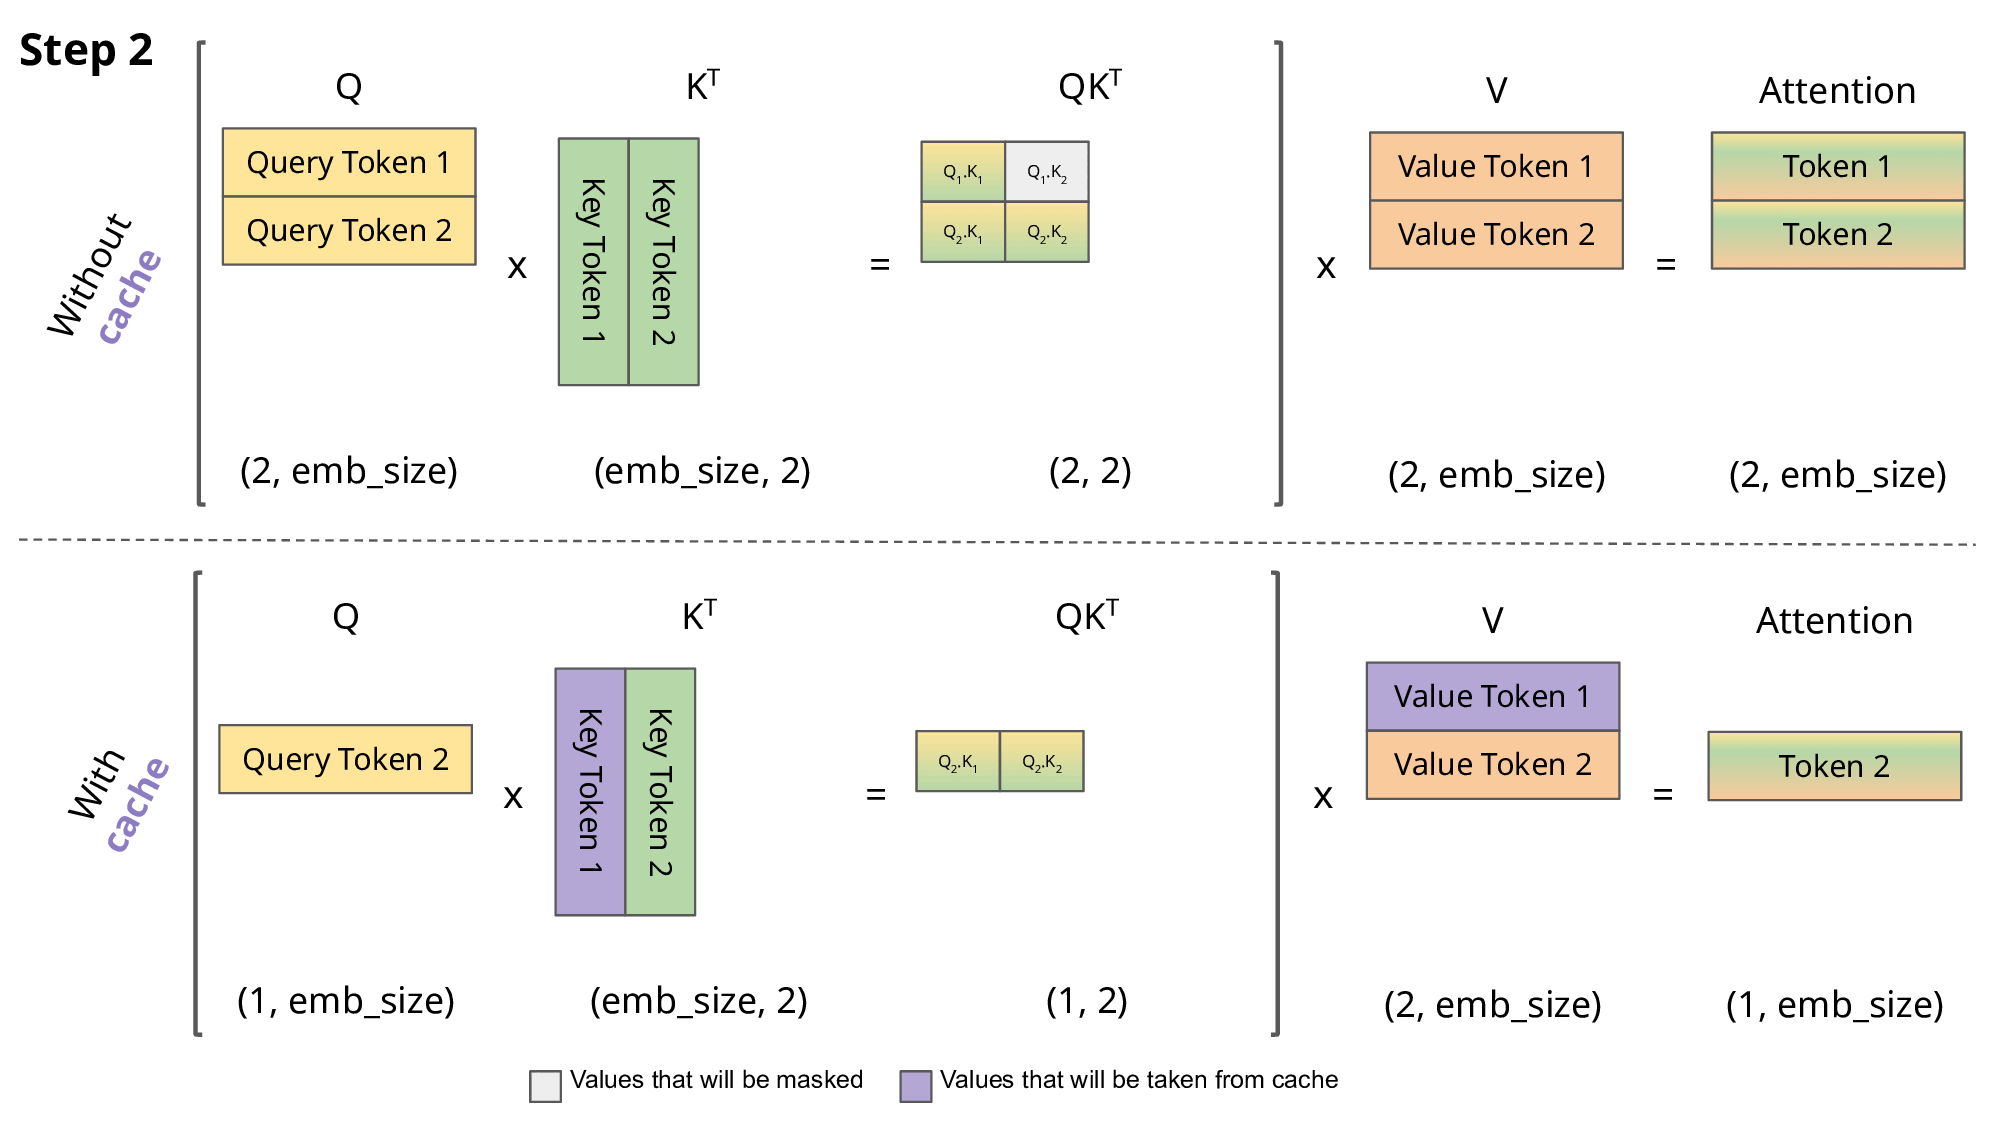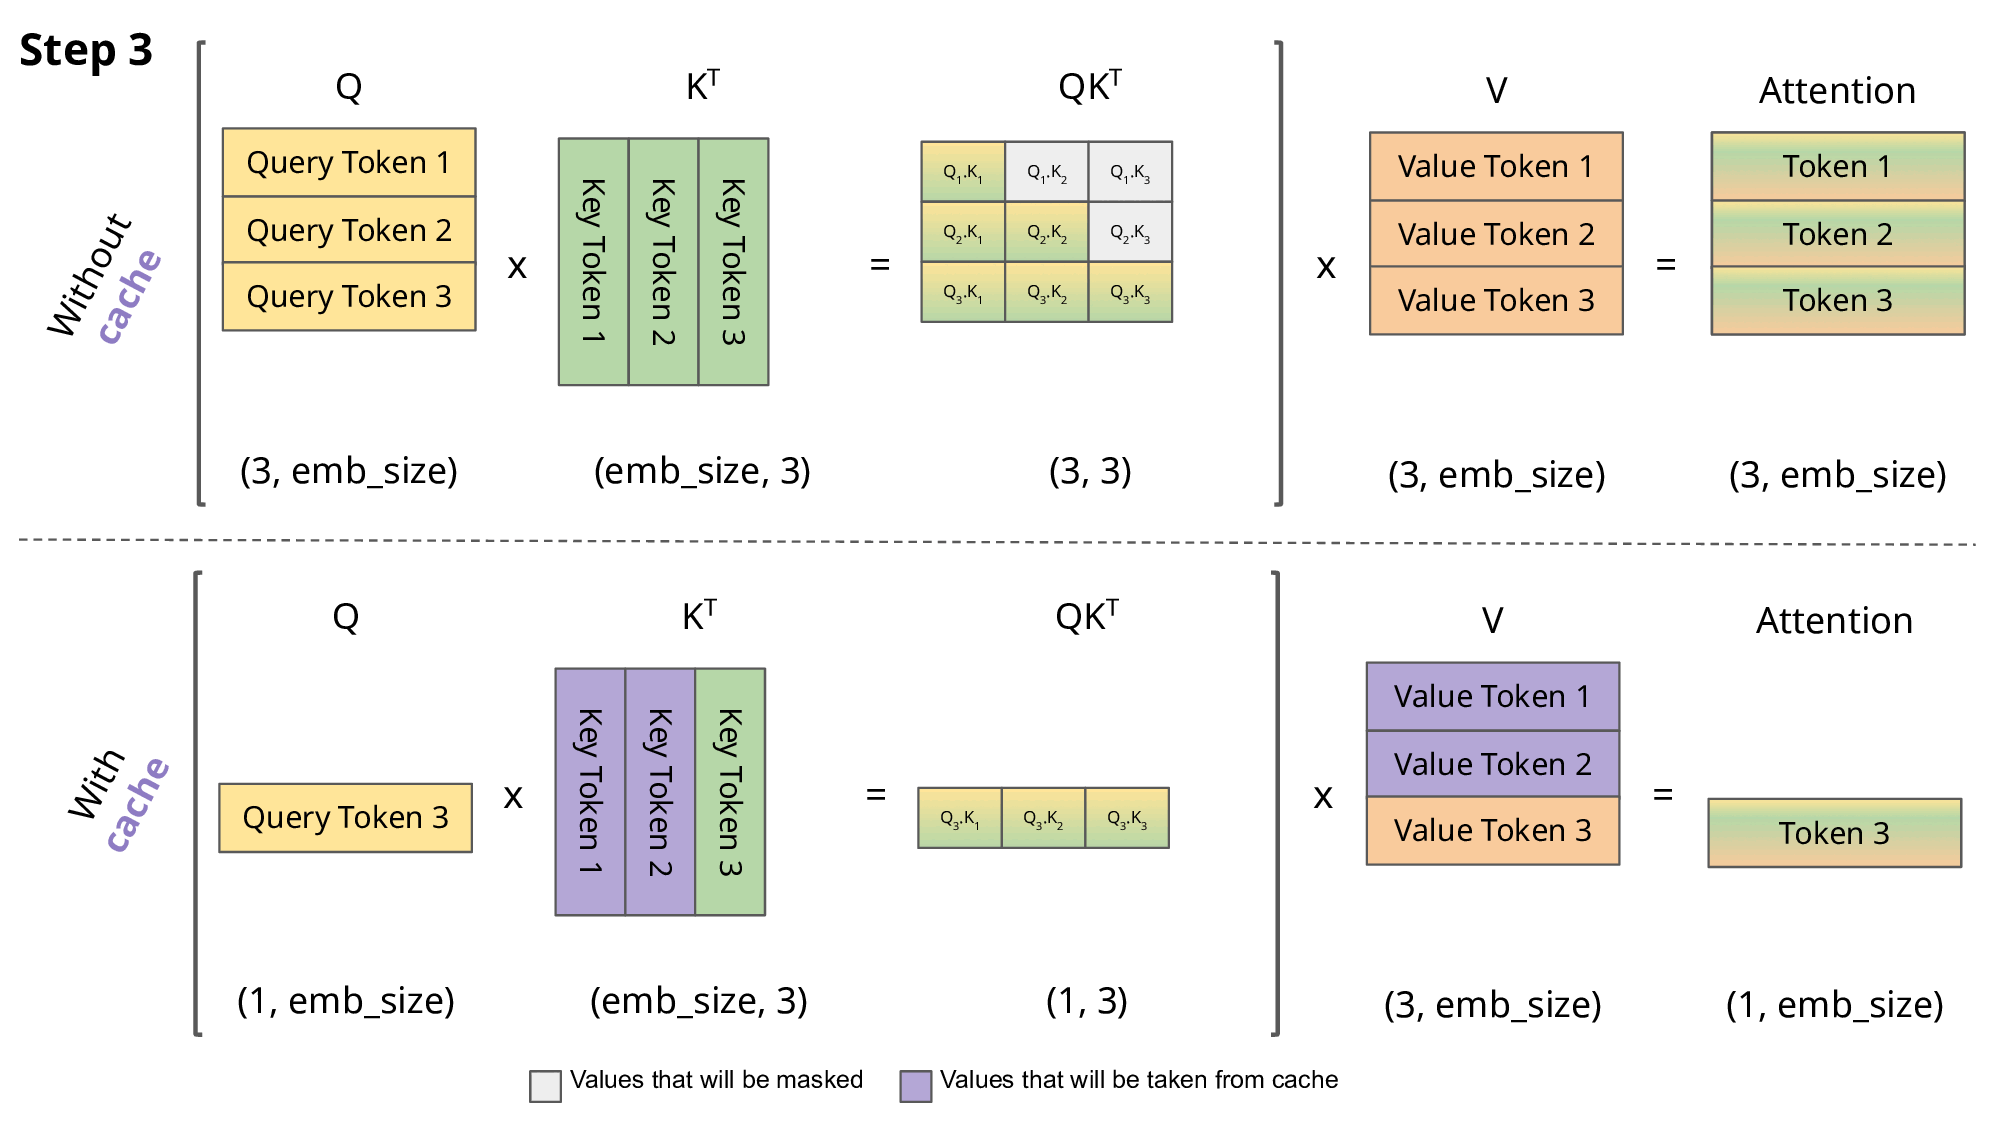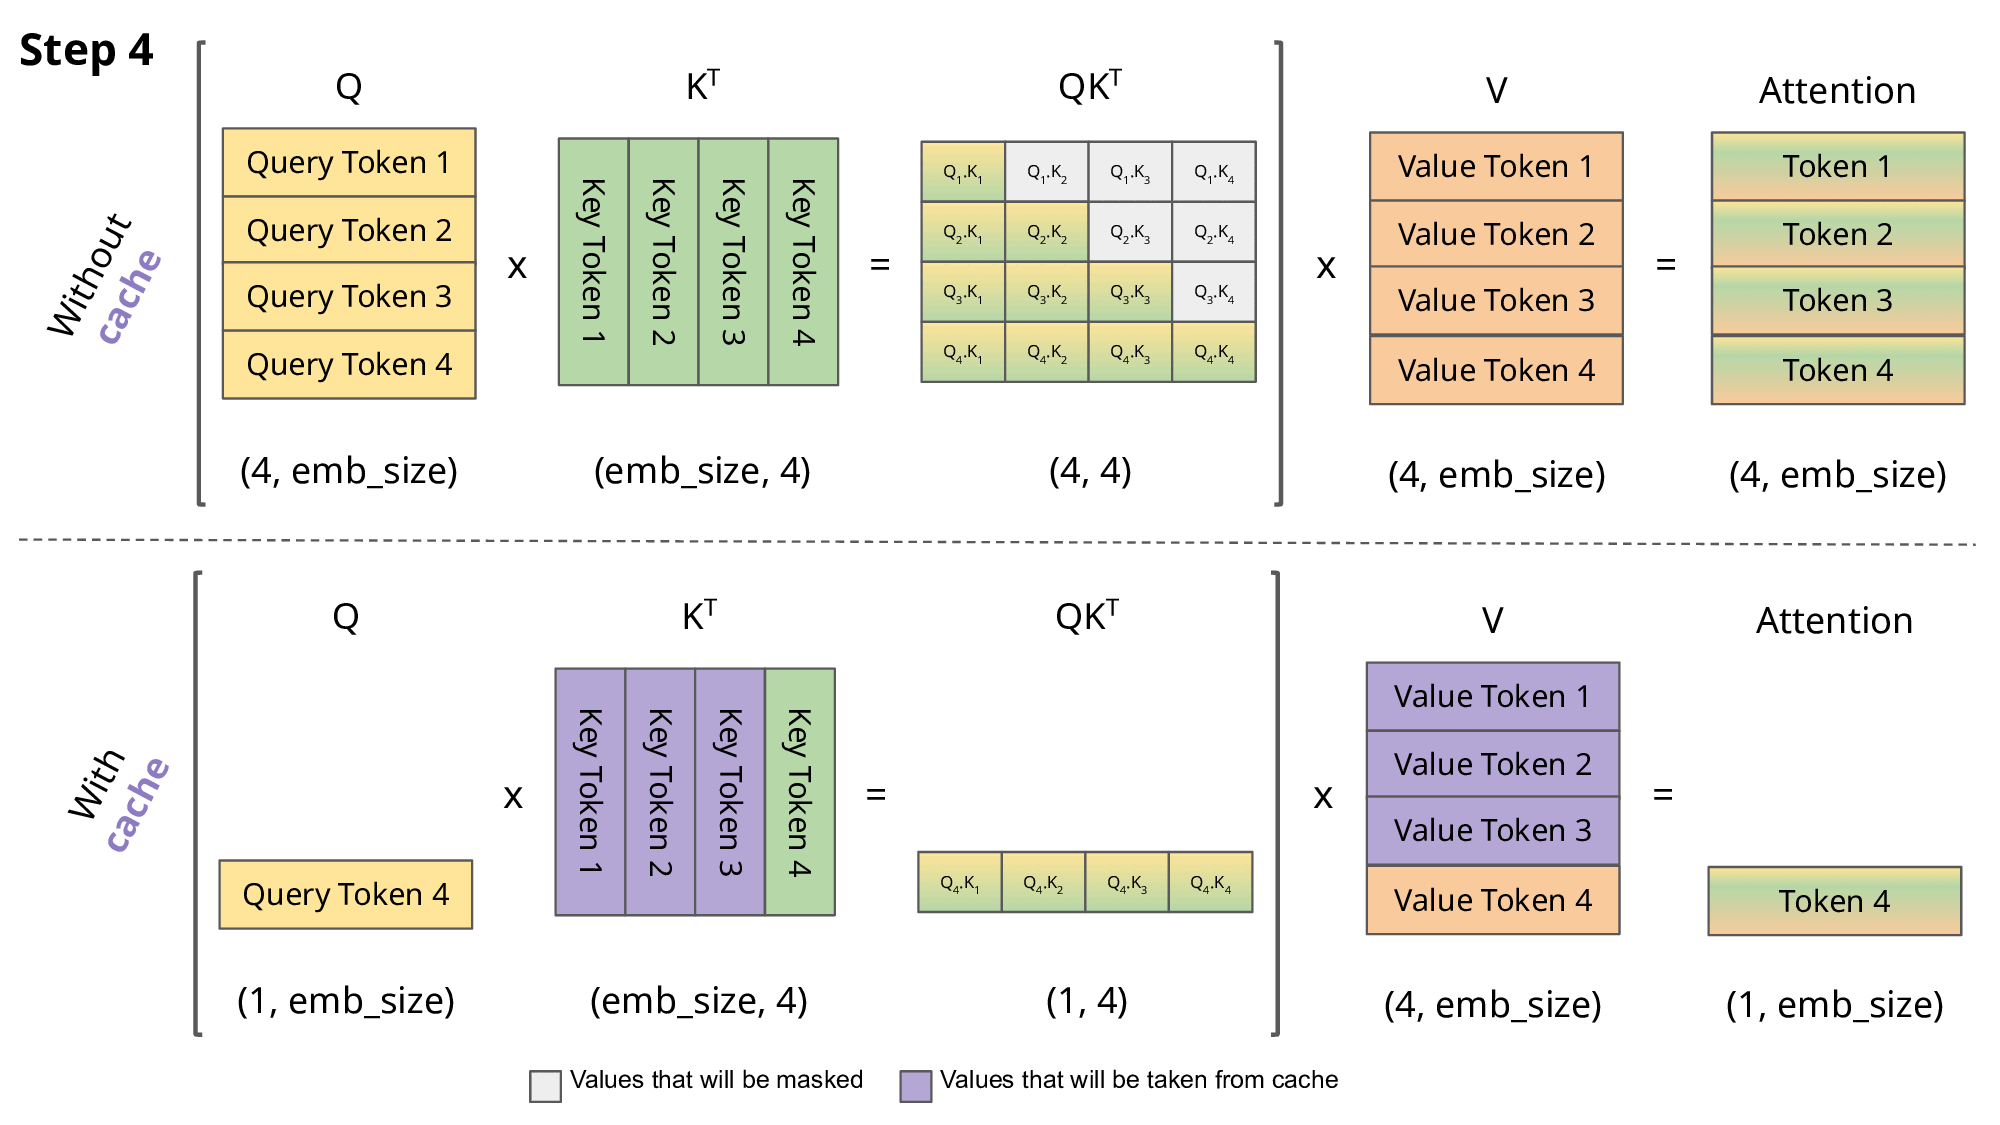
Optimizing LLM Inference: Managing the KV Cache | by Aalok Patwa | Medium

KV-Cache Offloading with LMCache | Open‑Source LLM Inferencing at Scale ...
How KV Cache Accelerates LLM Inference Performance