
Llm Inference Performance Latency And Throughput Metrics Youtube

LLM Inference Performance: Latency and Throughput Metrics - YouTube

Measuring LLM Inference Performance - YouTube

Evaluation Metrics of LLM Performance (13 Minutes) - YouTube

How to Benchmark LLM Inference Performance: TTFT, ITL, and Throughput ...

LLM Inference Latency Metrics Explained | PDF | Mean | Latency ...

Scaling Ultra Low Latency LLM Inference - YouTube

Deploying and Monitoring LLM Inference Endpoints - YouTube

High Performance LLM Inference in Production - YouTube

How to Benchmark LLM Inference Performance: TTFT, ITL, and Throughput ...
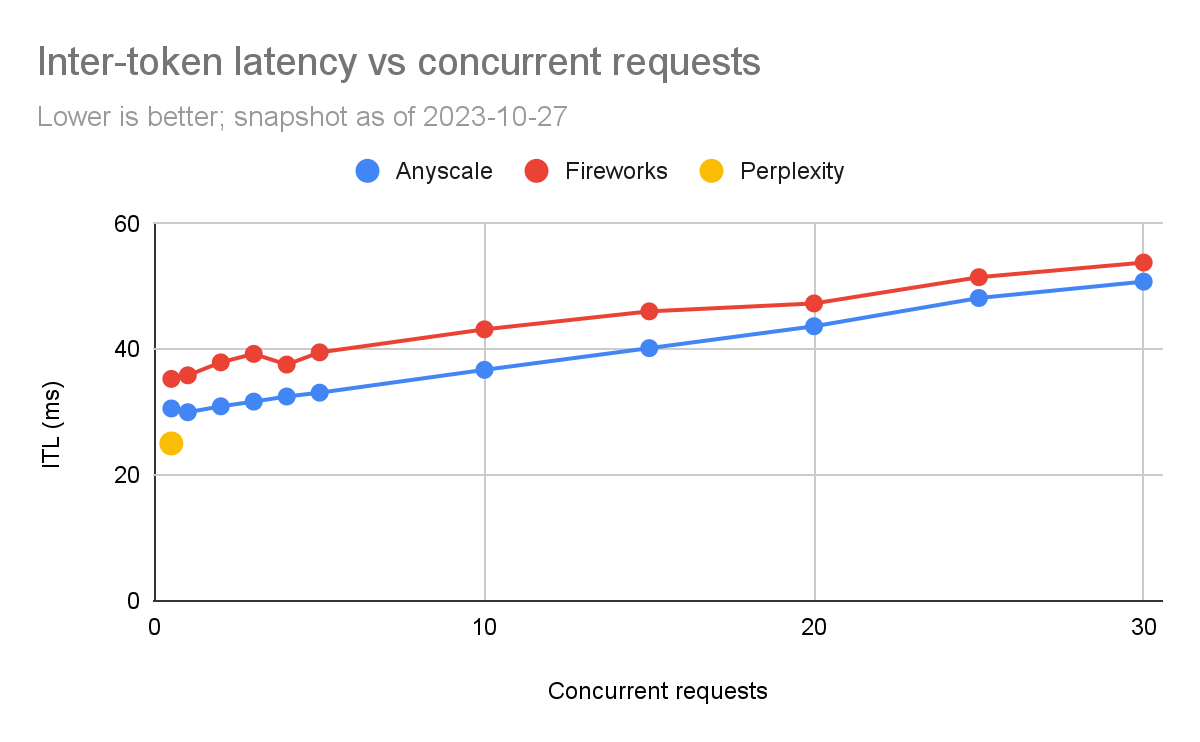
Reproducible Performance Metrics for LLM inference
Advertisement Space (300x250)

LLM Inference Optimization: Techniques That Actually Reduce Latency and ...

(PDF) Optimizing LLM Latency and Throughput for Interactive Web Interfaces
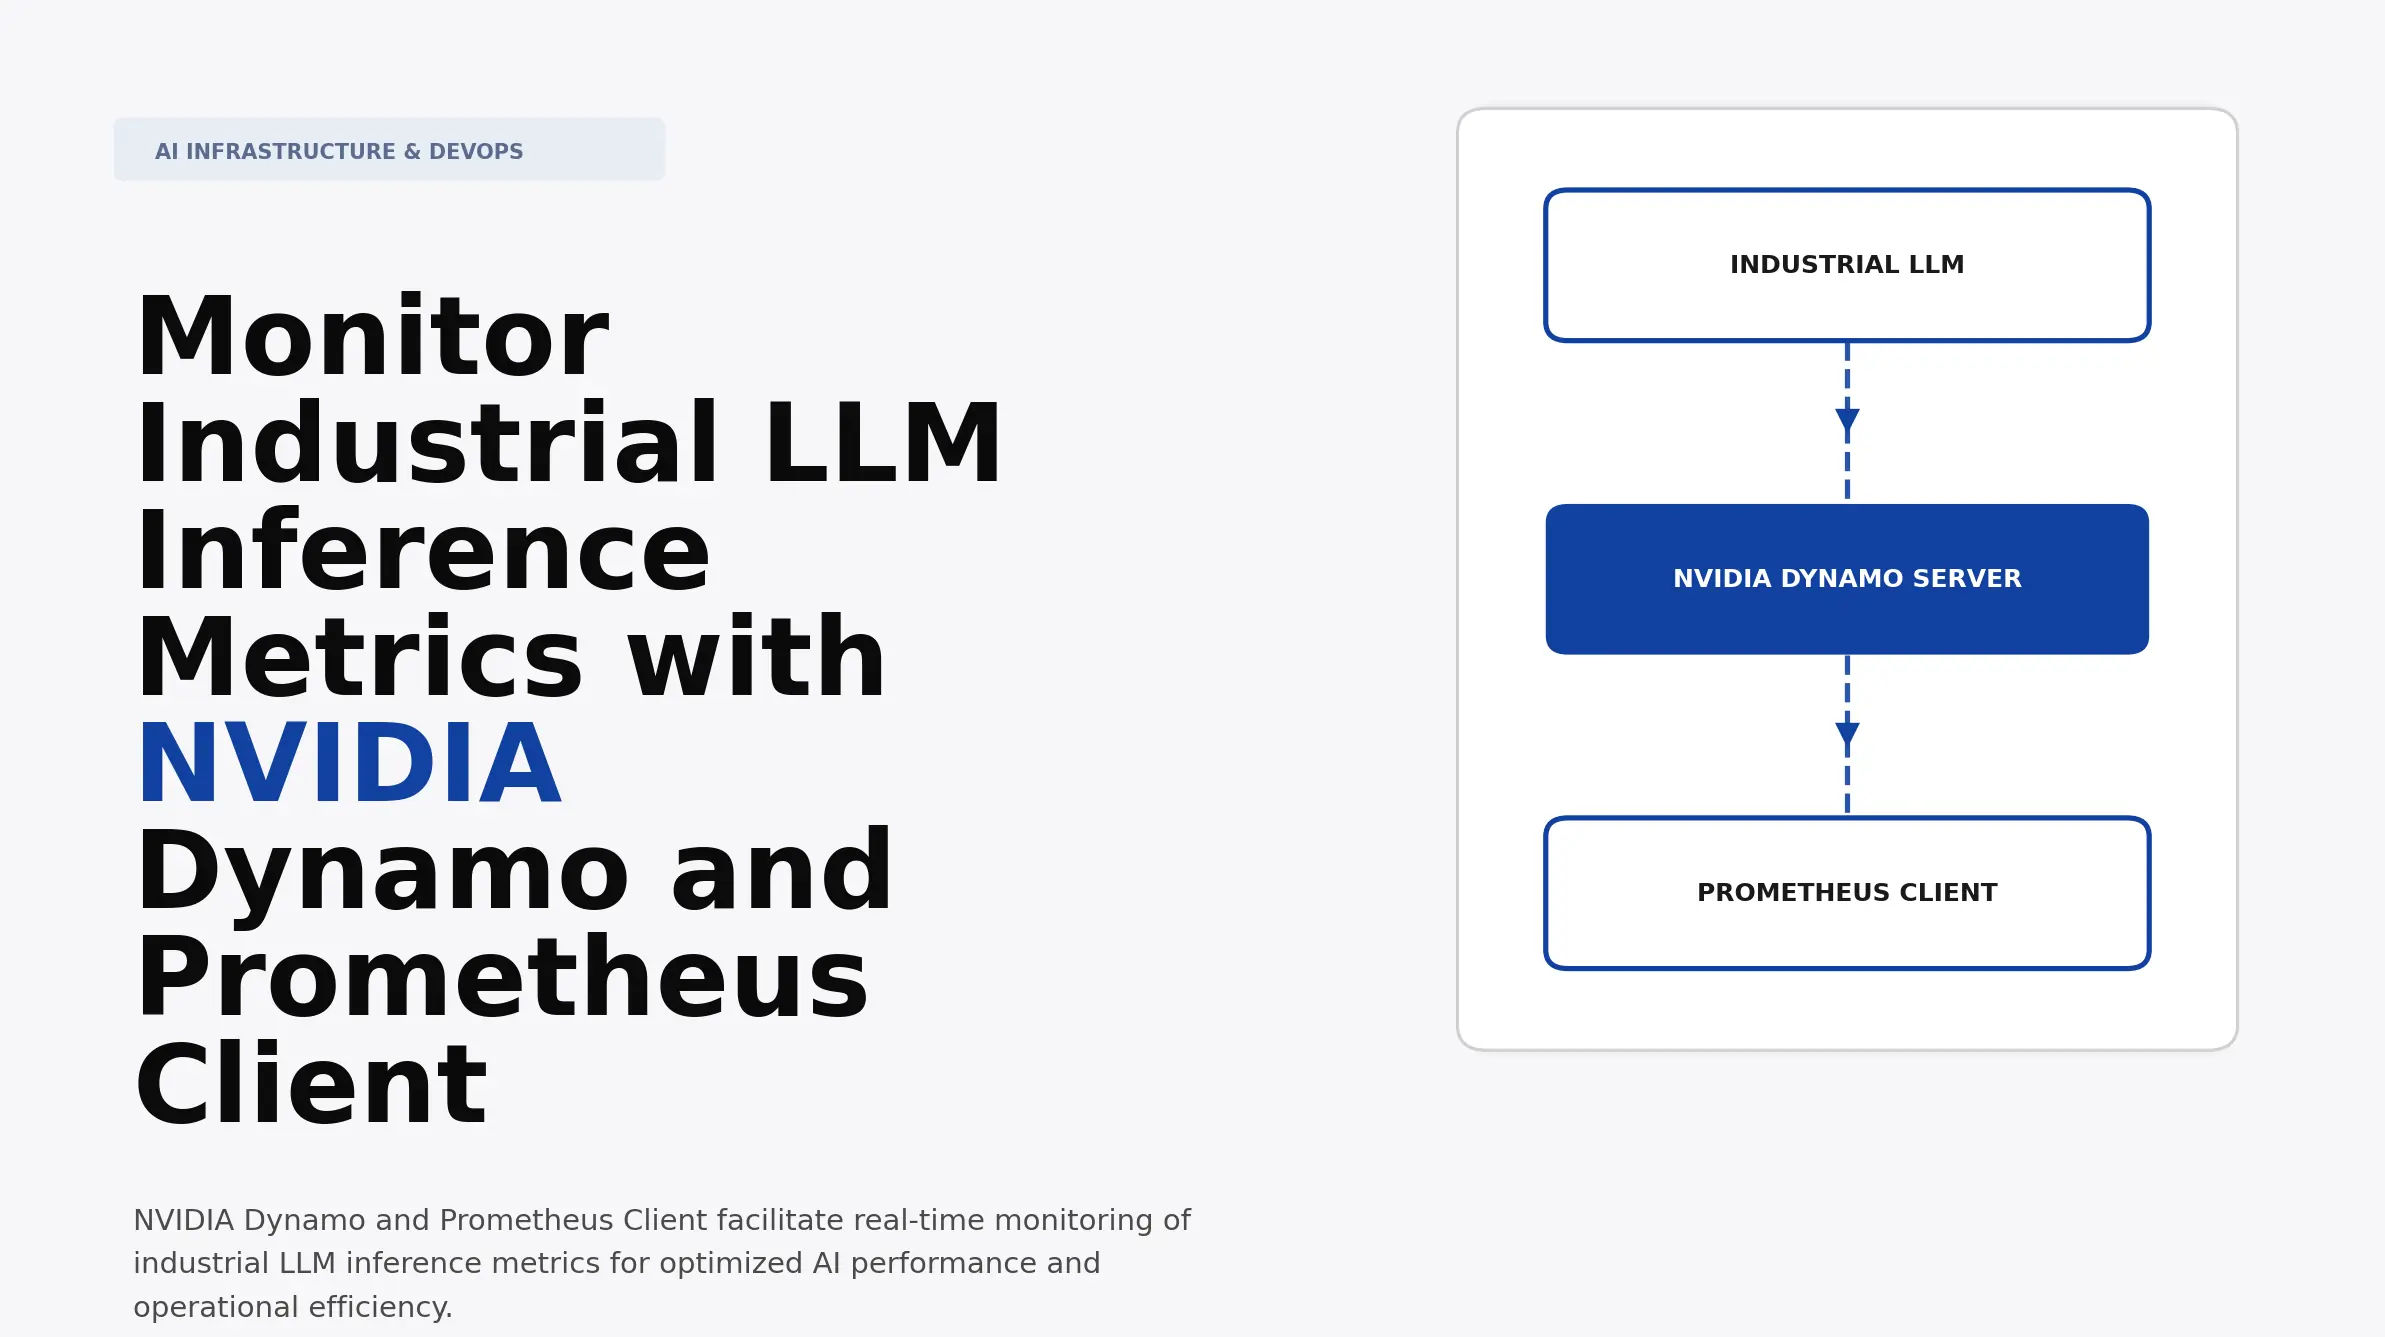
Monitor Industrial LLM Inference Metrics with NVIDIA Dynamo and ...
A guide to LLM inference and performance
LLM Inference Performance and Optimization on NVIDIA GB200 NVL72 S72503 ...
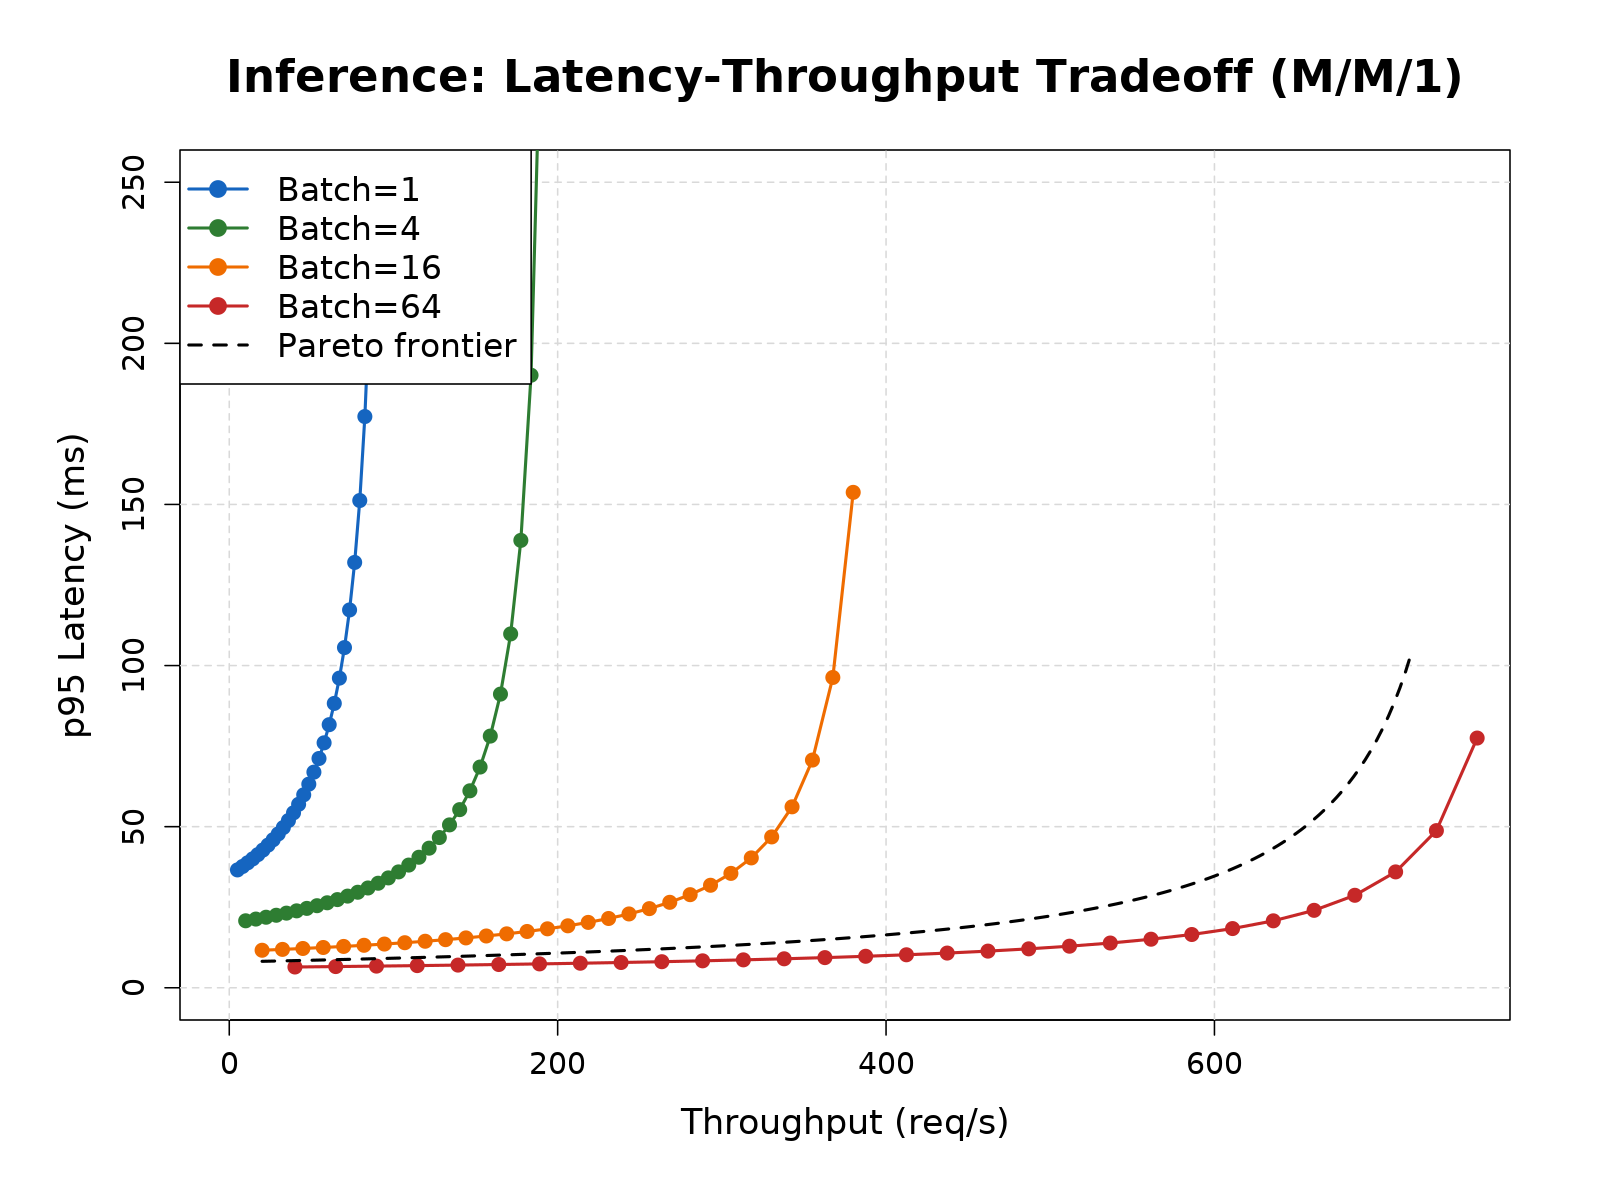
Inference Latency vs Throughput Tradeoff | MetricGate

LLM Inference Performance Benchmarking (Part 1)
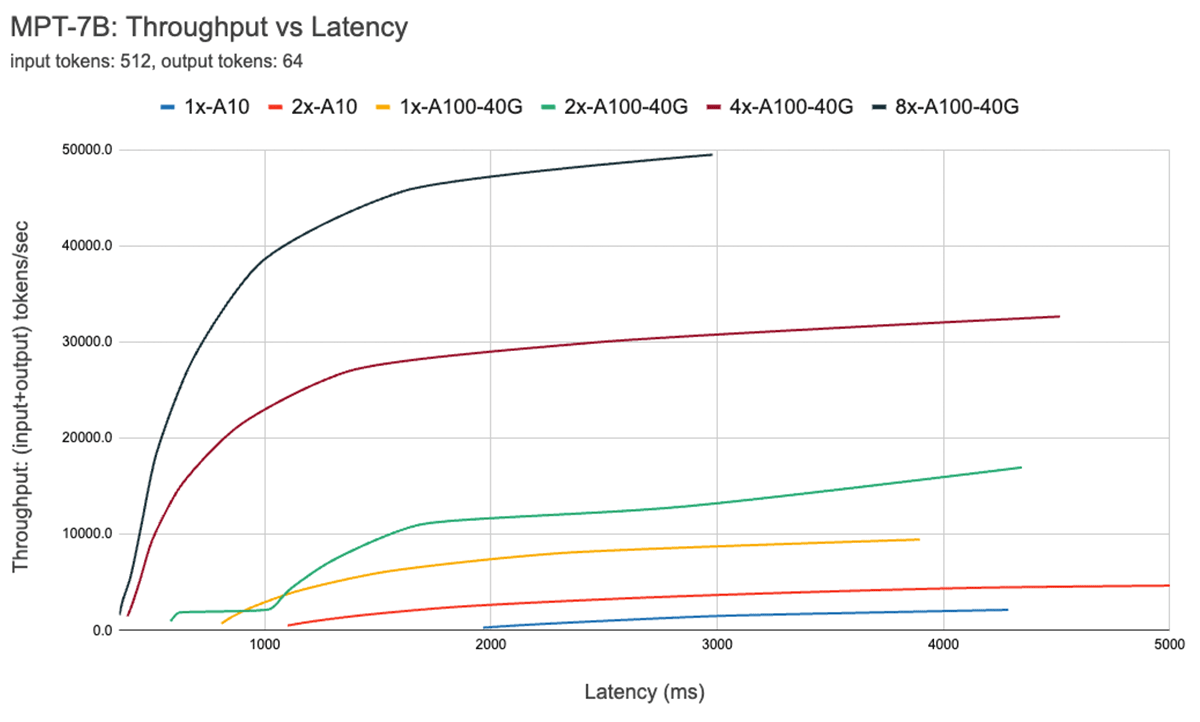
LLM Inference Performance Engineering: Best Practices | Databricks Blog

LLM Inference Scaling, Latency Collapse Simulation | Kaggle
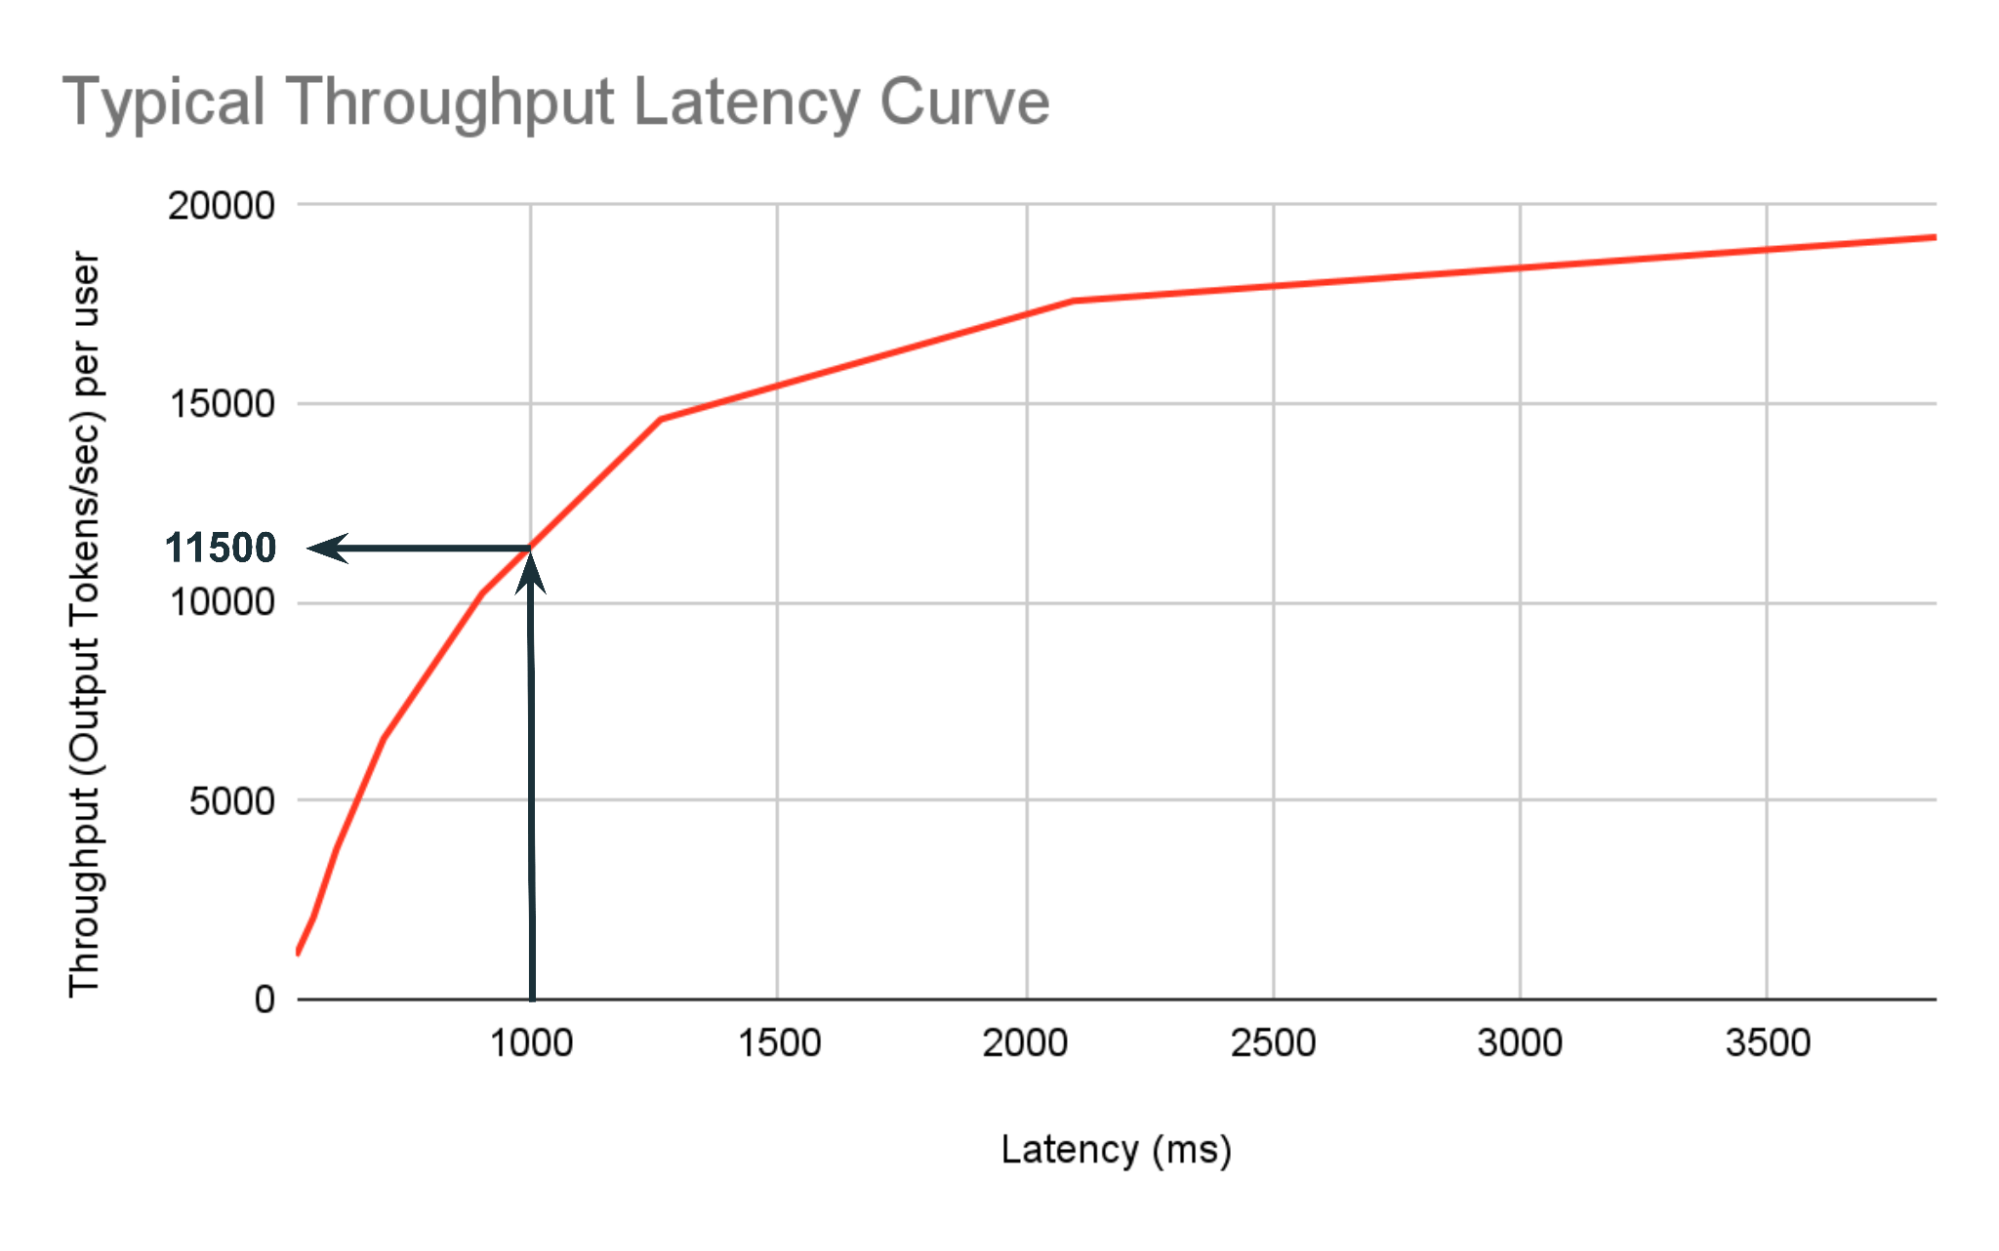
Fast, Secure and Reliable: Enterprise-grade LLM Inference | Databricks
Advertisement Space (336x280)
Challenges with Ultra-low Latency LLM Inference at Scale | Haytham ...
Defining LLM Performance Metrics (Latency, Throughput)
Latency vs Throughput — The Fundamental Trade-Off in LLM Serving ...

How do response time and latency factor into LLM evaluation?

How Does LLM Latency Challenge Real-time Applications? - AI and Machine ...

Learn How to Run an LLM Inference Performance Benchmark on NVIDIA GPUs ...

L-5. Latency & Throughput: Decoding Performance Metrics in System ...
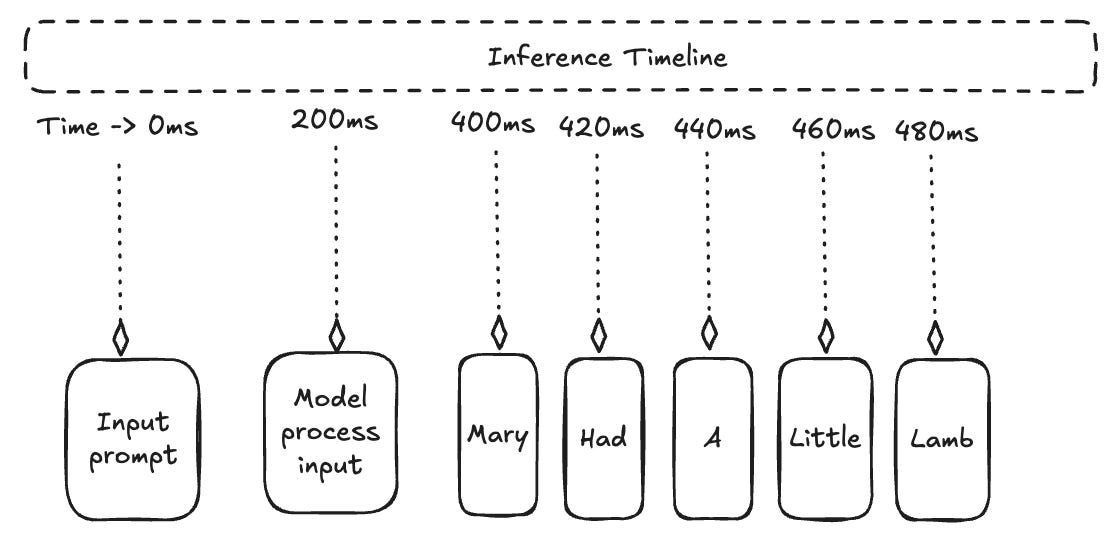
Part 2: Measuring LLM Inference Performance: Metrics, Tradeoffs, and ...
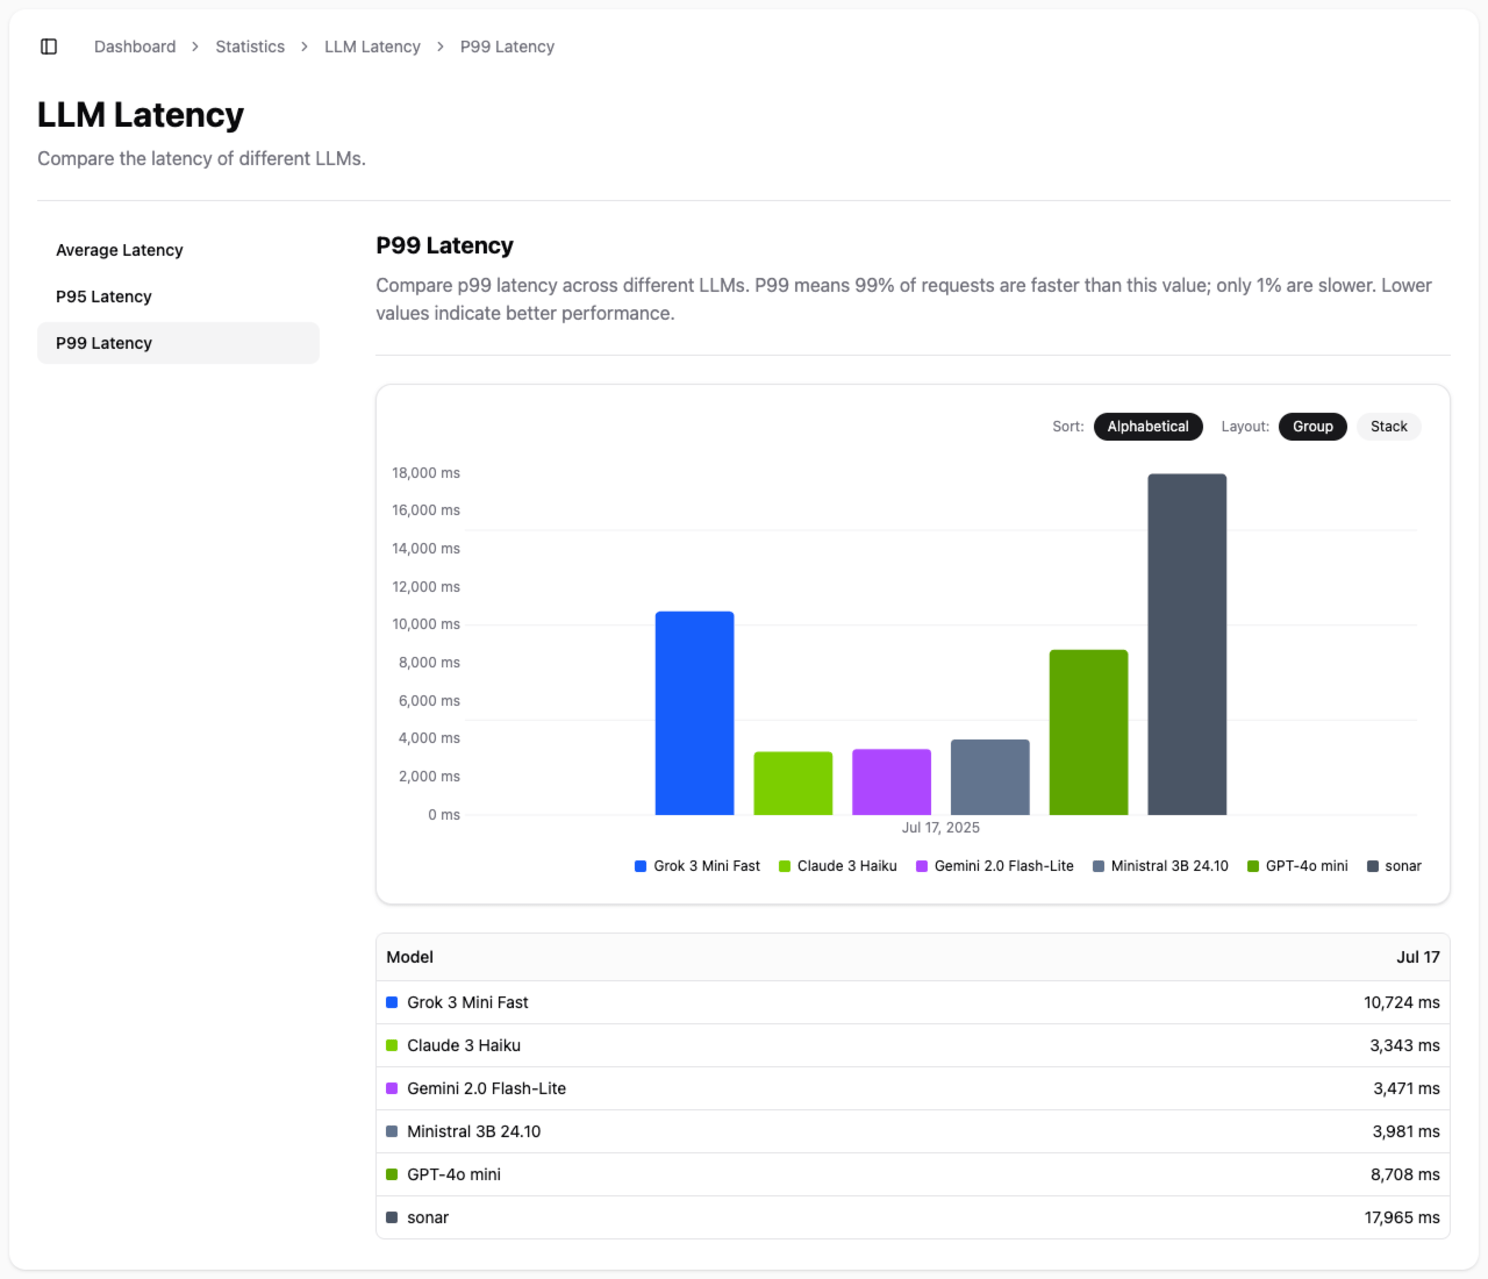
LLM Latency & Performance Monitoring | Nomodo.ai

Latency Monitoring Metrics - YouTube
Advertisement Space (336x280)
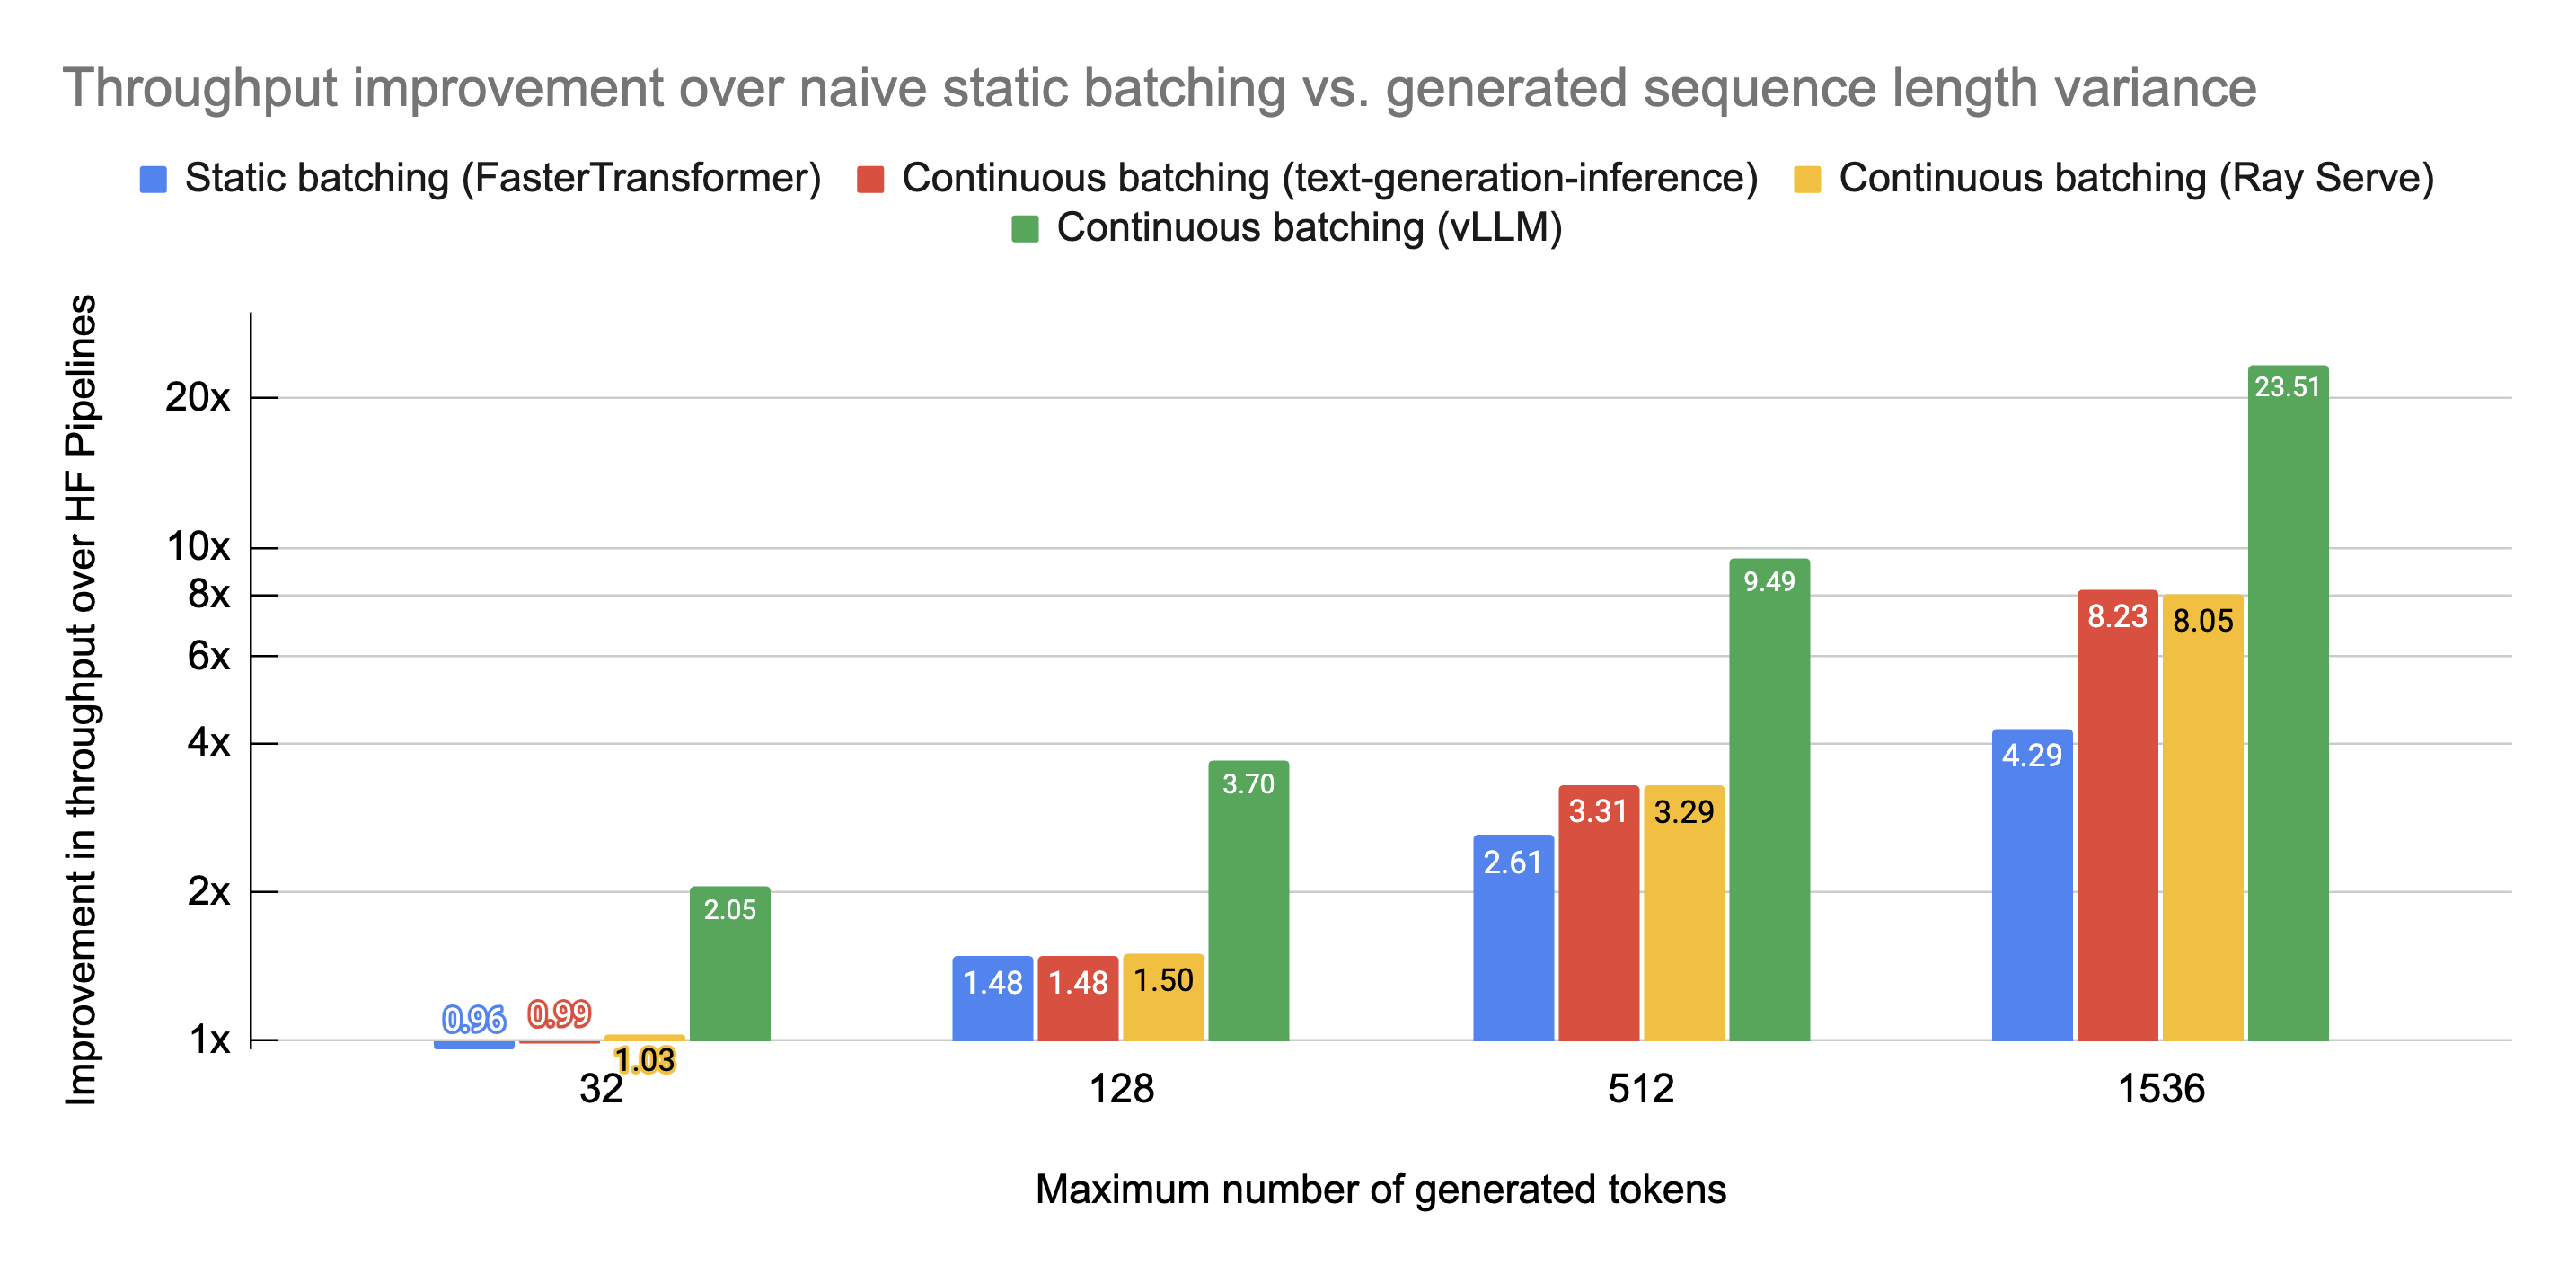
Scaling LLM inference with Ray and vLLM

Evaluating LLM inference performance on Red Hat OpenShift AI
A Guide to LLM Inference Performance Monitoring | Symbl.ai
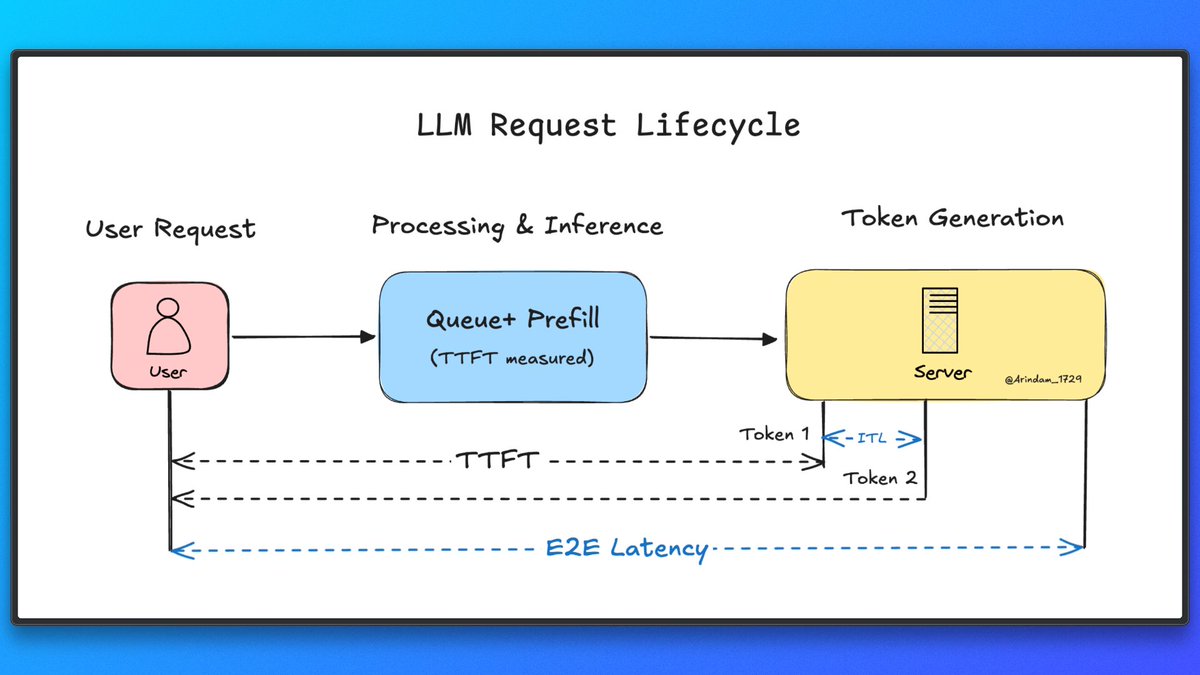
Most teams monitoring LLM inference treat latency as a single number ...

Towards Efficient LLM Inference via Collective and Adaptive Speculative ...

Run LLM inference at maximum throughput | Modal Docs