
Llm Inference Latency Metrics Explained Pdf Mean Latency

LLM Inference Latency Metrics Explained | PDF | Mean | Latency ...

LLM Inference Performance: Latency and Throughput Metrics - YouTube
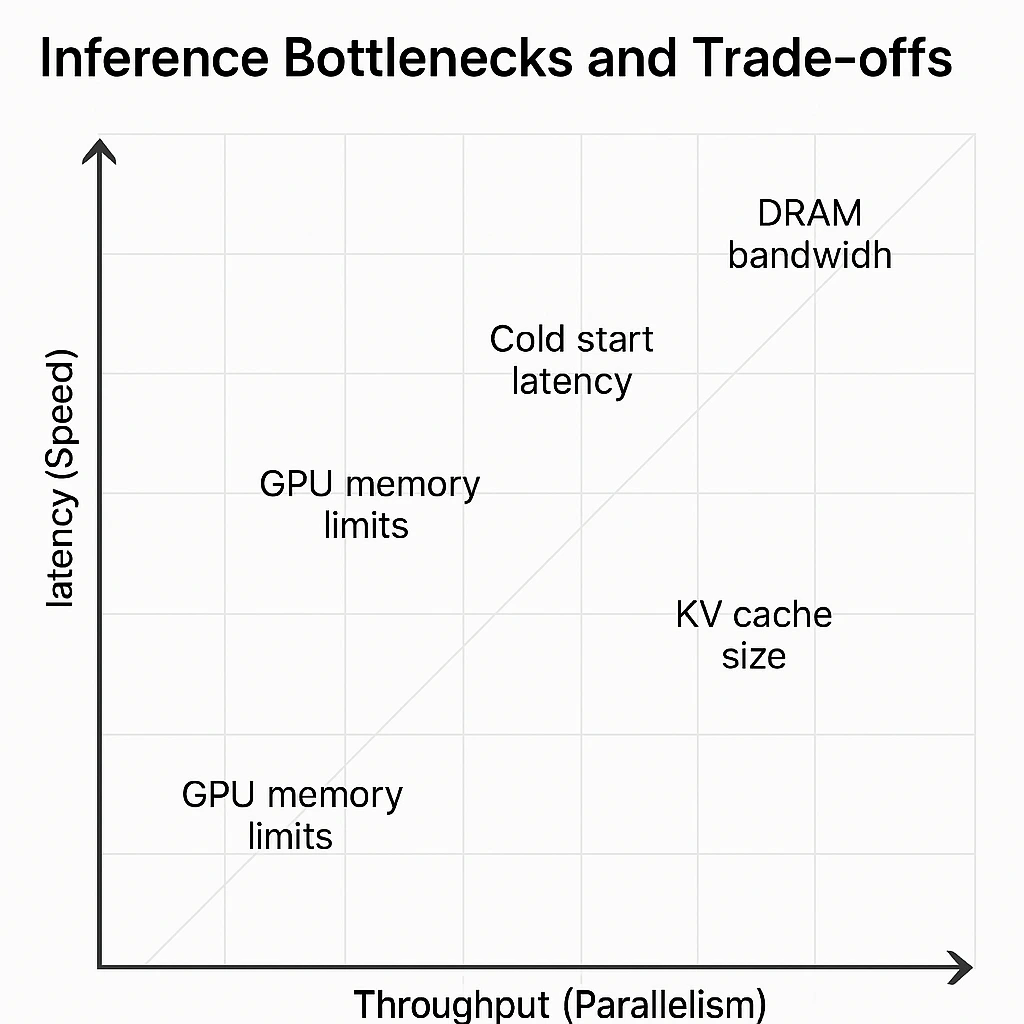
What Is LLM Inference? Process, Latency & Examples Explained (2026)
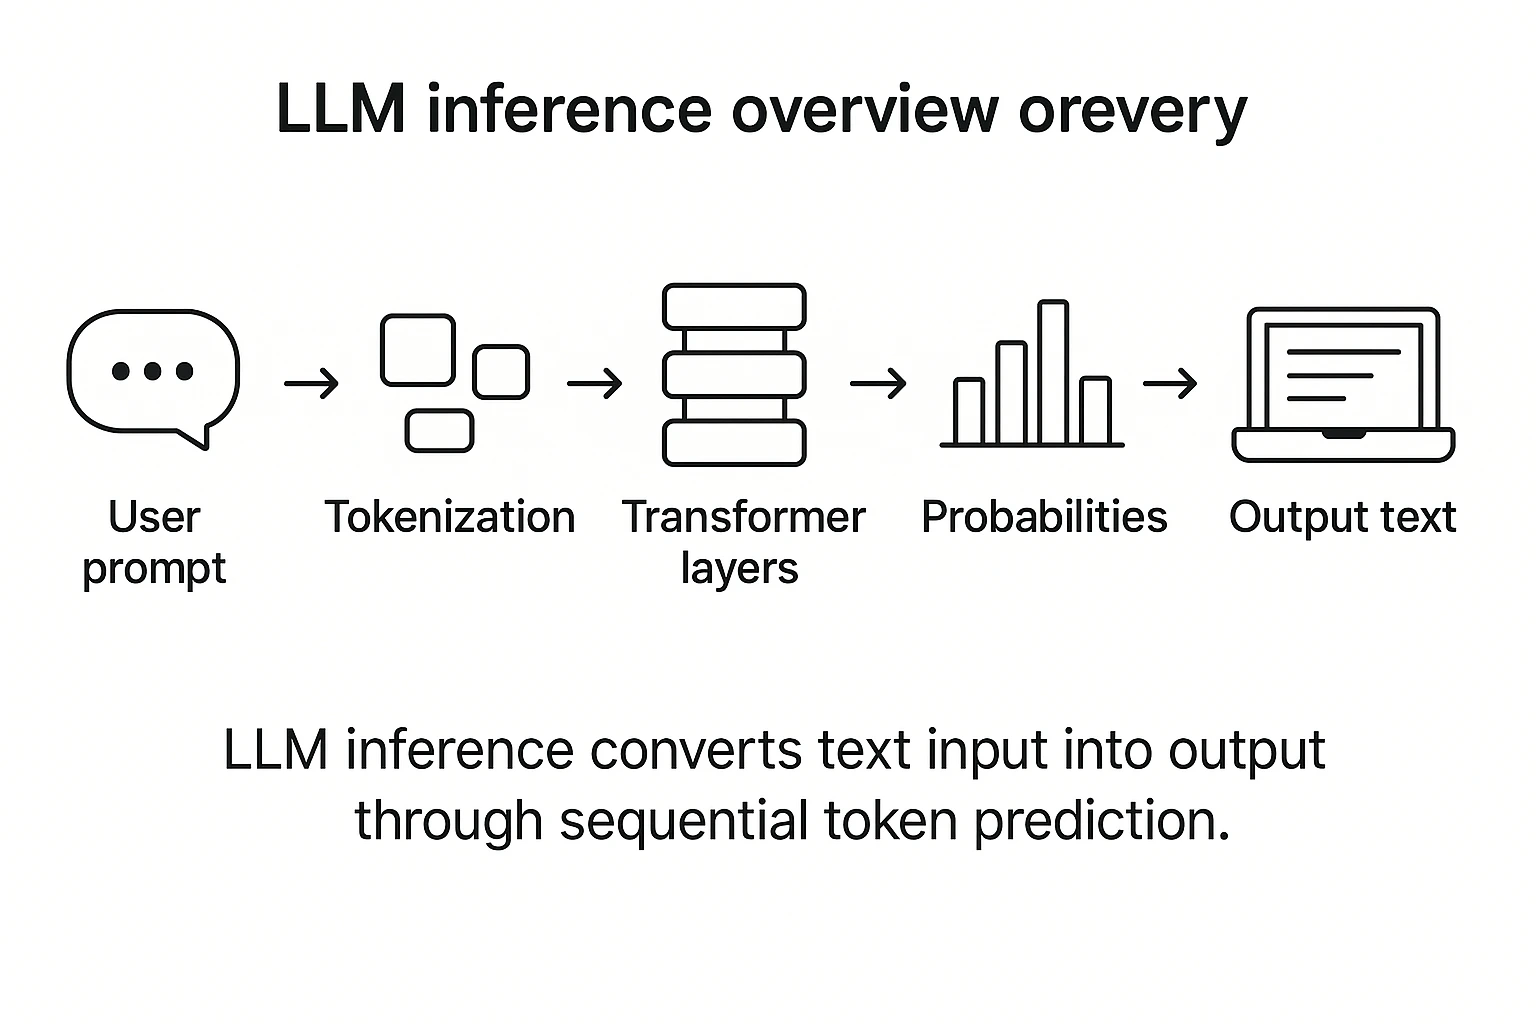
What Is LLM Inference? Process, Latency & Examples Explained (2026)
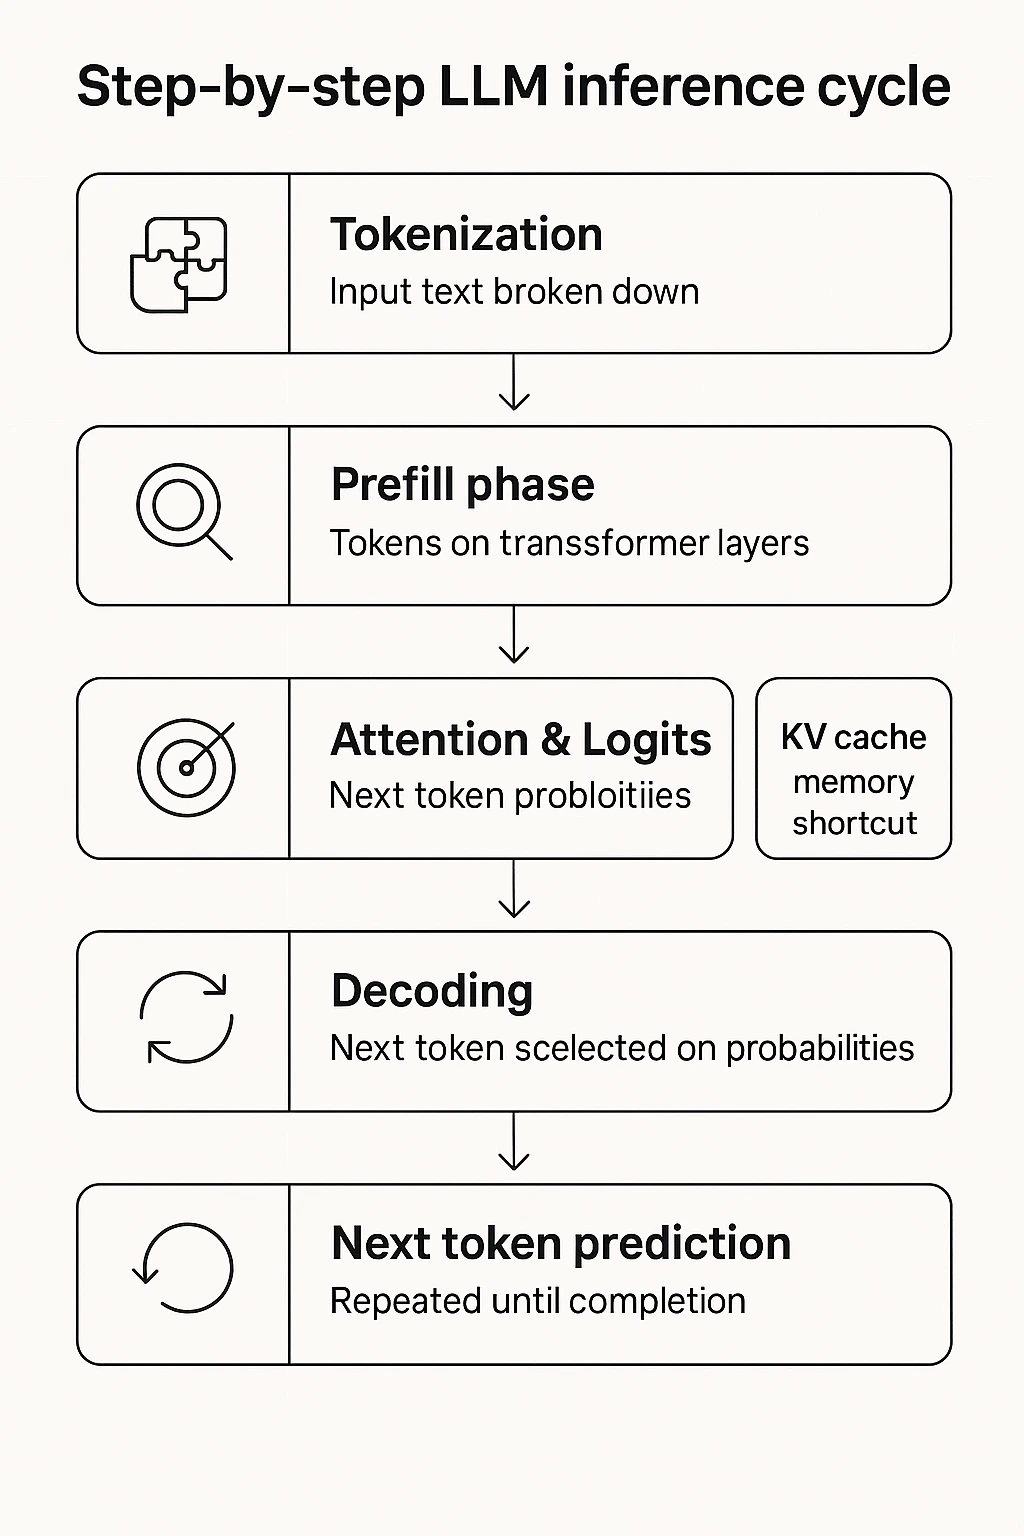
What Is LLM Inference? Process, Latency & Examples Explained (2026)

Cold Start Latency In LLM Inference: Causes, Metrics & Fixes

LLM Inference Scaling, Latency Collapse Simulation | Kaggle
LLM Inference SLO Engineering: TTFT, ITL, and P99 Latency Budgets for ...
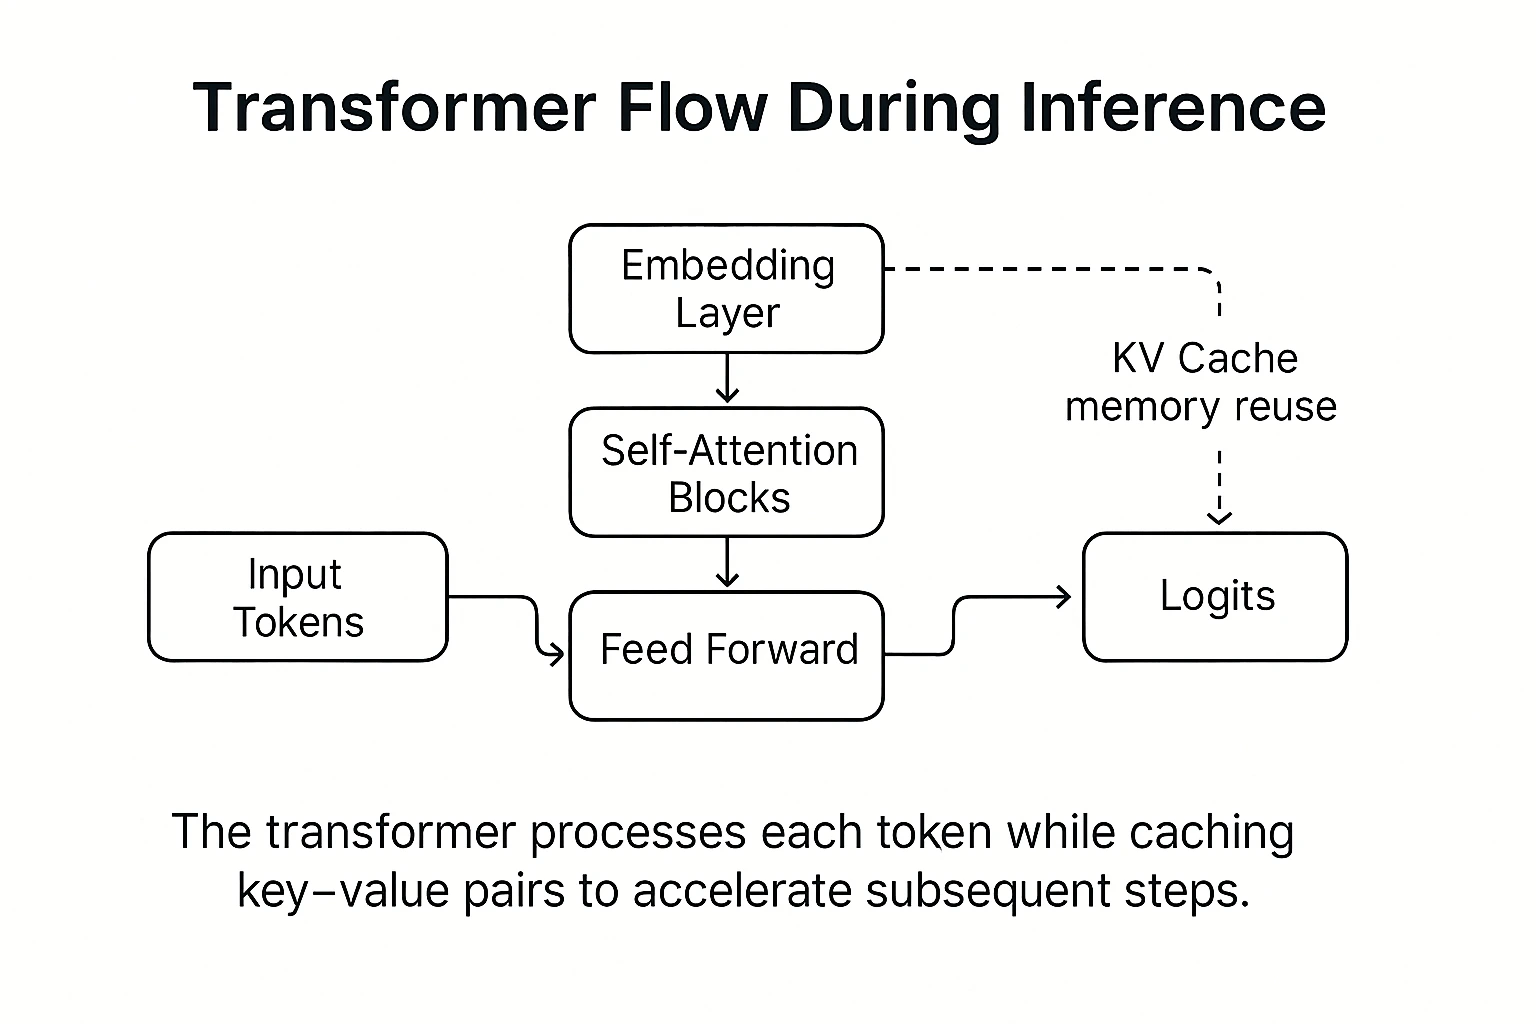
What Is LLM Inference? Process, Latency & Examples Explained (2026)

Improving LLM Inference Latency on CPUs with Model Quantization ...
Advertisement Space (300x250)
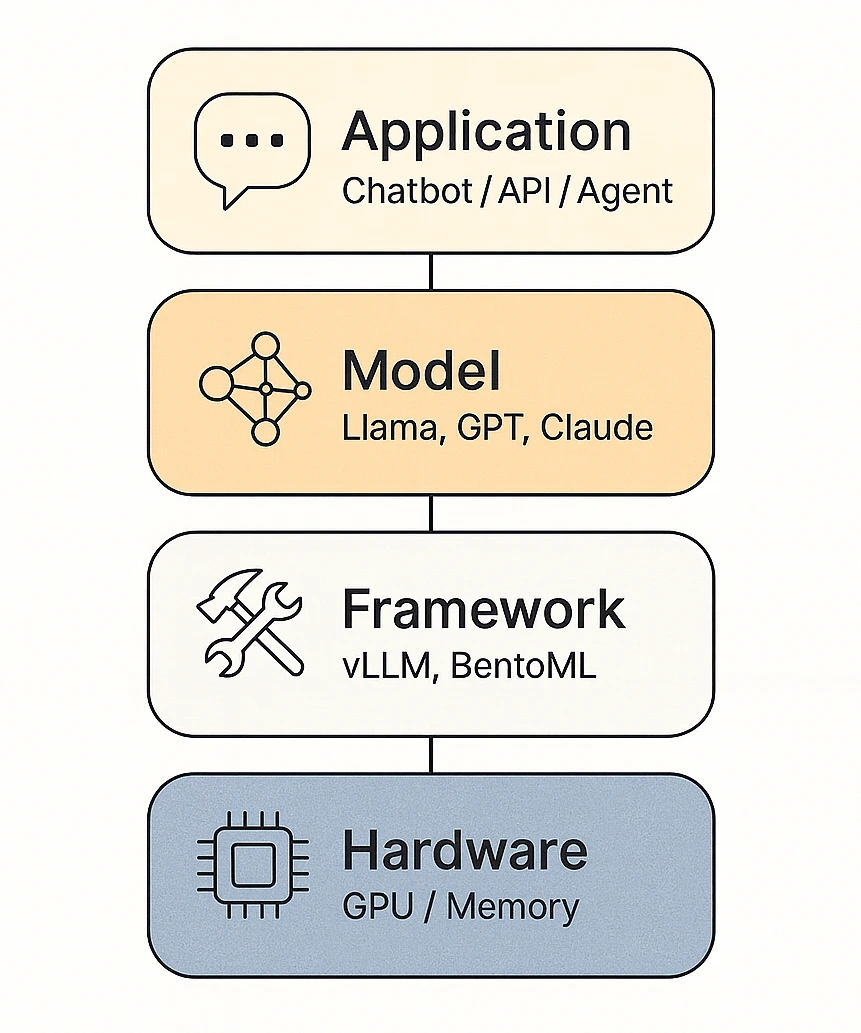
What Is LLM Inference? Process, Latency & Examples Explained (2026)
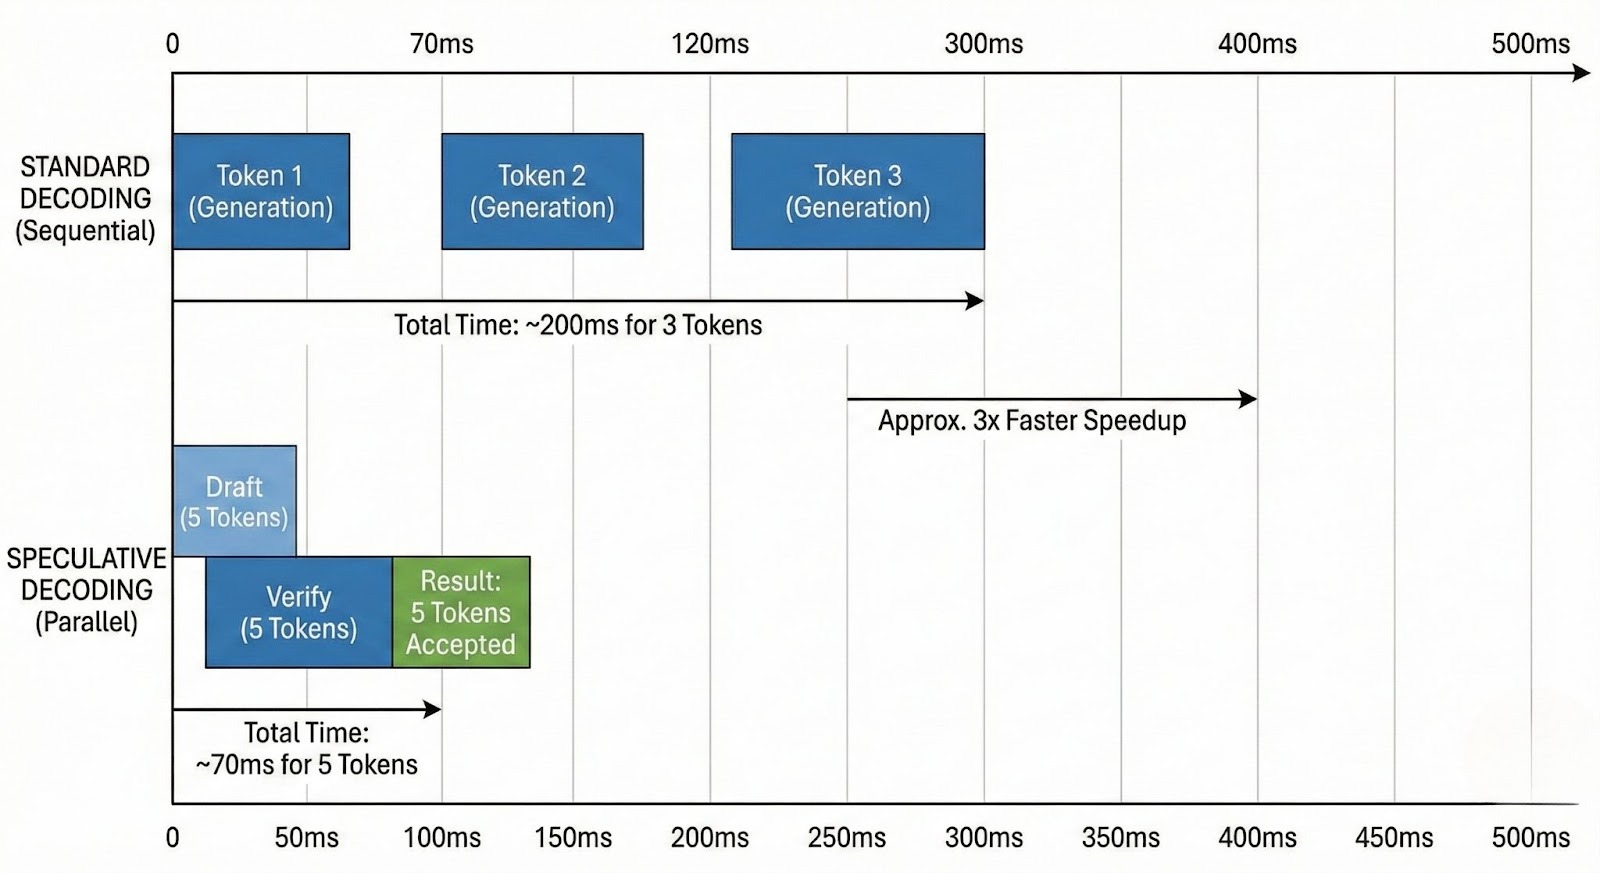
How to Achieve Ultra-Low Latency LLM Inference in the Cloud

Measuring LLM Inference Efficiency: Four Core Metrics Explained

High-Throughput LLM Inference Optimization | PDF | Parallel Computing ...
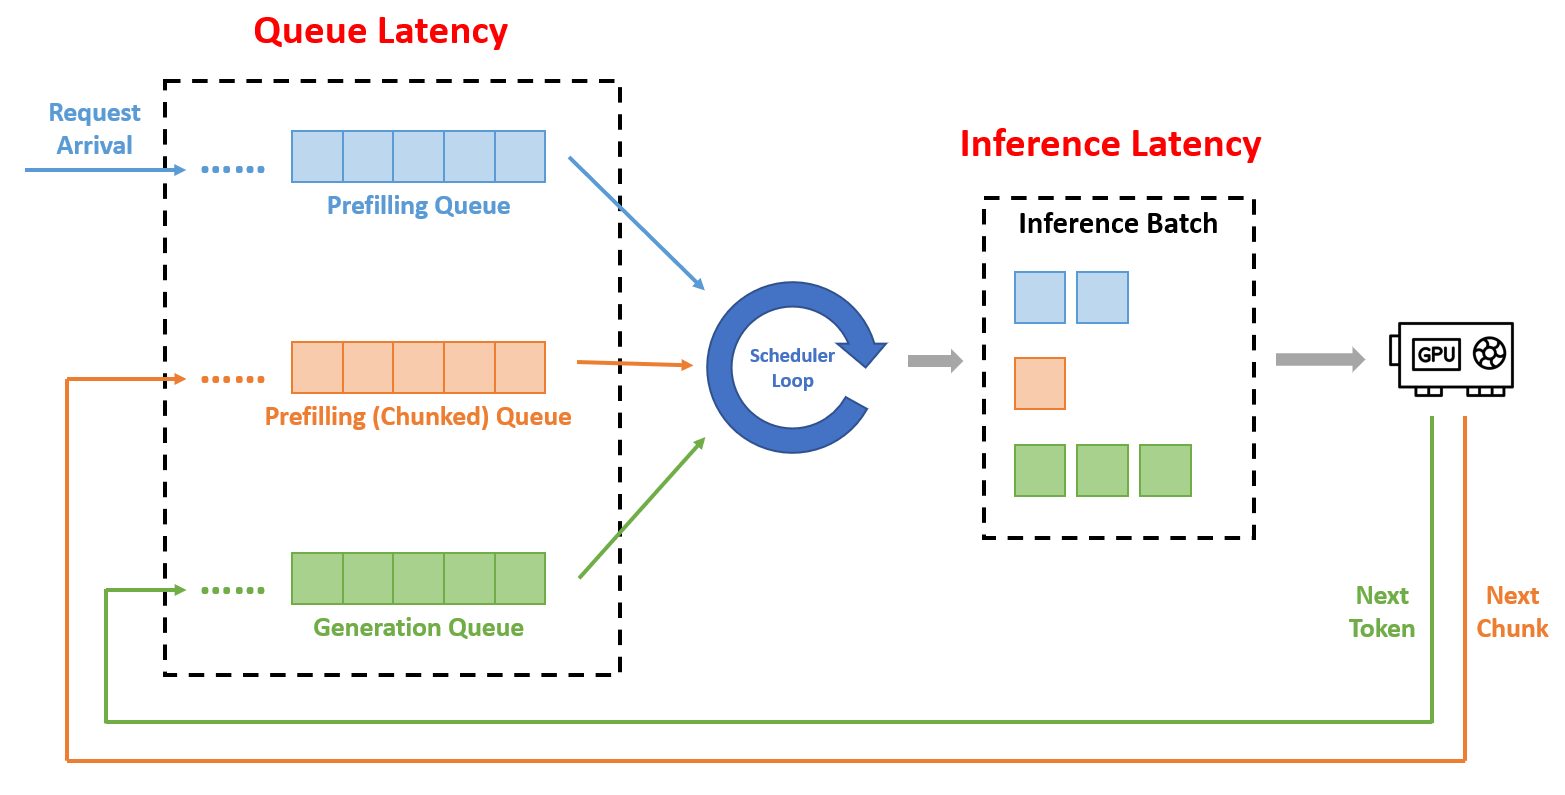
Latency in LLM Serving | Monsoon's Blog

3-Part Series: LLM Latency in Production (Part 1)
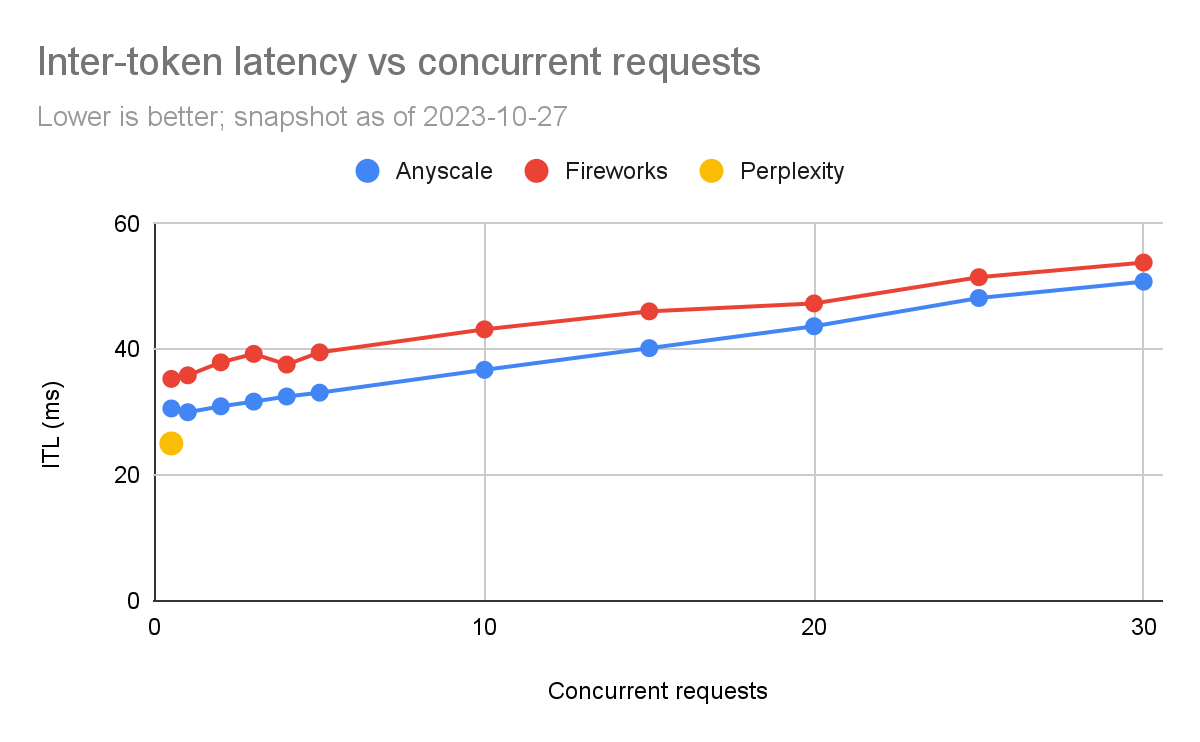
Reproducible Performance Metrics for LLM inference
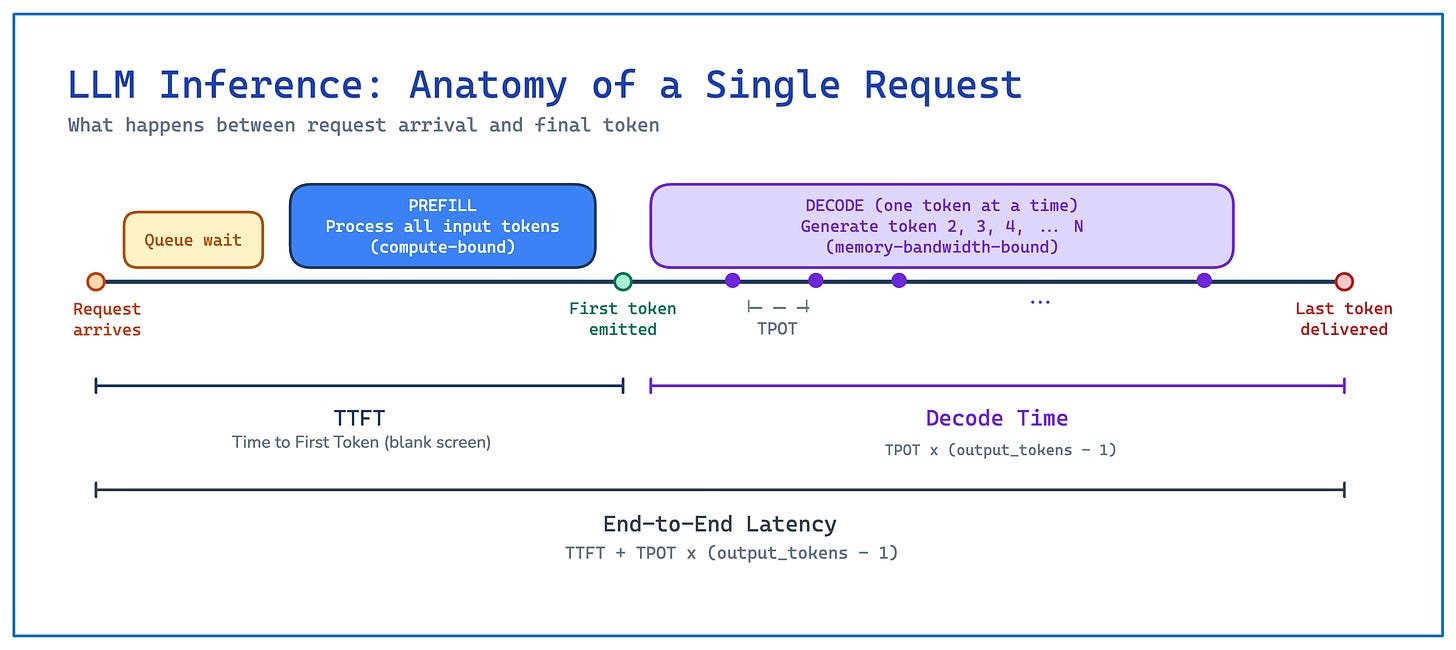
LLM Inference Metrics: TTFT, TPOT, TPS Explained
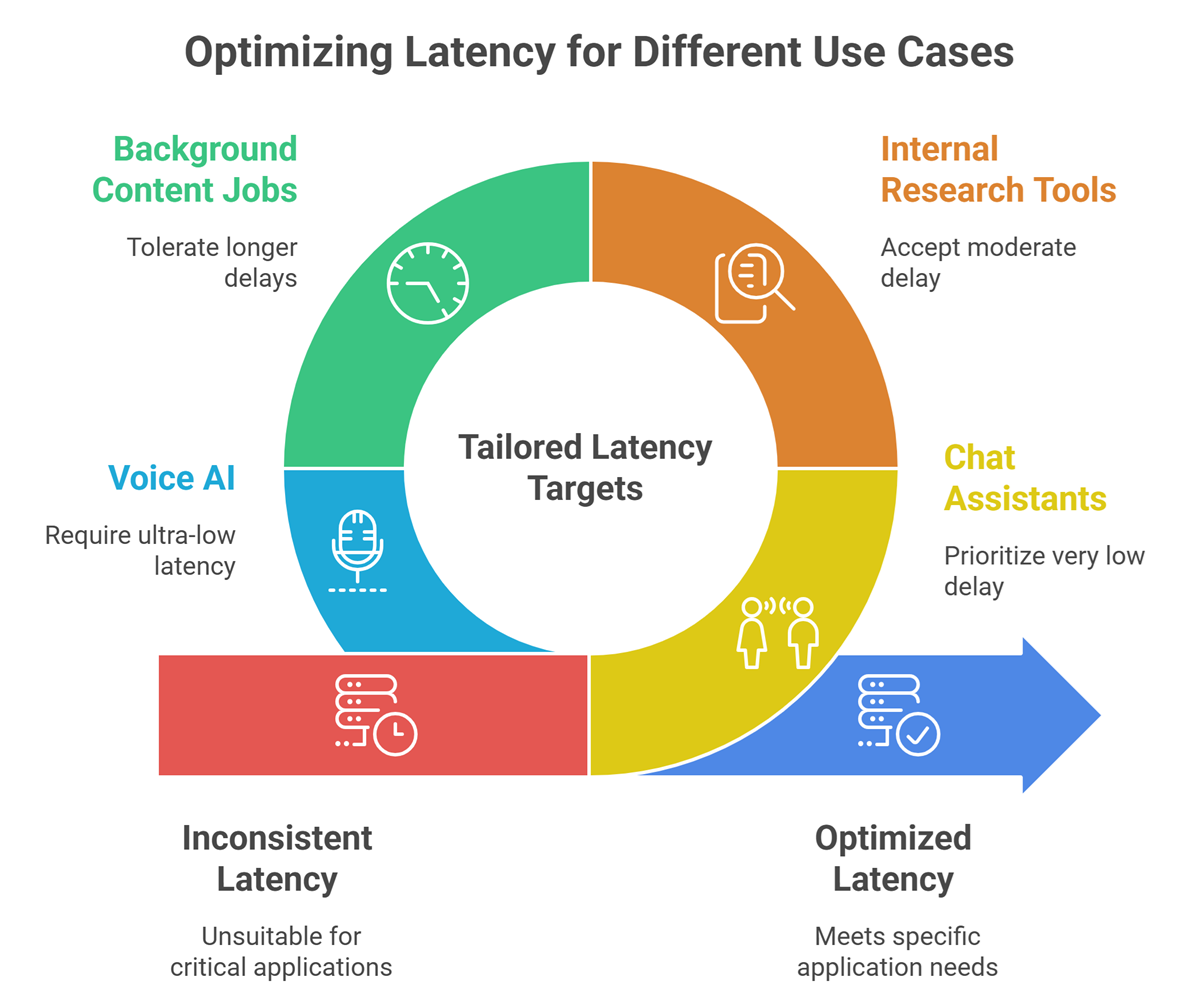
LLM Latency Optimization: Speed Up AI Responses Fast » AIML Insights

LLM Inference Metrics: TTFT, TPOT, TPS Explained
Advertisement Space (336x280)

How do response time and latency factor into LLM evaluation?

(PDF) Optimizing LLM Latency and Throughput for Interactive Web Interfaces

LLM Latency Benchmark Report
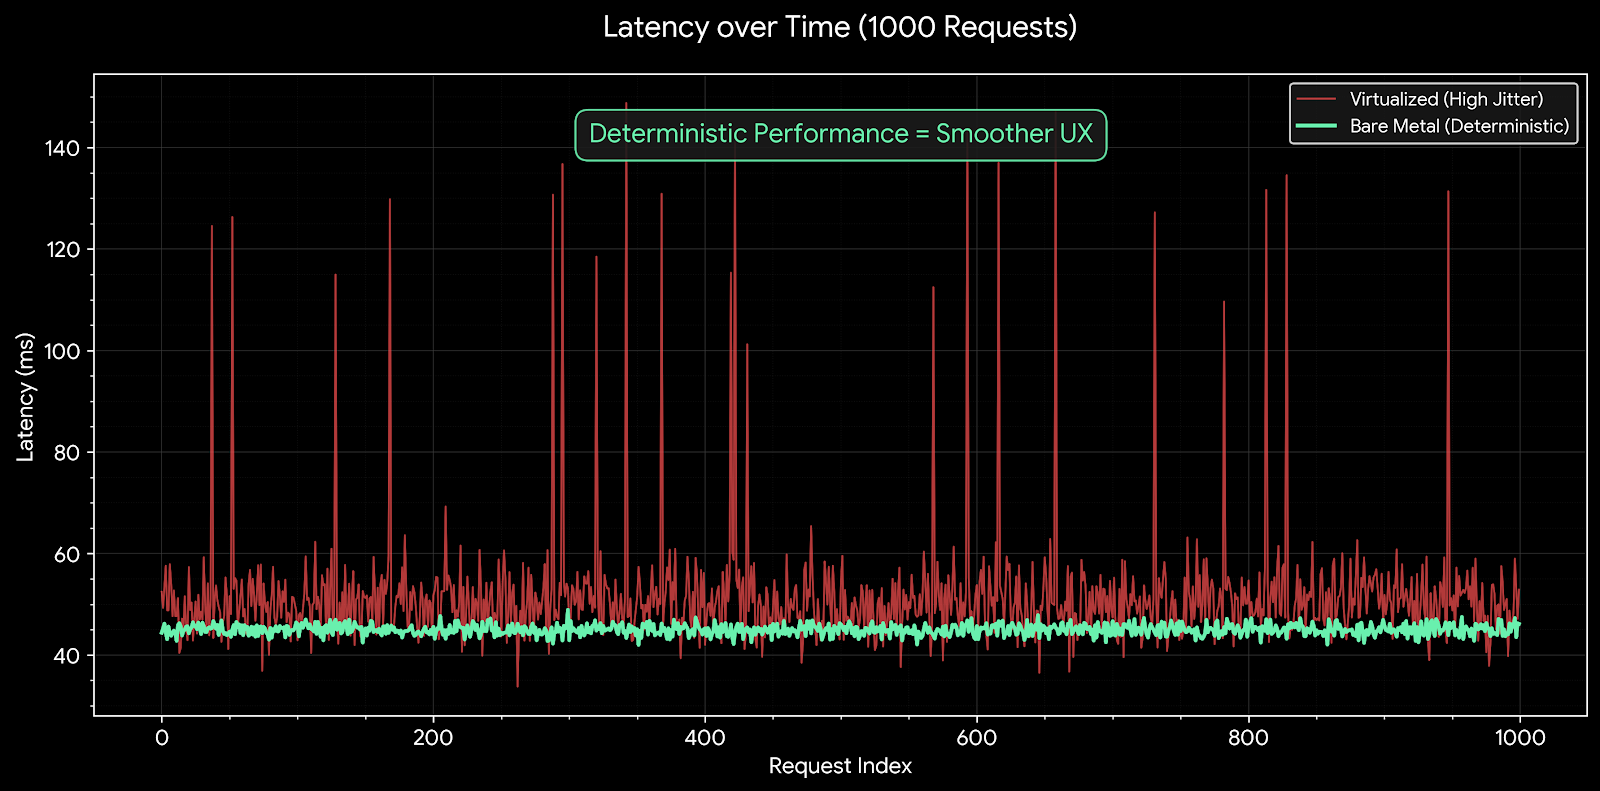
Lowest Latency AI Inference Provider for Open-Source LLMs

How SageMaker Enhances Salesforce Einstein’s LLM Latency and Throughput
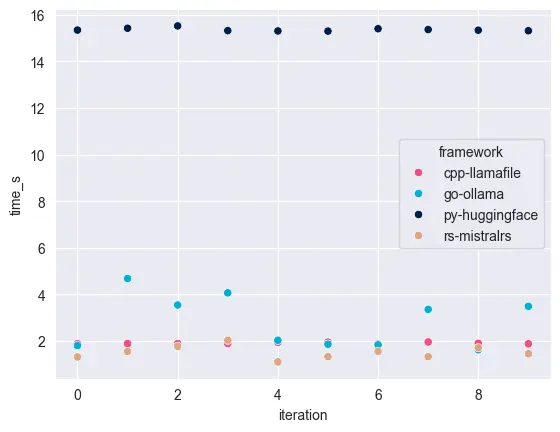
LLM serving latency benchmark

REAL data about LLM price and latency - USLUCK

LLM Latency Benchmark Report
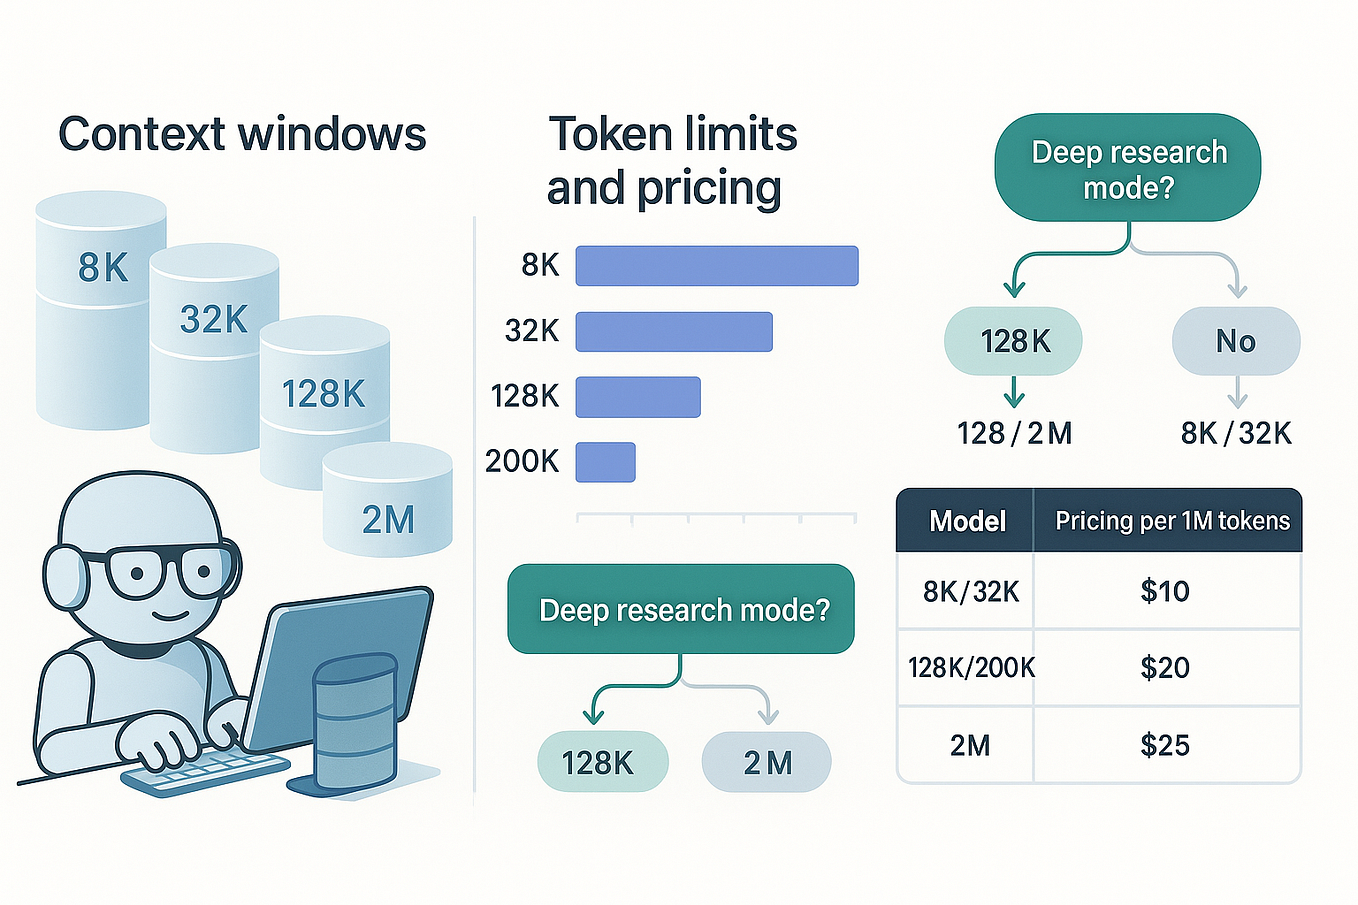
Demystifying LLM Benchmarks: Tokens, Quality, Latency & Throughput | by ...

Latency profile of the LLM with the prompt. The hardware here is a ...
Advertisement Space (336x280)
Latency Measurement: Definition & Techniques for NPUs | Inference Systems
LLM API Latency Compared: Speed Benchmarks 2026 — APIpulse
How do response time and latency factor into LLM evaluation?
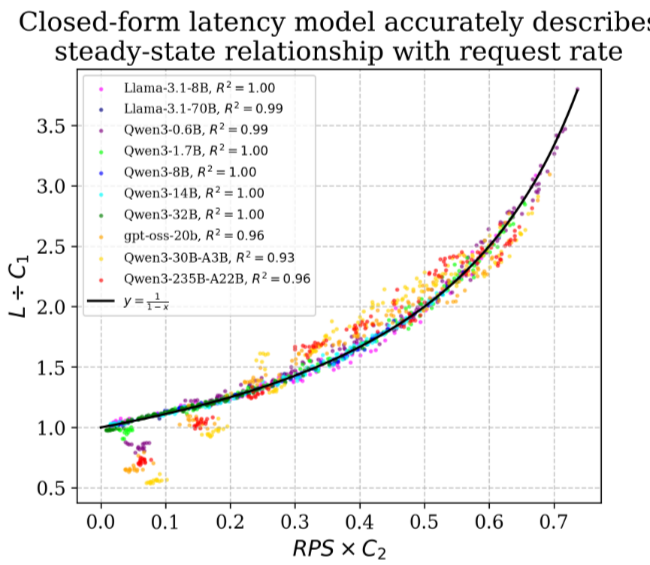
[论文评述] An Interpretable Latency Model for Speculative Decoding in LLM ...
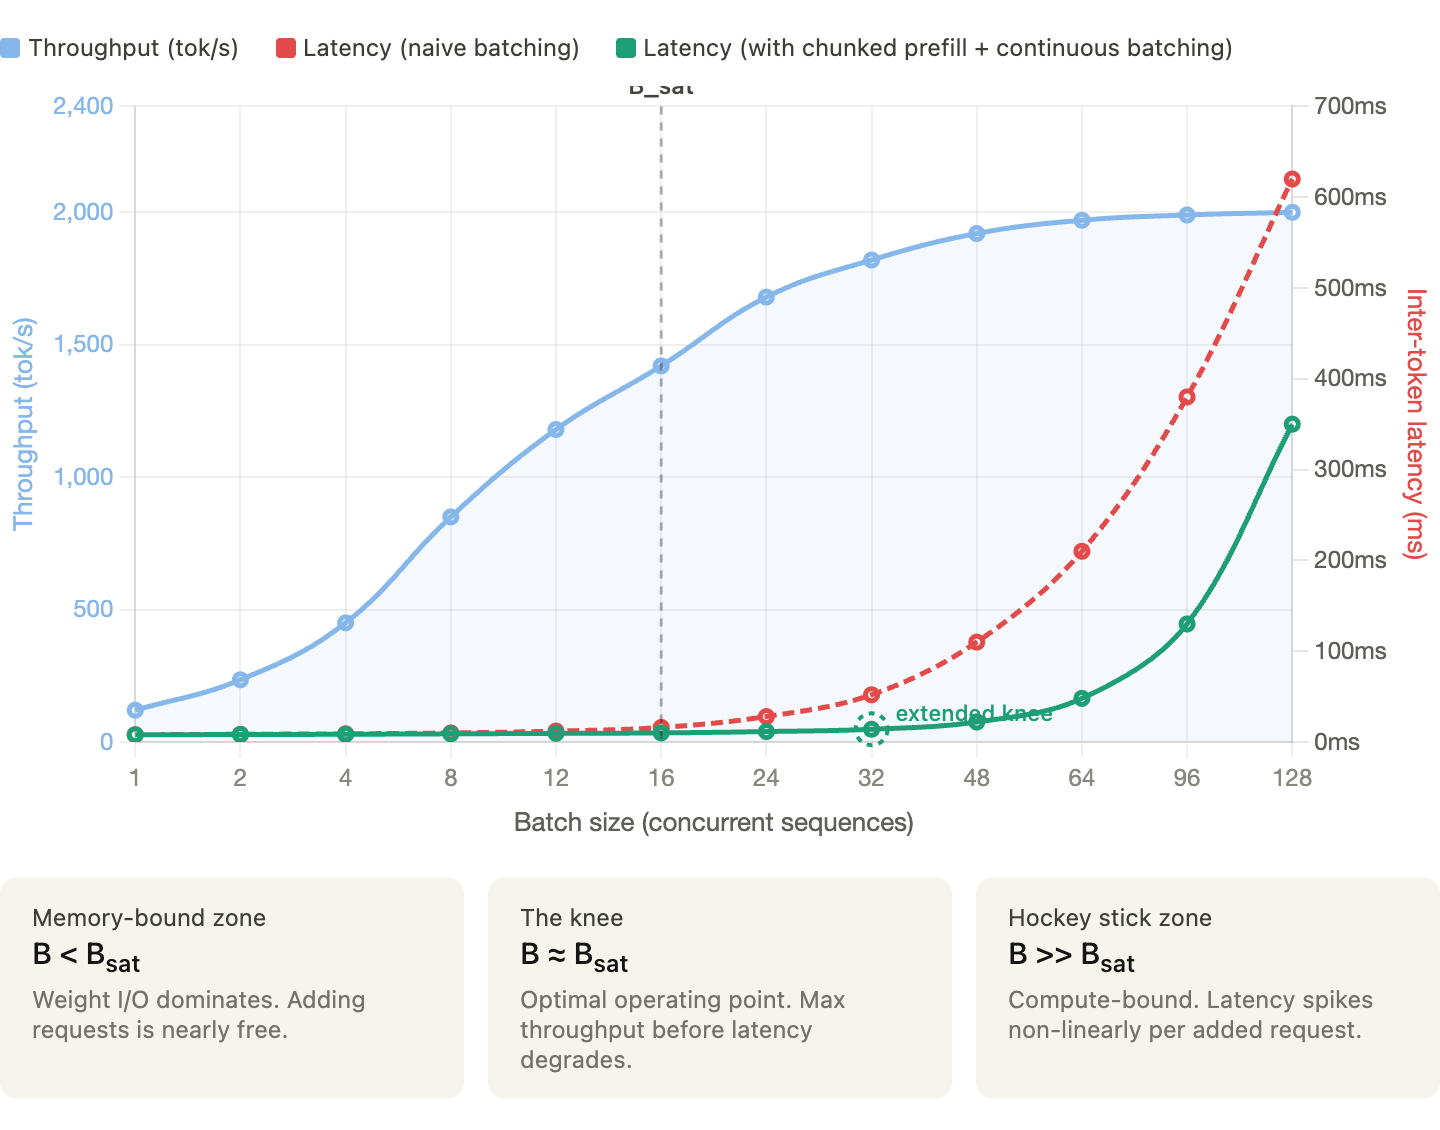
The LLM Inference Trilemma: Throughput, Latency, Cost | DigitalOcean

LLM in a flash: Efficient LLM Inference with Limited Memory