
Deploy Flashinfer On Gpu Cloud Llm Inference Kernels For Vllm And
Deploy FlashInfer on GPU Cloud: LLM Inference Kernels for vLLM and ...
vLLM Model Runner V2 on GPU Cloud: Deploy MRV2 for Faster LLM Inference ...
Modular MAX and Mojo on GPU Cloud: Deploy an LLM Inference Engine That ...
LLM Inference Router on GPU Cloud: Smart Model Routing for Cost and ...
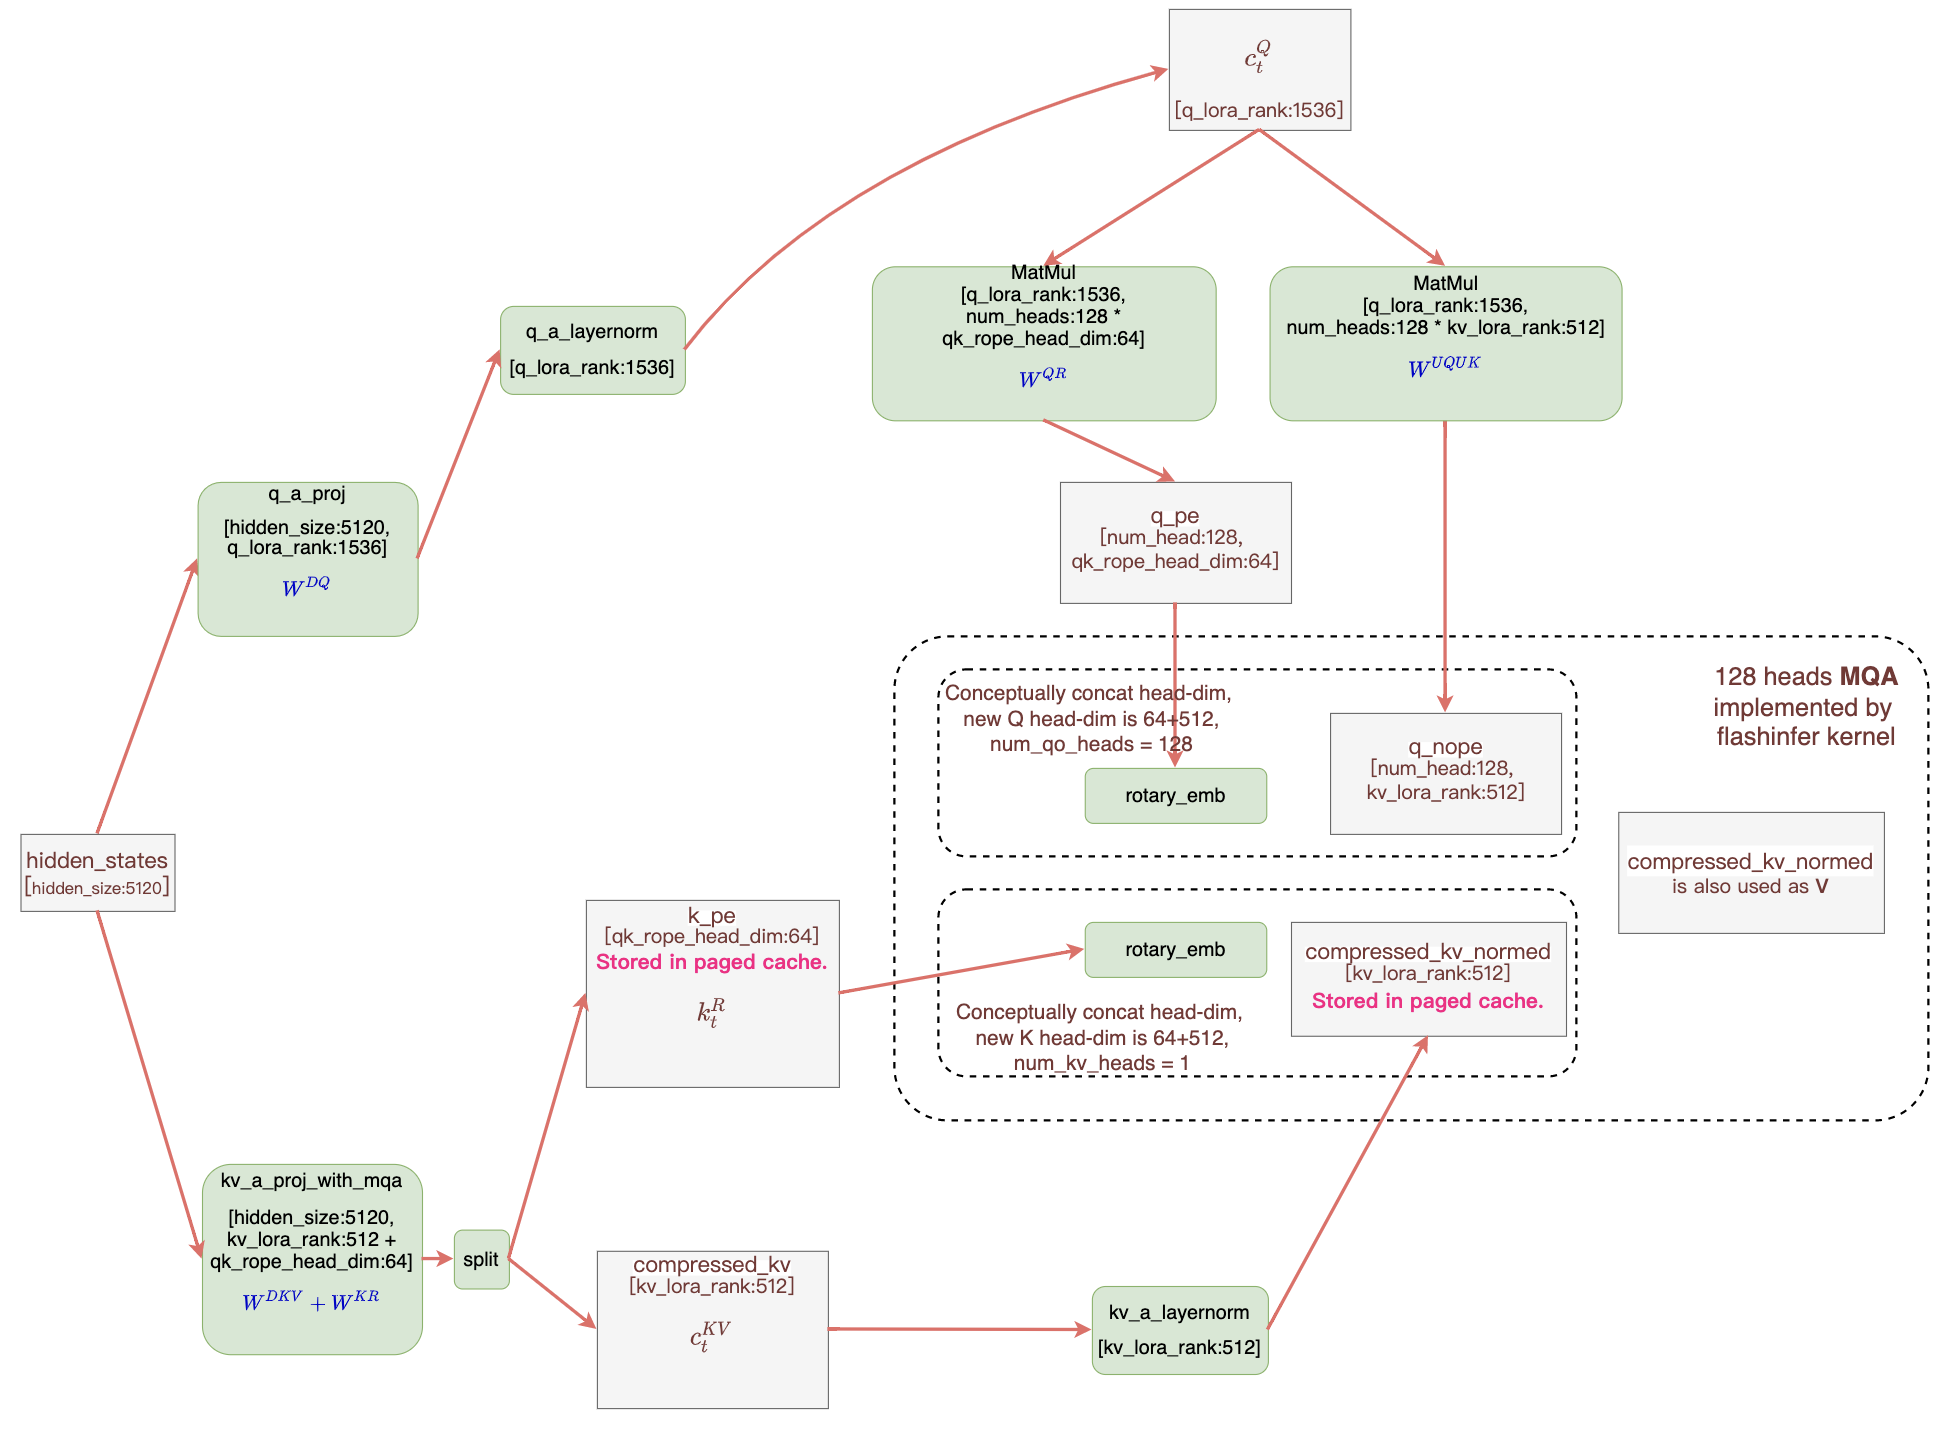
FlashInfer 0.2 - Efficient and Customizable Kernels for LLM Inference ...
FlashInfer 0.2 - Efficient and Customizable Kernels for LLM Inference ...

vLLM Review: High-Performance LLM Inference Engine for GPU ...

[论文评述] SpecOffload: Unlocking Latent GPU Capacity for LLM Inference on ...
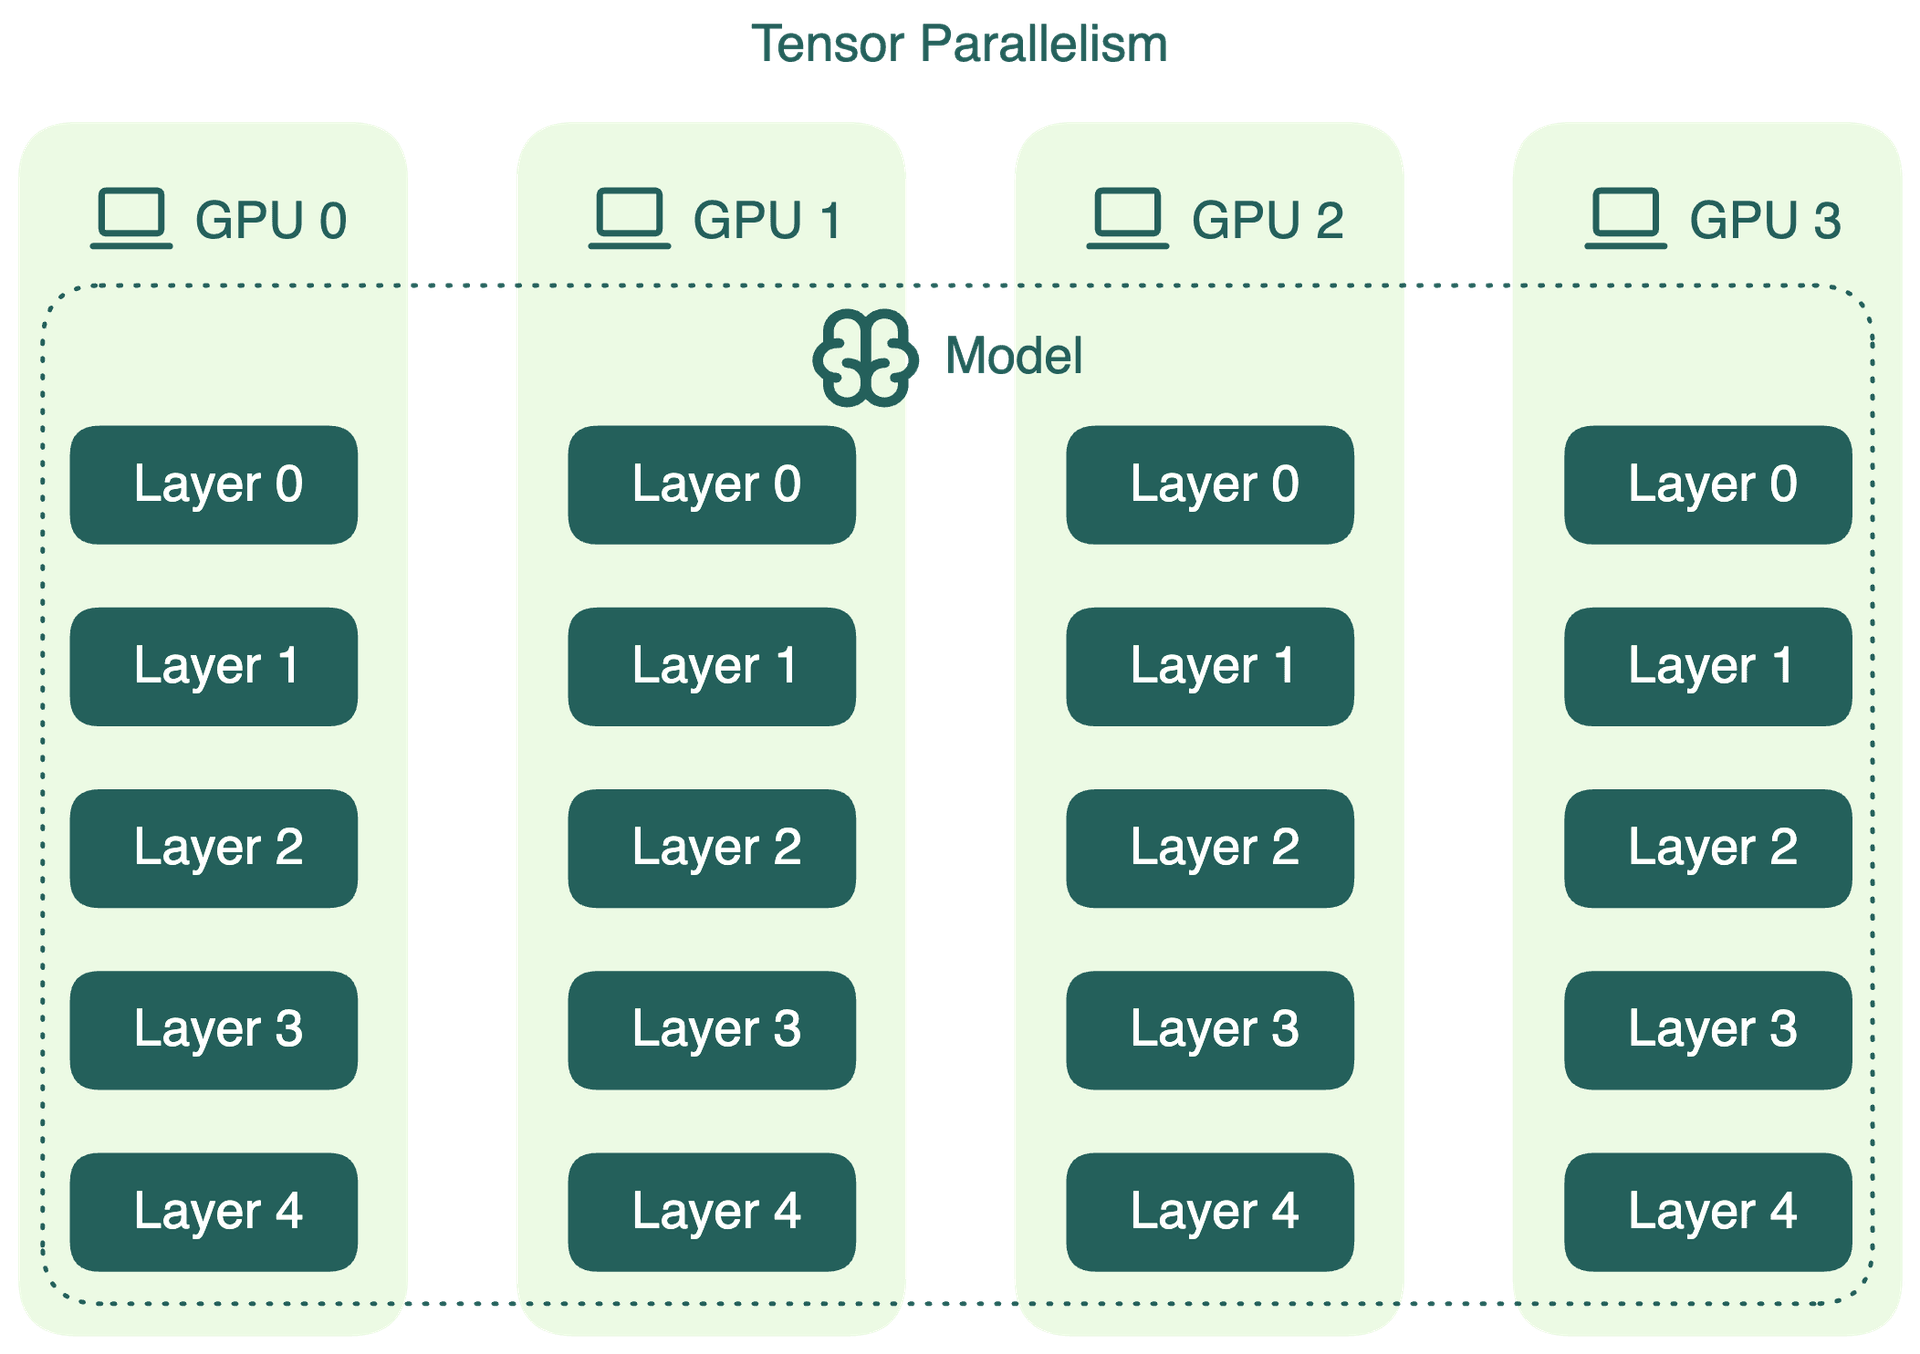
What is GPU Memory and Why it Matters for LLM Inference

vLLM is a high-performance library for LLM inference and serving ...
Advertisement Space (300x250)
Deploy LMDeploy on GPU Cloud: TurboMind Inference for InternLM, Qwen3 ...
LLM Observability on GPU Cloud: Deploy Langfuse, Arize Phoenix, and ...

Run High-Performance LLM Inference Kernels from NVIDIA Using FlashInfer ...

Run High-Performance LLM Inference Kernels from NVIDIA Using FlashInfer ...

Run High-Performance LLM Inference Kernels from NVIDIA Using FlashInfer ...
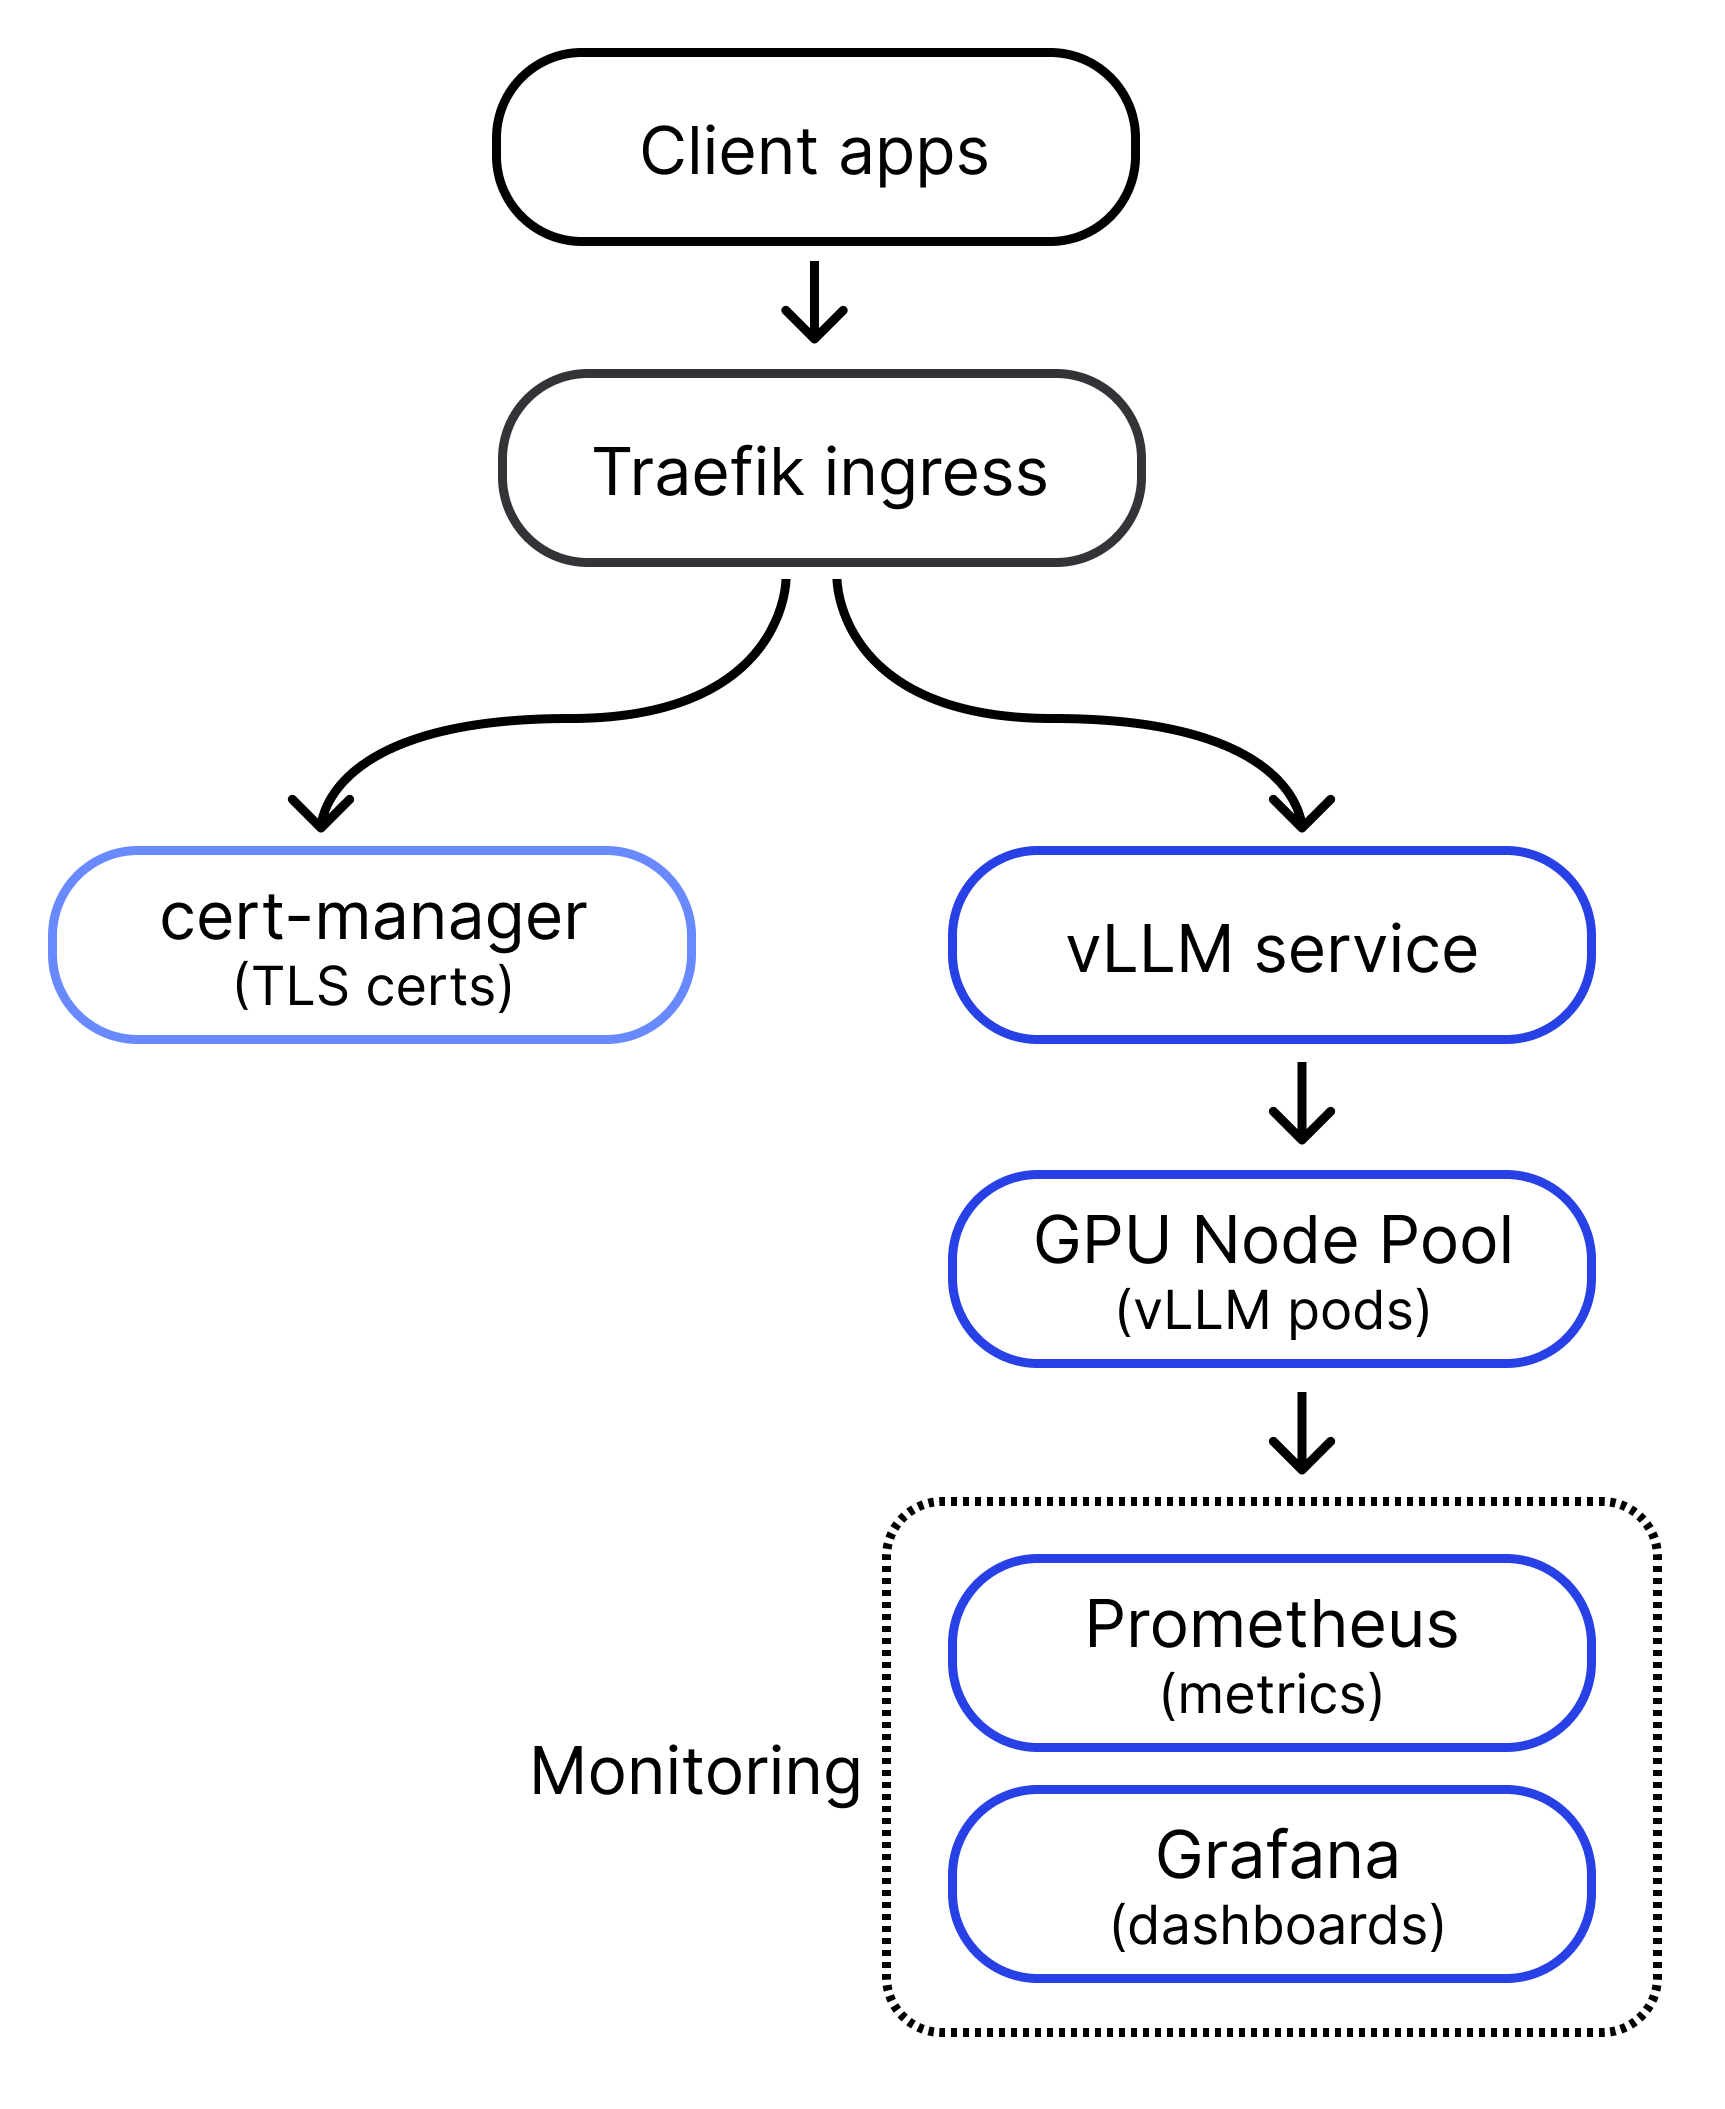
Deploy vLLM for inference - CoreWeave Docs

Run High-Performance LLM Inference Kernels from NVIDIA Using FlashInfer ...
How to Choose the Right GPU for vLLM Inference | DigitalOcean
Deploy vLLM-Omni on GPU Cloud: Fully Disaggregated Serving for Any-to ...

Deploy the vLLM Inference Engine to Run Large Language Models (LLM) on ...
Advertisement Space (336x280)

VLLM Quickstart Guide of HOS: High-Performance LLM Inference for ...
Deploy TokenSpeed on GPU Cloud: Self-Host the Speed-of-Light LLM ...
High-Performance LLM Infrastructure with Kubernetes and vLLM on Private ...

[论文评述] Characterizing and Optimizing LLM Inference Workloads on CPU-GPU ...
DFlash on GPU Cloud: 6x Faster LLM Inference with Block Diffusion ...

Run High-Performance LLM Inference Kernels from NVIDIA Using FlashInfer ...

How to Deploy GPU-Powered AI Model LLM on Google Cloud Run - Geeky Gadgets
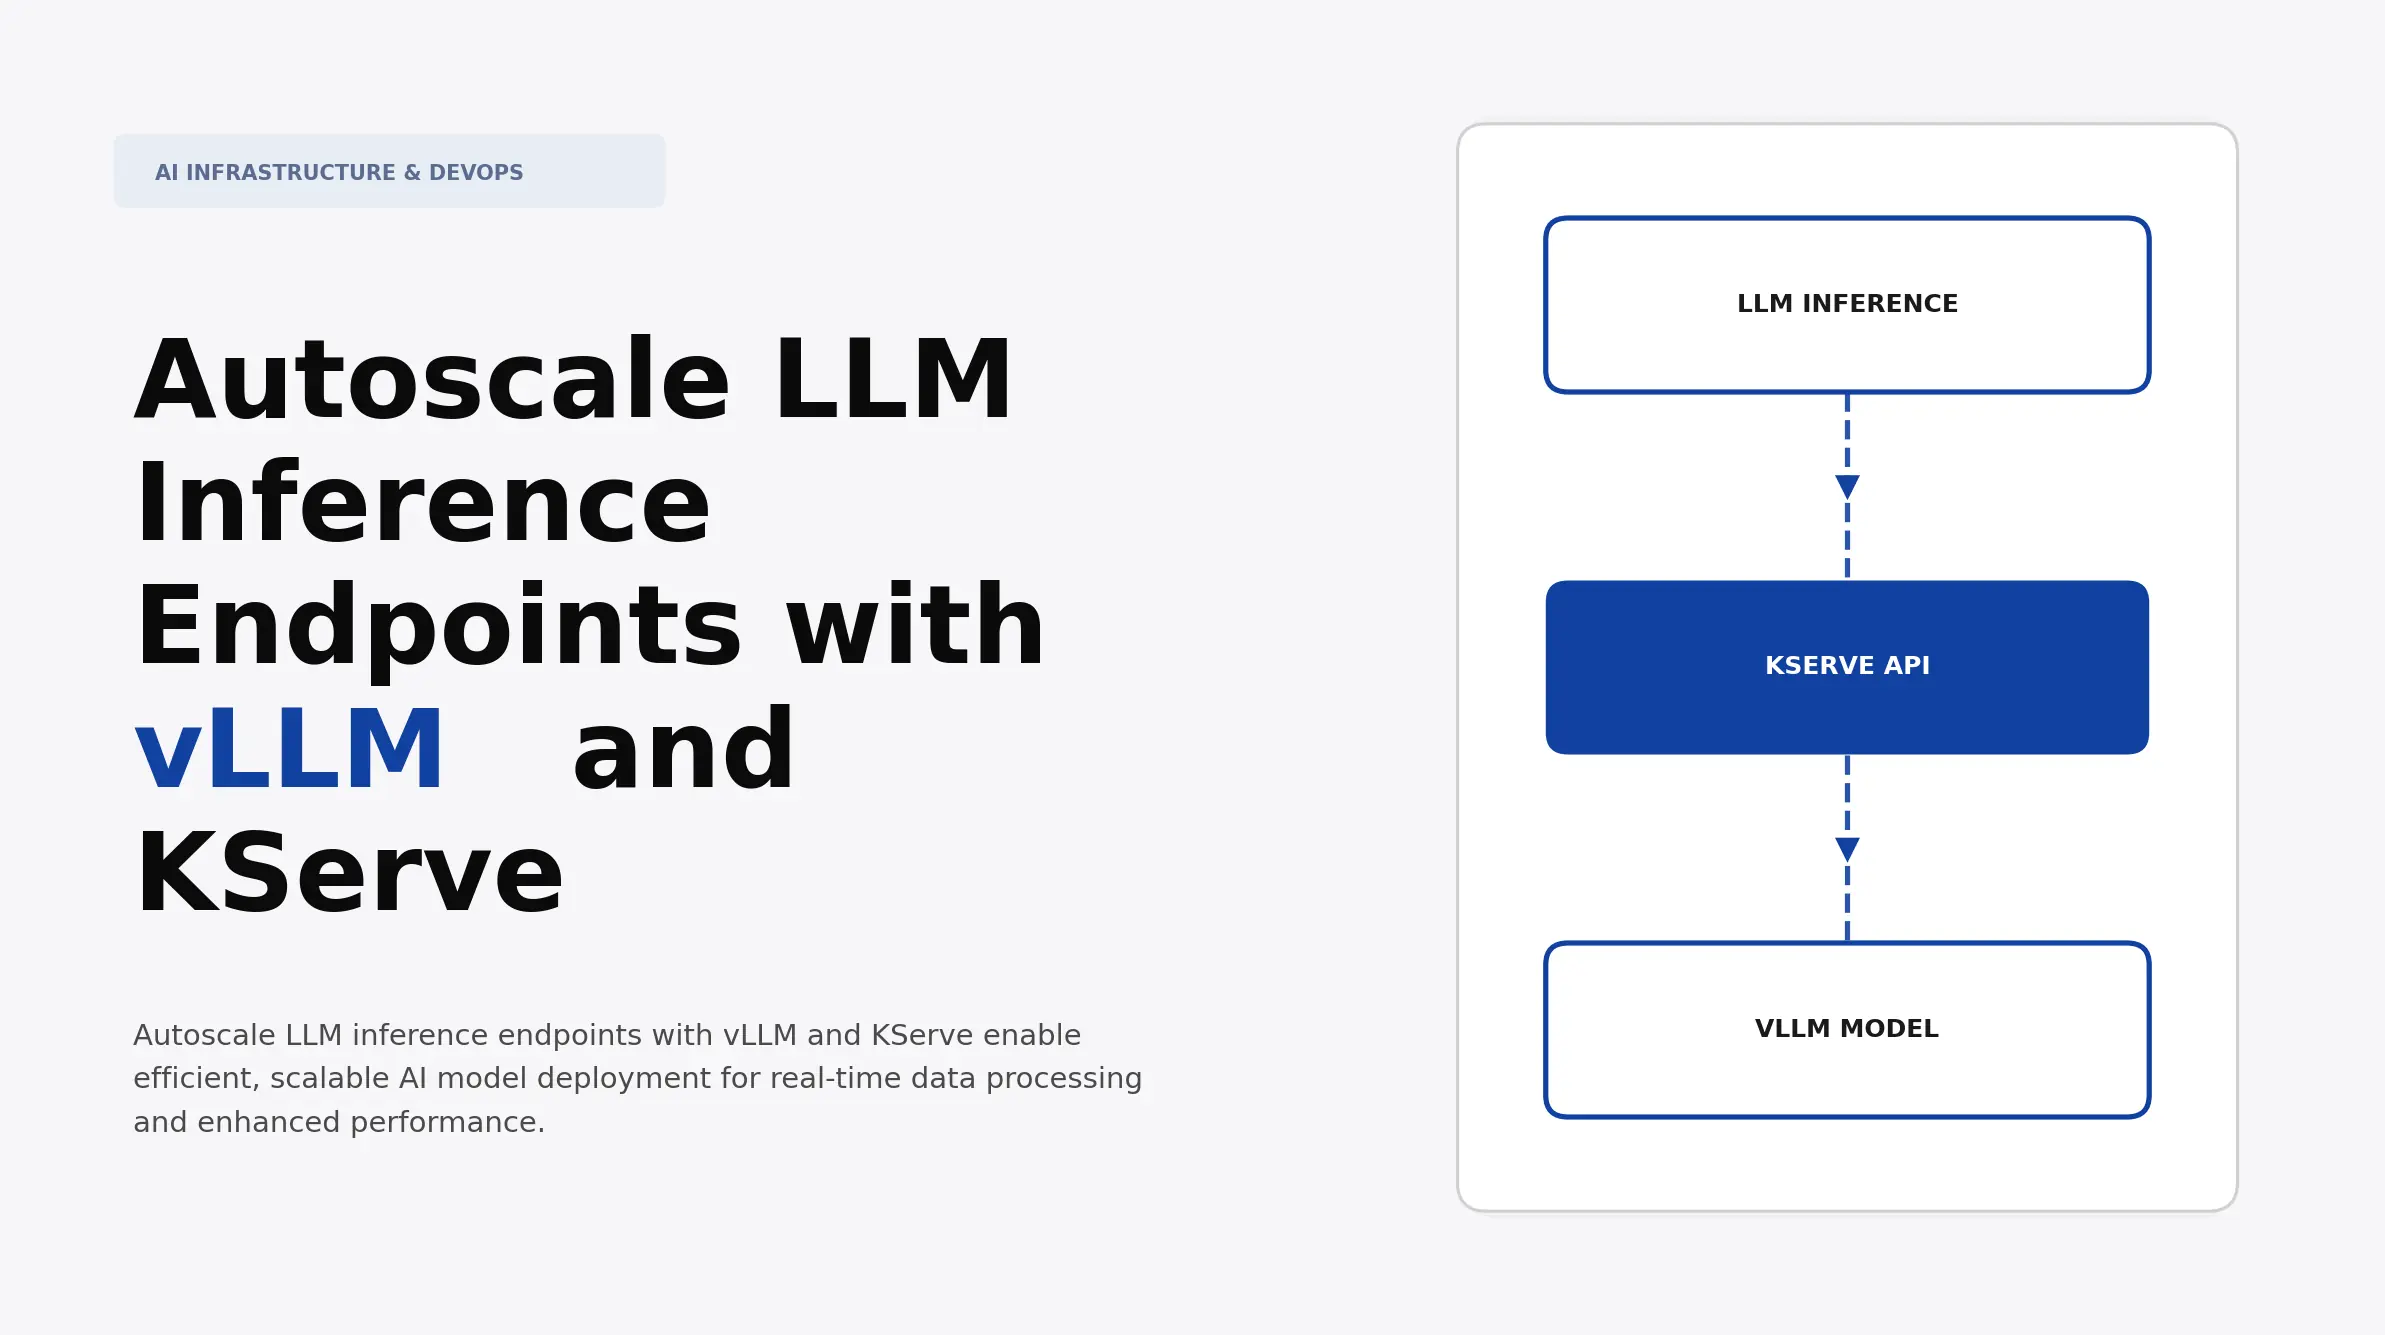
Autoscale LLM Inference Endpoints with vLLM and KServe | Atomic Loops

Run High-Performance LLM Inference Kernels from NVIDIA Using FlashInfer ...

Optimized LLM inference API for Mistral 7B using vLLM - a Lightning ...
Advertisement Space (336x280)
LLM Inference On-Premise vs GPU Cloud: 2026 Cost and Break-Even ...

Meet vLLM: For faster, more efficient LLM inference and serving

Parallel CPU-GPU Execution for LLM Inference on Constrained GPUs | AI ...
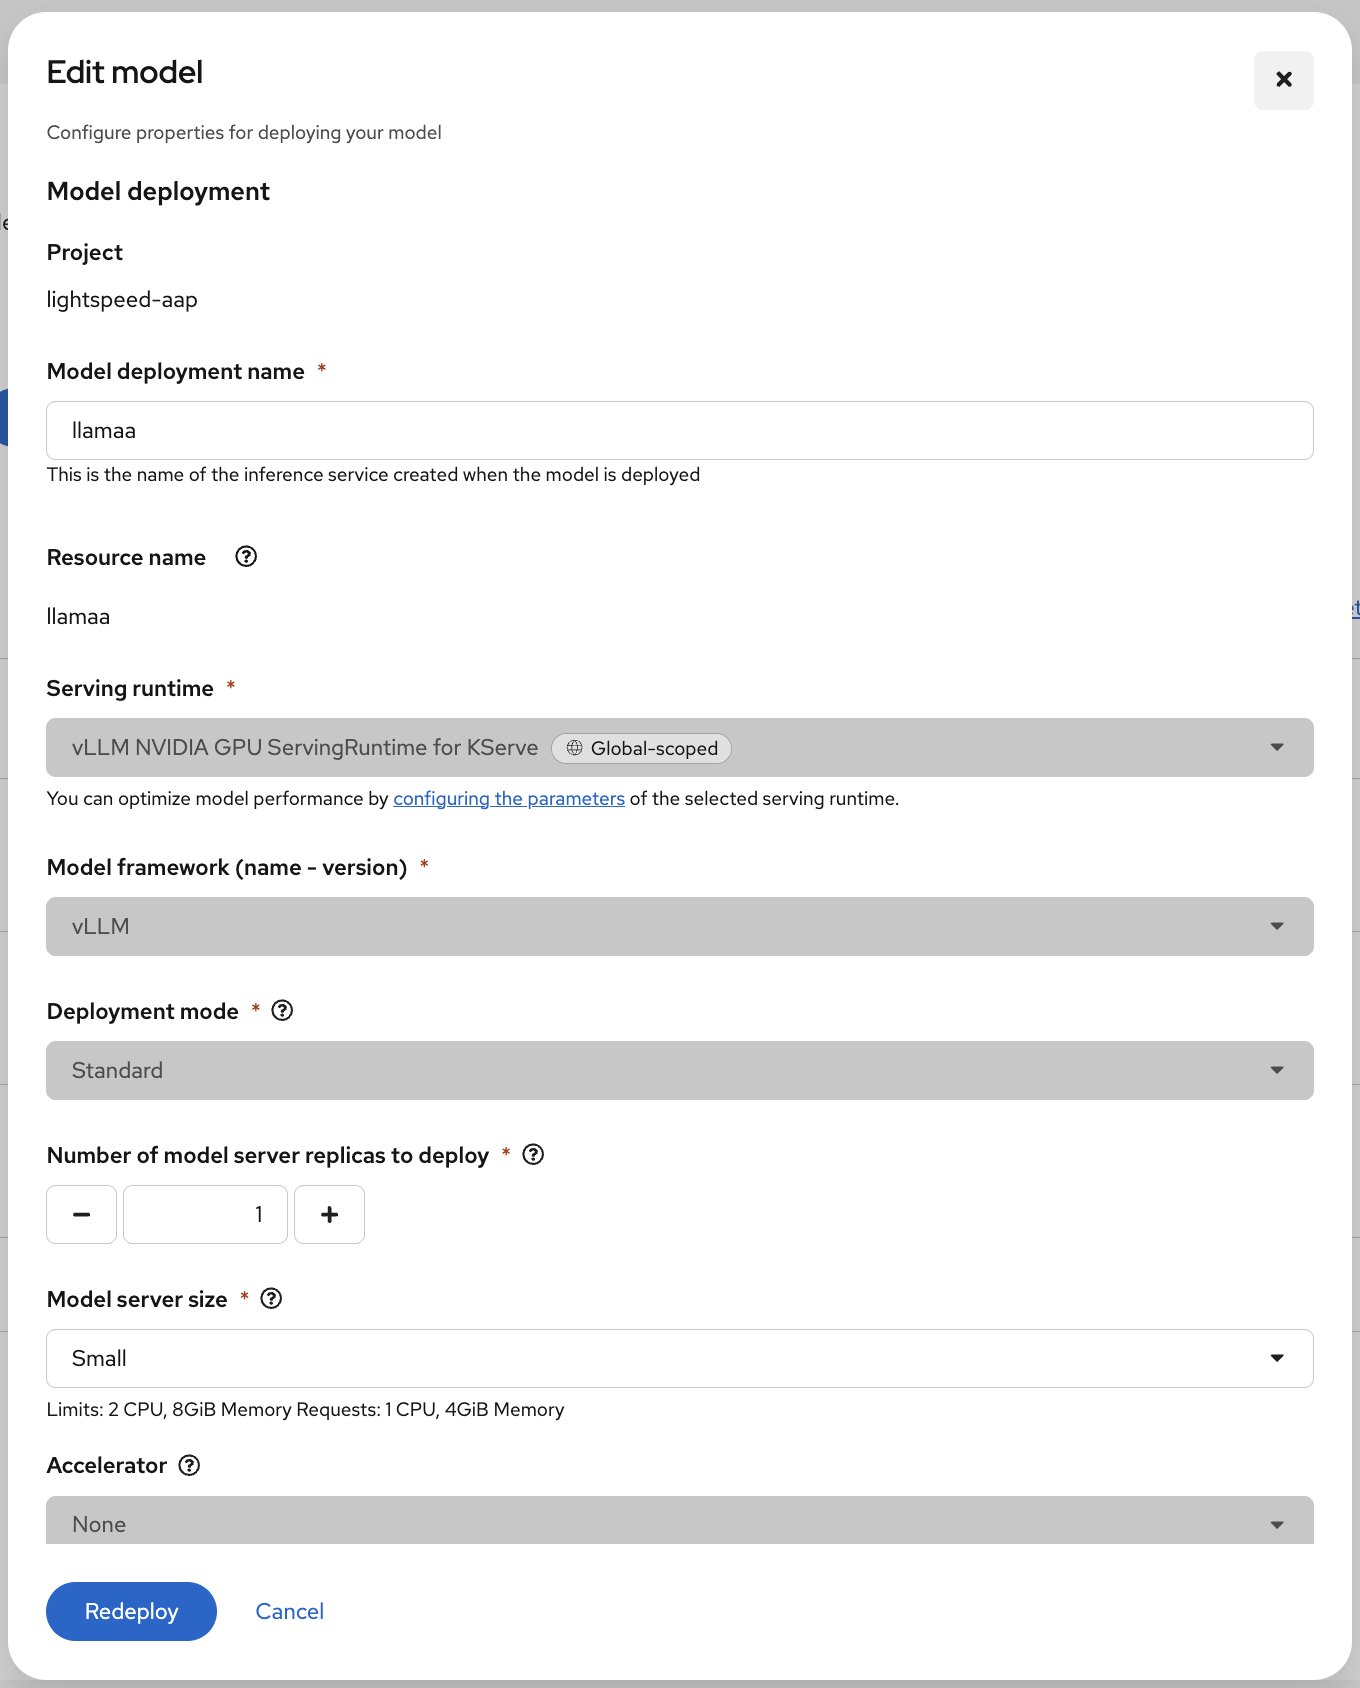
Deploy an LLM inference service on OpenShift AI | Red Hat Developer
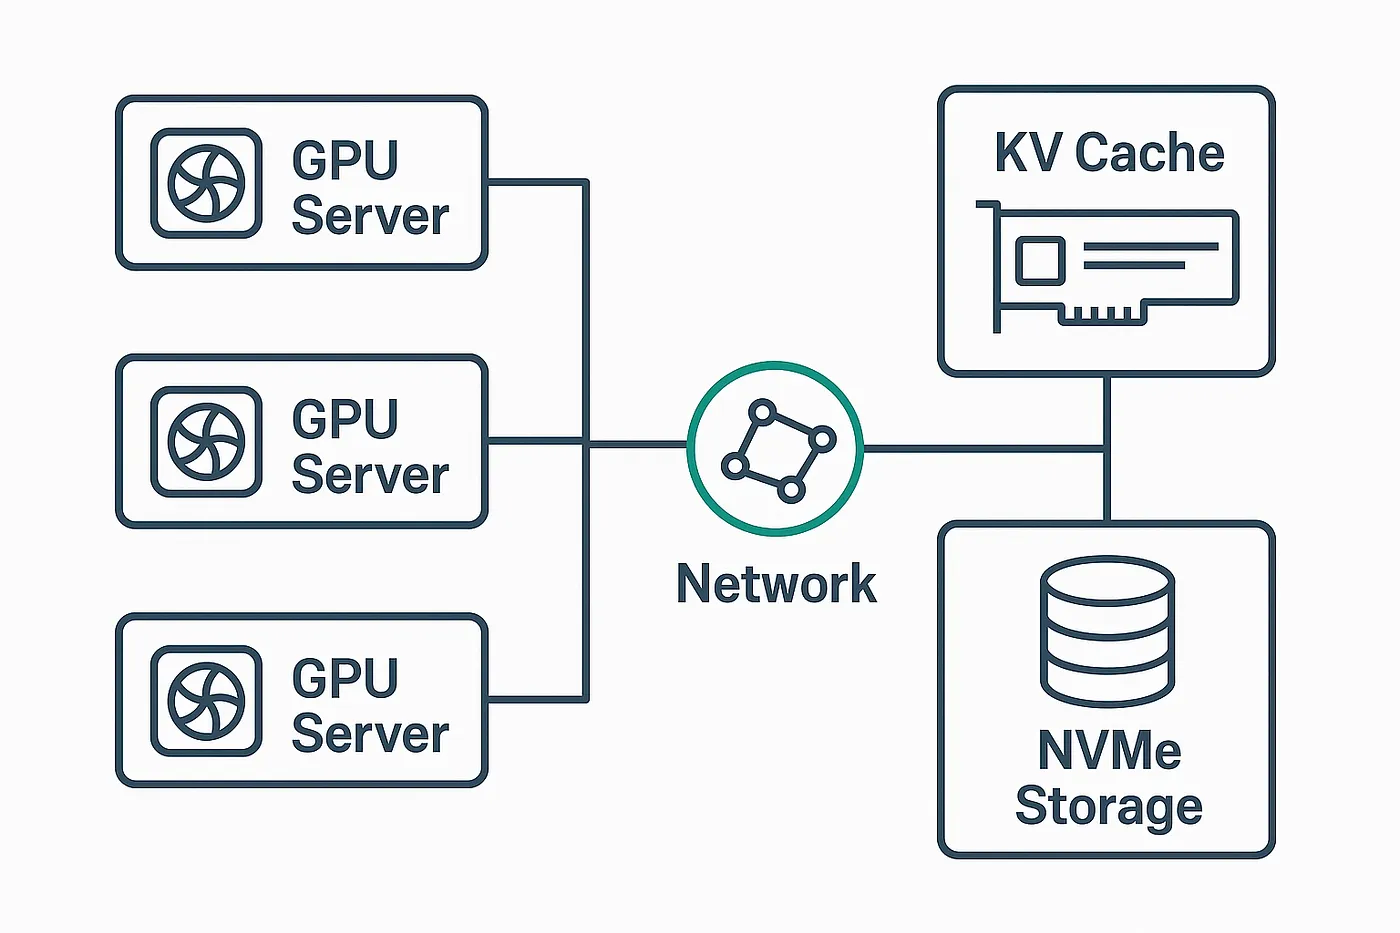
How to Give Your RTX GPU Nearly Infinite Memory for LLM Inference

9 Serverless GPU Playbooks for Cheap vLLM Inference | by Neurobyte | Medium