
Getting Started With Vllm Docker Gpu Powered Inference Using The

Getting Started with vLLM Docker: GPU-Powered Inference Using the ...

Getting Started with vLLM Docker: GPU-Powered Inference Using the ...

Getting Started with vLLM Docker: GPU-Powered Inference Using the ...

Getting Started with vLLM Docker: GPU-Powered Inference Using the ...
Getting Started with vLLM Docker: GPU-Powered Inference Using the ...

Getting Started with vLLM Docker: GPU-Powered Inference Using the ...

Getting Started with vLLM Docker: GPU-Powered Inference Using the ...

Getting Started with vLLM Docker: GPU-Powered Inference Using the ...
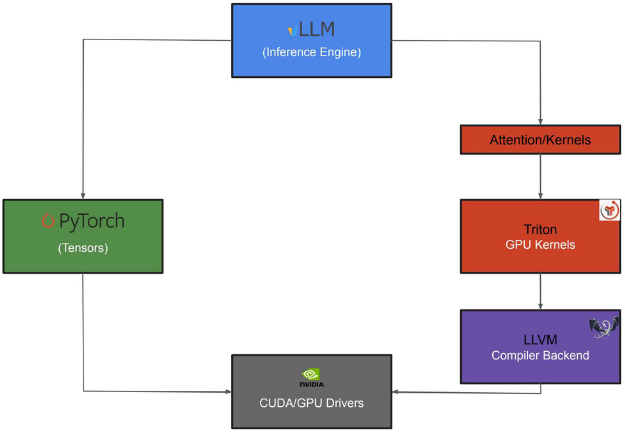
LLM Inference with vLLM Using GPU on Power9
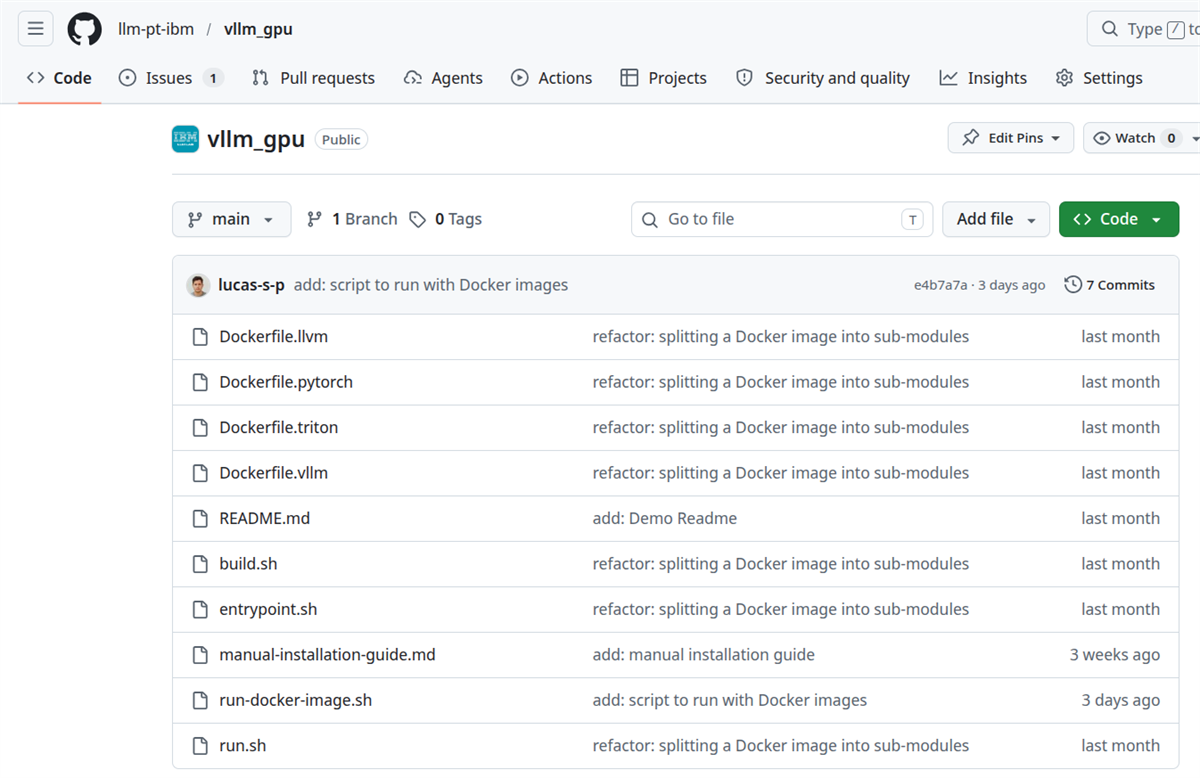
LLM Inference with vLLM Using GPU on Power9
Advertisement Space (300x250)
How to Choose the Right GPU for vLLM Inference | DigitalOcean
How to Run LLM Inference with vLLM in Docker

Trying to get GPU usage with inference server and Docker - 🤝 Community ...

AI Inference on AMD MI300X with vLLM Docker Image Validation
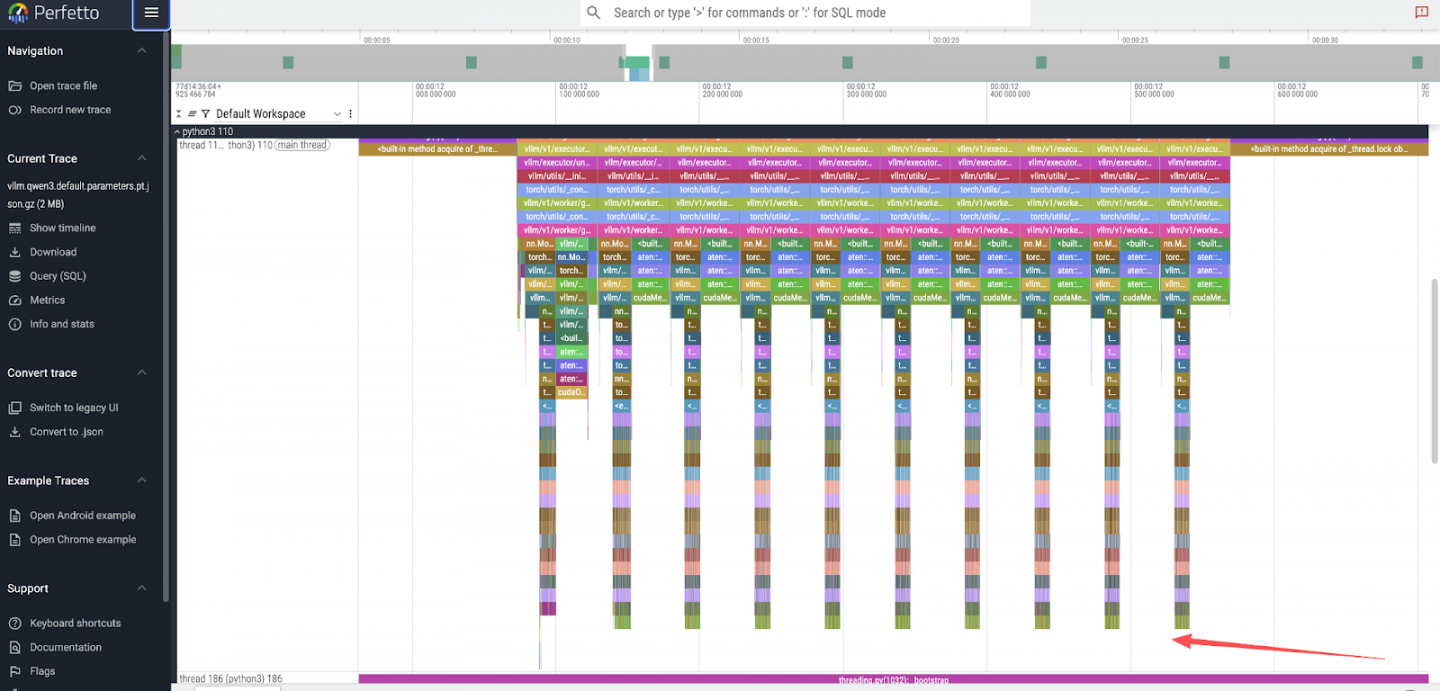
Profiling vLLM Inference Server with GPU acceleration on RHEL | Red Hat ...

Getting Started with vLLM | intel/llm-scaler | DeepWiki

Trying to get GPU usage with inference server and Docker - 🤝 Community ...

Getting Started with vLLM: Fast and Efficient LLM Inference | by Wenyi ...
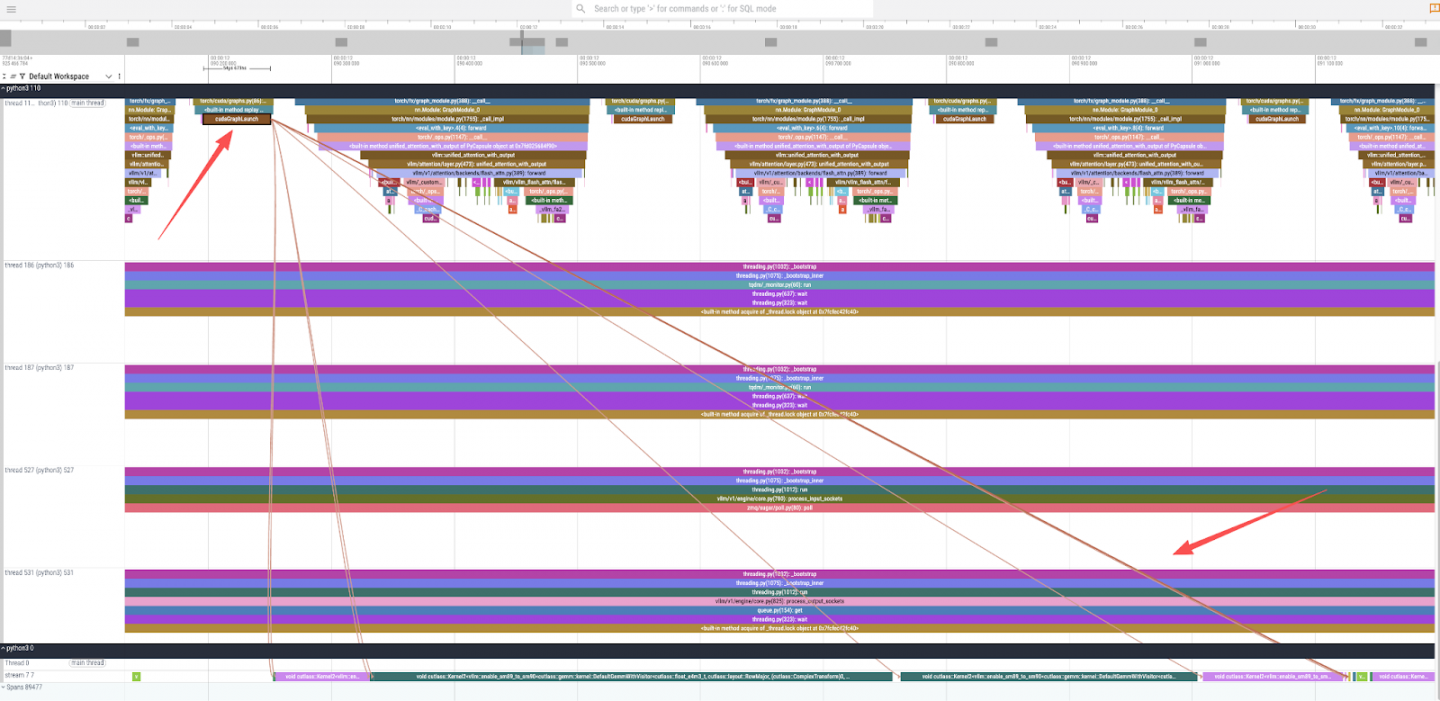
Profiling vLLM Inference Server with GPU acceleration on RHEL | Red Hat ...

How to Install Tensorflow on the GPU with Docker | Saturn Cloud Blog
Advertisement Space (336x280)
Profiling vLLM Inference Server with GPU acceleration on RHEL | Red Hat ...

Trying to get GPU usage with inference server and Docker - 🤝 Community ...

Docker Model Runner Adds vLLM for Fast AI Inference

NVIDIA MIG Explained: GPU Sharing for vLLM Inference Engines | Abhinav ...
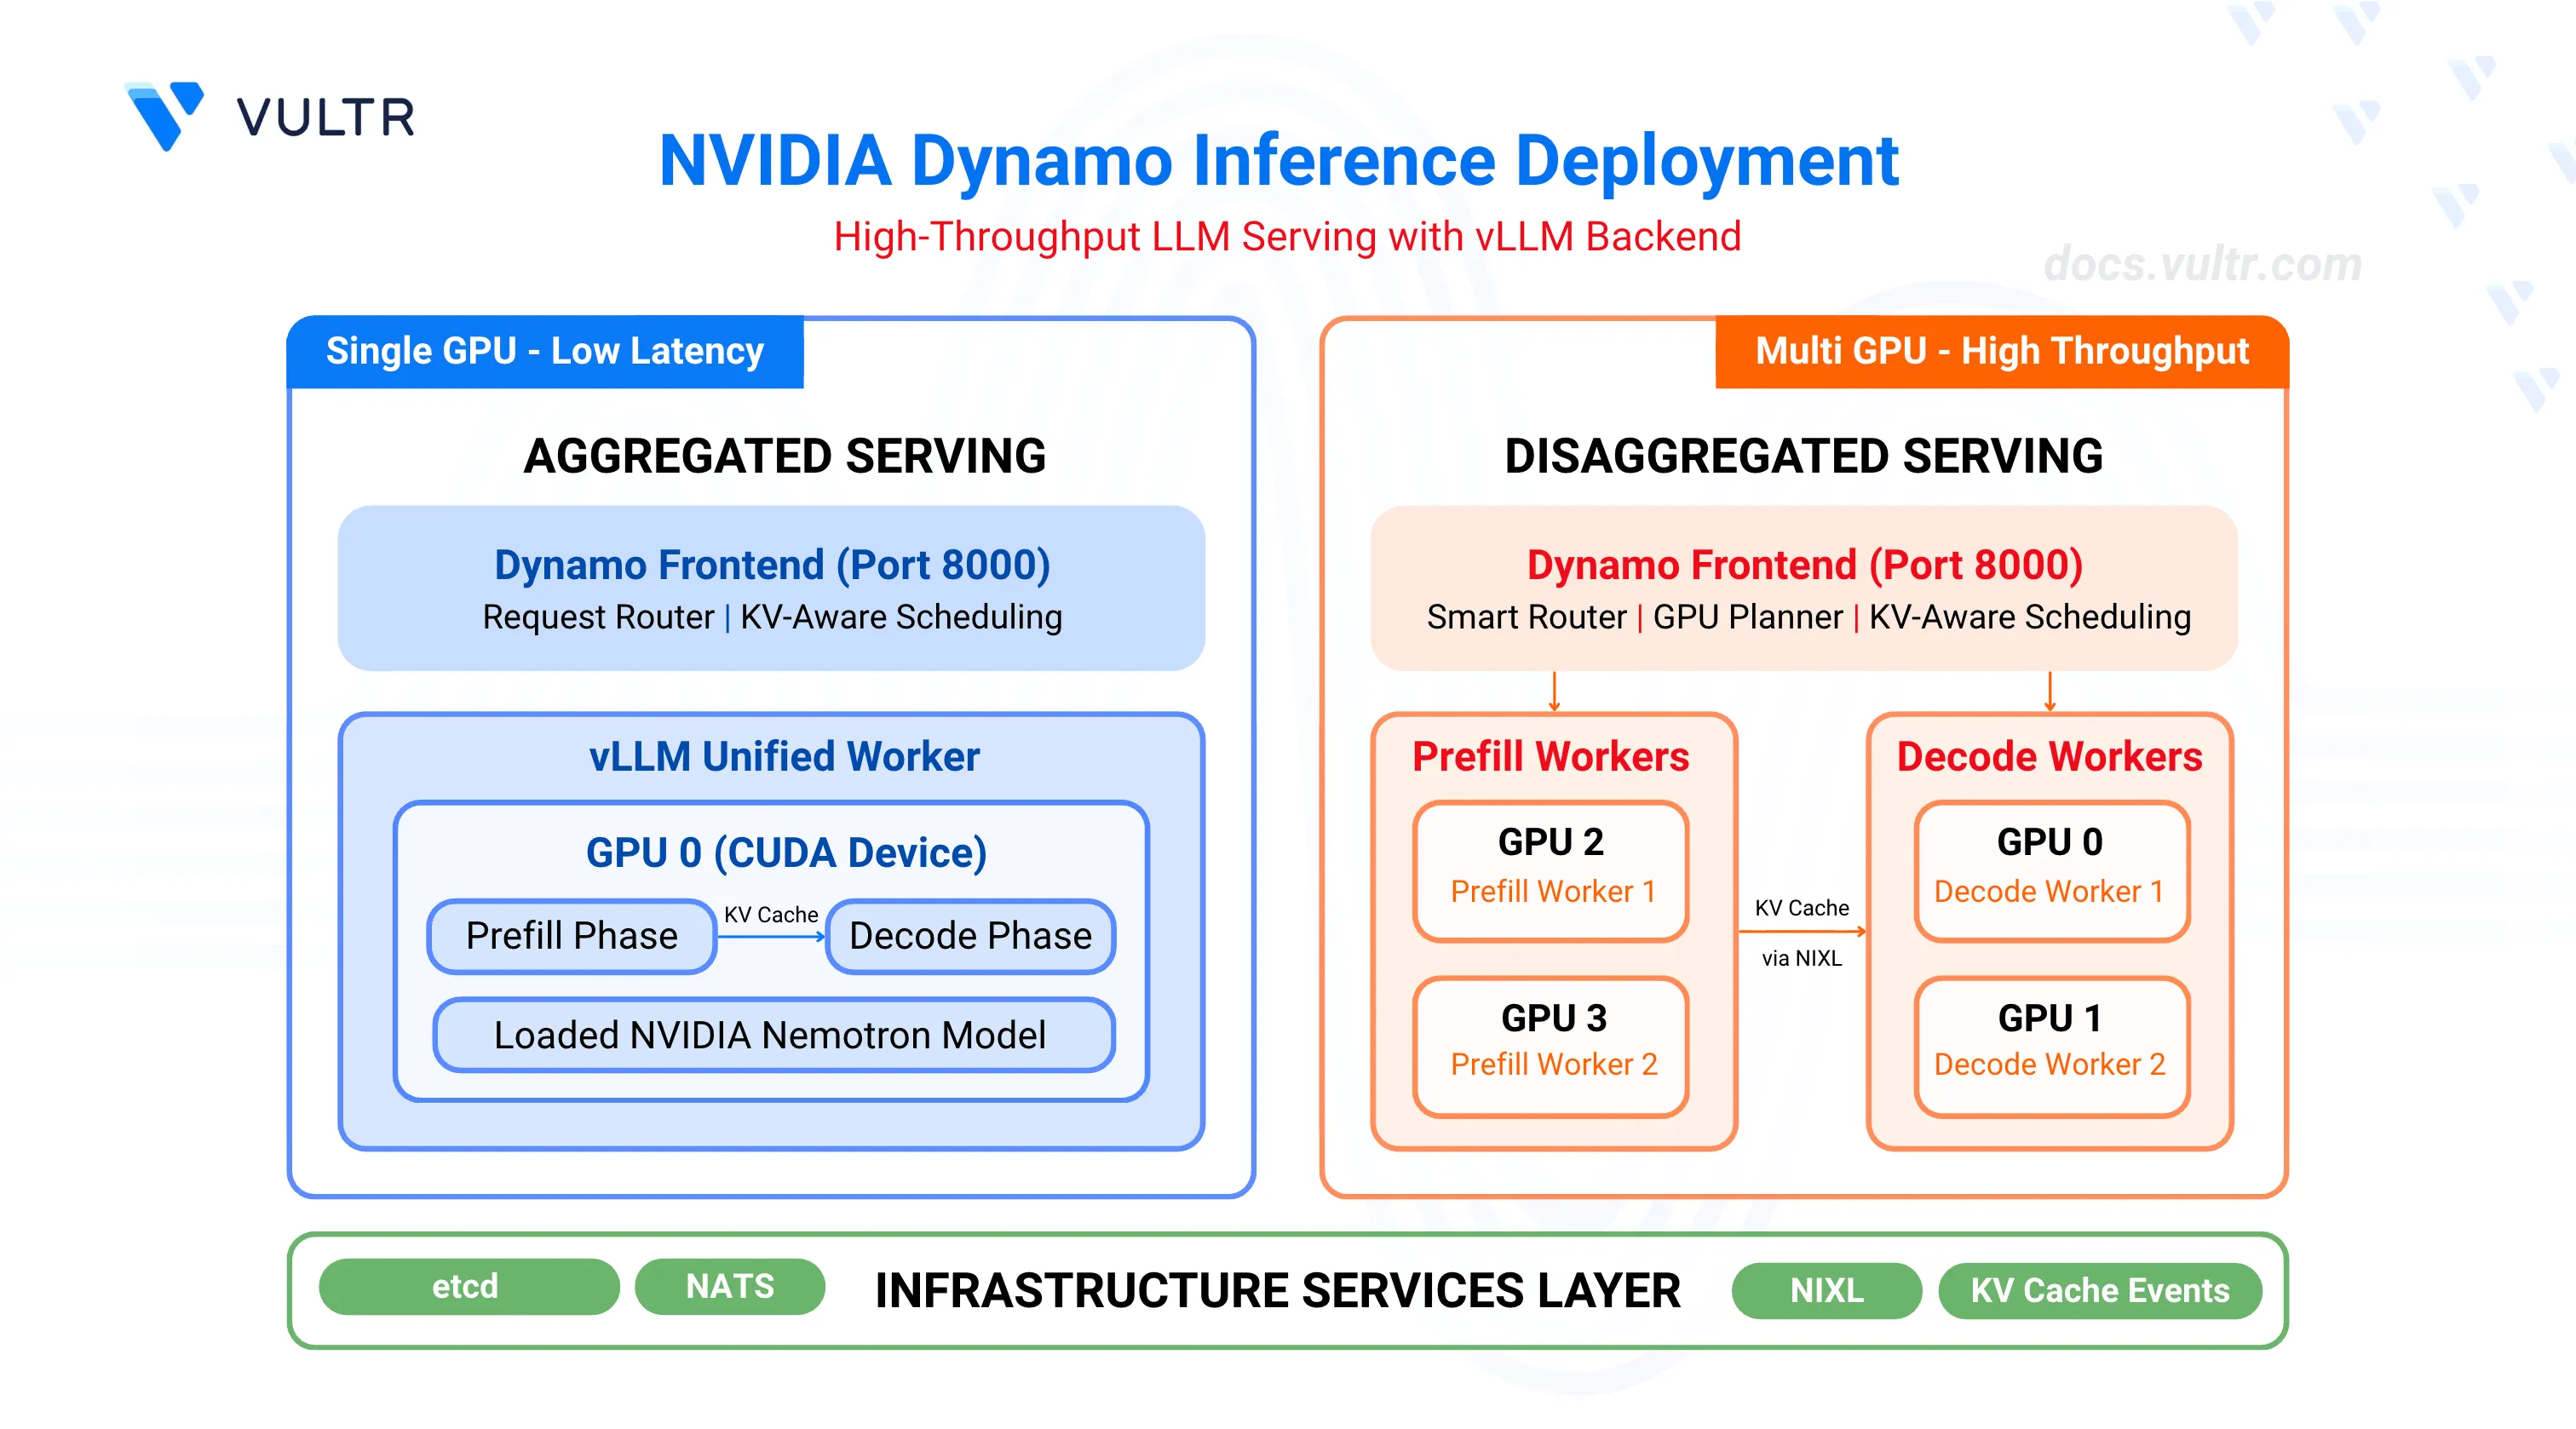
How to Deploy Inference Using NVIDIA Dynamo and vLLM | Vultr Docs
Orchestrate GPU Prefill-Decode Inference for Factory AI with NVIDIA ...
Discussion on "Deploying vLLM with Docker: The Complete Guide to ...
vLLM Distributed Inference stuck when using multi -GPU · Issue #2466 ...

Running LLM OpenAI Open Source Model with vLLM and GPU NVIDIA L4 | Viki ...

Docker Model Runner Brings vLLM to macOS with Apple Silicon
Advertisement Space (336x280)

vLLM Review: High-Performance LLM Inference Engine for GPU ...

Quickstart: High-throughput LLM inference with vLLM on Amazon EKS ...

Free Video: The Evolution of Multi-GPU Inference in vLLM from Anyscale ...

Local NVIDIA GPU Setup for Machine Learning using Docker | TensorFlow ...

Accelerating LLM Inference with vLLM - APC 技術ブログ

Optimized LLM inference API for Mistral 7B using vLLM - a Lightning ...