
Ltri Llm Streaming Long Context Inference For Llms With

Paper page - Ltri-LLM: Streaming Long Context Inference for LLMs with ...

[논문 리뷰] Ltri-LLM: Streaming Long Context Inference for LLMs with ...
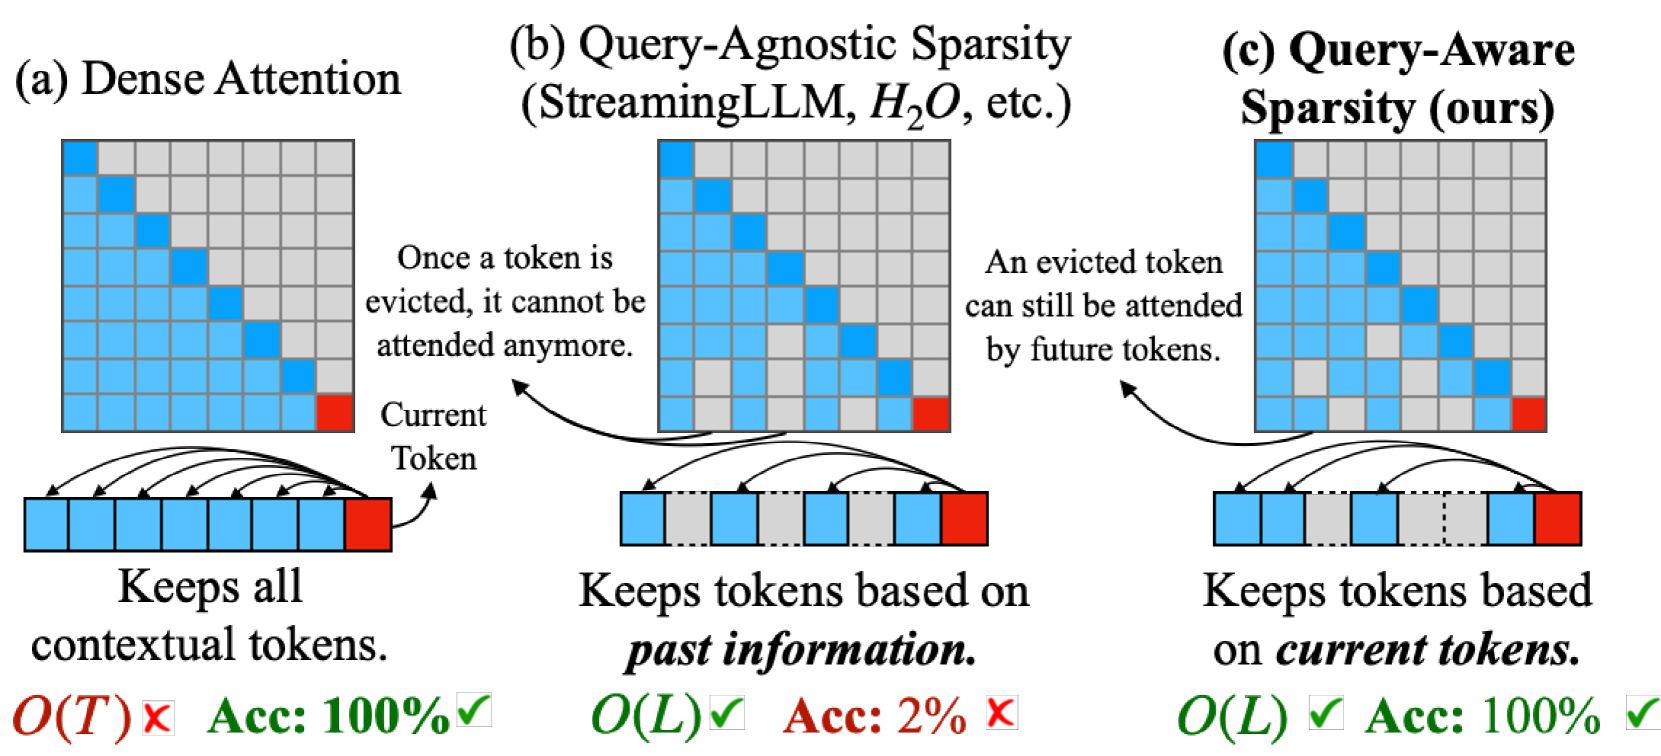
Near-Lossless Acceleration of Long Context LLM Inference with Adaptive ...

A New Data Synthesis Method for Long Context LLMs | ml-news – Weights ...

[논문 리뷰] TracLLM: A Generic Framework for Attributing Long Context LLMs

Streaming and longer context lengths for LLMs on Workers AI
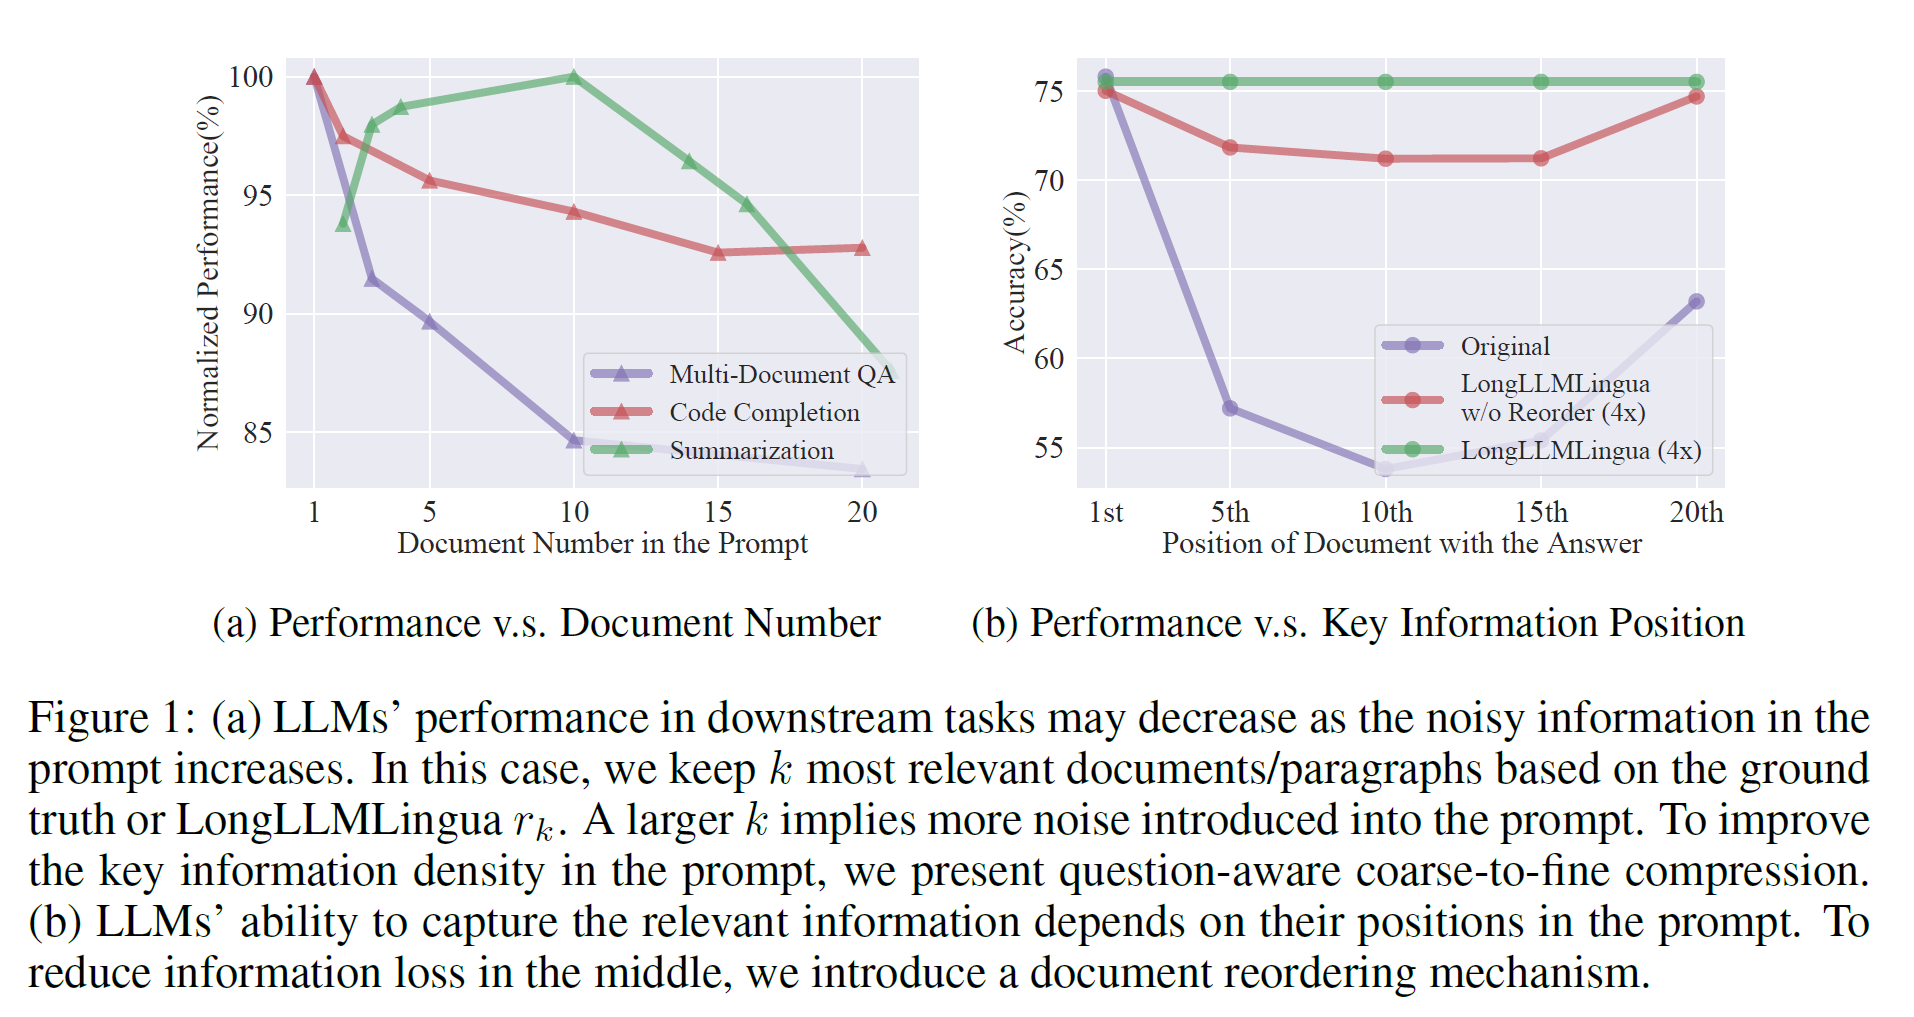
LongLLMLingua Model: A Solution for LLMs in Long Context Scenarios ...

Long Context LLMs Struggle with Long In-Context Learning Finds that ...

LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...
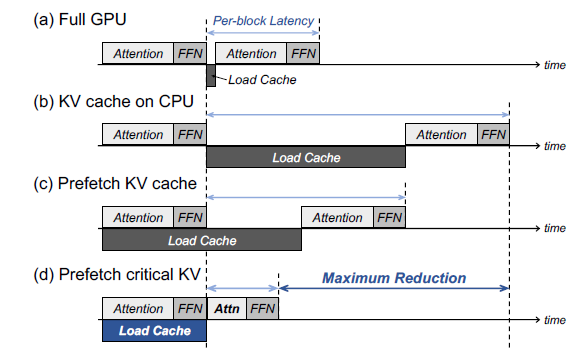
LLM Inference: Accelerating Long Context Generation with KV Cache ...
Advertisement Space (300x250)
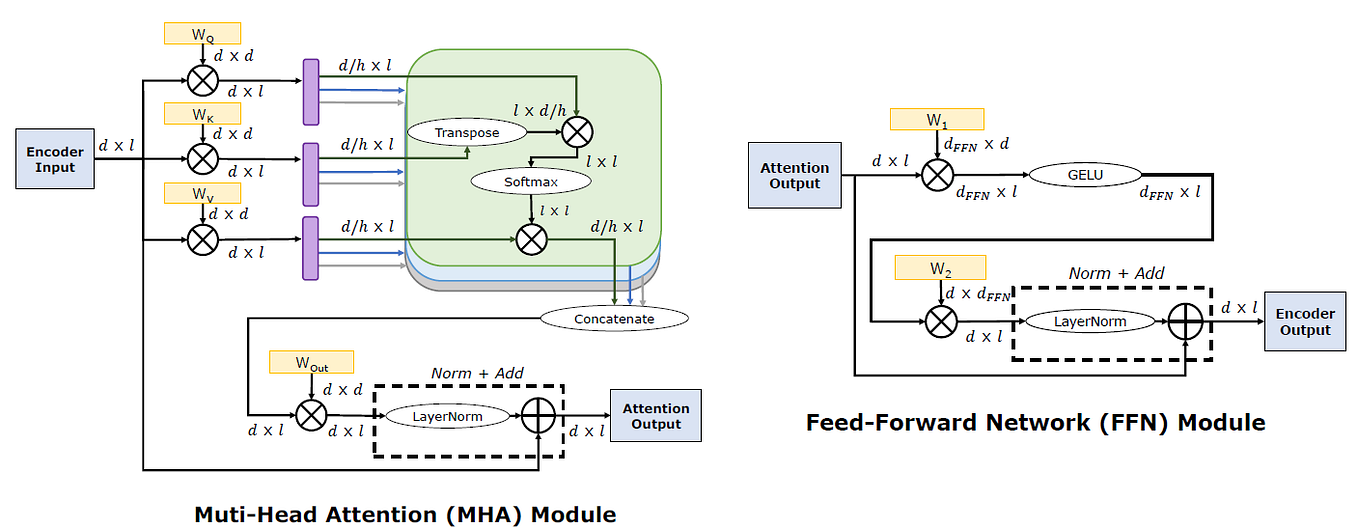
LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...

Long Context LLMs Struggle with Long In-Context Learning Finds that ...
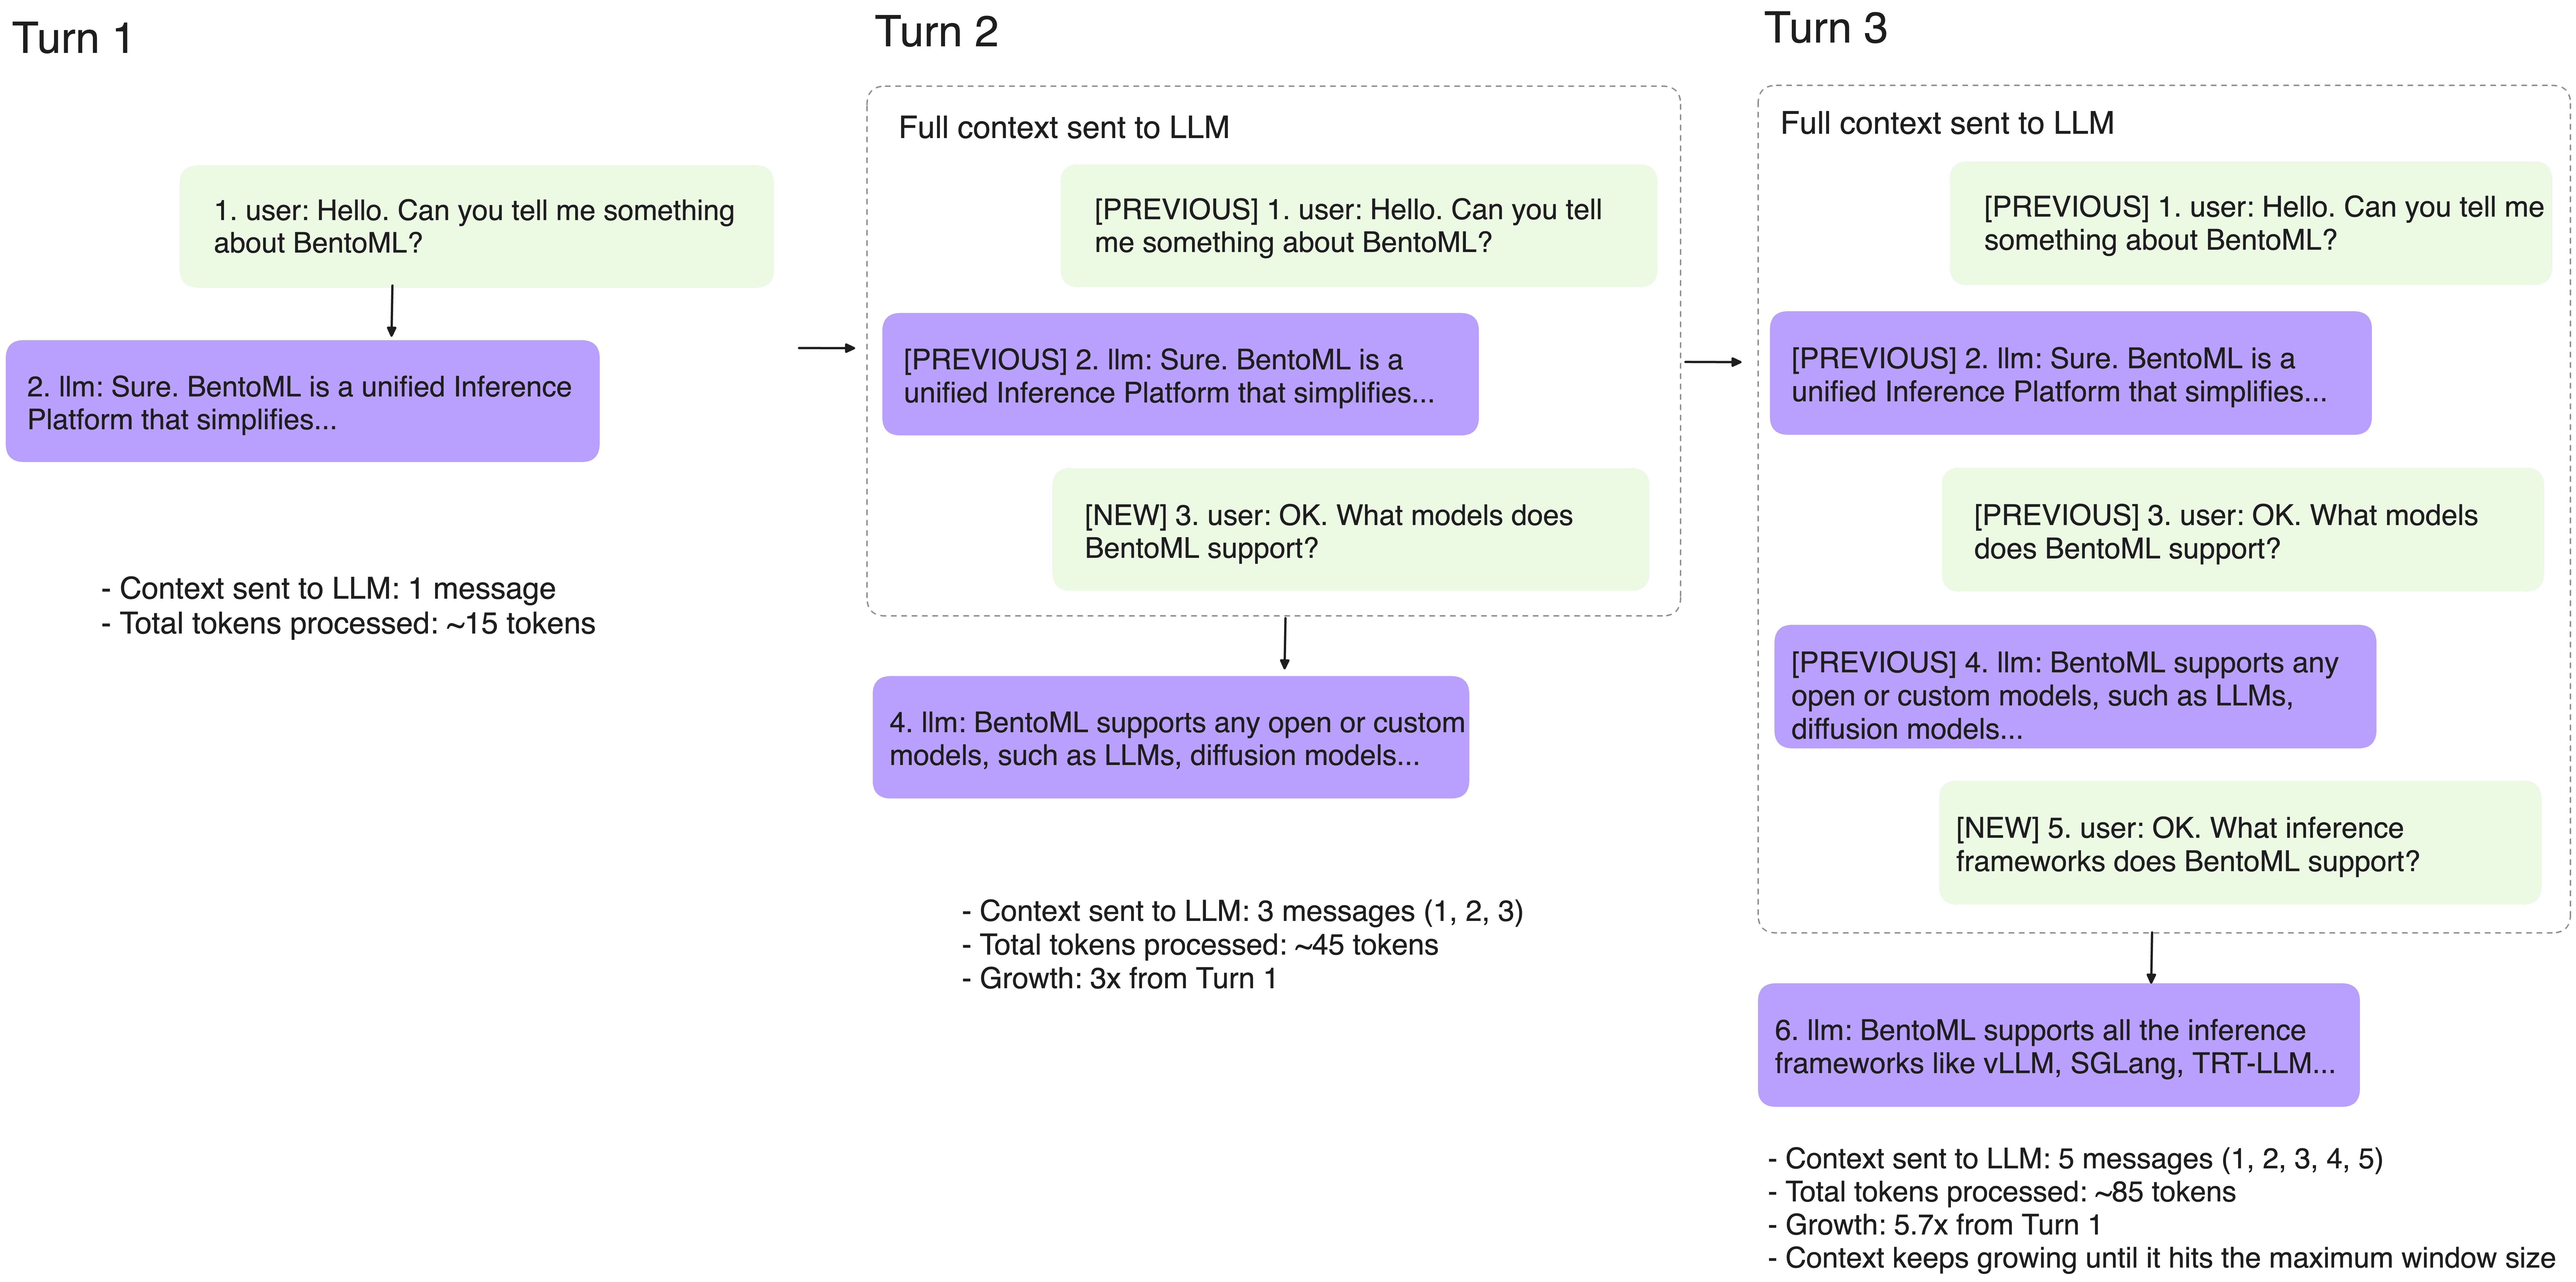
What is GPU Memory and Why it Matters for LLM Inference

DuoAttention: Efficient Long-Context LLM Inference with Retrieval and ...
LLMs Long Context Comprehension Benchmark

Paper page - DuoAttention: Efficient Long-Context LLM Inference with ...
DuoAttention: Efficient Long-Context LLM Inference with Retrieval and ...

Giraffe - Long Context LLMs - The Abacus.AI Blog
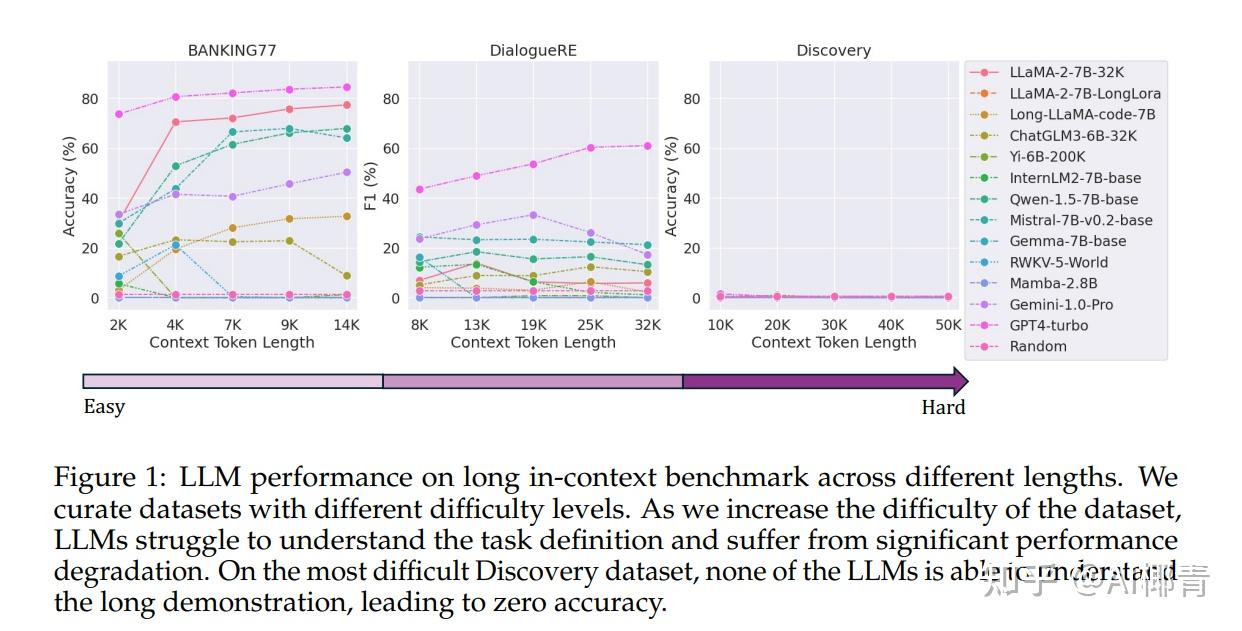
Long-context LLMs Struggle with Long In-context Learning - 知乎

Real-Time Streaming LLM Inference Guide 2026 | Iterathon
Advertisement Space (336x280)

Star Attention: Efficient LLM Inference over Long Sequences | AI ...

DuoAttention: Efficient Long-Context LLM Inference with Retrieval and ...
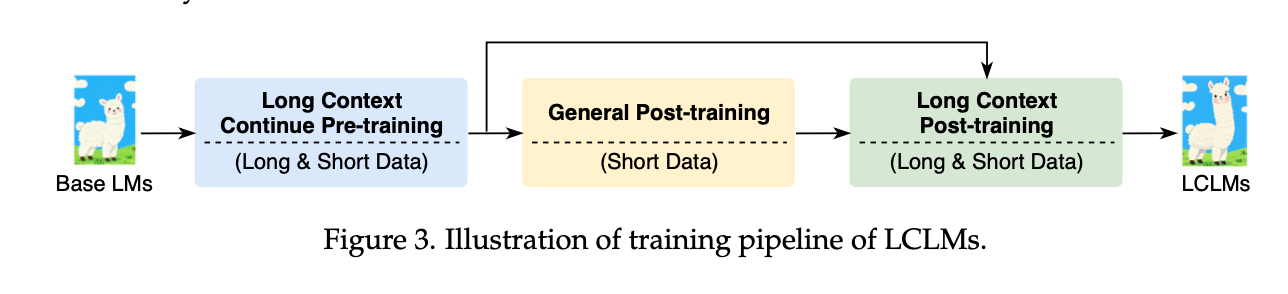
Long Context LLM (1): Pre-training부터 Post-training까지 data 전략 | ML감자
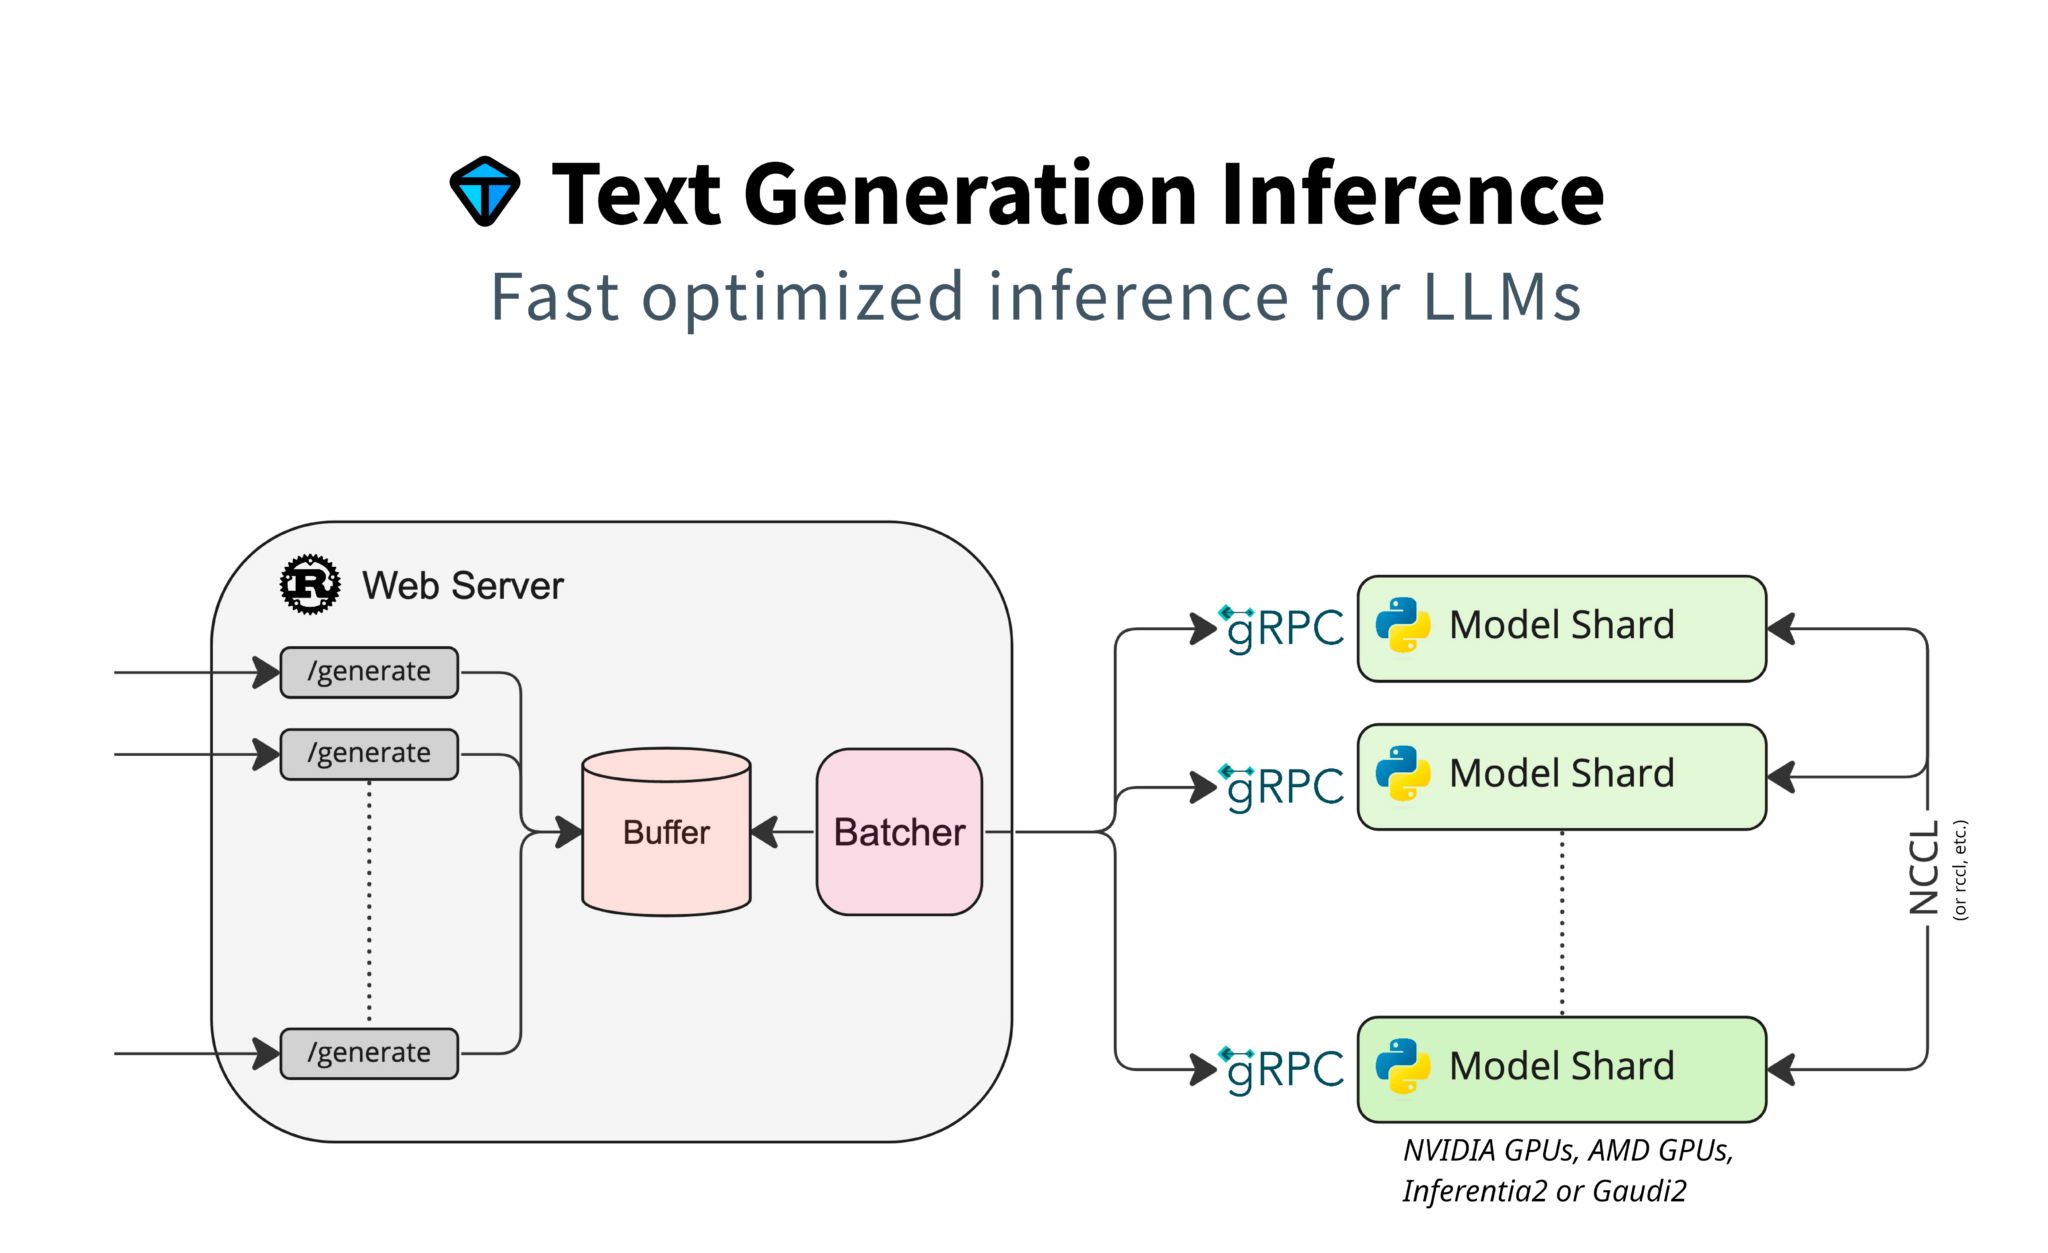
Leverage Hugging Face TGI for multiple LLM Inference APIs - Massed Compute
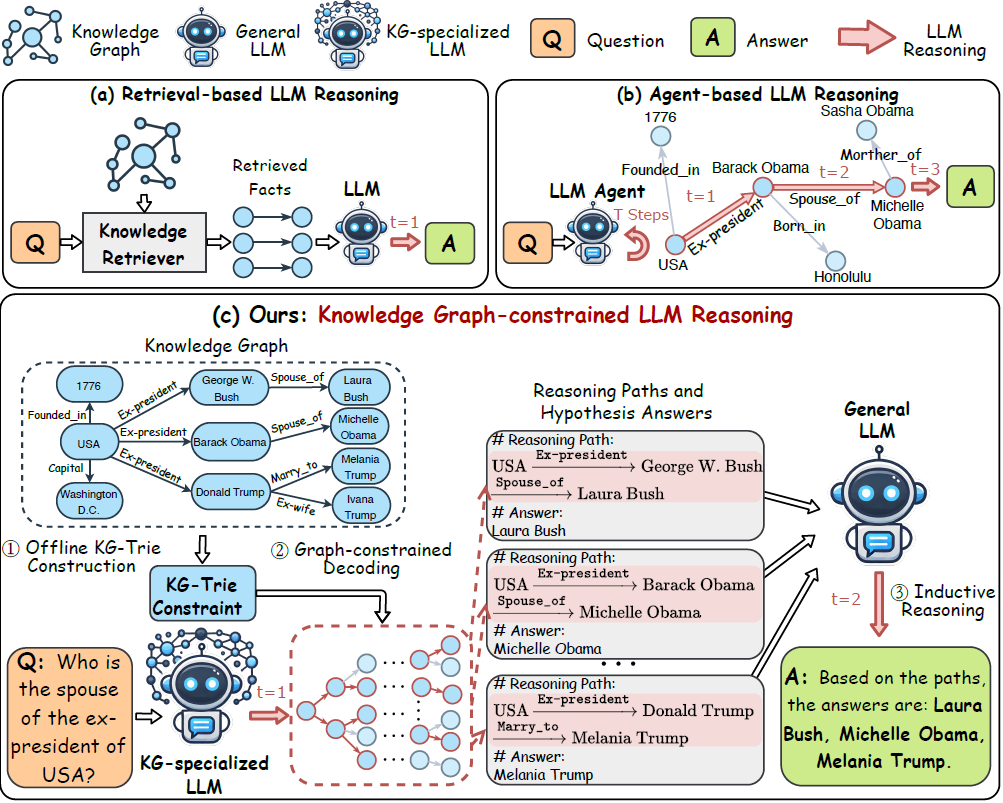
Vidur: A Large-Scale Simulation Framework for LLM Inference Performance ...
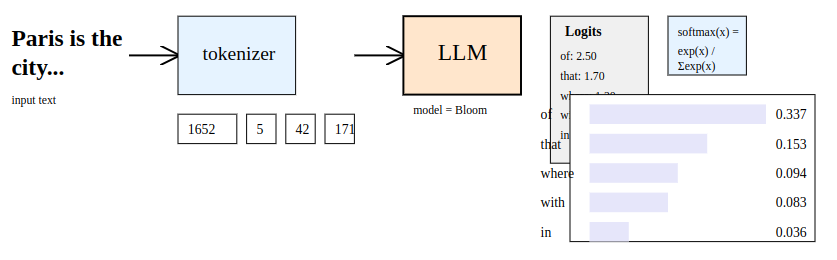
LLM by Examples: Inference with TinyLlama 1.1B | by MB20261 | Medium
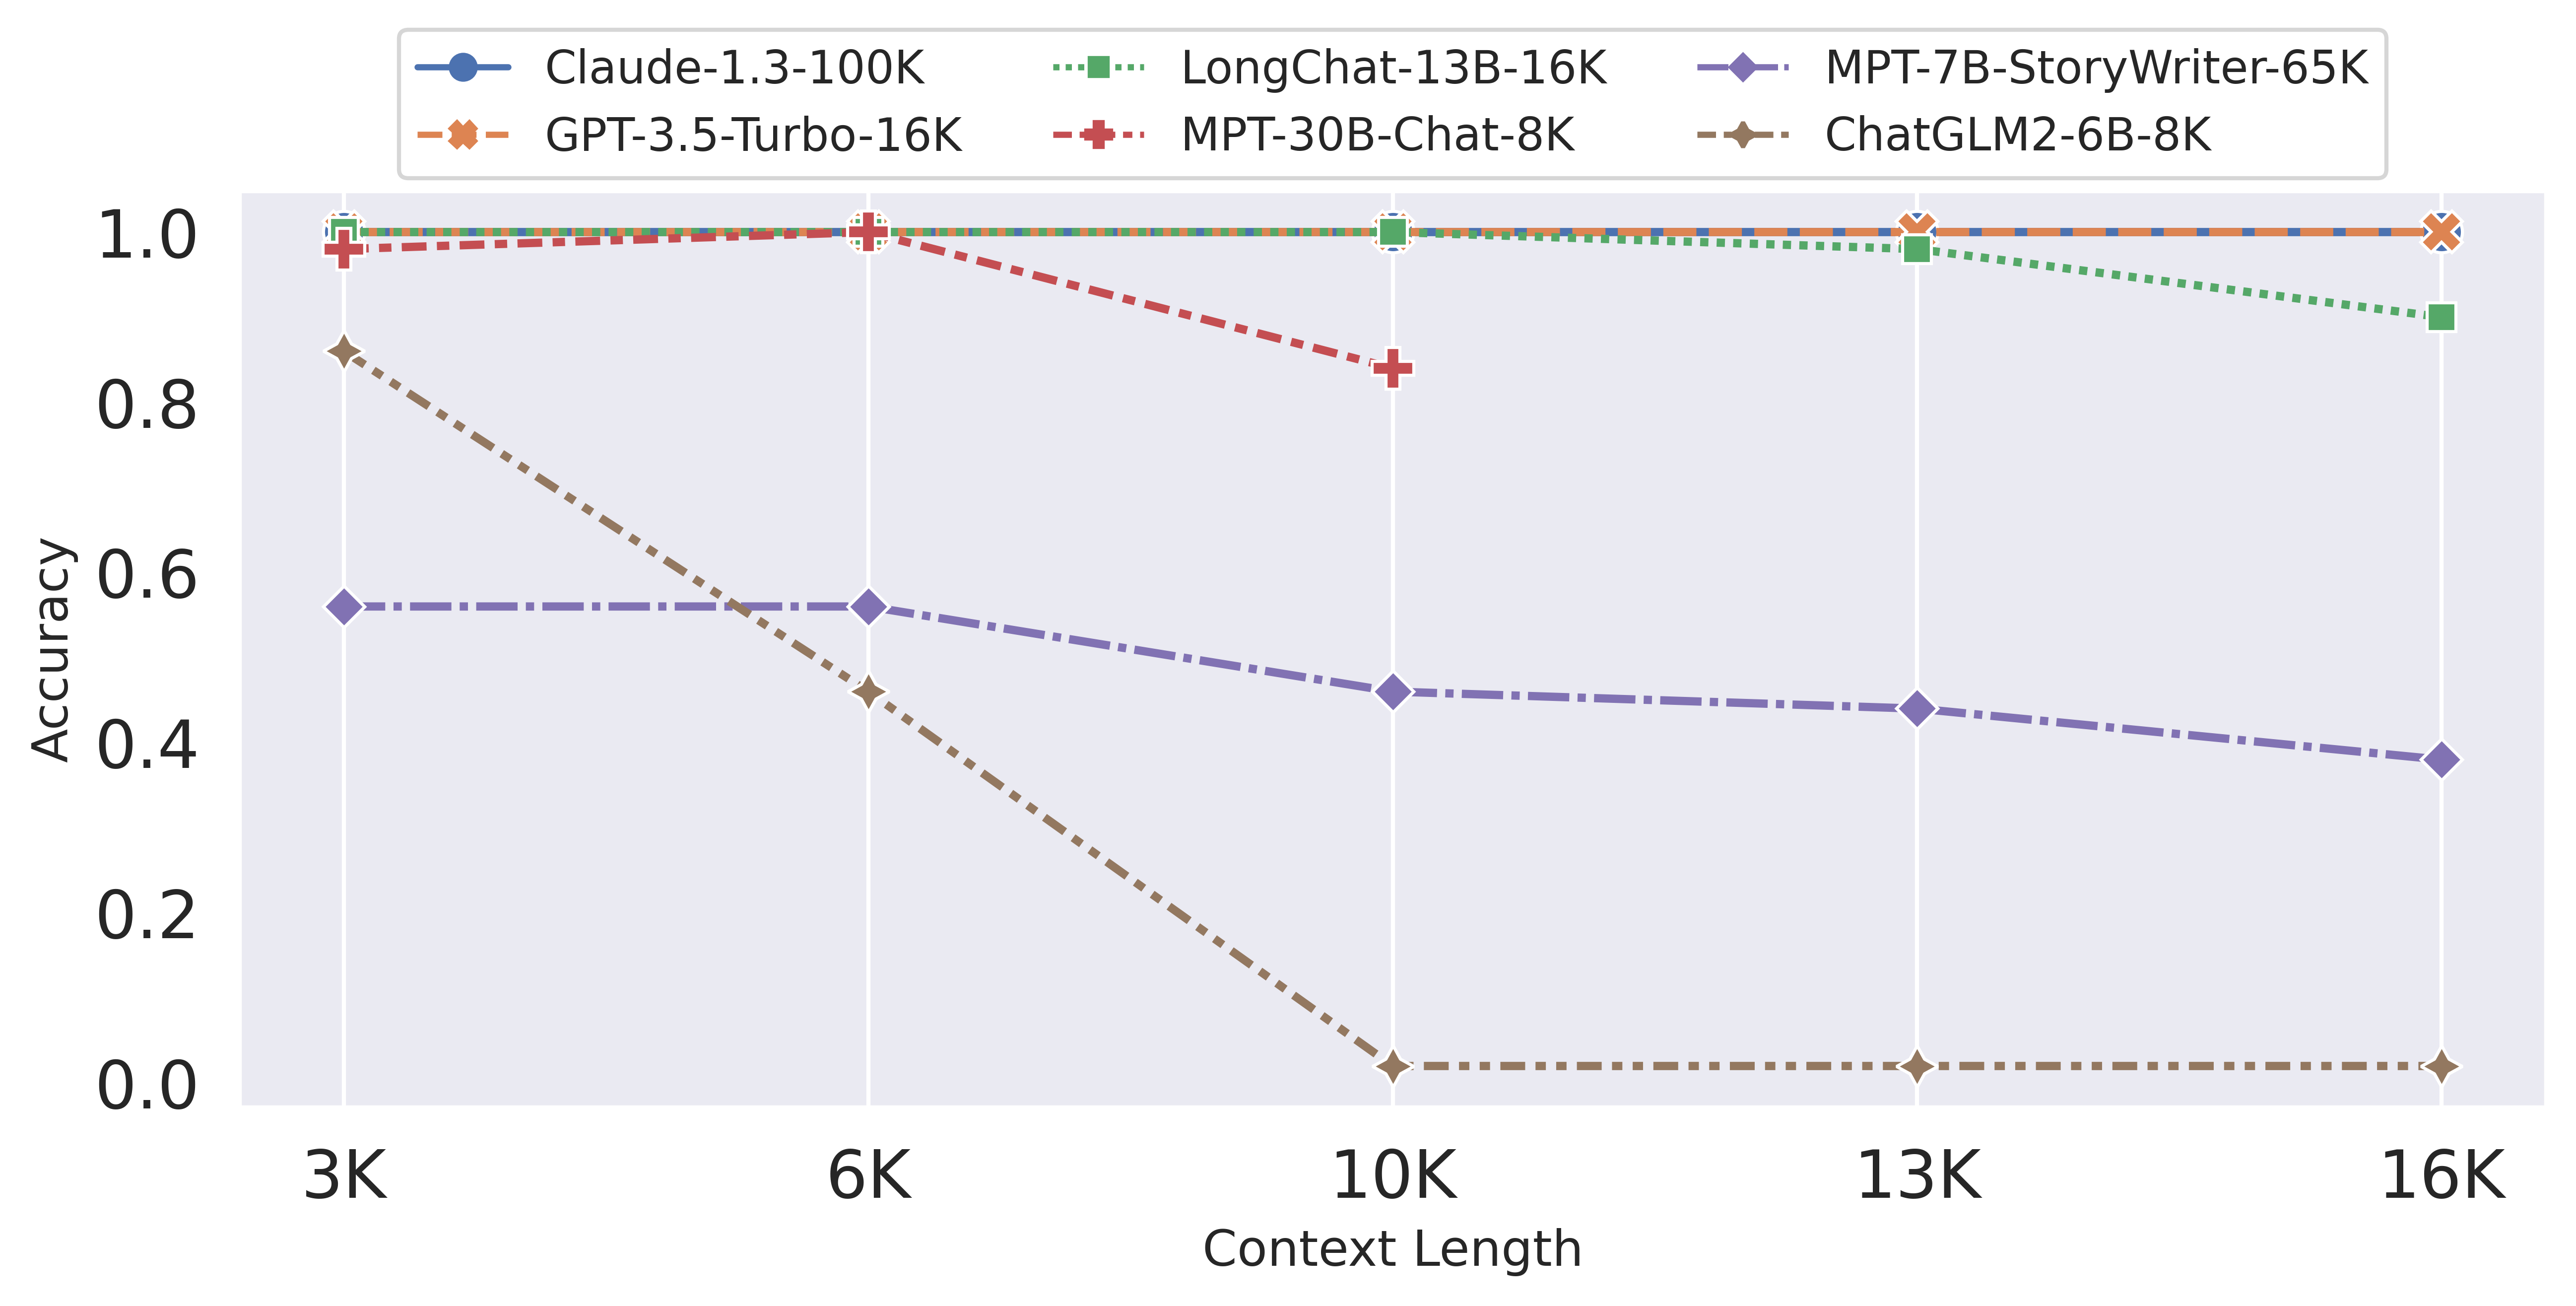
How Long Can Open-Source LLMs Truly Promise on Context Length? - LMSYS ...
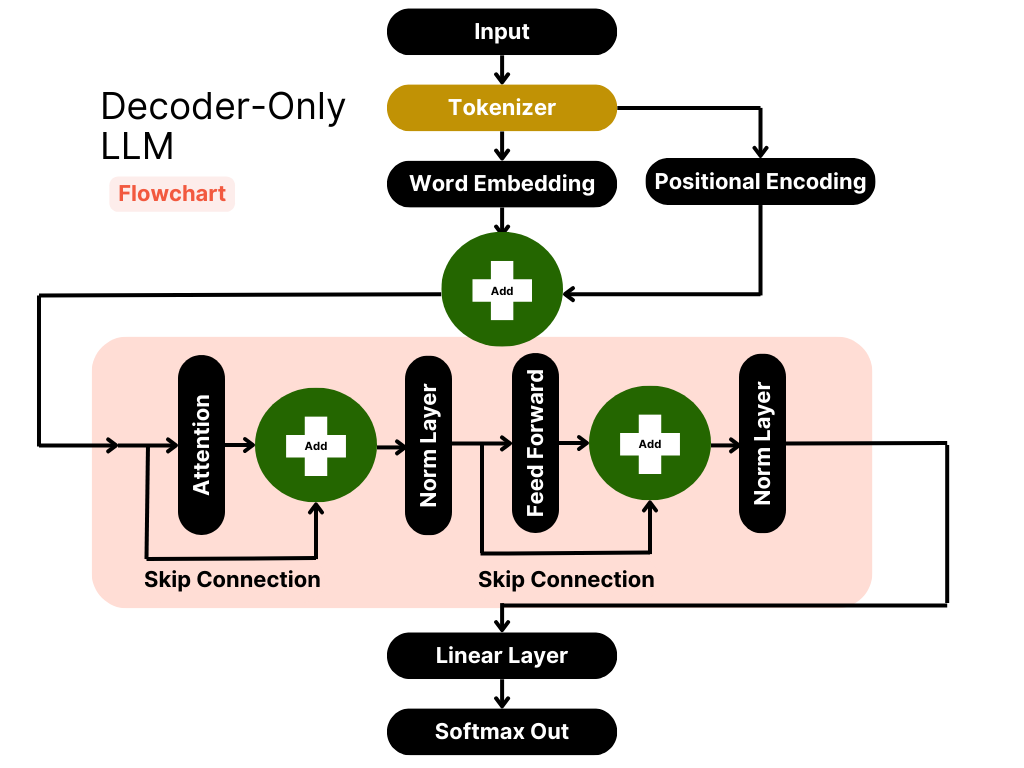
Streaming LLM Output with Django, React, and LangChain | by Maxim ...

DuoAttention: Efficient Long-Context LLM Inference with Retrieval and ...

Serving Inference for LLMs: A Case Study with NVIDIA Triton Inference ...
Advertisement Space (336x280)
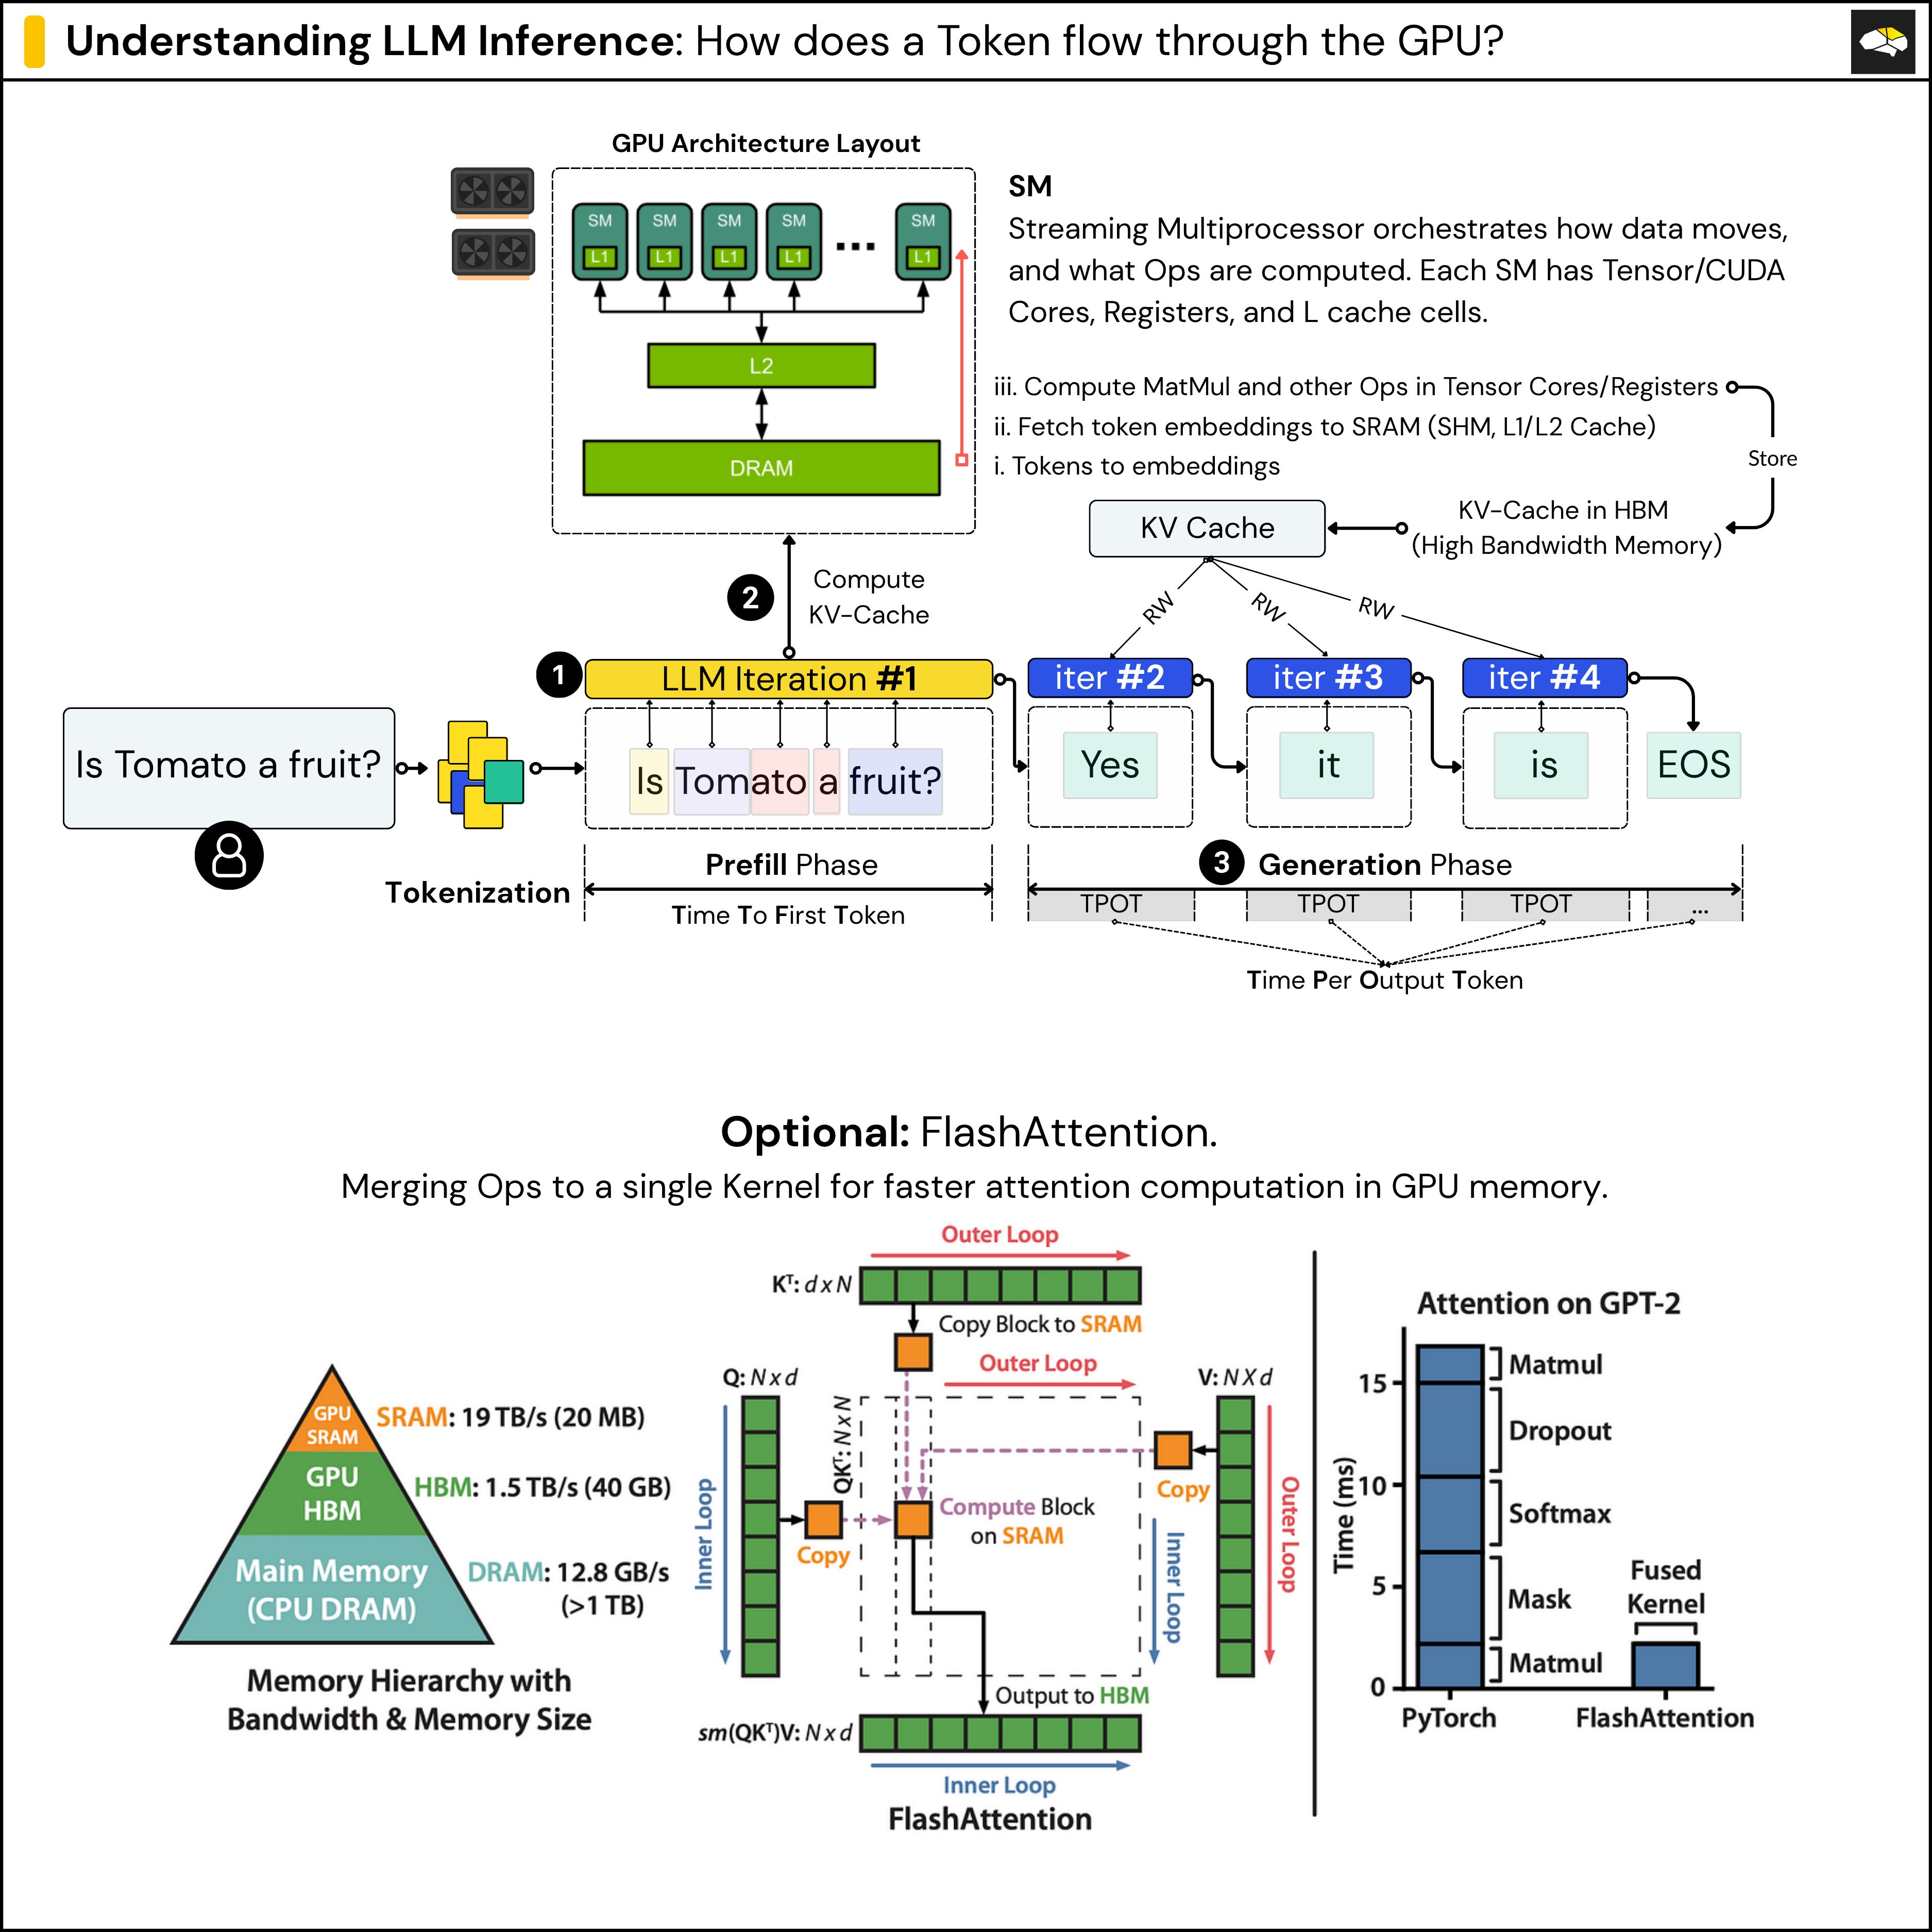
Understanding LLM Inference - by Alex Razvant
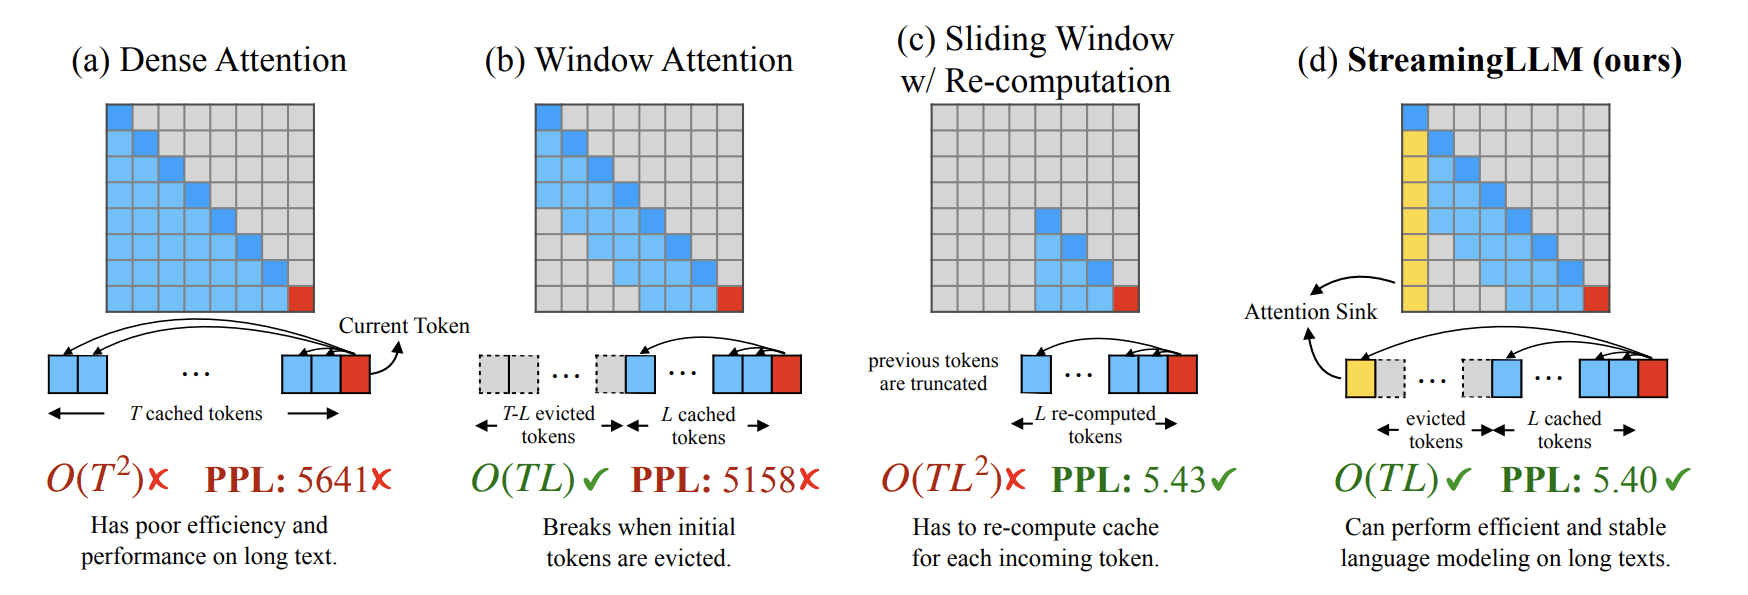
Introduction to Streaming-LLM: LLMs for Infinite-Length Inputs - KDnuggets

RetrievalAttention: Accelerating Long-Context LLM Inference via Vector ...

MILLION: Mastering Long-Context LLM Inference Via Outlier-Immunized KV ...

Accelerating LLM Inference: Introducing SampleAttention for Efficient ...
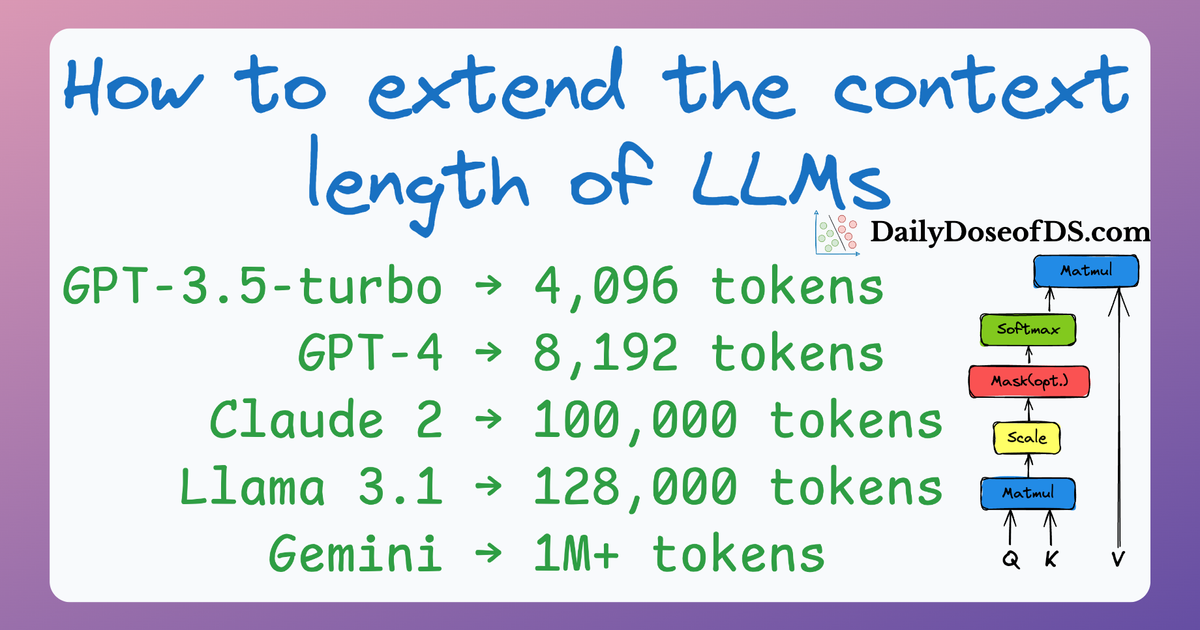
Techniques to Extend Context Length of LLMs