
Metric Gpu Kv Cache Usage Deka Gpu Documentations
Metric: GPU KV Cache Usage | Deka GPU Documentations
Example: Autoscaling vLLM with KEDA based on GPU KV Cache Usage ...
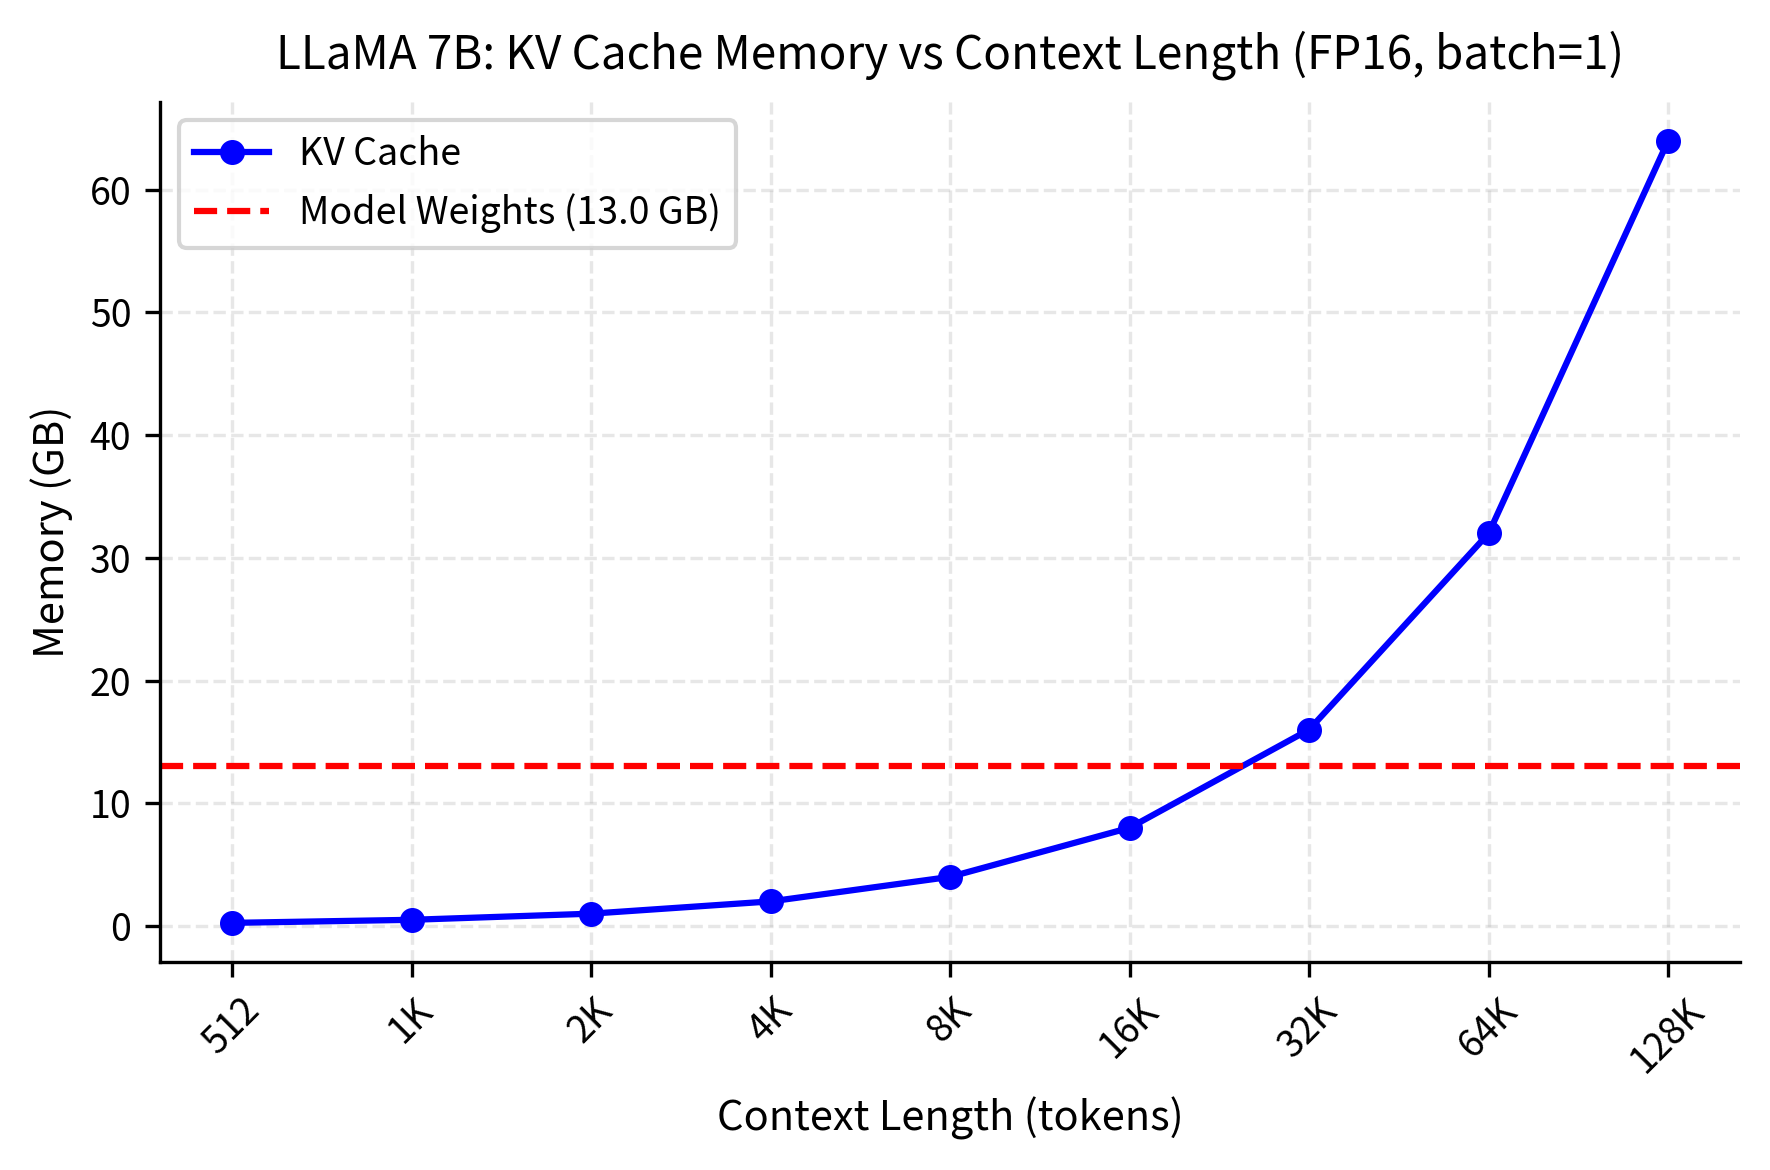
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...
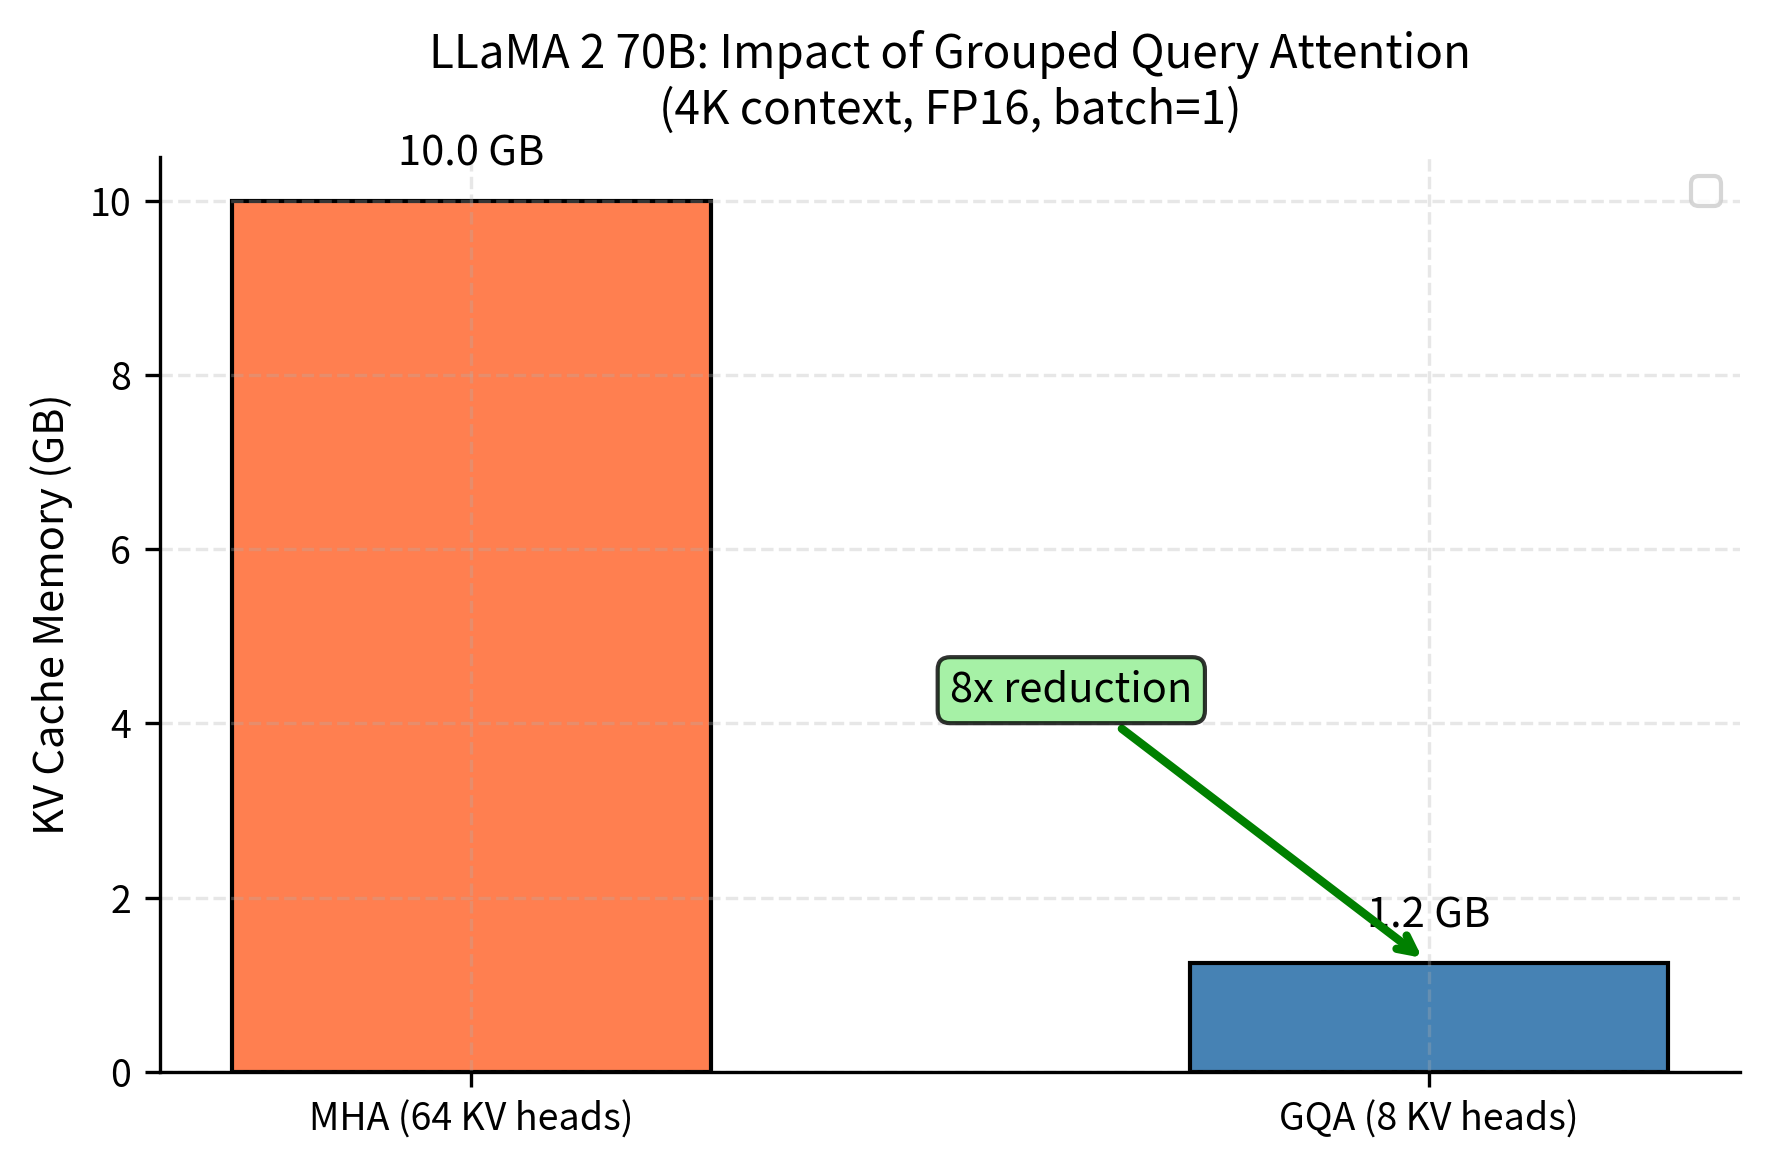
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...
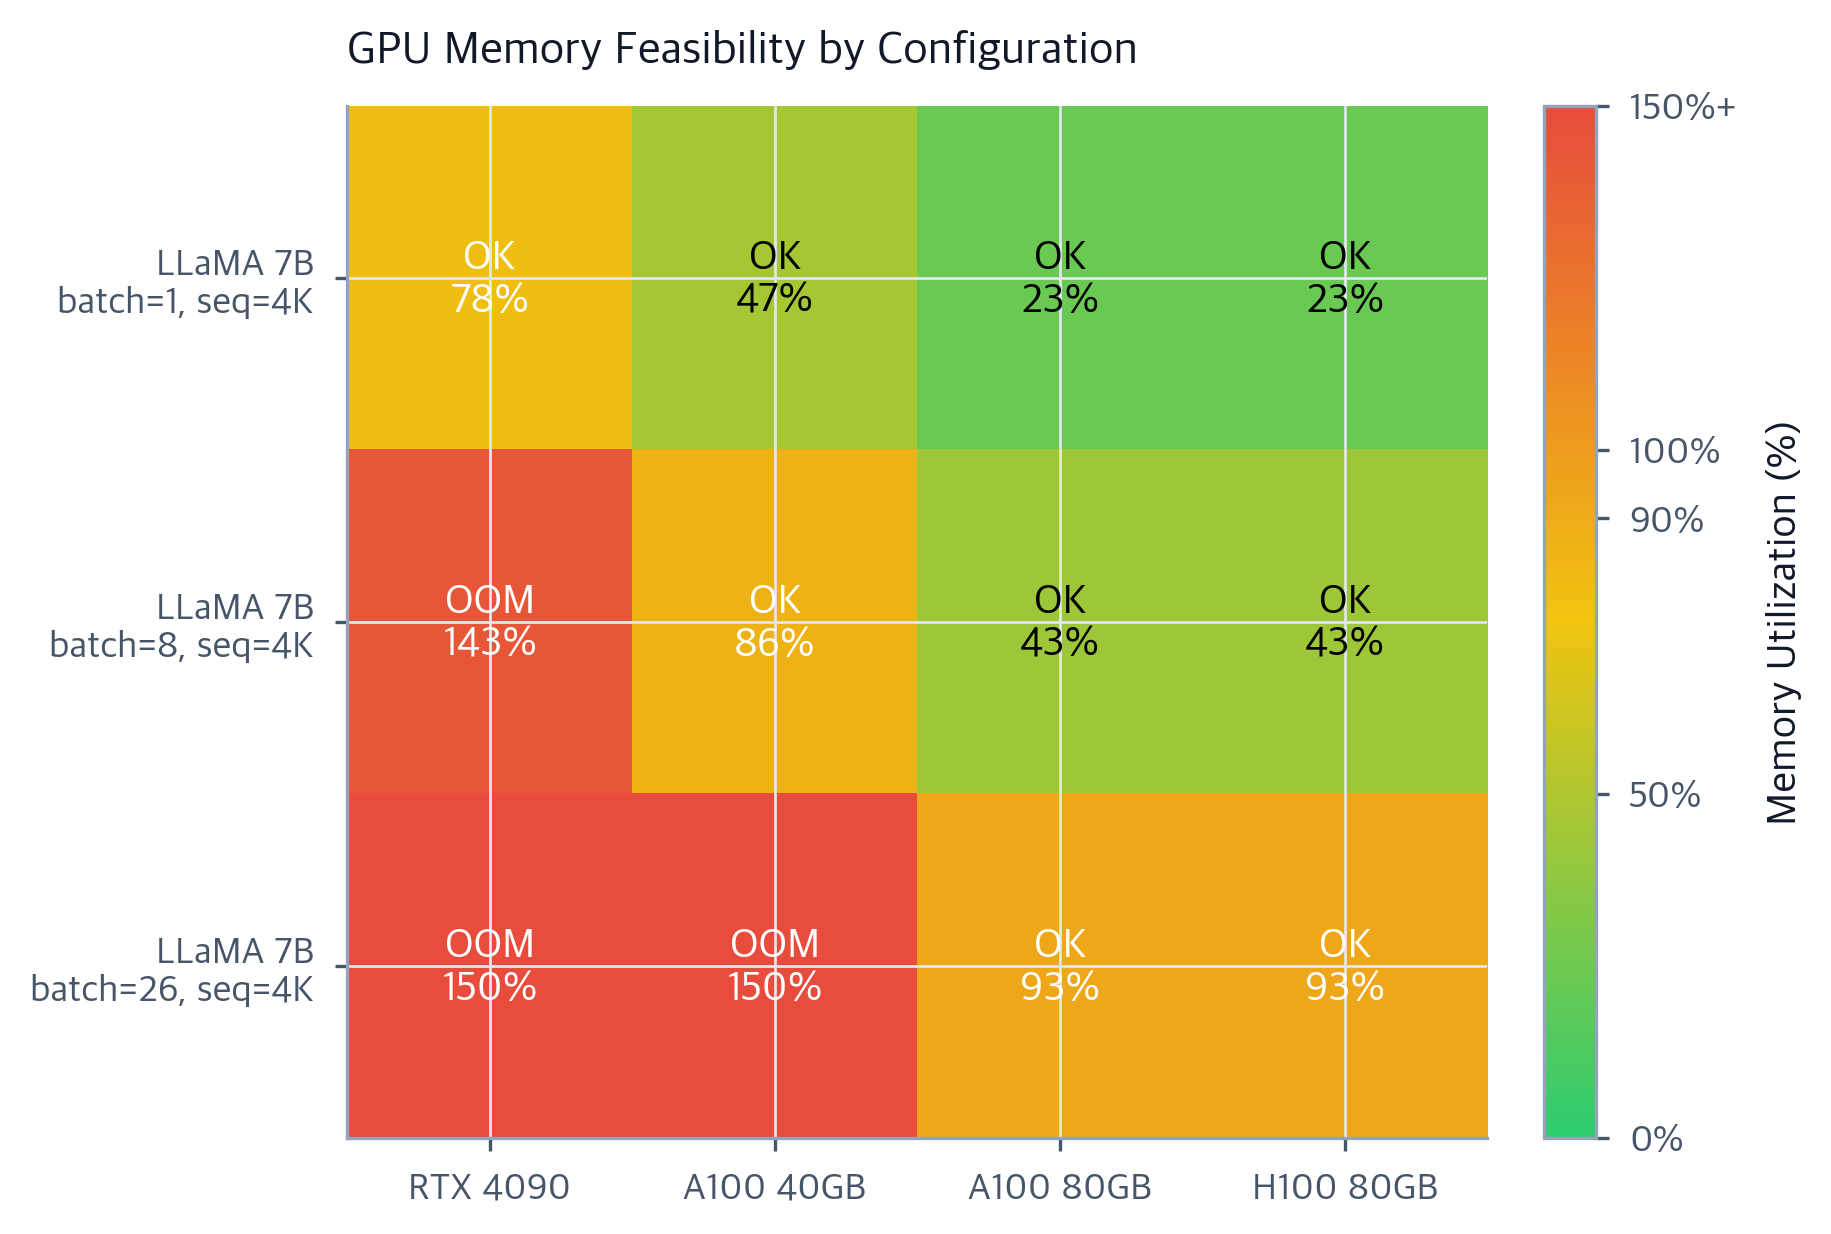
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...
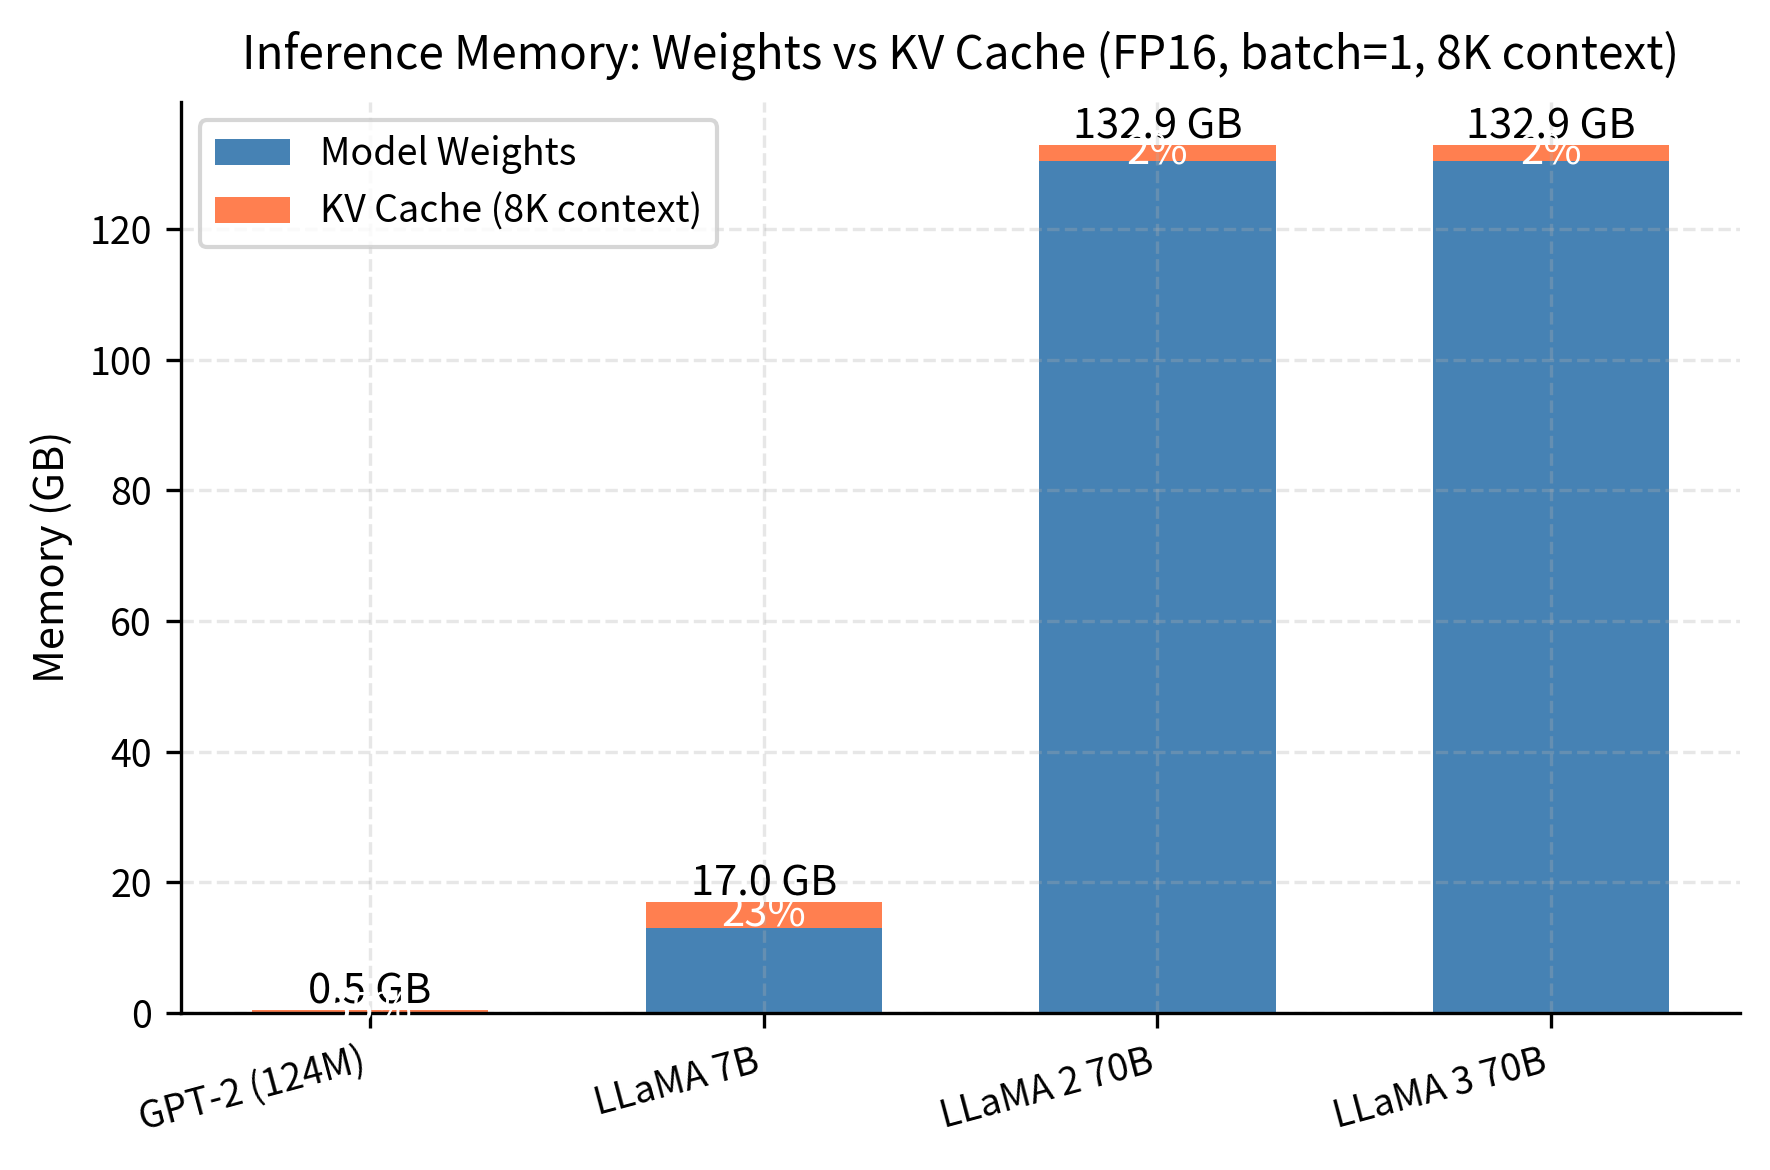
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...
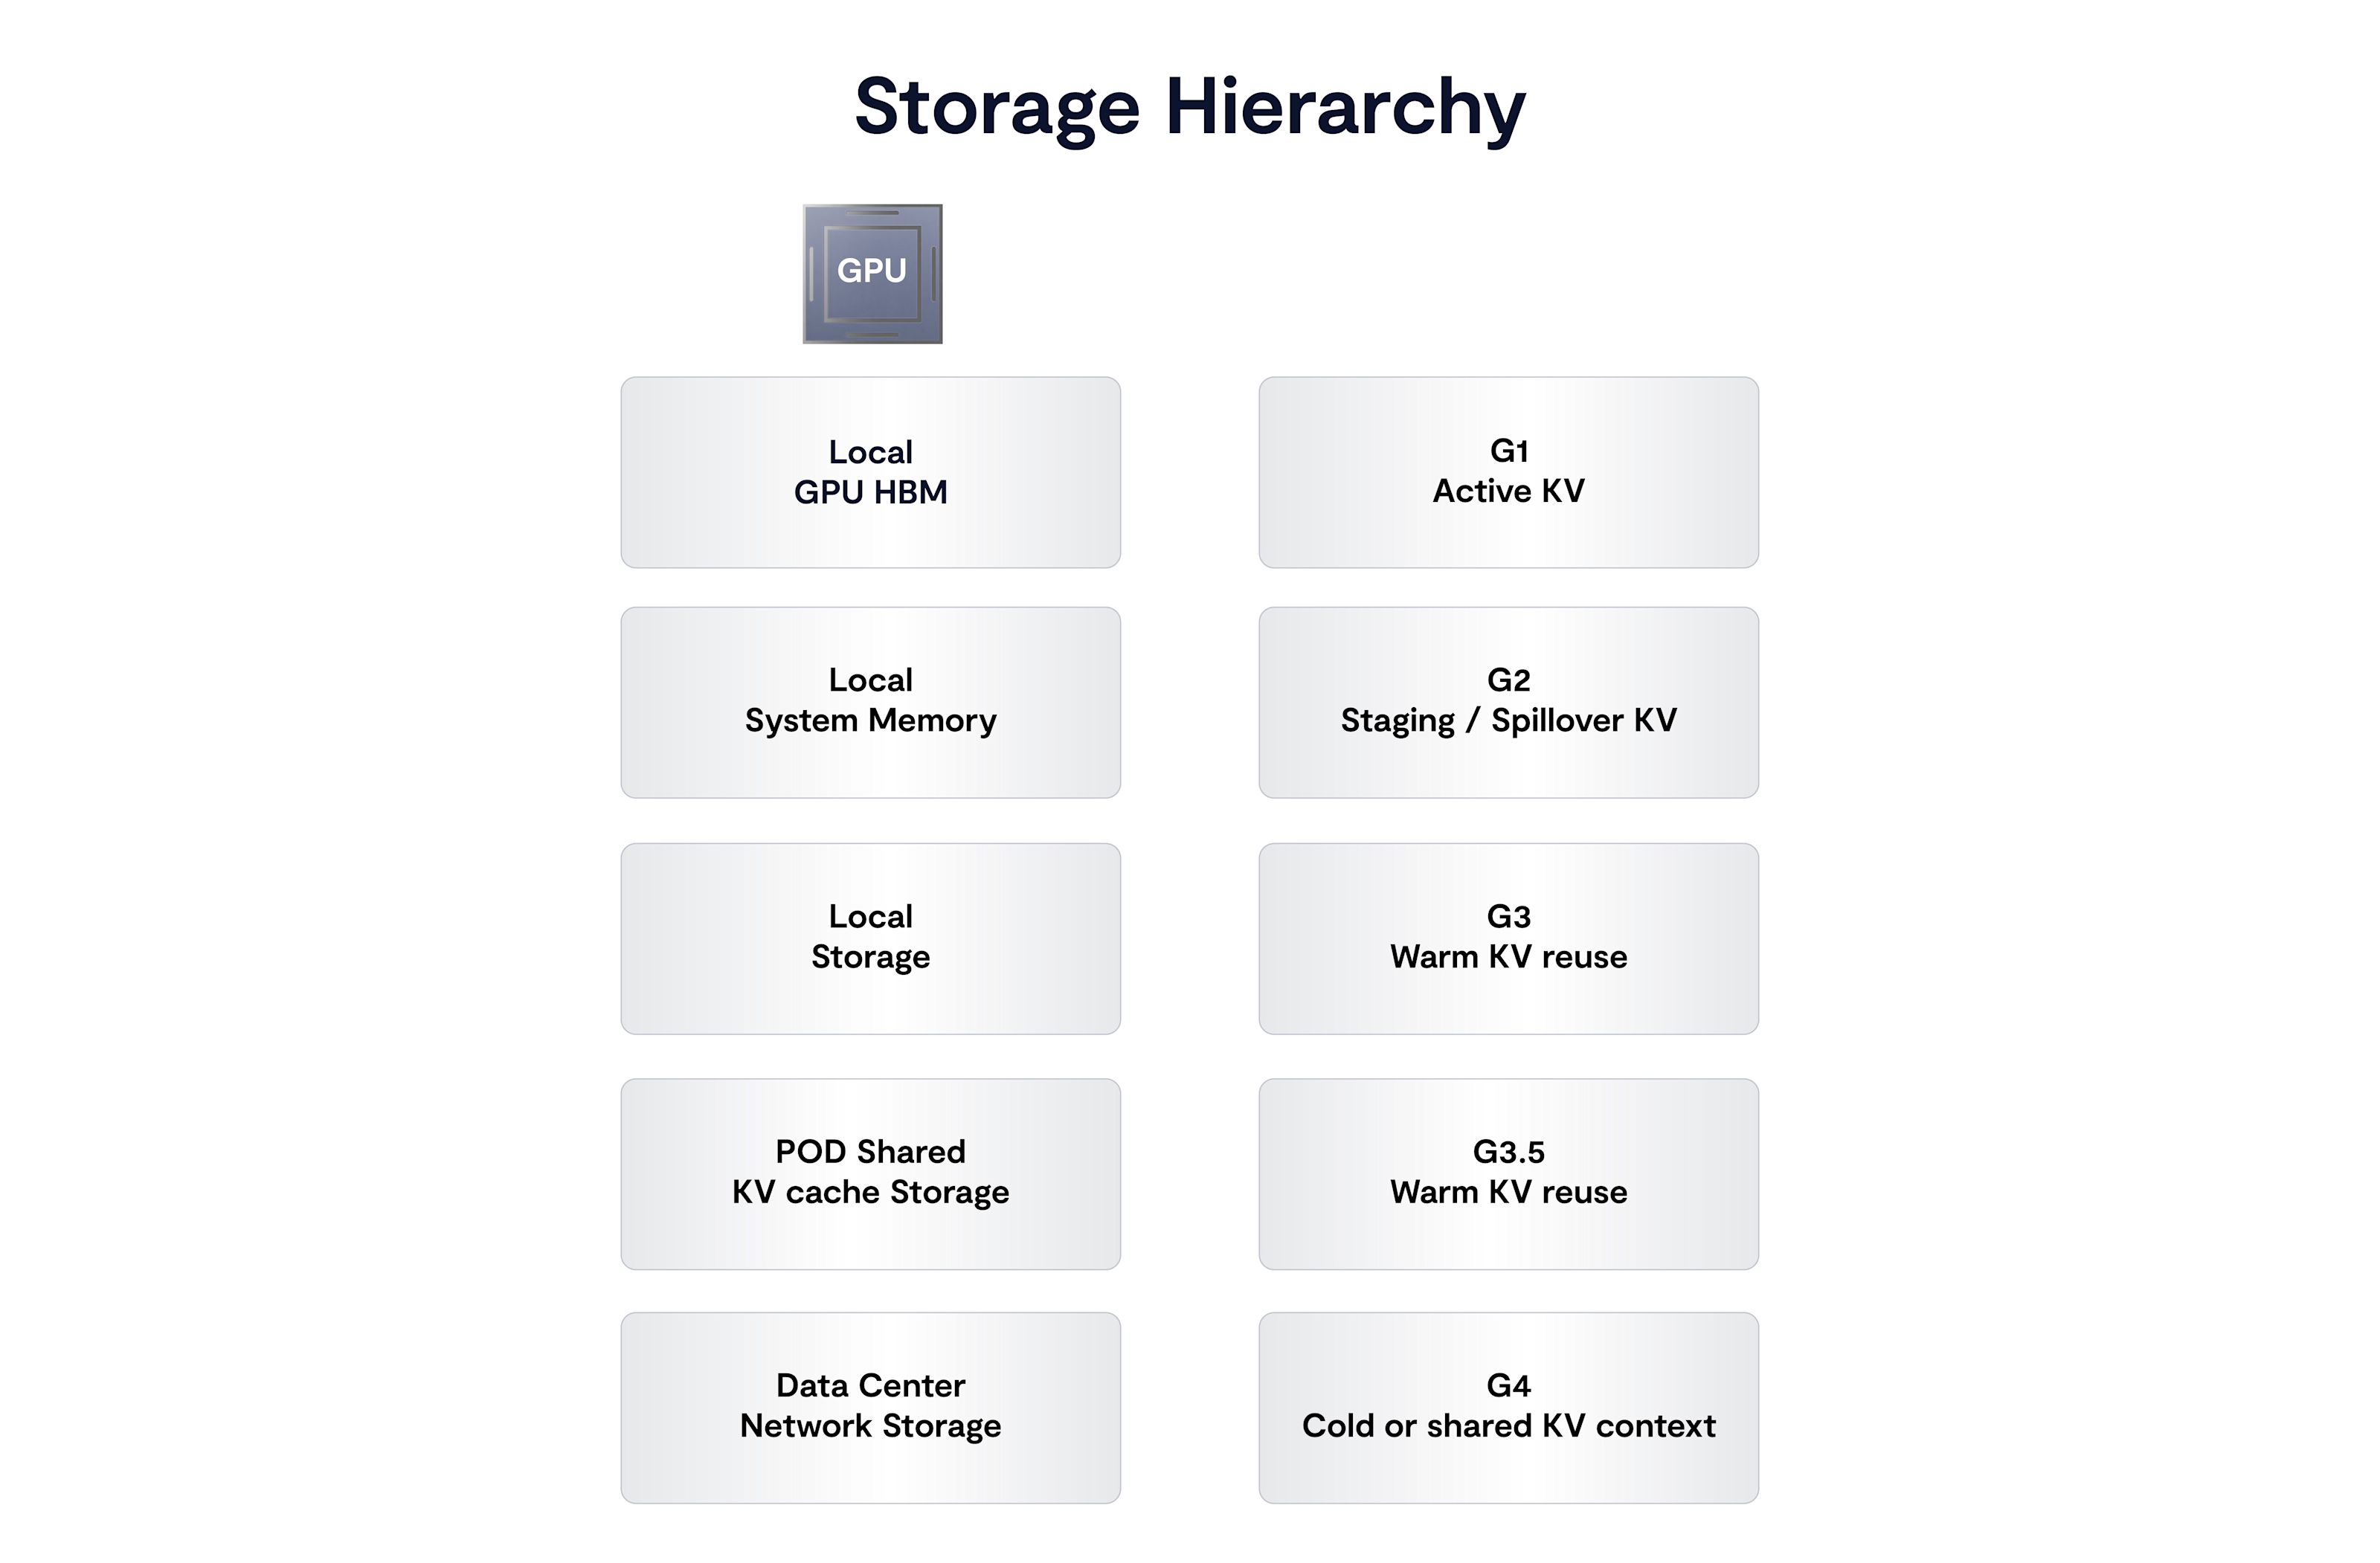
Stop Wasting GPU Cycles: A Practical Guide to Right-Sizing KV Cache ...
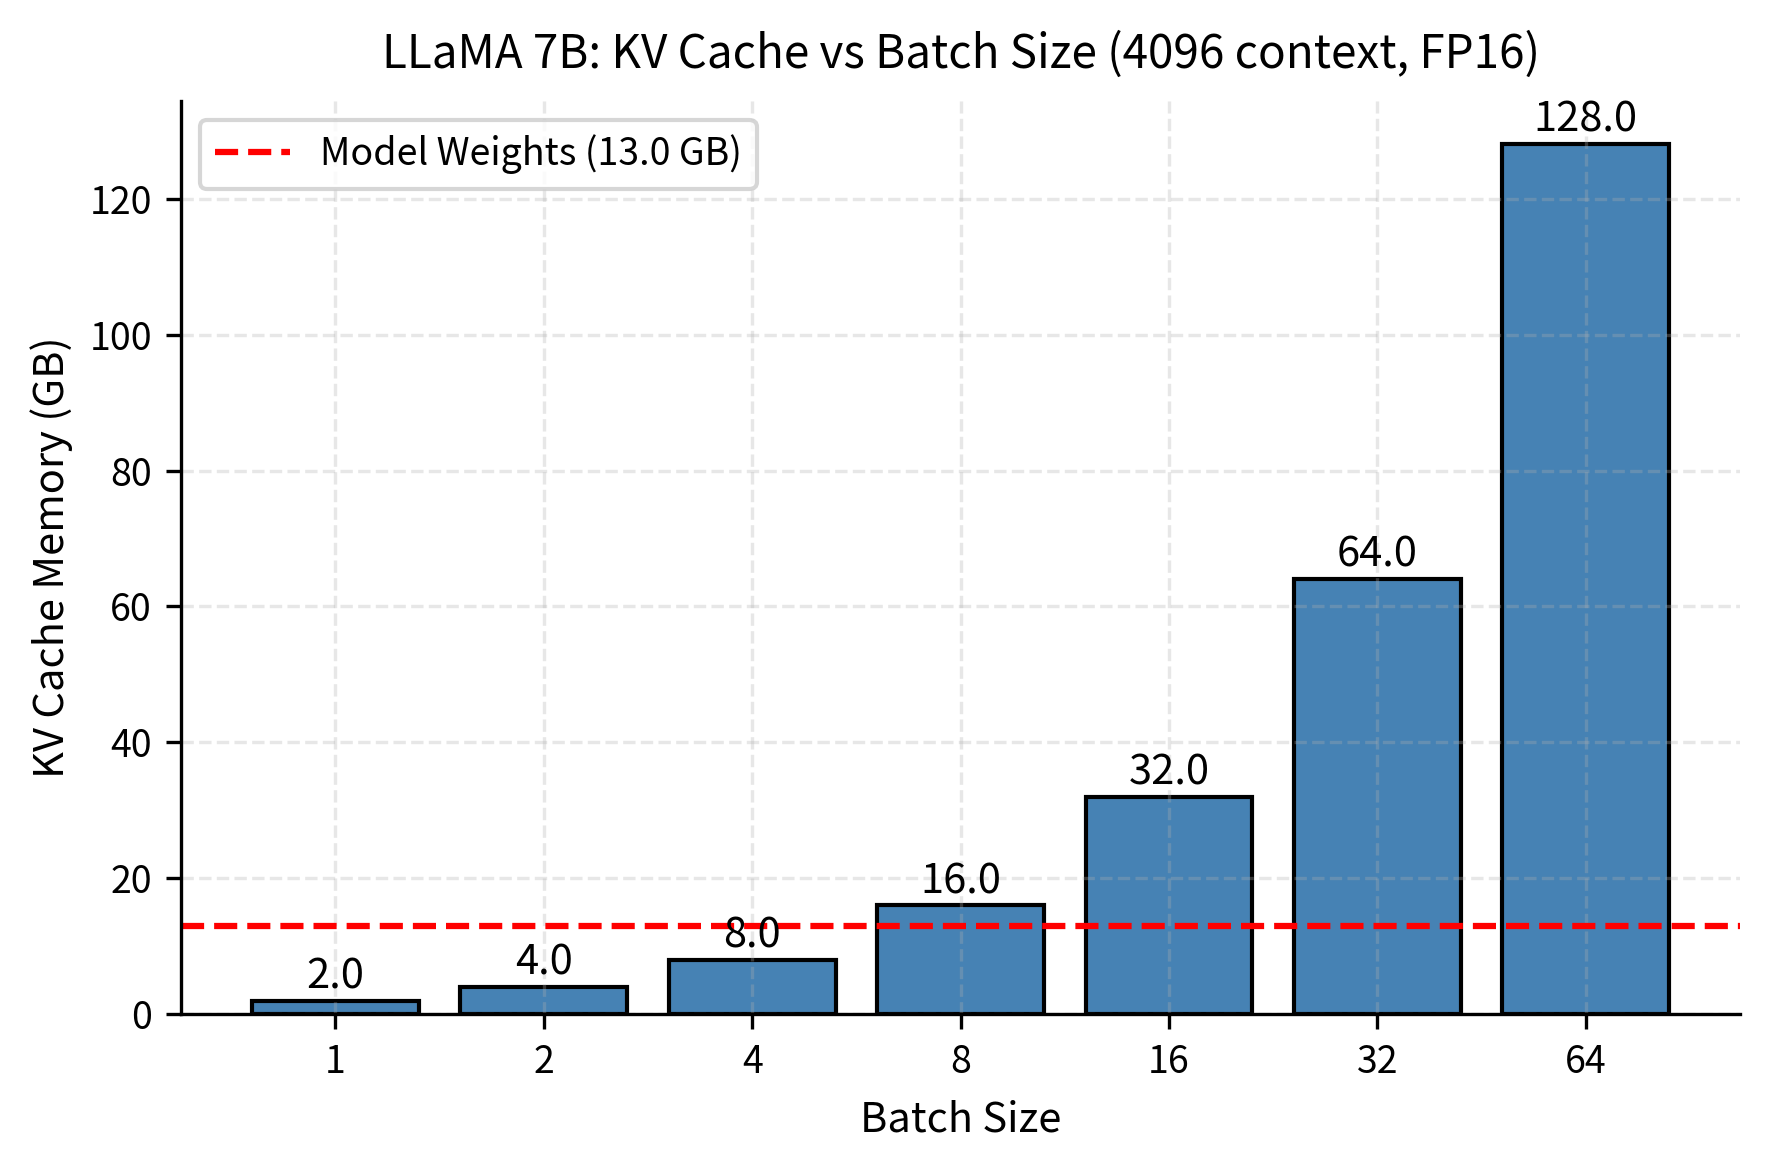
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...
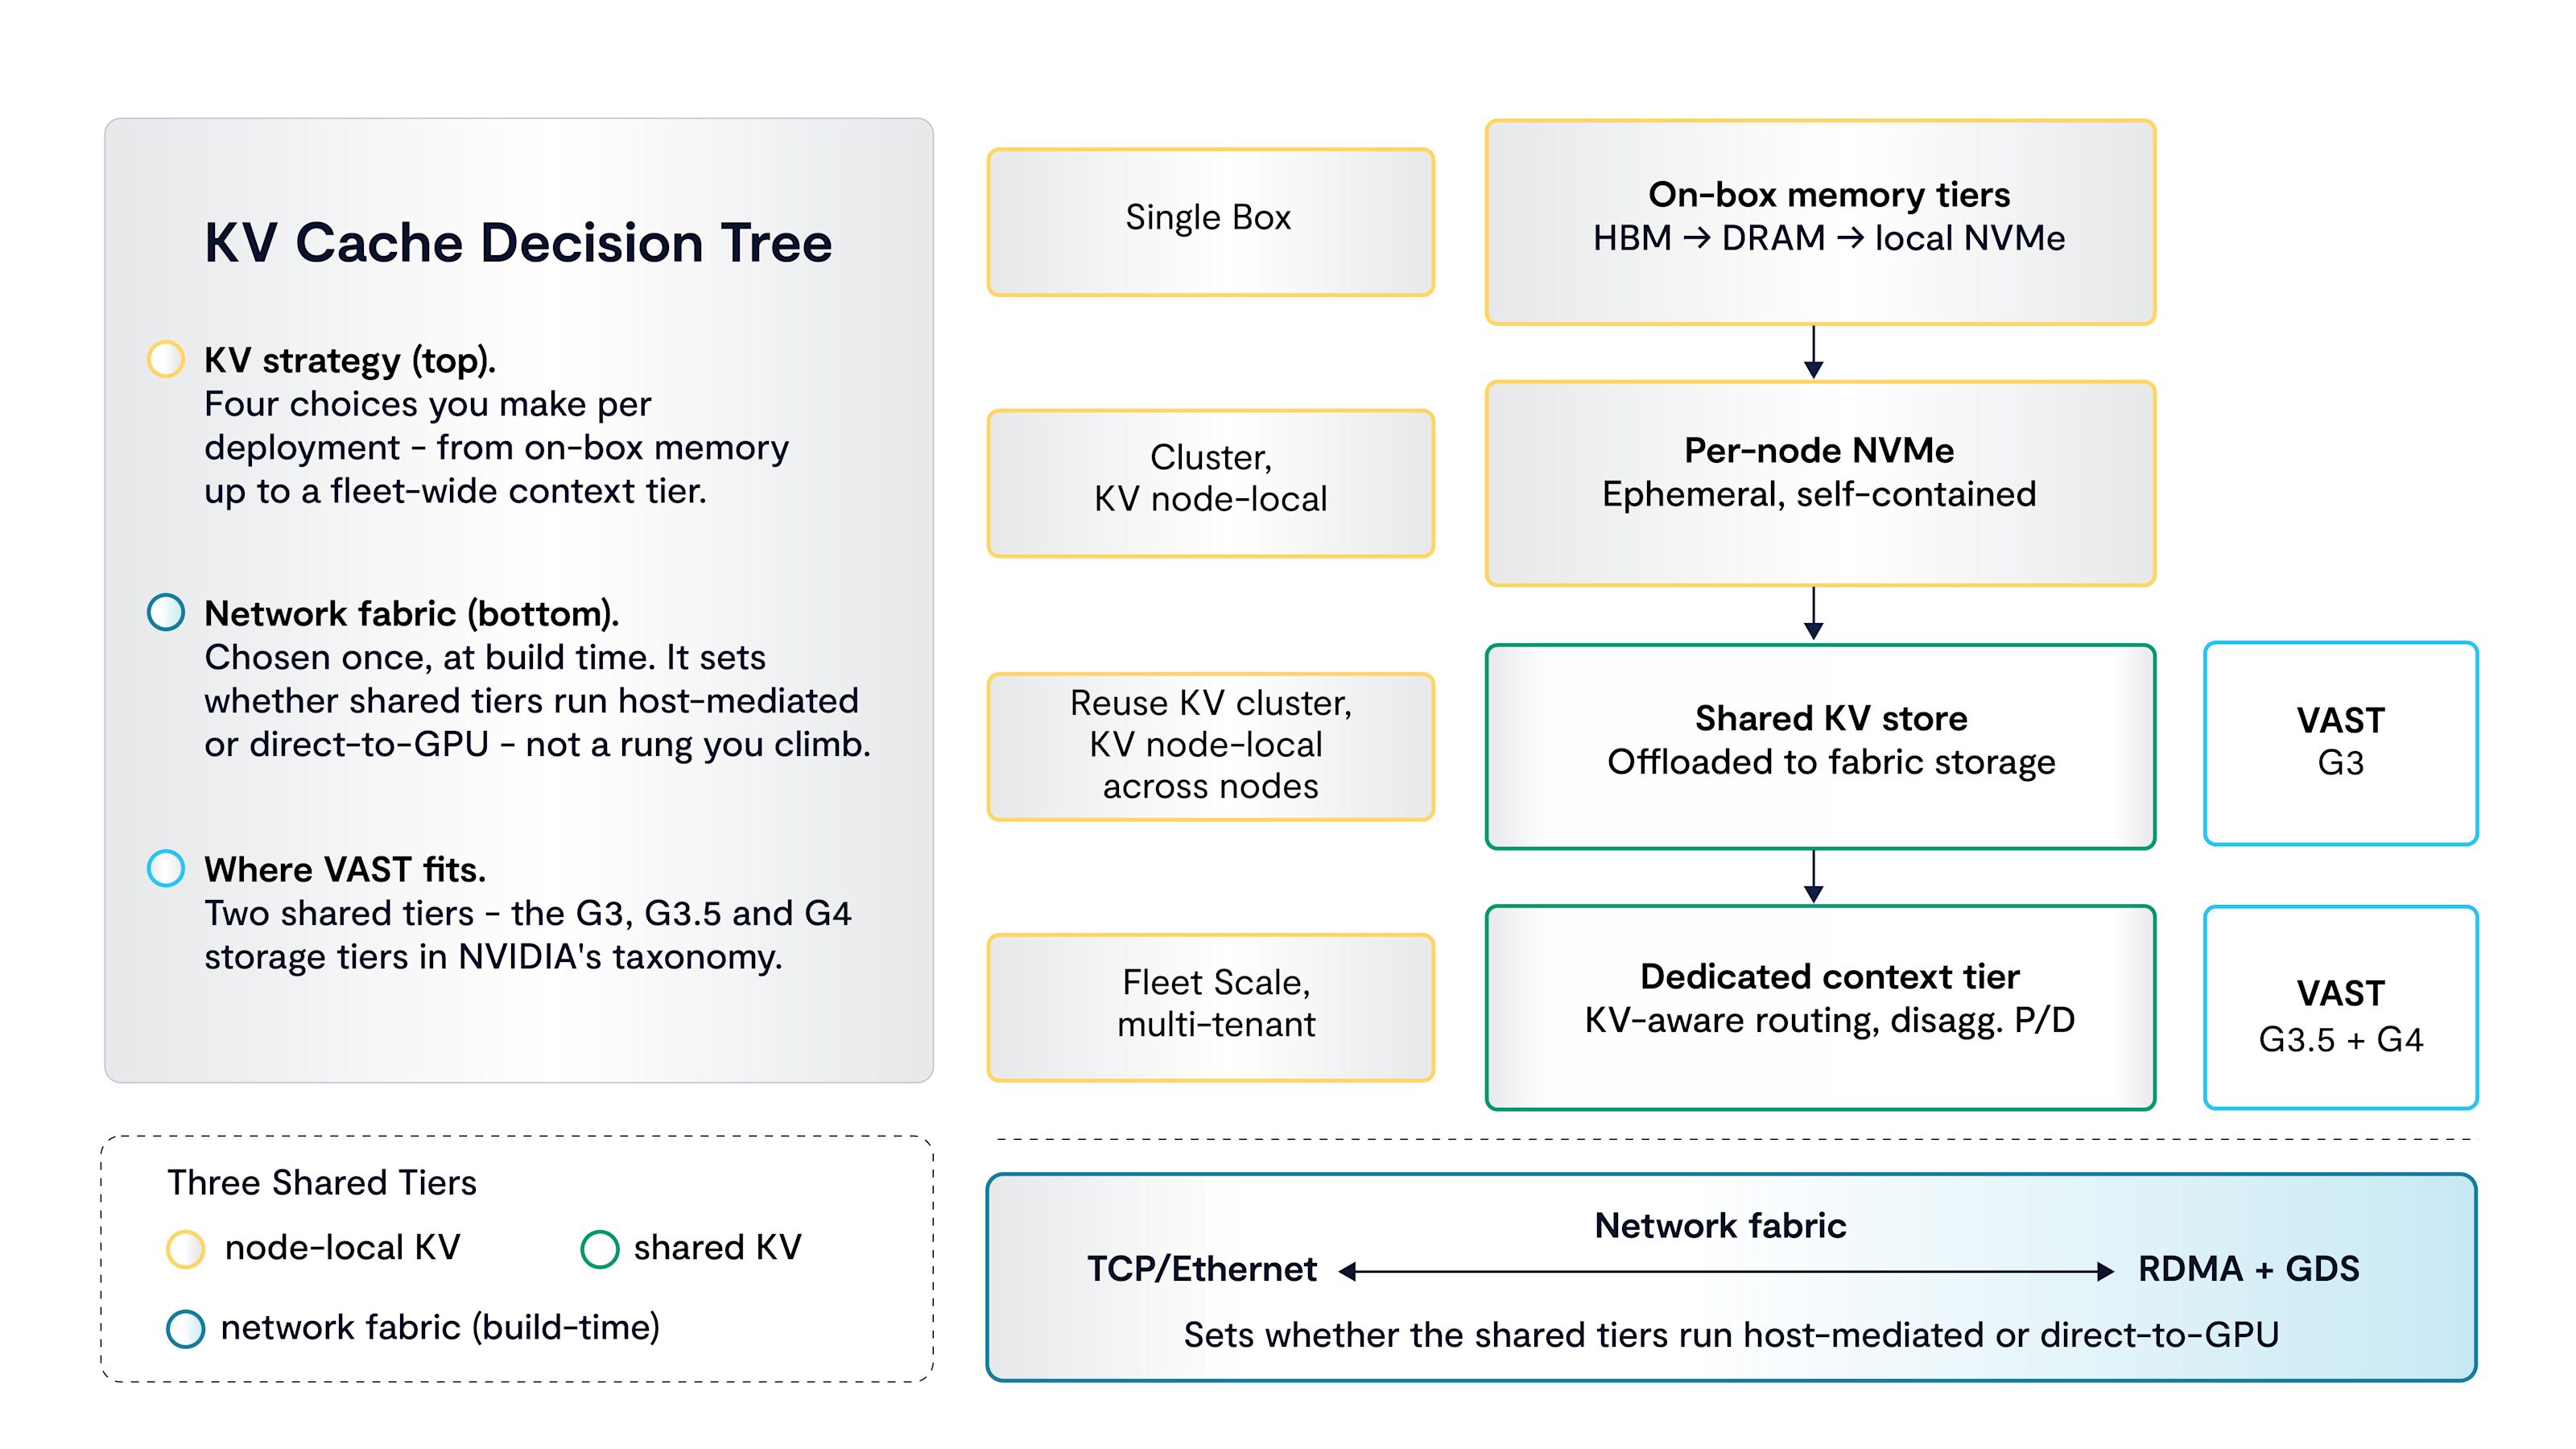
Stop Wasting GPU Cycles: A Practical Guide to Right-Sizing KV Cache ...
KV Cache Sizing — GPU Memory for LLM Serving | tutorialQ
Advertisement Space (300x250)
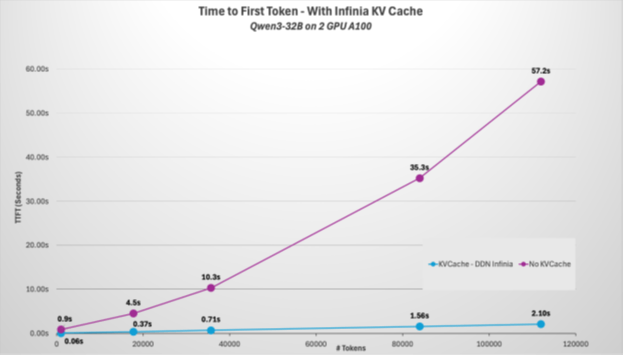
How DDN Eliminates the GPU Waste Spiral for AI Reasoning with KV Cache
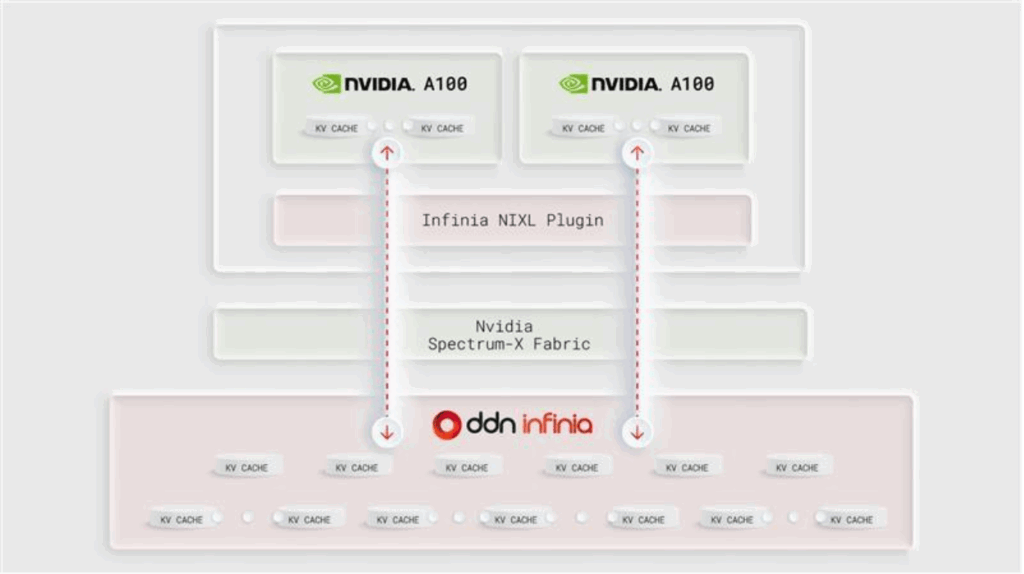
How DDN Eliminates the GPU Waste Spiral for AI Reasoning with KV Cache
KV Cache Optimization: Serve 10x More Users on the Same GPU (2026 ...

GPU 已经等不起了:KV Cache 语义化催生的 AI 存储大变局_阿里云瑶池数据库kvcache亮相nvidia gtc2026-CSDN博客

Get Real-Time Visibility into GPU Usage Across Kubernetes Clusters ...
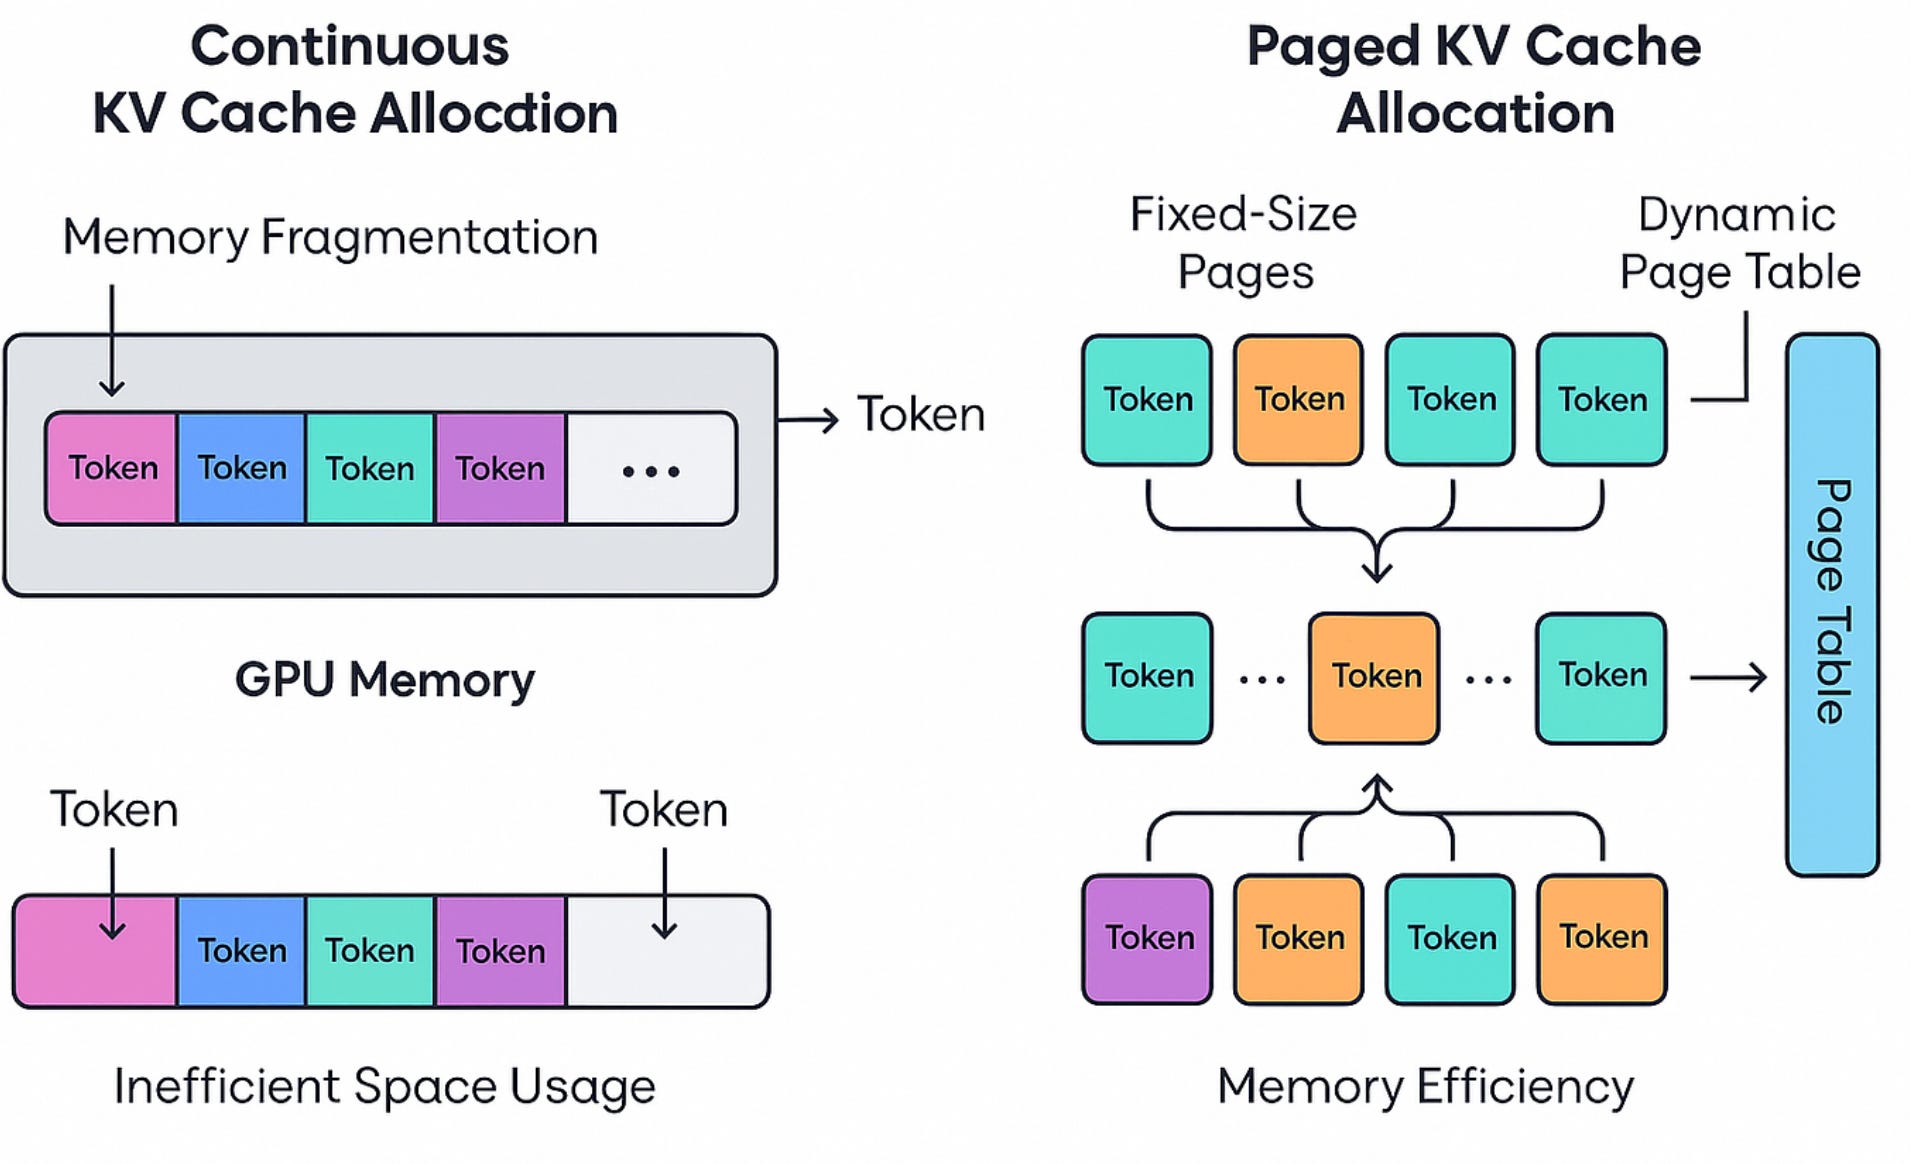
The Hidden Cost of LLM Infrastructure: How MLOps Mistakes Waste GPU ...
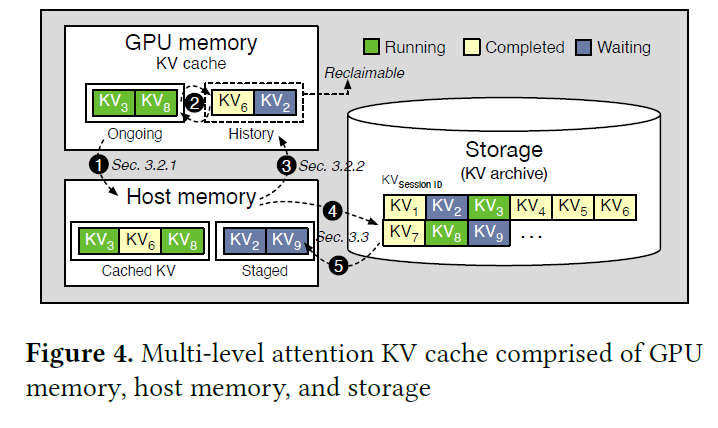
CUDA Meets Python: How NVIDIA Is Ushering in a New Era of GPU ...

How to Reduce KV Cache Bottlenecks with NVIDIA Dynamo | NVIDIA ...

Tutti: Making SSD-Backed KV Cache Practical for Long-Context LLM Serving

5x Faster Time to First Token with NVIDIA TensorRT-LLM KV Cache Early ...
Advertisement Space (336x280)
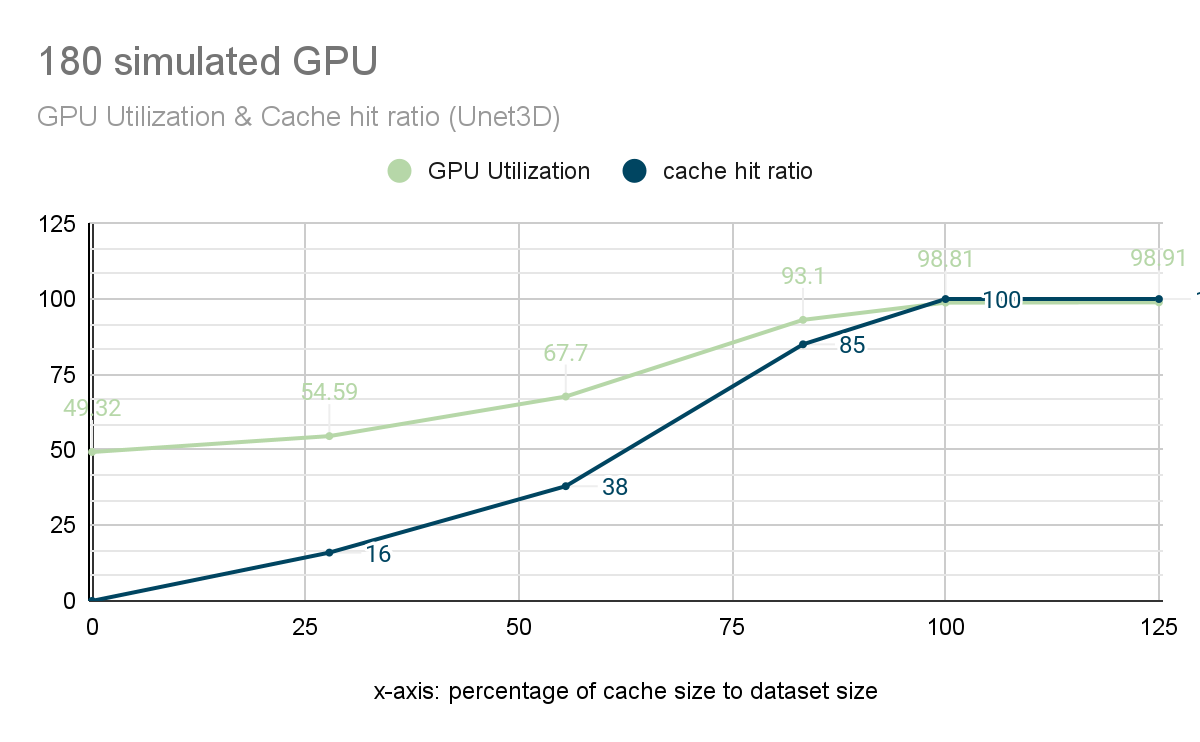
98% GPU Utilization Achieved in 1k GPU-Scale AI Training Using ...
Accelerate Large-Scale LLM Inference and KV Cache Offload with CPU-GPU ...

Understanding and Coding the KV Cache in LLMs from Scratch

Host KV Cache for Dedicated Endpoints | FriendliAI
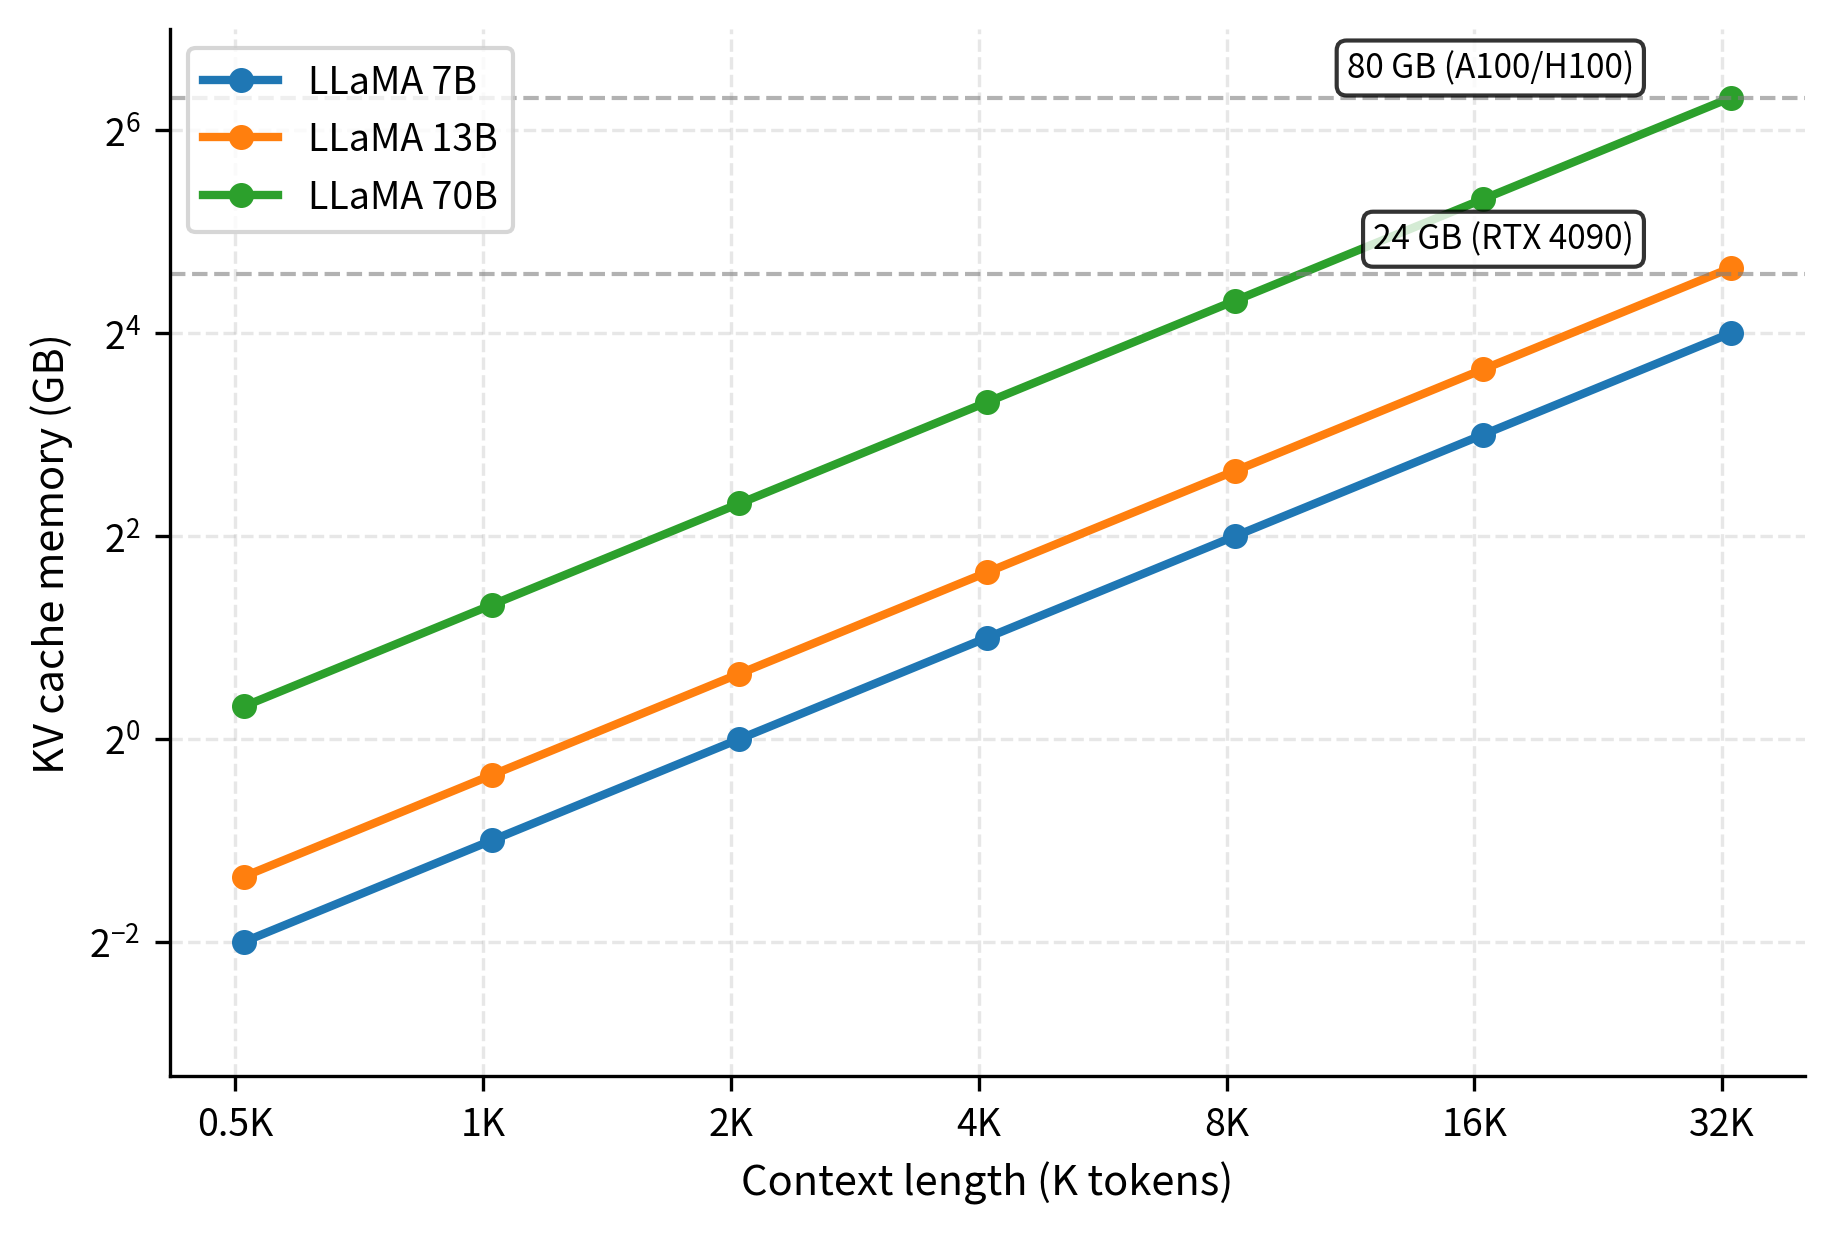
KV Cache Explained: Efficient Attention for LLM Generation ...

Scaling Multi-Turn LLM Inference with KV Cache Storage Offload and Dell ...
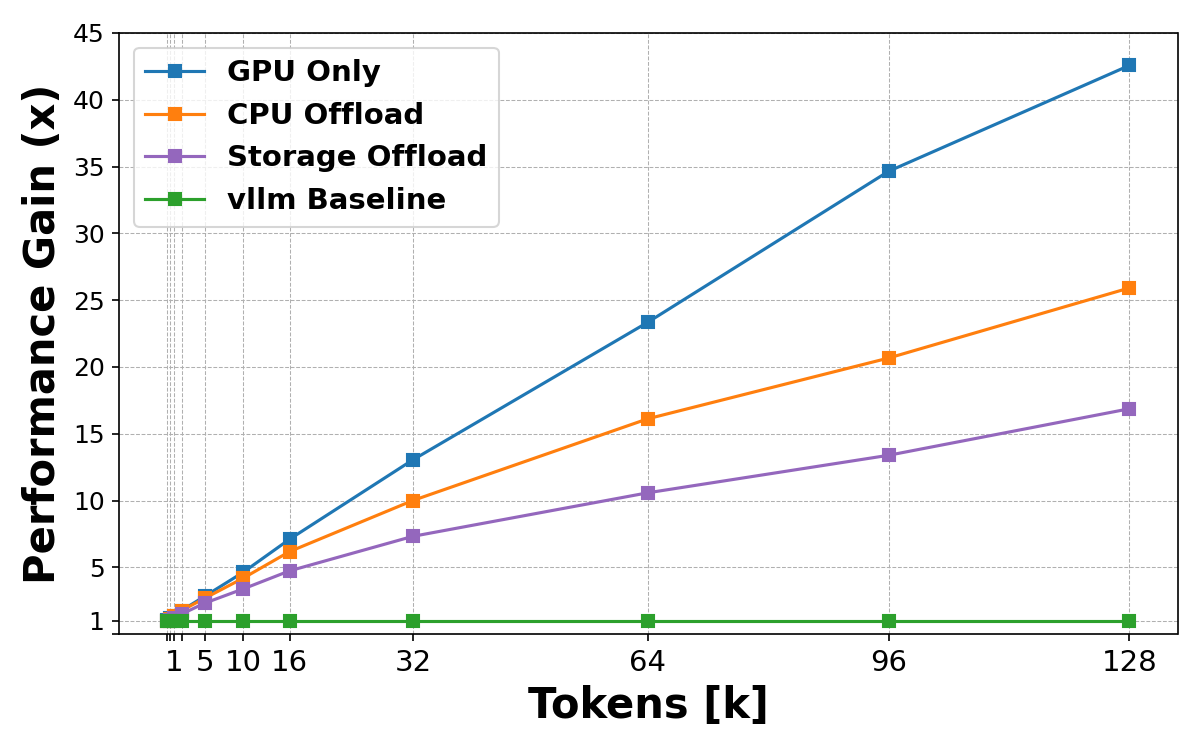
Native KV Cache Offloading to Any Filesystem with llm-d | llm-d
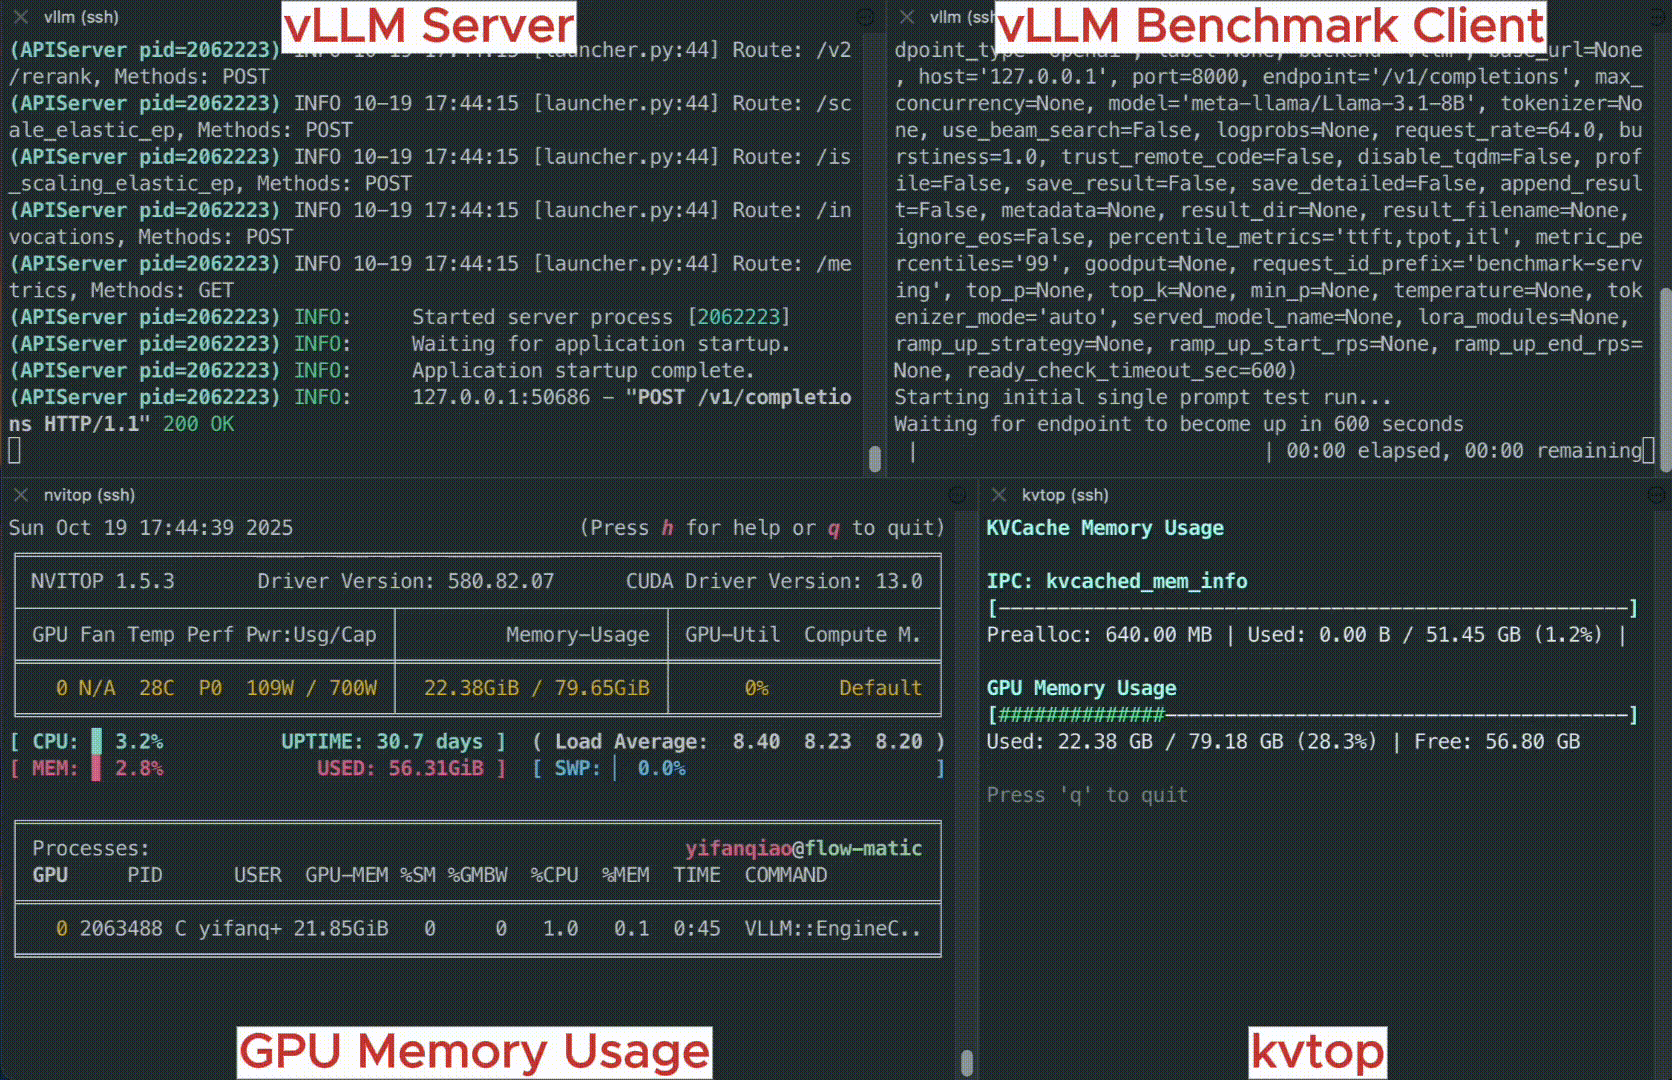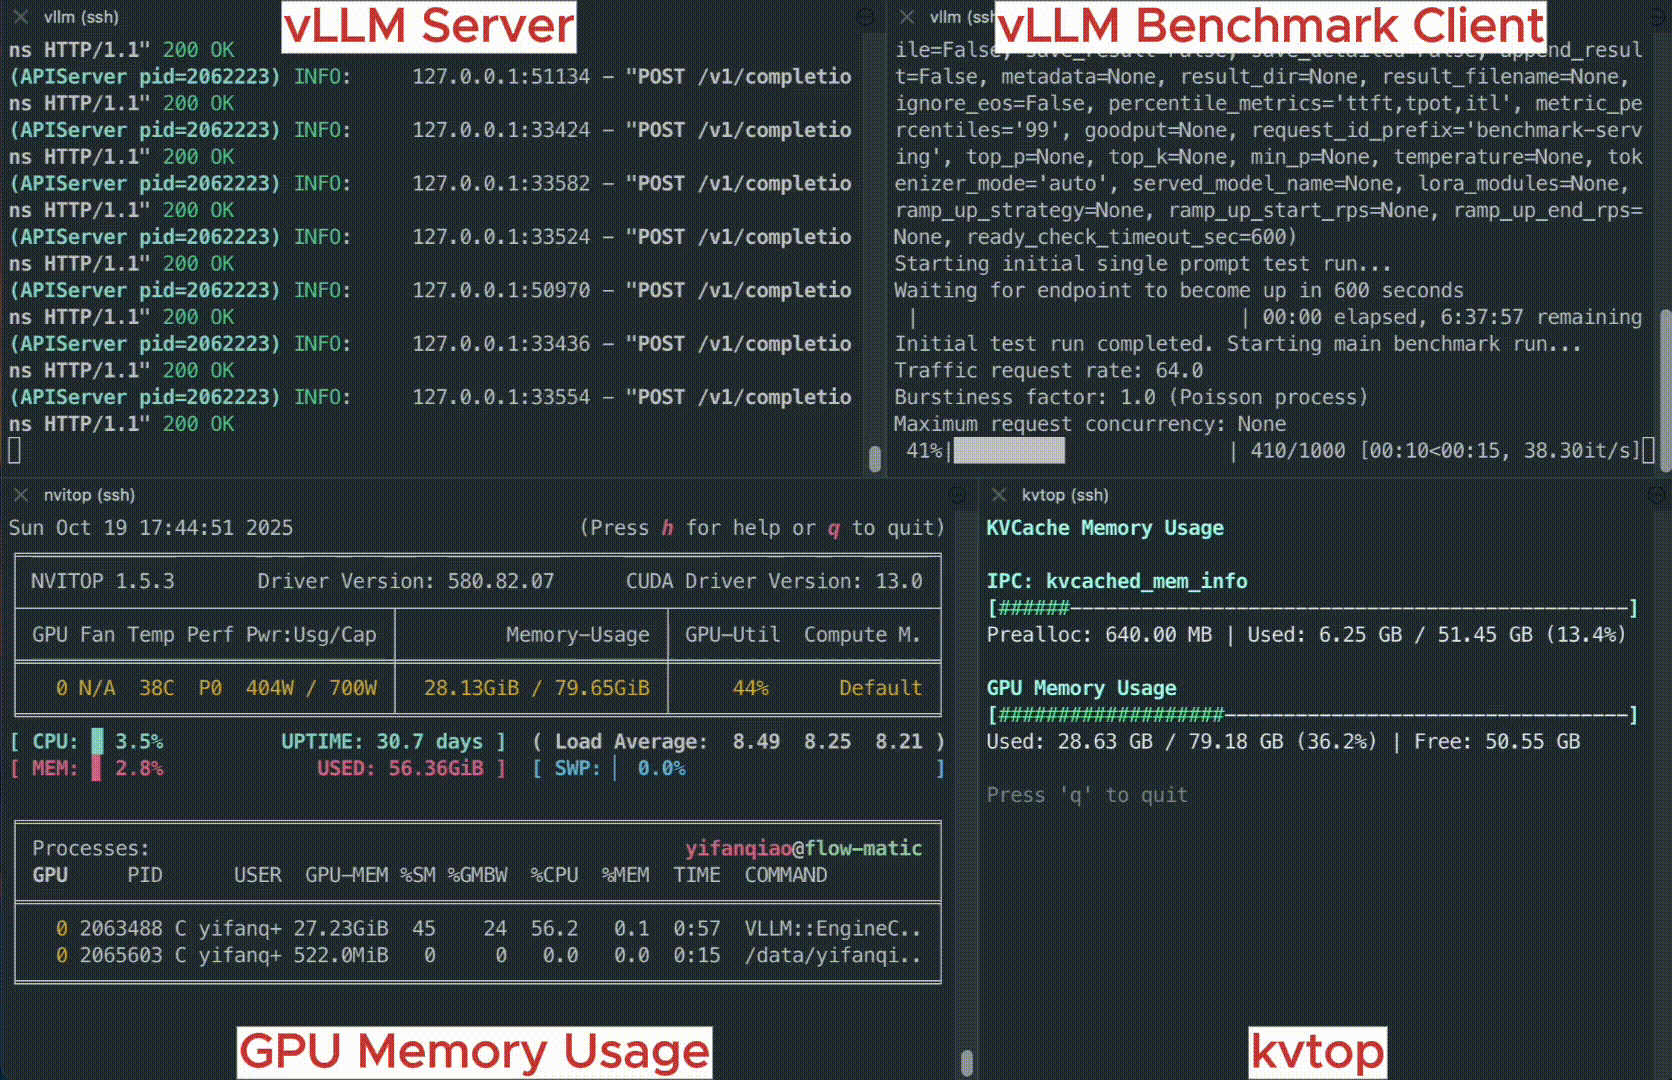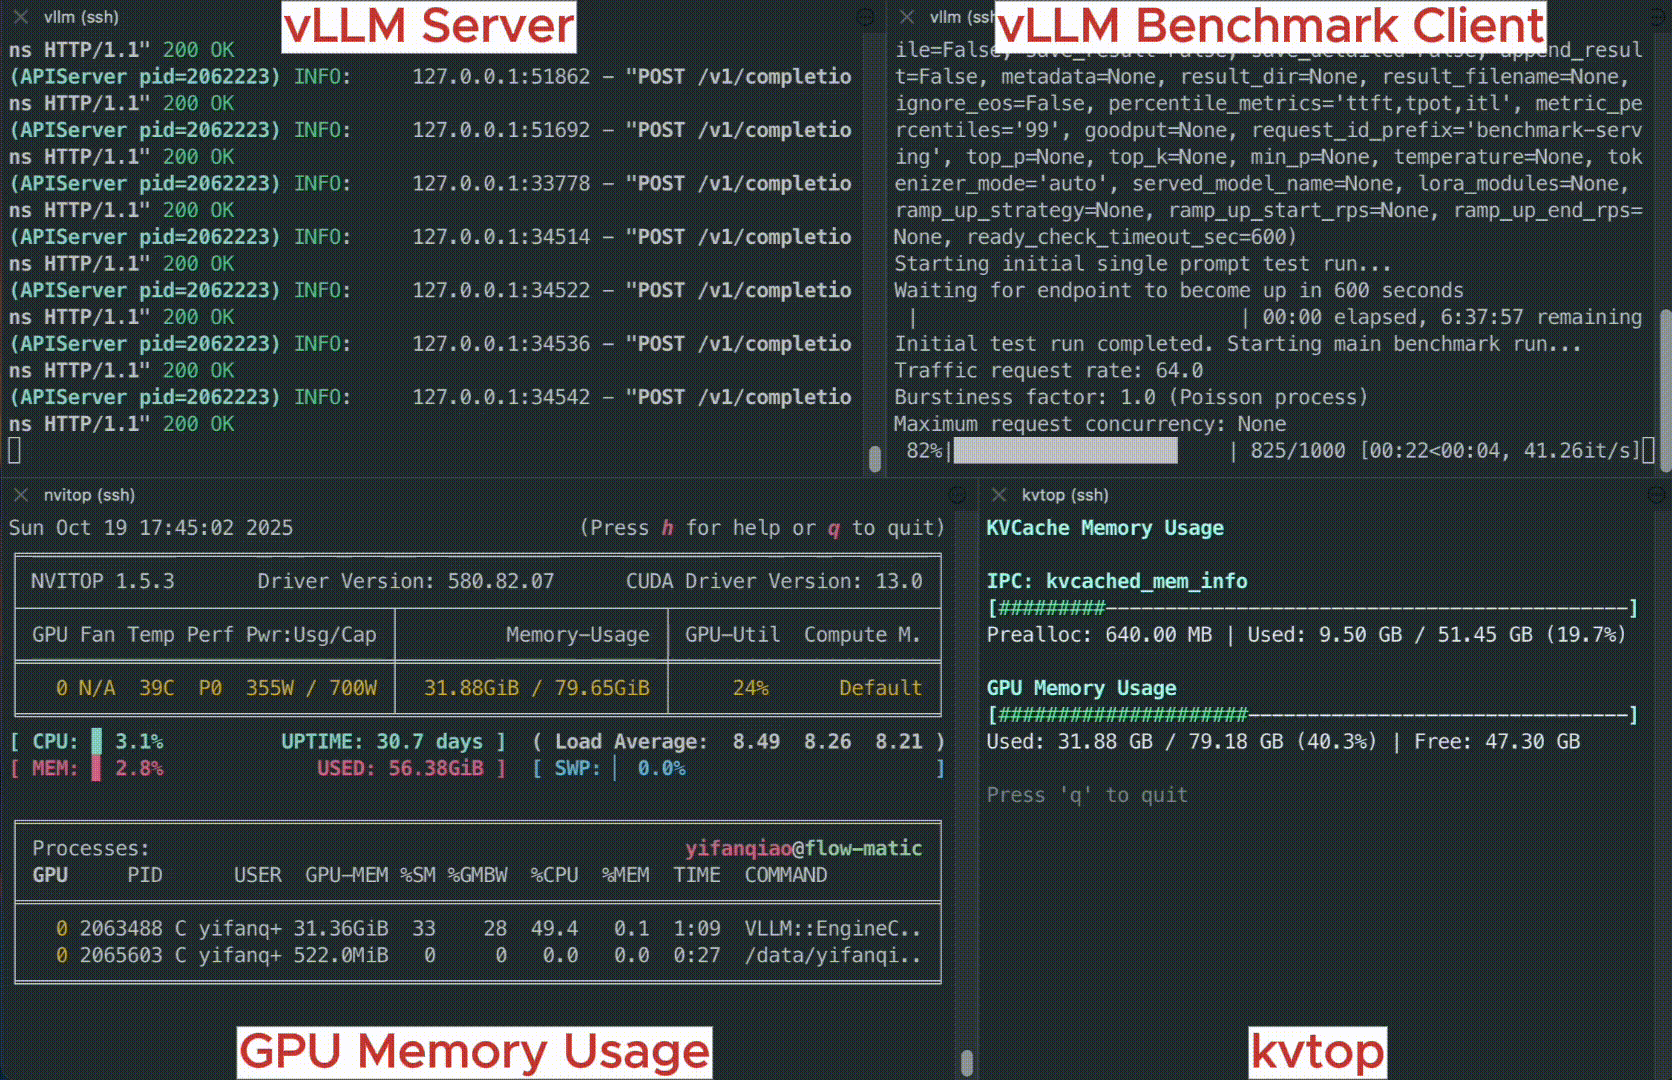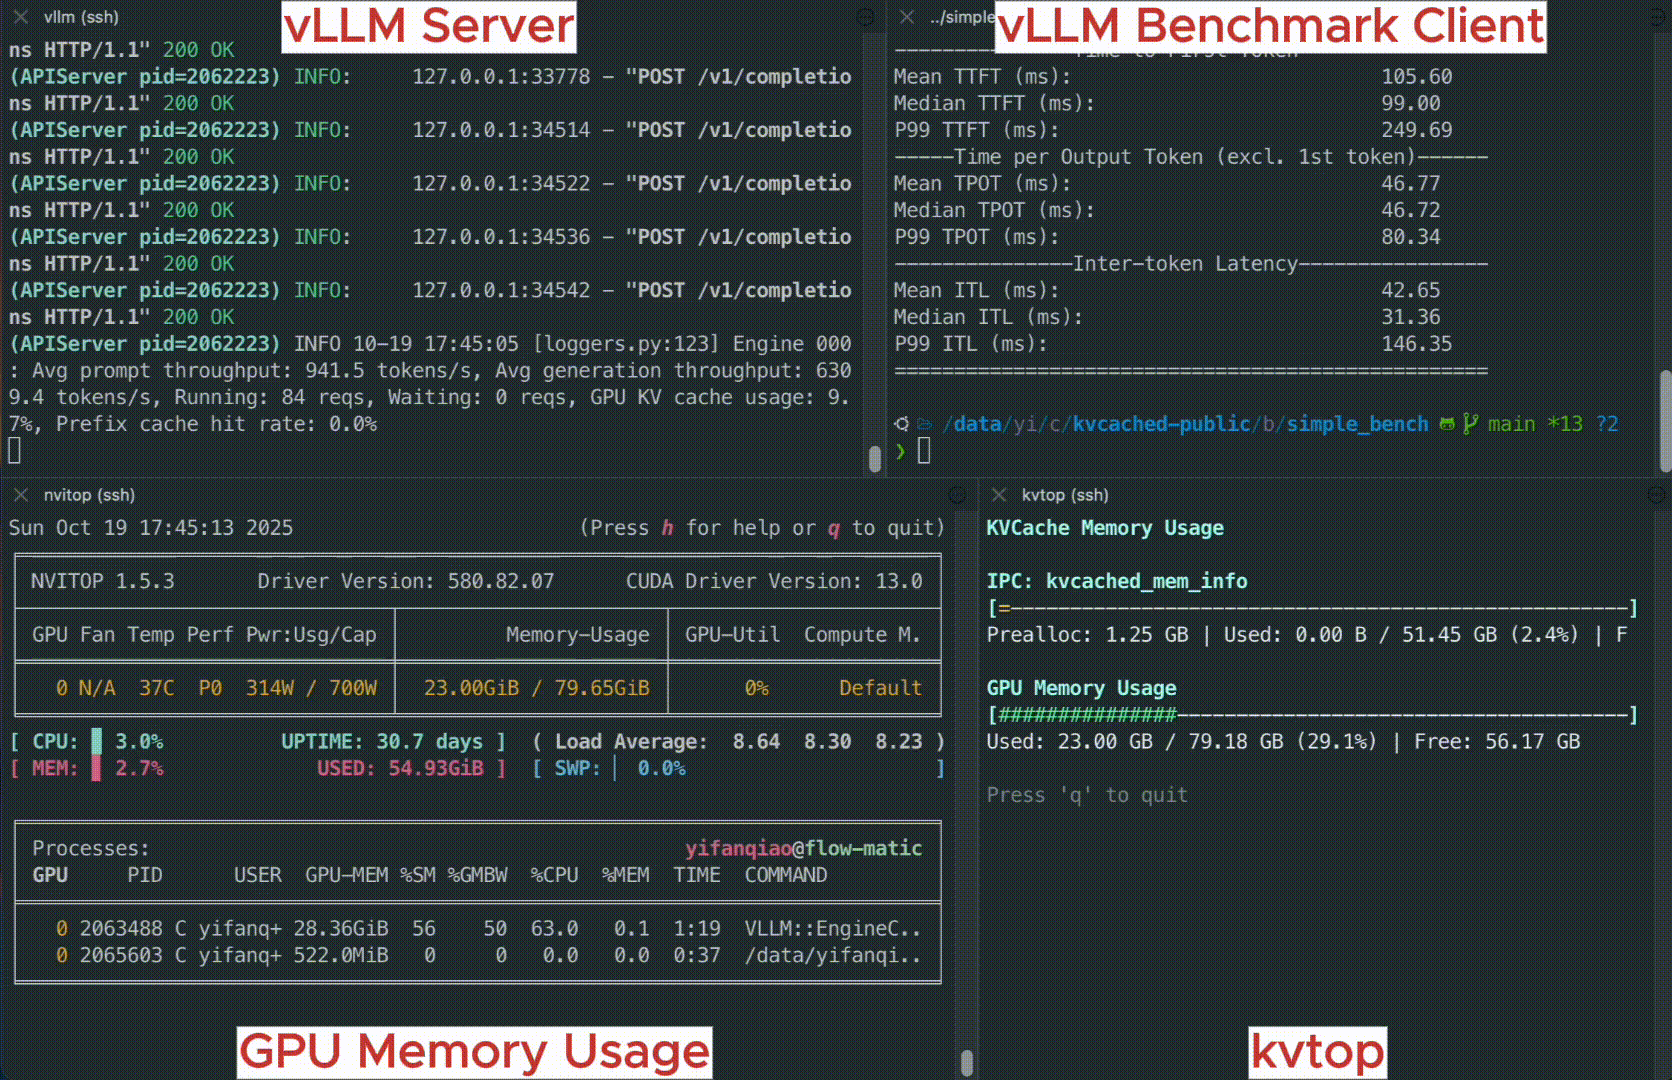
GitHub - ovg-project/kvcached: Virtualized Elastic KV Cache for Dynamic ...

Efficient Remote KV Cache Reuse with GPU-native Video Codec
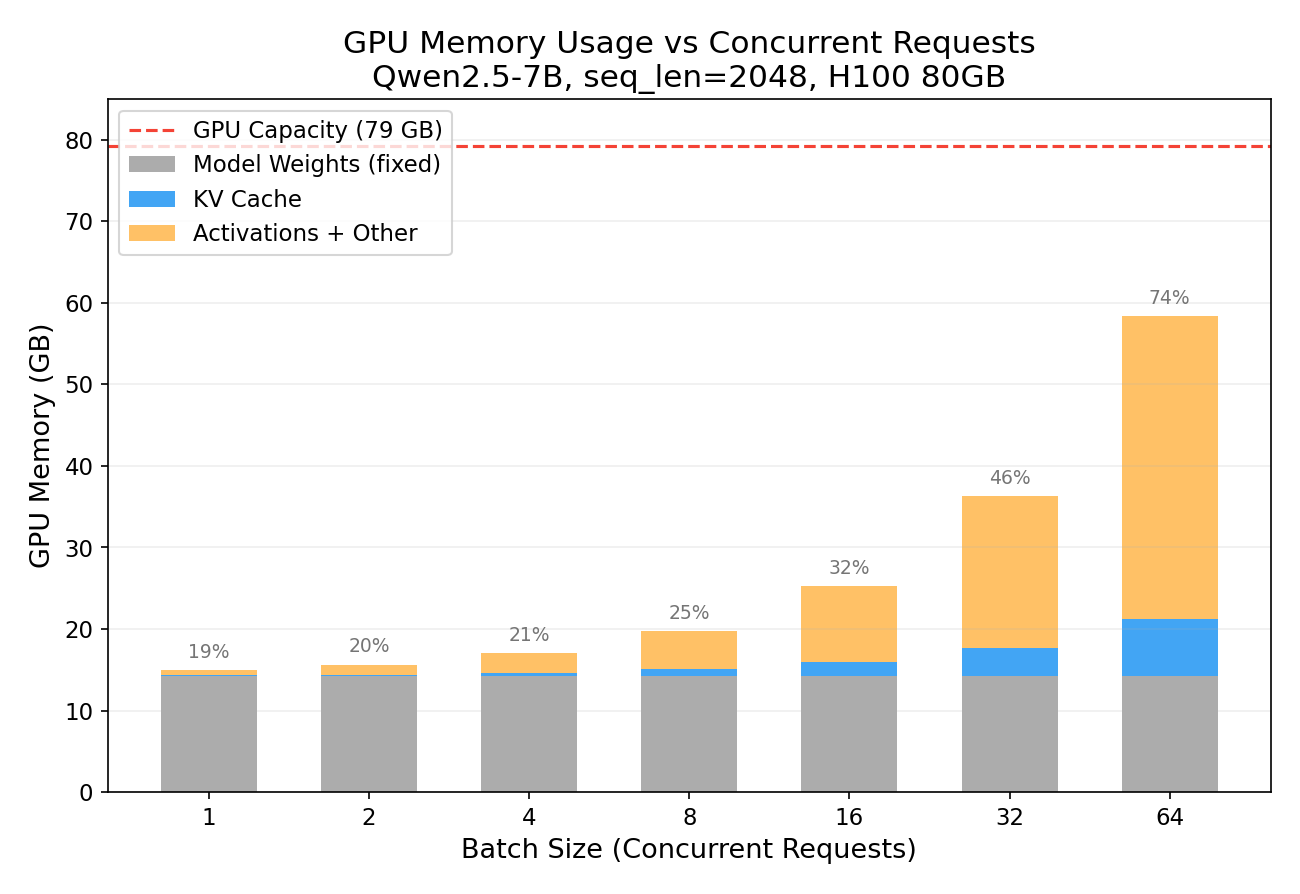
Understanding KV Cache in LLM Inference - Jingchao’s Website
Advertisement Space (336x280)

Comparative Characterization of KV Cache Management Strategies for LLM ...

LLM Inference: Accelerating Long Context Generation with KV Cache ...
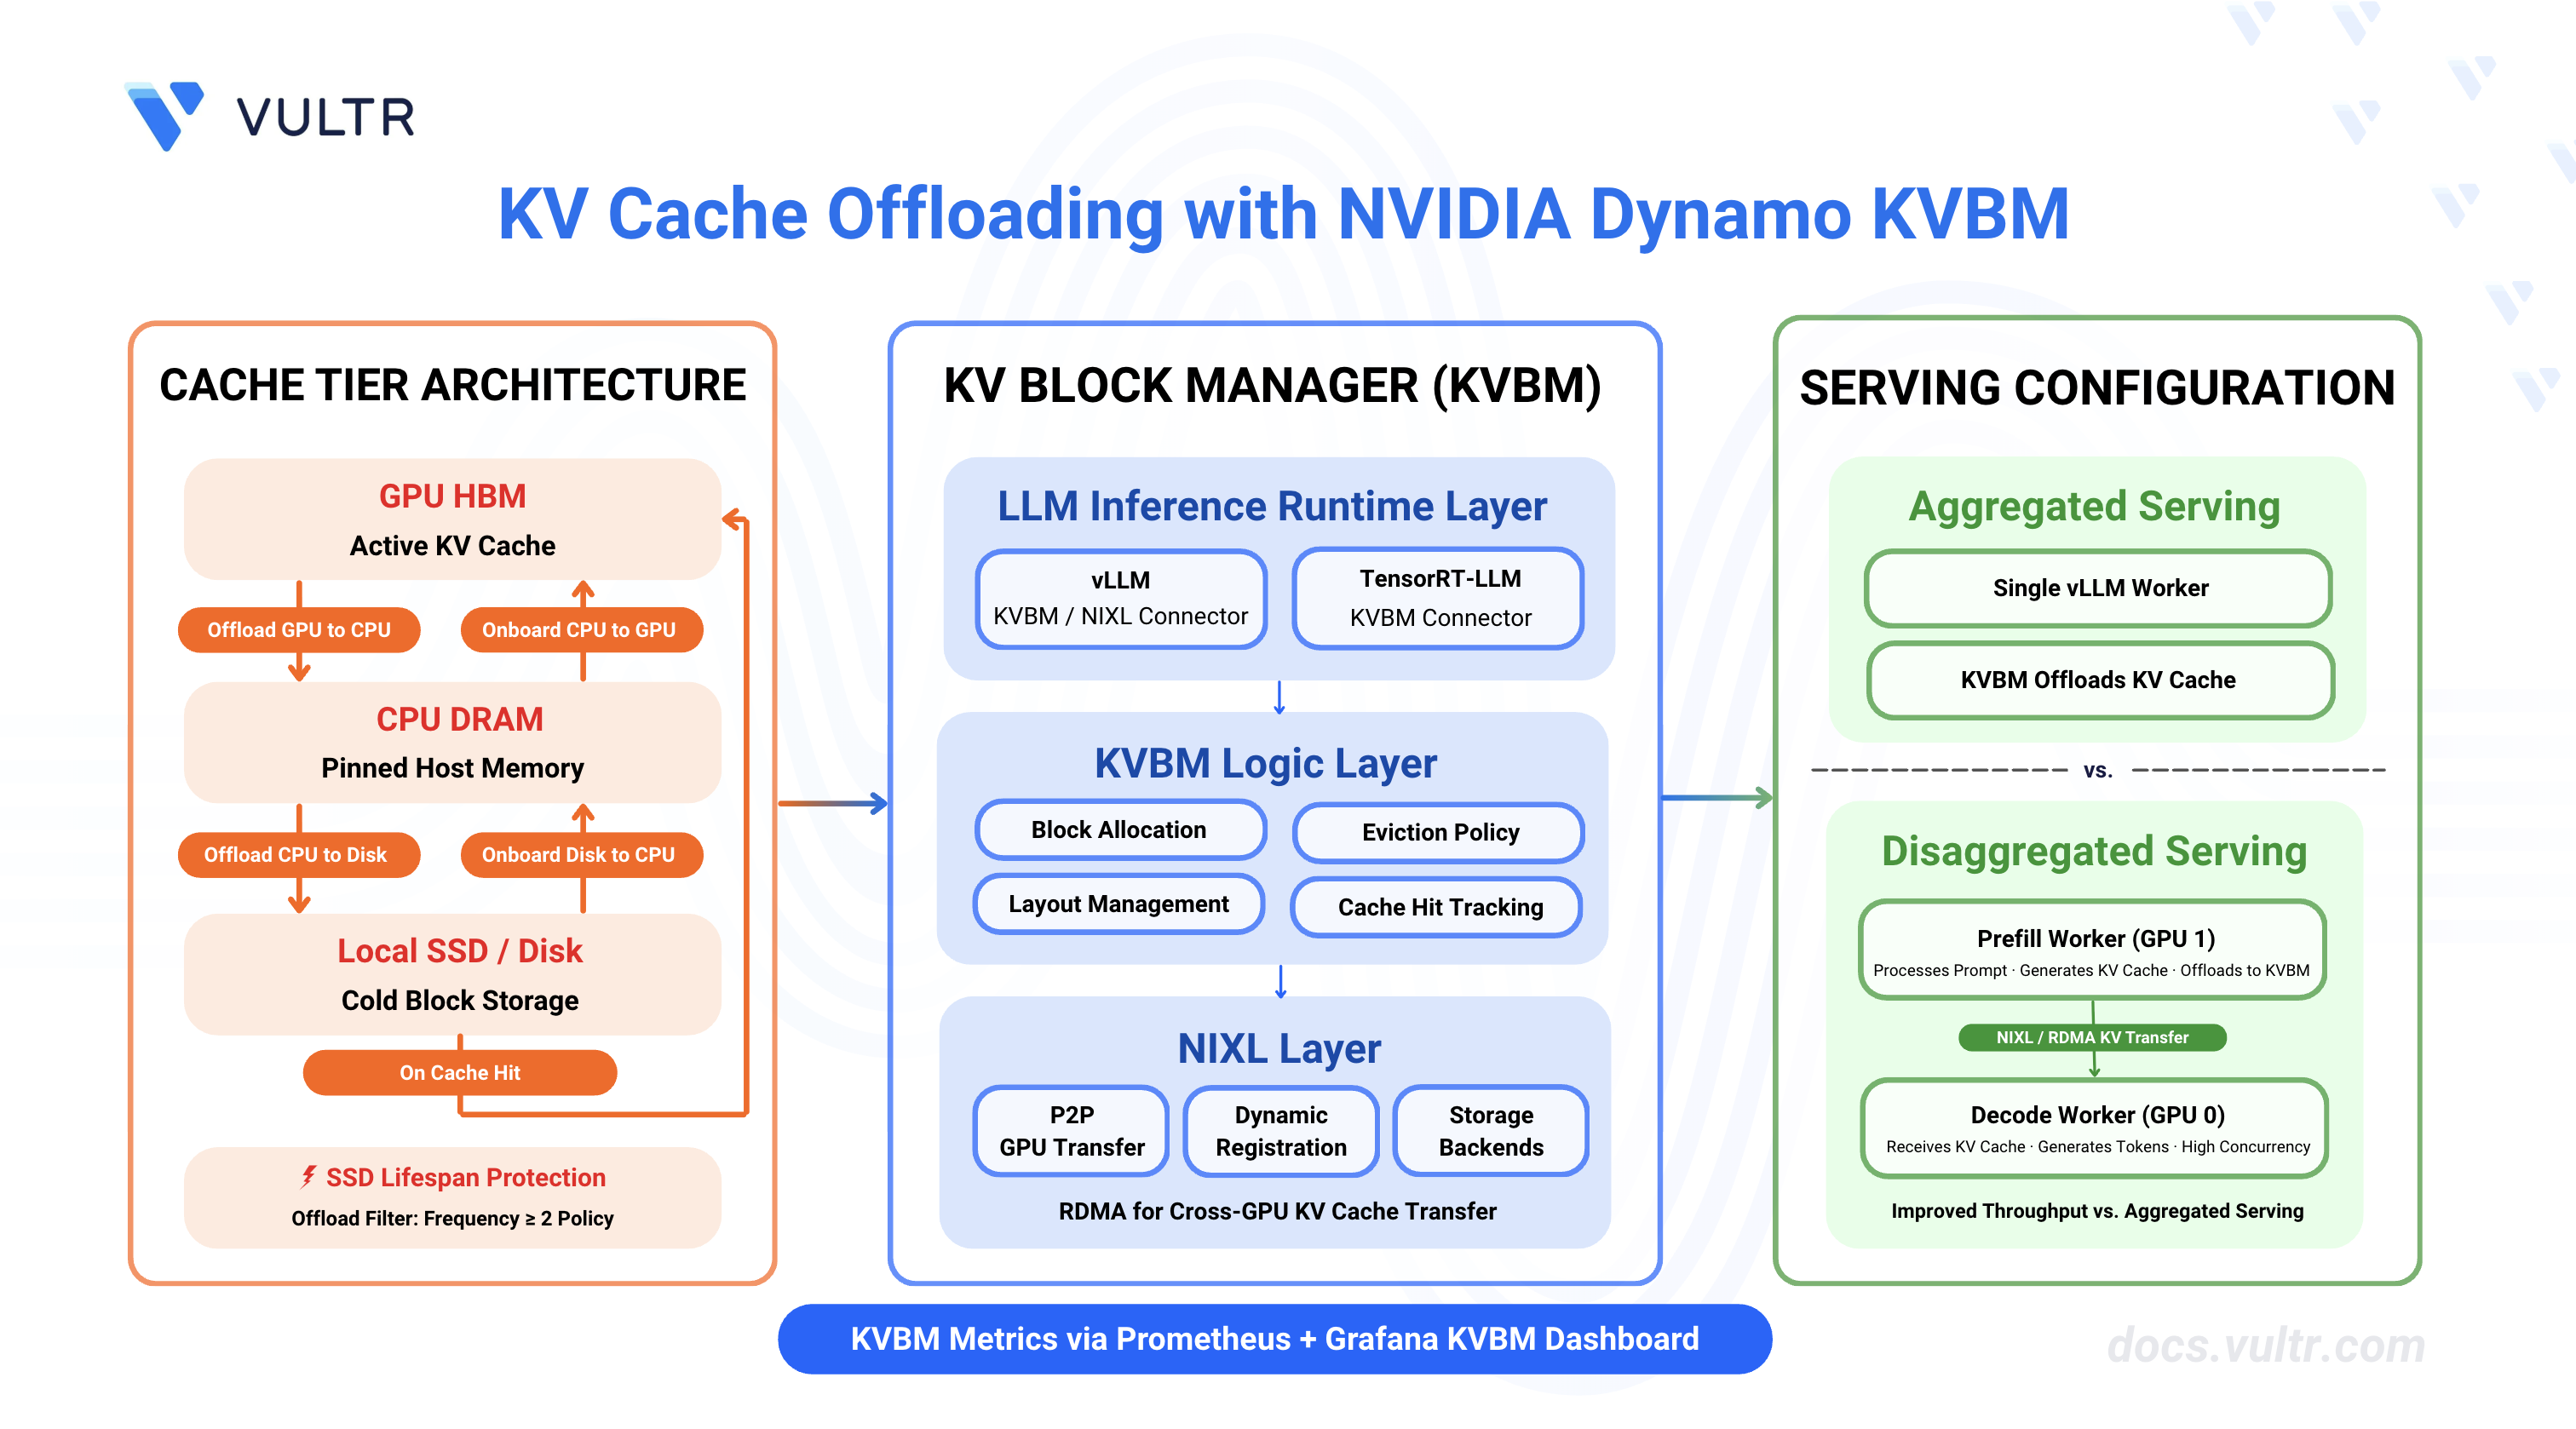
How to Manage KV Cache in NVIDIA Dynamo | Vultr Docs
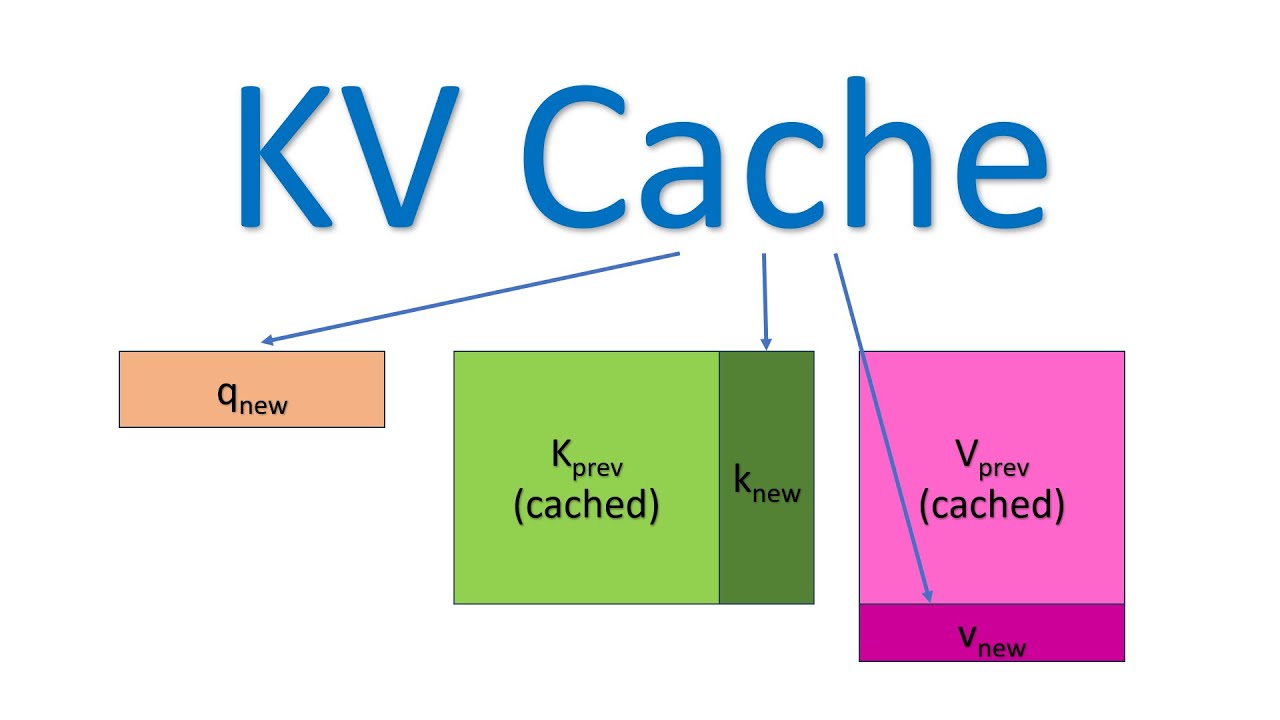
GPU memory requirements for serving Large Language Models | UnfoldAI
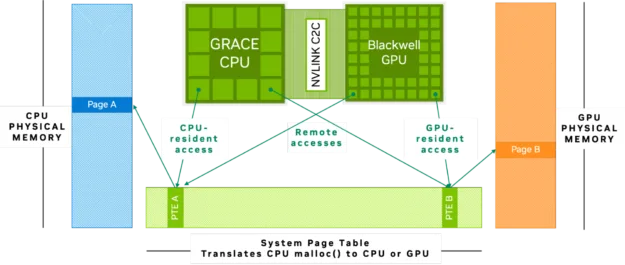
Accelerate Large-Scale LLM Inference and KV Cache Offload with CPU-GPU ...

ICMSP unlocks greater AI scale when Solidigm SSDs store context in KV cache