
Example Autoscaling Vllm With Keda Based On Gpu Kv Cache Usage
Example: Autoscaling vLLM with KEDA based on GPU KV Cache Usage ...
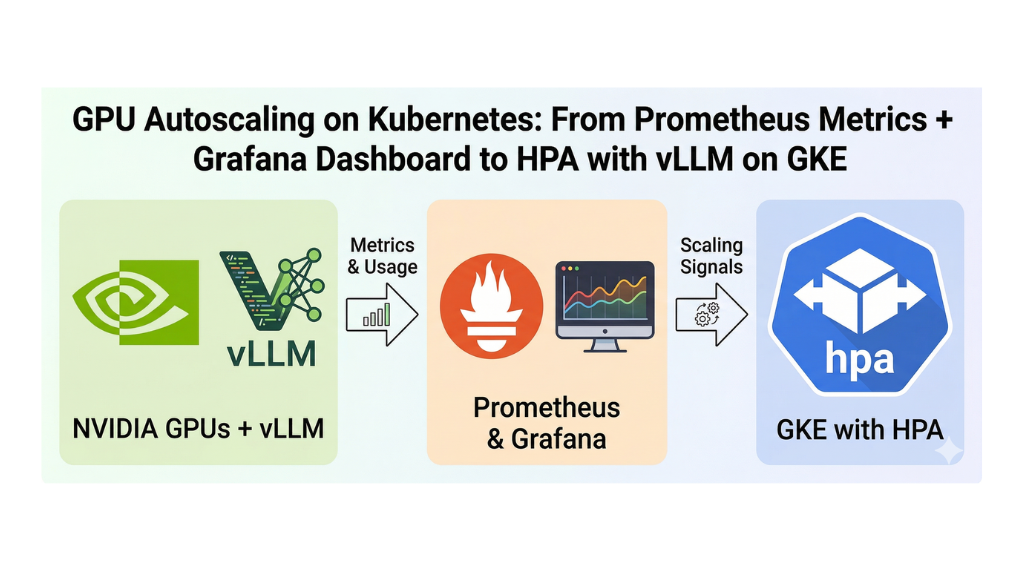
GPU Autoscaling on Kubernetes: From Prometheus Metrics to HPA with vLLM ...
vLLM model serving server hangs when GPU KV cache usage reaches 10% ...

Dynamic KV Cache compression based on vLLM framework
[RFC]: Dynamic KV Cache compression based on vLLM framework · Issue ...

GPU autoscaling on Kubernetes with KEDA: Building an external scaler | CNCF
[Usage]: The GPU KV cache usage is still small (below 20% most of time ...
Metric: GPU KV Cache Usage | Deka GPU Documentations
Why is the GPU KV cache usage very low? · Issue #5626 · vllm-project ...
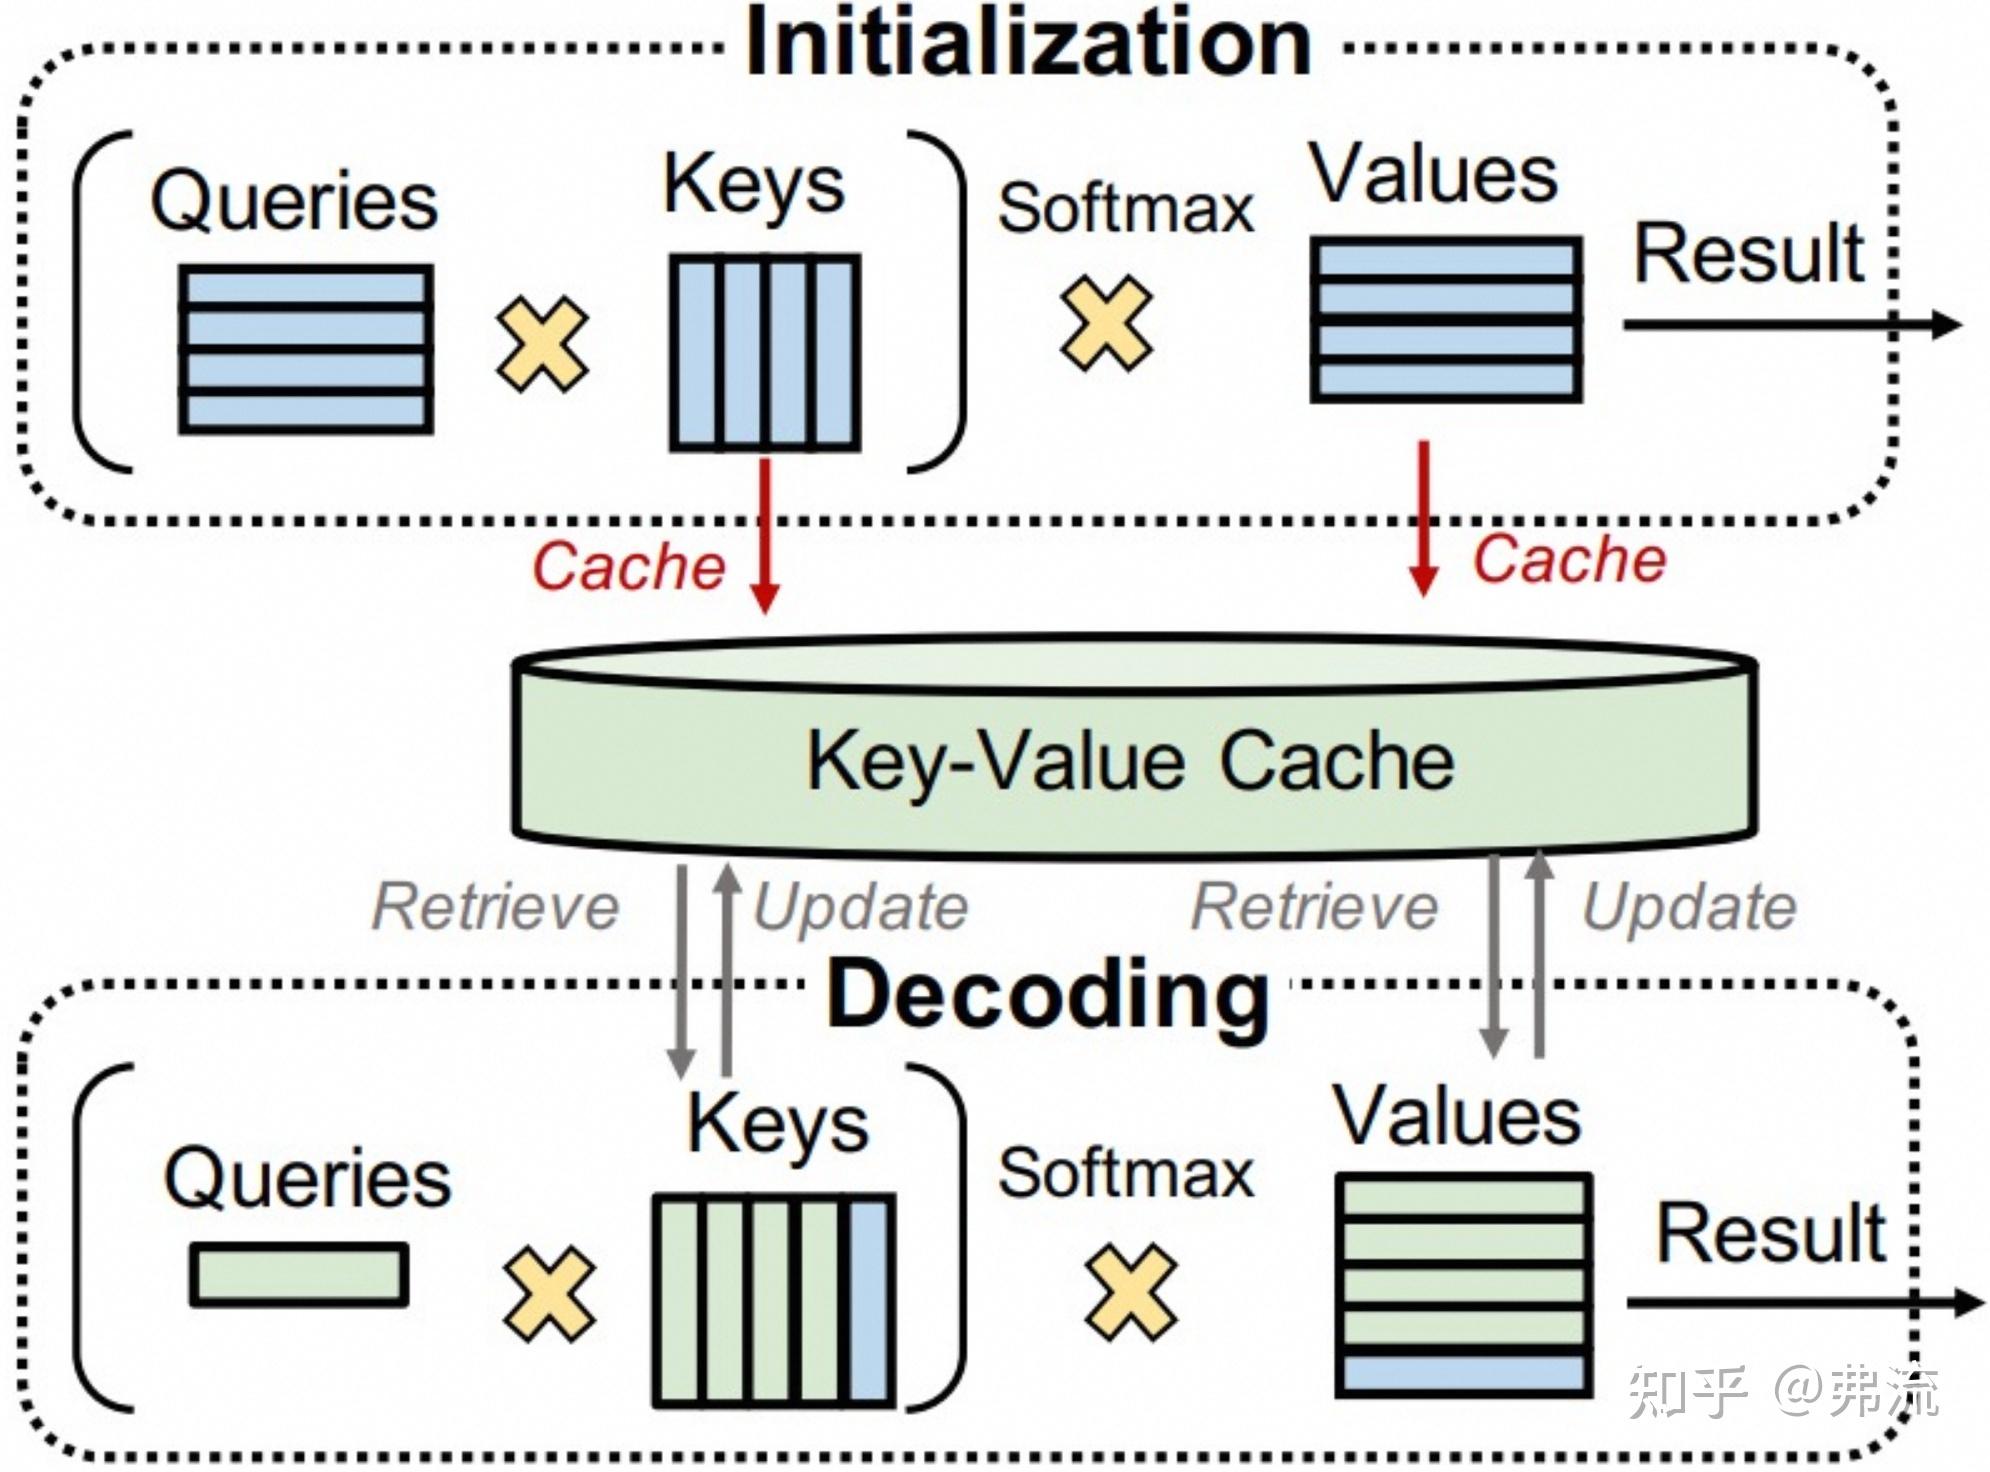
vLLM V1 源码解读(二):PagedAttention——用操作系统的思想管 GPU 的 KV Cache - 知乎
Advertisement Space (300x250)
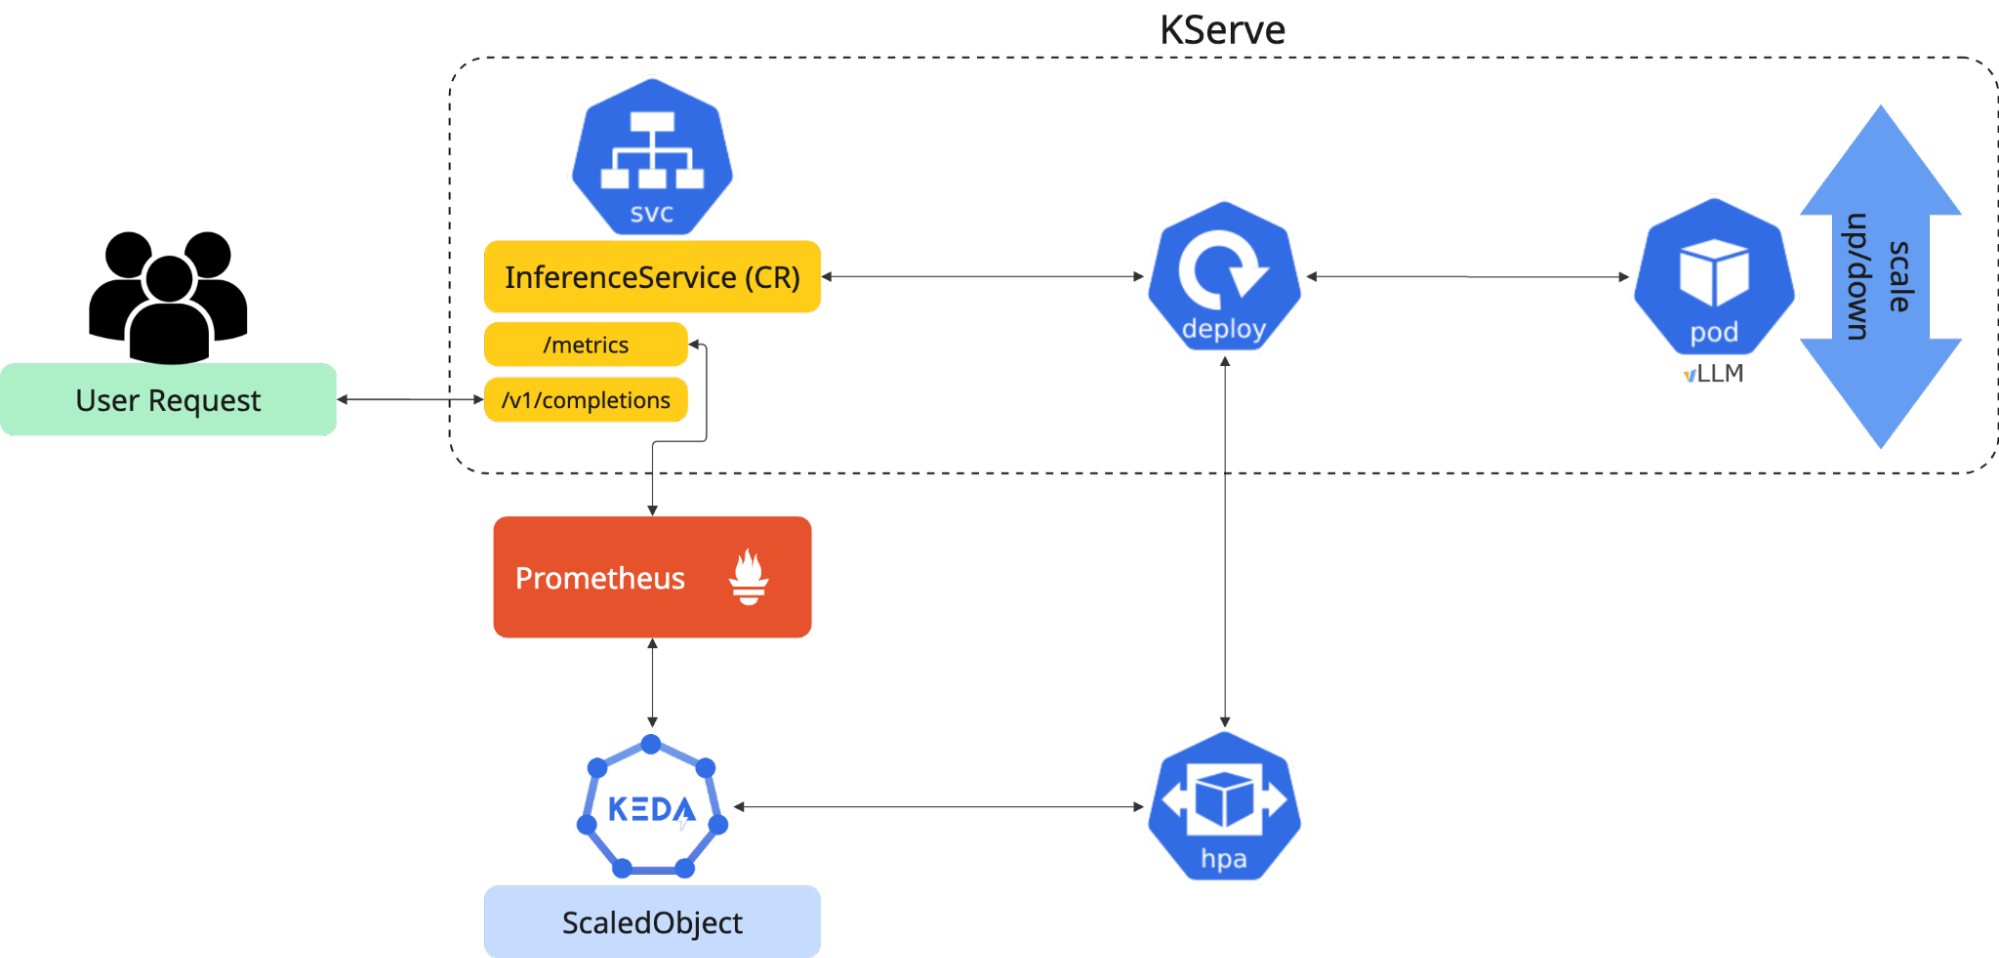
How to set up KServe autoscaling for vLLM with KEDA | Red Hat Developer

Dynamic Model Autoscaling with KEDA - AI on OpenShift

Autoscaling with KEDA | Open‑Source LLM Inferencing at Scale: vLLM ...
KV Cache Optimization: Serve 10x More Users on the Same GPU (2026 ...
GPU Autoscaling on Kubernetes with KEDA: Why CPU Metrics Fail AI ...

Hybrid KV Cache Manager - vLLM

Scaling Multi-Turn LLM Inference with KV Cache Storage Offload and Dell ...

How to Reduce KV Cache Bottlenecks with NVIDIA Dynamo | NVIDIA ...
vLLM 推理 GPU 选型指南:显存、KV Cache 与性能瓶颈全解析本文系统解析 vLLM 推理运行机制,深入讲清 - 掘金
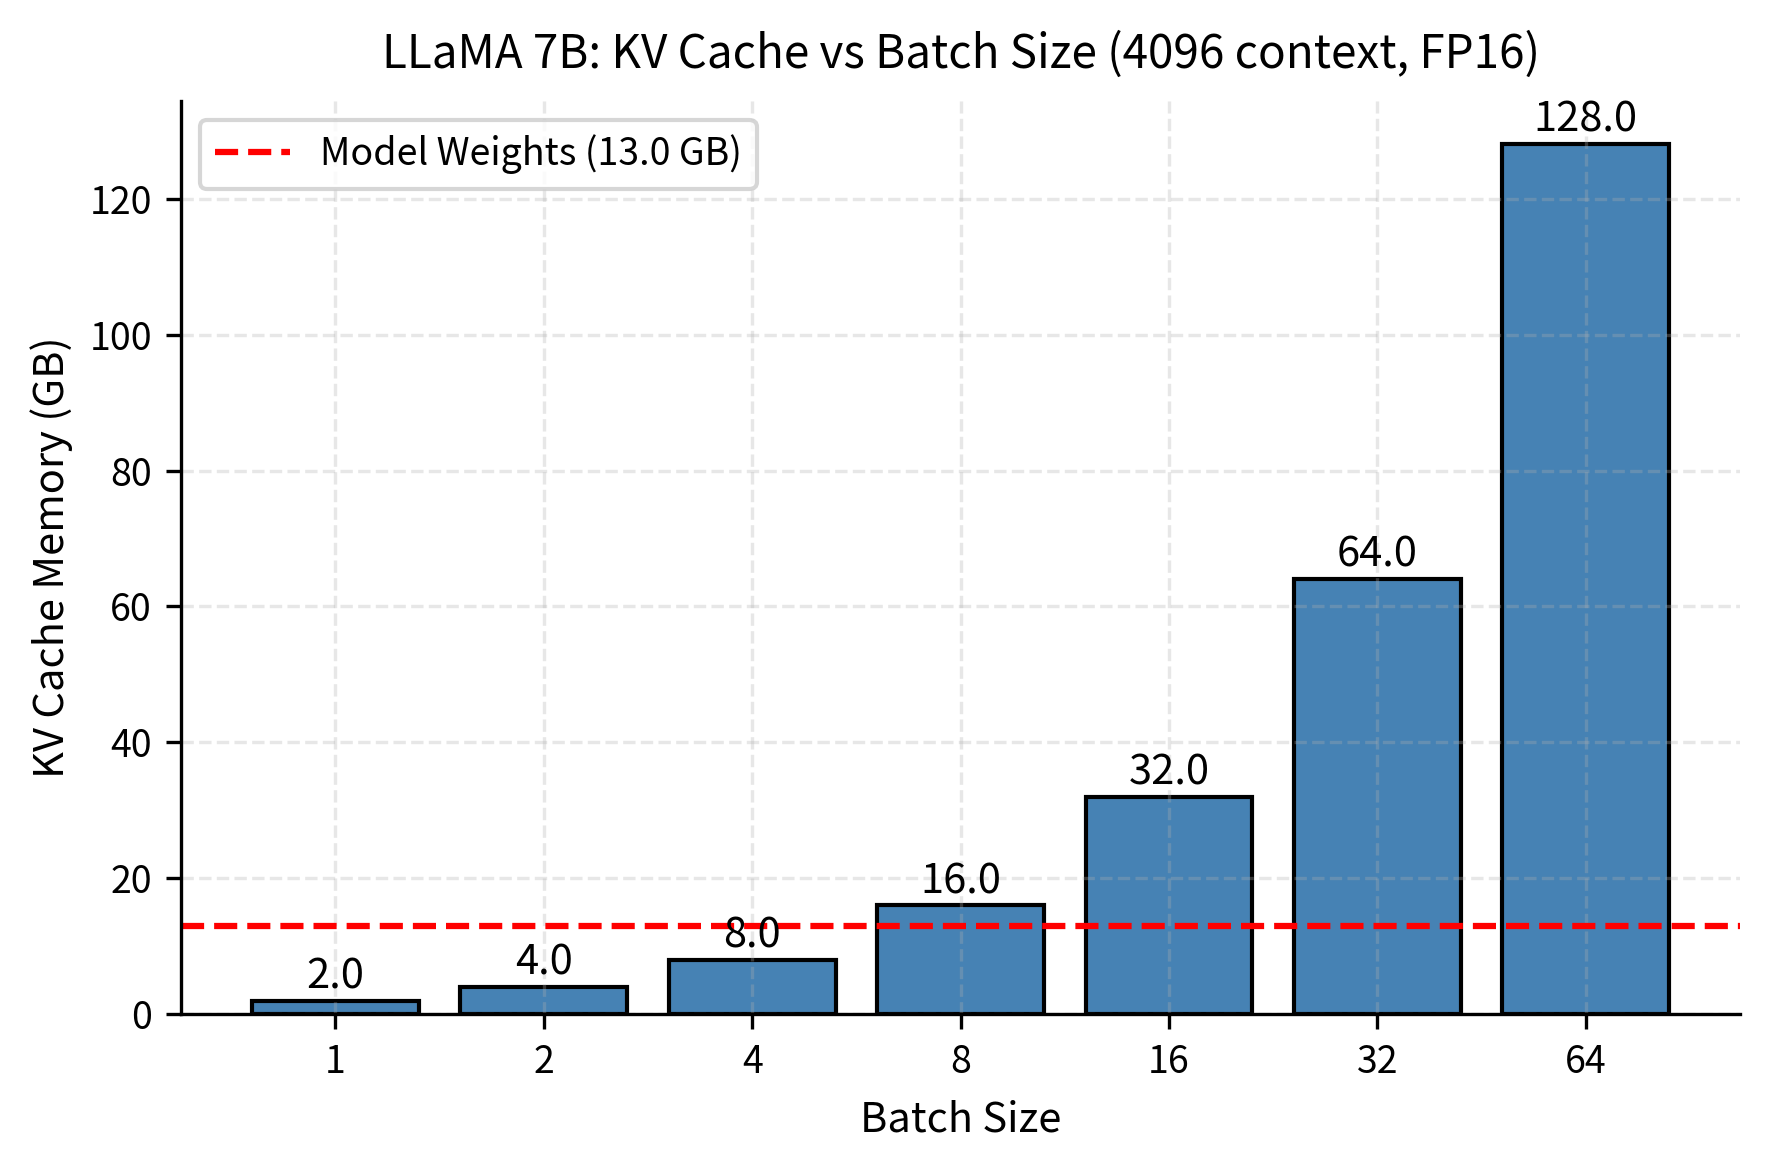
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...
Advertisement Space (336x280)

Cost-optimized ML on production: Autoscaling GPU Nodes on Kubernetes to ...
GPU KV cache usage: 100.0%以后就卡住 · Issue #1206 · vllm-project/vllm · GitHub
KV Cache Sizing — GPU Memory for LLM Serving | tutorialQ
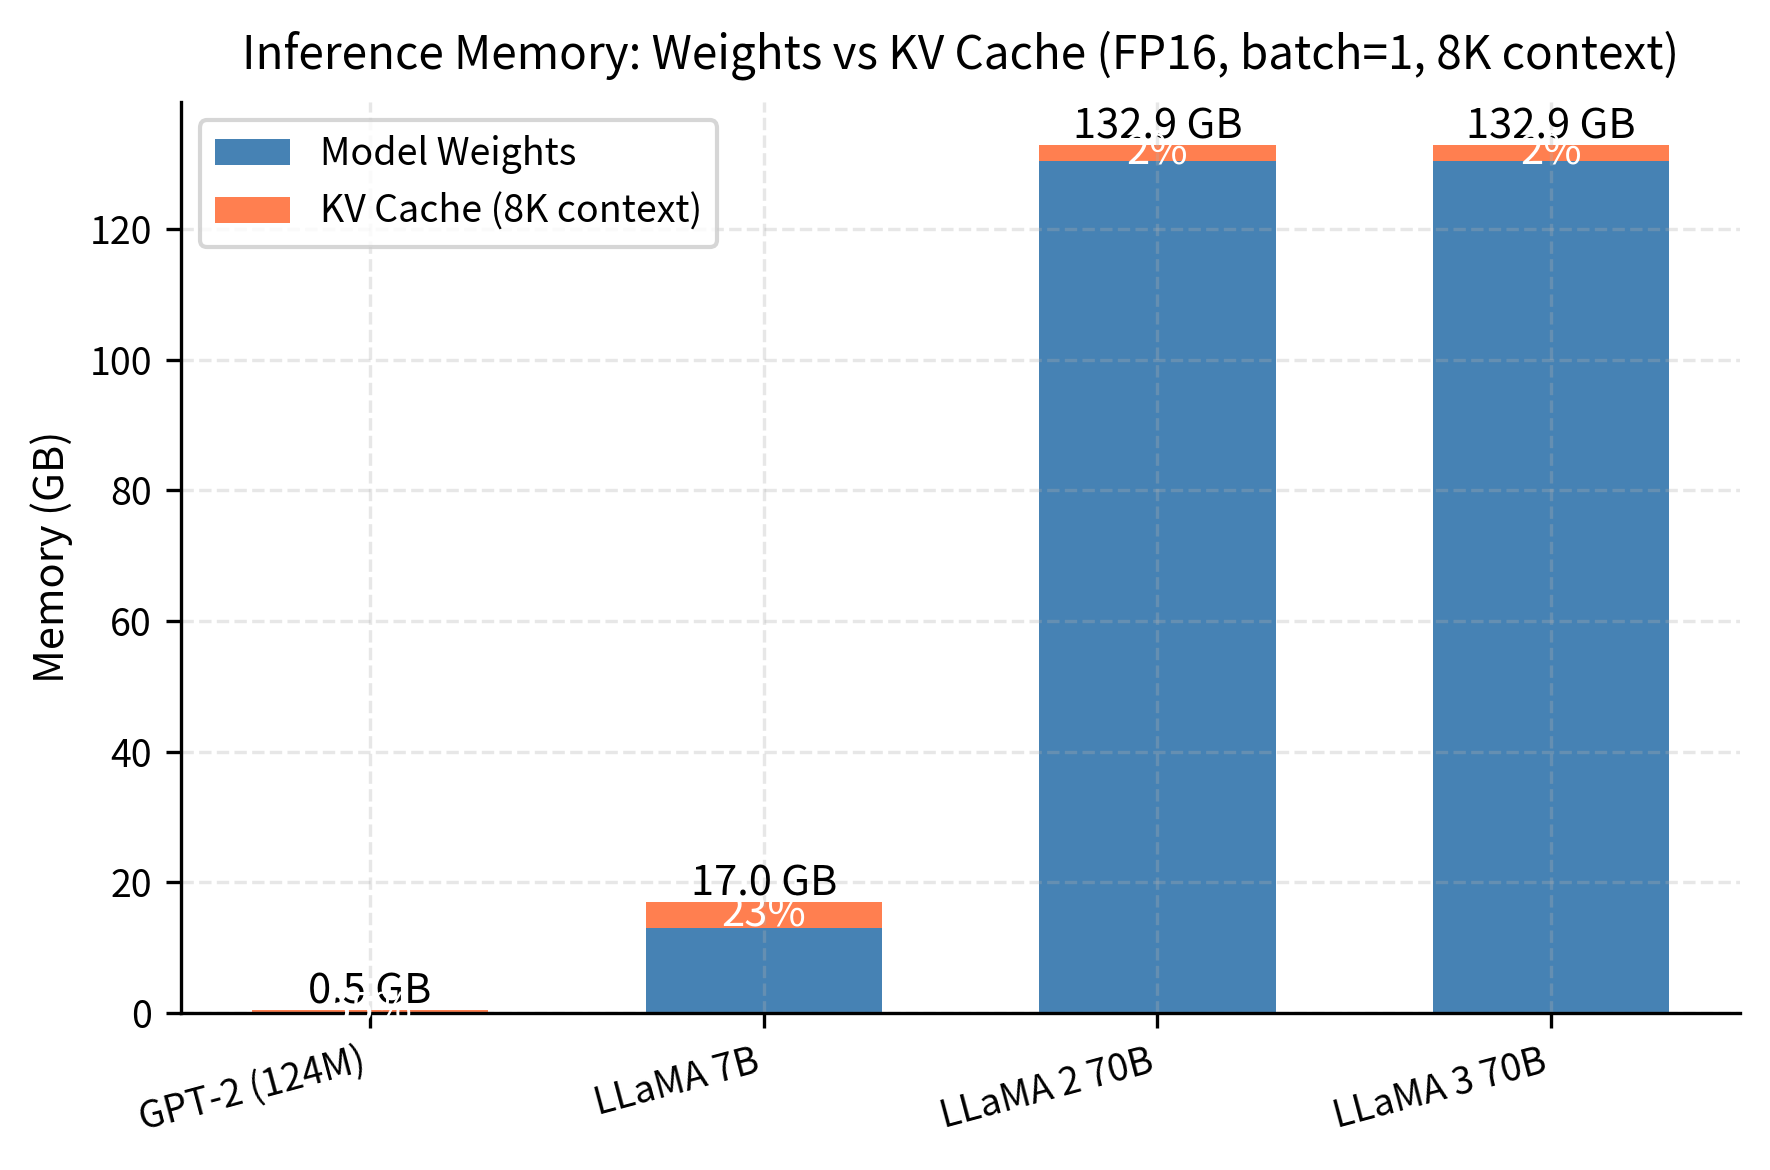
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...
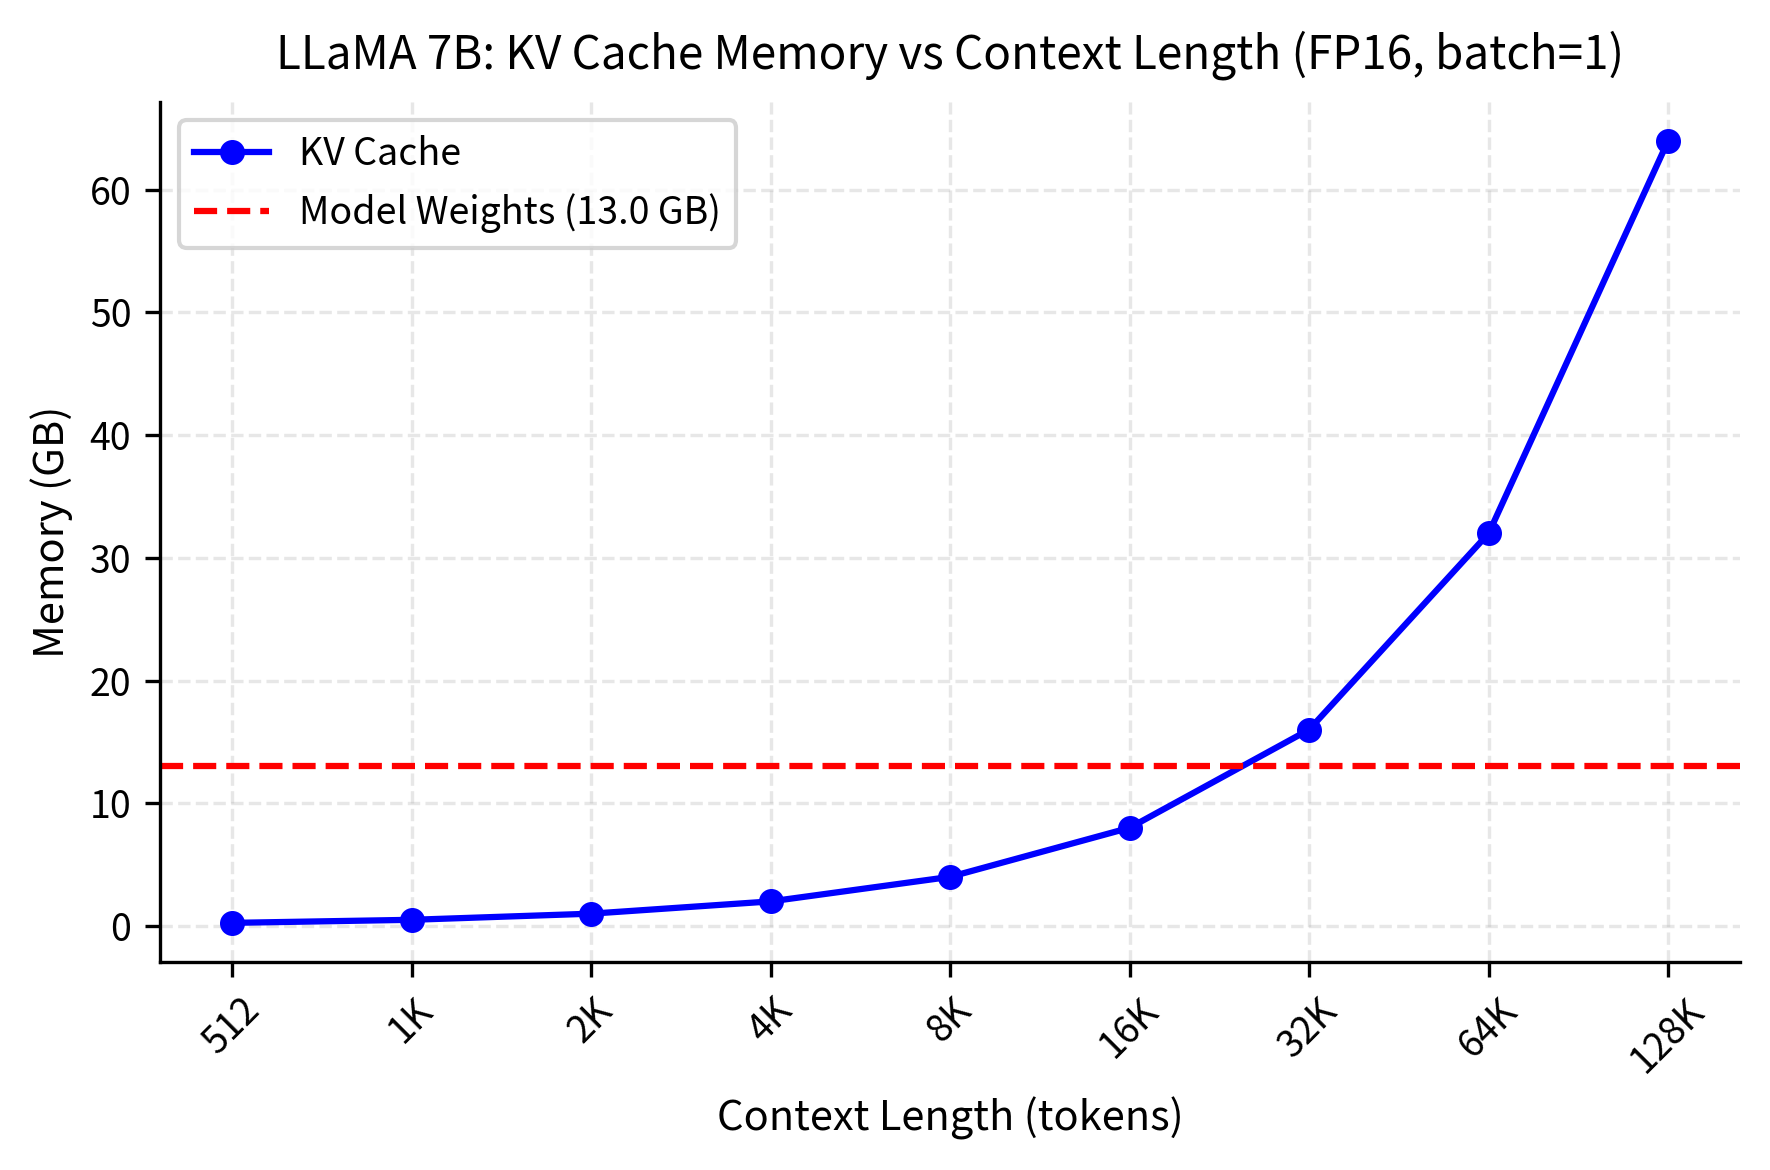
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...

Why vLLM autoscaling on Kubernetes breaks (and what to use instead ...

LLM Inference Bottleneck: KV Cache vs GPU Memory | Osama Altaf posted ...
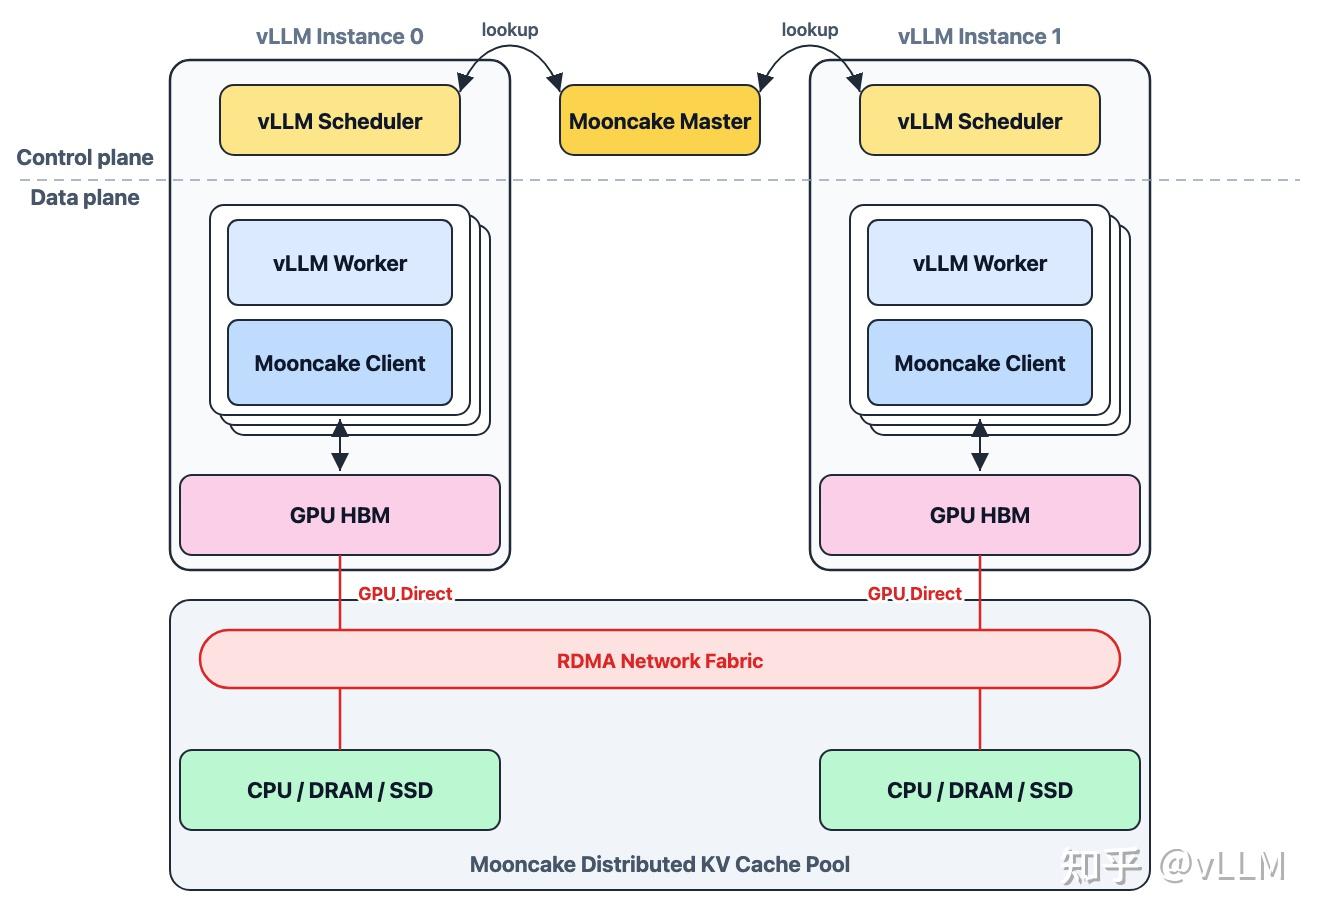
vLLM × Mooncake:用分布式 KV Cache Pool 服务大规模 Agentic 推理 - 知乎
[Feature]: API for evicting all KV cache from GPU memory (or `sleep ...
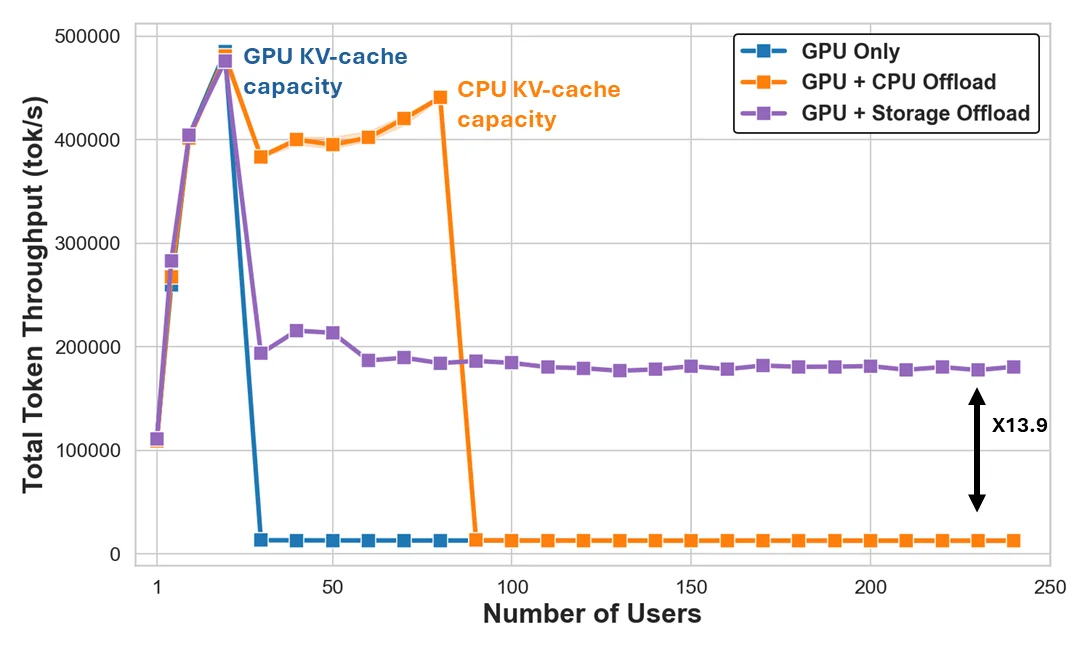
Native KV Cache Offloading to Any Filesystem with llm-d | llm-d
Advertisement Space (336x280)

Efficient Remote KV Cache Reuse with GPU-native Video Codec

Cost-optimized ML on production: Autoscaling GPU Nodes on Kubernetes to ...
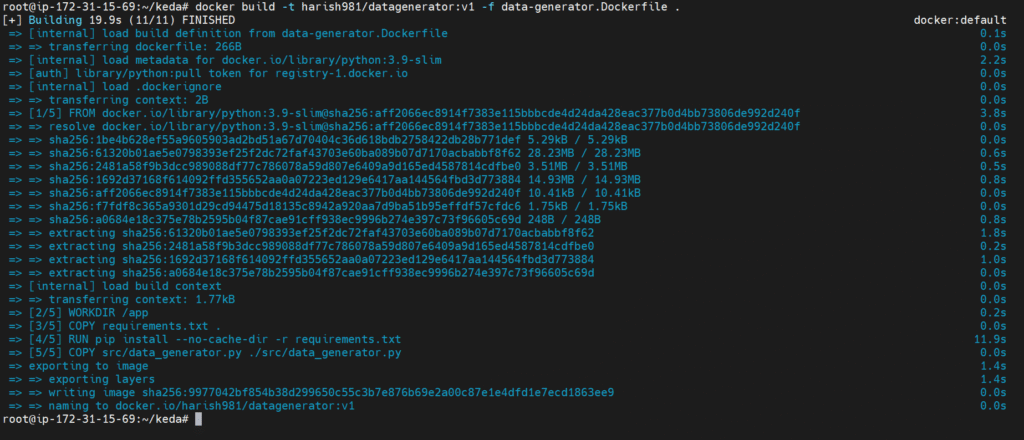
Simple Guide to Autoscaling with KEDA in Kubernetes

Mastering CUDA with PyTorch: Tips and Tricks for Efficient GPU ...
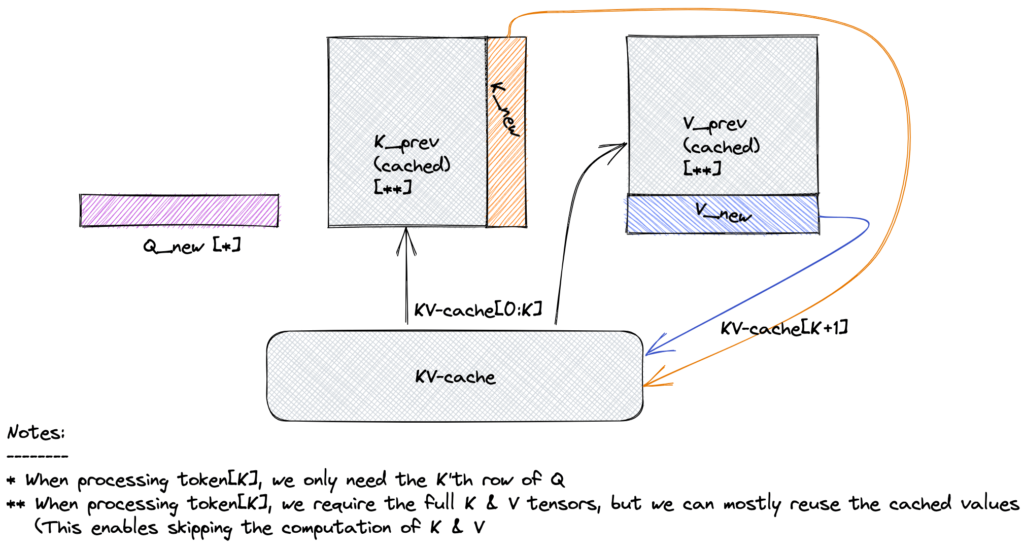
KV Cache in Transformer Models - Data Magic AI Blog
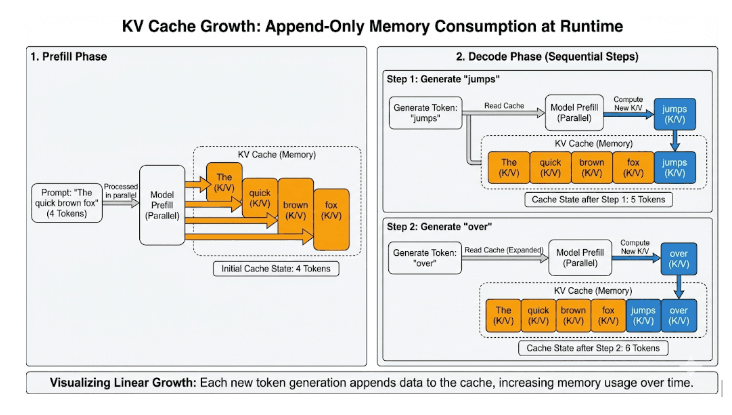
vLLM 推理 GPU 资源配置完全指南——从显存计算到量化与硬件选型 - 卓普云 AI Droplet