
Scaling Large Moe Models With Wide Expert Parallelism On Nvl72 Rack

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...
Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...
Advertisement Space (300x250)

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...
Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...
Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...
Advertisement Space (336x280)

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

For Frontier MoE models, Wide Expert Parallelism with large scale up ...

Deploy MoE models with expert parallelism and Prefill-Decode separation ...
MoE models over a distributed setup with Expert Parallelism. | Download ...
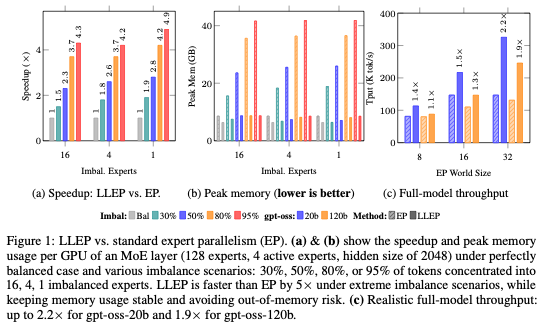
(1/5) MoE scaling loves Expert Parallelism (EP)… until routing gets ...
Scaling MoE Models with Distributed Training
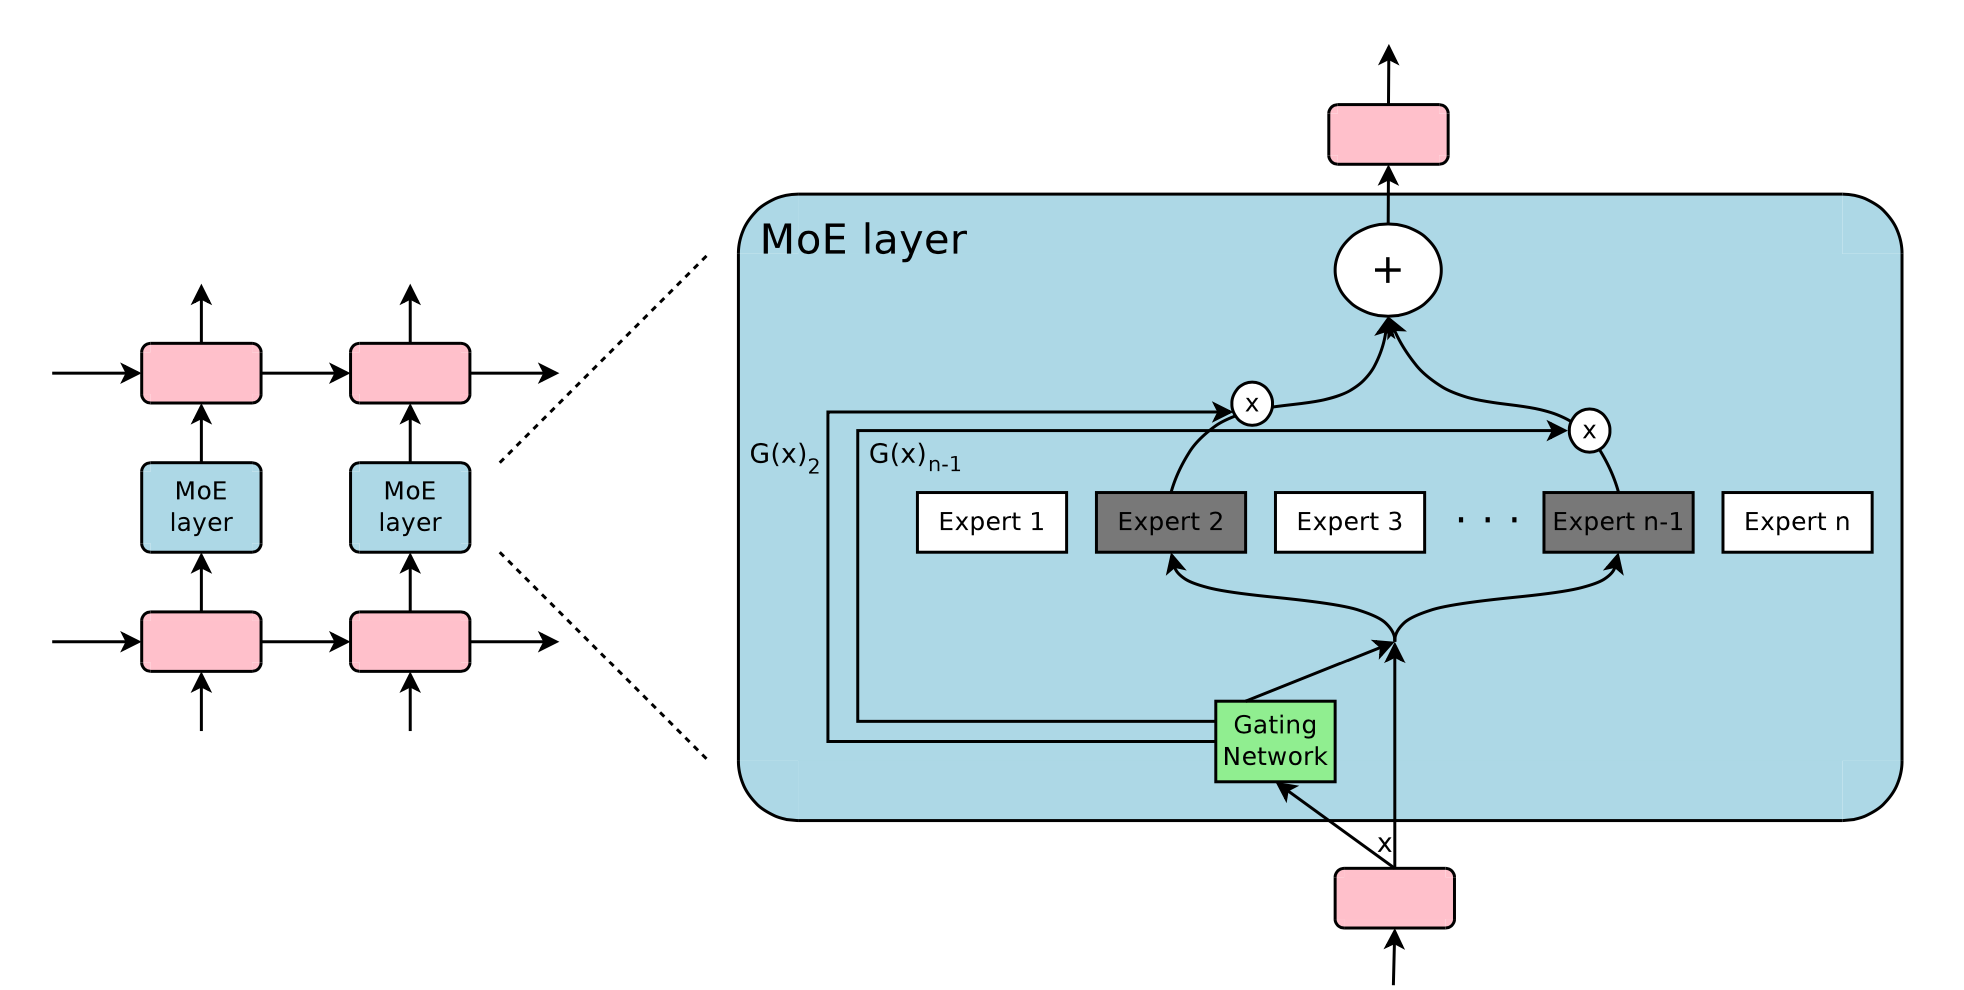
How to Train Really Large Models on Many GPUs? | Lil'Log

[2407.20018] Efficient Training of Large Language Models on Distributed ...

Scalable Pretraining of Large Mixture of Experts Language Models on ...
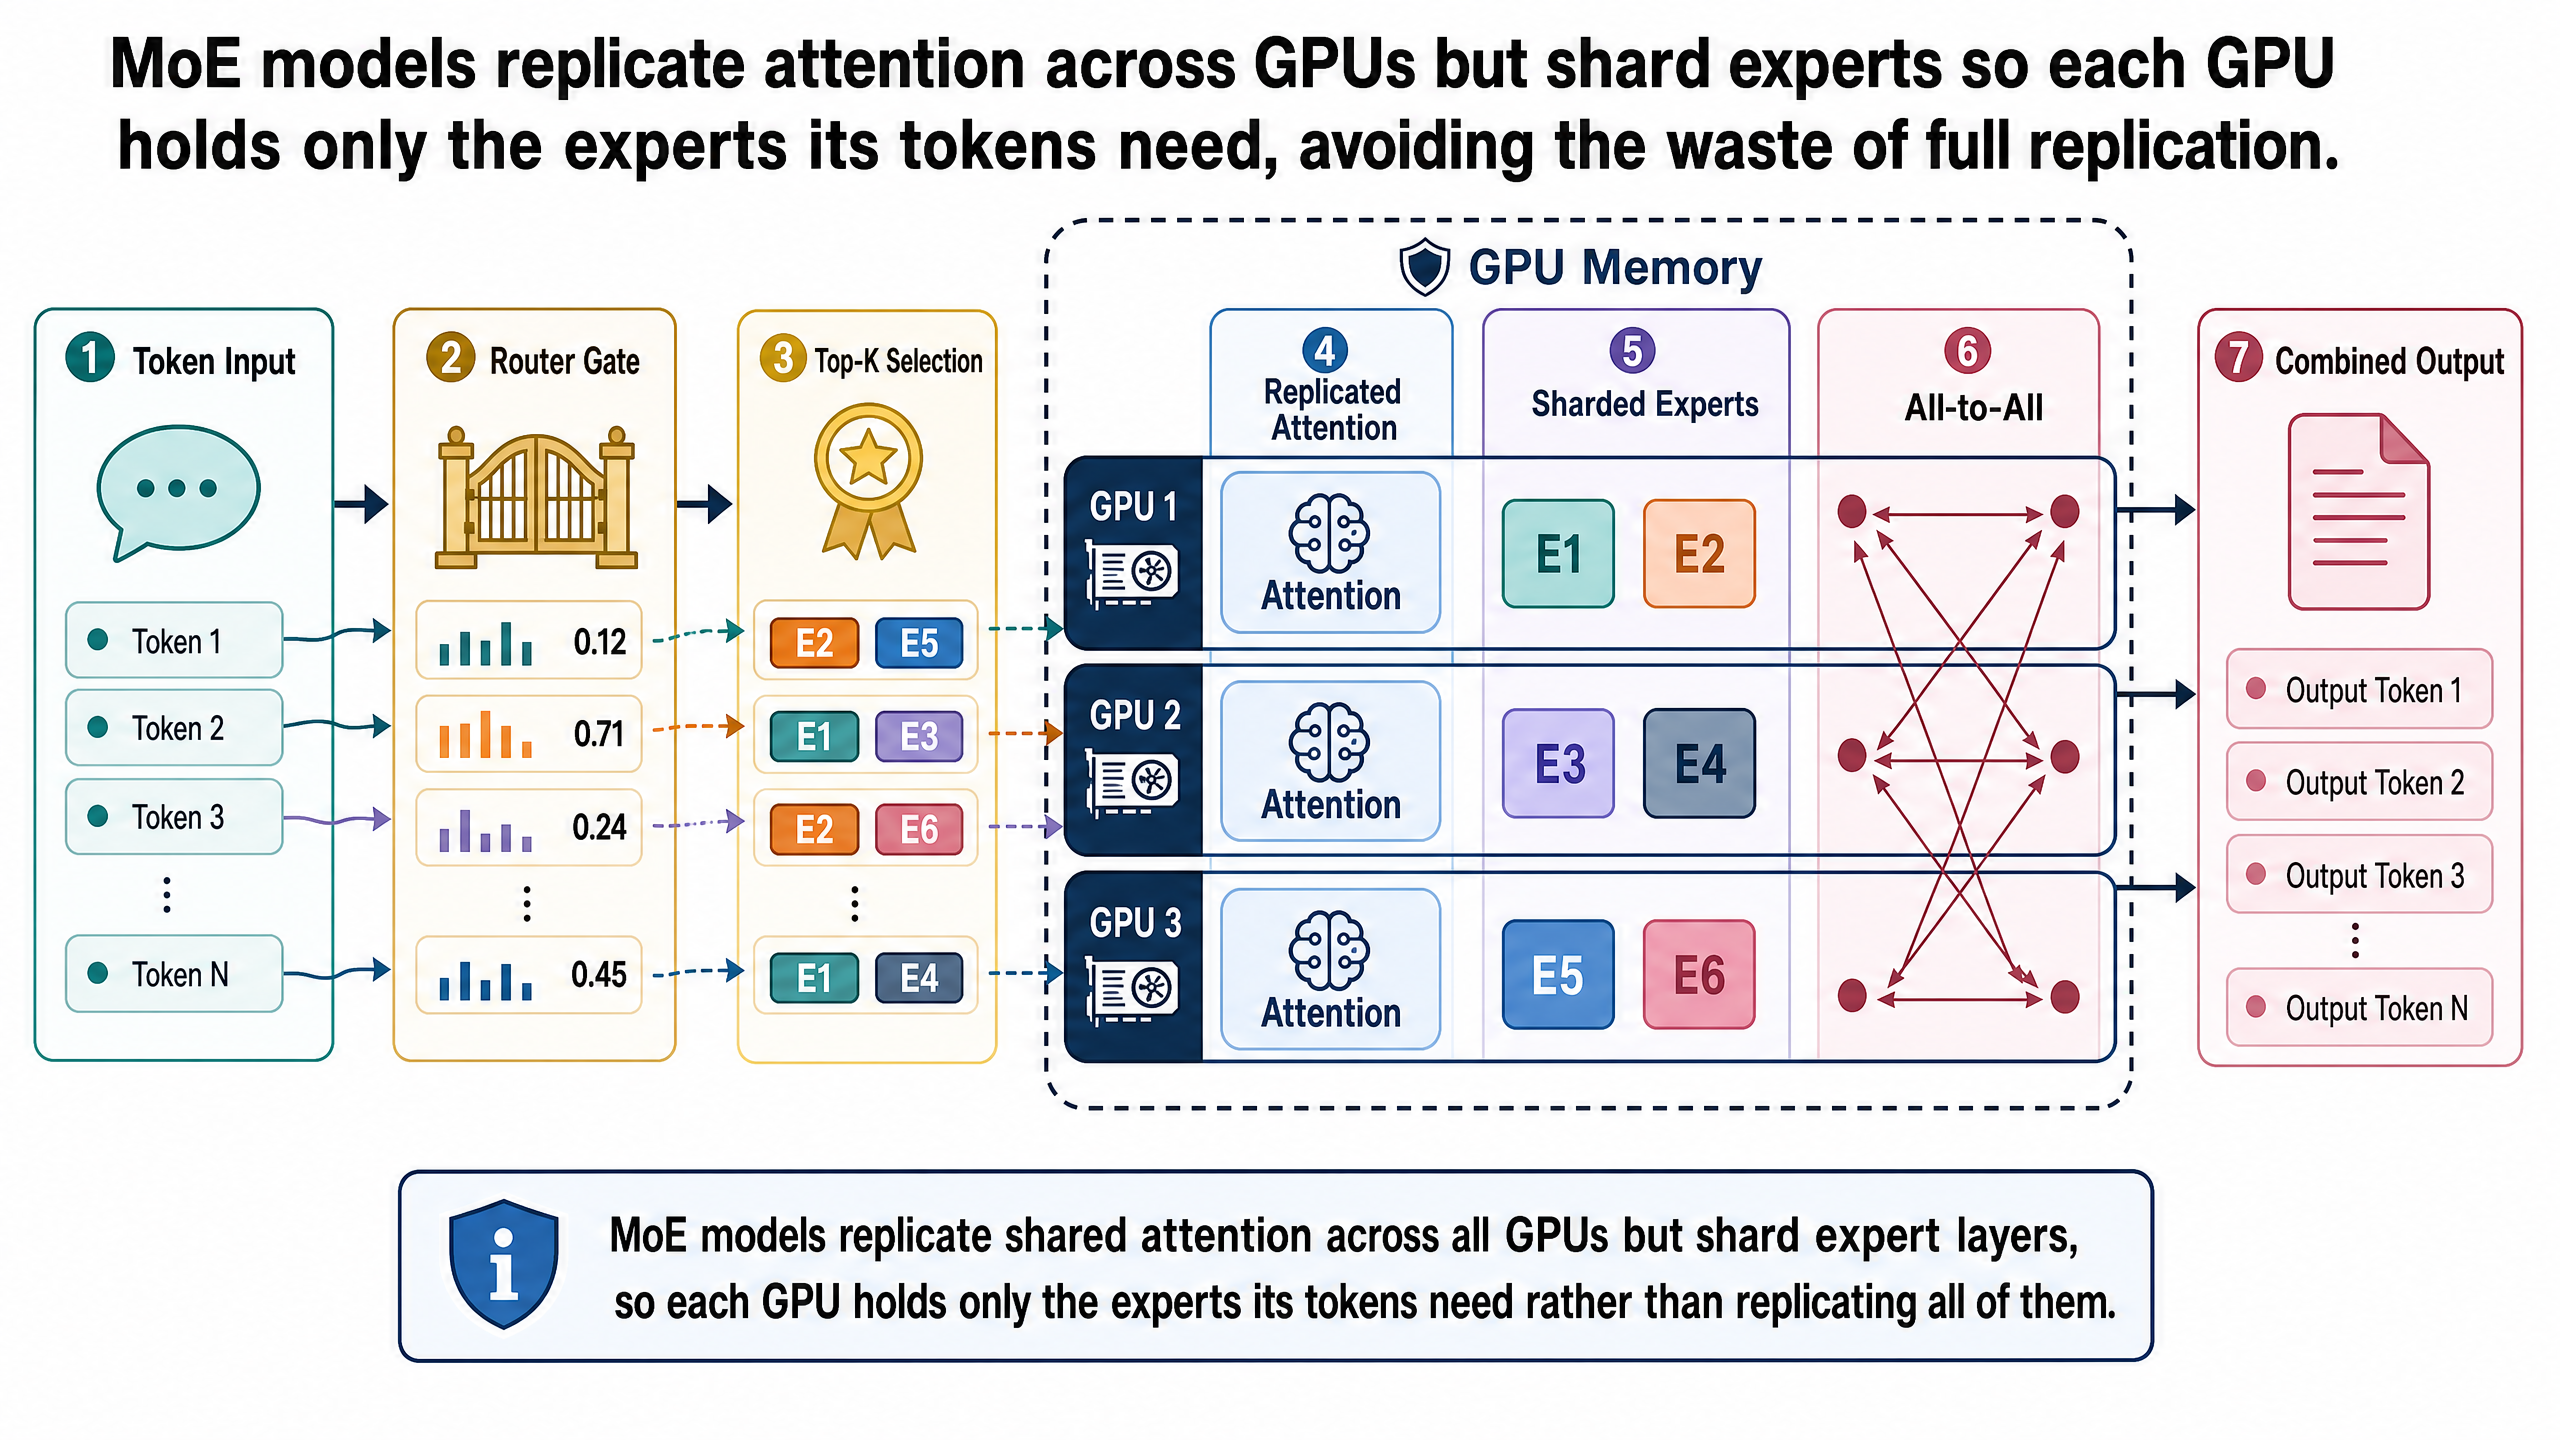
MoE Sharding: Parallelism Strategies for Mixture-of-Experts Models ...
Advertisement Space (336x280)
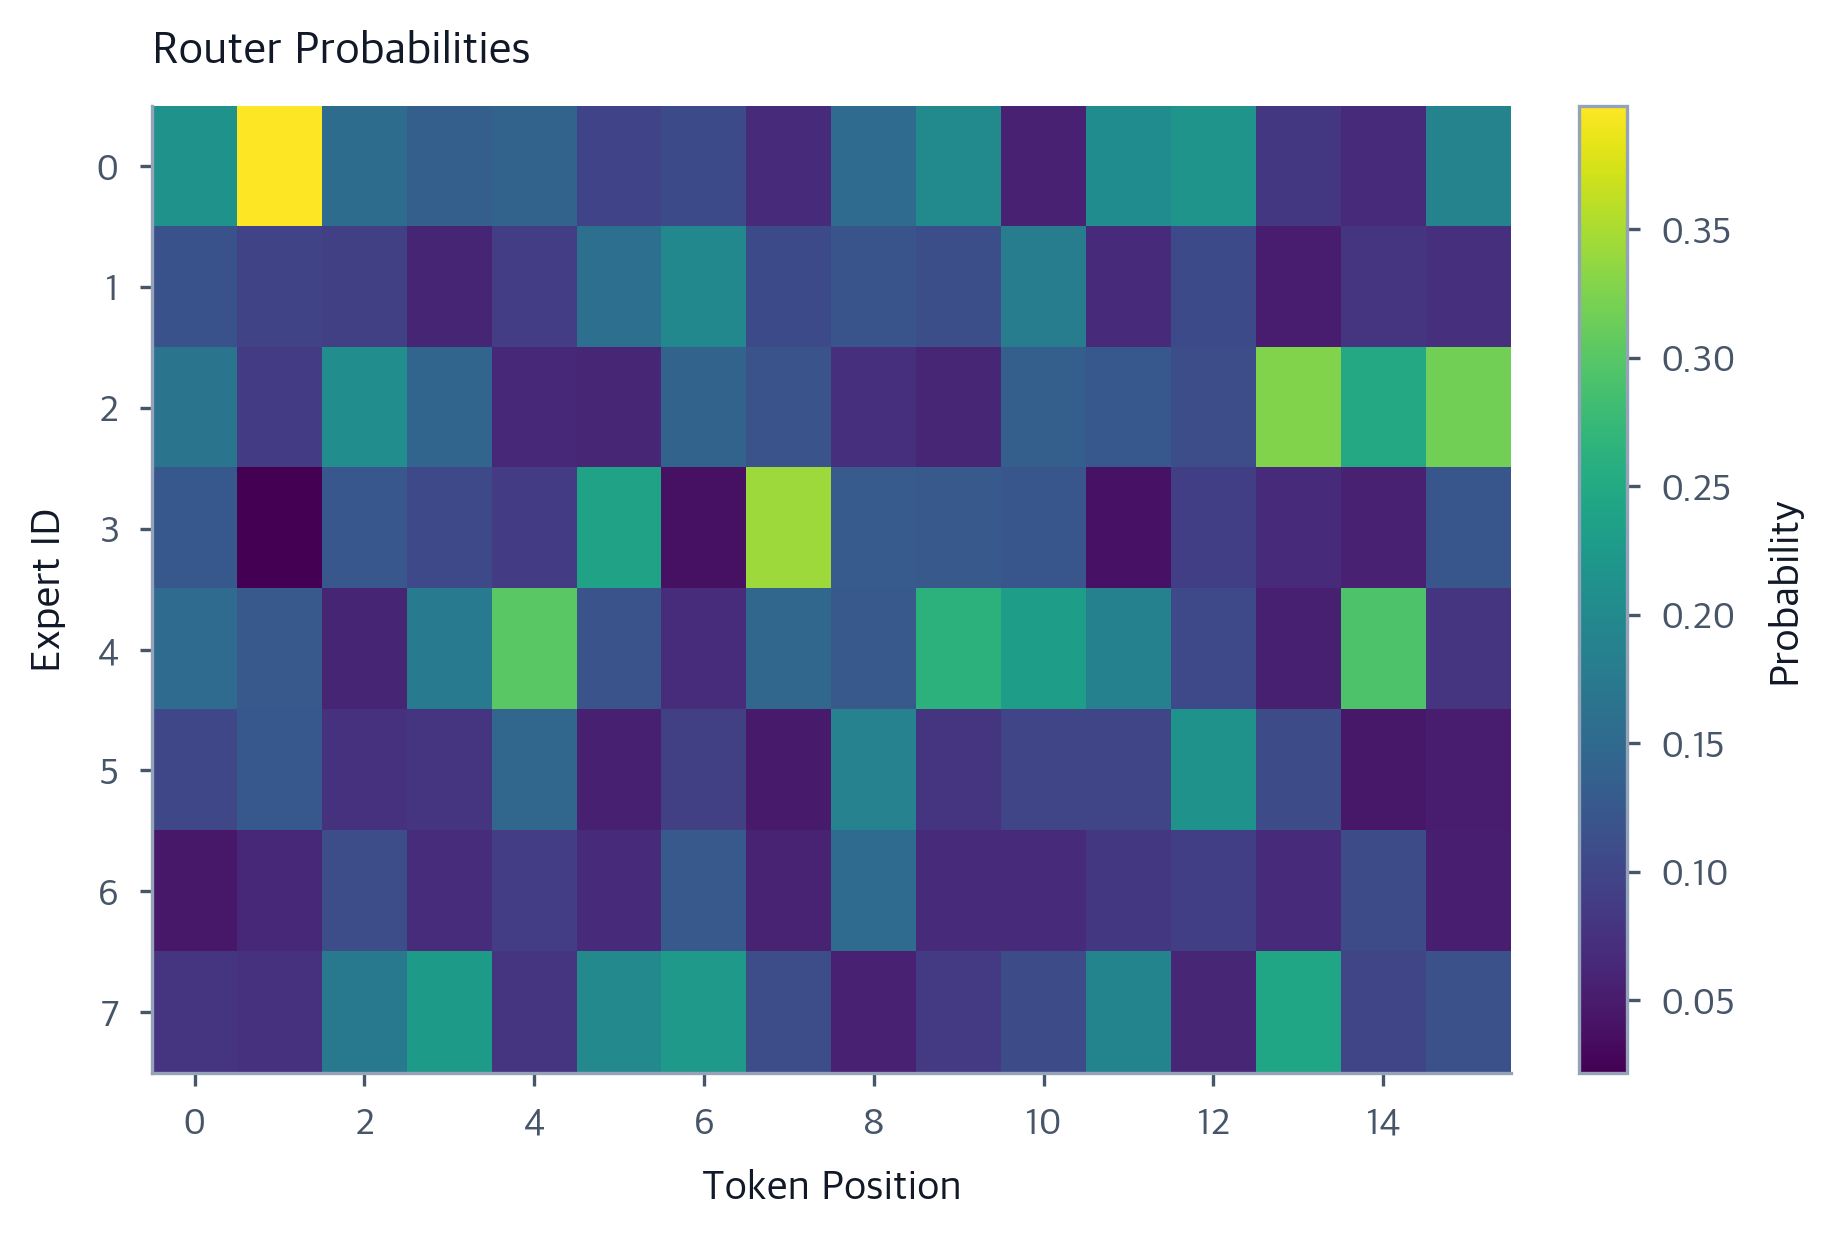
Expert Parallelism: Distributed Computing for MoE Models - Interactive ...
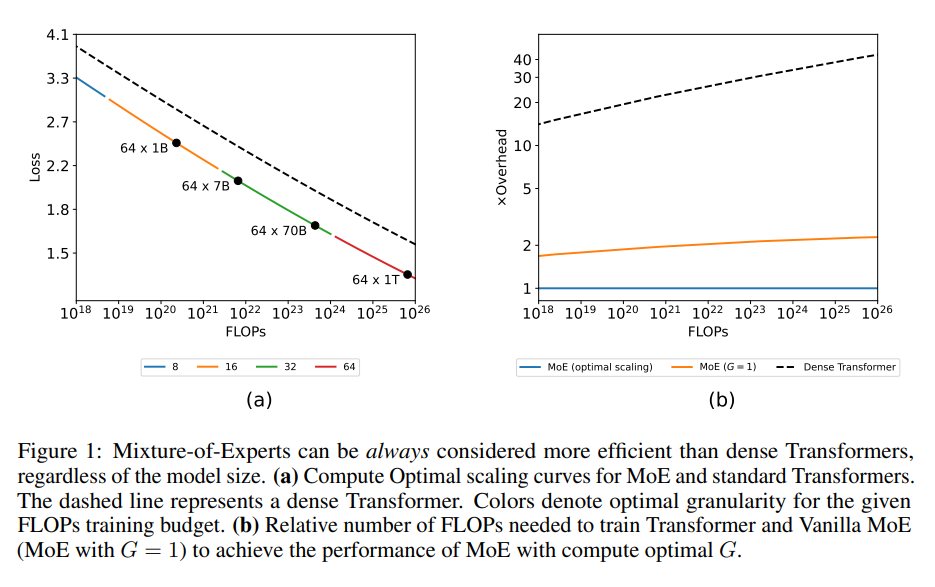
Optimizing Large Language Models with Granularity: Unveiling New ...

[论文评述] Faster MoE LLM Inference for Extremely Large Models

Expert Parallelism: Distributed Computing for MoE Models - Interactive ...

New Open Source Qwen3-Next Models Preview Hybrid MoE Architecture ...

New Open Source Qwen3-Next Models Preview Hybrid MoE Architecture ...