
Moe Model Inference On Gpu Cloud Expert Parallelism Memory And Cost
MoE Model Inference on GPU Cloud: Expert Parallelism, Memory, and Cost ...
Deploy DeepSeek V4 on GPU Cloud: MoE Inference with vLLM and Expert ...
Speculative Decoding for MoE Models on GPU Cloud: Expert Parallelism ...
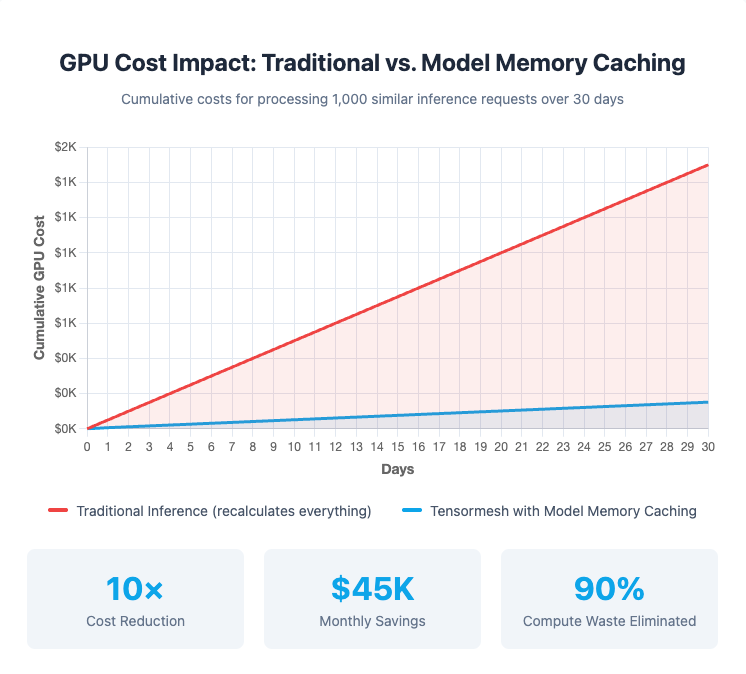
GPU Cost Crisis: How Model Memory Caching Cuts AI Inference Costs Up to ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...
Dynamic Expert Quantization on GPU Cloud: Run Giant MoE Models on Fewer ...
Advertisement Space (300x250)
Deploy MiMo-V2-Flash on GPU Cloud: Xiaomi's 309B MoE Model Setup Guide ...
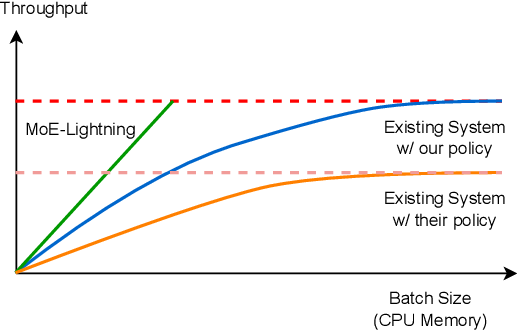
Figure 1 from MoE-Lightning: High-Throughput MoE Inference on Memory ...

MoE-Gen: High-Throughput MoE Inference on a Single GPU with Module ...

(PDF) MoE-Gen: High-Throughput MoE Inference on a Single GPU with ...

Paper page - MoE-Gen: High-Throughput MoE Inference on a Single GPU ...
MoE Inference Costs 8.6x GPU Memory of Dense Models
Integrating Expert and Data Parallelism in MoE

ICML Poster FloE: On-the-Fly MoE Inference on Memory-constrained GPU

DeepSpeed: Advancing MoE inference and training to power next ...

Figure 1 from A Scheduling Framework for Efficient MoE Inference on ...
Advertisement Space (336x280)

DeepSpeed: Advancing MoE inference and training to power next ...
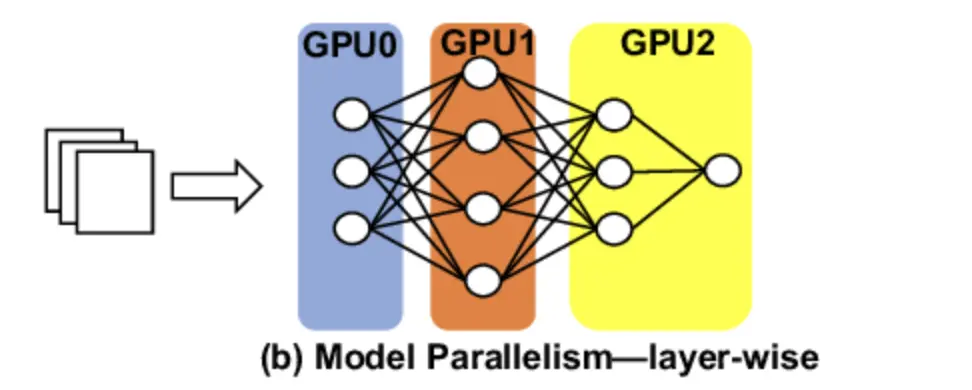
What is Inference Parallelism and How it Works
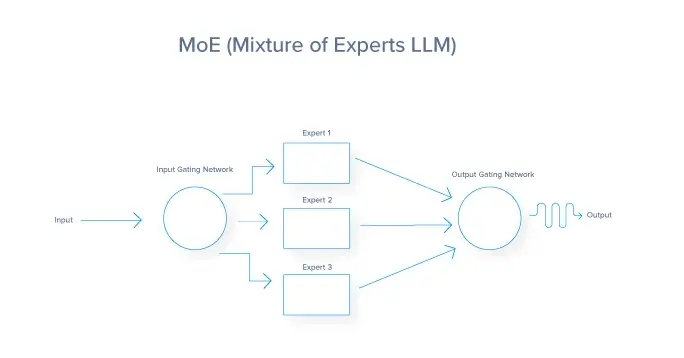
What is Inference Parallelism and How it Works

CoX-MoE: Coalesced Expert Execution for High-Throughput MoE Inference ...

DeepSpeed: Advancing MoE inference and training to power next ...
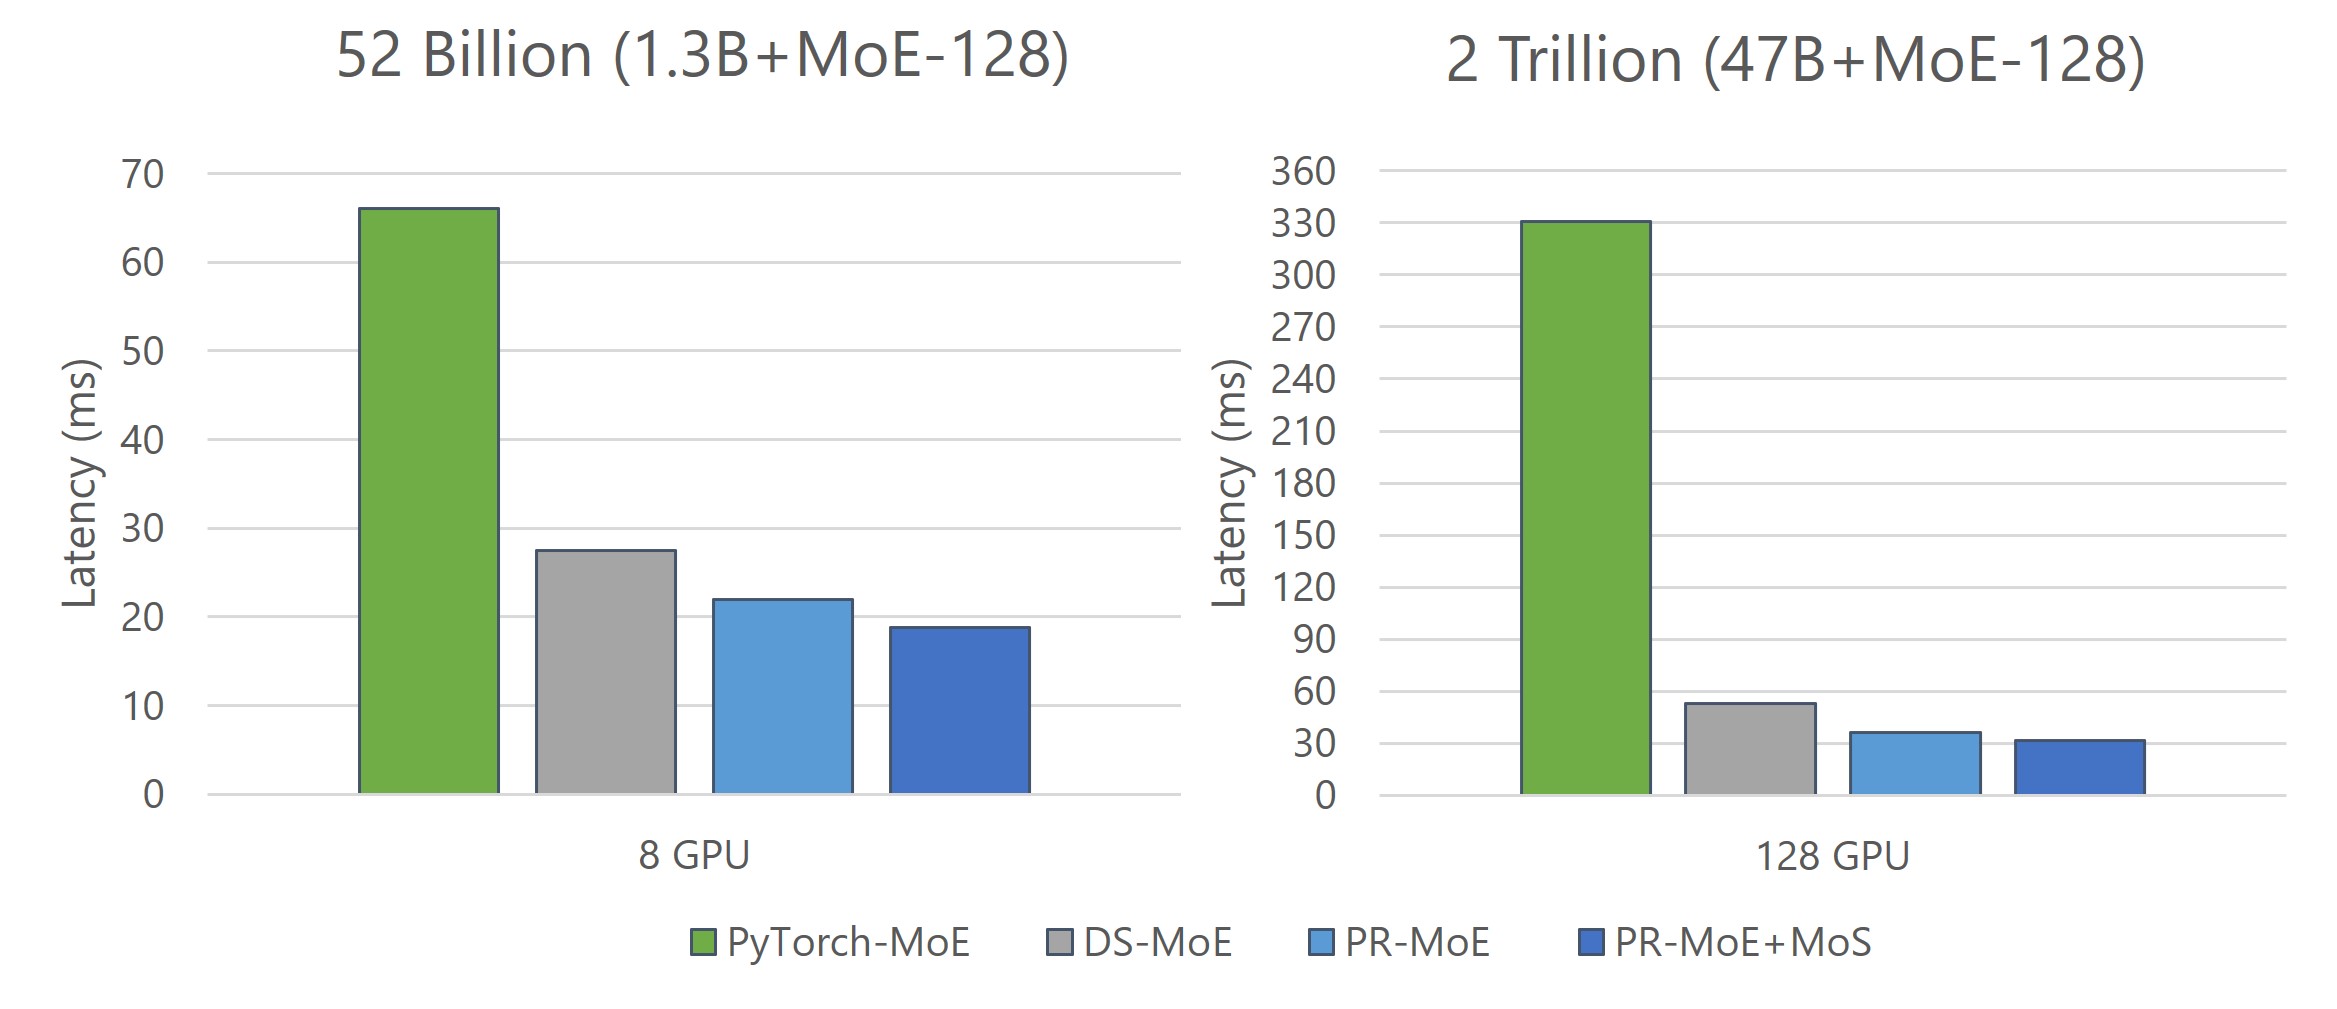
DeepSpeed: Advancing MoE inference and training to power next ...

Parallelism and Memory Optimization Techniques for Training Large ...
Deploy Mistral Large 3 on GPU Cloud: Self-Host the 675B MoE with vLLM ...

CoX-MoE: Coalesced Expert Execution for High-Throughput MoE Inference ...
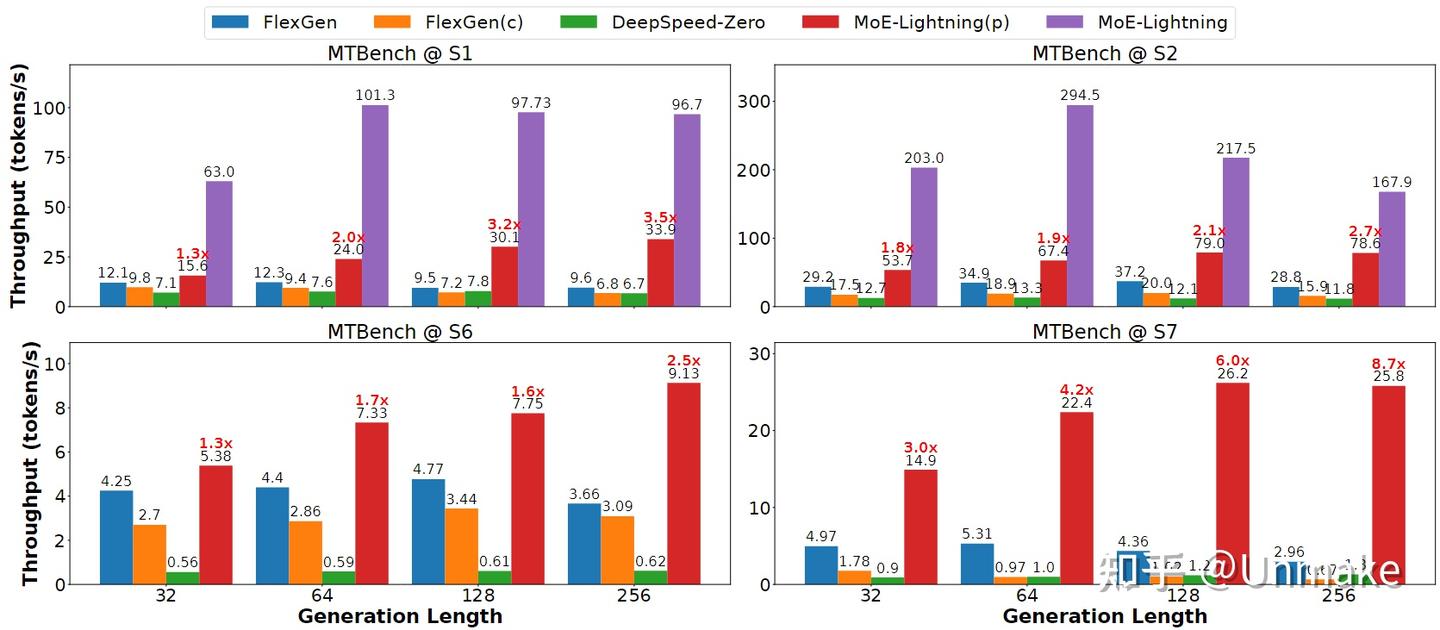
MoE-Lightning: High-Throughput MoE Inference on Memory-constrained GPUs ...
Advertisement Space (336x280)

[논문 리뷰] ExpertFlow: Adaptive Expert Scheduling and Memory Coordination ...
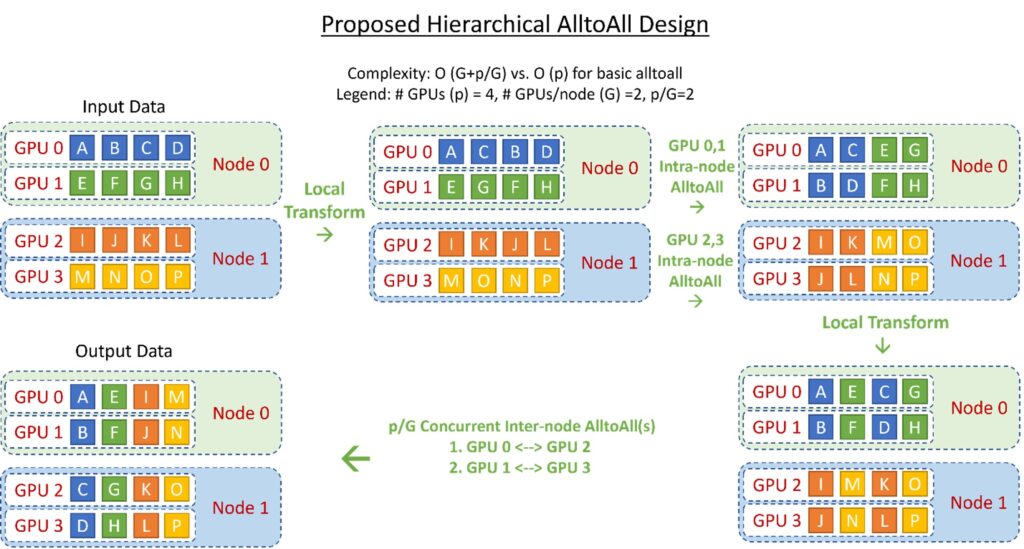
DeepSpeed: Advancing MoE inference and training to power next ...

Accelerating Distributed MoE Training and Inference with Lina | AI ...

EPS-MoE: Expert Pipeline Scheduler for Cost-Efficient MoE Inference

Expert Parallelism: Distributed Computing for MoE Models - Interactive ...
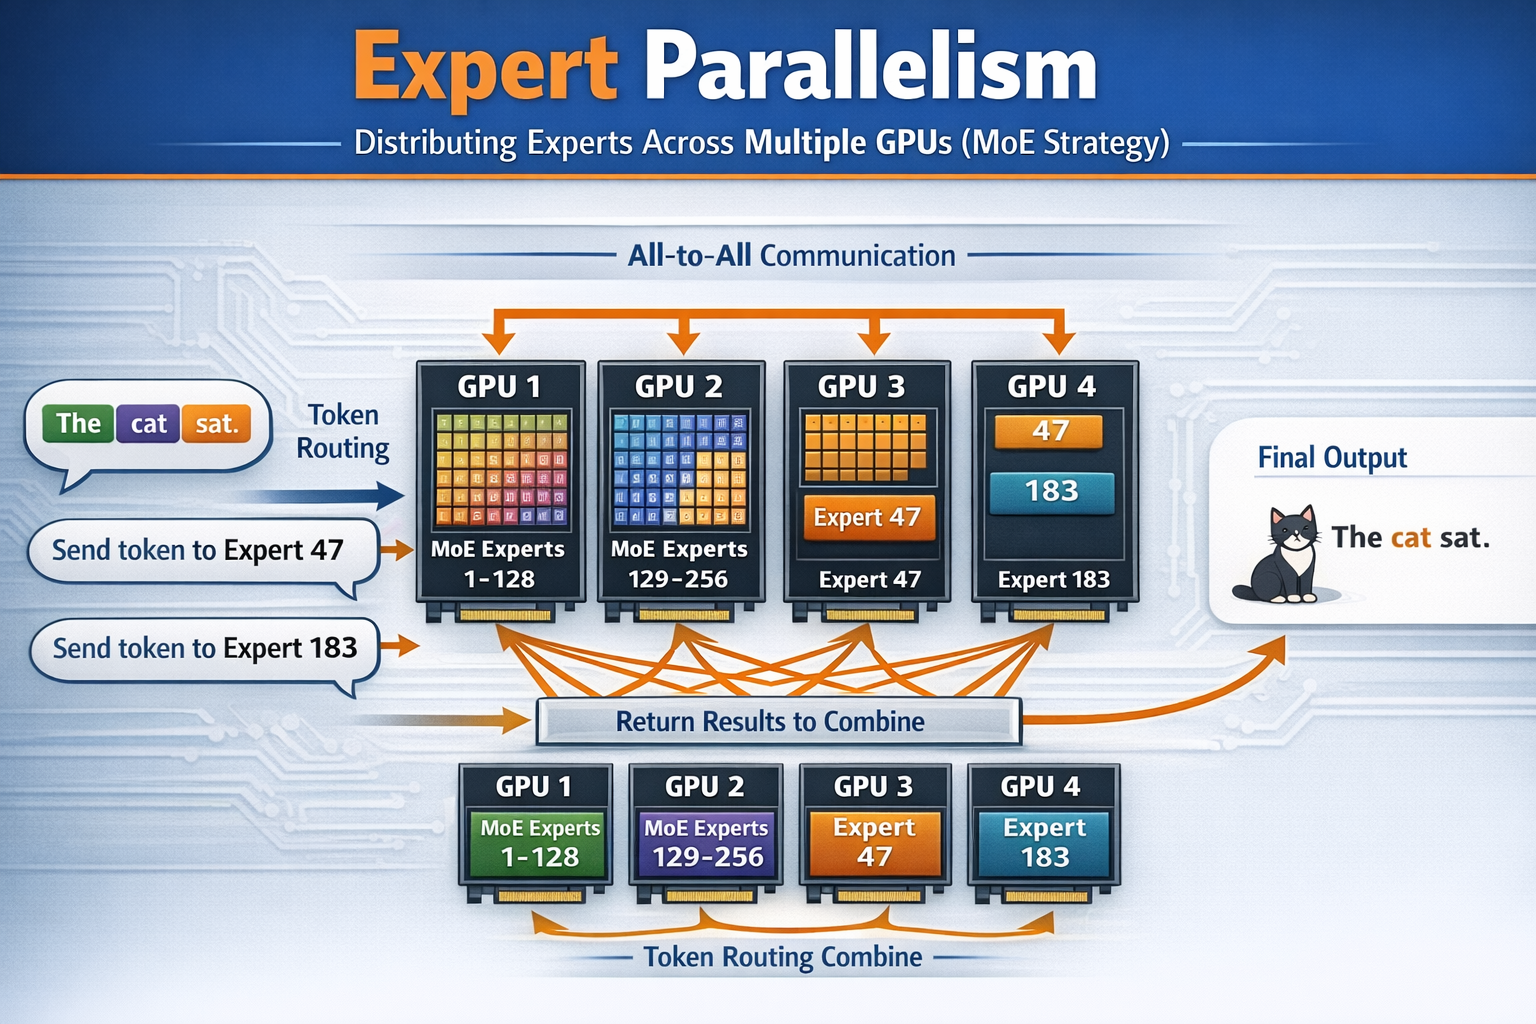
The State of AI Inference and Running Models at Home