
Optimizing Cloud Inference Workloads Pdf Graphics Processing Unit
Optimizing Cloud Inference Workloads | PDF | Graphics Processing Unit ...

Splitwise: Optimizing LLM Inference | PDF | Graphics Processing Unit ...

Optimizing Cloud Monitoring Alerts | PDF | Statistical Inference ...

ZOne: Optimizing GPU Big Data Processing | PDF | Graphics Processing ...
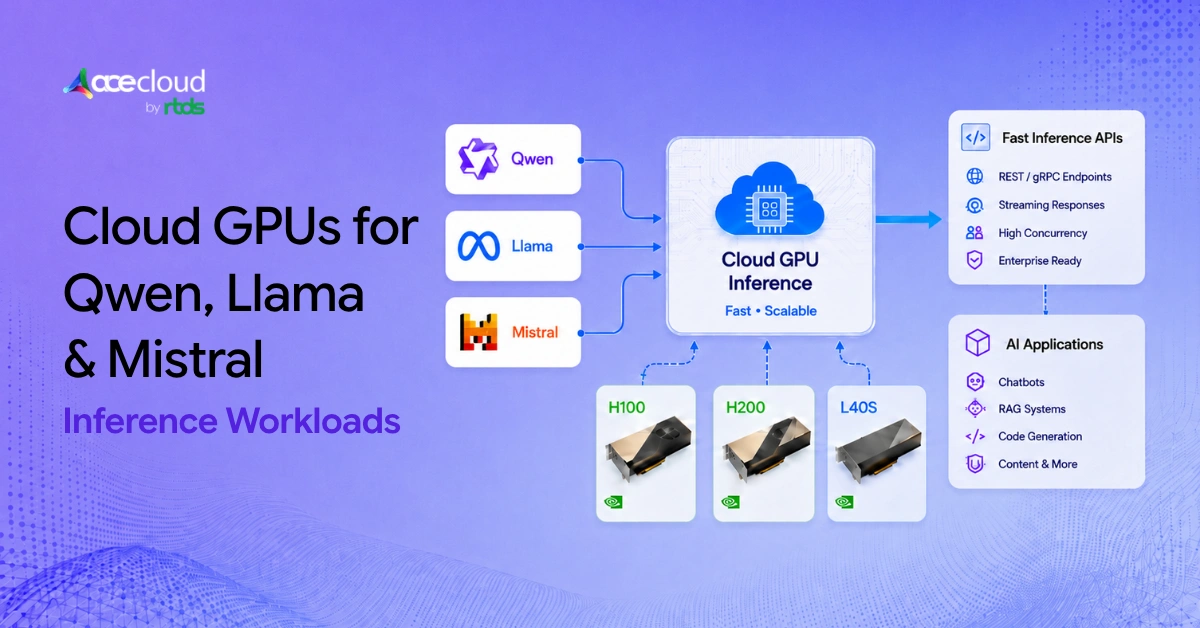
Best Cloud GPUs For Qwen, Llama And Mistral Inference Workloads
Leveraging CPUs for AI Inference Workloads with Google Cloud C3D and ...
How to Architect AI Workloads for Sovereign Cloud | Inference Systems

(PDF) Characterizing and Optimizing LLM Inference Workloads on CPU-GPU ...
AI Integration for Endpoint Security for Cloud Workloads | Inference ...
Leveraging CPUs for AI Inference Workloads with Google Cloud C3D and ...
Advertisement Space (300x250)

Optimizing AI Inference on GPUs | PDF | Deep Learning | Program ...
AI Integration for Spectro Cloud AI/ML Workloads | Inference Systems
Edge AI vs Cloud Processing for Real-Time Field Analysis | Inference ...

Free Video: Optimizing Cloud Workloads with Intel Infrastructure ...
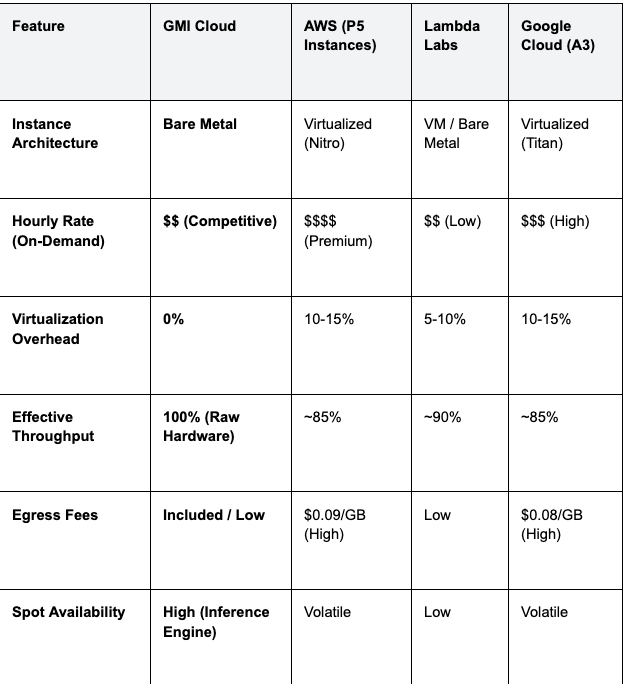
Compare GPU Cloud Pricing for LLM Inference Workloads

Optimizing GNN Inference Processing on Very Long Vector Processor ...
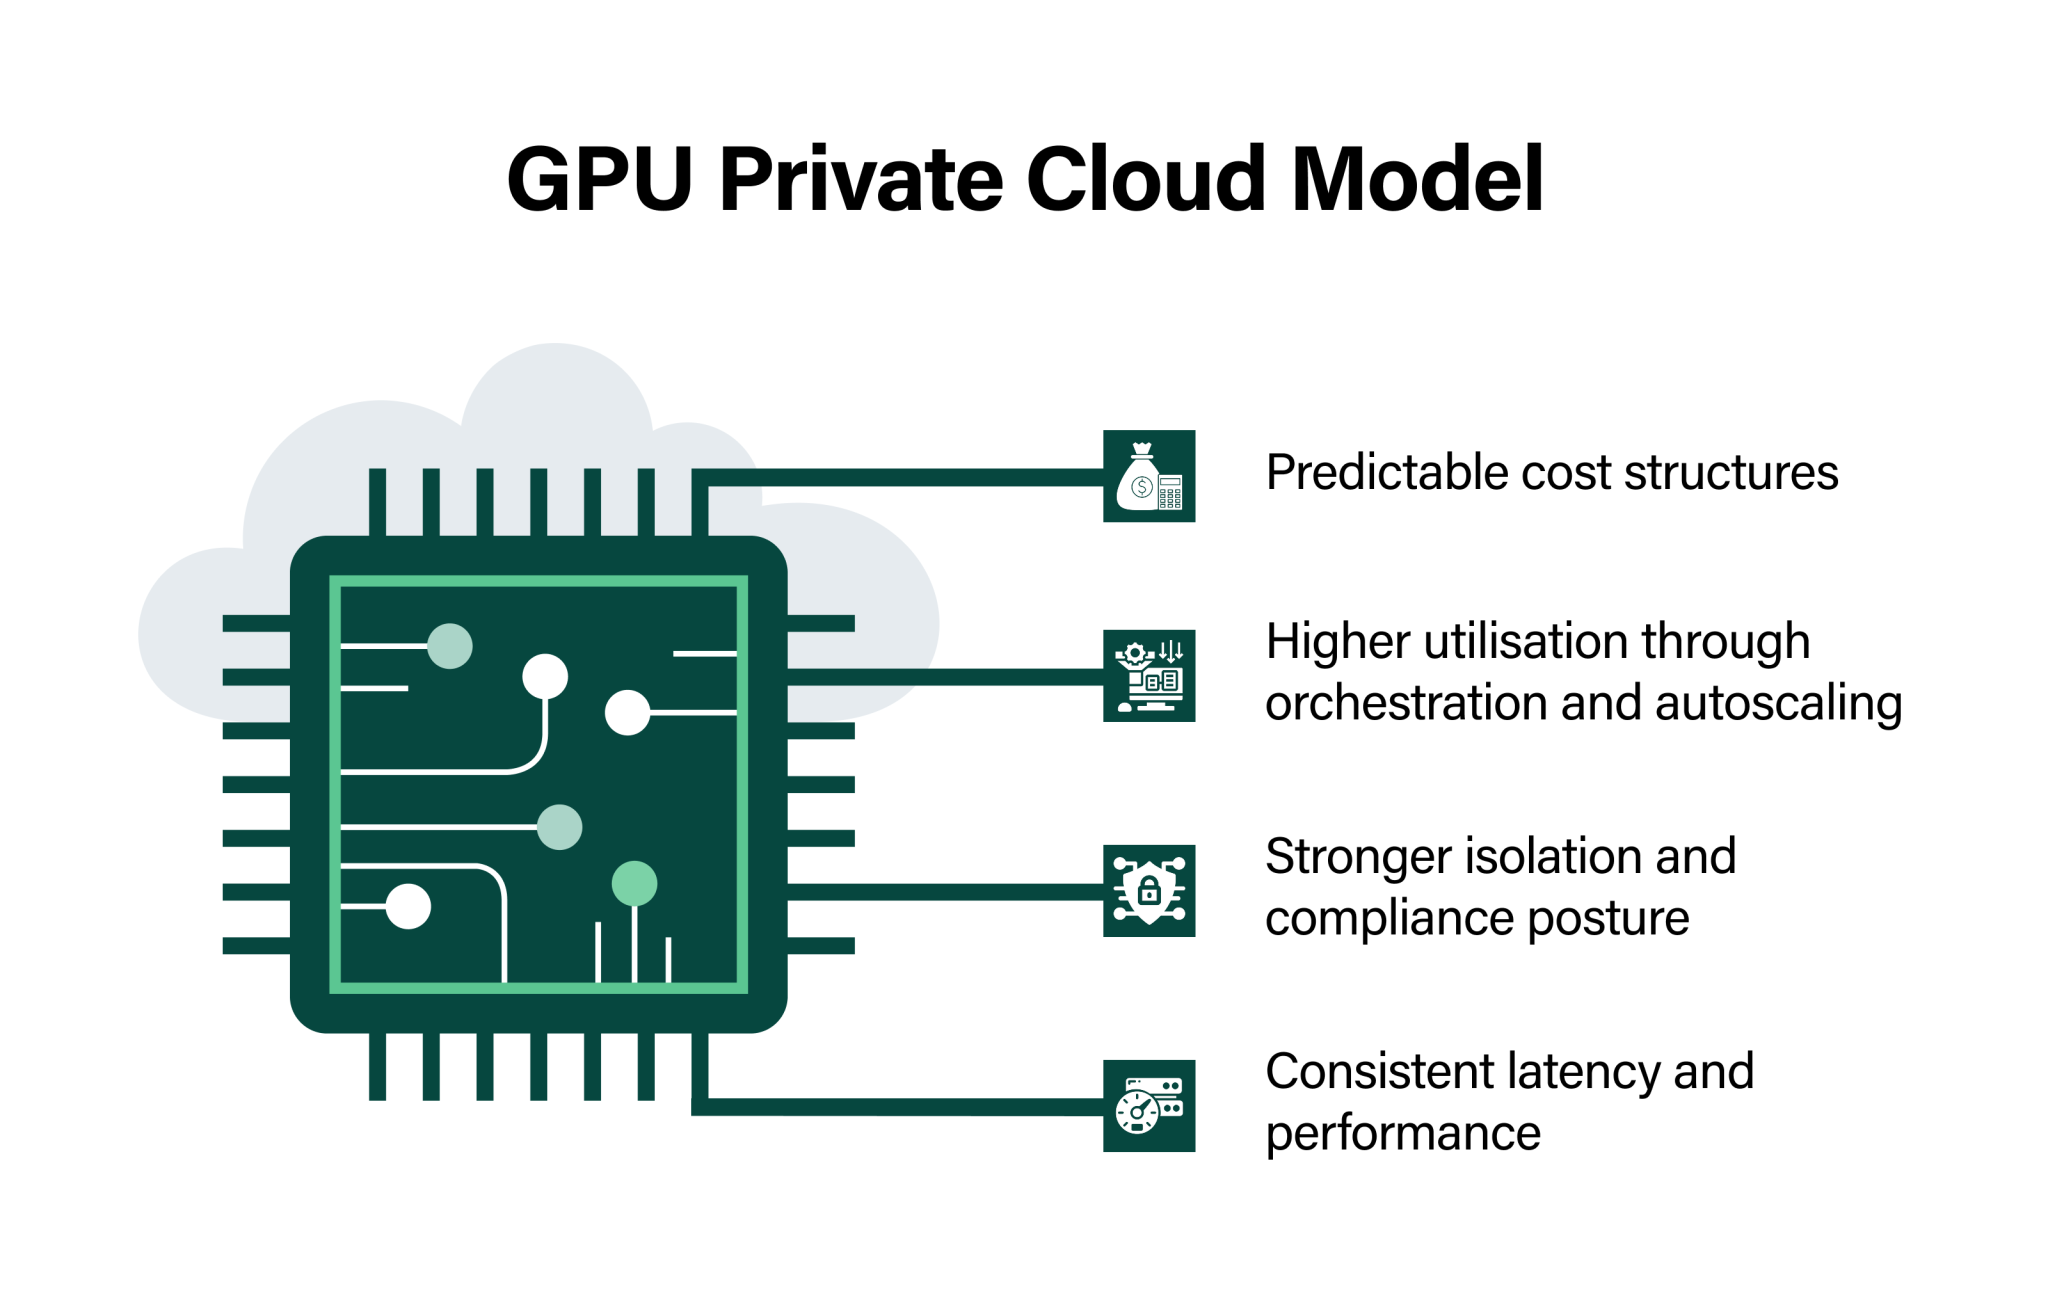
Control GenAI Inference Costs with GPU Private Cloud
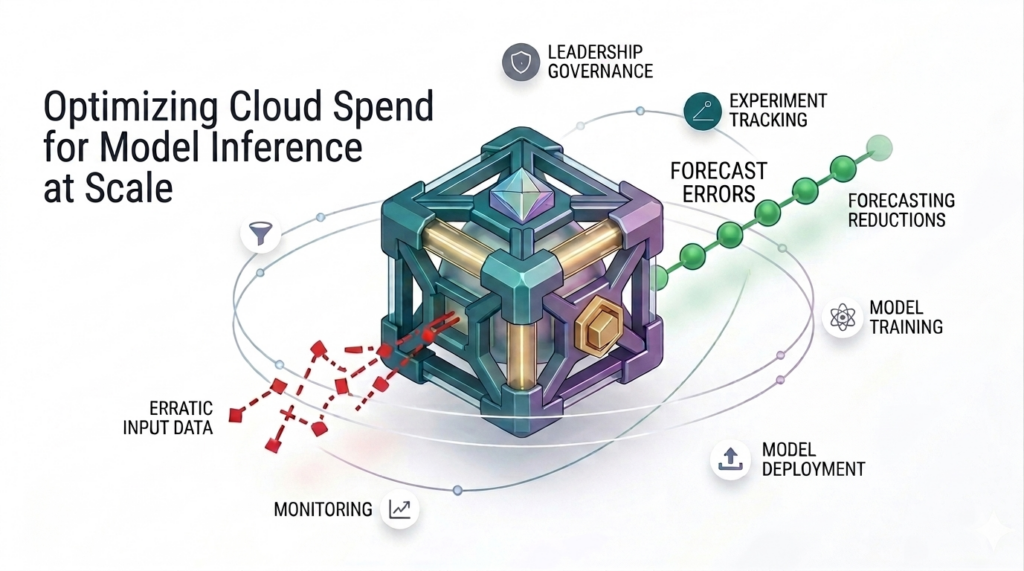
Optimize Cloud Spend for Model Inference at Scale
AI Integration for SentinelOne Cloud Workload Protection | Inference ...
Optimizing Compute & Storage for AI Workloads - Binadox
Advertisement Space (336x280)

(PDF) Optimizing GPU-Intensive Workloads with Converged Infrastructure

Optimizing AI Inference Workloads: Reducing Latency, Boosting ...

Hybrid Cloud Intelligent Workload Management | PDF | Workload | Cloud ...
Cloud AI Inference Workload Capacity Consumption to Surpass Training by ...
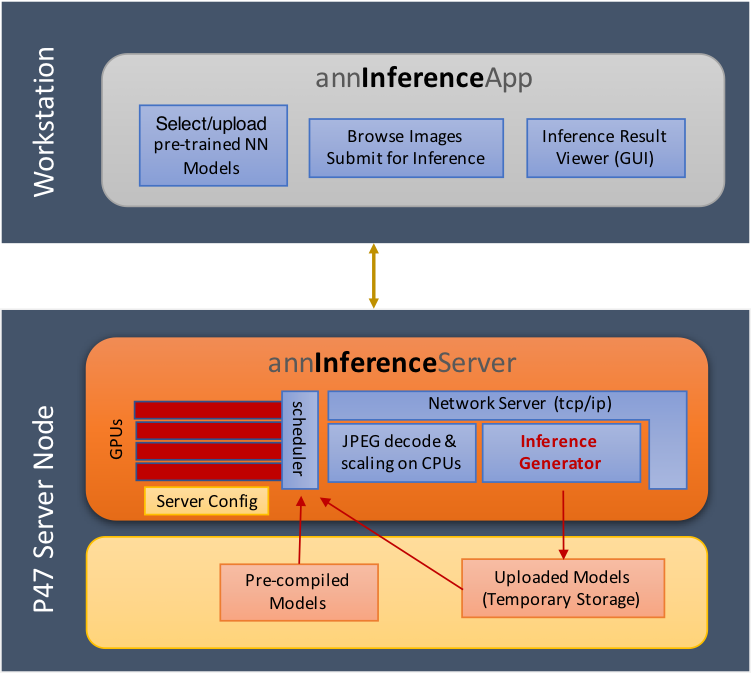
Cloud Inference Application — MIVisionX 2.5.0 Documentation
Cloud Cost Optimization AI Development | Inference Systems
How to Design a Sustainable Cloud Architecture for AI | Inference Systems
Local Inference vs Cloud APIs: Latency and Cost | Suhas Bhairav

Batchllm: Optimizing Large Batched LLM Inference With Global Prefix ...
How to Optimize AI Inference Costs for Scalable Cloud Deployments
Advertisement Space (336x280)
Cost-efficient AI inference with Cloud TPU v5e on GKE | Google Cloud Blog
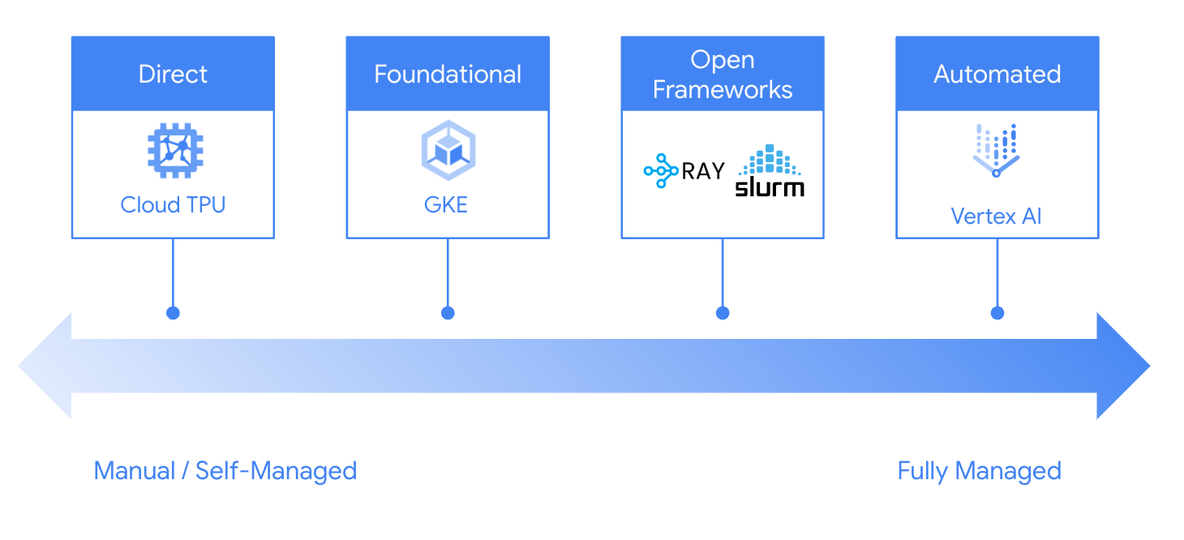
Inference.Ai Matches Ai Workloads With Cloud Gpu Compute – UEUFA
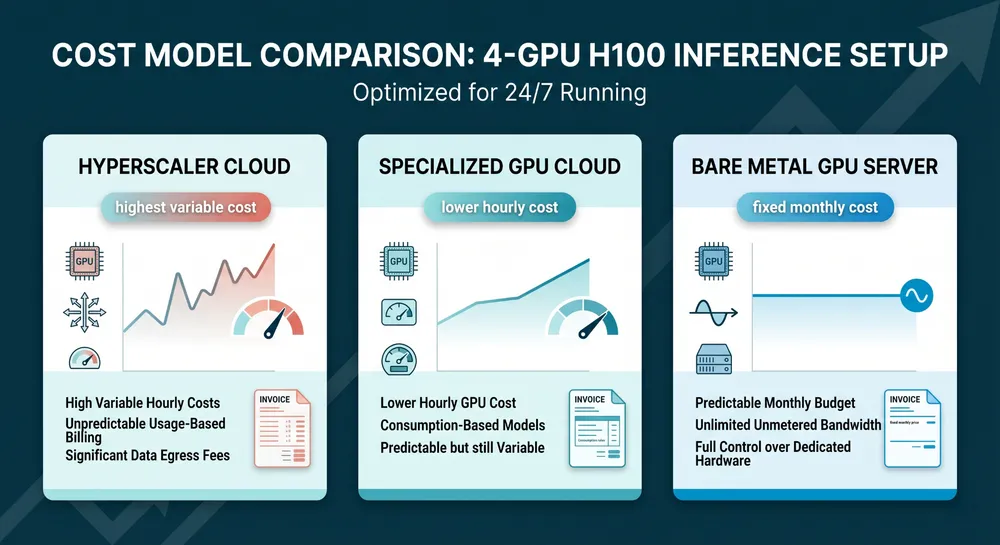
AI Inference on Bare Metal: Why Smart Teams Are Ditching Cloud GPUs in 2026

How to Monitor Cloud GPU Use for Model Training and Inference

Network compute agnostic Performance Analysis for Cloud workloads
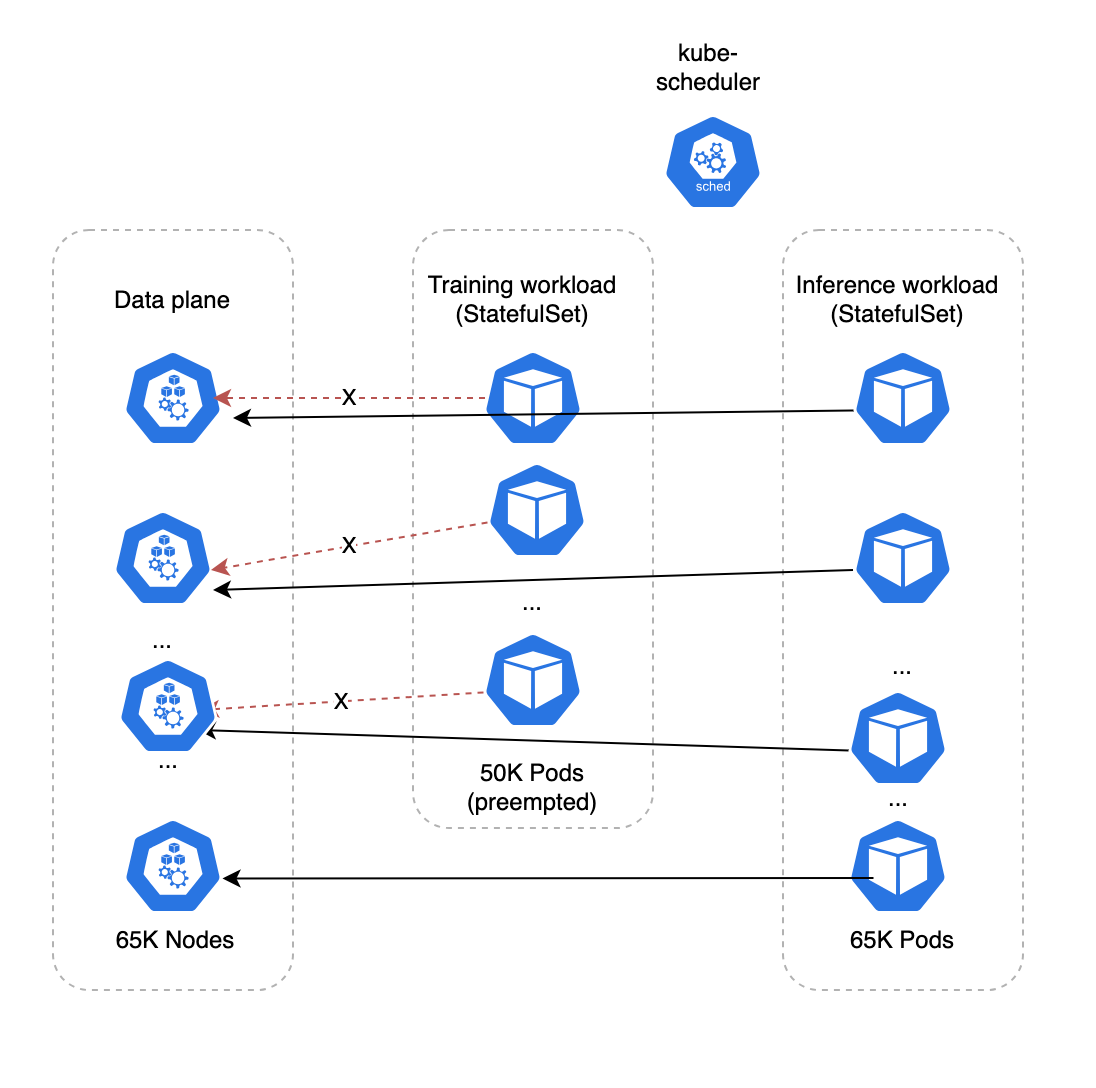
Benchmarking a 65,000-node GKE cluster with AI workloads | Google Cloud ...