
Paper Page Tuning Layernorm In Attention Towards Efficient Multi

Paper page - Tuning LayerNorm in Attention: Towards Efficient Multi ...
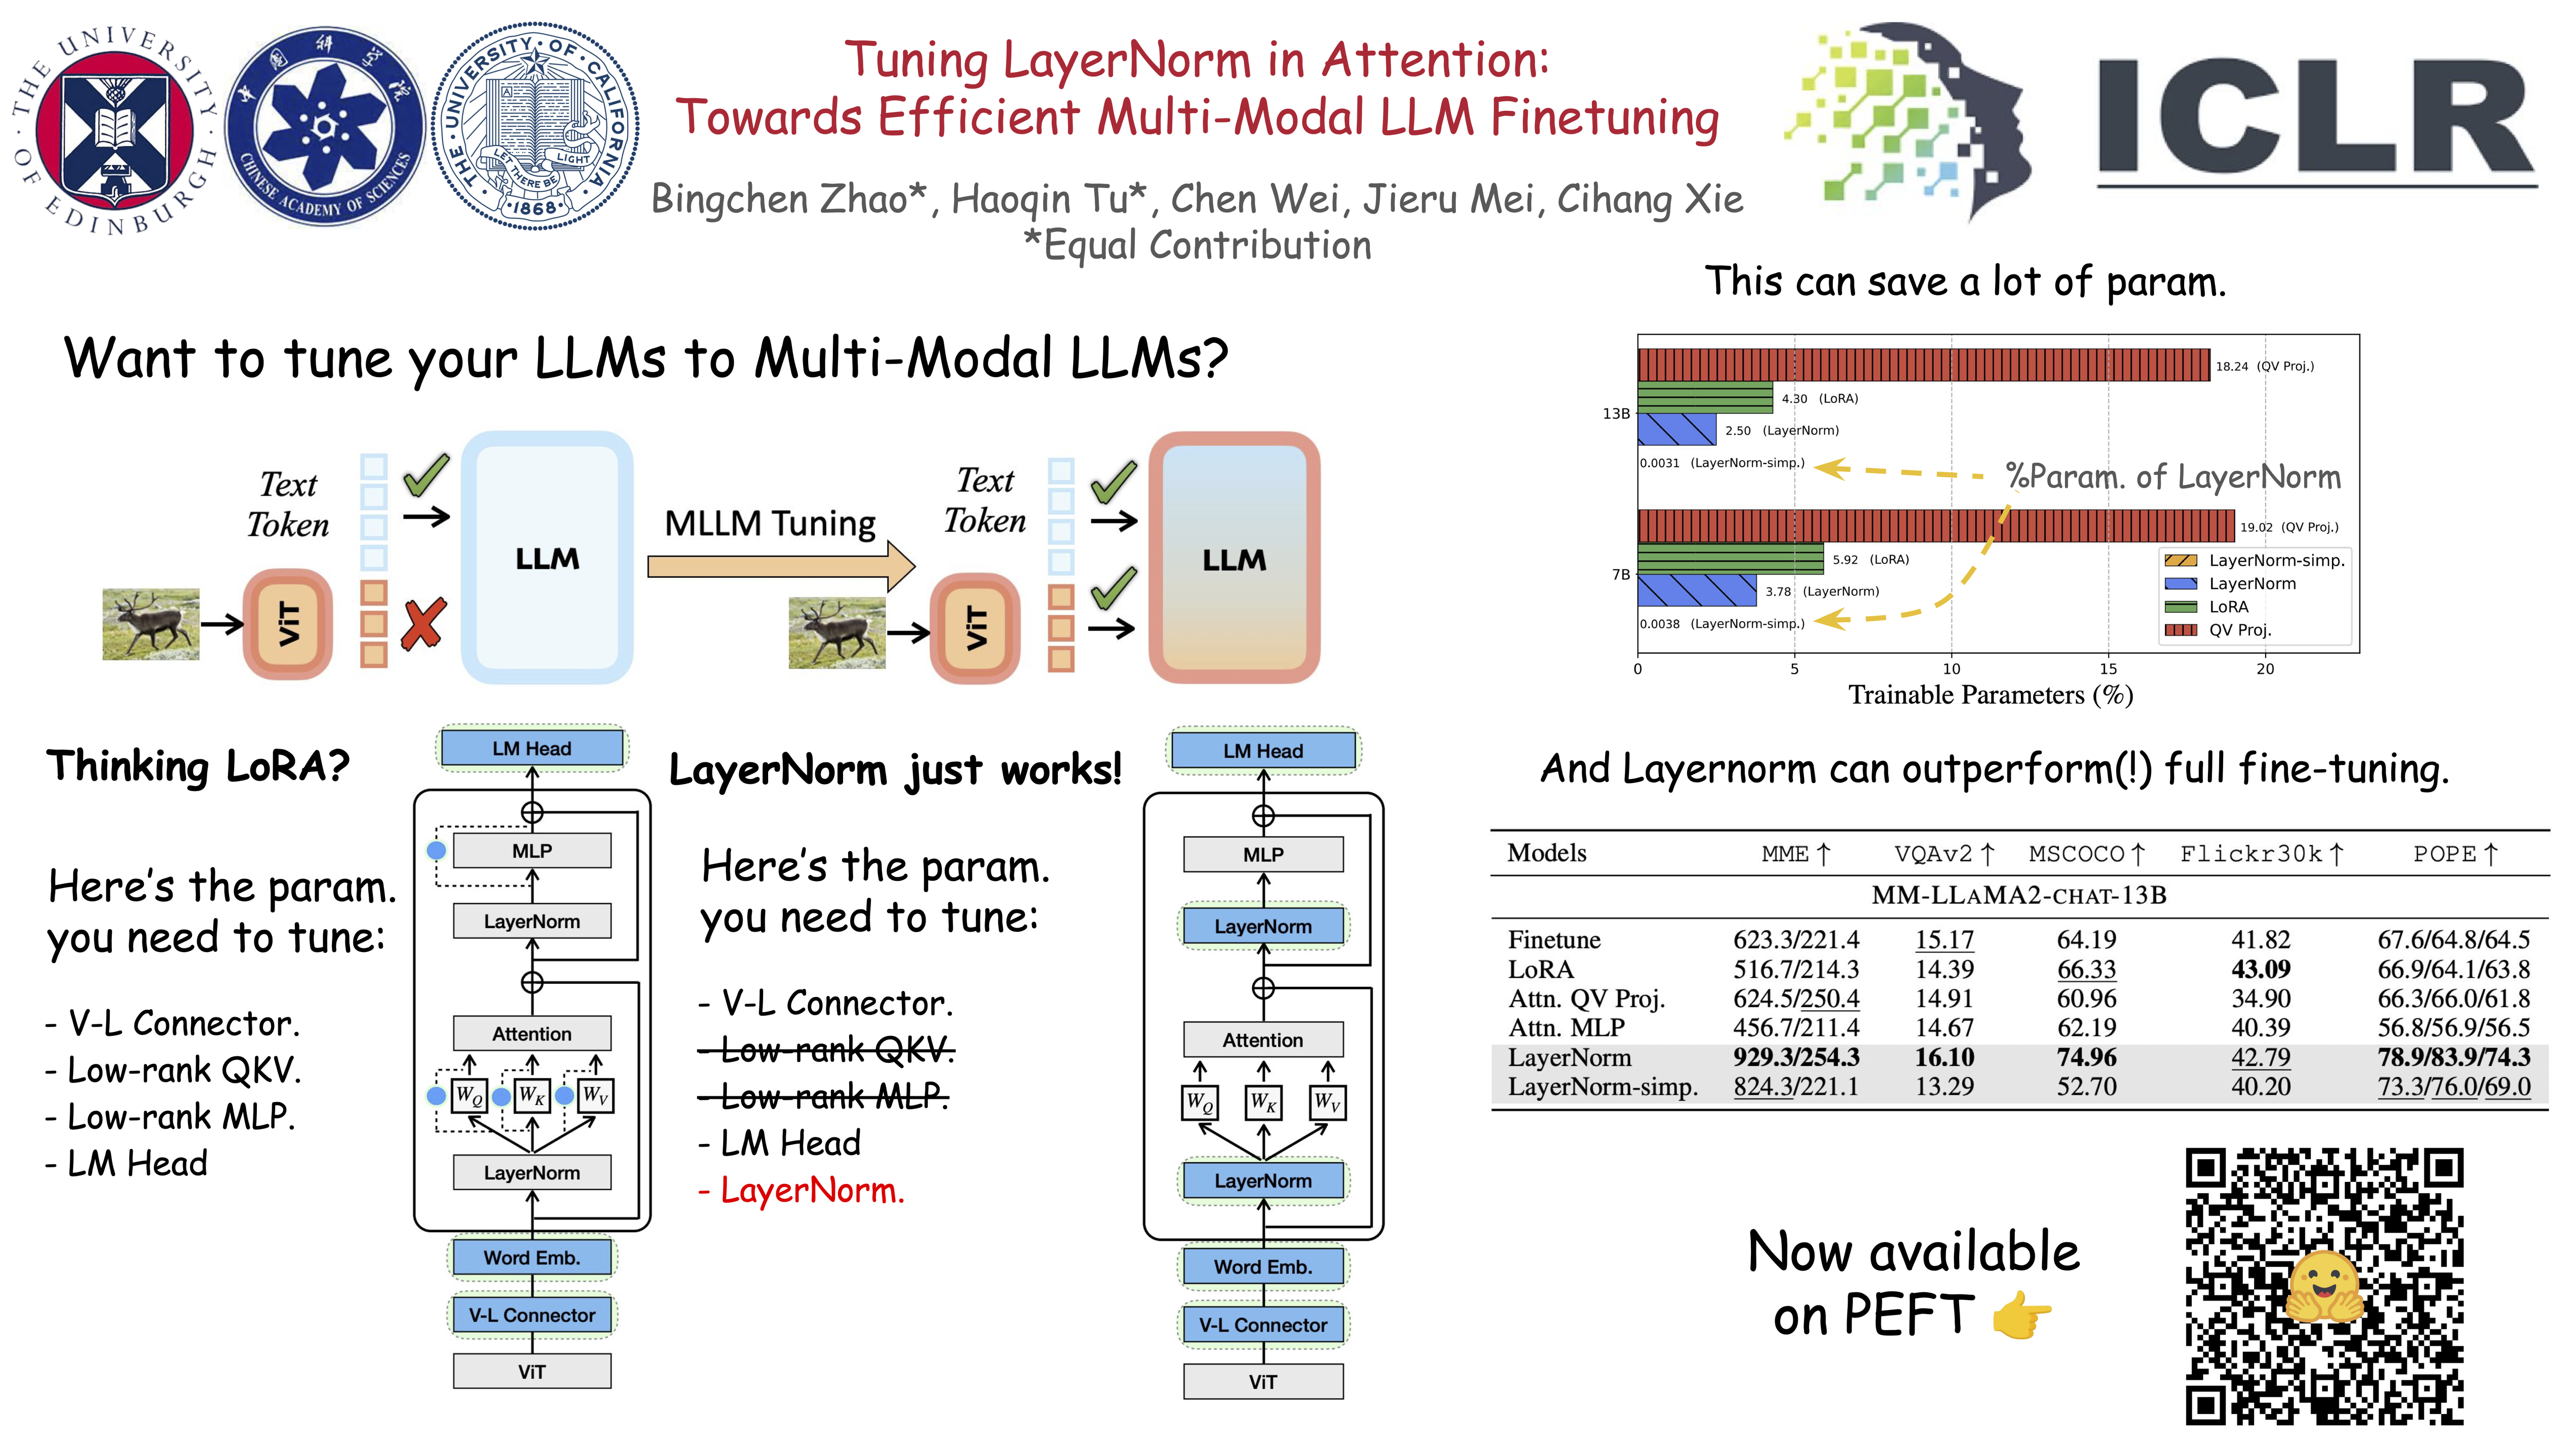
ICLR Poster Tuning LayerNorm in Attention: Towards Efficient Multi ...

[2312.11420] Tuning LayerNorm in Attention: Towards Efficient Multi ...

[2312.11420] Tuning LayerNorm in Attention: Towards Efficient Multi ...

[2312.11420] Tuning LayerNorm in Attention: Towards Efficient Multi ...

[2312.11420] Tuning LayerNorm in Attention: Towards Efficient Multi ...

[2312.11420] Tuning LayerNorm in Attention: Towards Efficient Multi ...

TUNING LAYERNORM IN ATTENTION TOWARDS EFFI CIENT MULTI MODAL LLM ...
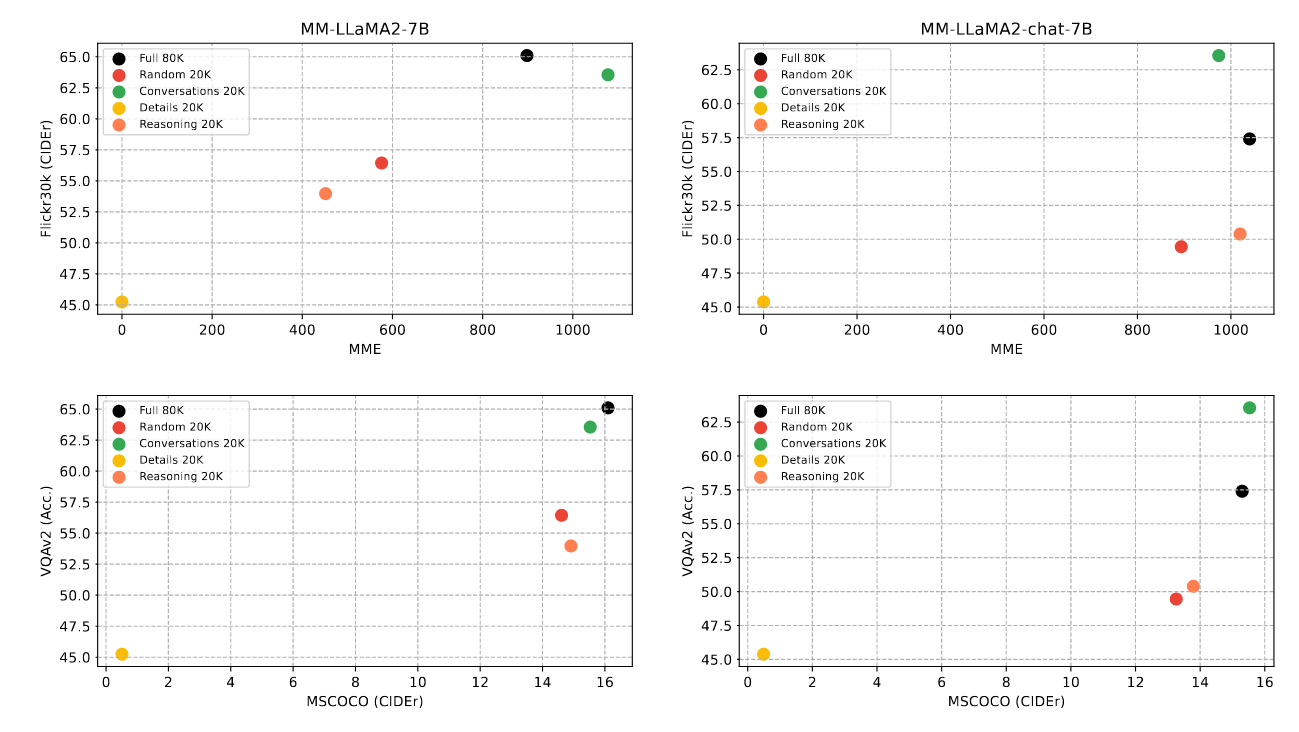
Tuning LayerNorm in Attention: Towards Efficient Multi-Modal LLM ...
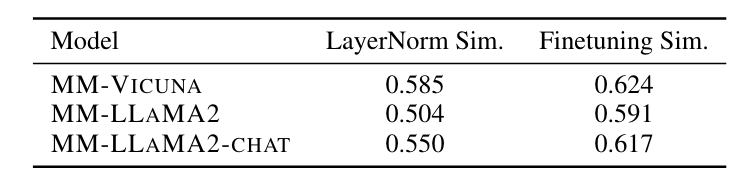
Tuning LayerNorm in Attention: Towards Efficient Multi-Modal LLM ...
Advertisement Space (300x250)
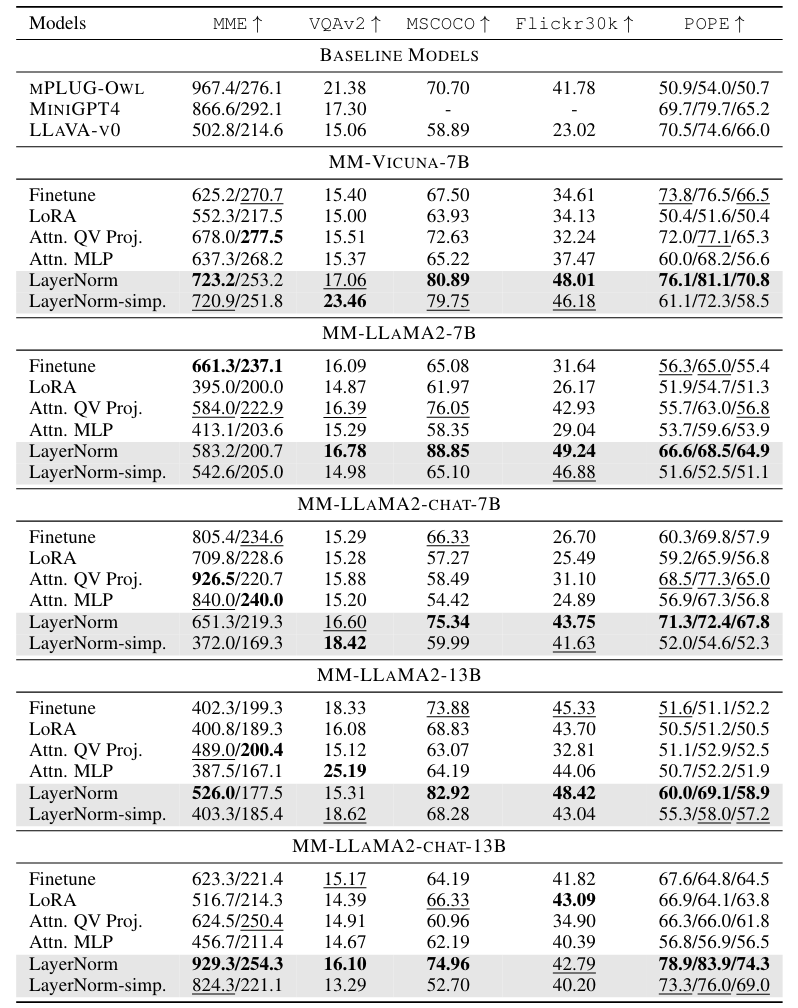
Tuning LayerNorm in Attention: Towards Efficient Multi-Modal LLM ...
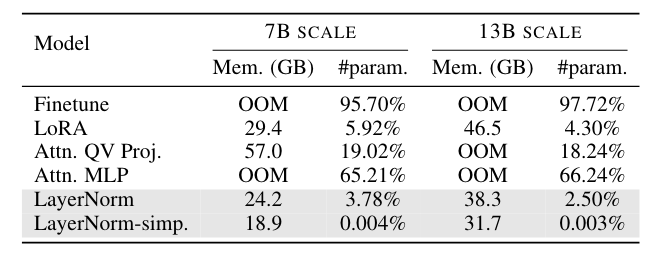
Tuning LayerNorm in Attention: Towards Efficient Multi-Modal LLM ...
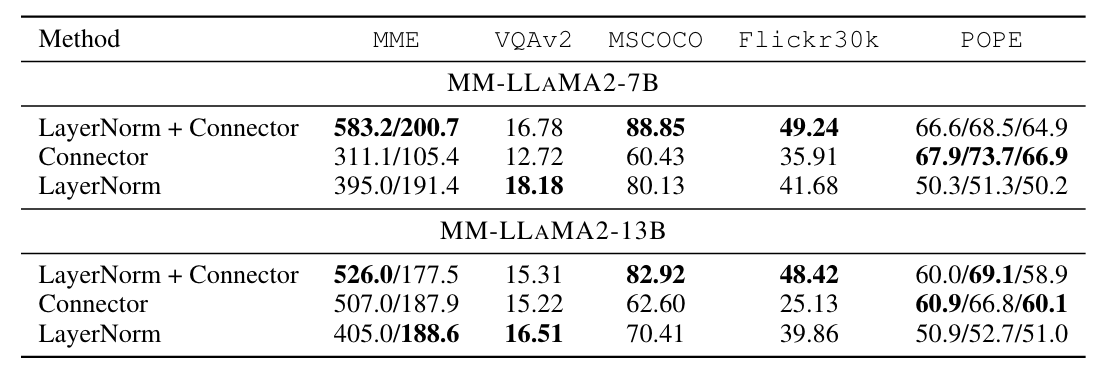
[論文介紹] Tuning LayerNorm in Attention: Towards Efficient Multi-Modal LLM ...

Paper page - ModalPrompt: Towards Efficient Multimodal Continual ...

Paper page - On the Effectiveness of LayerNorm Tuning for Continual ...

Paper page - Retrospective Sparse Attention for Efficient Long-Context ...

Paper page - Hybrid Linear Attention Done Right: Efficient Distillation ...

Paper page - Towards Economical Inference: Enabling DeepSeek's Multi ...

Paper page - Mixture-of-LoRAs: An Efficient Multitask Tuning for Large ...

Paper page - LoRA in LoRA: Towards Parameter-Efficient Architecture ...
Advertisement Space (336x280)

Paper page - HINT: Hypernetwork Instruction Tuning for Efficient Zero ...

Paper page - Efficient Attention: Attention with Linear Complexities

Paper page - TPLA: Tensor Parallel Latent Attention for Efficient ...

Paper page - BurstAttention: An Efficient Distributed Attention ...

Paper page - PockEngine: Sparse and Efficient Fine-tuning in a Pocket

Paper page - Exploring Sparsity for Parameter Efficient Fine Tuning ...

[Literature Review] Contextual Attention Modulation: Towards Efficient ...

Concept Drift Guided LayerNorm Tuning for Efficient Multimodal Metaphor ...

Paper page - LayerNorm: A key component in parameter-efficient fine-tuning

Paper page - ALPS: Attention Localization and Pruning Strategy for ...
Advertisement Space (336x280)

[论文评述] Gradient-guided Attention Map Editing: Towards Efficient ...

Paper page - Token Sparse Attention: Efficient Long-Context Inference ...

Paper page - M^3IT: A Large-Scale Dataset towards Multi-Modal ...

Paper page - You can remove GPT2's LayerNorm by fine-tuning

Paper page - Multi-head Temporal Latent Attention

Paper page - EDGE-LLM: Enabling Efficient Large Language Model ...