
Quantize And Run Industrial Edge Llms At Int4 Precision With Quanto And
Quantize and Run Industrial Edge LLMs at INT4 Precision with Quanto and ...
Quantize and Deploy Industrial LLMs with torchao and ExecuTorch ...
Run Edge LLMs on IoT Devices with Ollama and llama.cpp | Atomic Loops
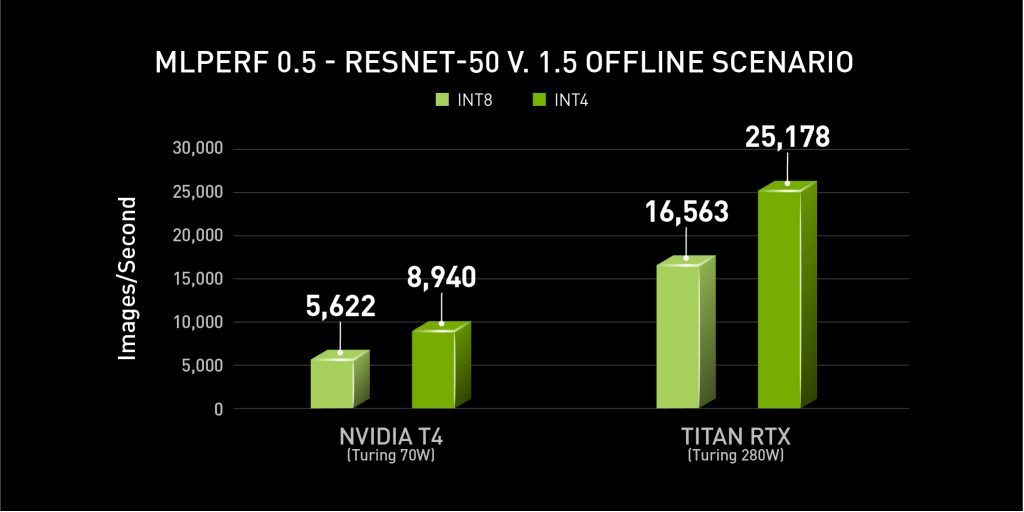
Int4 Precision for AI Inference - Edge AI and Vision Alliance
Fine-Tune Quantized LLMs on Industrial Data with bitsandbytes and TRL ...
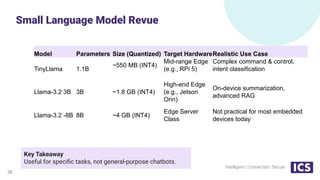
Reality Check Deploying Computer Vision and LLMs at the Edge | PDF
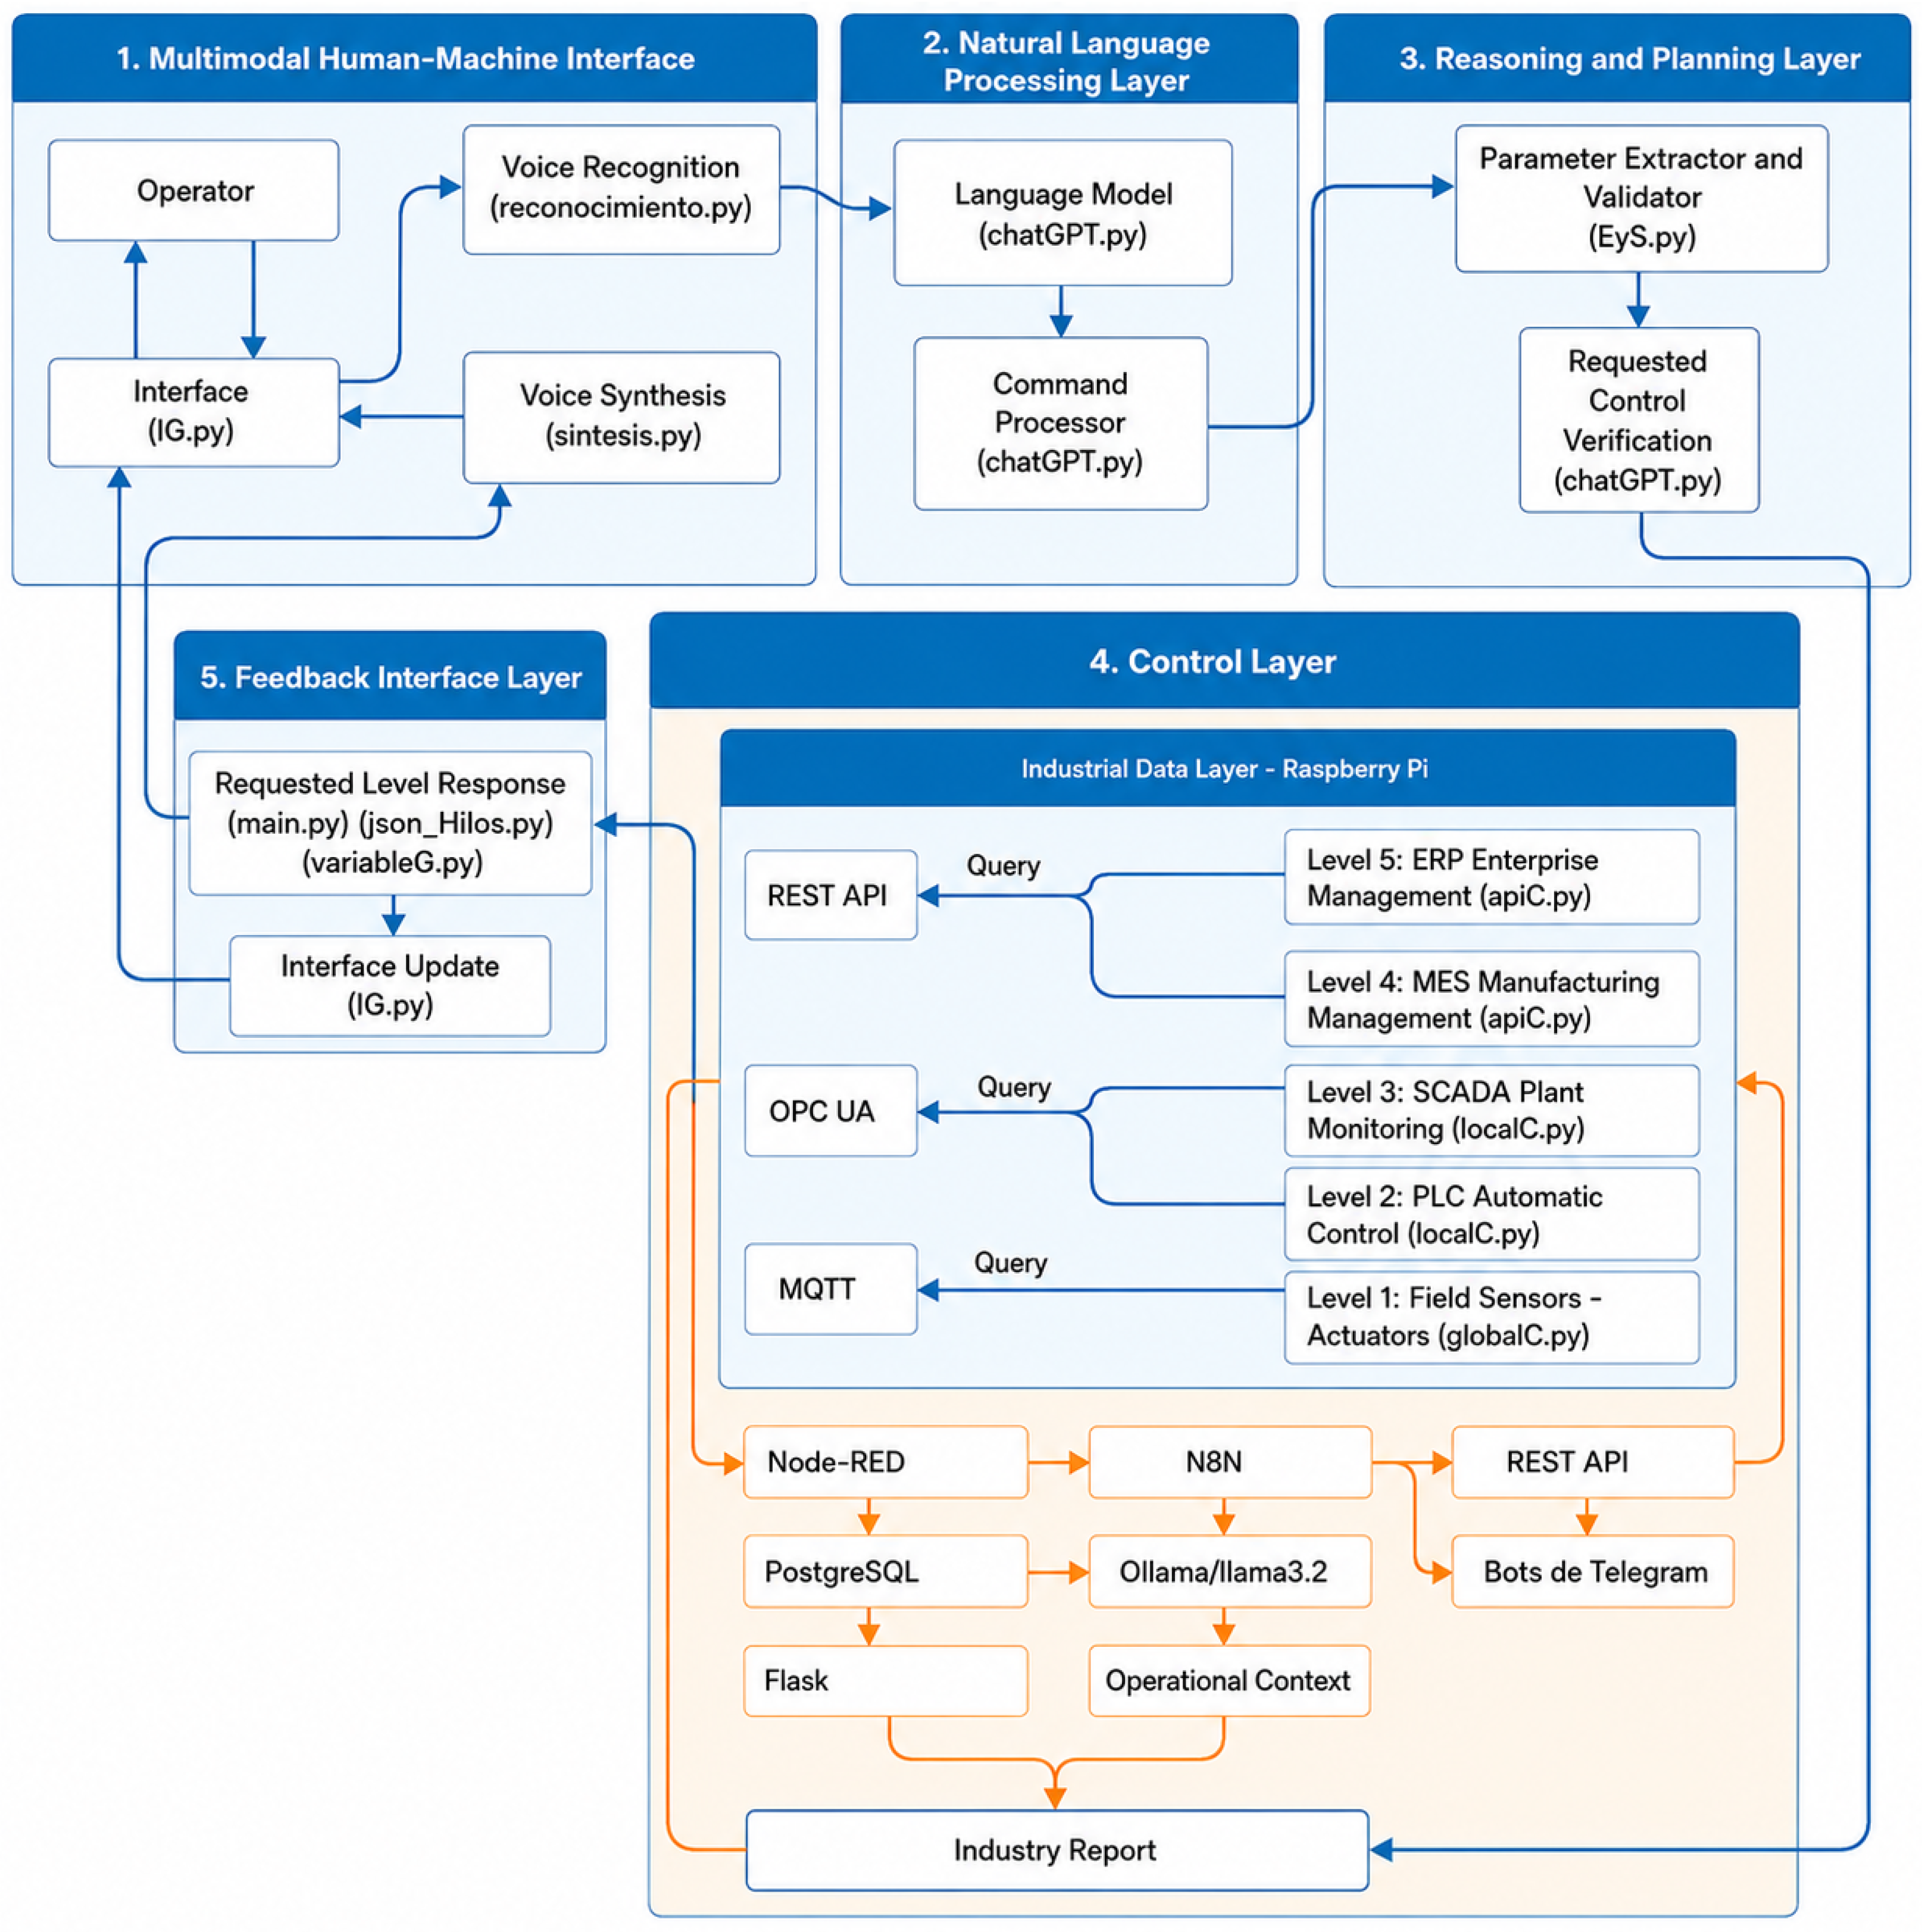
Local LLMs for Industrial Supervision and Control: An Edge AI Event ...

Unlock Local AI: How to Convert and Run Any Transformer Model with INT4 ...
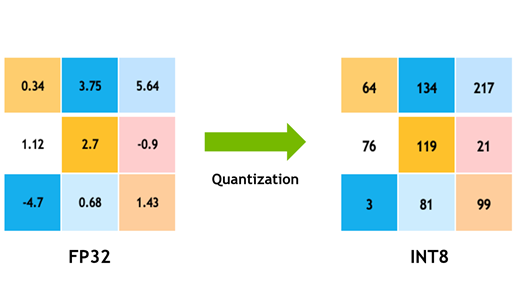
Optimizing LLMs for Performance and Accuracy with Post-Training ...

How LLMs run faster with INT4 quantization | Borys Nadykto posted on ...
Advertisement Space (300x250)
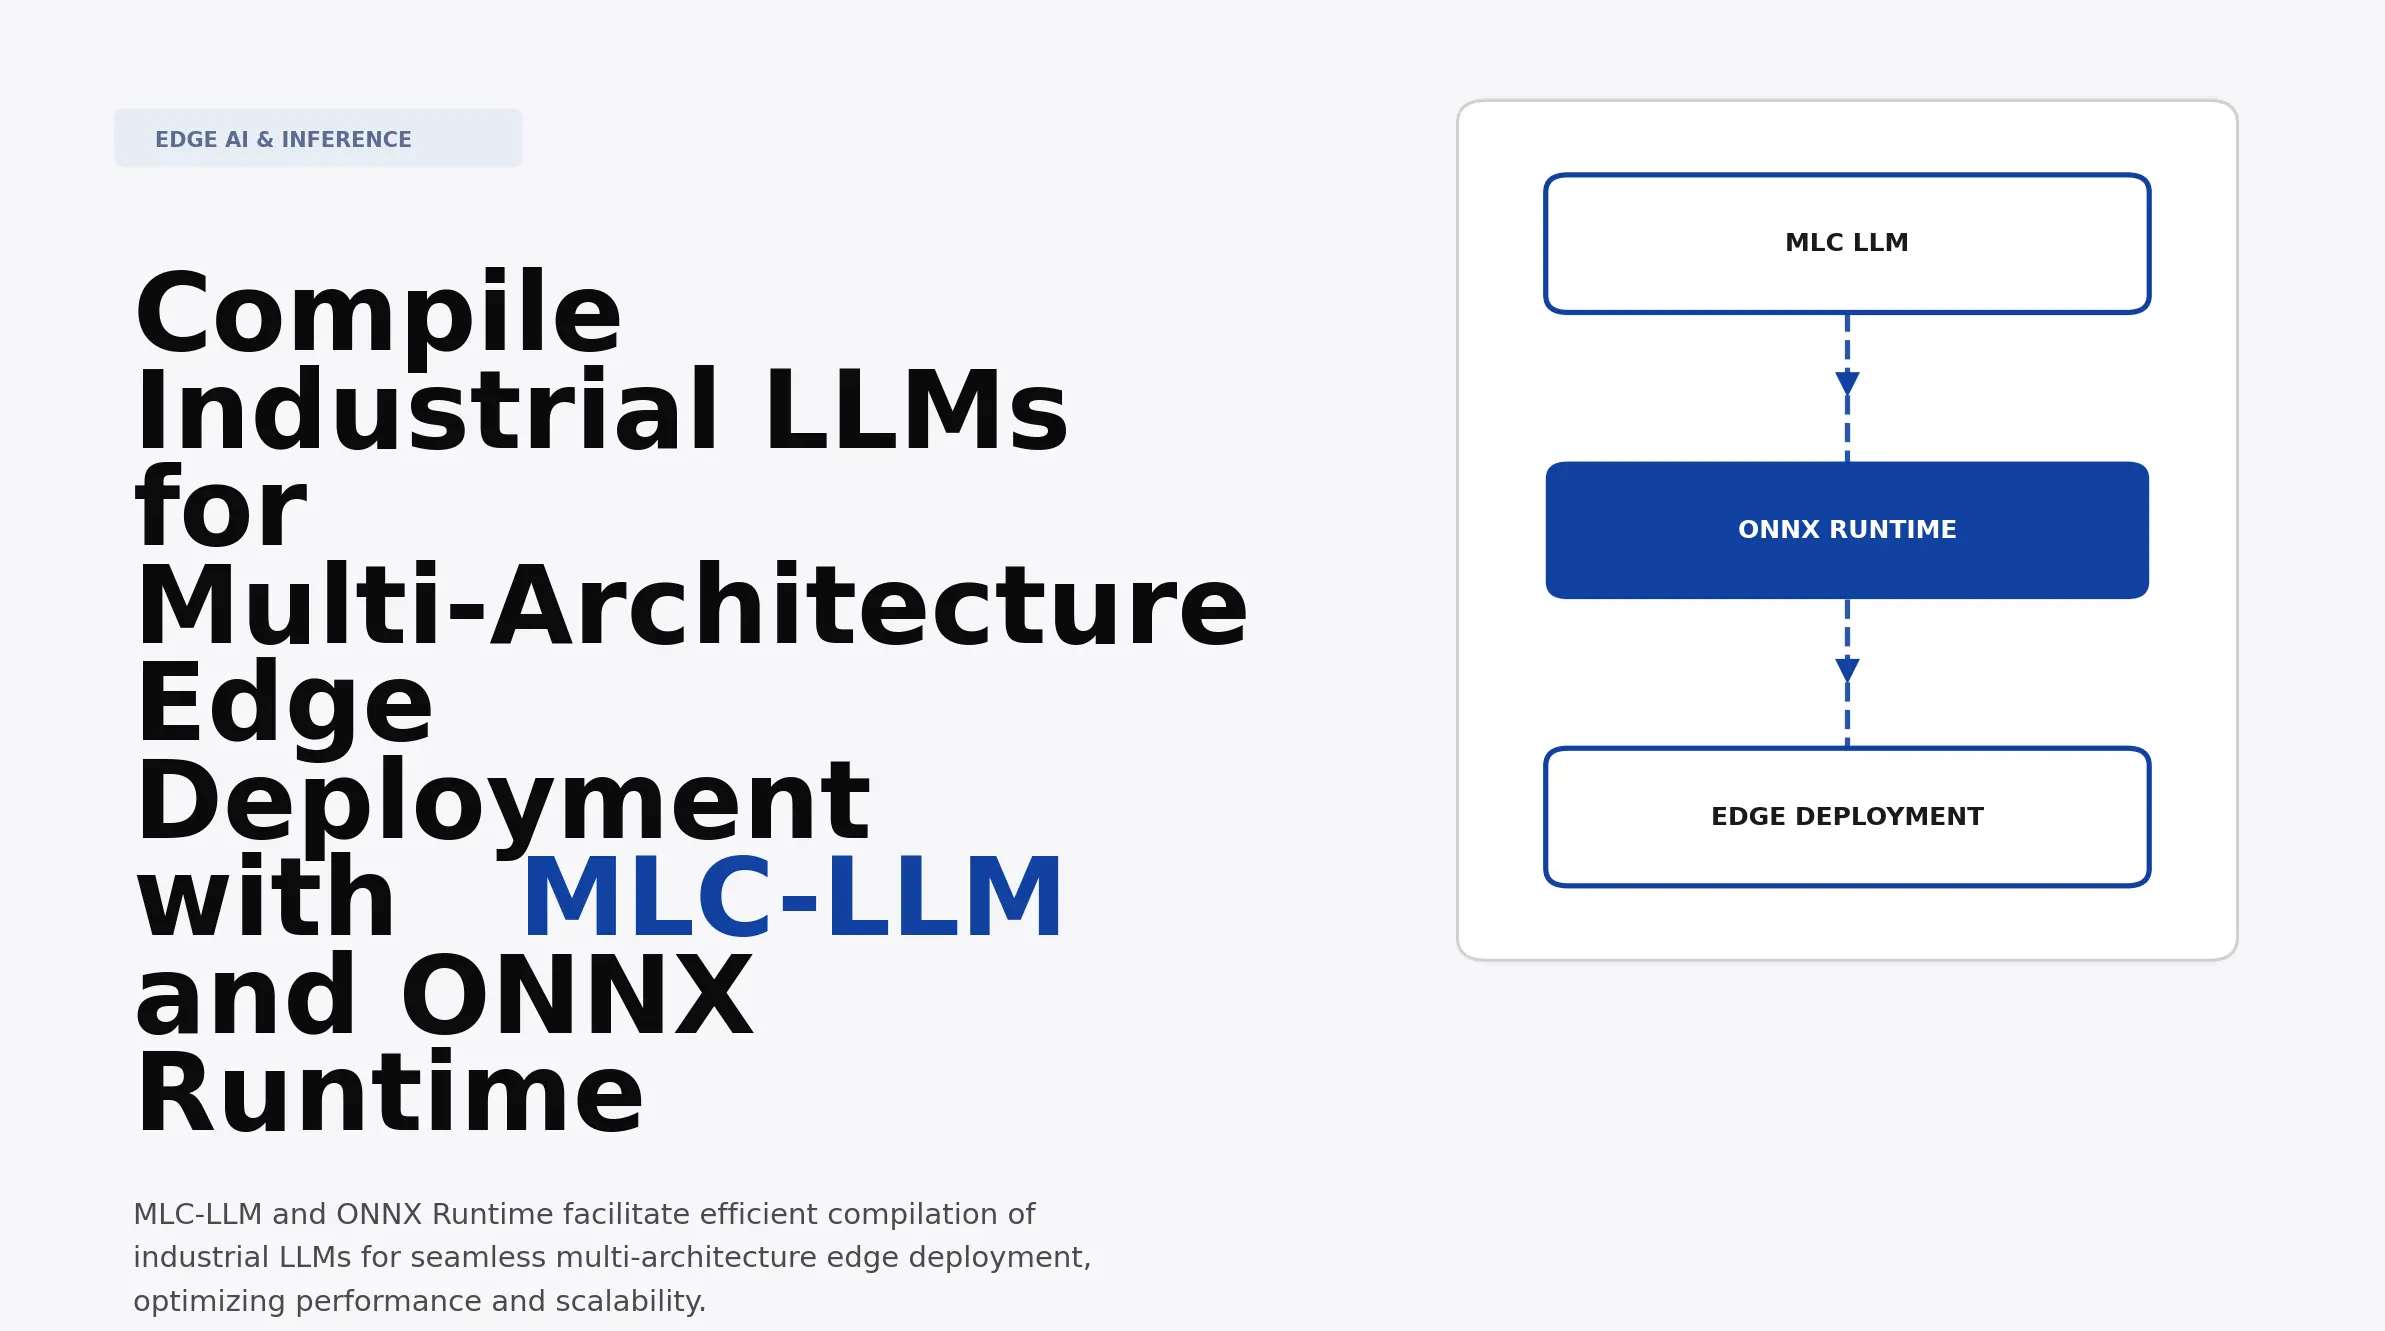
Compile Industrial LLMs for Multi-Architecture Edge Deployment with MLC ...

Optimizing LLMs for Performance and Accuracy with Post-Training ...

Optimizing LLMs for Performance and Accuracy with Post-training ...

Run Big LLMs on Small GPUs: A Hands-On Guide to 4-bit Quantization and ...

Edge AI at Home: Run Local LLMs on Your Windows GPU eBook by CHIA‑HUNG ...

Post-Training Quantization of LLMs with NVIDIA NeMo and NVIDIA TensorRT ...
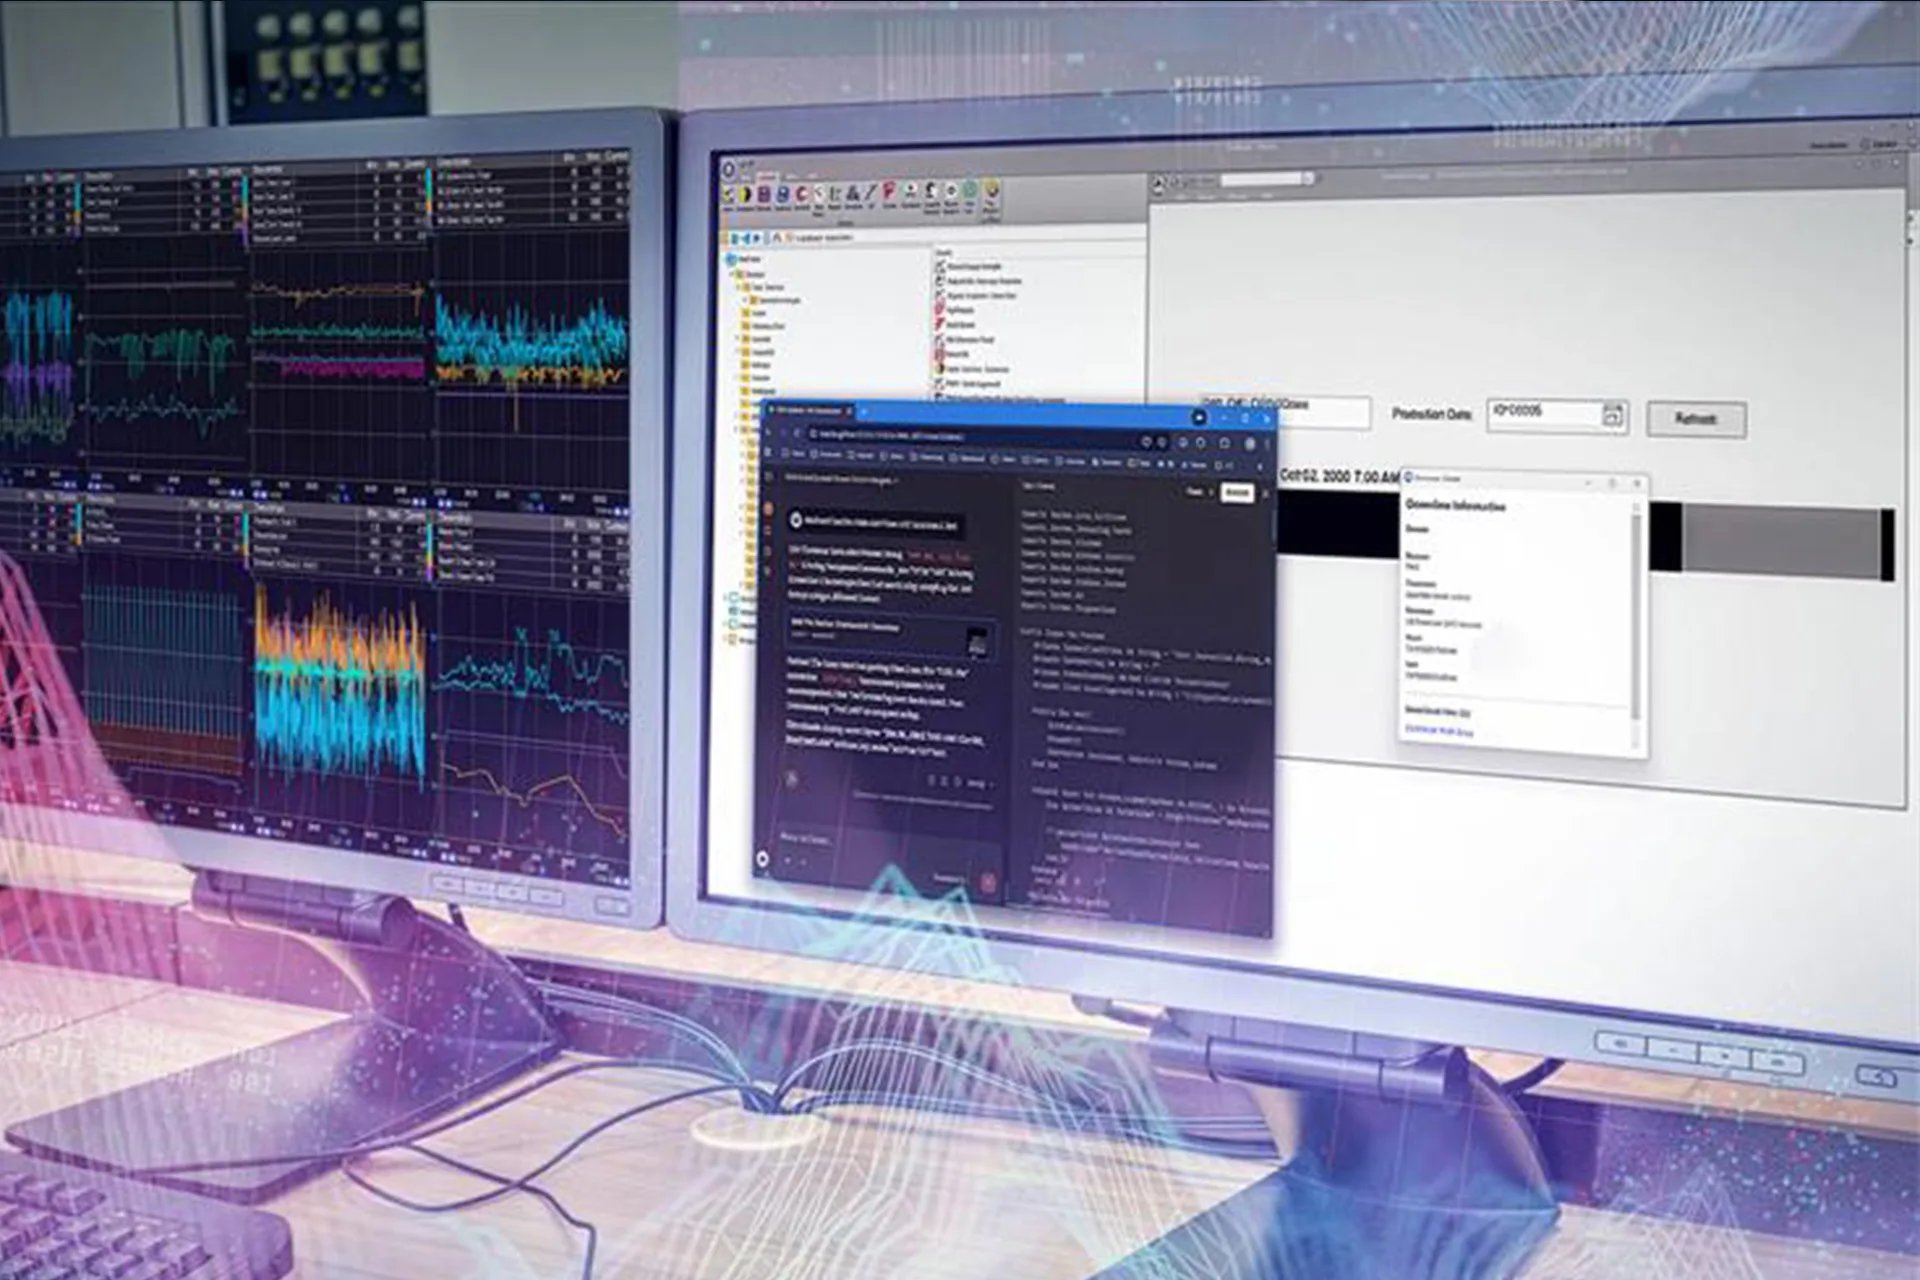
LLMs Are Transforming Industrial Data Visualization and Automation ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

UniQL: Unified Quantization and Low-rank Compression for Adaptive Edge ...
Automatically Quantize LLMs with AutoRound | Intel Software - YouTube
Advertisement Space (336x280)
LLMs and quantization explained
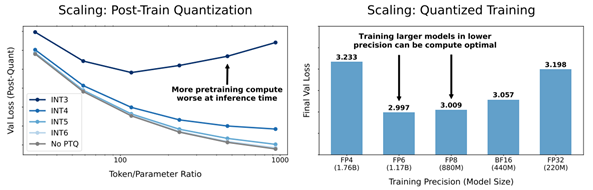
OpenVINO™ Blog | Q4'24: Technology Update – Low Precision and Model ...

How to run LLMs on your laptop with quantization | Maxym Muzychenko ...

Running LLMs on Raspberry Pi and Microcontrollers | AI Tutorial | Next ...
EP 226 - Neuromorphic for LLMs on the Edge - Industrial IoT Spotlight ...

INT4 Quantization: Group-wise Methods & NF4 Format for LLMs ...
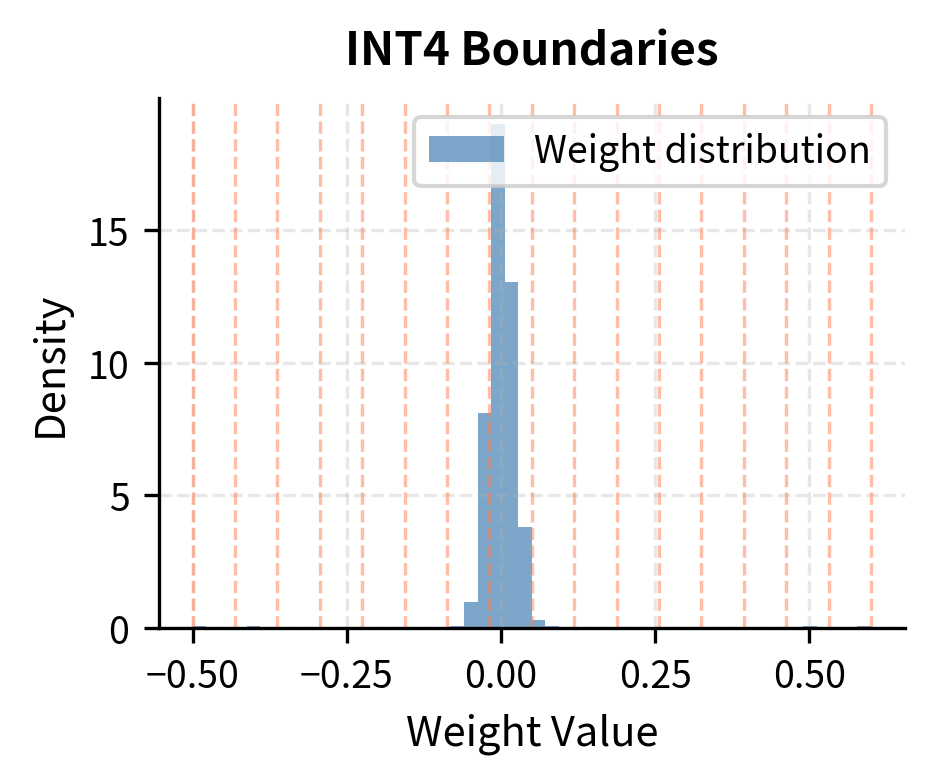
INT4 Quantization: Group-wise Methods & NF4 Format for LLMs ...

INT4 Quantization: Group-wise Methods & NF4 Format for LLMs ...

Quantization is what you should understand if you want to run LLMs in ...
Model Memory Requirements Explained: How FP32, FP16, BF16, INT8, and ...
Advertisement Space (336x280)
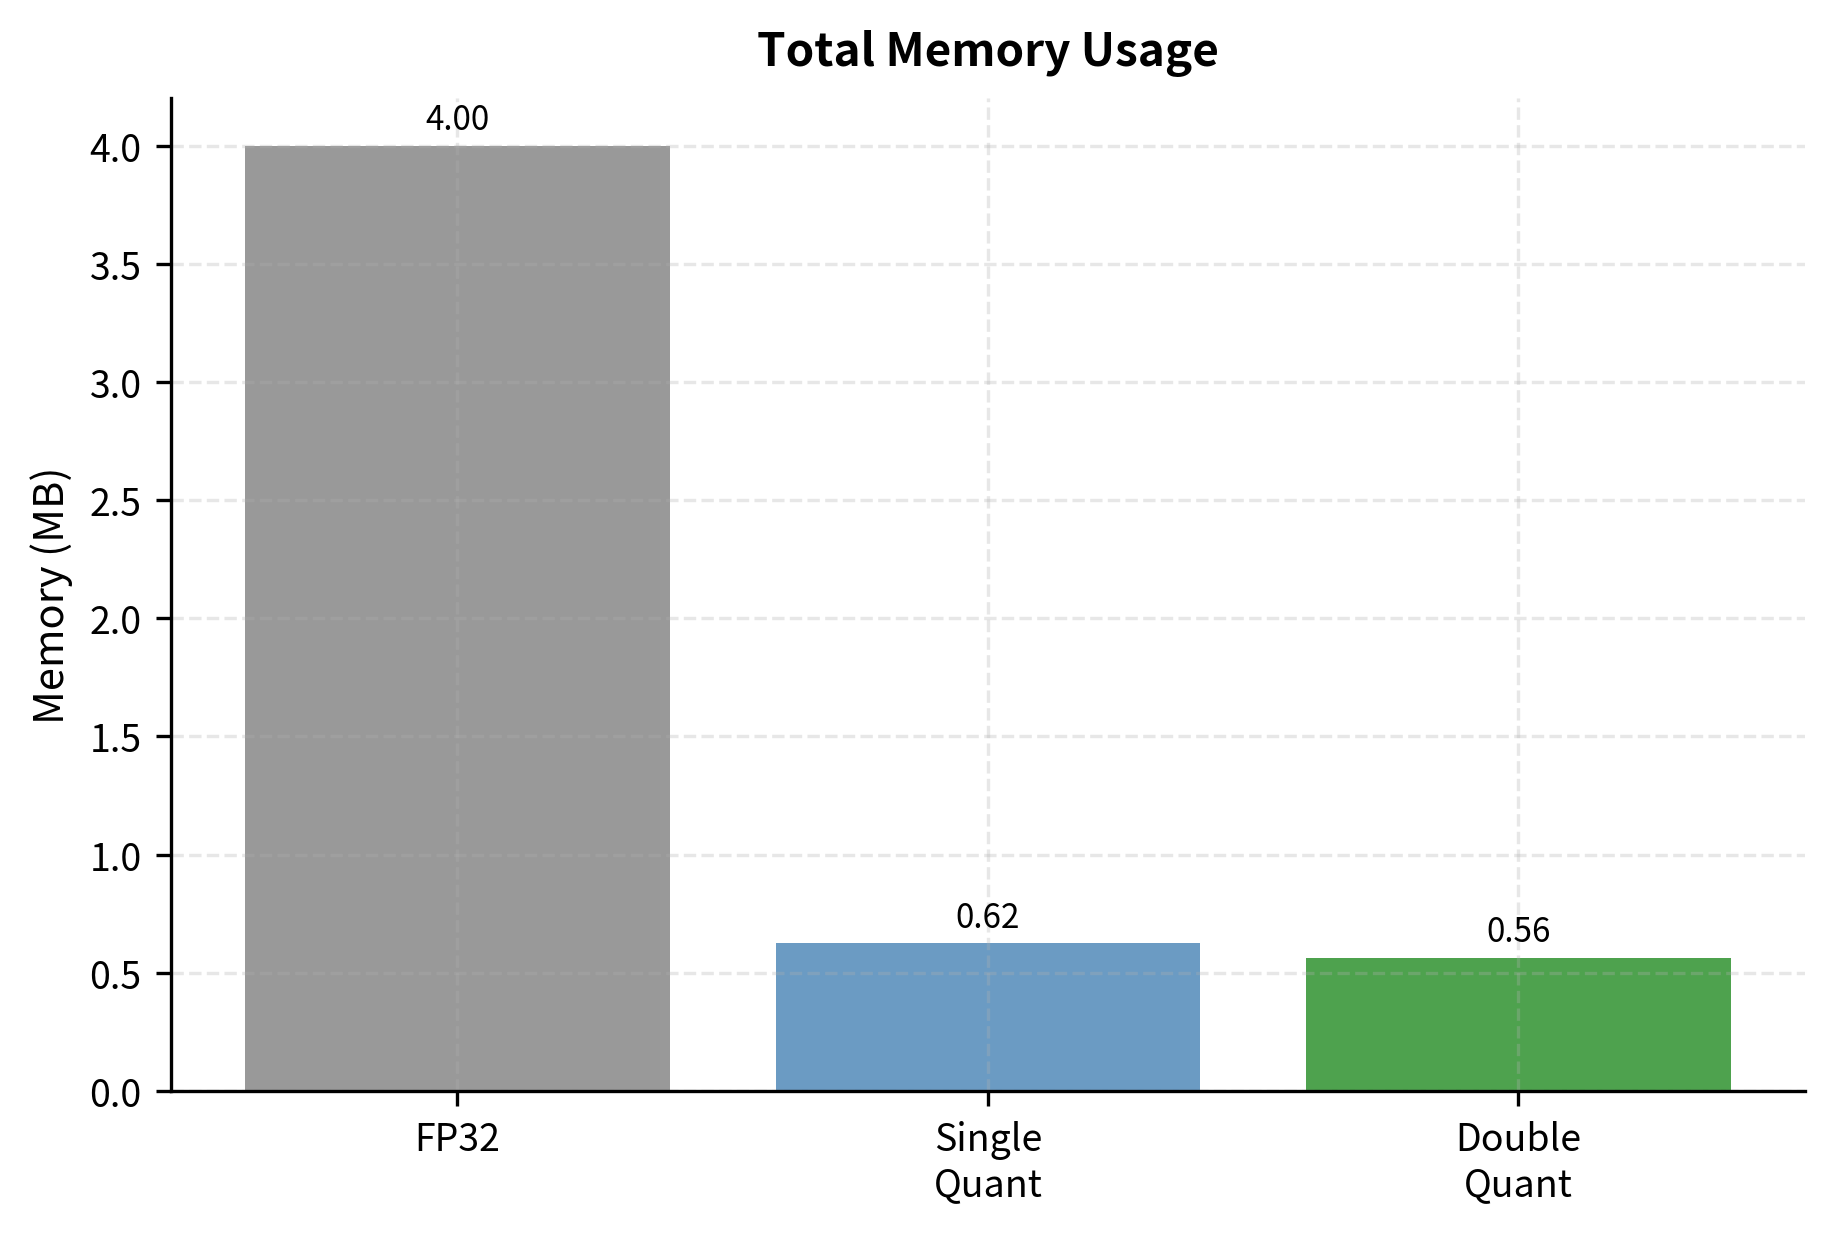
INT4 Quantization: Group-wise Methods & NF4 Format for LLMs ...
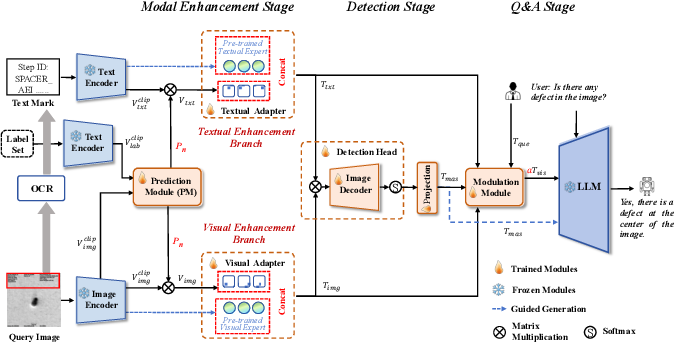
Figure 2 from Deploying Edge LLMs for Wafer Defect Detection in Chip ...

Liquid AI Open-Sources LFM2: A New Generation of Edge LLMs - MarkTechPost

Advantech Supercharges Open-Source LLMs with a F - Advantech

INT4 Quantization: Group-wise Methods & NF4 Format for LLMs ...

Paper page - UniQL: Unified Quantization and Low-rank Compression for ...