
Deploy Moe Models With Expert Parallelism And Prefill Decode Separation

Deploy MoE models with expert parallelism and Prefill-Decode separation ...

Deploy MoE models with expert parallelism and Prefill-Decode separation ...

Deploy MoE models with expert parallelism and Prefill-Decode separation ...

Deploy MoE models with expert parallelism and Prefill-Decode separation ...

Deploy MoE models with expert parallelism and Prefill-Decode separation ...

Deploy MoE models with expert parallelism and Prefill-Decode separation ...

Deploy MoE models with expert parallelism and Prefill-Decode separation ...

Deploy MoE models with expert parallelism and Prefill-Decode separation ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...
Advertisement Space (300x250)

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...
MoE models over a distributed setup with Expert Parallelism. | Download ...

Deploy MoE models menggunakan paralelisme ahli dan pemisahan Prefill ...
Speculative Decoding for MoE Models on GPU Cloud: Expert Parallelism ...

Deploy MoE models menggunakan paralelisme ahli dan pemisahan Prefill ...
Integrating Expert and Data Parallelism in MoE
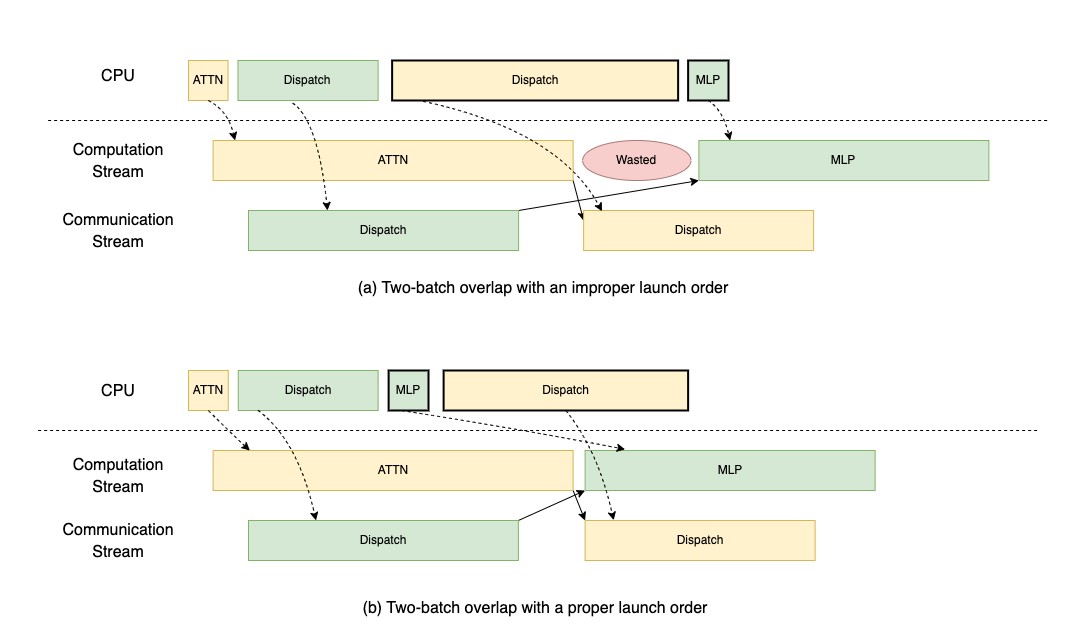
Deploying DeepSeek with PD Disaggregation and Large-Scale Expert ...
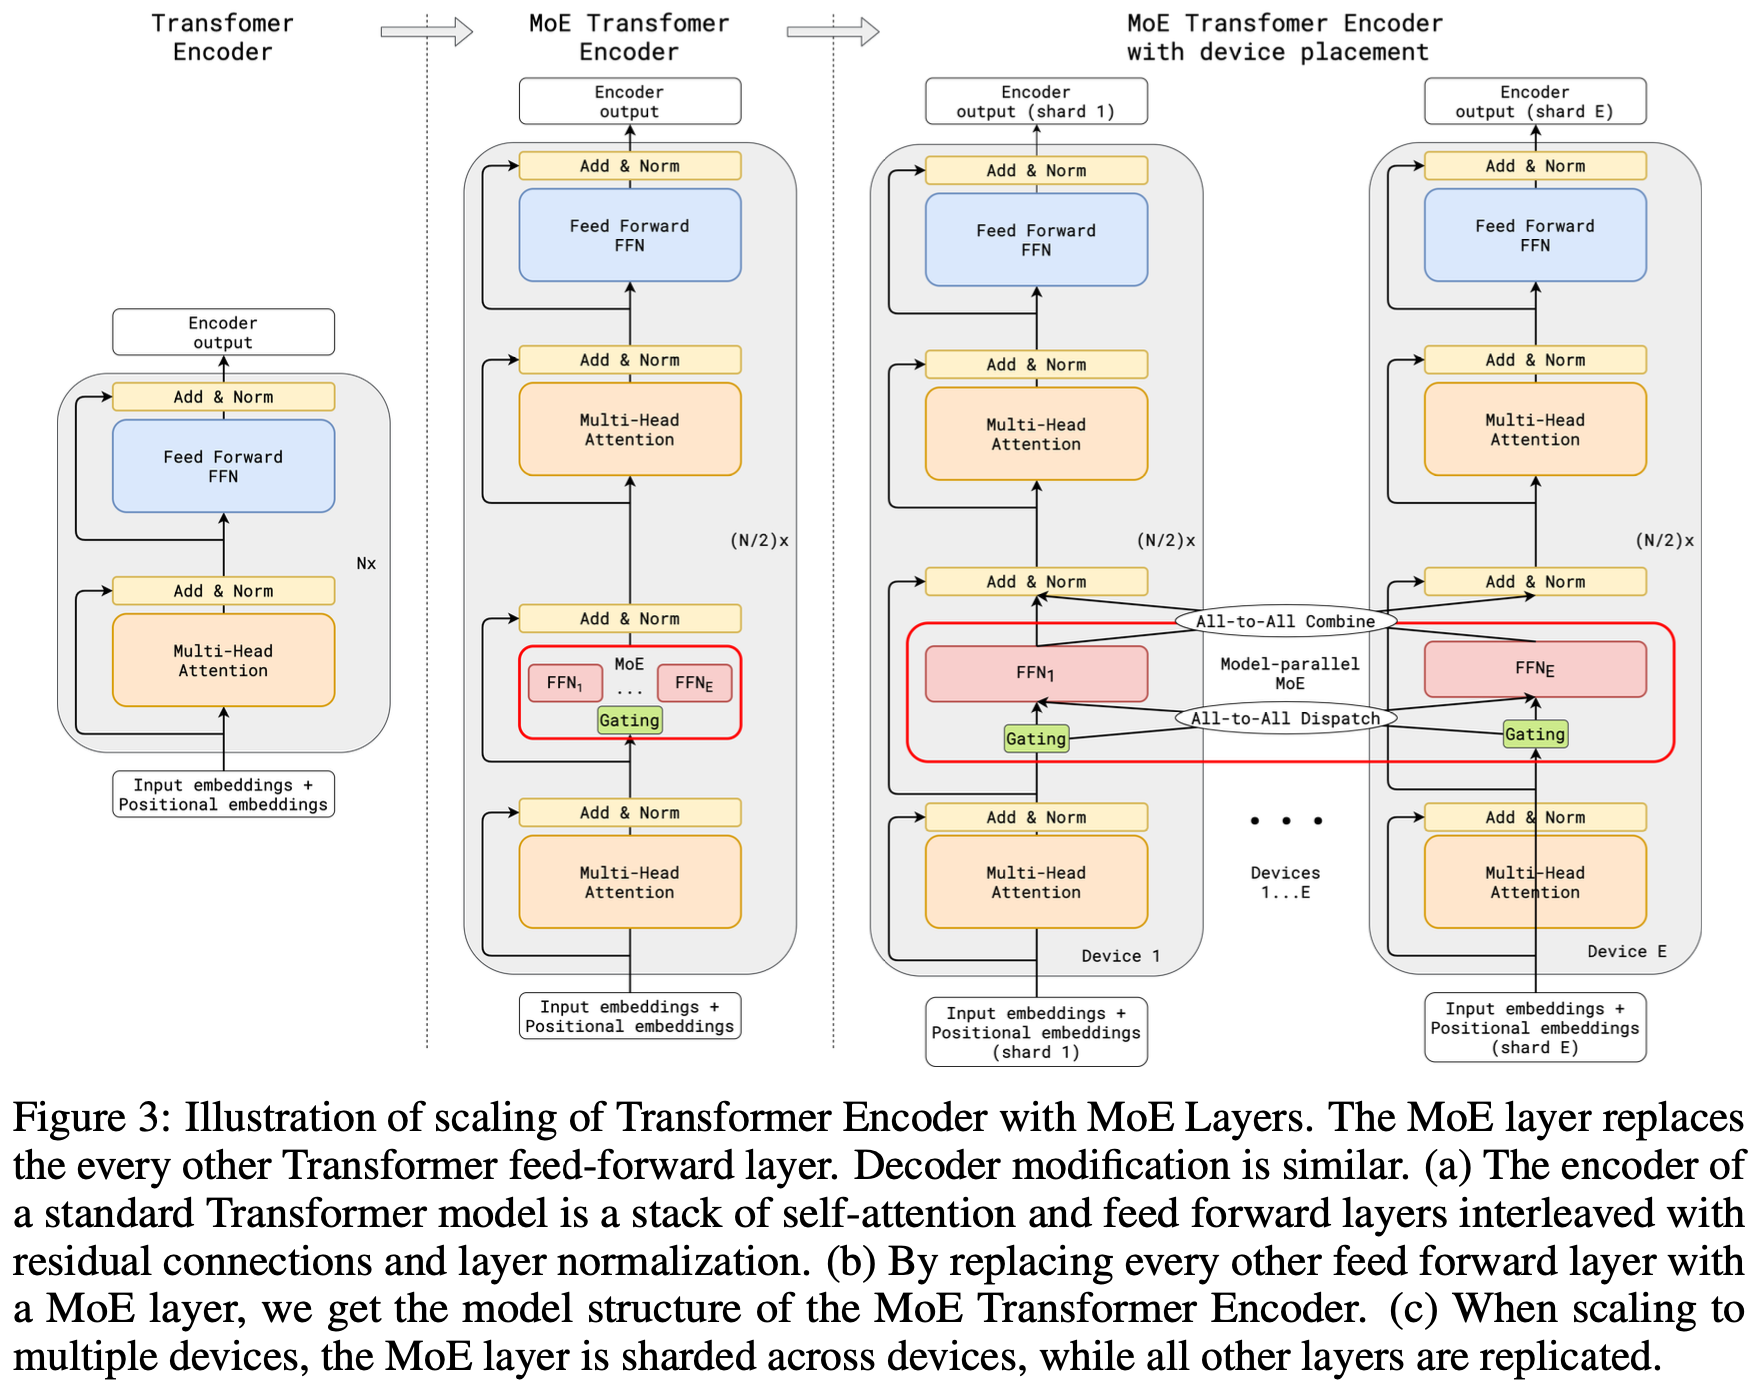
Distributed Mixture-of-Experts and Expert Parallelism | Bruno Magalhaes
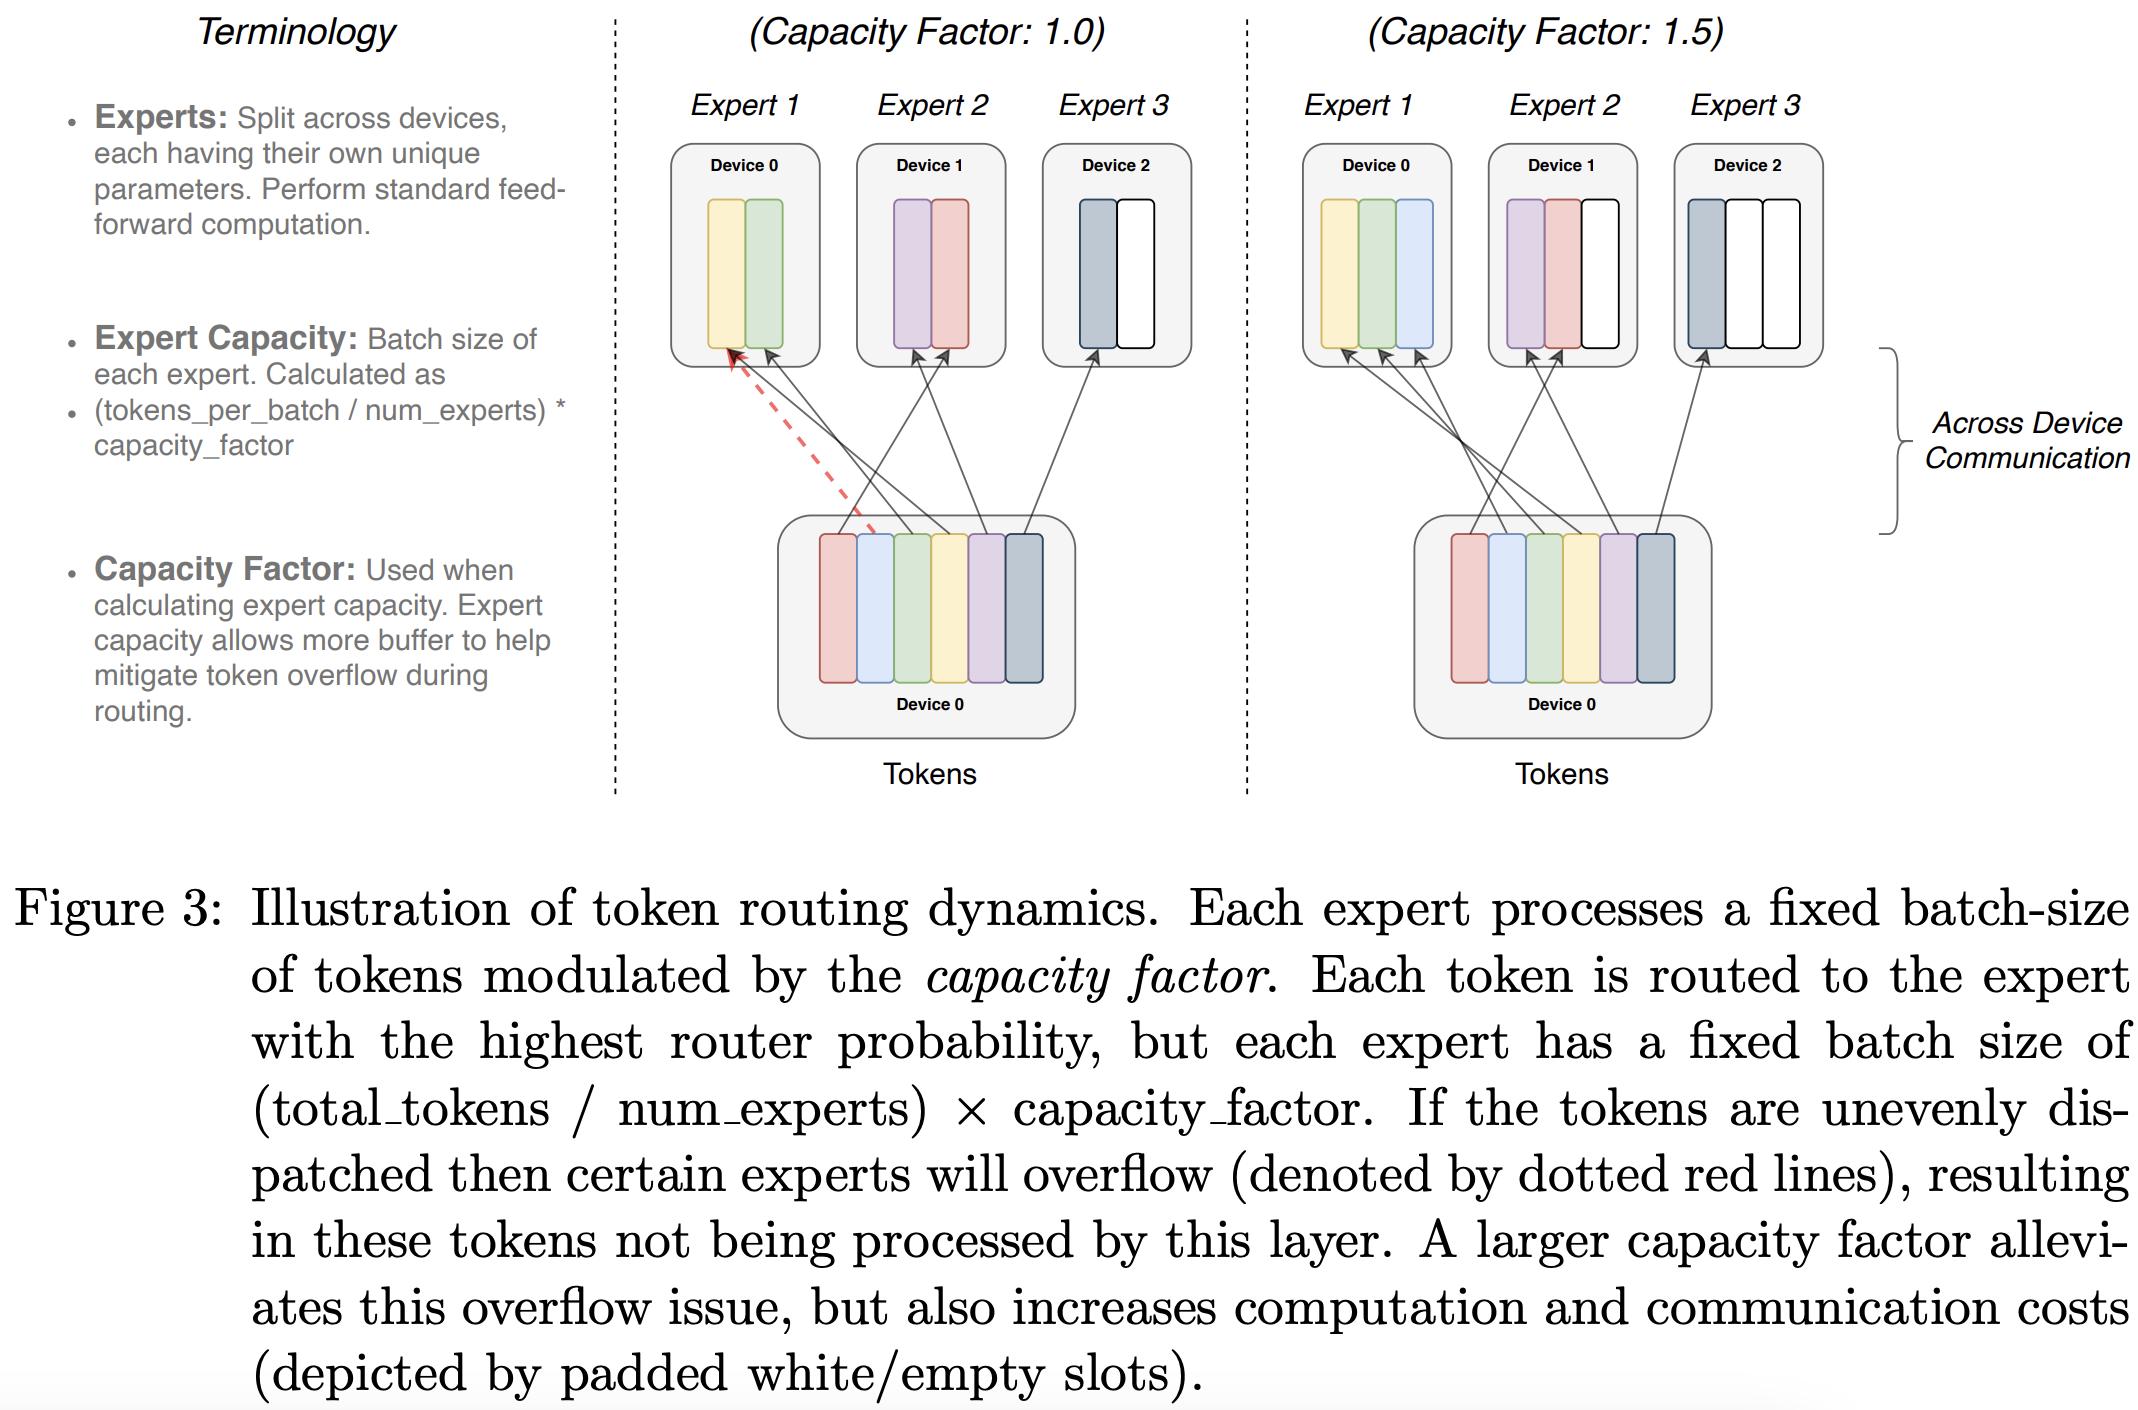
Distributed Mixture-of-Experts and Expert Parallelism | Bruno Magalhaes
Advertisement Space (336x280)

Figure 4 from MPMoE: Memory Efficient MoE for Pre-Trained Models With ...
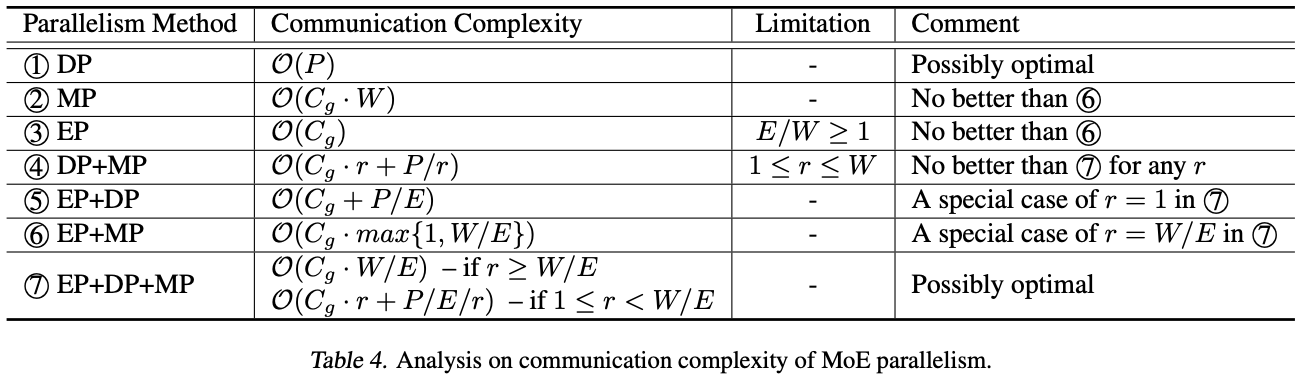
Distributed Mixture-of-Experts and Expert Parallelism | Bruno Magalhaes
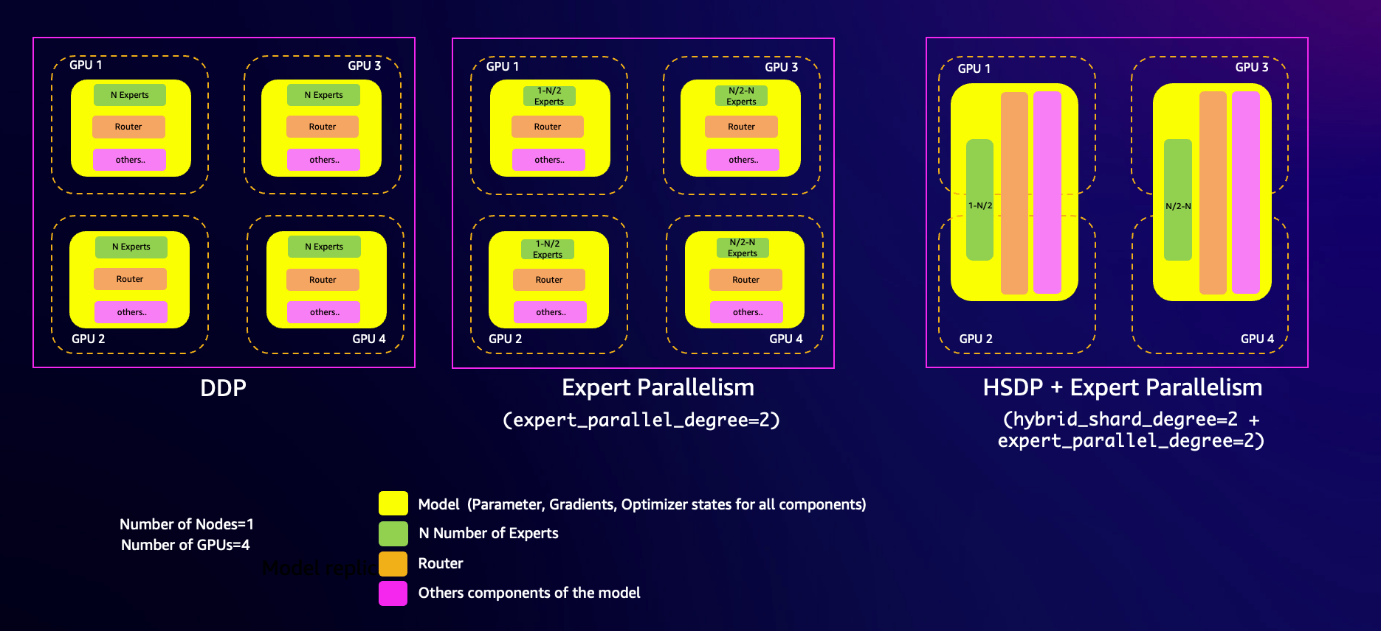
Tuto Startup - Accelerate Mixtral 8x7B pre-training with expert parallelism
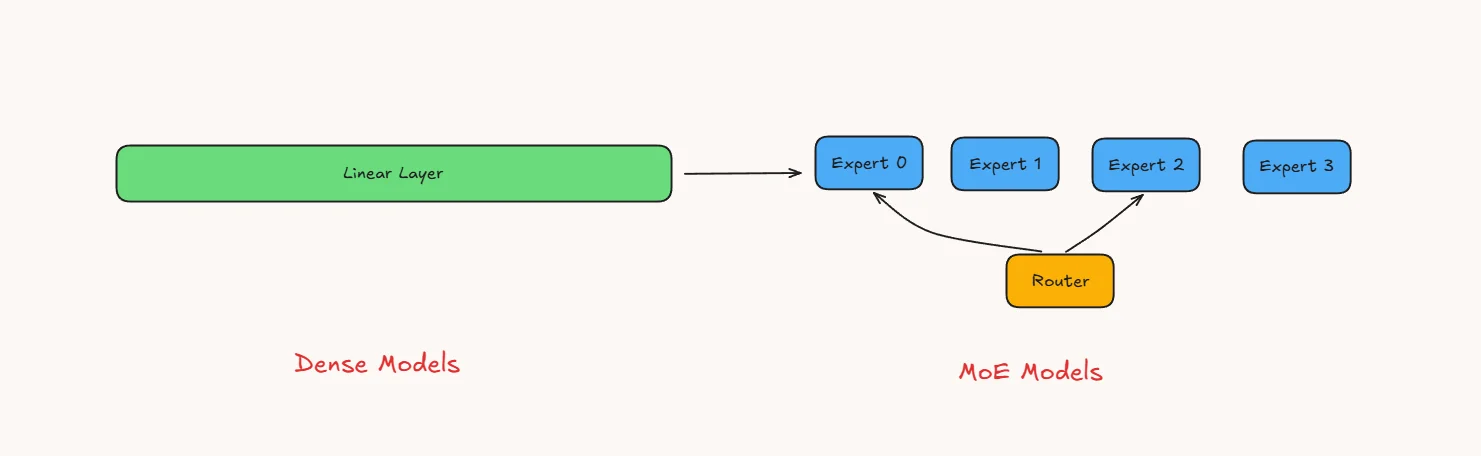
Expert Parallelism and Mixed Parallelism Strategies in vLLM | Jarvis ...
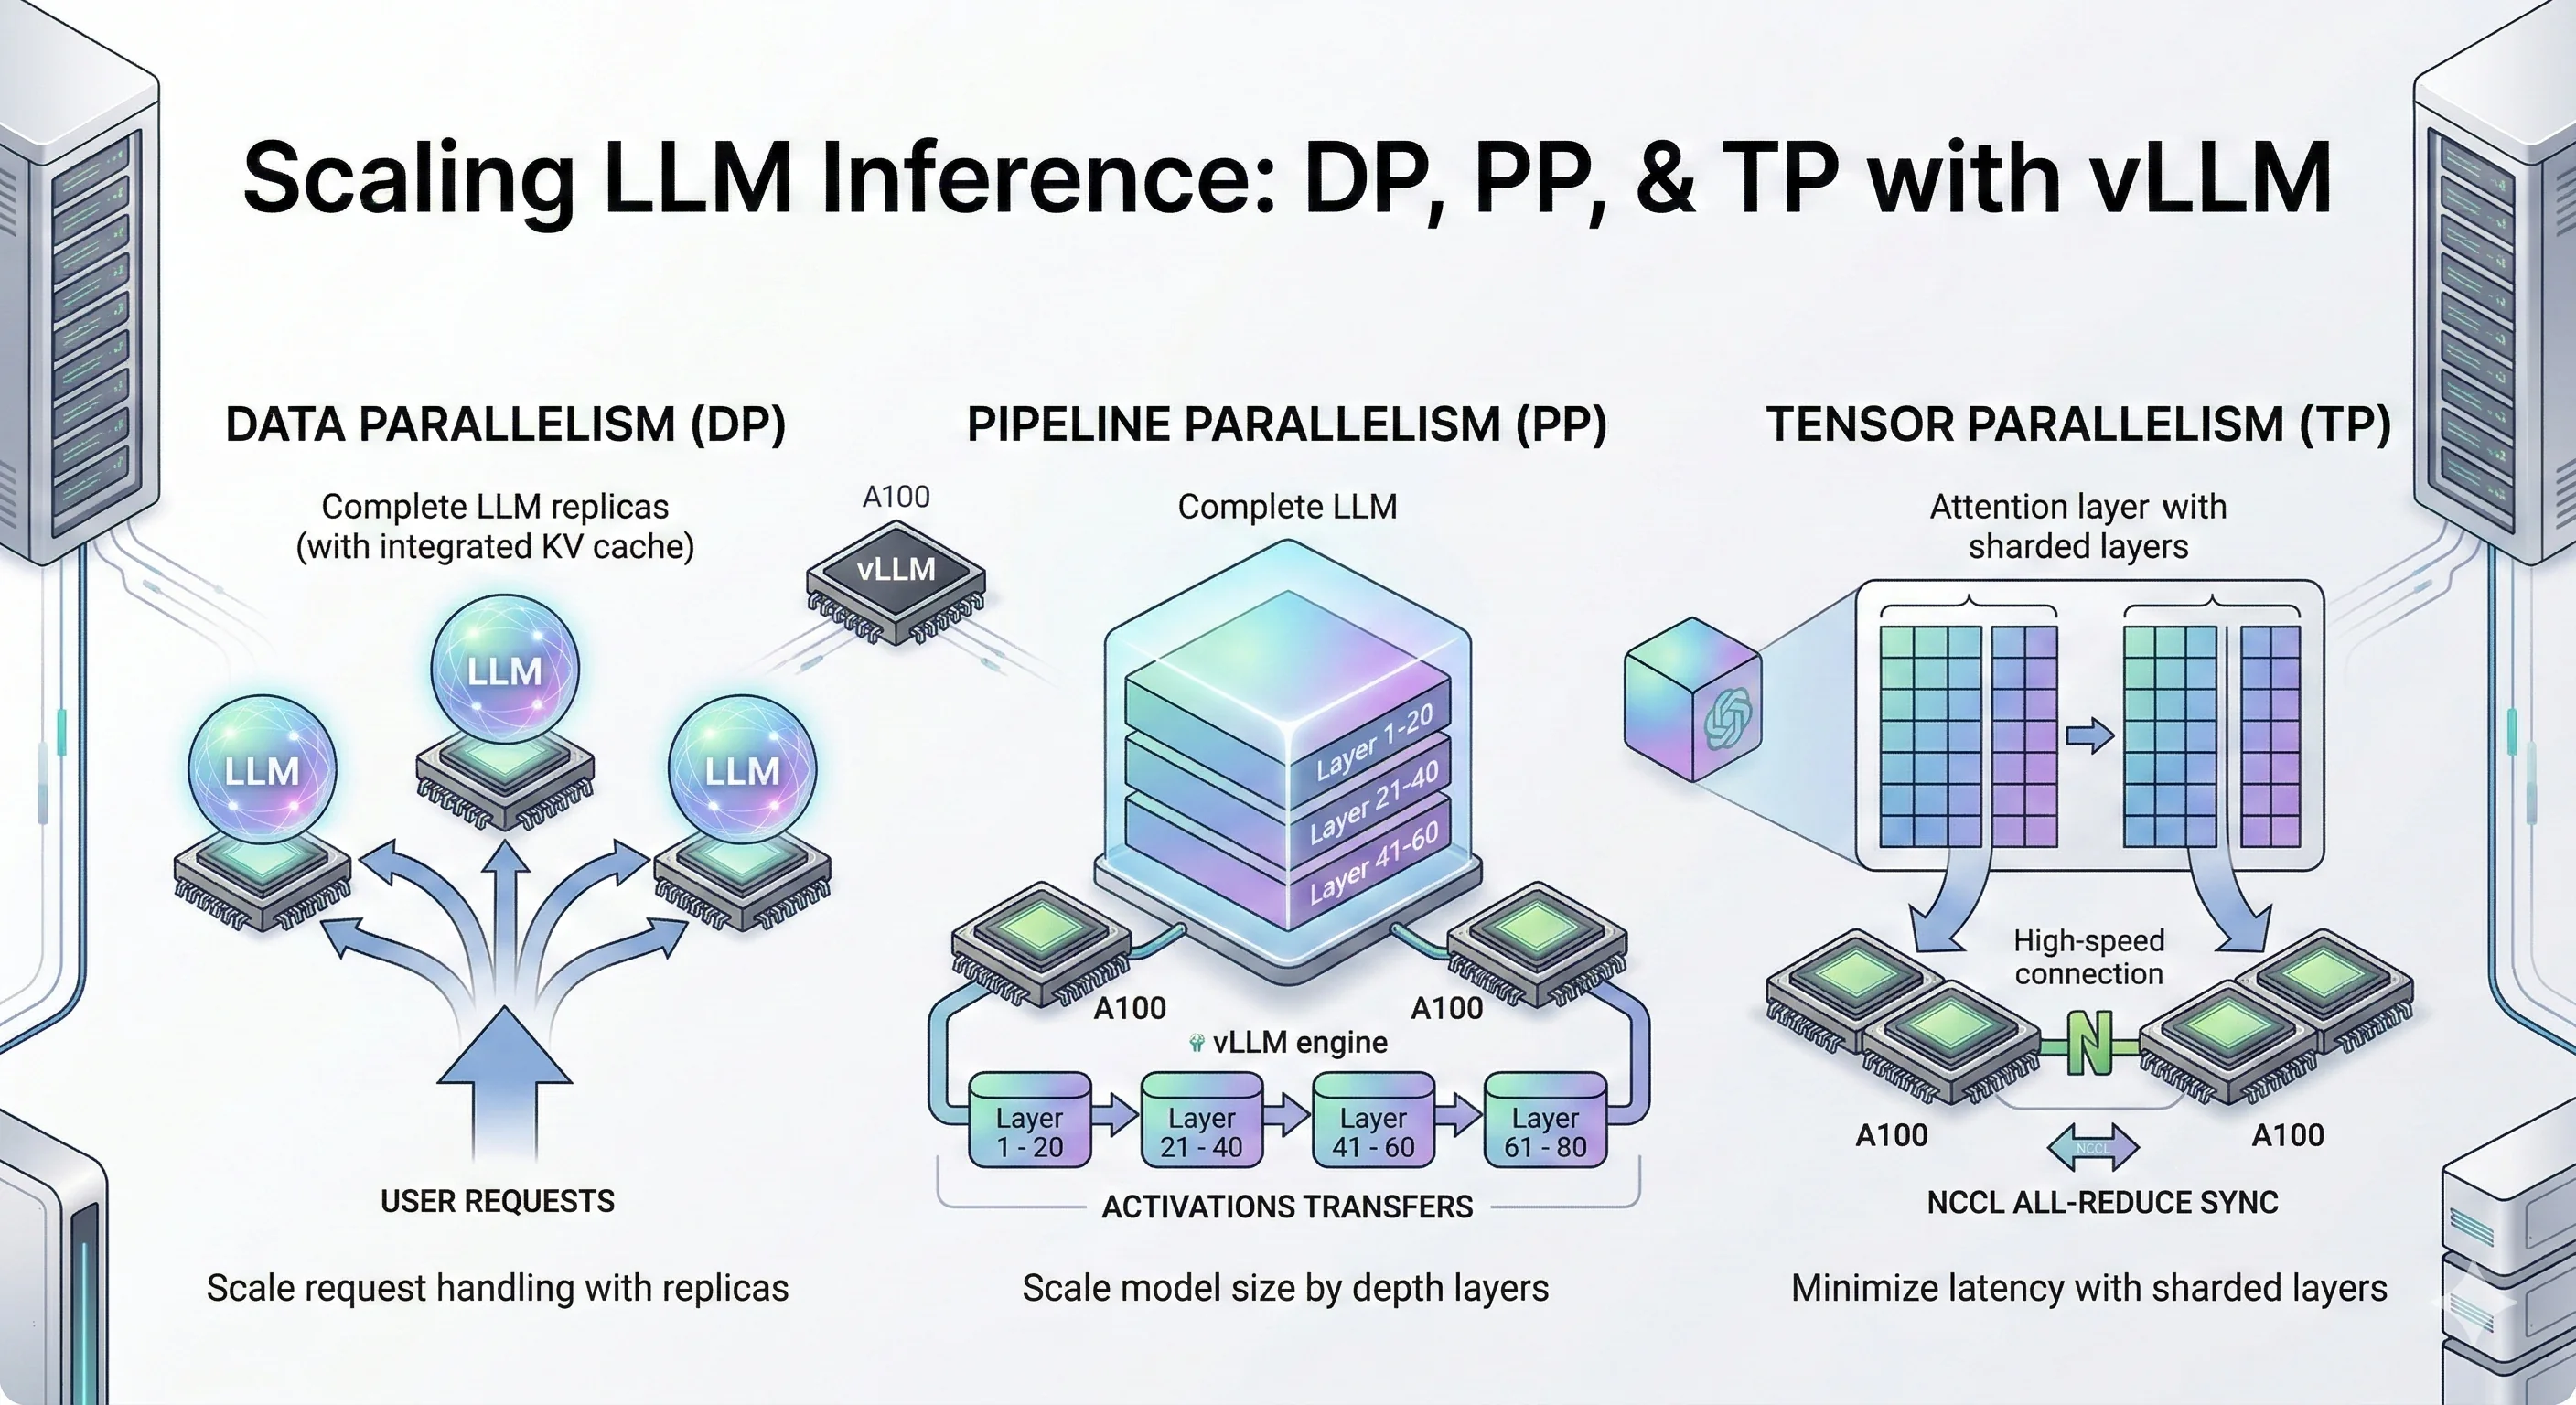
Expert Parallelism and Mixed Parallelism Strategies in vLLM | Jarvis ...
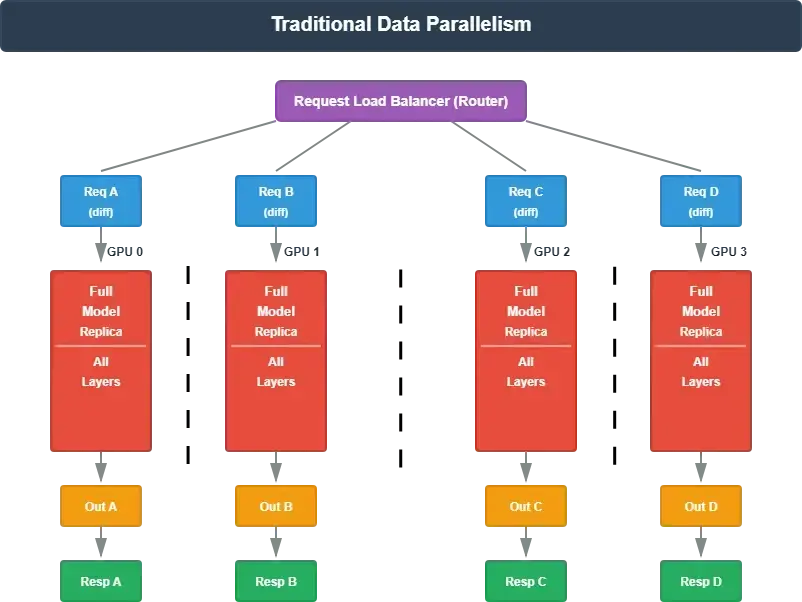
vLLM MoE 调优手册(上篇):TP、DP、PP 与 Expert Parallelism 实战指南 - 知乎
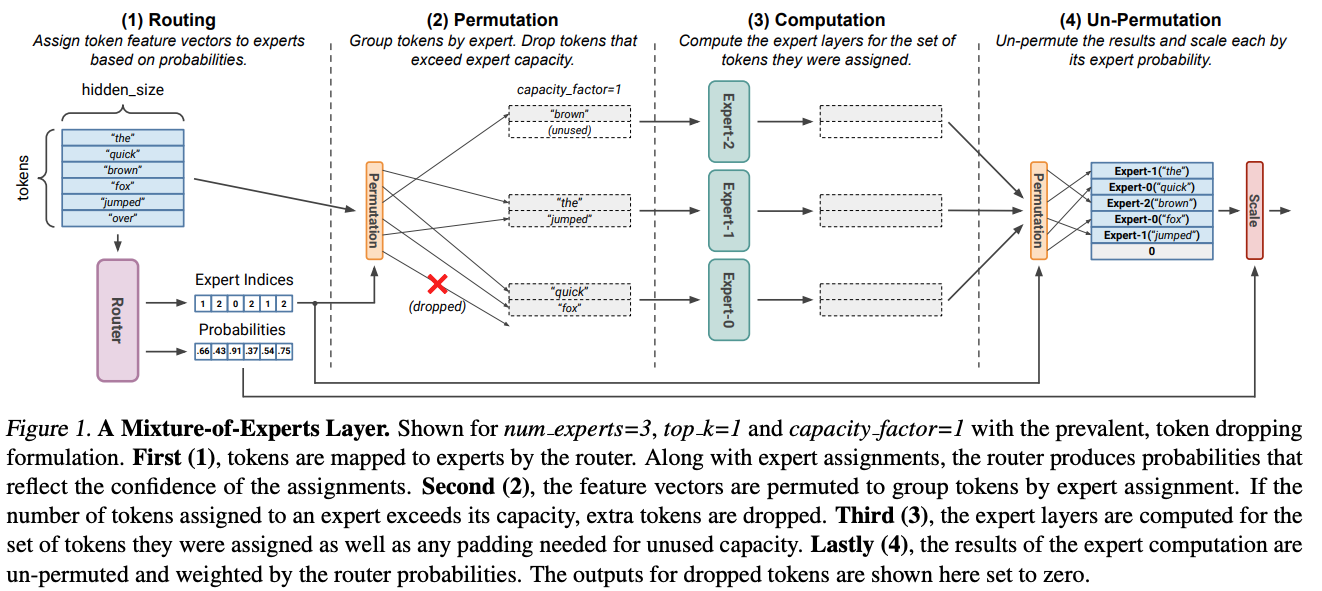
Distributed Mixture-of-Experts and Expert Parallelism | Bruno Magalhaes
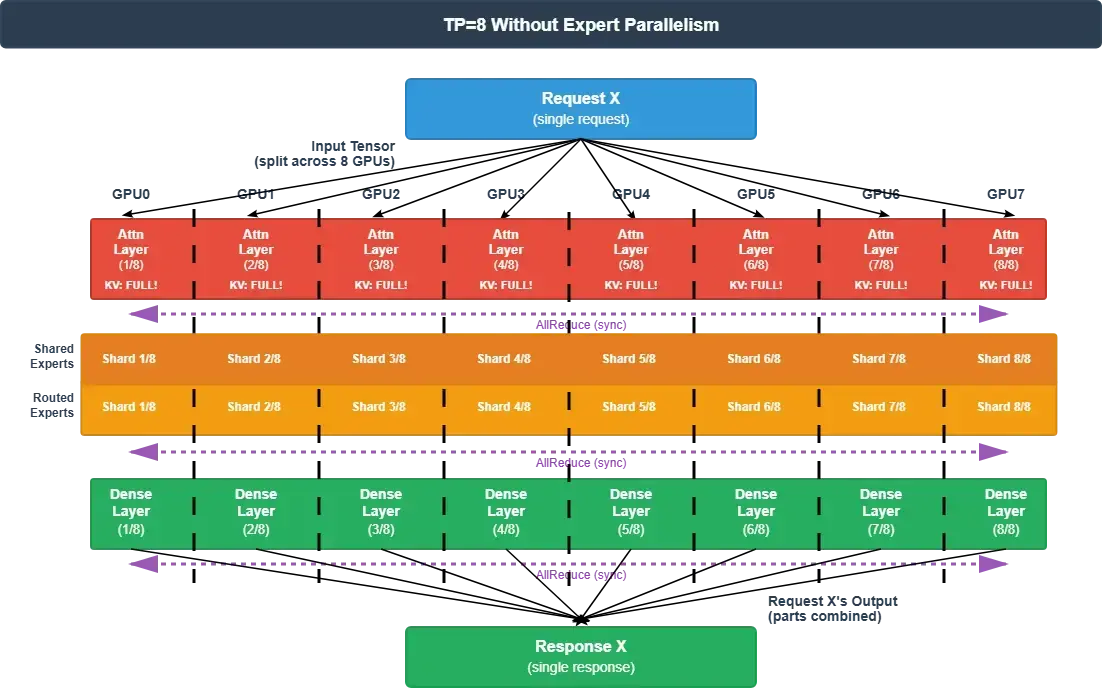
vLLM MoE 调优手册(下篇):TP、DP、PP 与 Expert Parallelism 实战指南 - 知乎

在 NVL72 机架级系统上使用 Wide Expert Parallelism 扩展大型 MoE 模型 - NVIDIA 技术博客
MoE Post-Training Guide: Load Balancing, Routing Replay, and Expert ...
Advertisement Space (336x280)

Fast Inference of MoE Language Models with Offloading
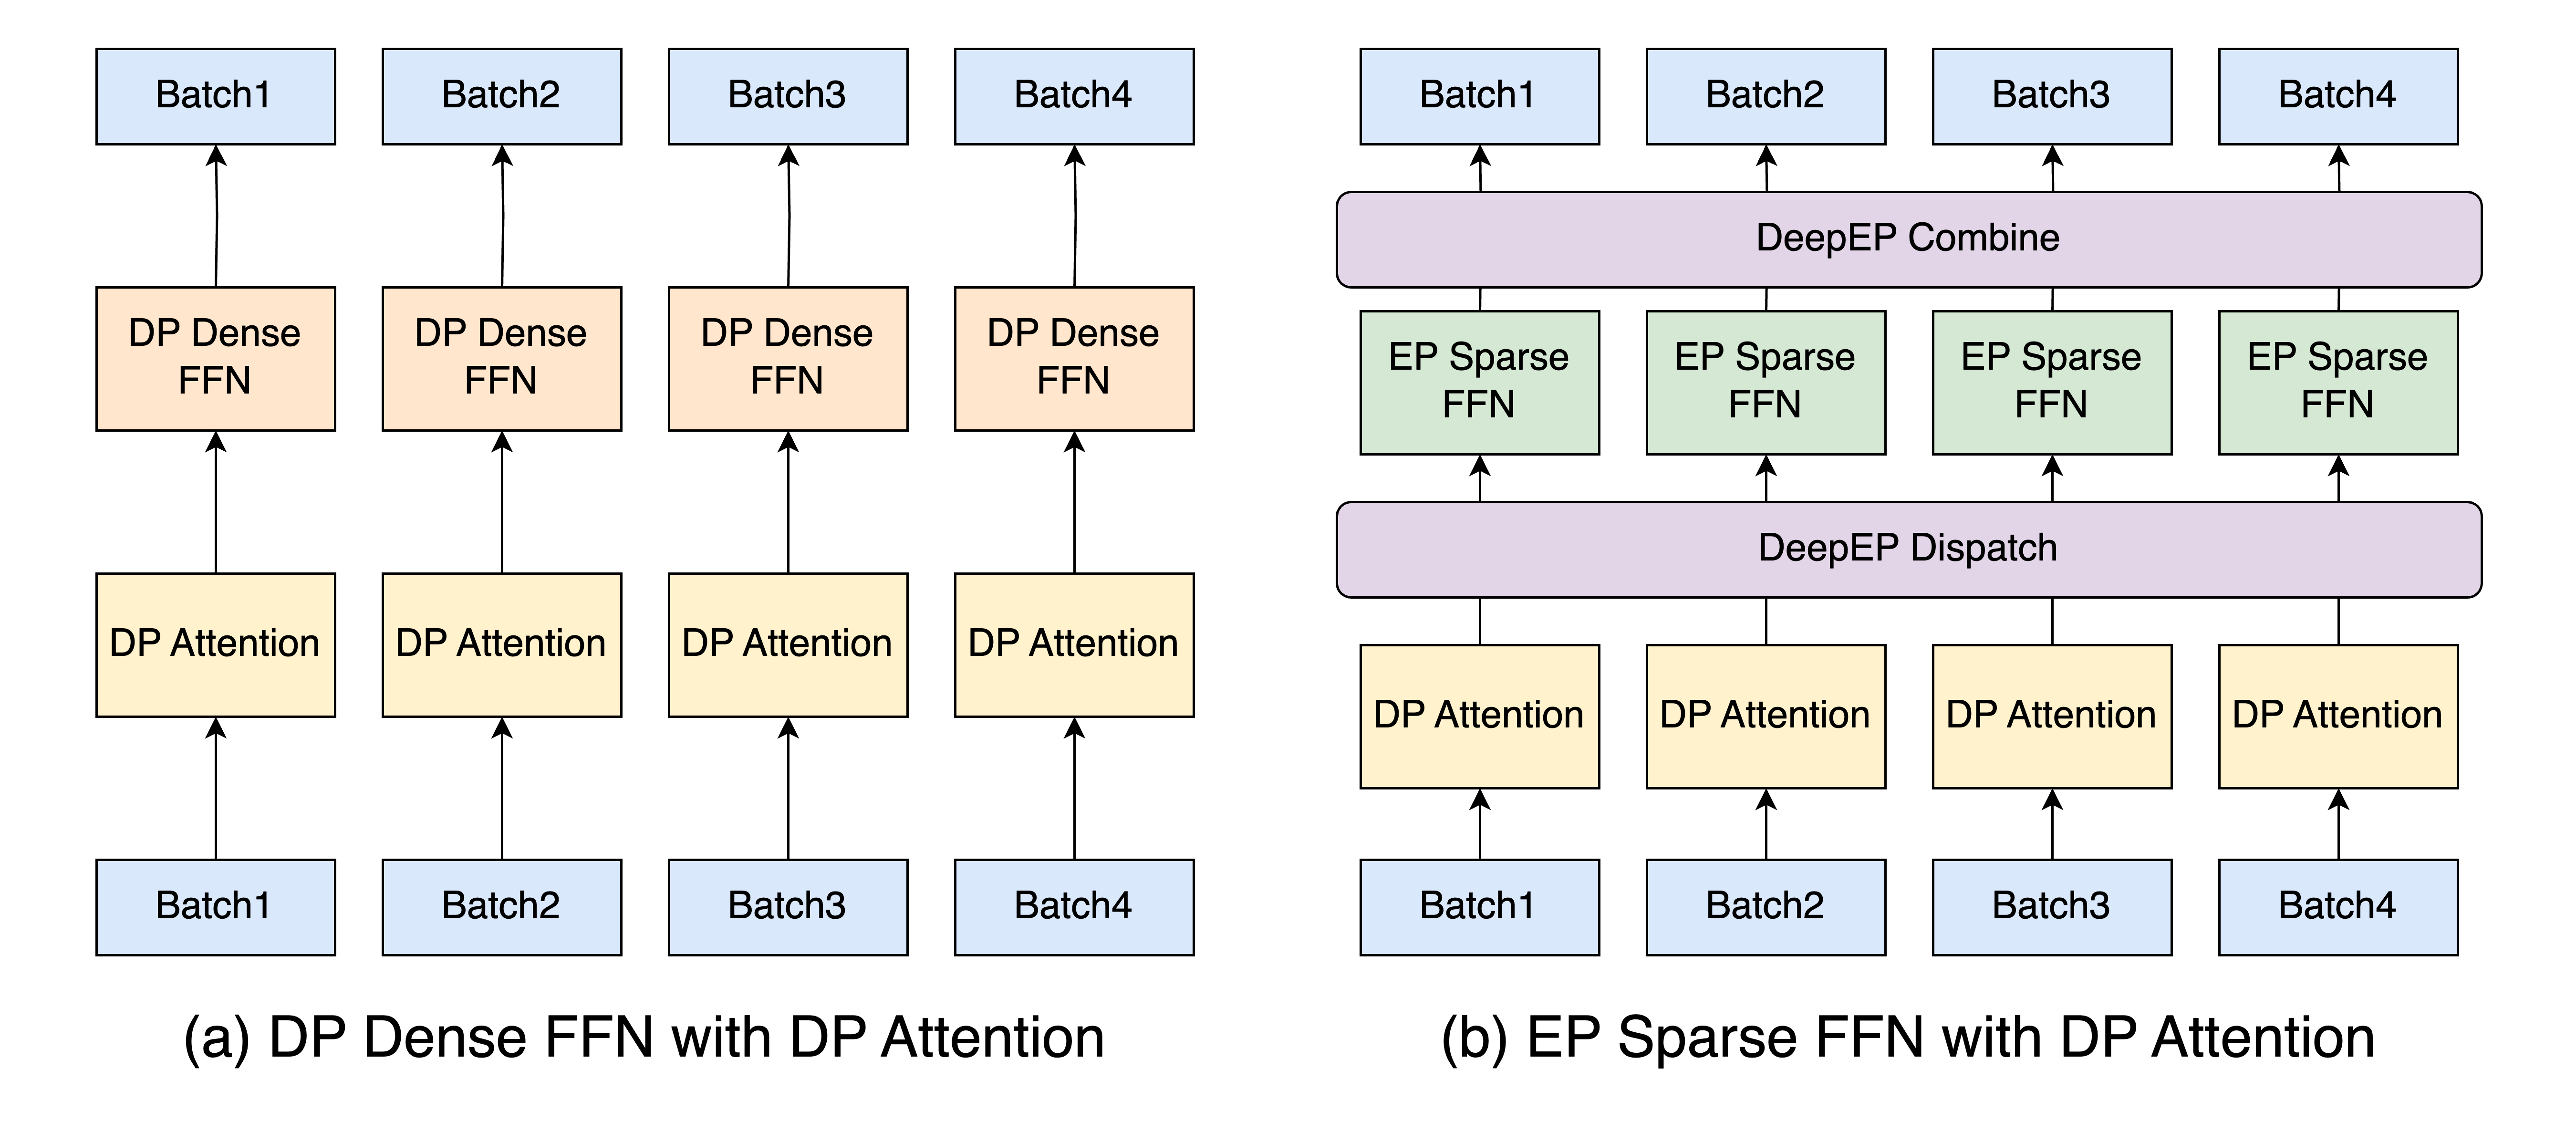
Deploying DeepSeek with PD Disaggregation and Large-Scale Expert ...

The vLLM MoE Playbook: A Practical Guide to TP, DP, PP and Expert ...

DeepSpeed: Advancing MoE inference and training to power next ...

Accelerating Mixture-of-Experts Training with Adaptive Expert ...

Scalable Training of Mixture-of-Experts Models with Megatron Core