
Serving At The Limit Llm Inference With Vllm And Triton On Kubernetes
Serving at the Limit: LLM Inference with vLLM and Triton on Kubernetes ...

Scaling LLM Inference on GKE: Serving with vLLM or llm-d | by Don ...
High-Performance LLM Infrastructure with Kubernetes and vLLM on Private ...
Efficient LLM Inference and Serving with vLLM
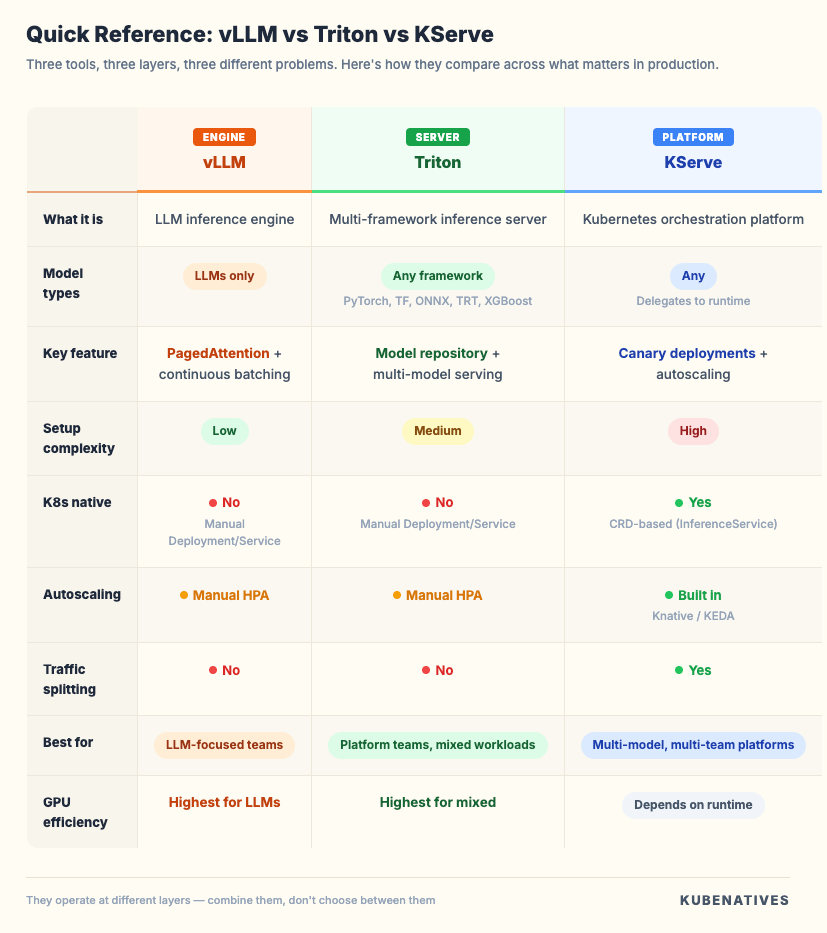
vLLM vs Triton vs KServe: Model Serving on Kubernetes
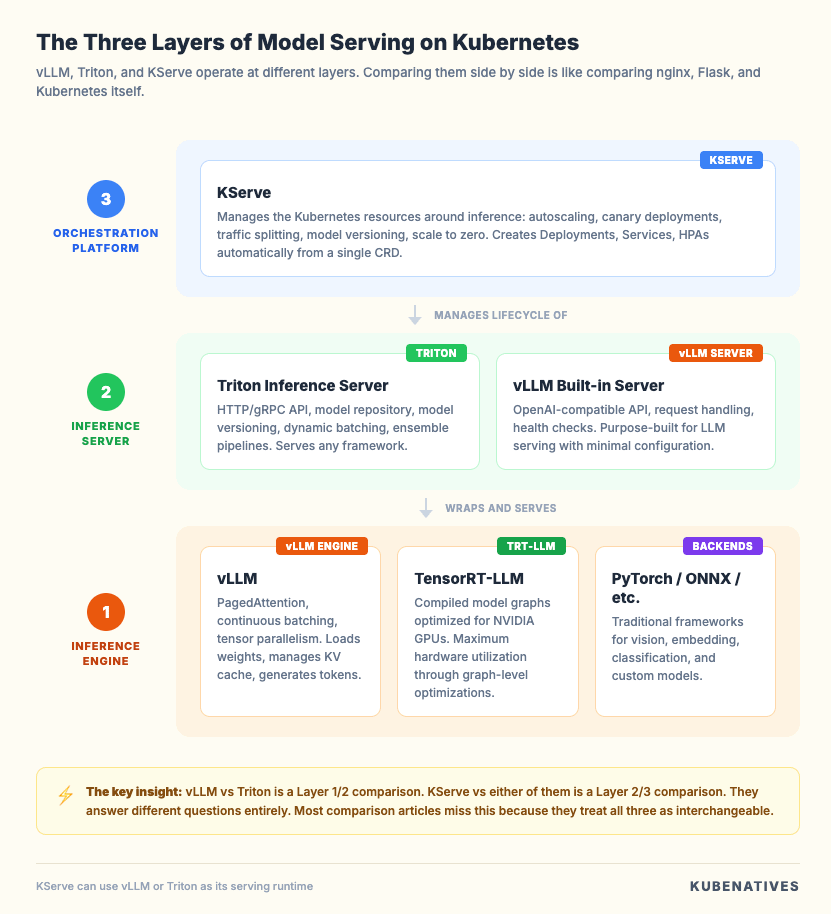
vLLM vs Triton vs KServe: Model Serving on Kubernetes
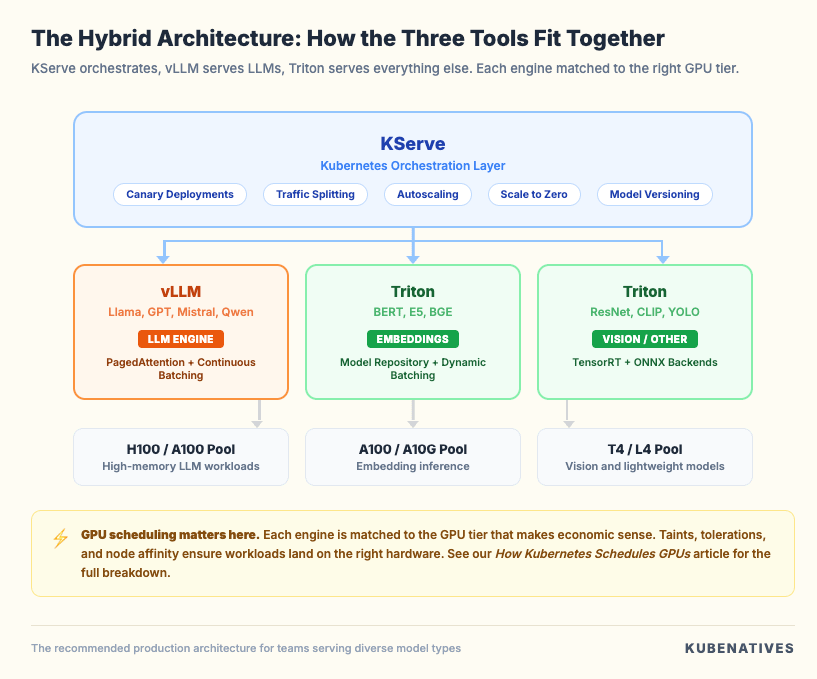
vLLM vs Triton vs KServe: Model Serving on Kubernetes
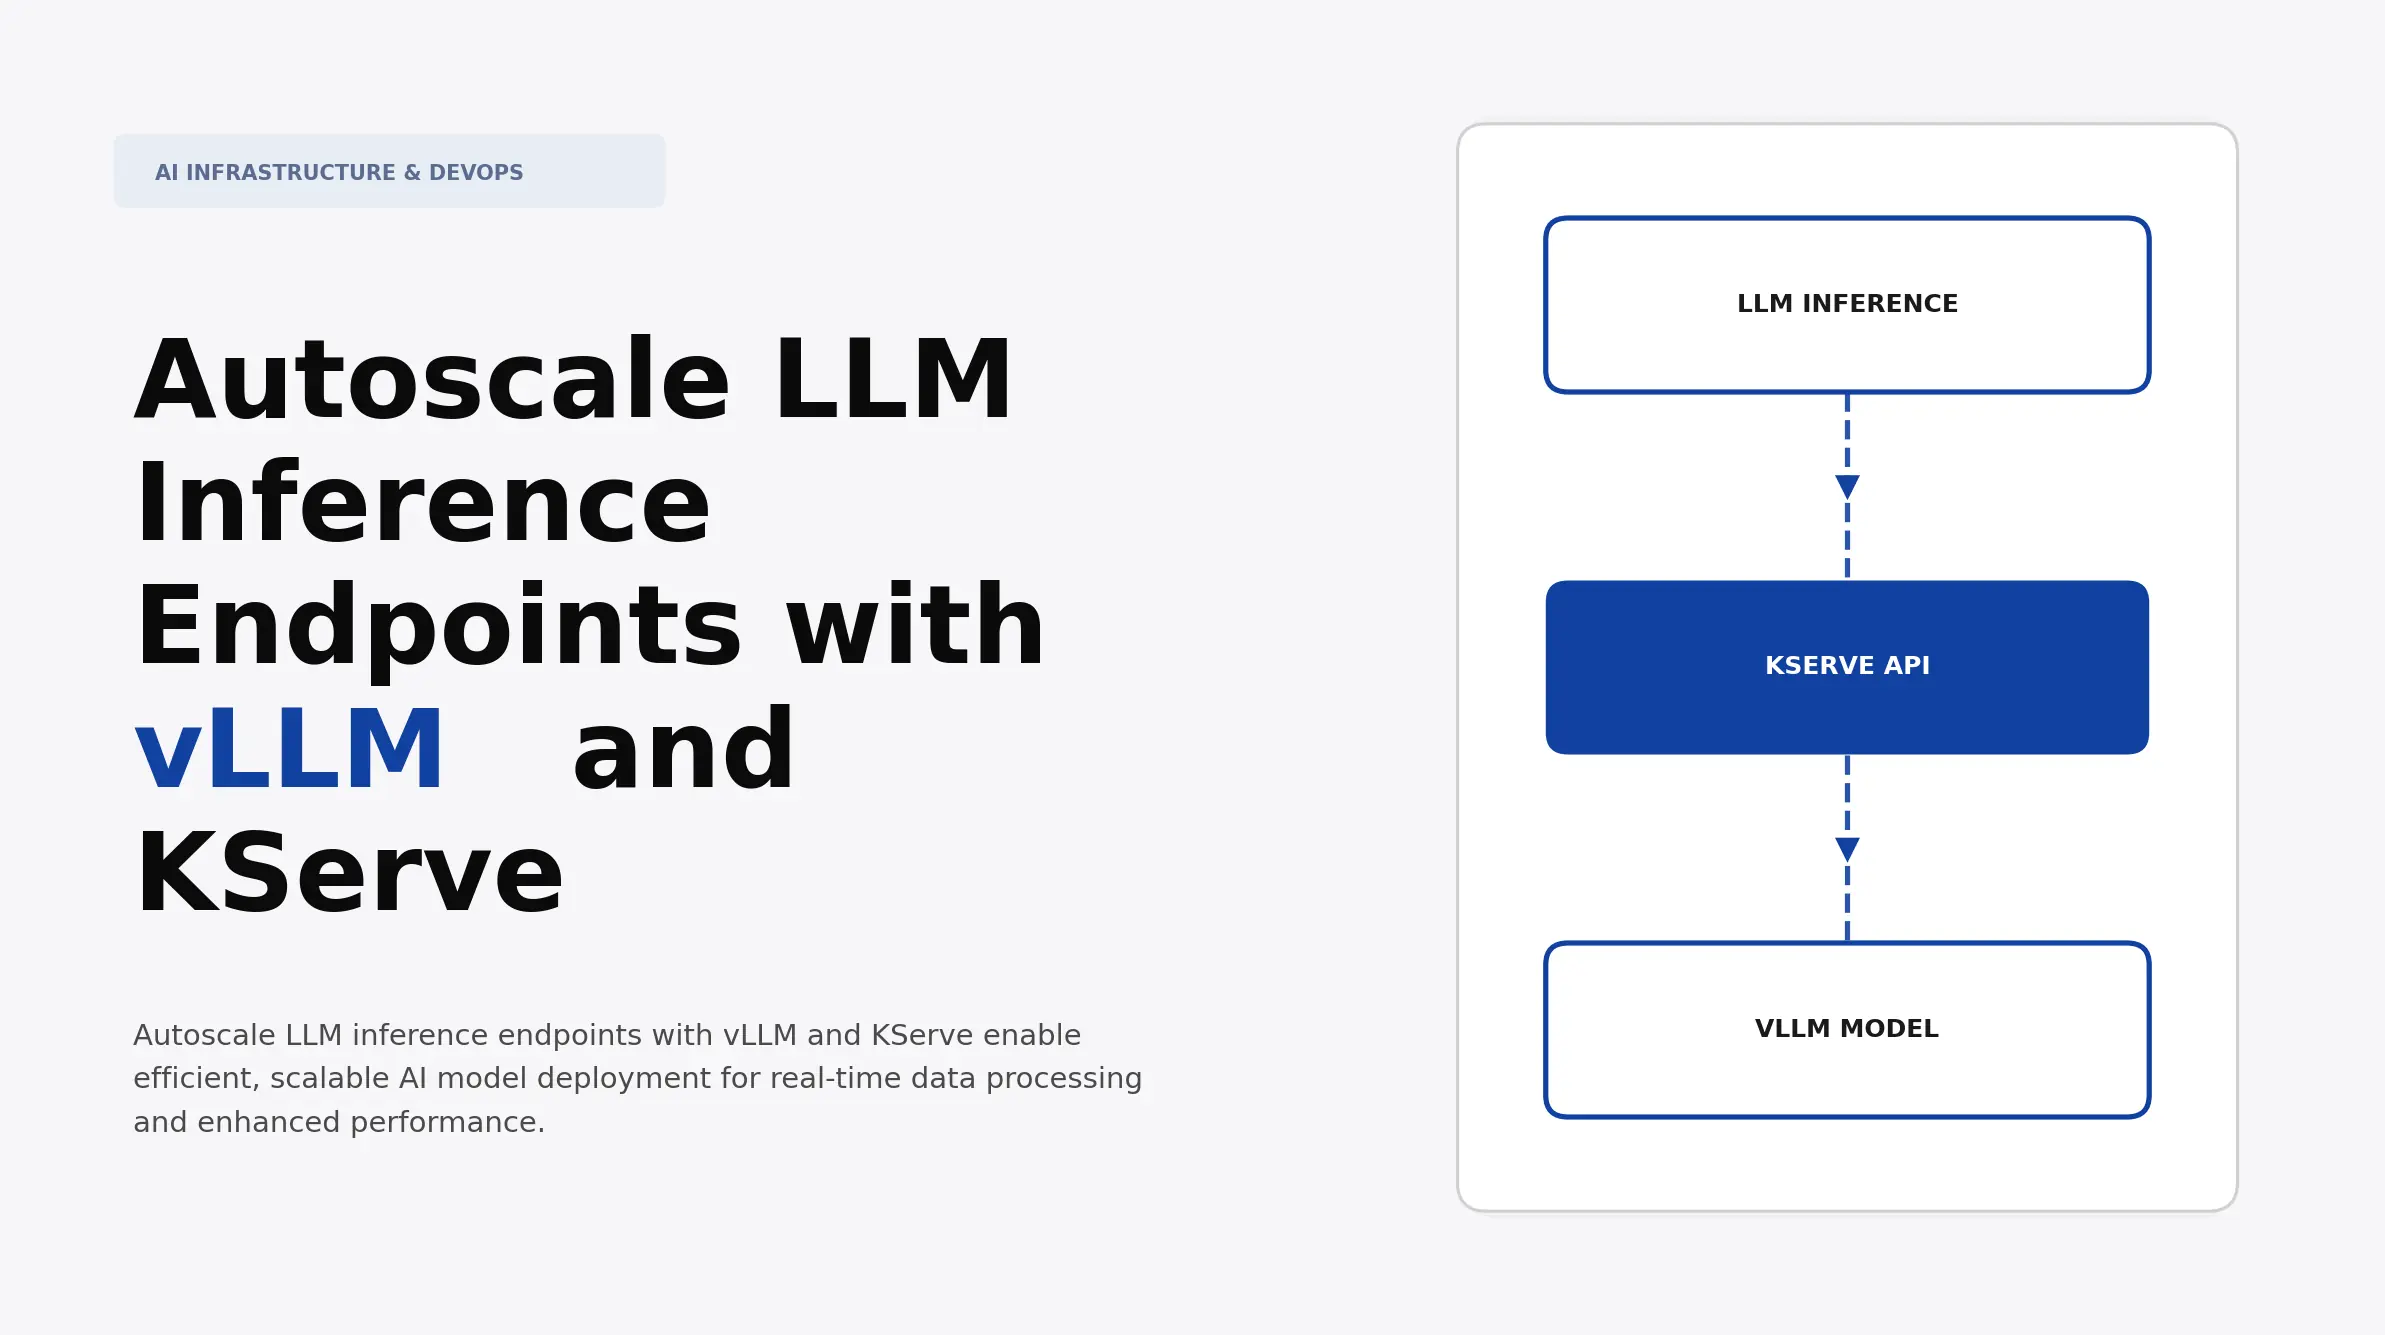
Autoscale LLM Inference Endpoints with vLLM and KServe | Atomic Loops
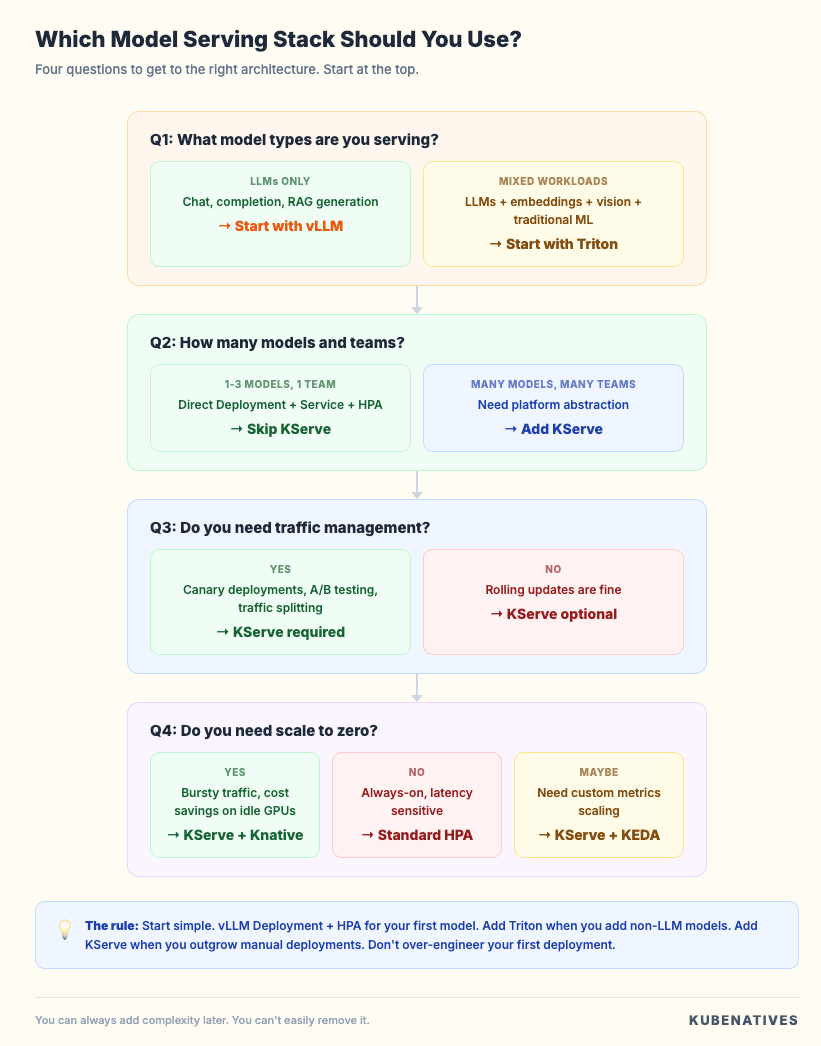
vLLM vs Triton vs KServe: Model Serving on Kubernetes

Quickstart: High-throughput LLM inference with vLLM on Amazon EKS ...
Advertisement Space (300x250)
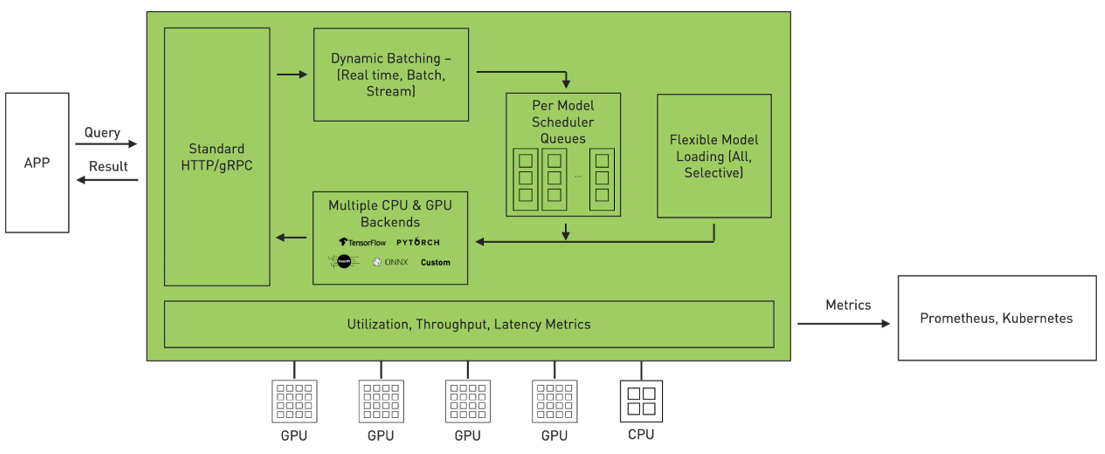
Simplifying and Scaling Inference Serving with NVIDIA Triton 2.3 ...
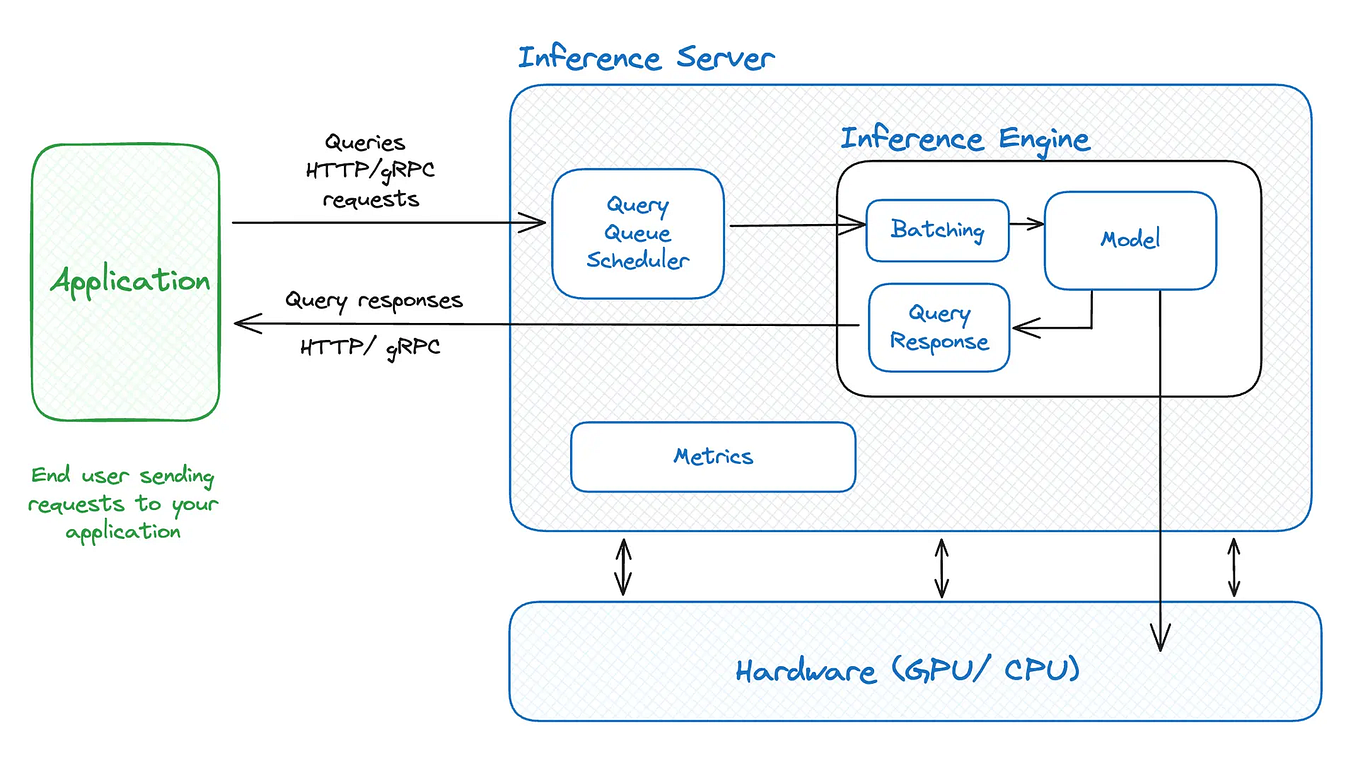
Transforming LLM Serving: NVIDIA Triton Inference Server Meets vLLM ...

Transforming LLM Serving: NVIDIA Triton Inference Server Meets vLLM ...

vLLM vs. Triton Inference Server: In-Depth Comparison for Optimized LLM ...
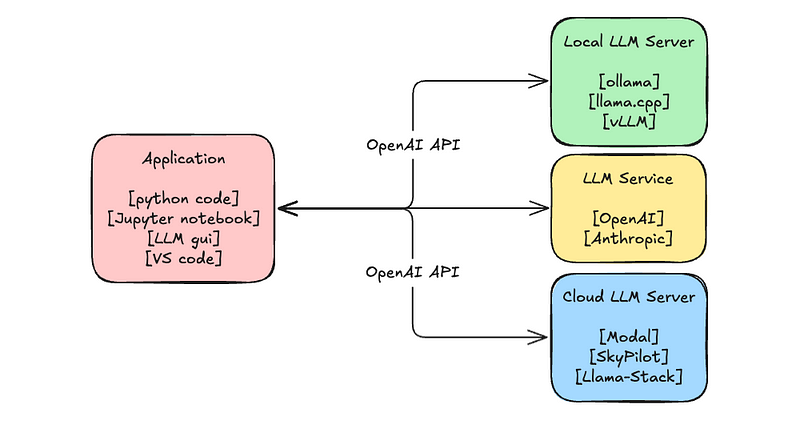
Transforming LLM Serving: NVIDIA Triton Inference Server Meets vLLM ...
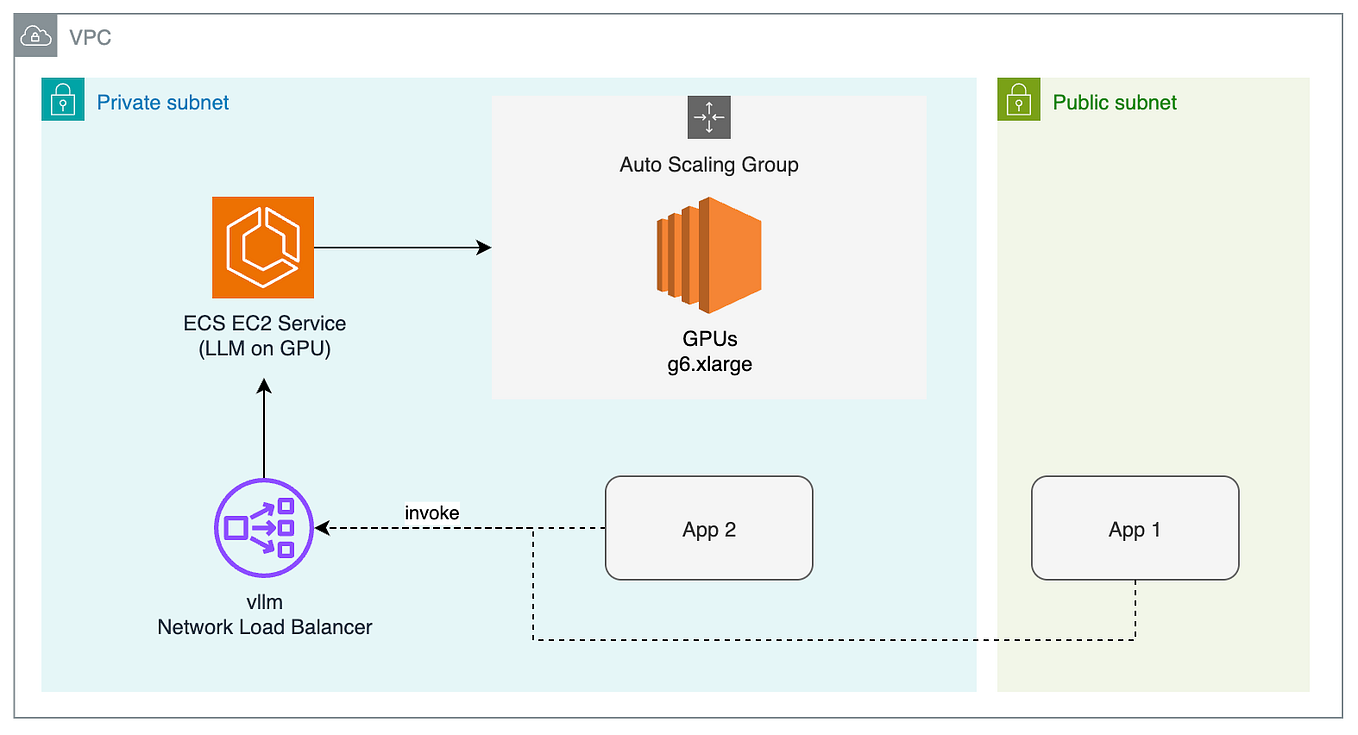
Transforming LLM Serving: NVIDIA Triton Inference Server Meets vLLM ...

vLLM vs. Triton Inference Server: In-Depth Comparison for Optimized LLM ...

vLLM vs. Triton Inference Server: In-Depth Comparison for Optimized LLM ...

LLM Deployment: A Guide to NVIDIA Triton Inference Server and TensorRT ...

🤖 LLM Inferencing with TensorRT-LLM + Triton Inference Server | by ...
Advertisement Space (336x280)
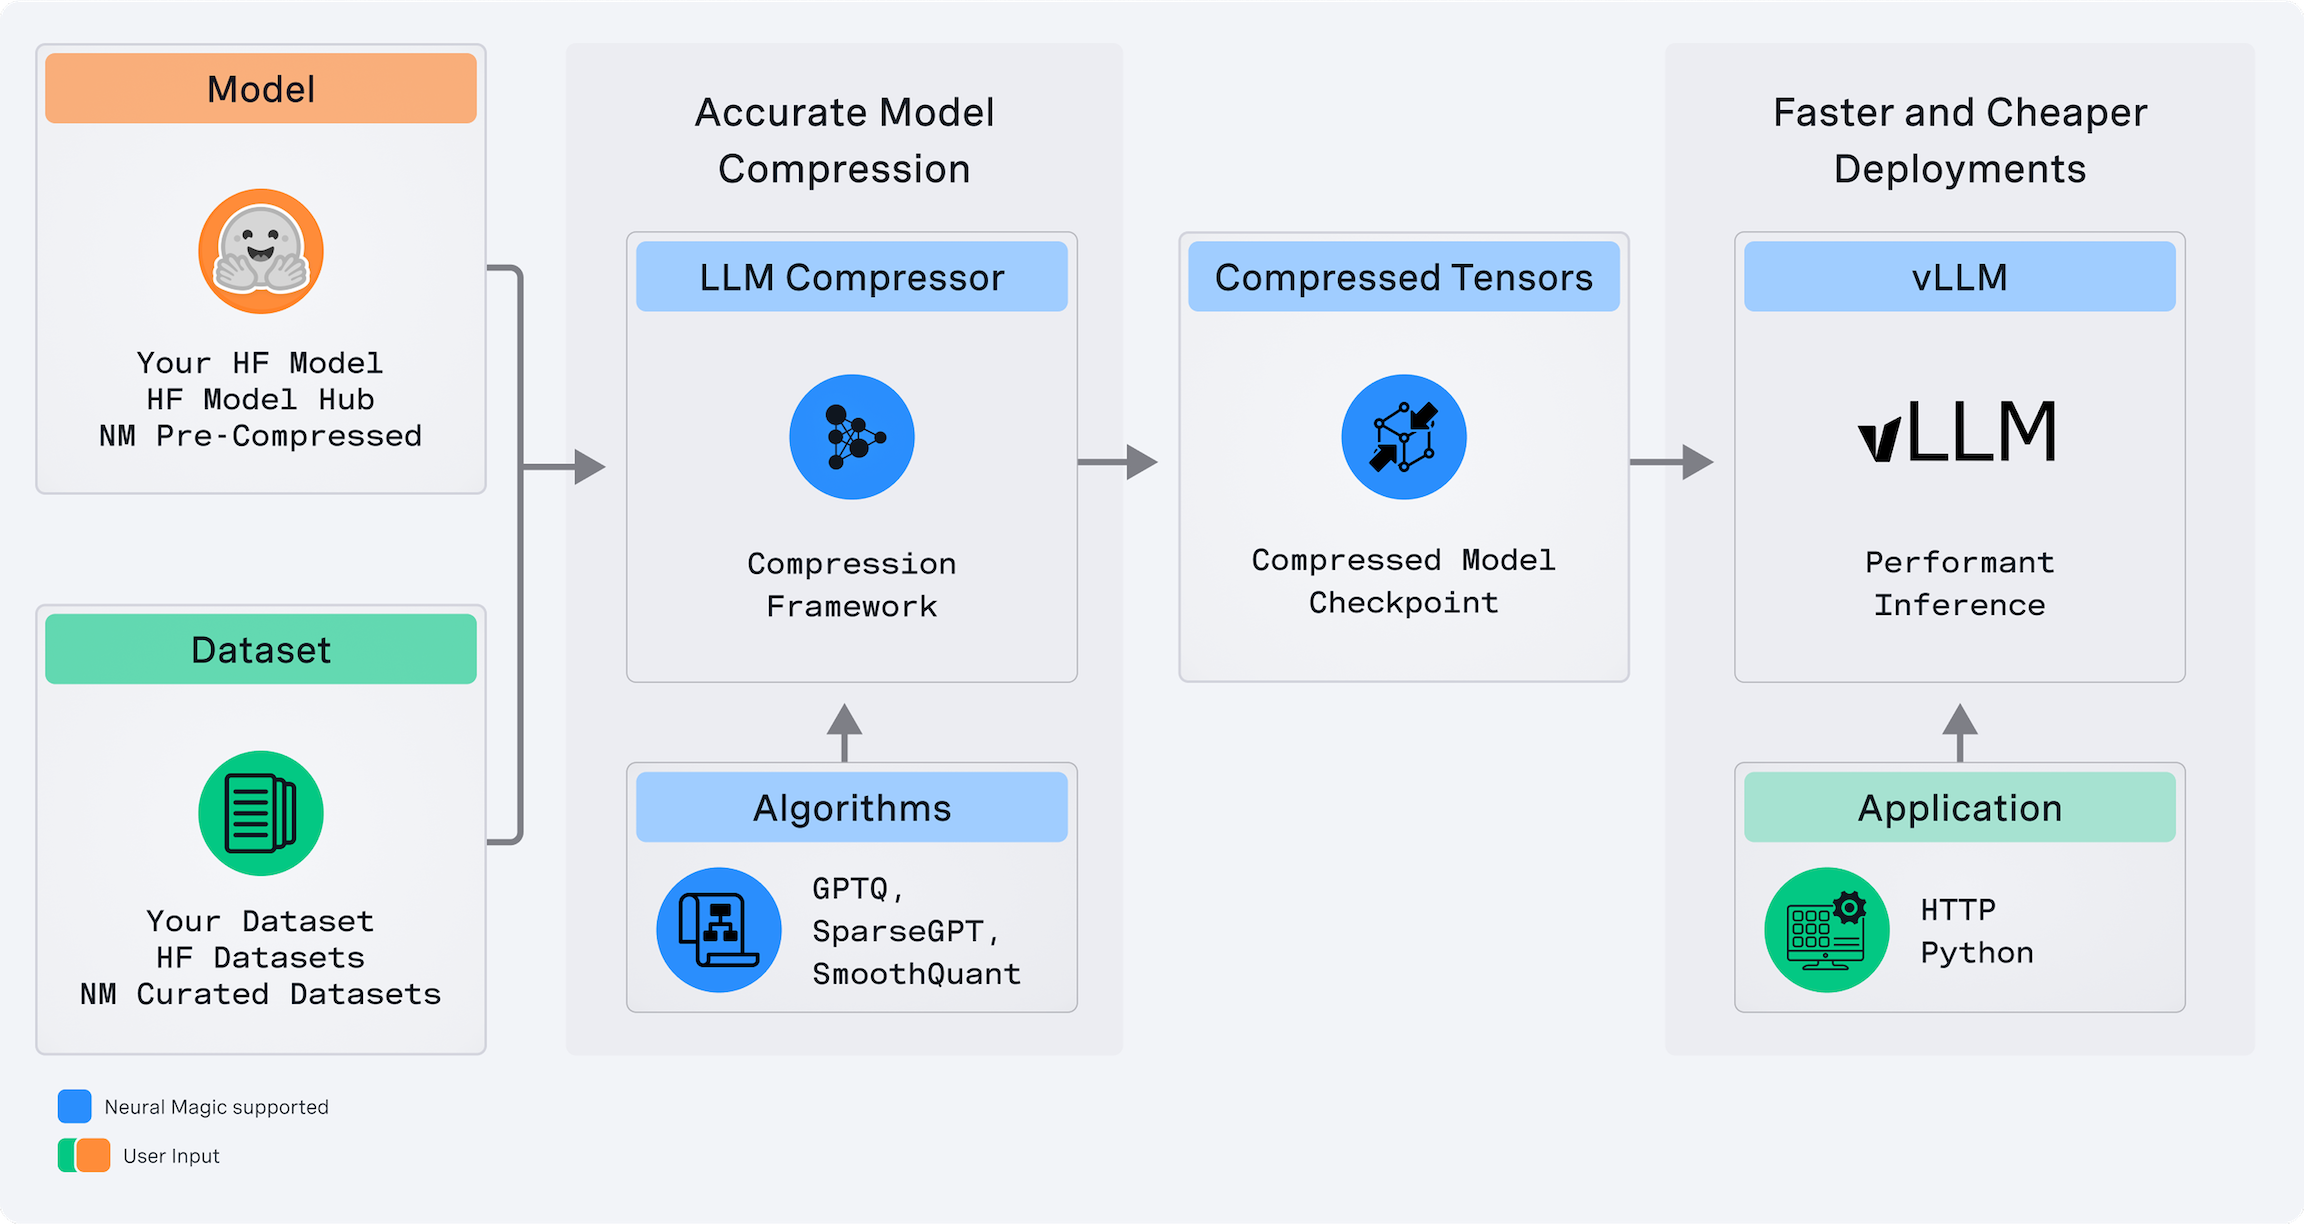
LLM Compressor is here: Faster inference with vLLM | Red Hat Developer
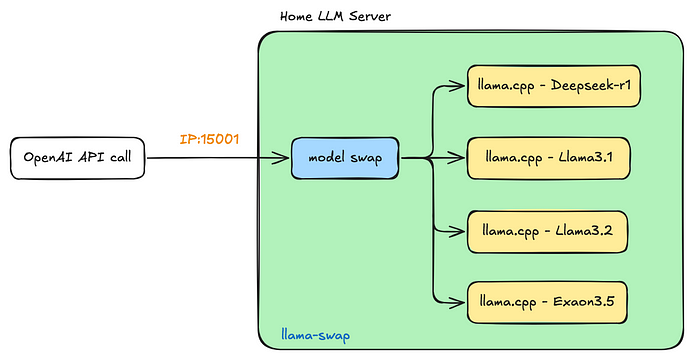
Transforming LLM Serving: NVIDIA Triton Inference Server Meets vLLM ...
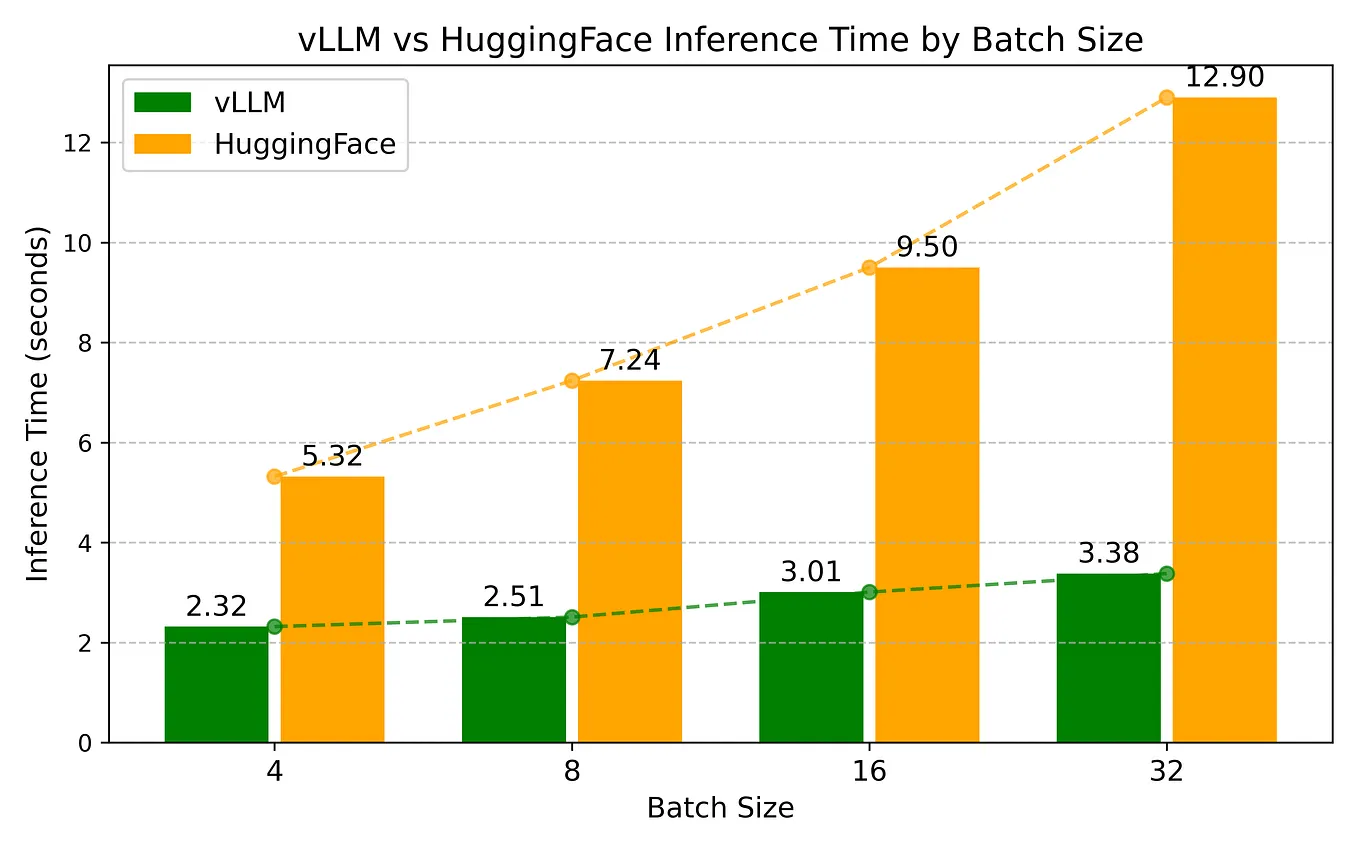
LLM Deployment: A Guide to NVIDIA Triton Inference Server and TensorRT ...
LLM Deployment: A Guide to NVIDIA Triton Inference Server and TensorRT ...
Transforming LLM Serving: NVIDIA Triton Inference Server Meets vLLM ...
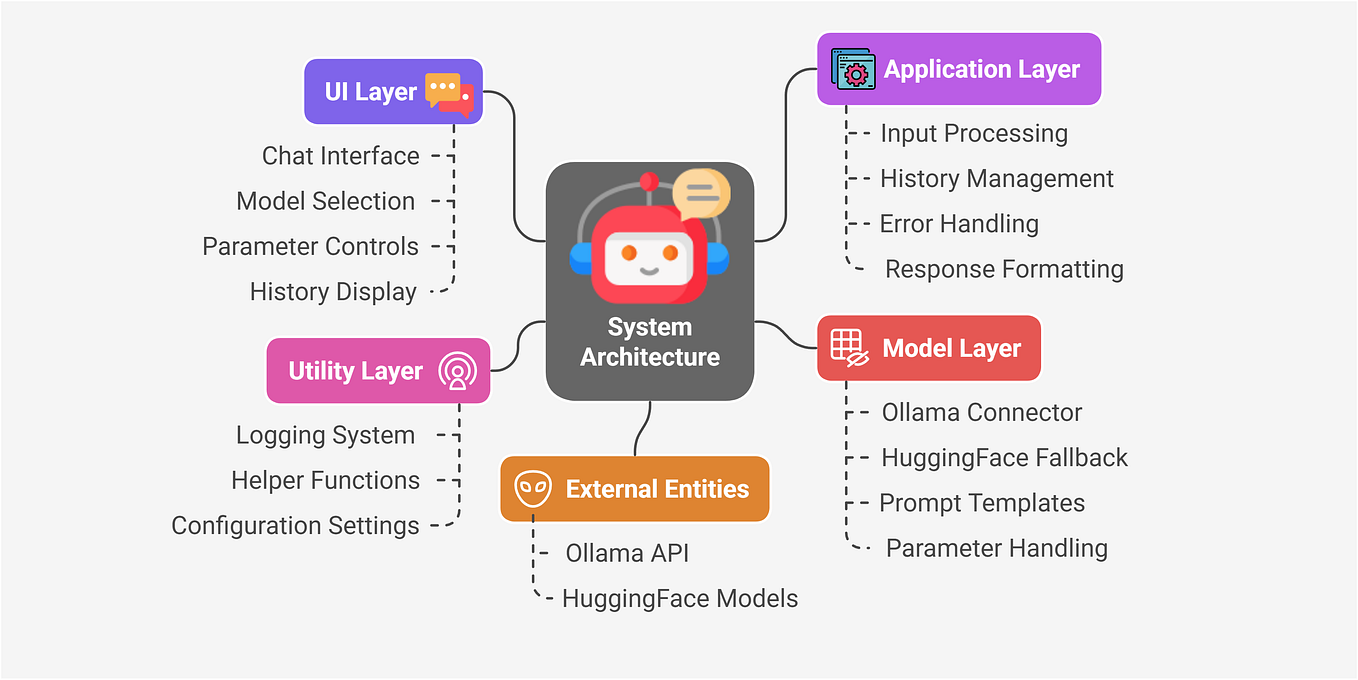
Transforming LLM Serving: NVIDIA Triton Inference Server Meets vLLM ...
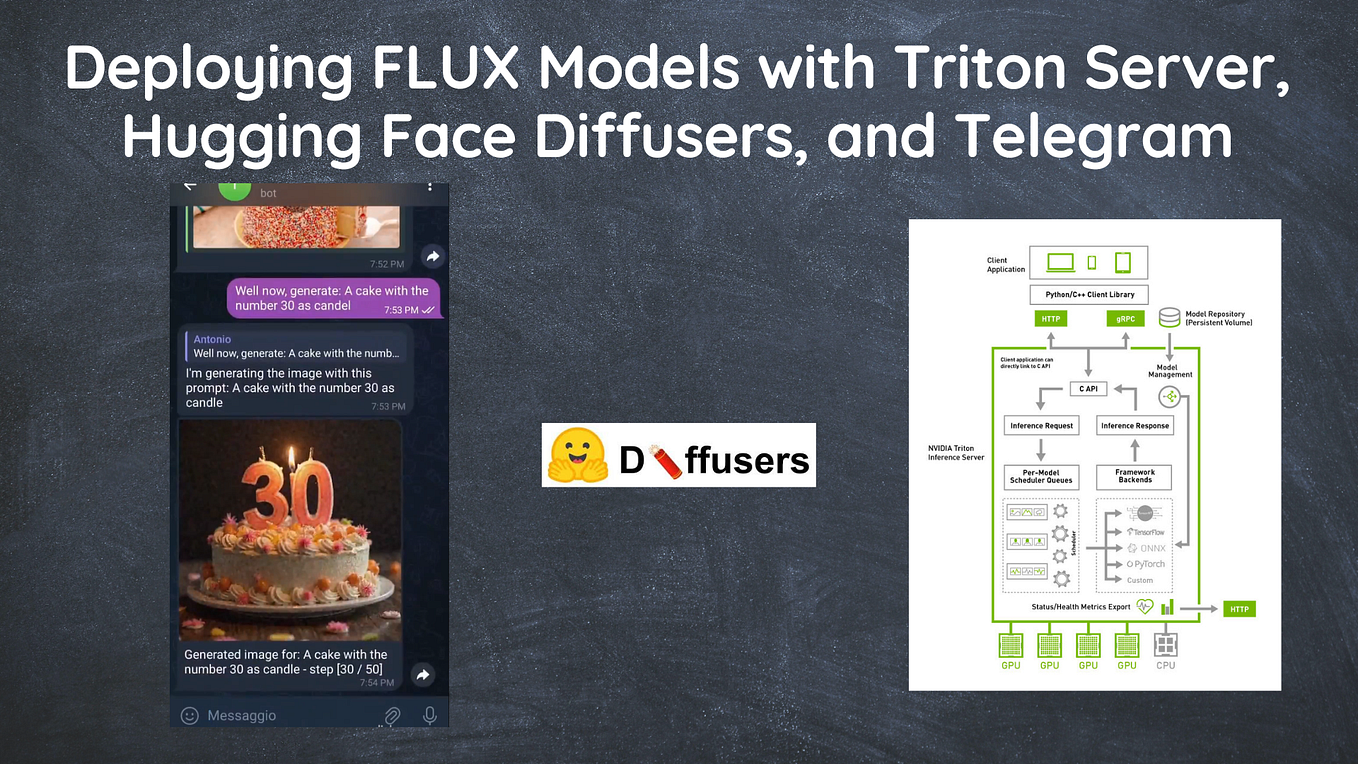
Transforming LLM Serving: NVIDIA Triton Inference Server Meets vLLM ...
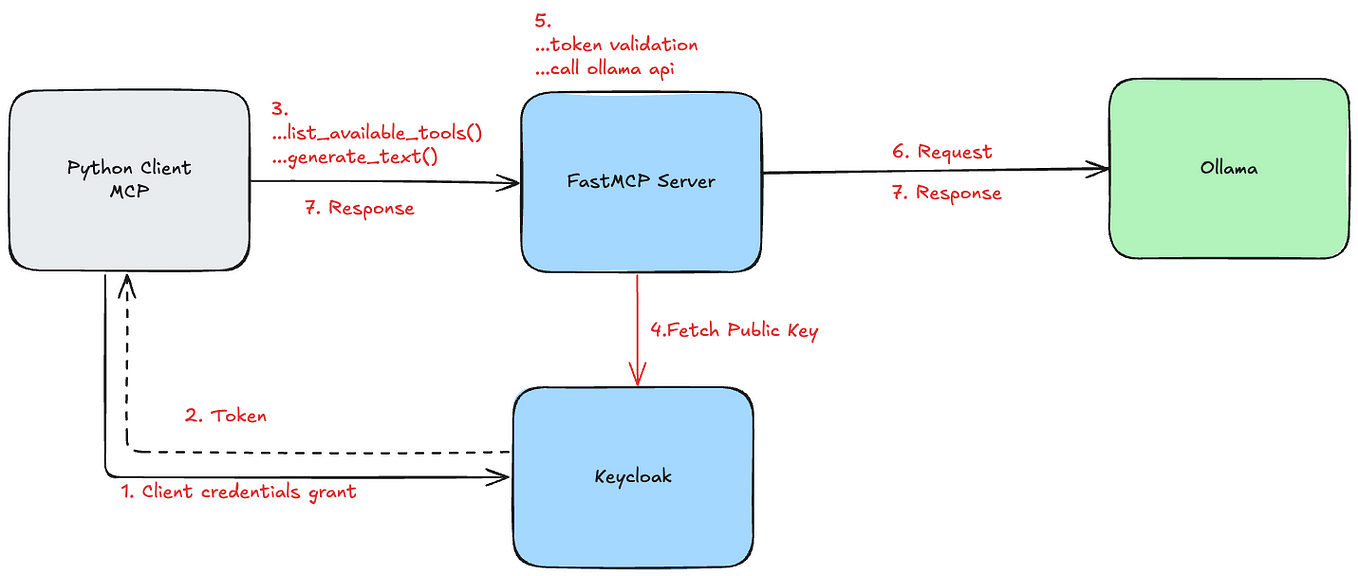
LLM Deployment: A Guide to NVIDIA Triton Inference Server and TensorRT ...

Serving Inference for LLMs: A Case Study with NVIDIA Triton Inference ...
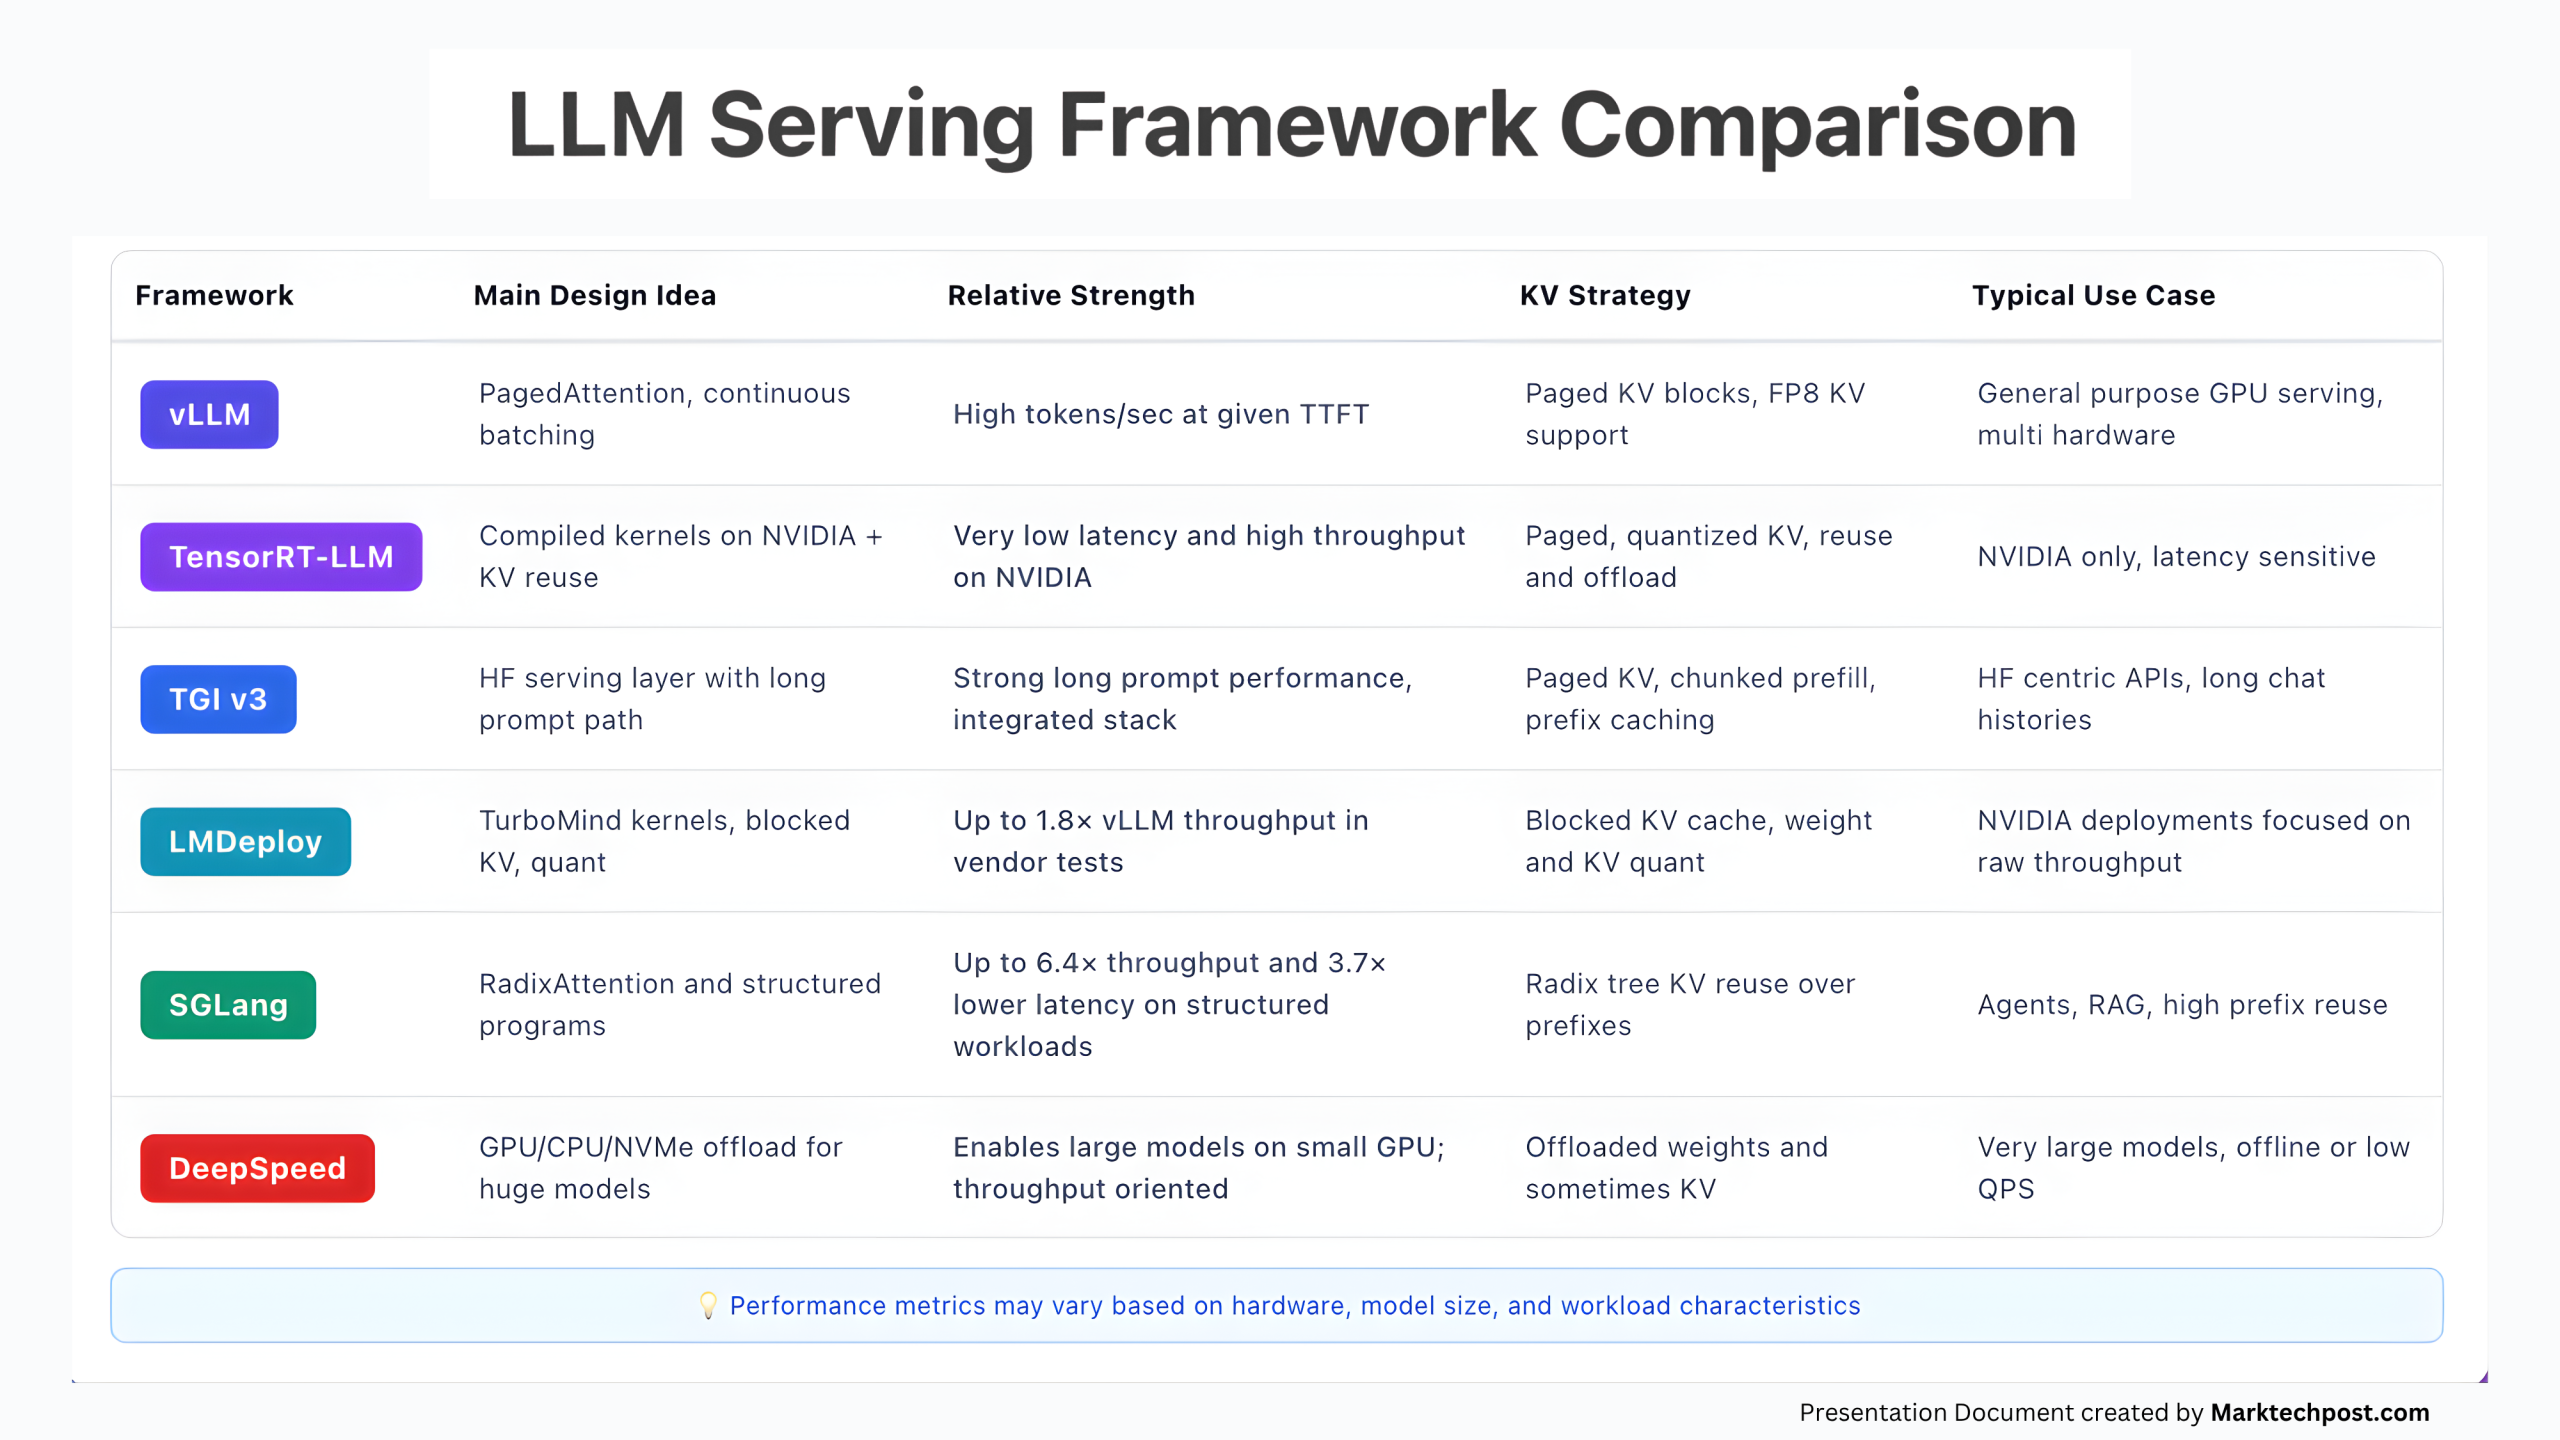
Comparing the Top 6 Inference Runtimes for LLM Serving in 2025 ...
Advertisement Space (336x280)
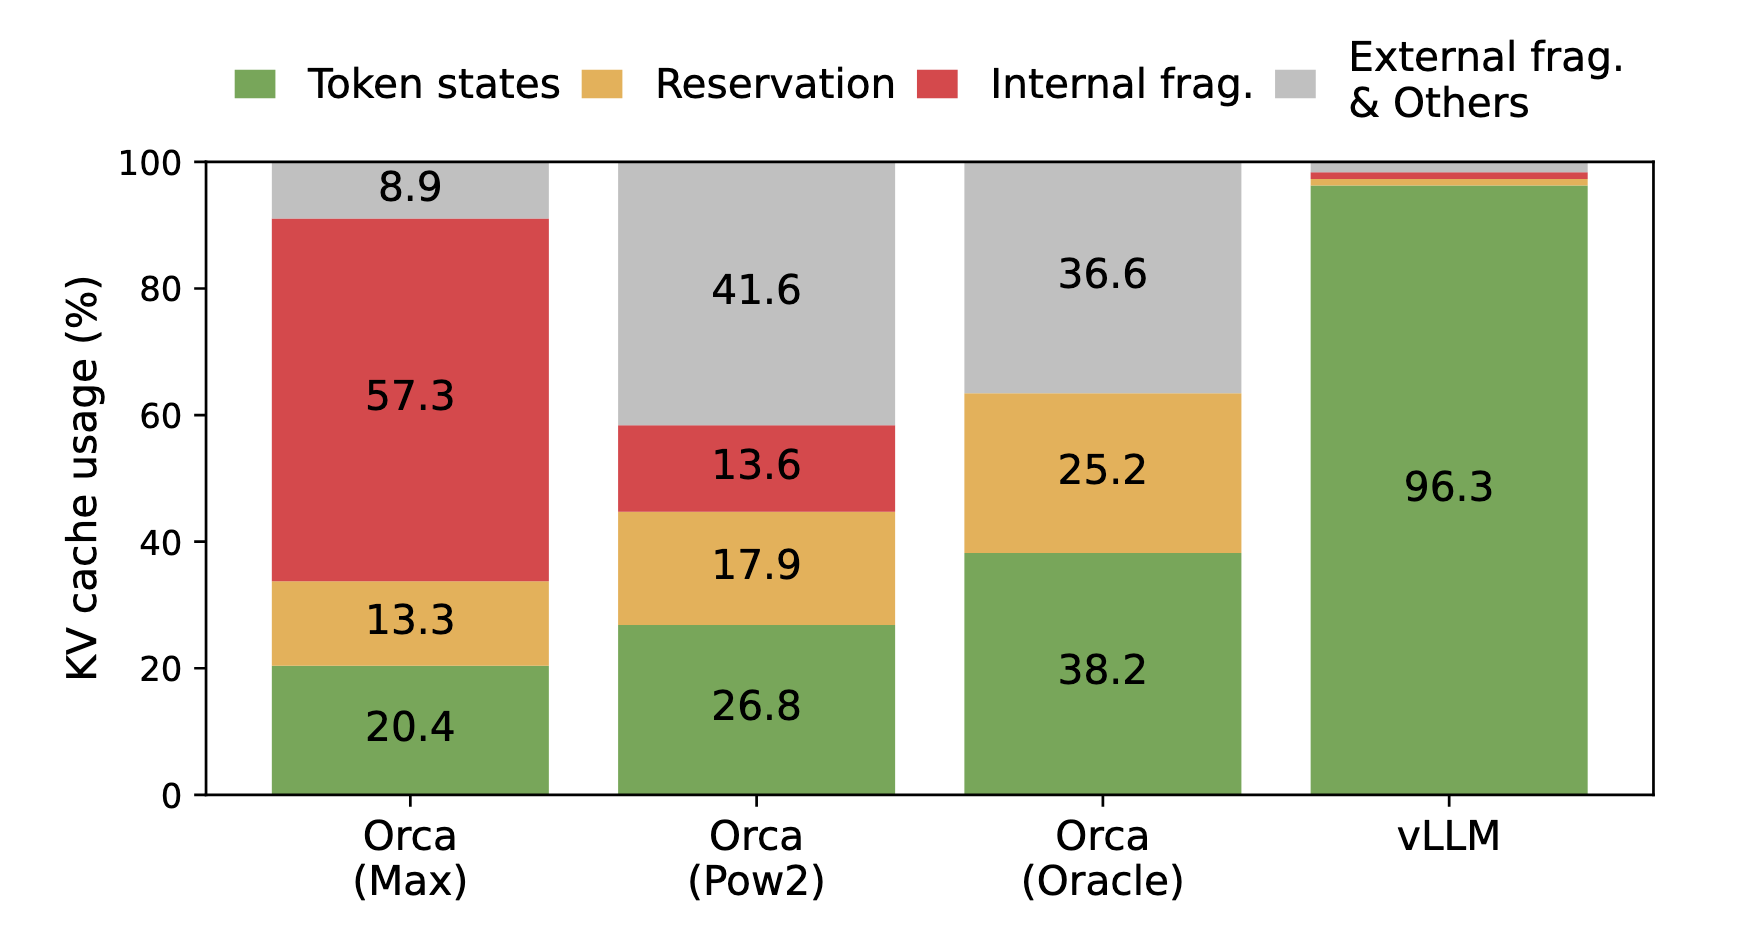
Daniele Salvagni - Dense Model Serving on AWS EKS with Triton, vLLM ...

Guide to LLM Serving Stacks: vLLM vs TGI vs Triton | by Roushan Kumar ...

Scaling Llms with Nvidia Triton and Tensorrt-LLM: The Complete Guide to ...
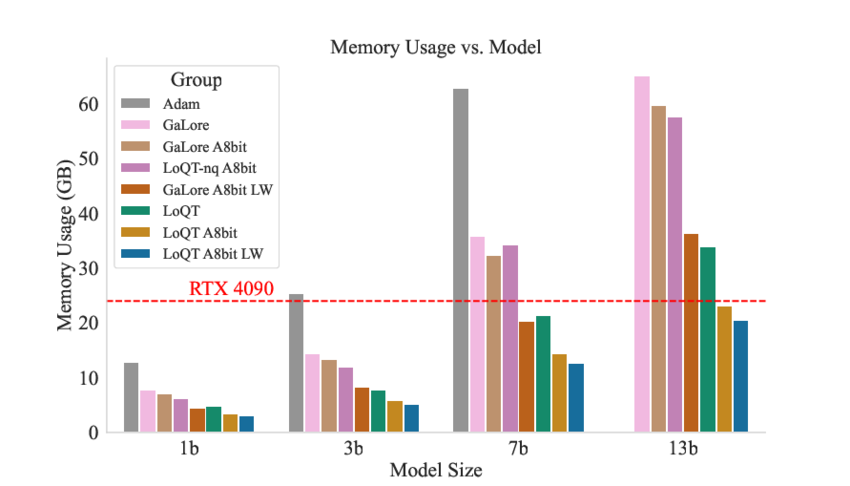
Transforming LLM Serving: NVIDIA Triton Inference Server Meets vLLM ...

Comparing two LLM serving frameworks: Friendli Inference vs. vLLM

Multi-Node LLM Serving Using sig LWS and vLLM - CECG