
Serving Multiple Models In Vllm With Single Or Multiple Engines Issue
Serving multiple models in vLLM with single or multiple engines · Issue ...

Model Variant: Serving Multiple Models with Ease
Can vllm serving clients by using multiple model instances? · Issue ...

Model Variant: Serving Multiple Models with Ease

Efficiently Serving Multiple Machine Learning Models with Lorax and ...

Serving Large Language Models with vLLM on AMD ROCm GPUs | by Trade ...
Disaggregated Serving for Hybrid SSM Models in vLLM | vLLM Blog
[Misc]: How can I serve multiple models on a single port using the ...
Serving Models with vLLM | vllm-project/speculators | DeepWiki

Serving Large Language Models with vLLM on AMD ROCm GPUs | by Trade ...
Advertisement Space (300x250)
[Feature]: Multiple models one server · Issue #21481 · vllm-project ...
Free Video: Improve AI Inference - Serving Models With KServe and VLLM ...
[Usage]: How to use vllm serve in ddp mode? (single node multiple gpus ...
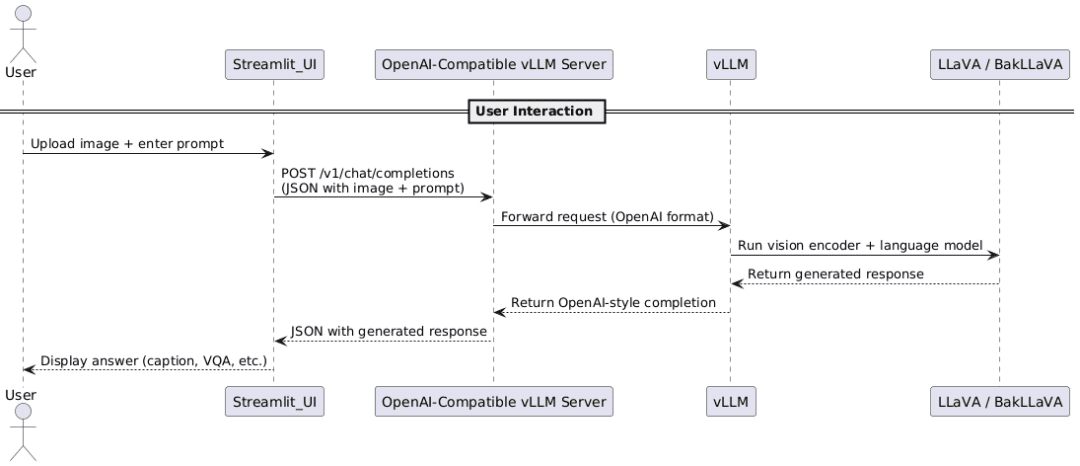
The Rise of Multimodal LLMs and Efficient Serving with vLLM - PyImageSearch
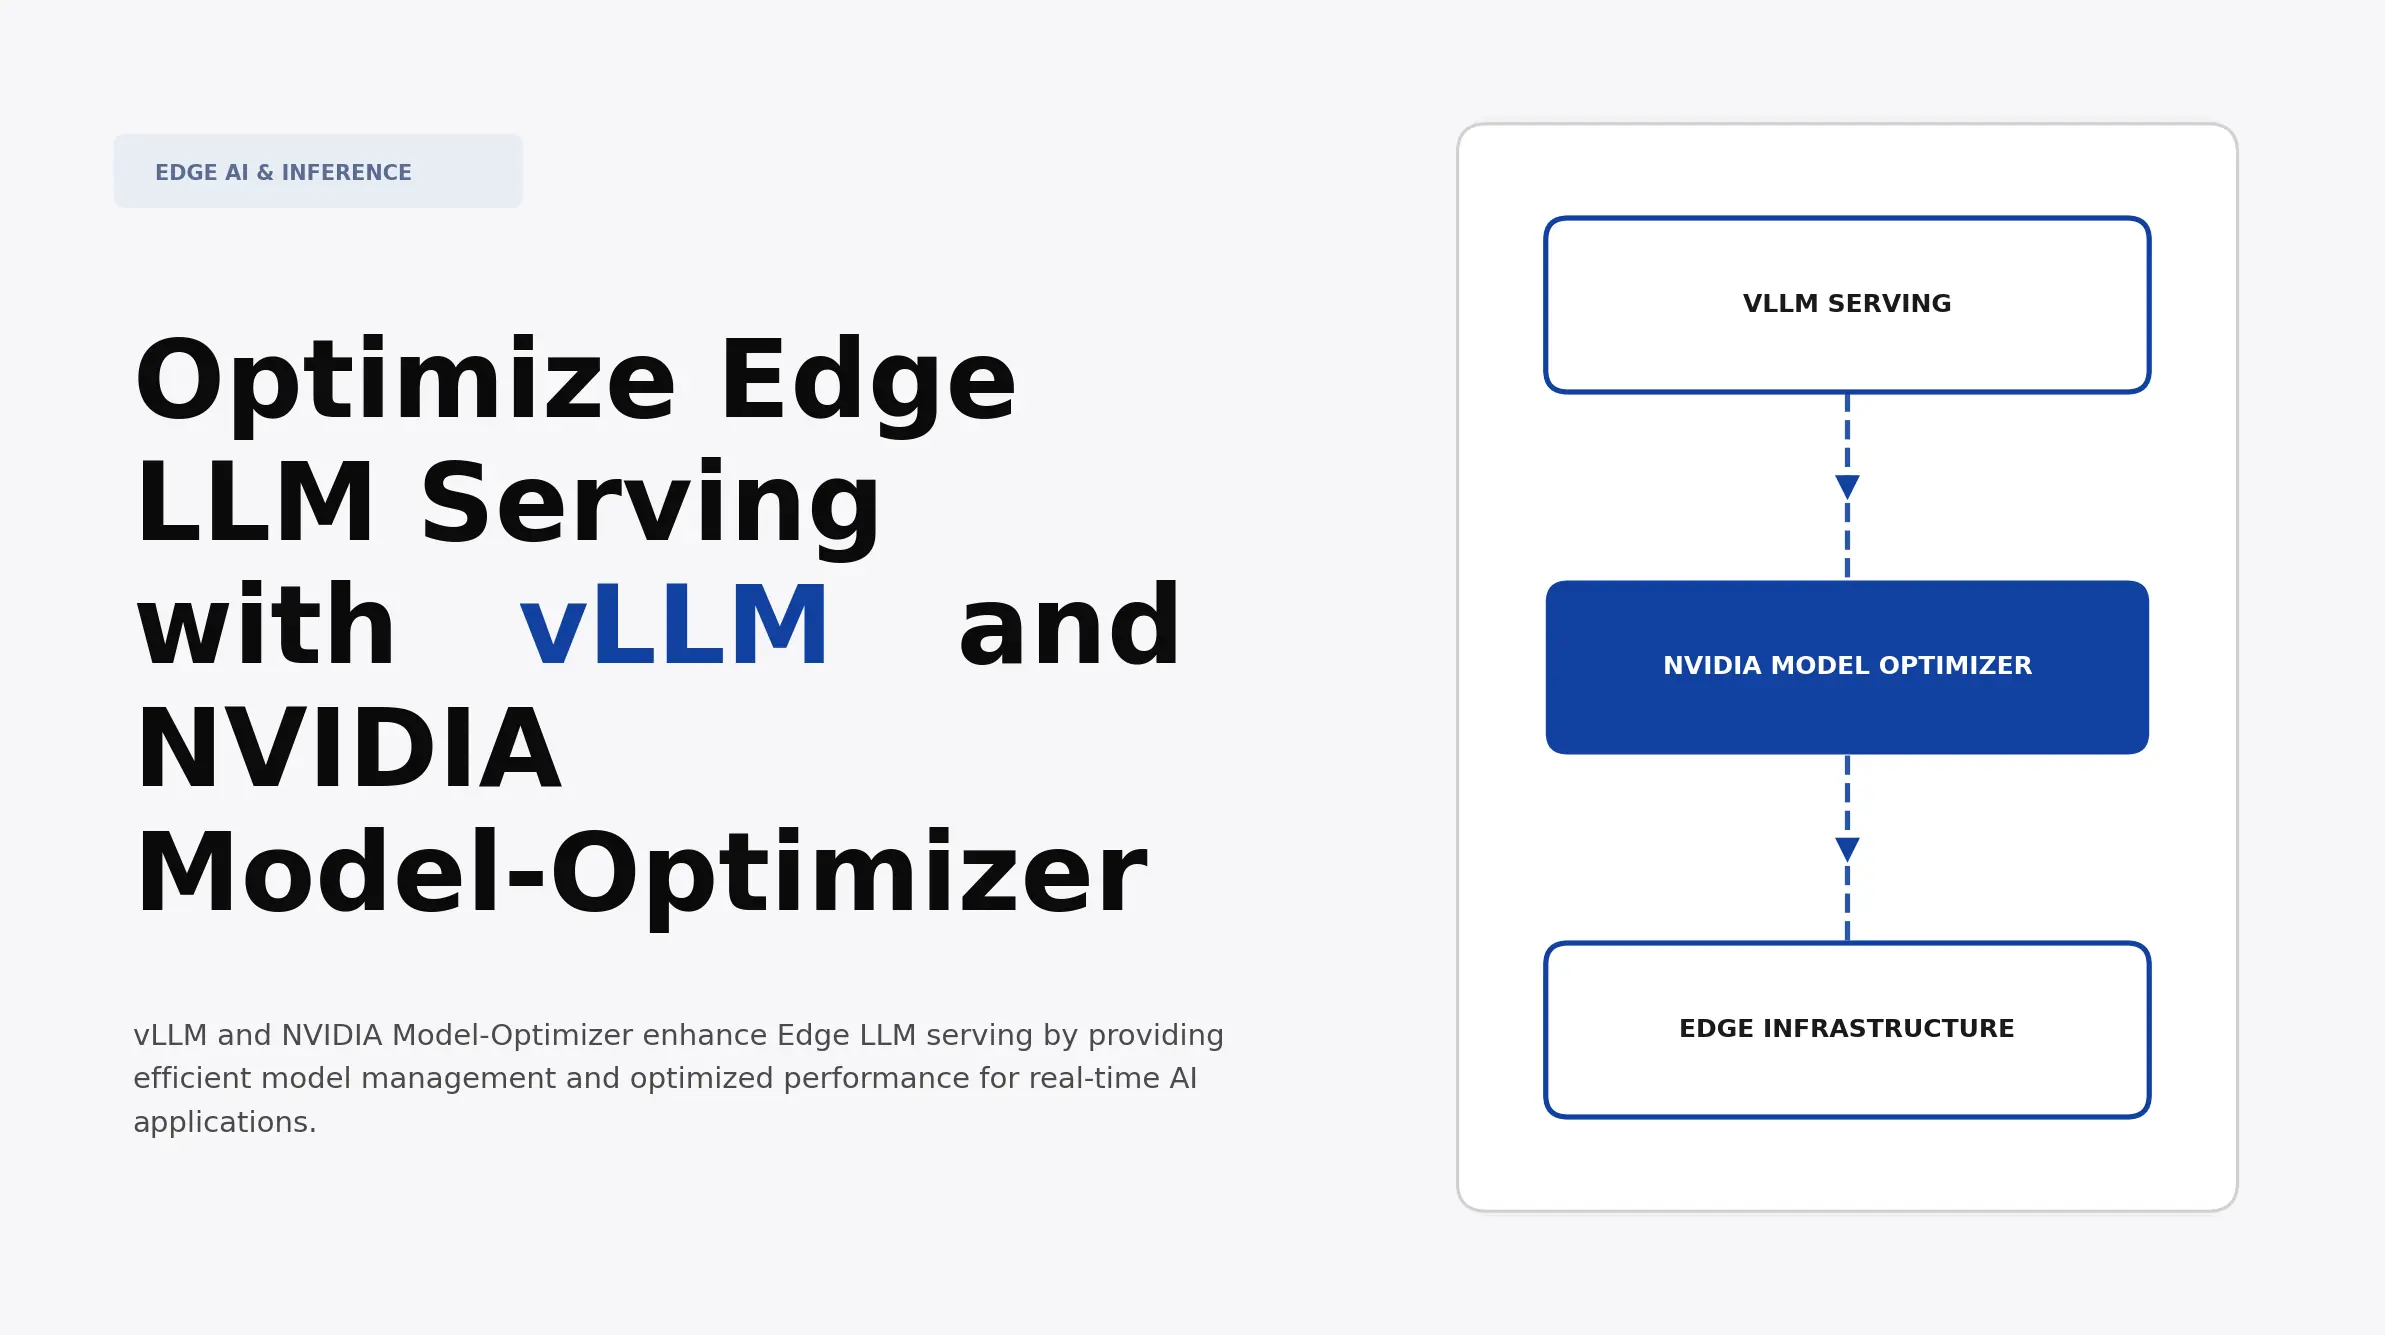
Optimize Edge LLM Serving with vLLM and NVIDIA Model-Optimizer | Atomic ...
OpenShift AI Model Serving with vLLM (2026 Guide)
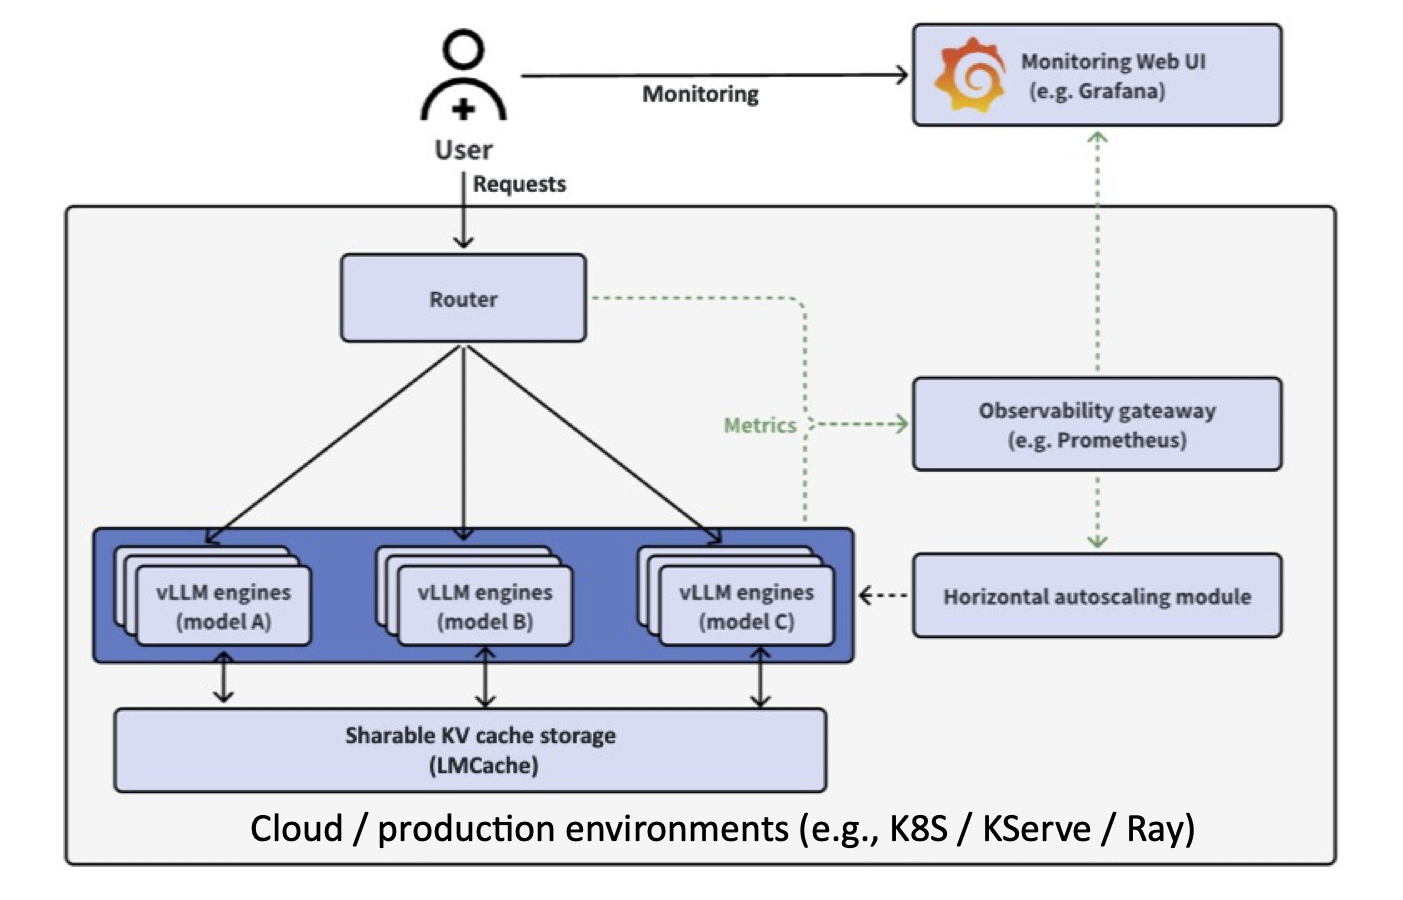
High Performance and Easy Deployment of vLLM in K8S with “vLLM ...

[vLLM vs TensorRT-LLM] #10 Serving Multiple LoRAs at Once - SqueezeBits

FireAttention — Serving Open Source Models 4x faster than vLLM by ...
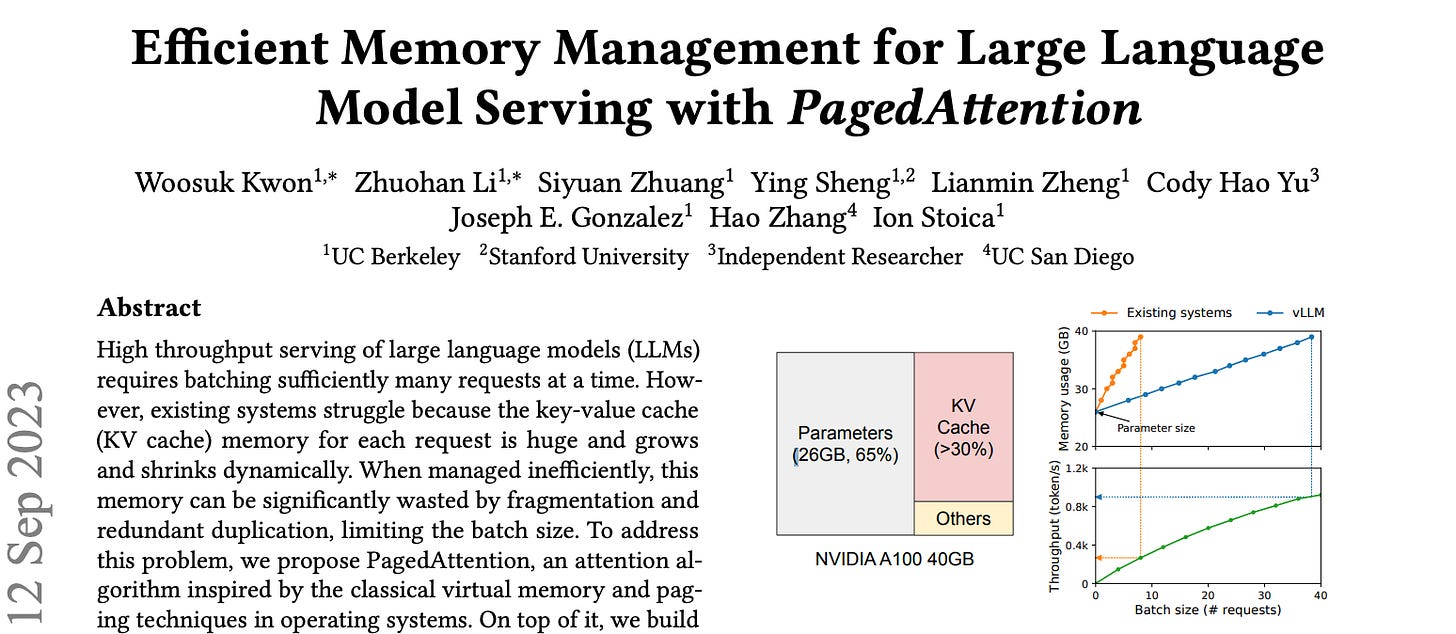
Practical Large Language Model Serving with vLLM on Google VertexAI ...
Advertisement Space (336x280)

[vLLM vs TensorRT-LLM] #10 Serving Multiple LoRAs at Once - The ...

BAAI/bge-m3 · Regarding serving with the vLLM engine.
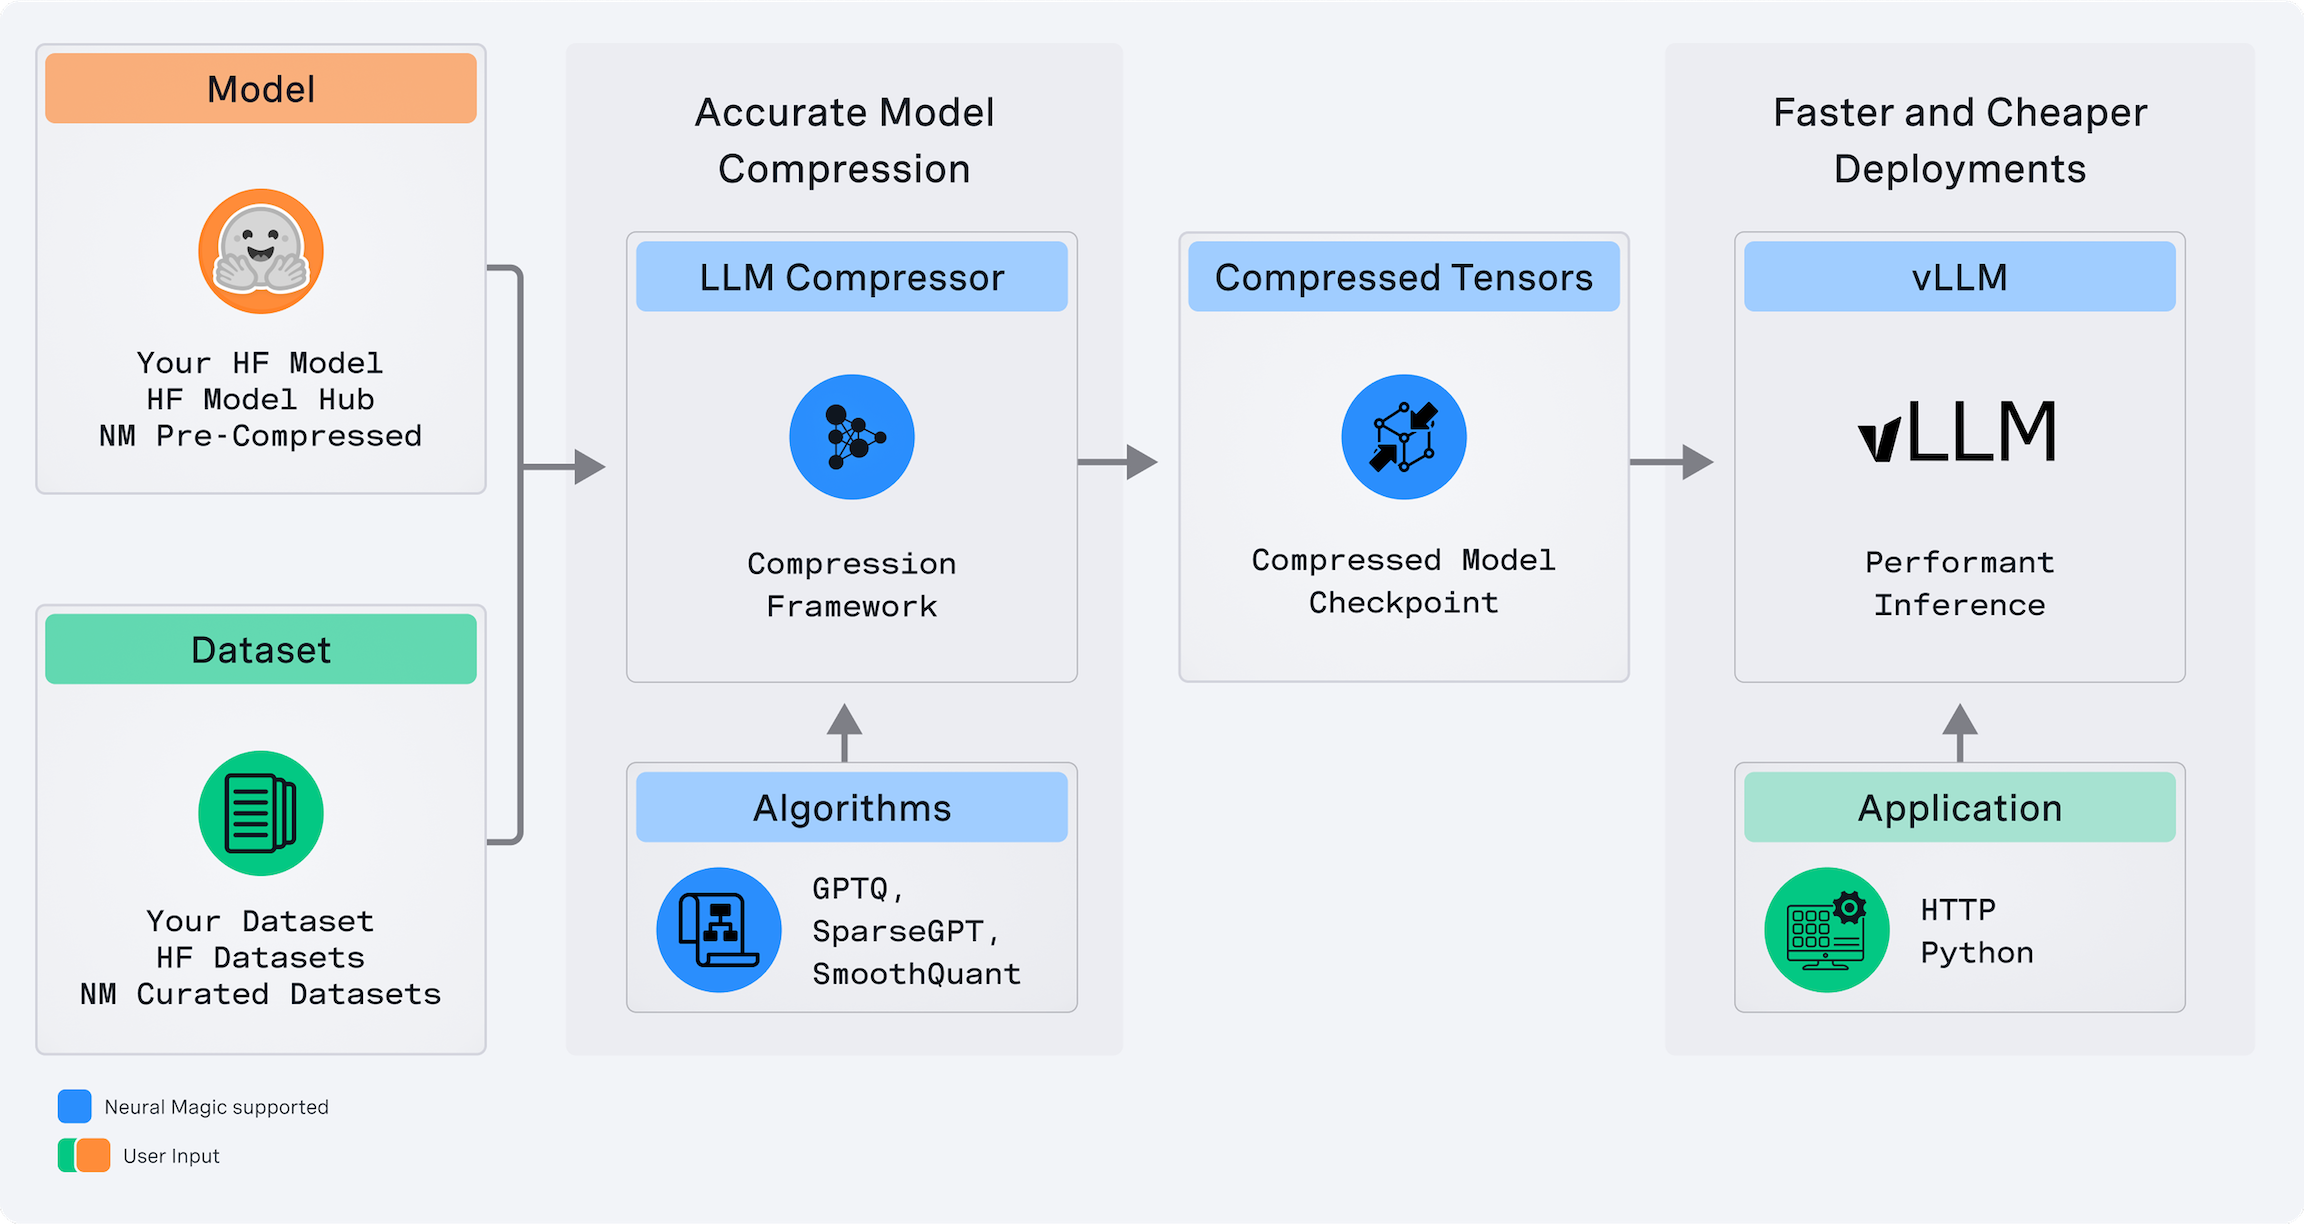
LLM Compressor is here: Faster inference with vLLM | Red Hat Developer
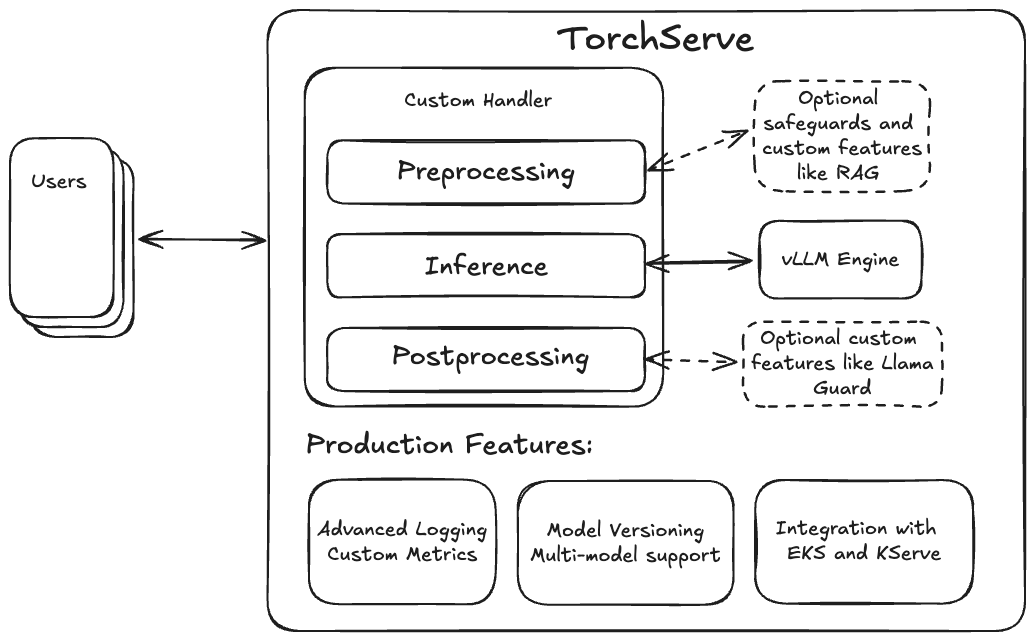
Deploying LLMs with TorchServe + vLLM – PyTorch
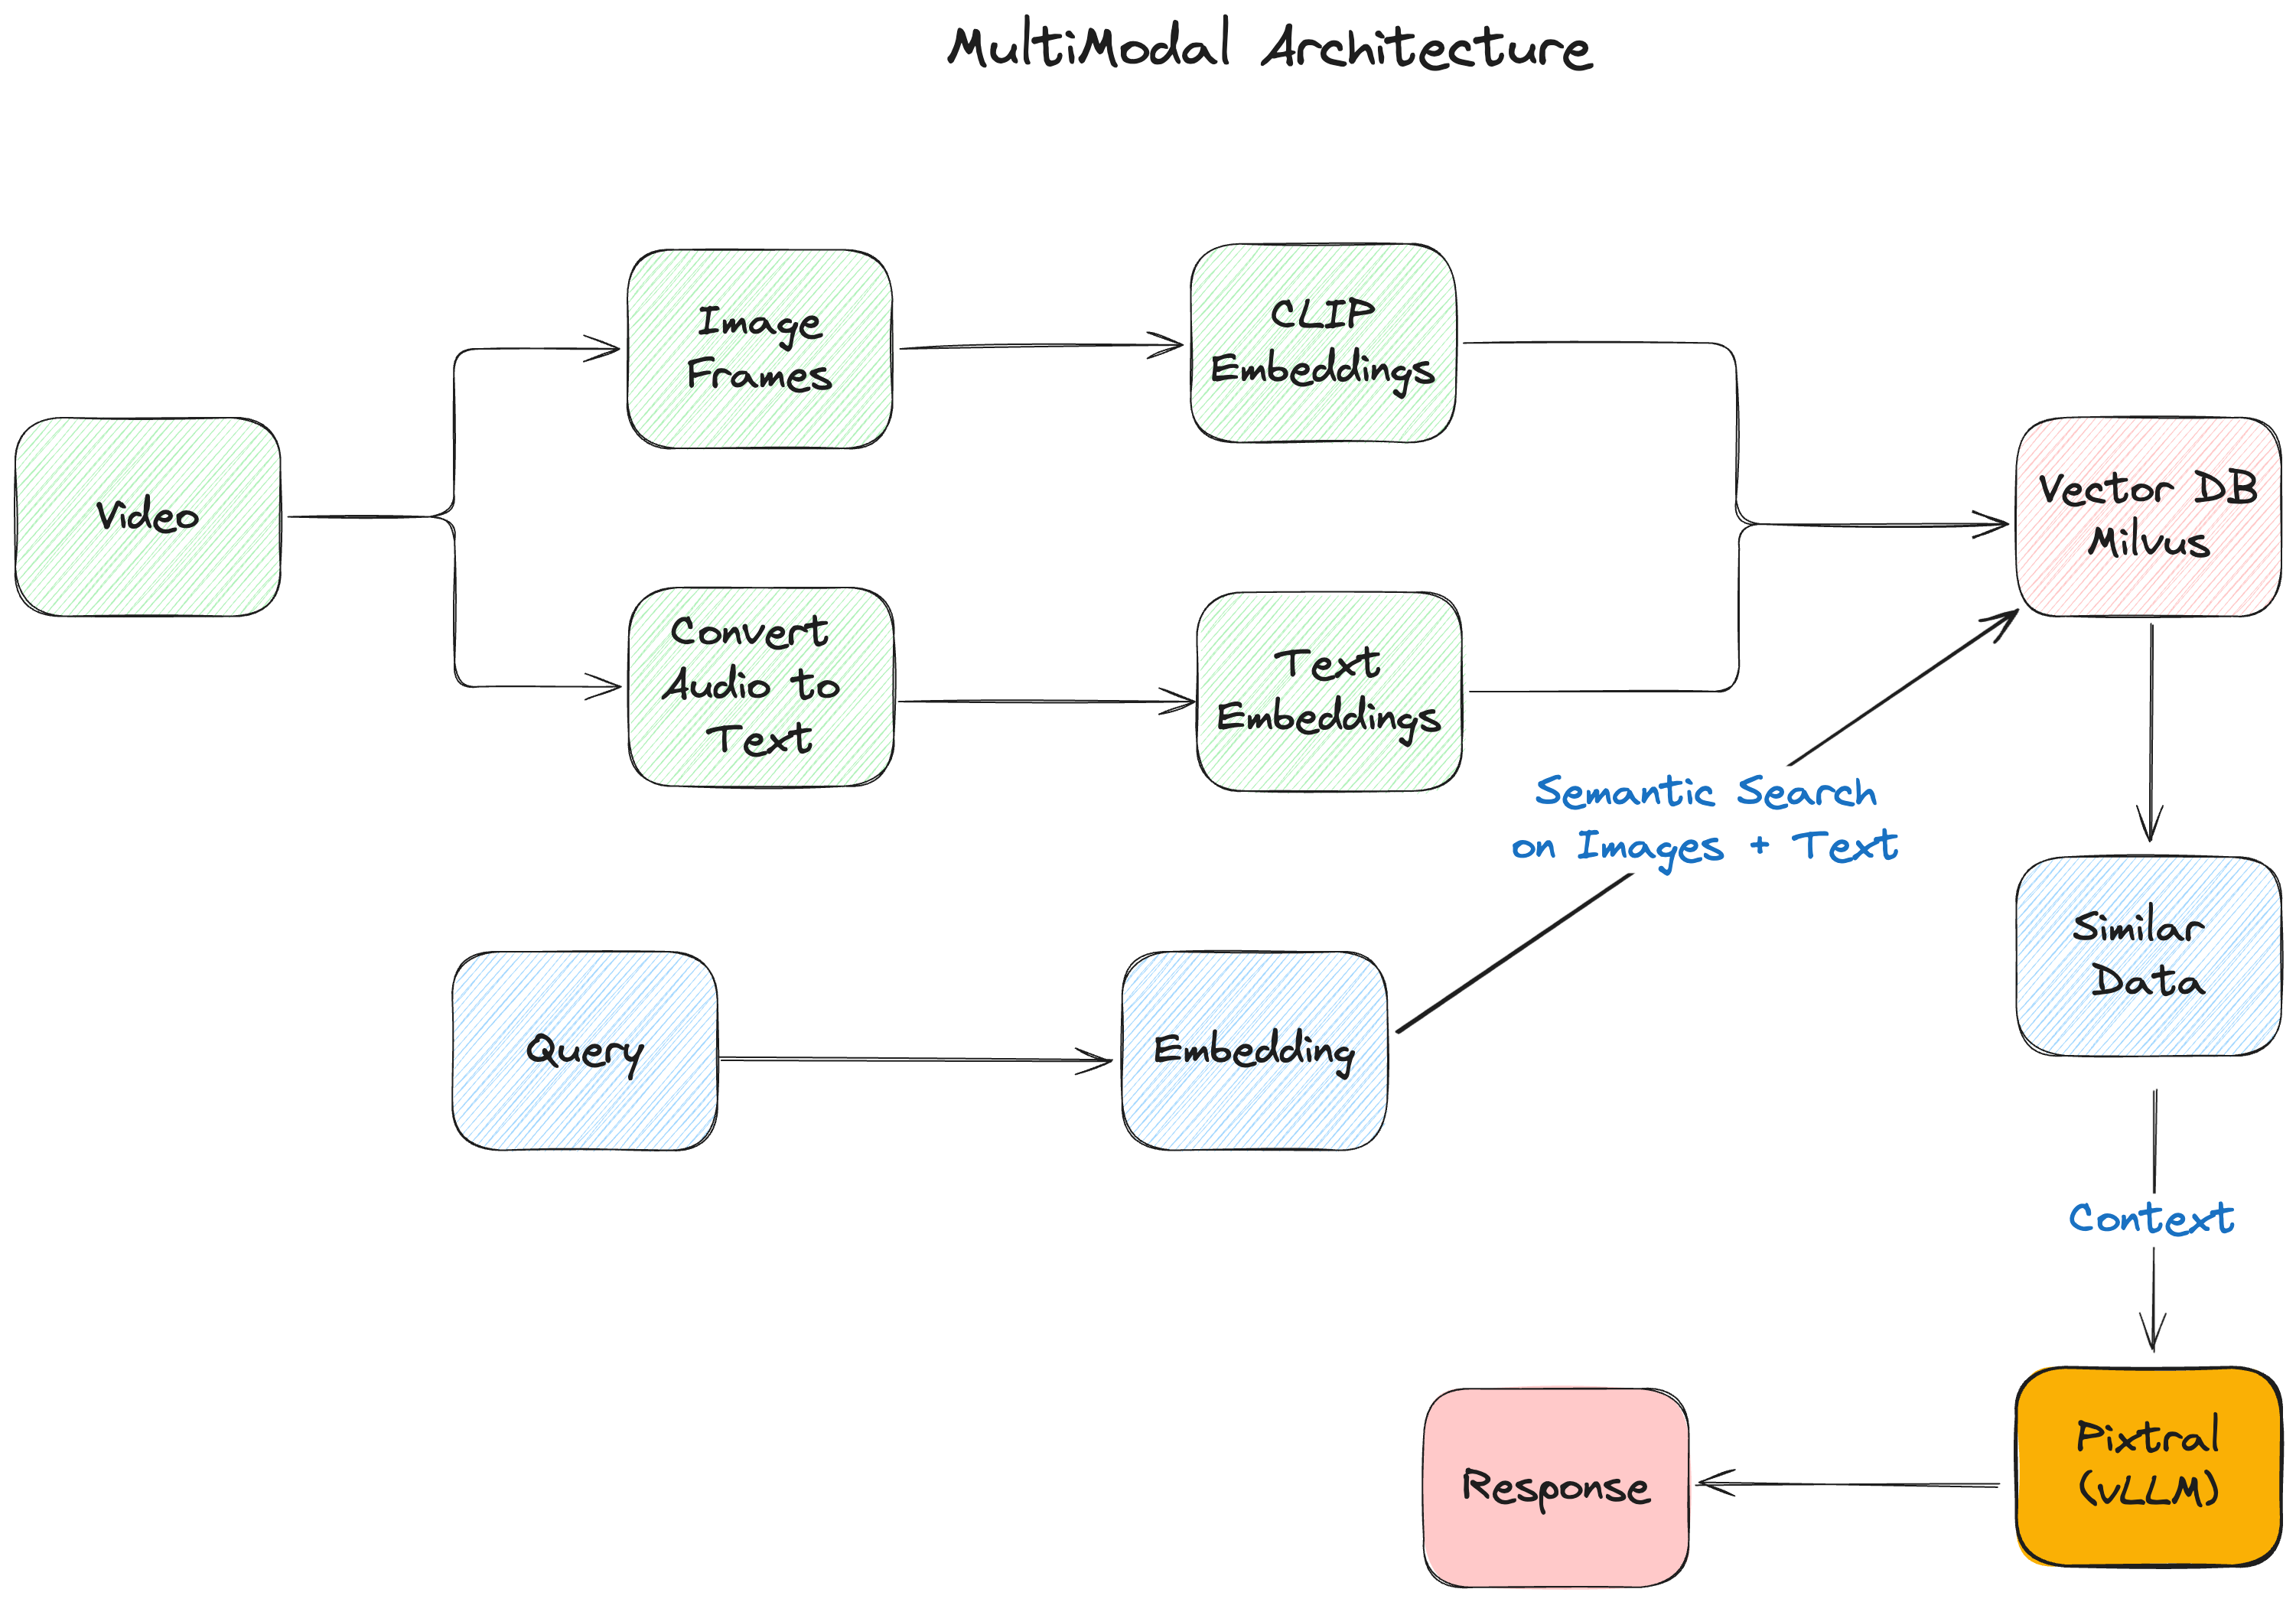
Deploying a Multimodal RAG System with vLLM and Milvus - Zilliz blog
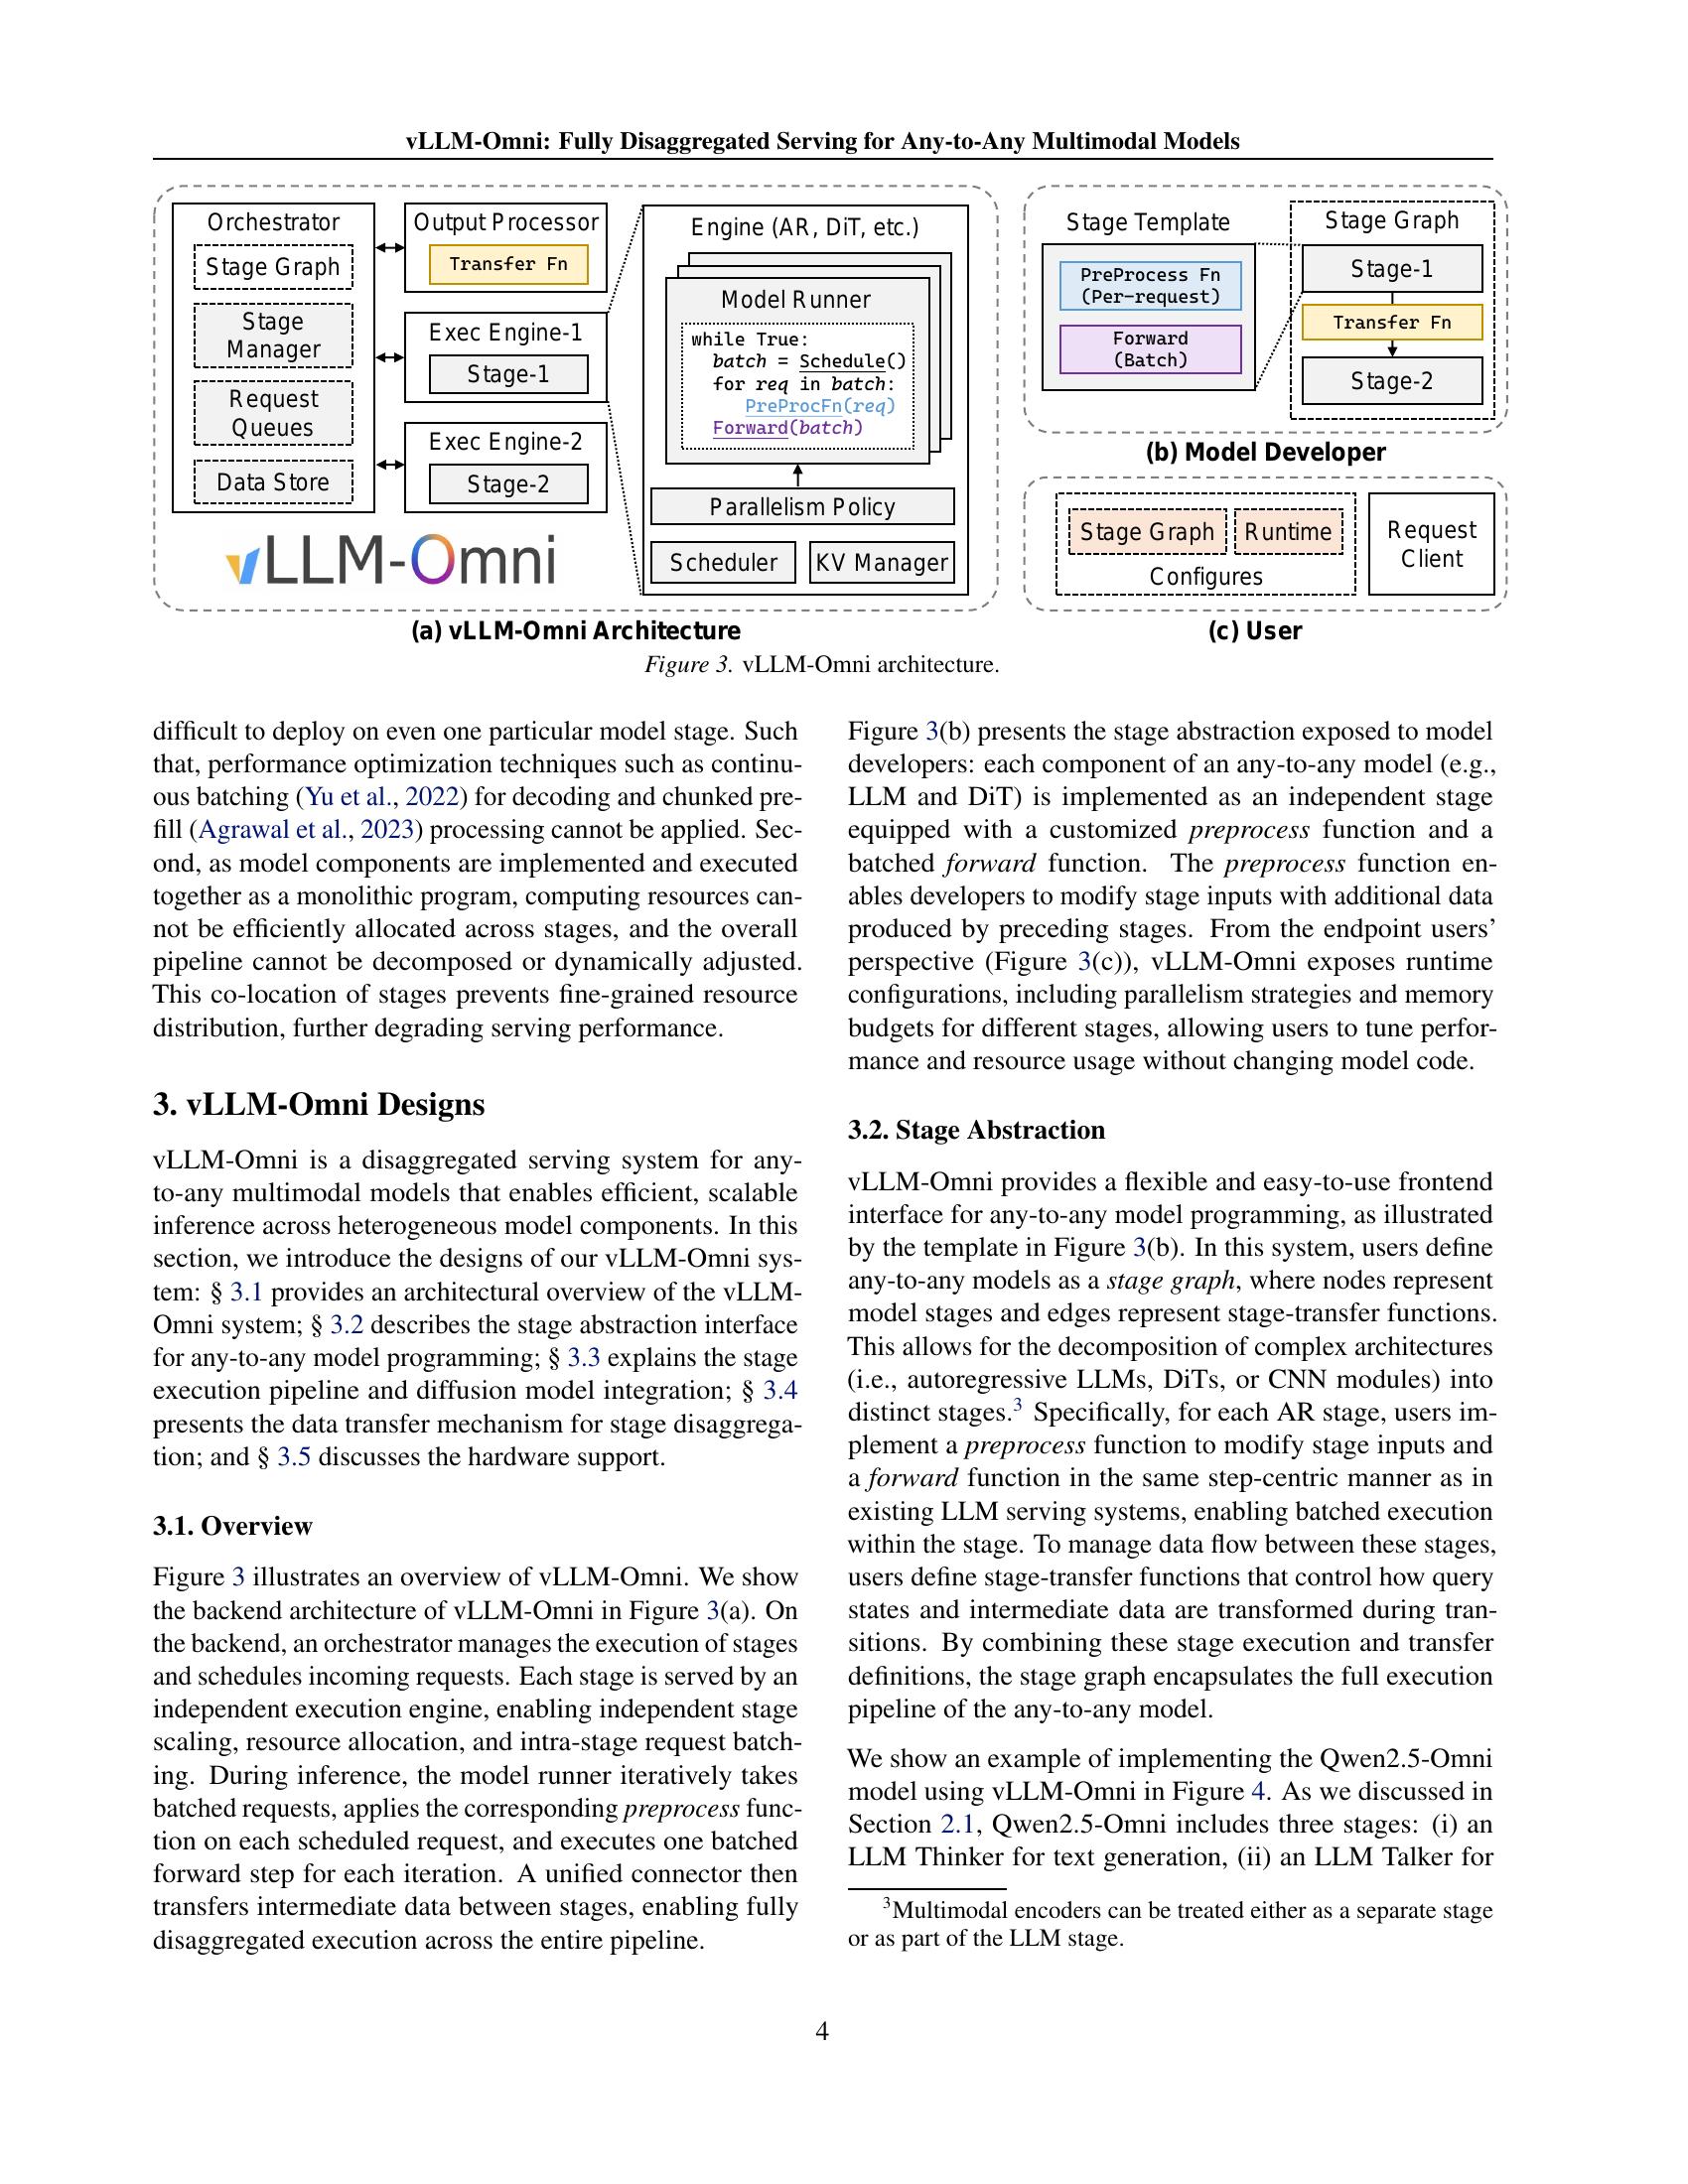
vLLM-Omni: Fully Disaggregated Serving for Any-to-Any Multimodal Models ...
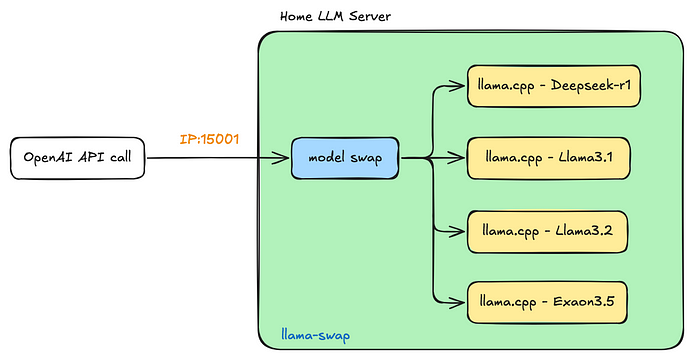
LLM inference engines performance testing: SGLang VS. vLLM | by ...

Beyond the Model: How vLLM Powers Enterprise-Scale LLM Serving | by ...

Comparing two LLM serving frameworks: Friendli Inference vs. vLLM
Encoder Disaggregation for Scalable Multimodal Model Serving | vLLM Blog
Advertisement Space (336x280)

Unlocking Enterprise AI with Gaudi 3: Model Serving and Fine-Tuning at ...
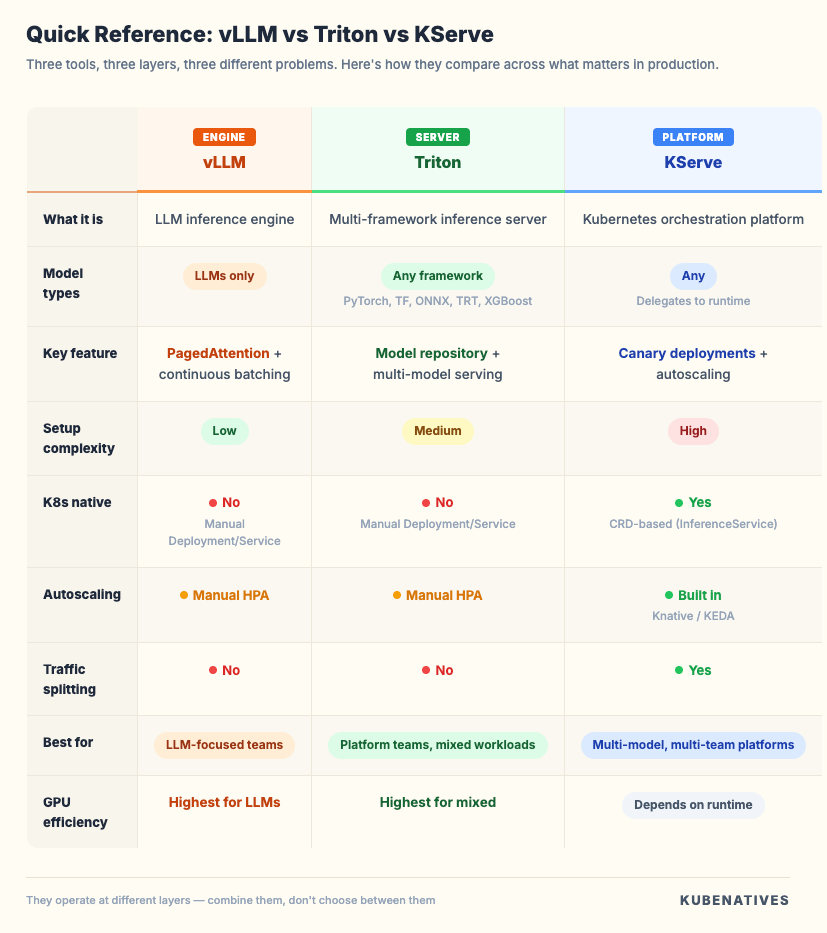
vLLM vs Triton vs KServe: Model Serving on Kubernetes
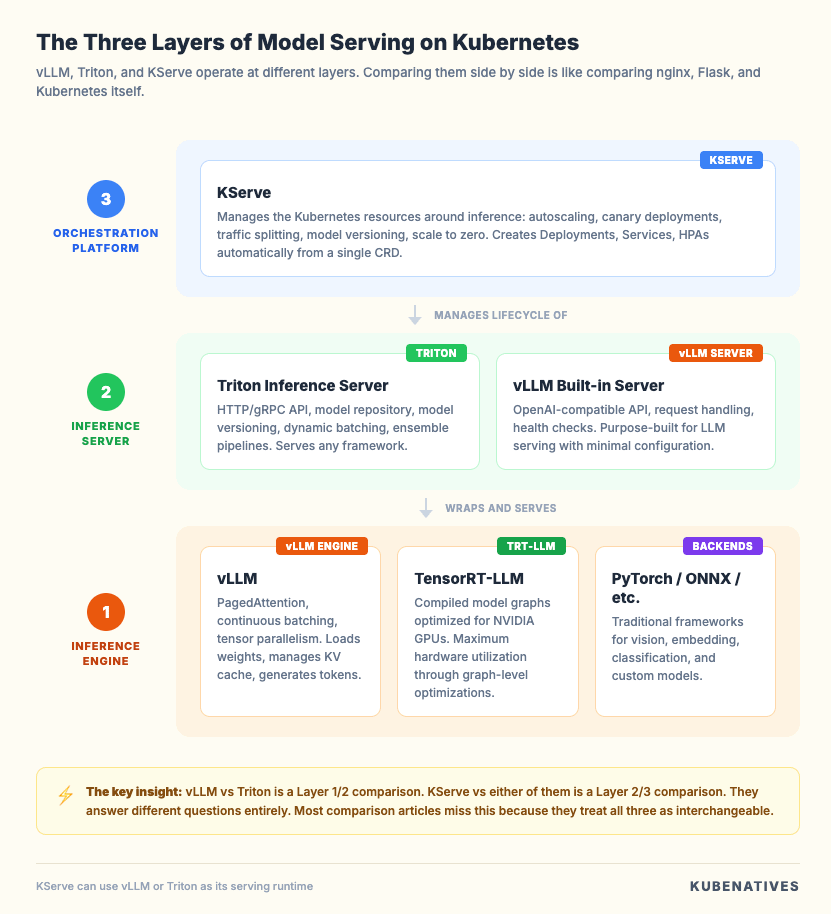
vLLM vs Triton vs KServe: Model Serving on Kubernetes

vLLM-Omni: Fully Disaggregated Serving for Any-to-Any Multimodal Models ...
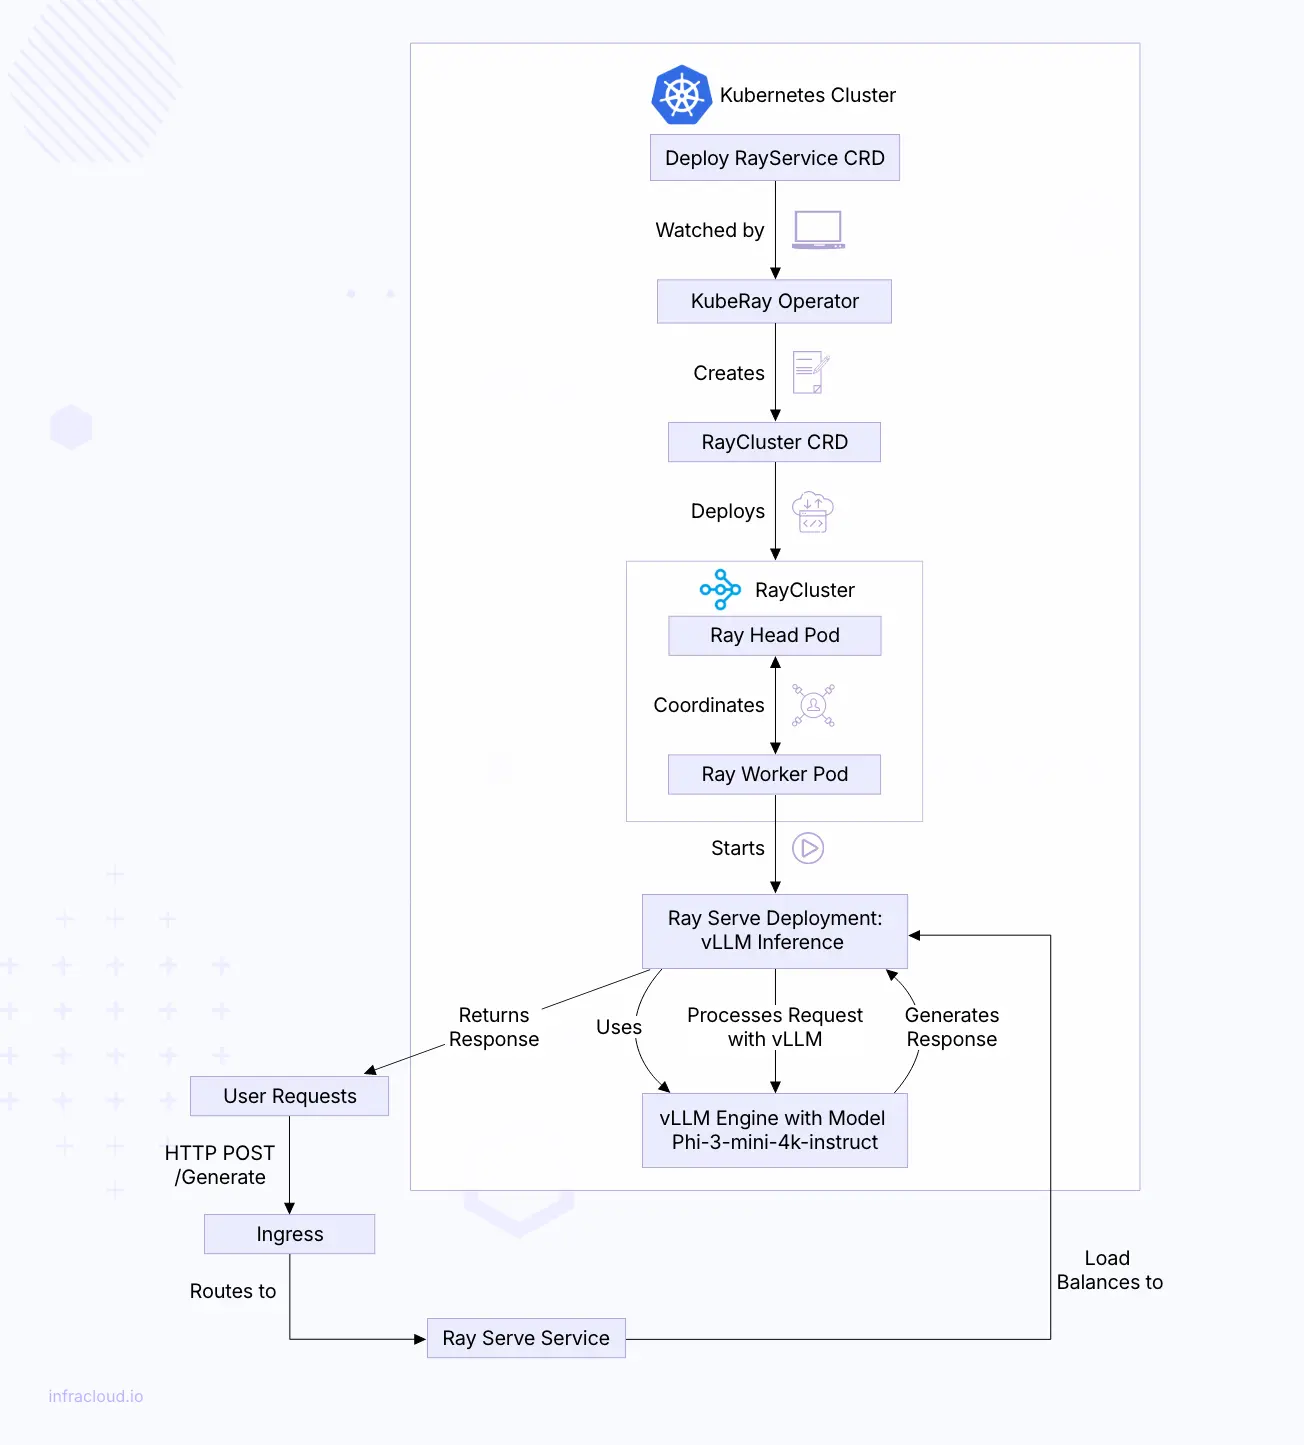
Running Phi 3 with vLLM and Ray Serve

Simplifying Model Serving with Kubernetes and Ray: Inside DoubleVerify ...