
Serving Models With Vllm Vllm Projectspeculators Deepwiki
Serving Models with vLLM | vllm-project/speculators | DeepWiki
Serving multiple models in vLLM with single or multiple engines · Issue ...
Serving DeepSeek Models on Vast.ai with vLLM and Langchain!

Serving Large Language Models with vLLM on AMD ROCm GPUs | by Trade ...

Serving DeepSeek Models on Vast.ai with vLLM and Langchain!

Serving AI Models At Scale With Vllm
Free Video: Improve AI Inference - Serving Models With KServe and VLLM ...
OpenShift AI Model Serving with vLLM (2026 Guide)
[Usage]: vLLM serving with local model · Issue #12378 · vllm-project ...
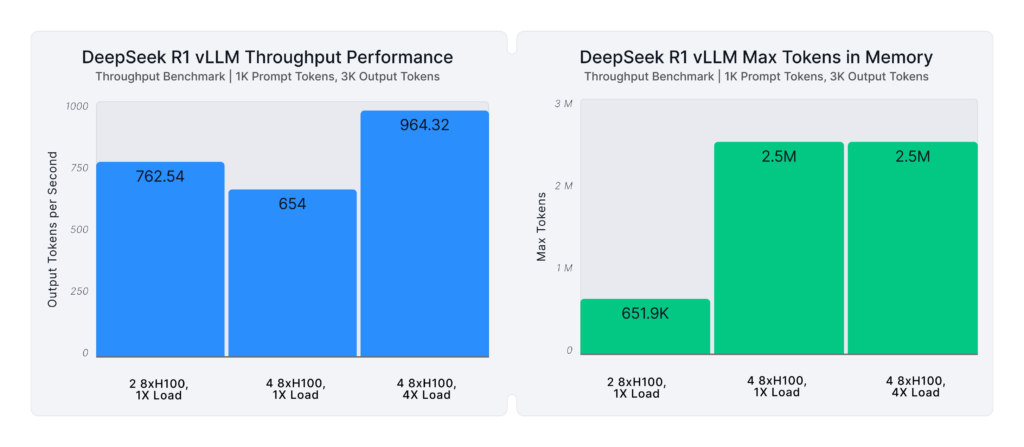
Enhancing DeepSeek models with MLA and FP8 optimizations in vLLM
Advertisement Space (300x250)
Ray Serve LLM on Anyscale: Wide-EP and Disaggregated Serving with vLLM
Now Serving NVIDIA Nemotron with vLLM | vLLM Blog
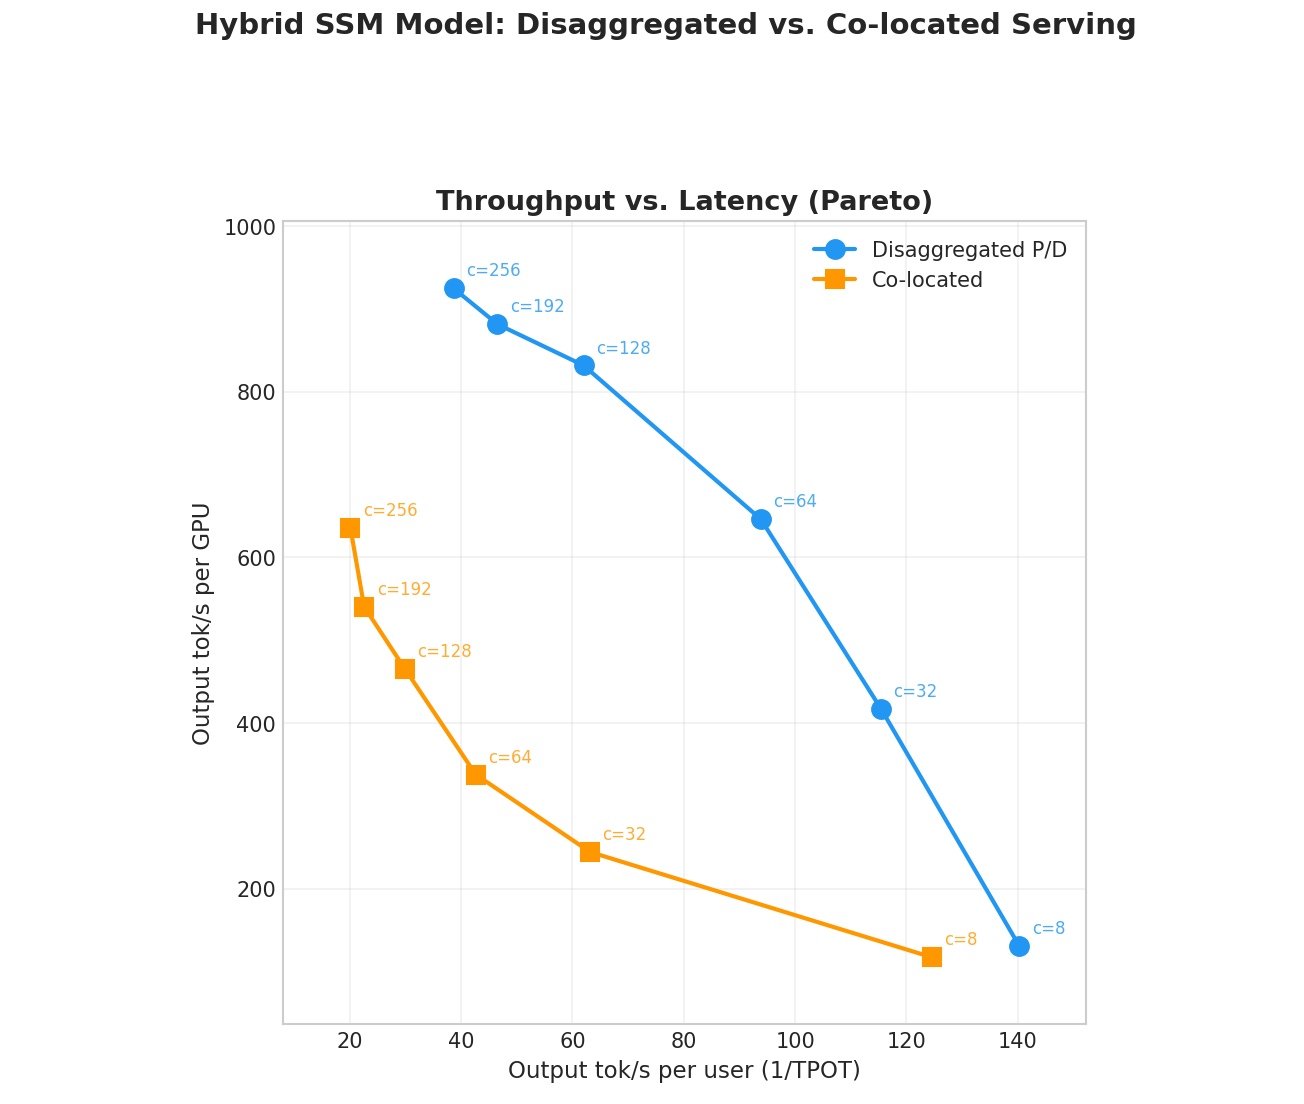
Disaggregated Serving for Hybrid SSM Models in vLLM | vLLM Blog
Optimizing Large Language Models with vLLM and Related Tools.pdf
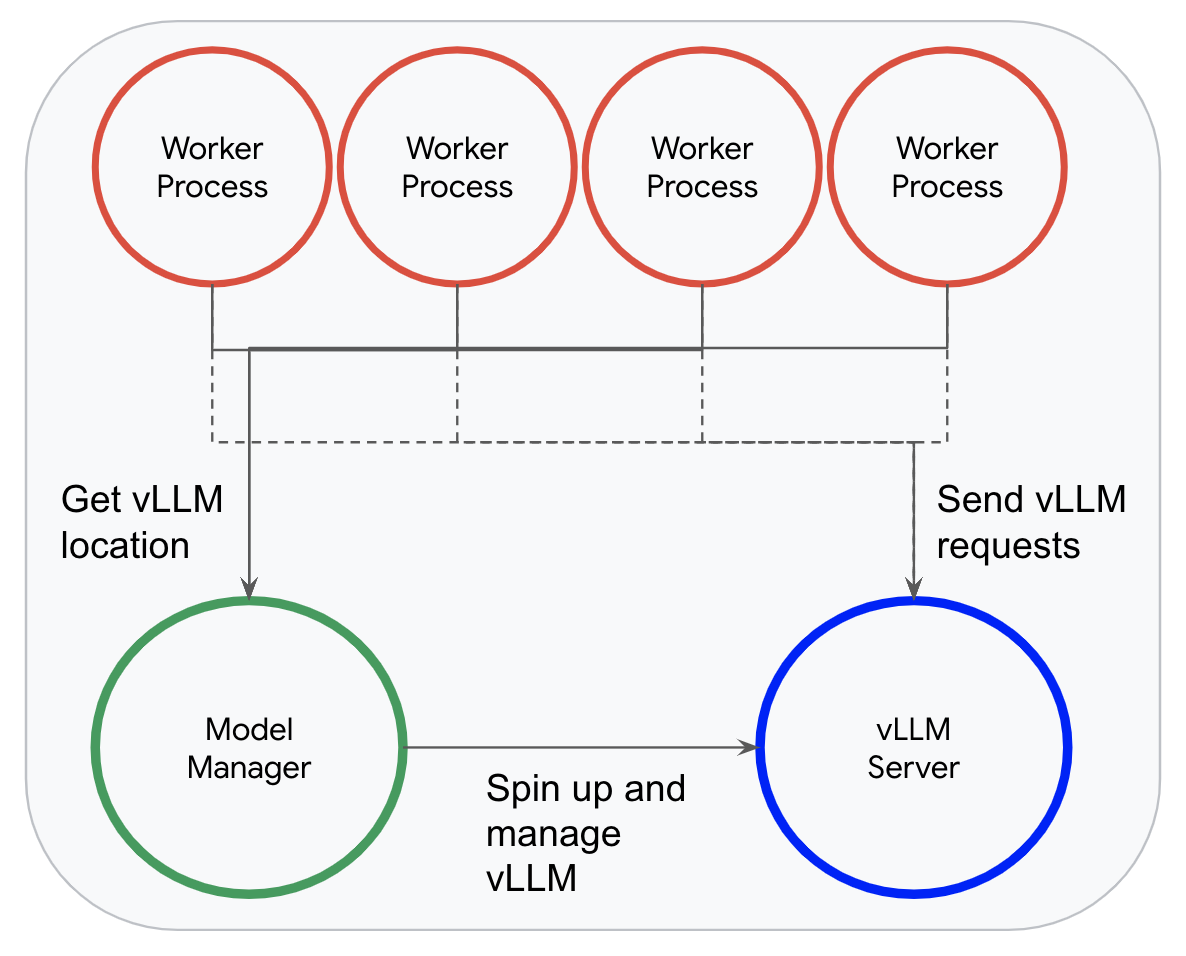
Inference with Gemma using Dataflow and vLLM - Google Developers Blog
Diving into speculative decoding training support for vLLM with ...

vLLM support for DeepSeek V4 base models is on the way! The V4 release ...

How vLLM solves LLM serving issues for AI apps | Aaroh Bhardwaj posted ...

vLLM Deployment Guide | MiniMax-AI/MiniMax-01 | DeepWiki

A Gentle Introduction to vLLM for Serving - KDnuggets
Advertisement Space (336x280)
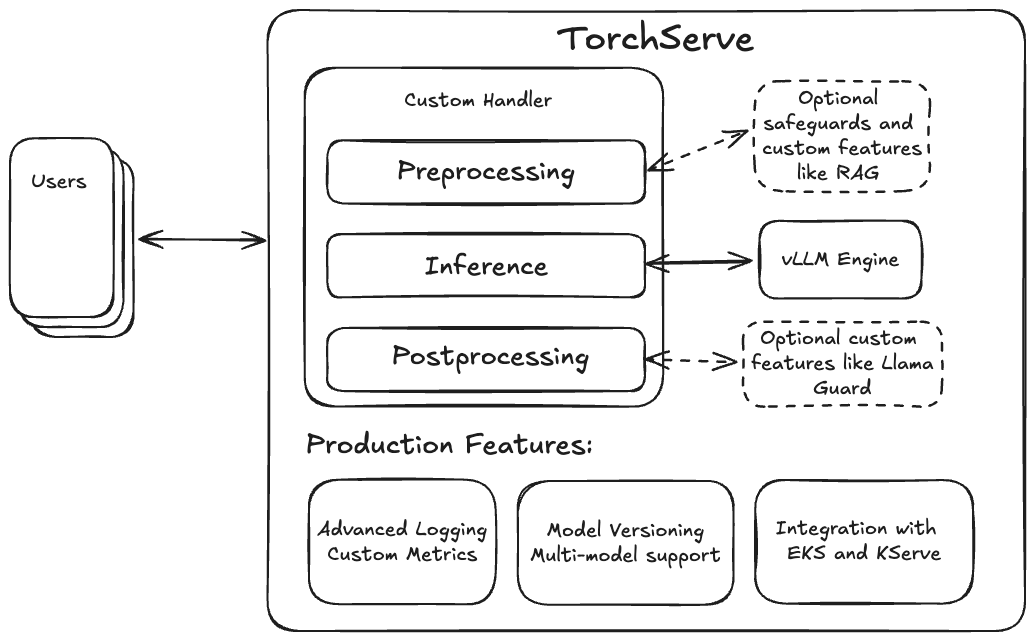
Deploying LLMs with TorchServe + vLLM – PyTorch

A Brief Introduction to Optimized Batched Inference with vLLM | by ...

PagedAttention and vLLM serve Large Language Models faster and cheaper ...
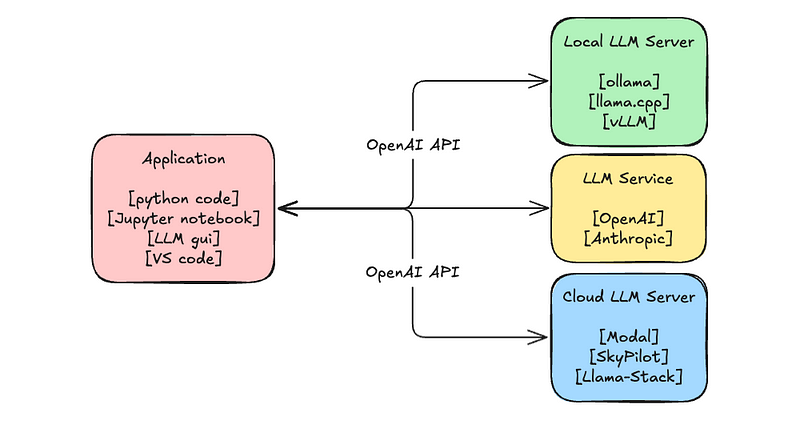
A Brief Introduction to Optimized Batched Inference with vLLM | by ...

vLLM Large Scale Serving: DeepSeek @ 2.2k tok/s/H200 with Wide-EP ...

How-to Install vLLM and Serve AI Models Locally – Step by Step Easy ...
vLLM Tutorial: Fast, OpenAI‑Compatible LLM Serving Guide
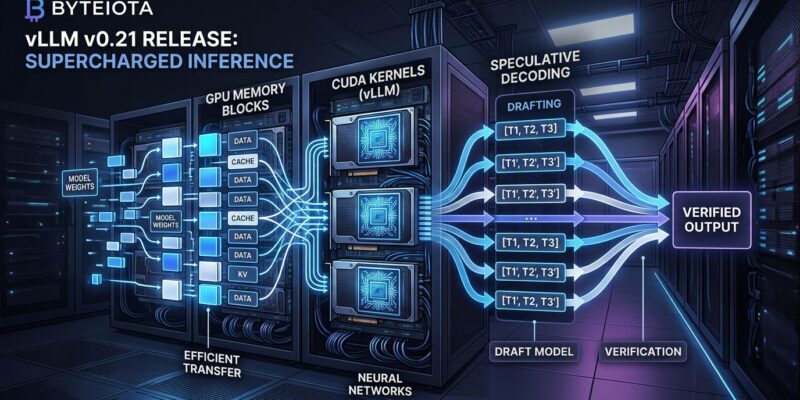
vLLM v0.21.0: Spec Decode for Reasoning Models — Upgrade Now | byteiota
Encoder Disaggregation for Scalable Multimodal Model Serving | vLLM Blog
vLLM Large Scale Serving: DeepSeek @ 2.2k tok/s/H200 with Wide-EP ...
Advertisement Space (336x280)

Deploying a Model with vLLM :: vLLM Master Class
Can vllm serving clients by using multiple model instances? · vllm ...

Deploy DeepSeek-R1 with the vLLM V1 engine and build an AI-powered ...

Model Variant: Serving Multiple Models with Ease
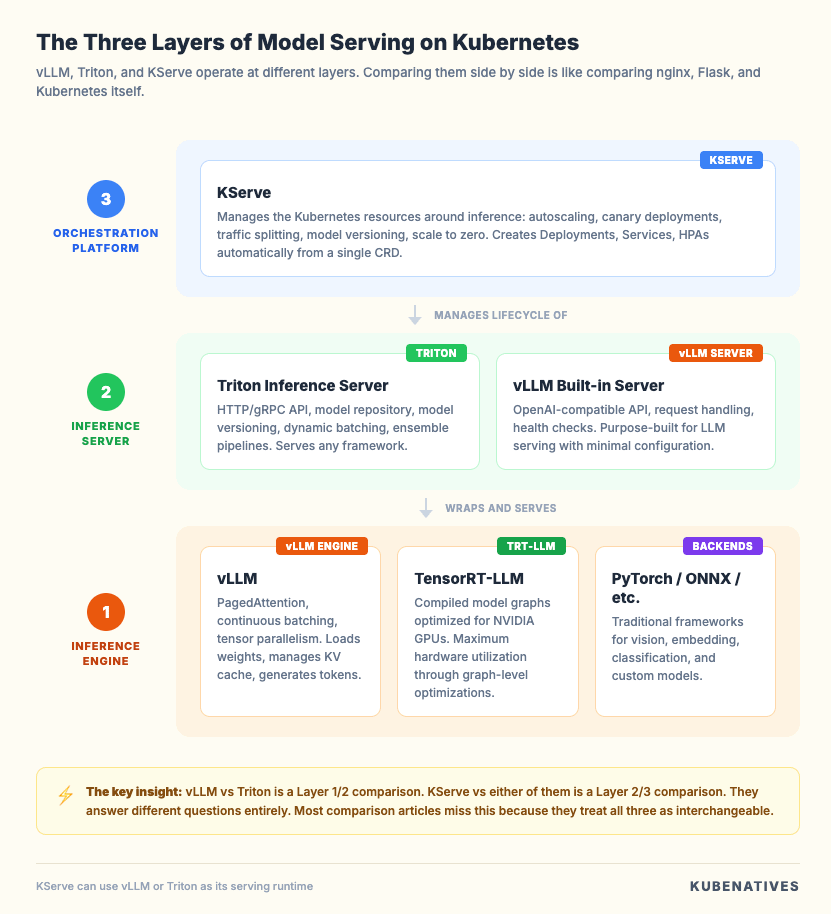
vLLM vs Triton vs KServe: Model Serving on Kubernetes
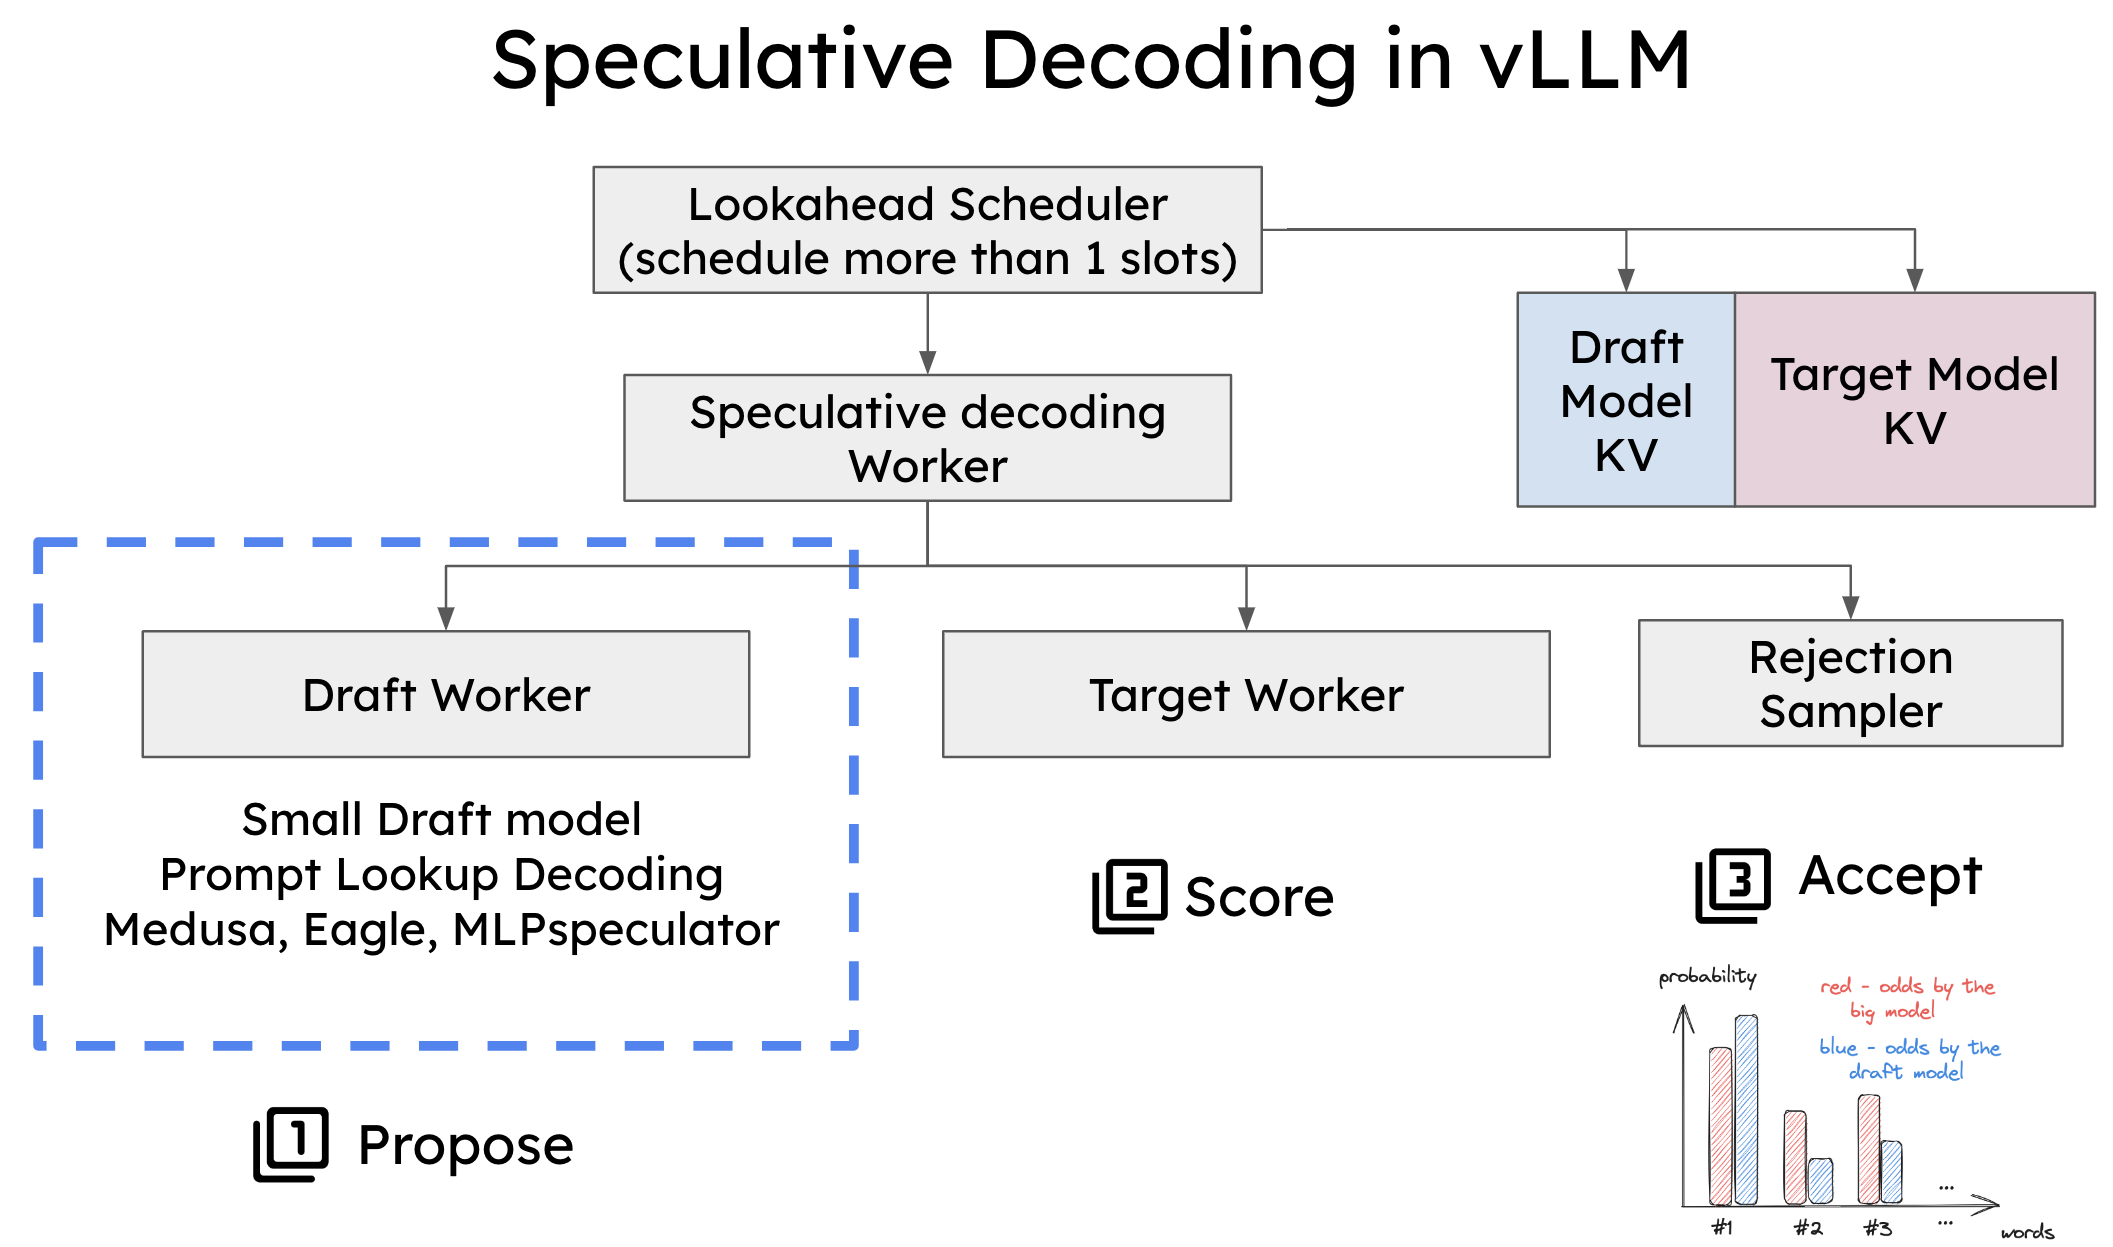
Speculative Decoding in vLLM | OpenLM.ai