
Specexec Massively Parallel Speculative Decoding For Interactive Llm
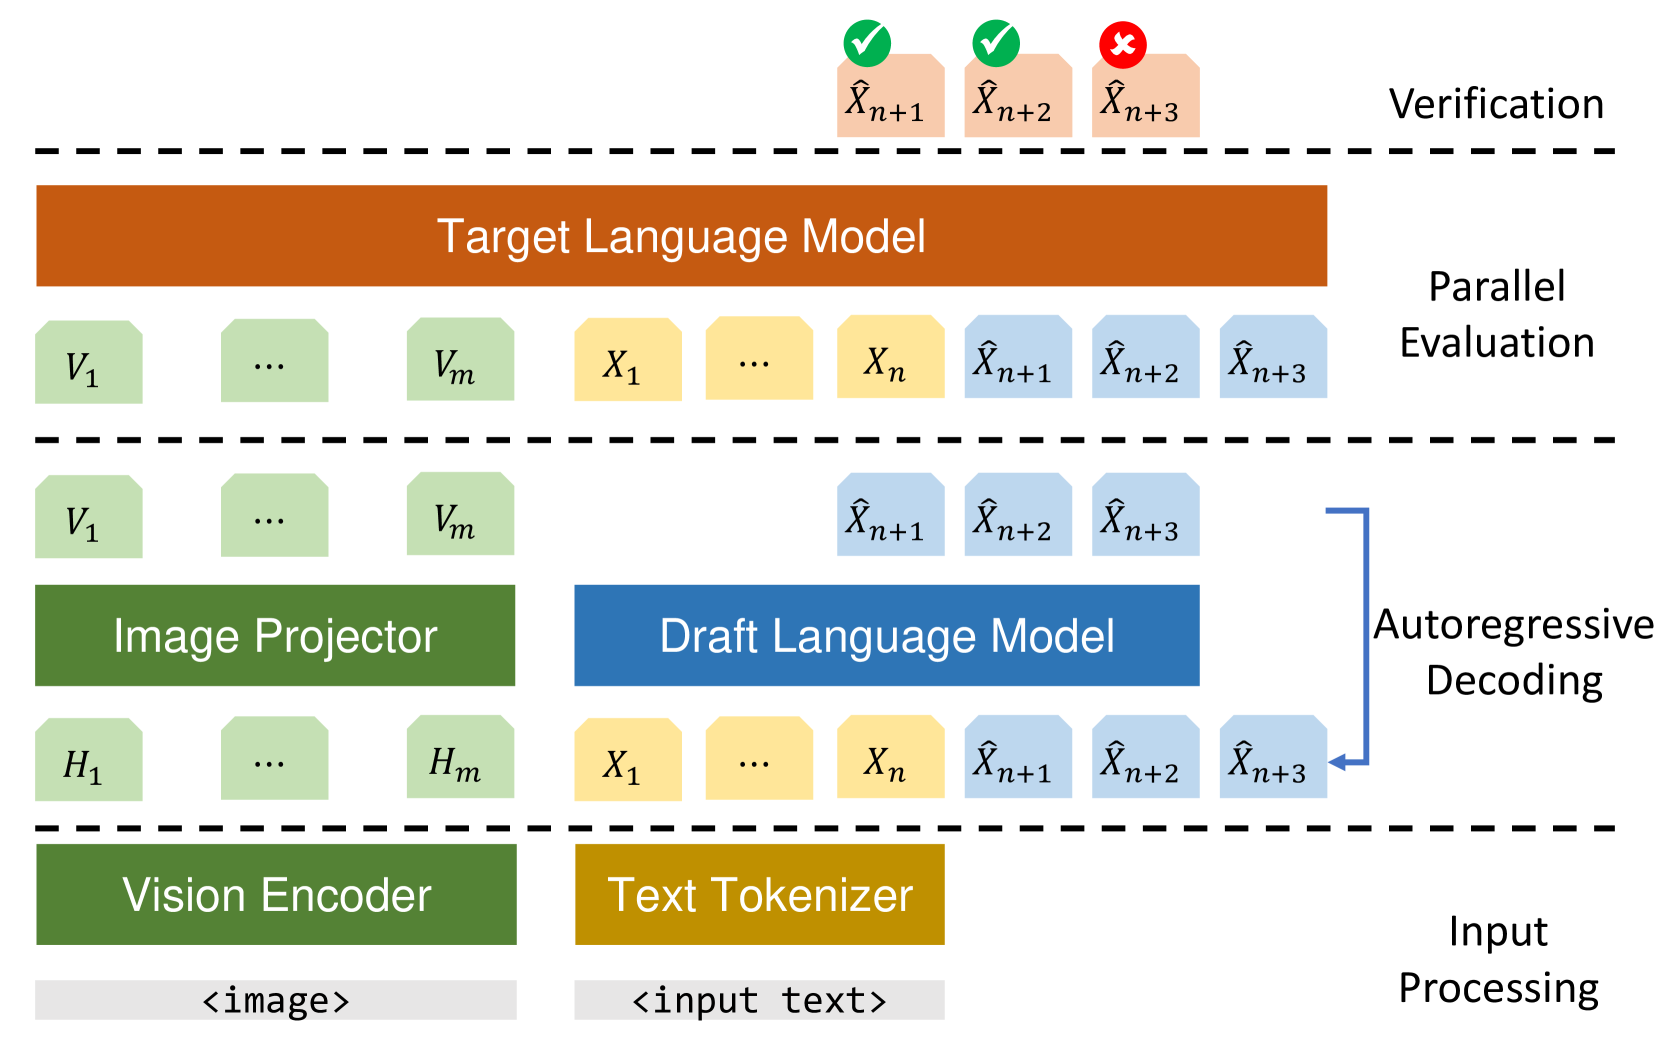
SpecExec: Massively Parallel Speculative Decoding for Interactive LLM ...
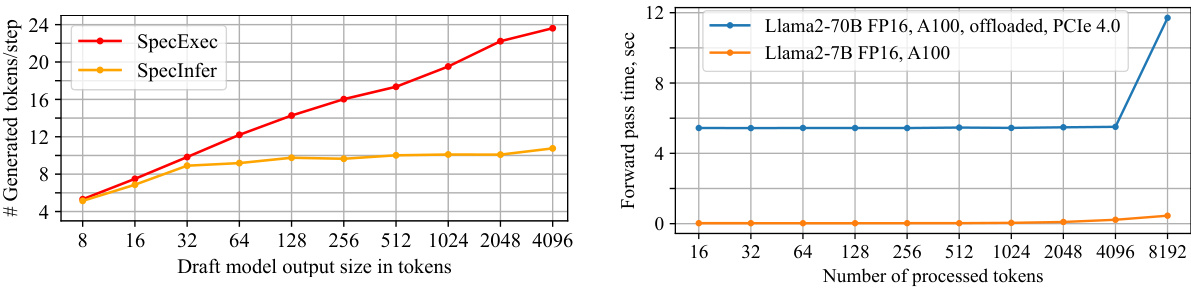
SpecExec: Massively Parallel Speculative Decoding For Interactive LLM ...

SpecExec: Massively Parallel Speculative Decoding for Interactive LLM ...
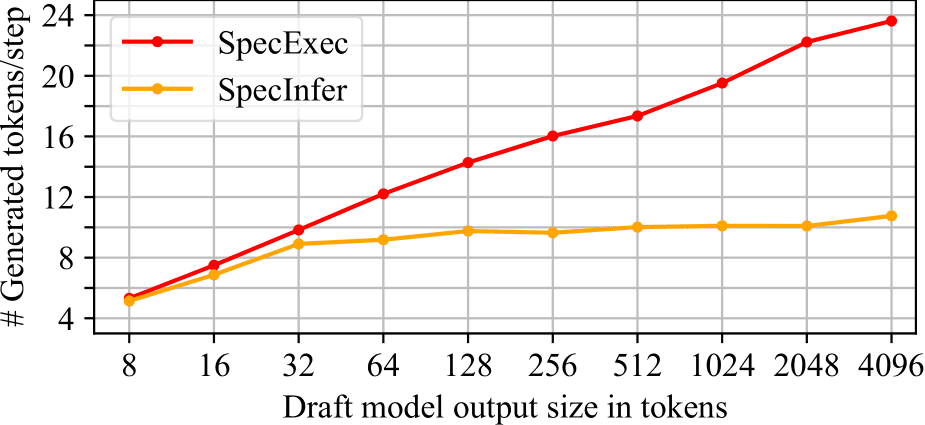
SpecExec: Massively Parallel Speculative Decoding for Interactive LLM ...
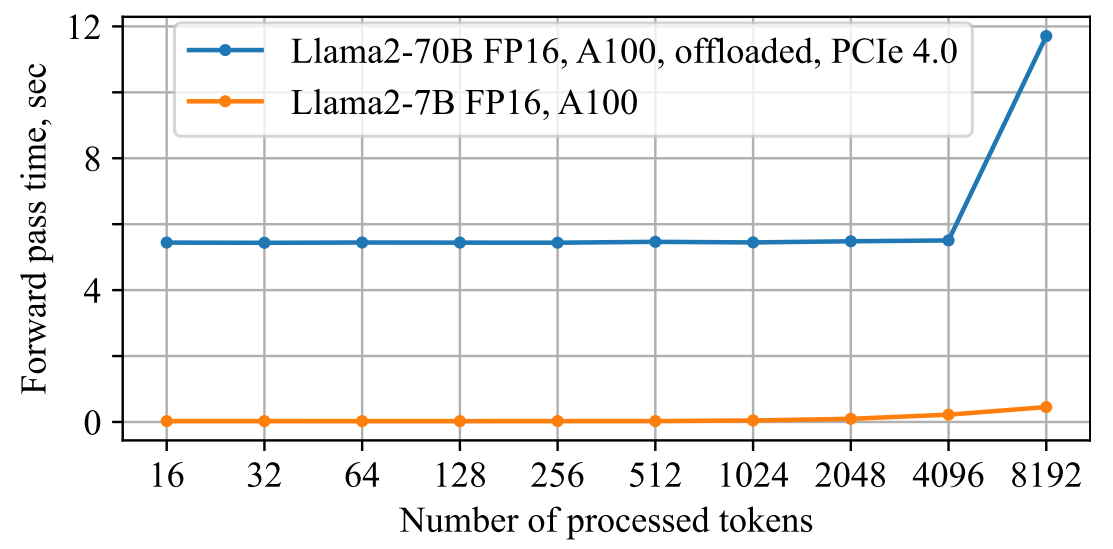
SpecExec: Massively Parallel Speculative Decoding for Interactive LLM ...
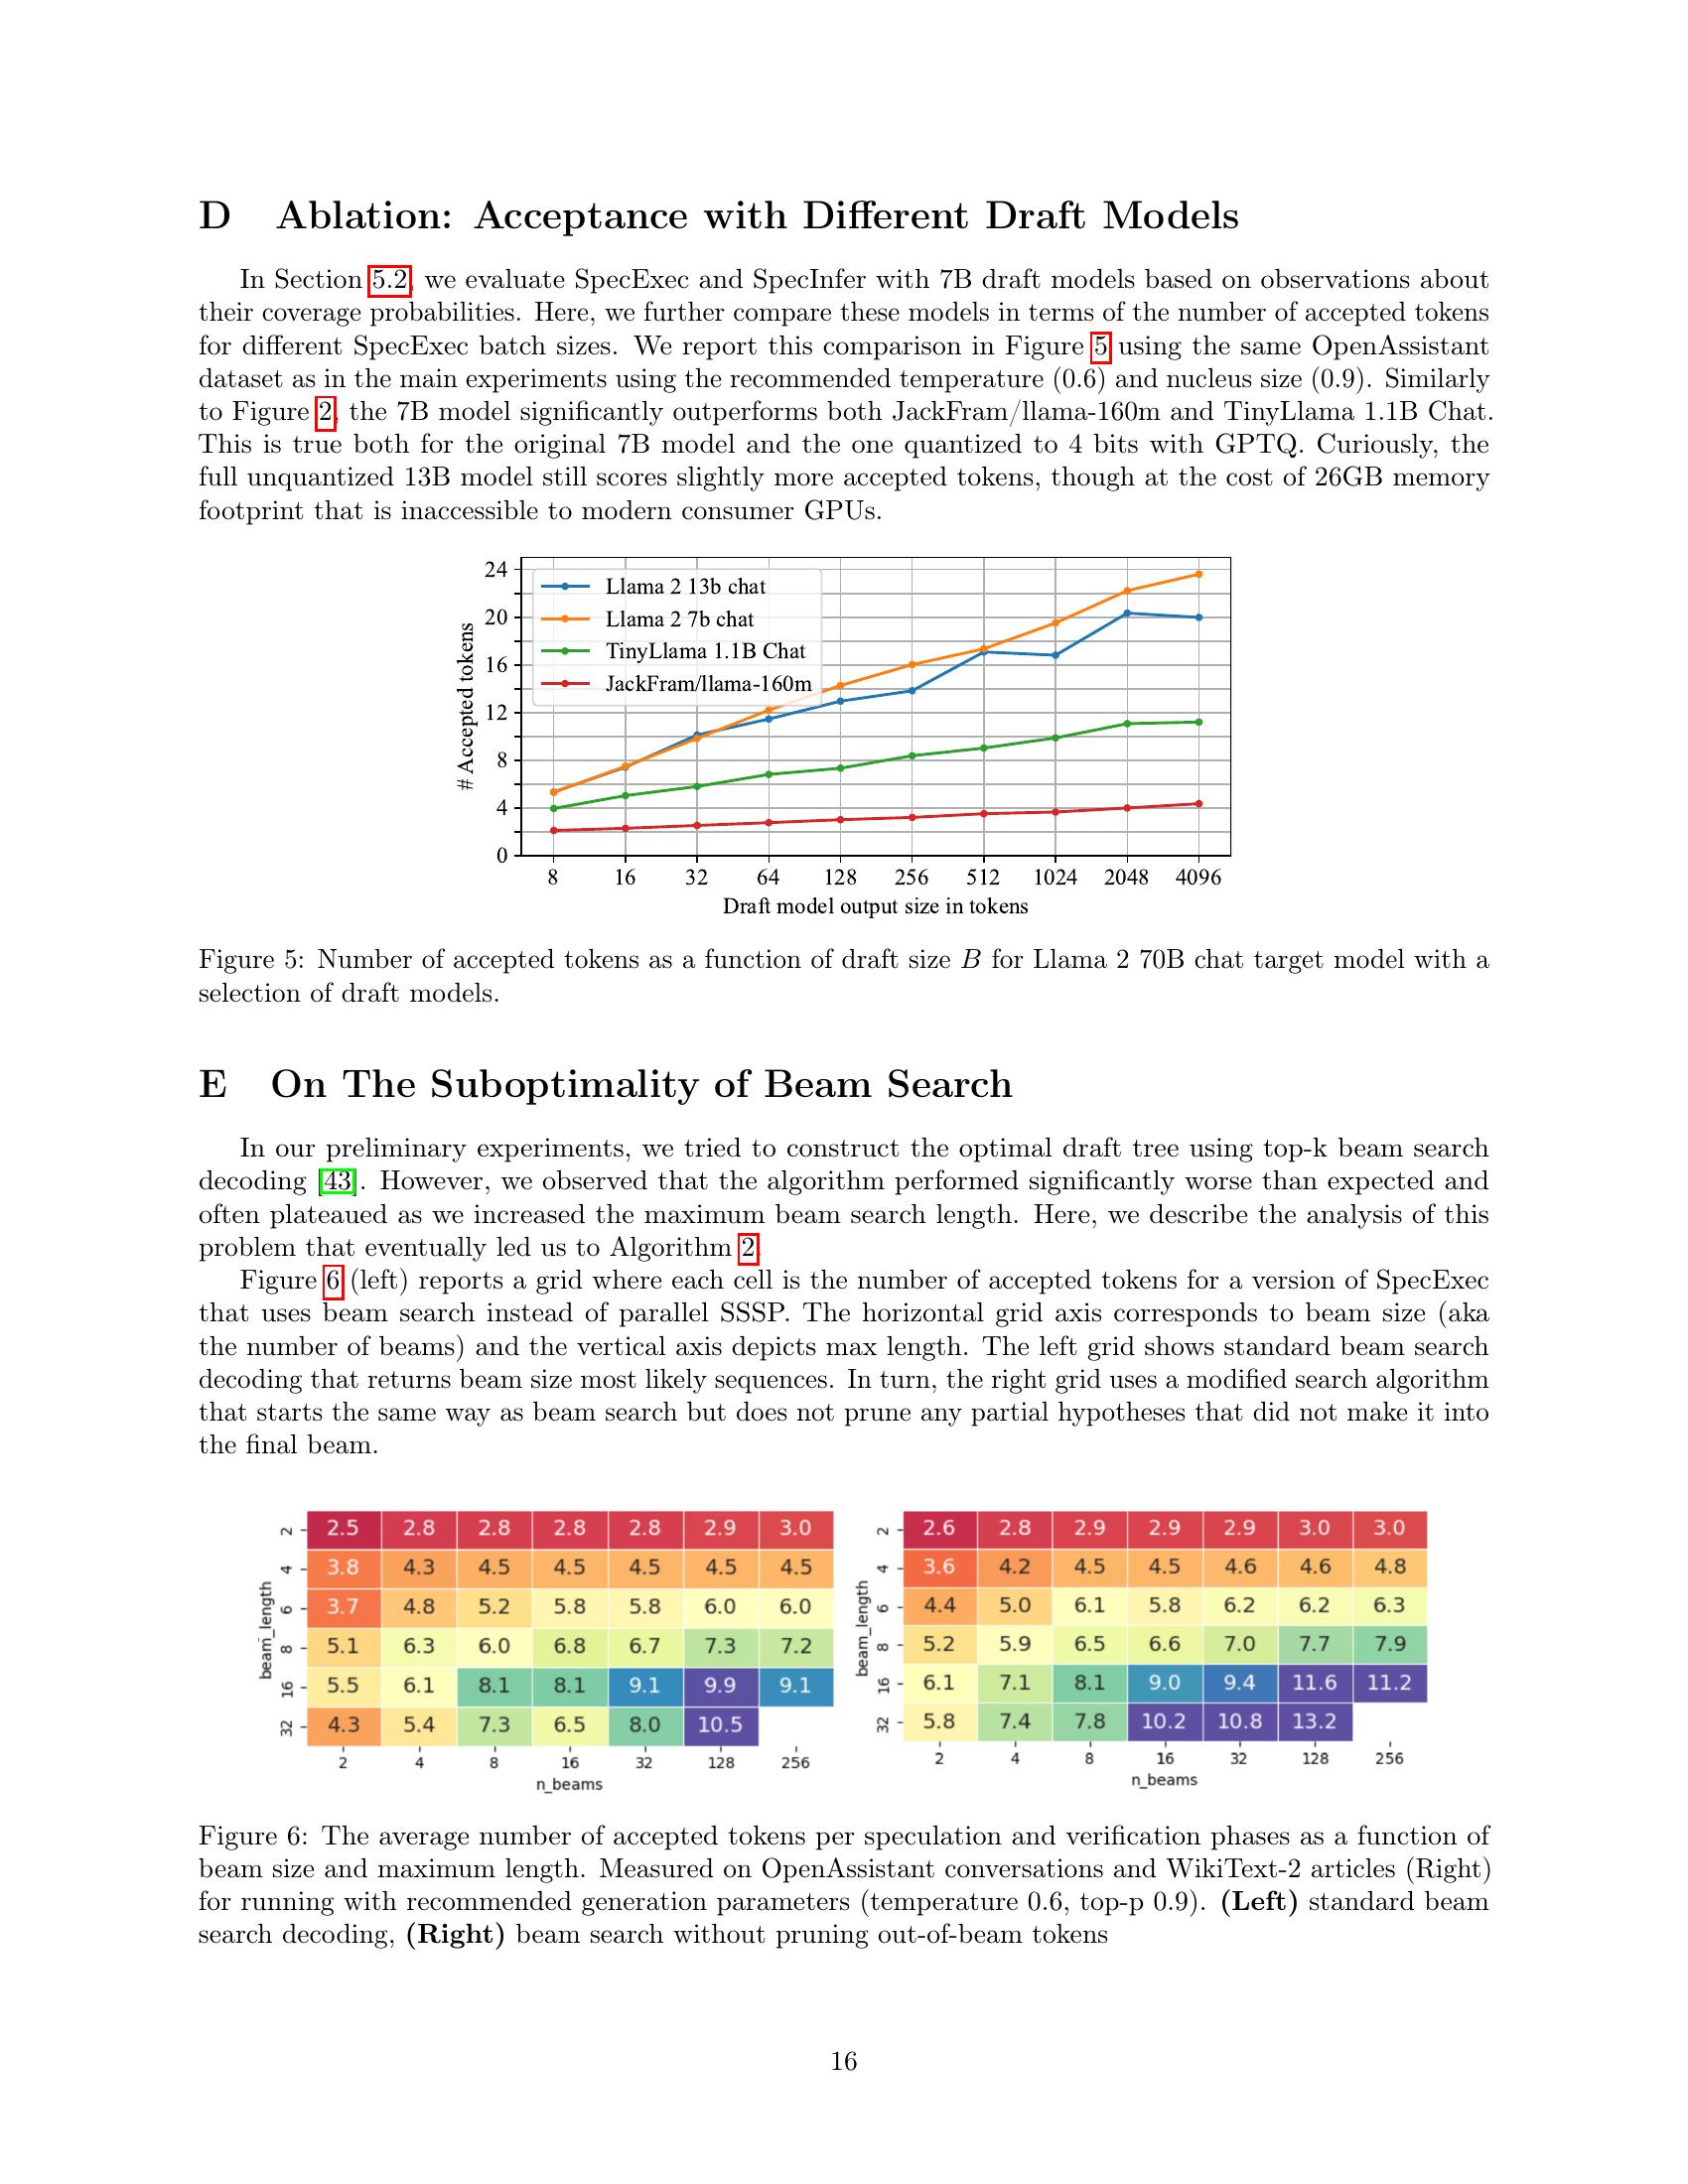
SpecExec: Massively Parallel Speculative Decoding for Interactive LLM ...

SpecExec: Massively Parallel Speculative Decoding for Interactive LLM ...

SpecExec: Massively Parallel Speculative Decoding for Interactive LLM ...
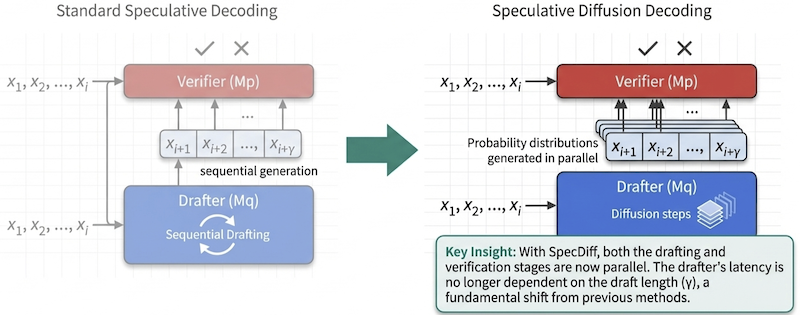
Massively Speeding up LLM inference with Speculative Diffusion Decoding ...
PSD paper — Parallel speculative decoding for diffusion LLMs — What ...
Advertisement Space (300x250)
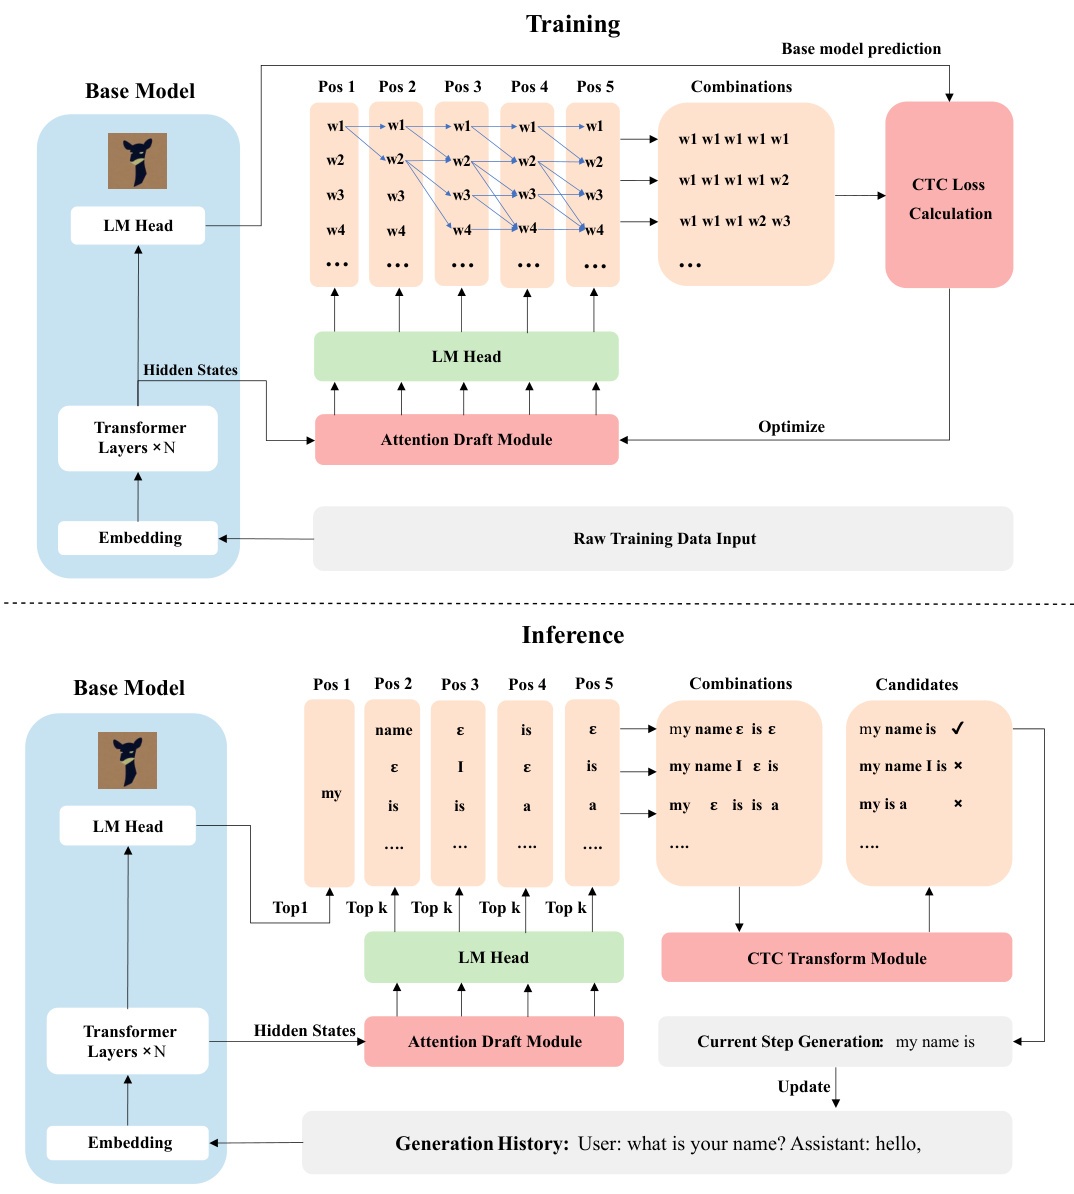
Speculative Decoding with CTC-based Draft Model for LLM Inference ...

[论文评述] Reward-Guided Speculative Decoding for Efficient LLM Reasoning

[논문 리뷰] ParallelSpec: Parallel Drafter for Efficient Speculative Decoding

[2503.10325] Collaborative Speculative Inference for Efficient LLM ...
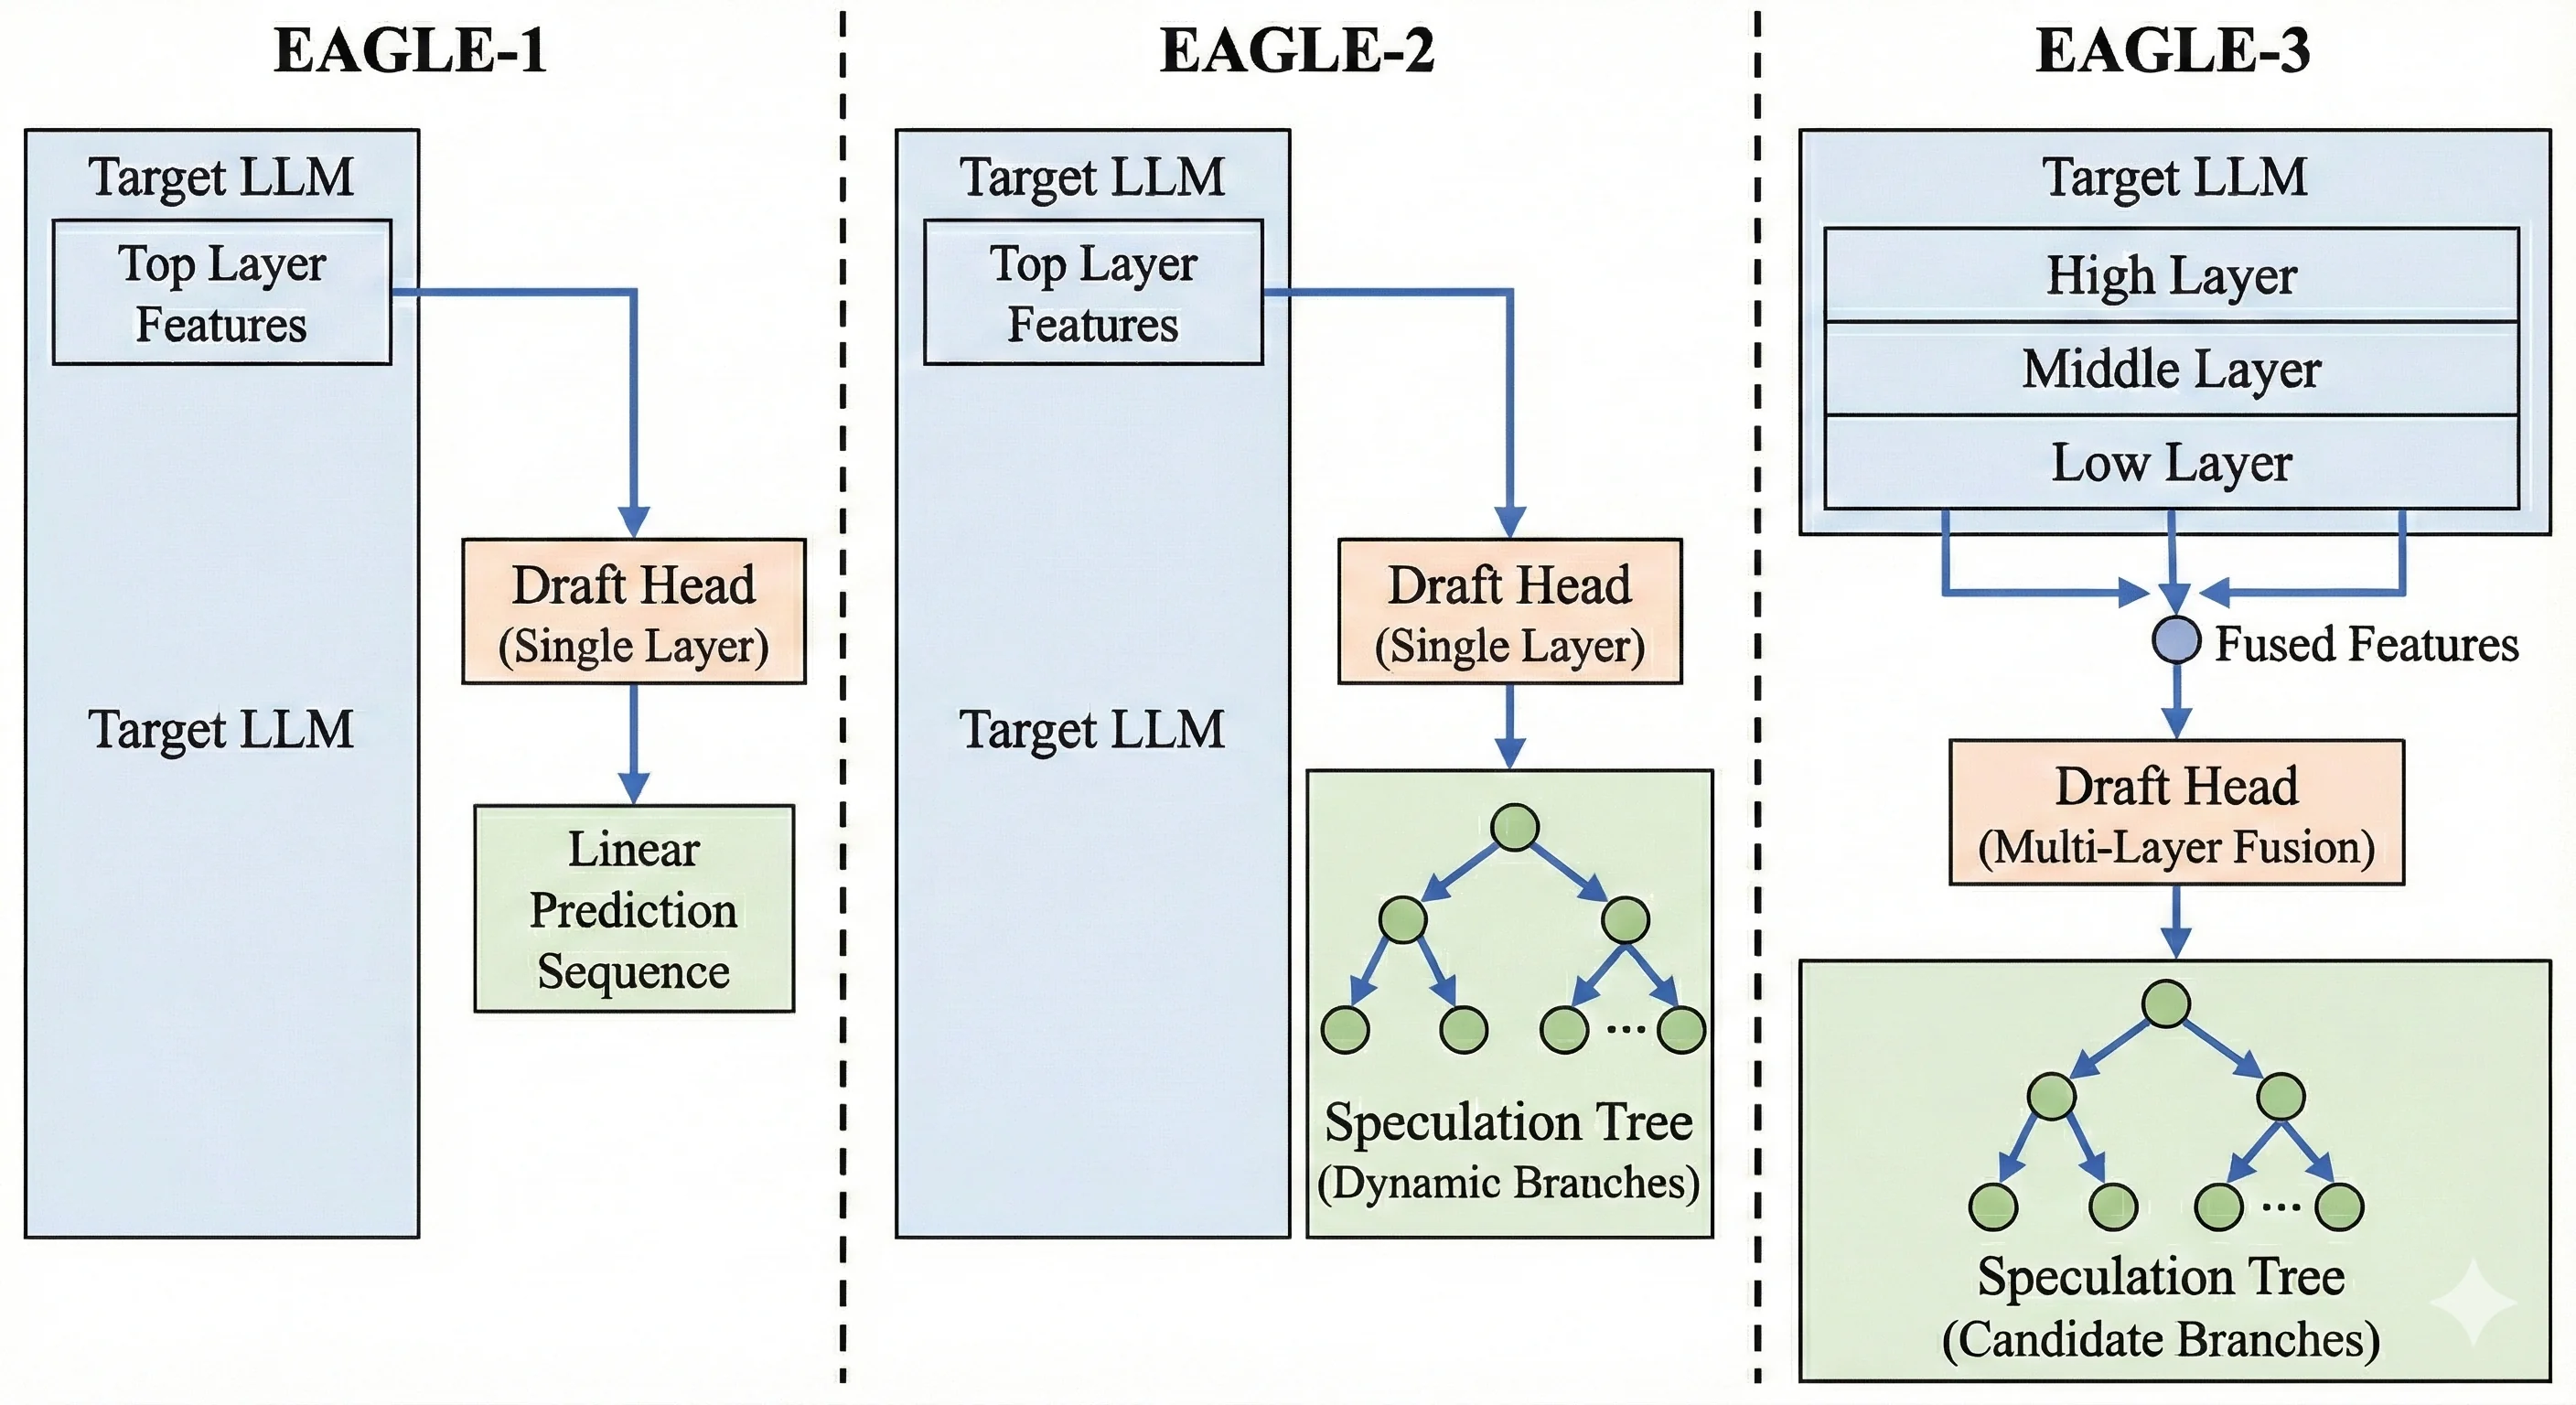
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...

Boosting LLM Inference Speed Using Speculative Decoding | Towards Data ...
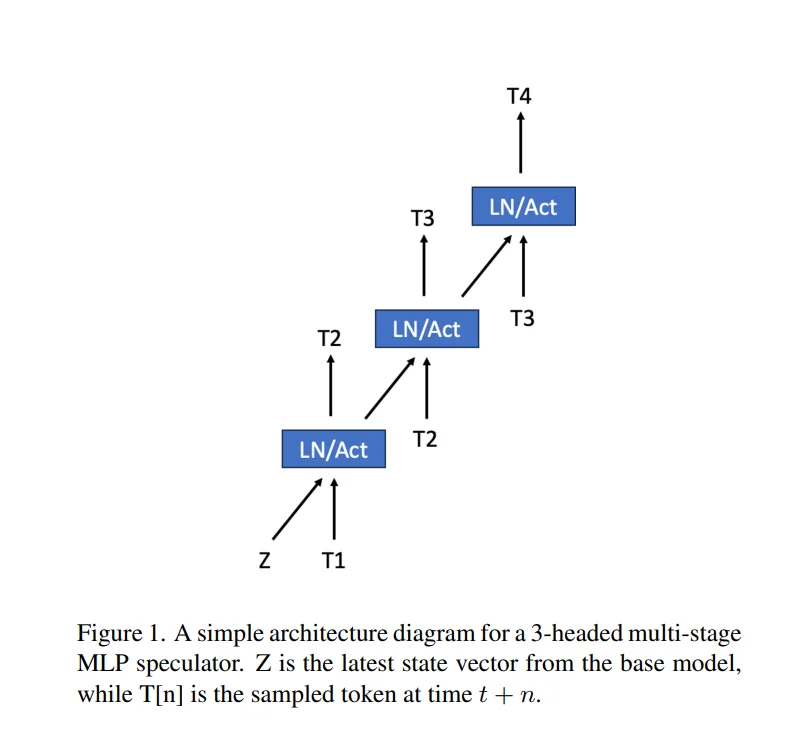
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
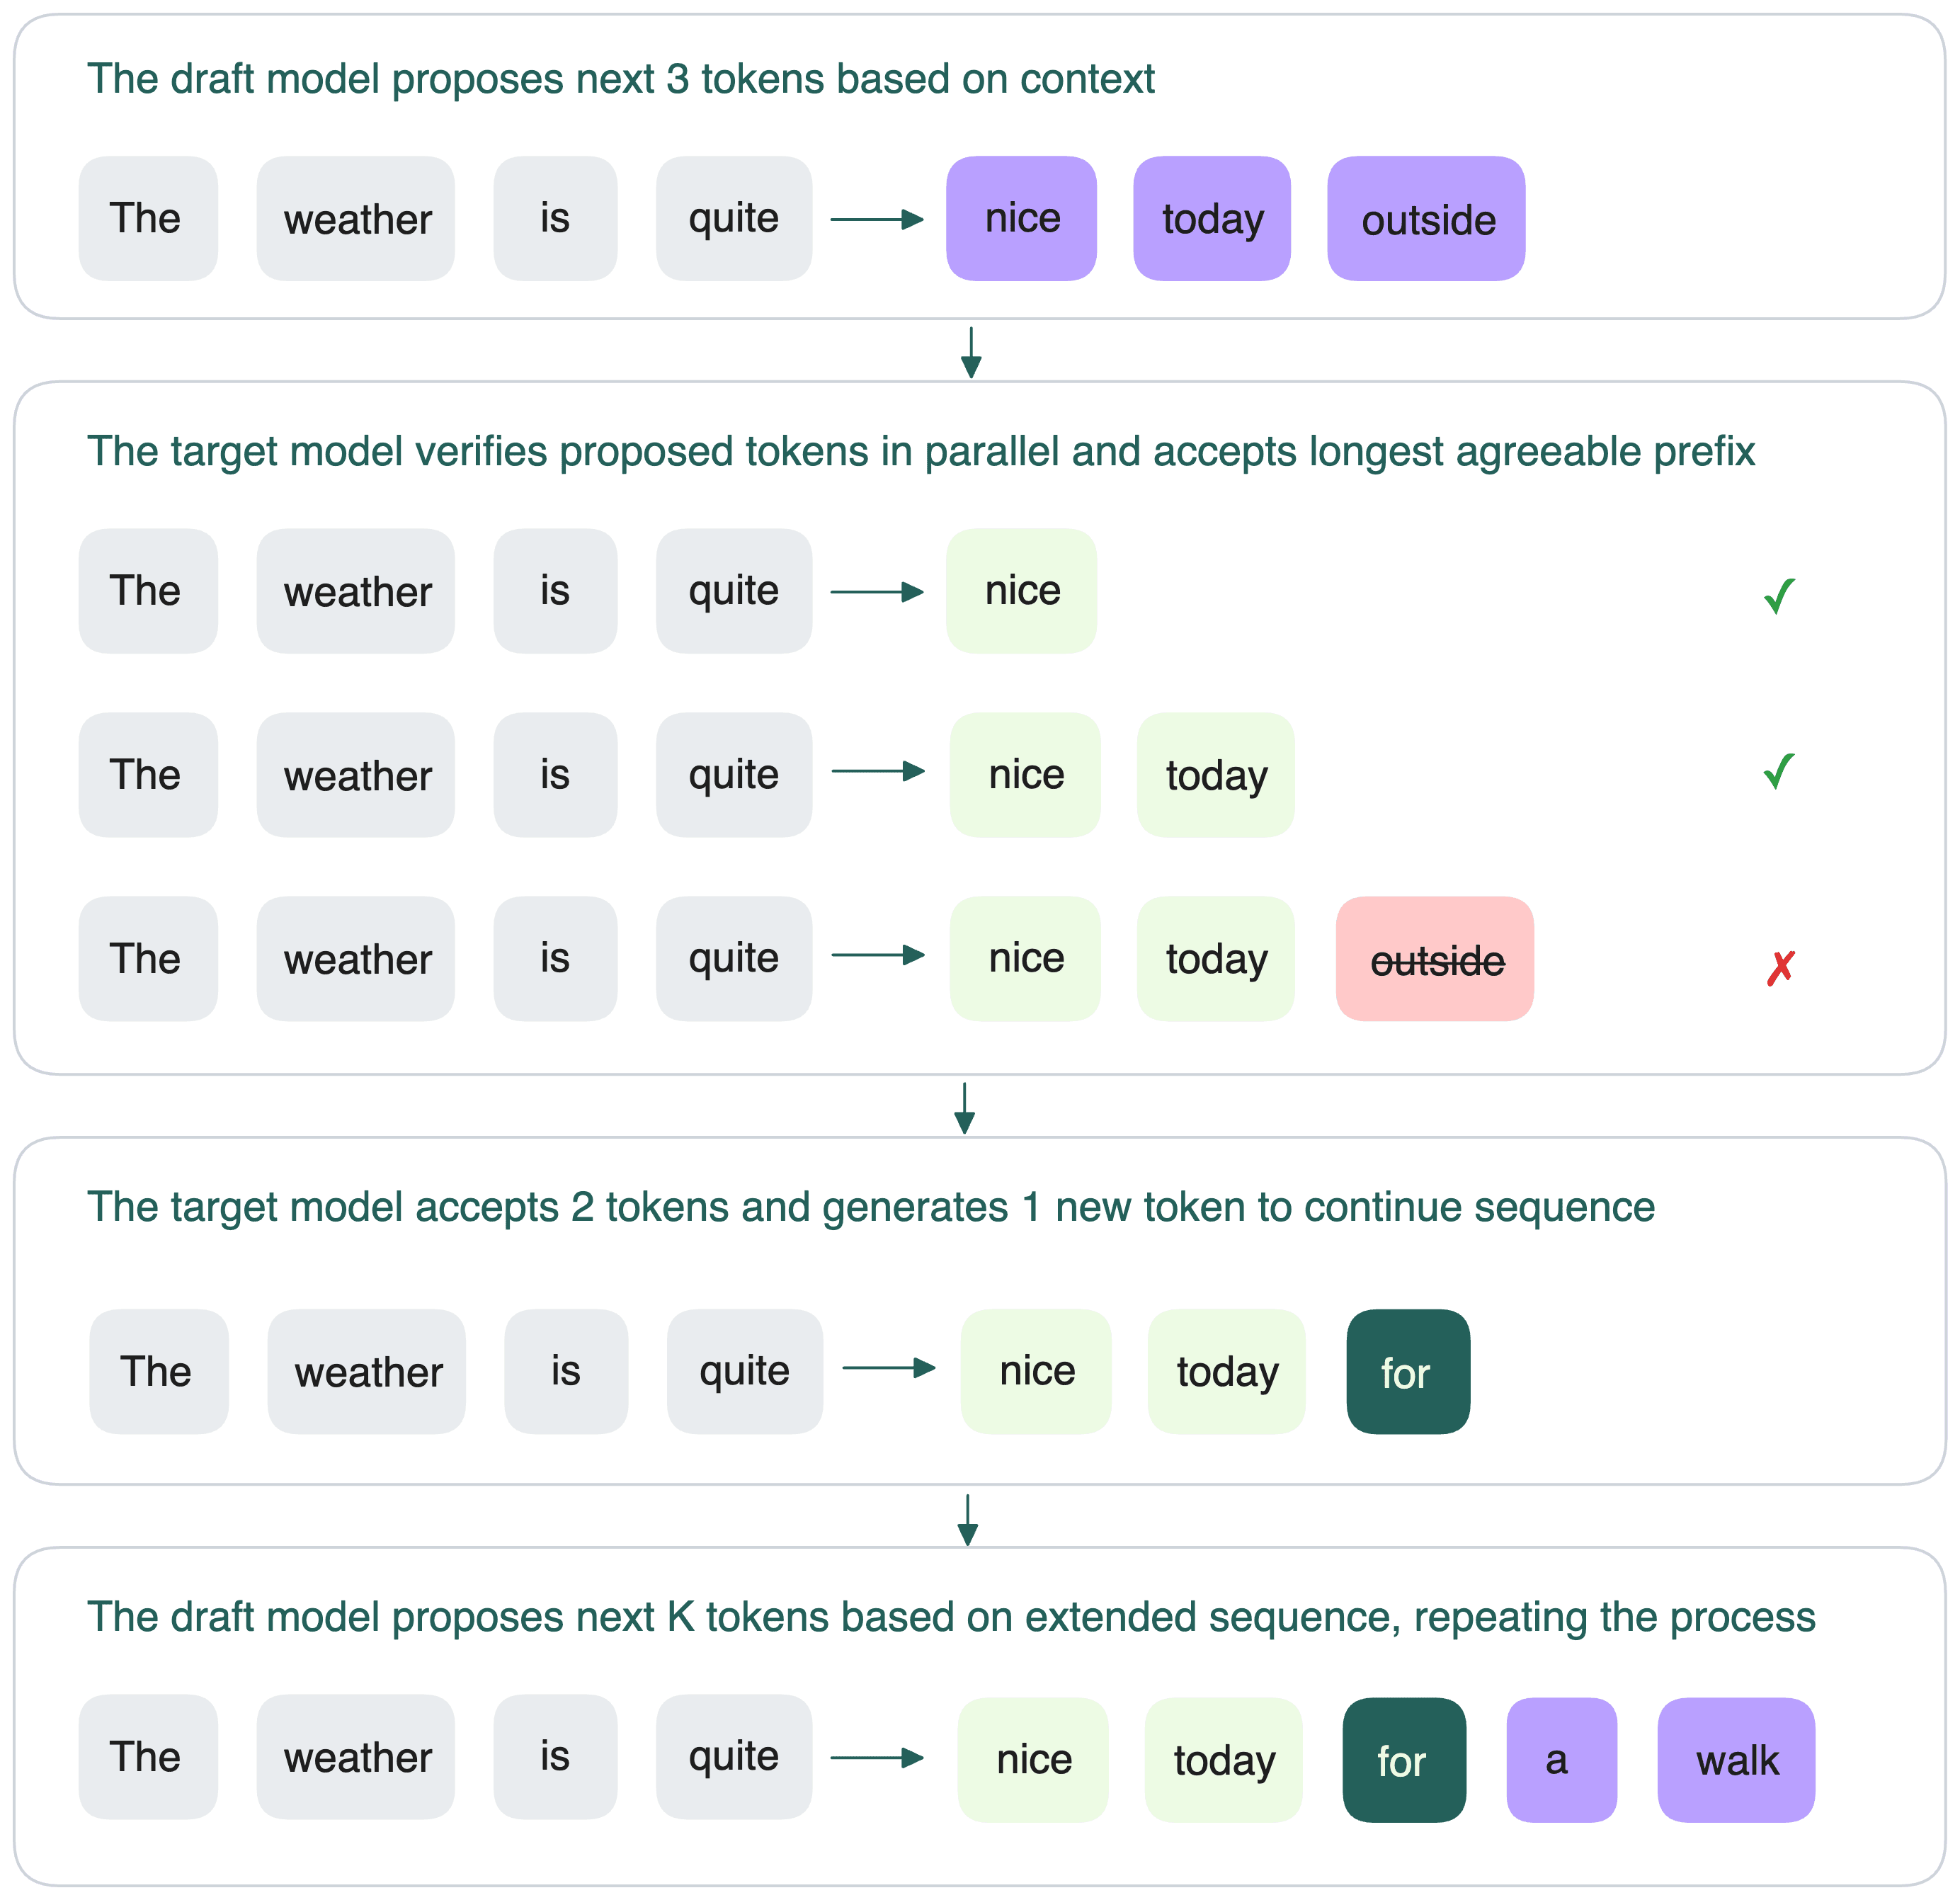
Get 3× Faster LLM Inference with Speculative Decoding Using the Right ...
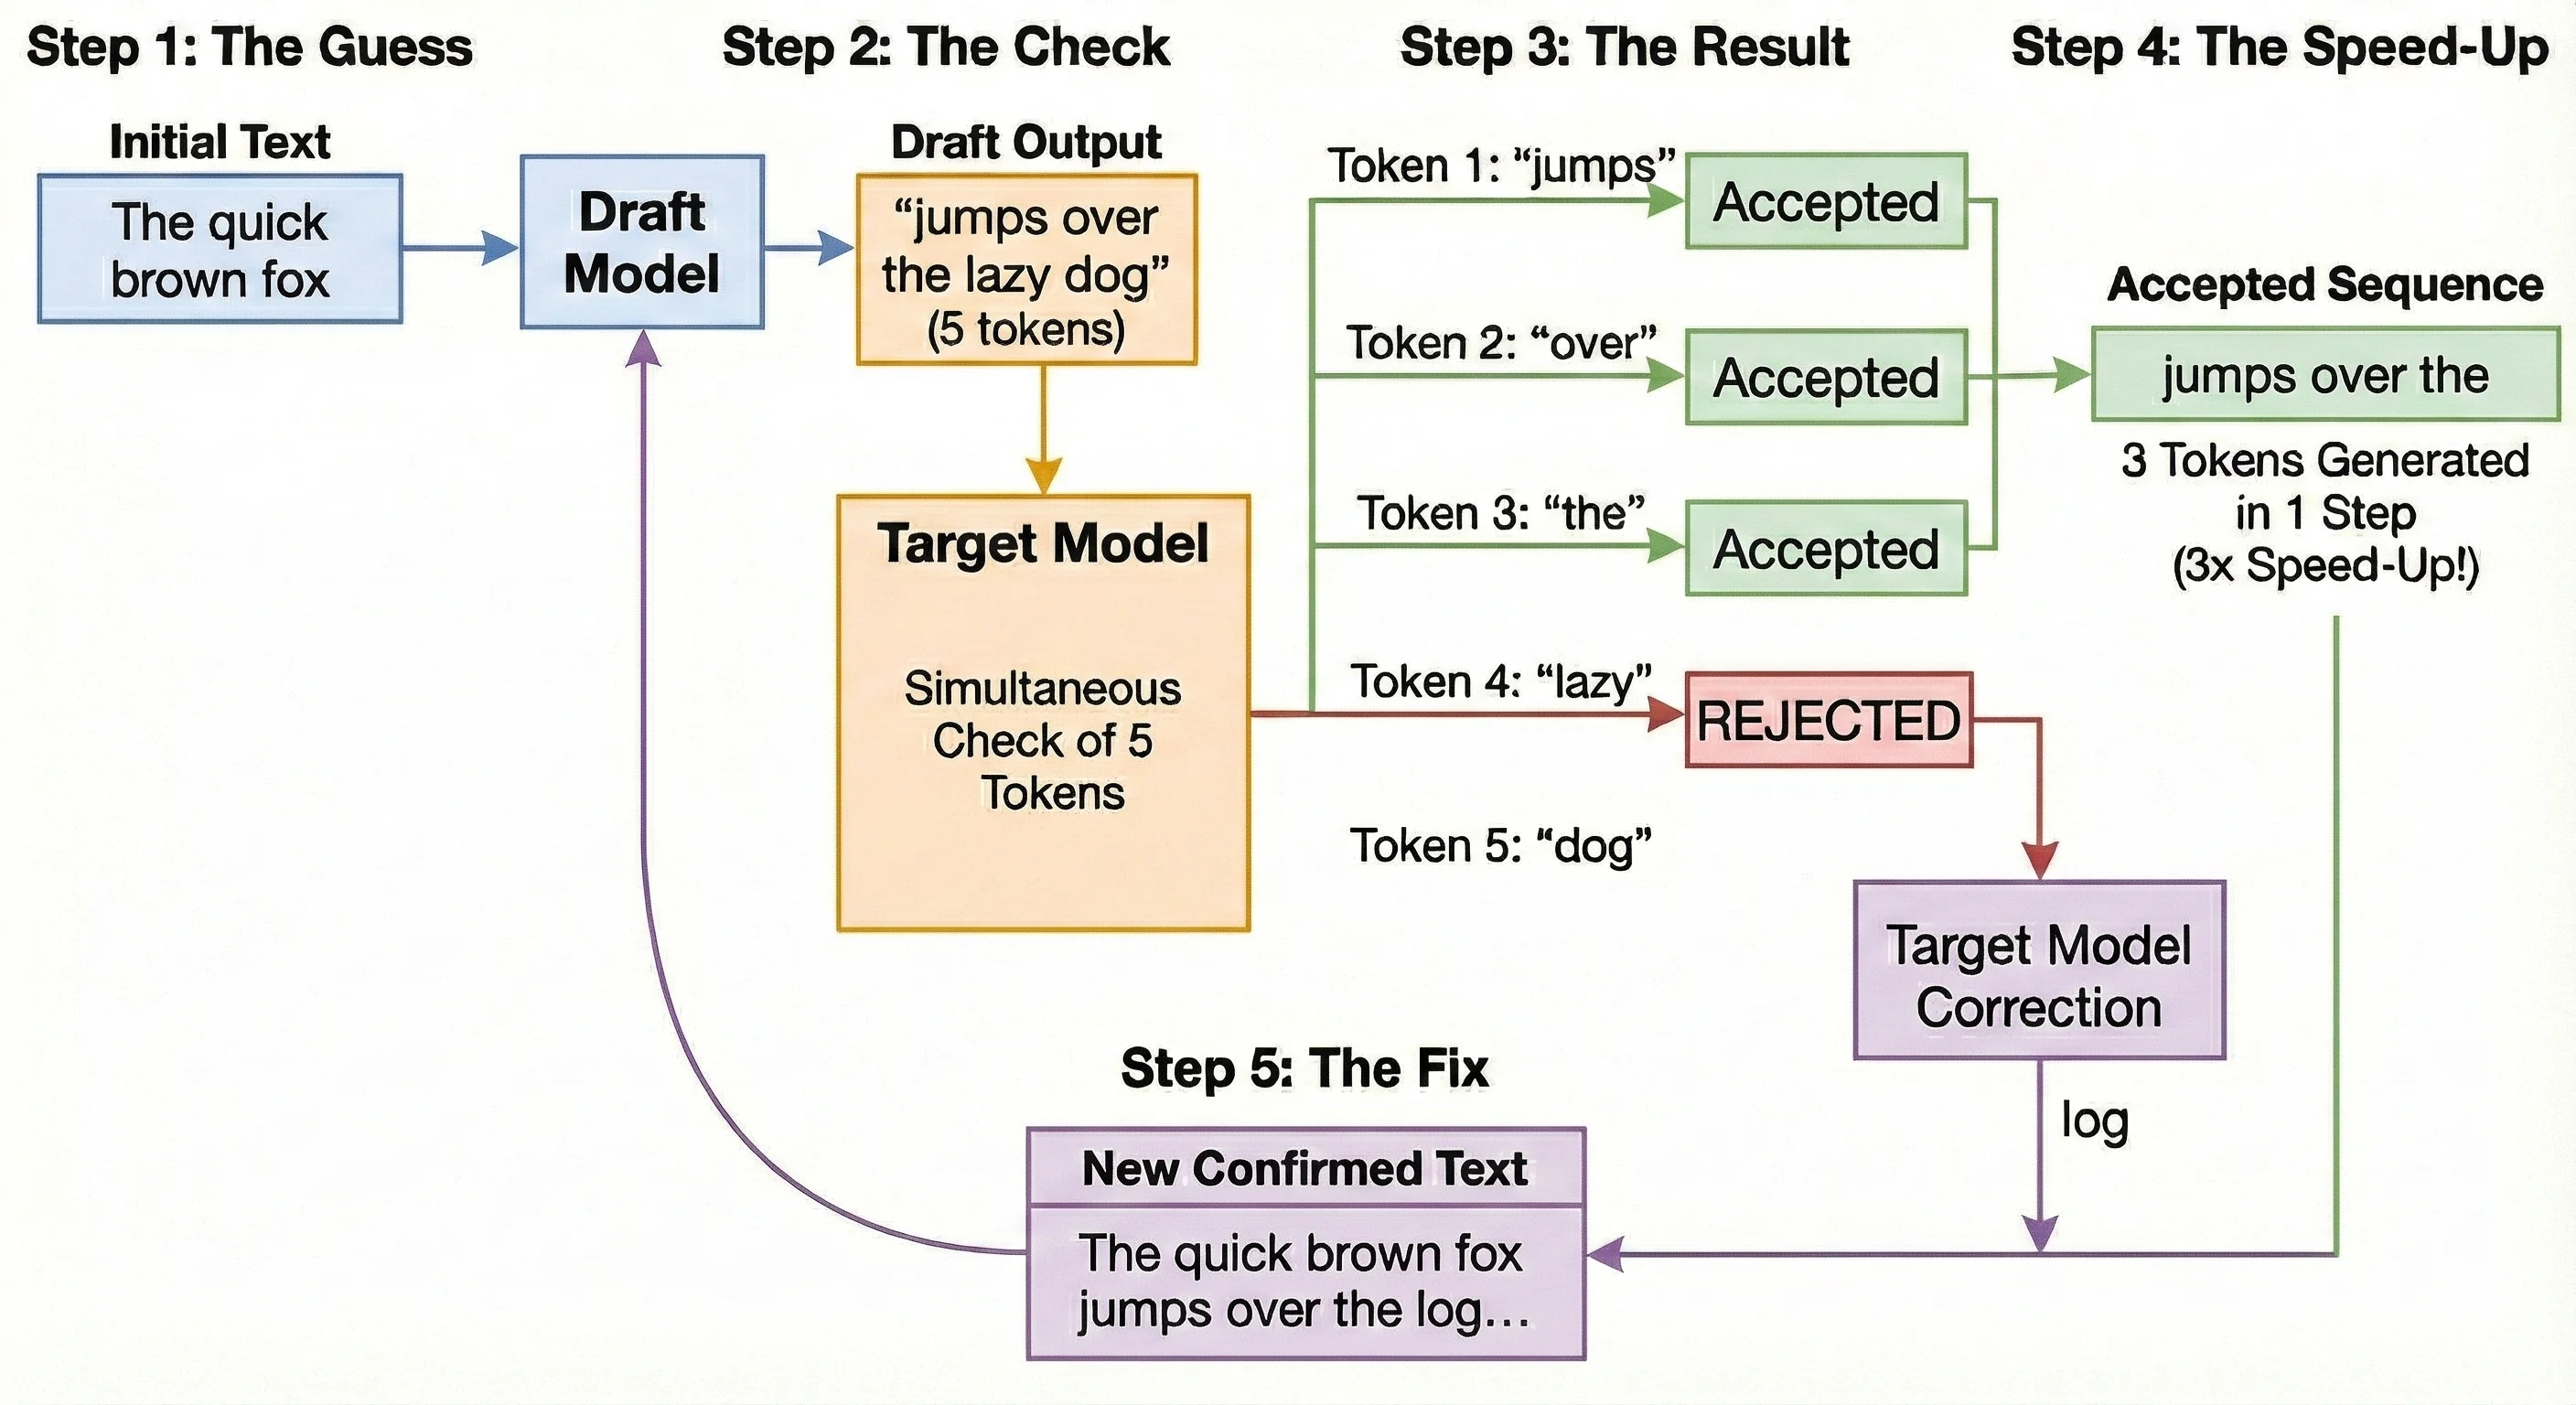
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
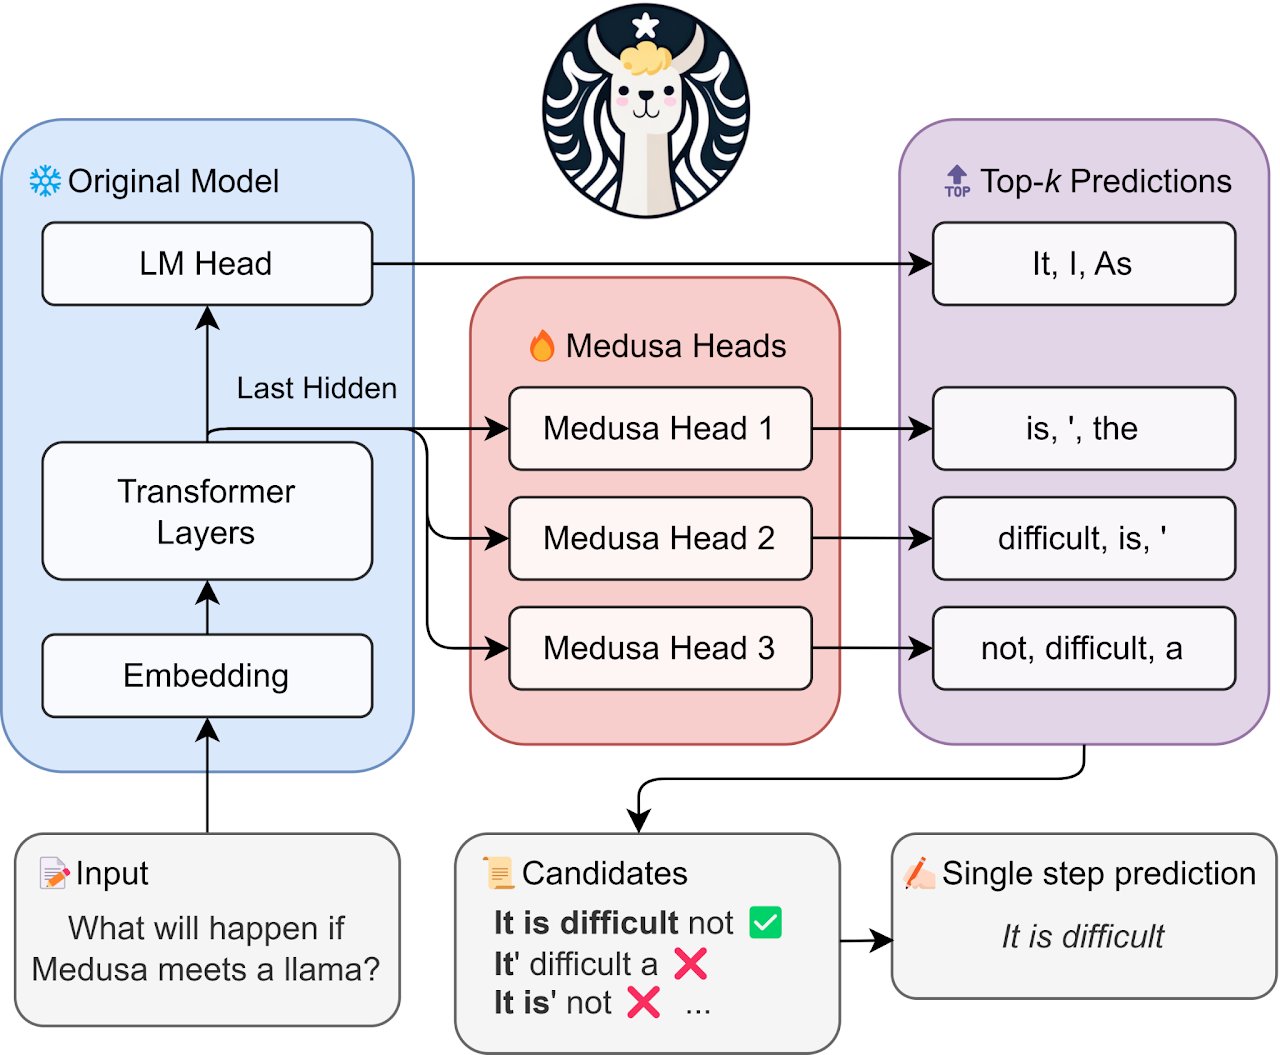
Accelerate LLM Inference with Speculative Decoding | Charles Xu
Advertisement Space (336x280)
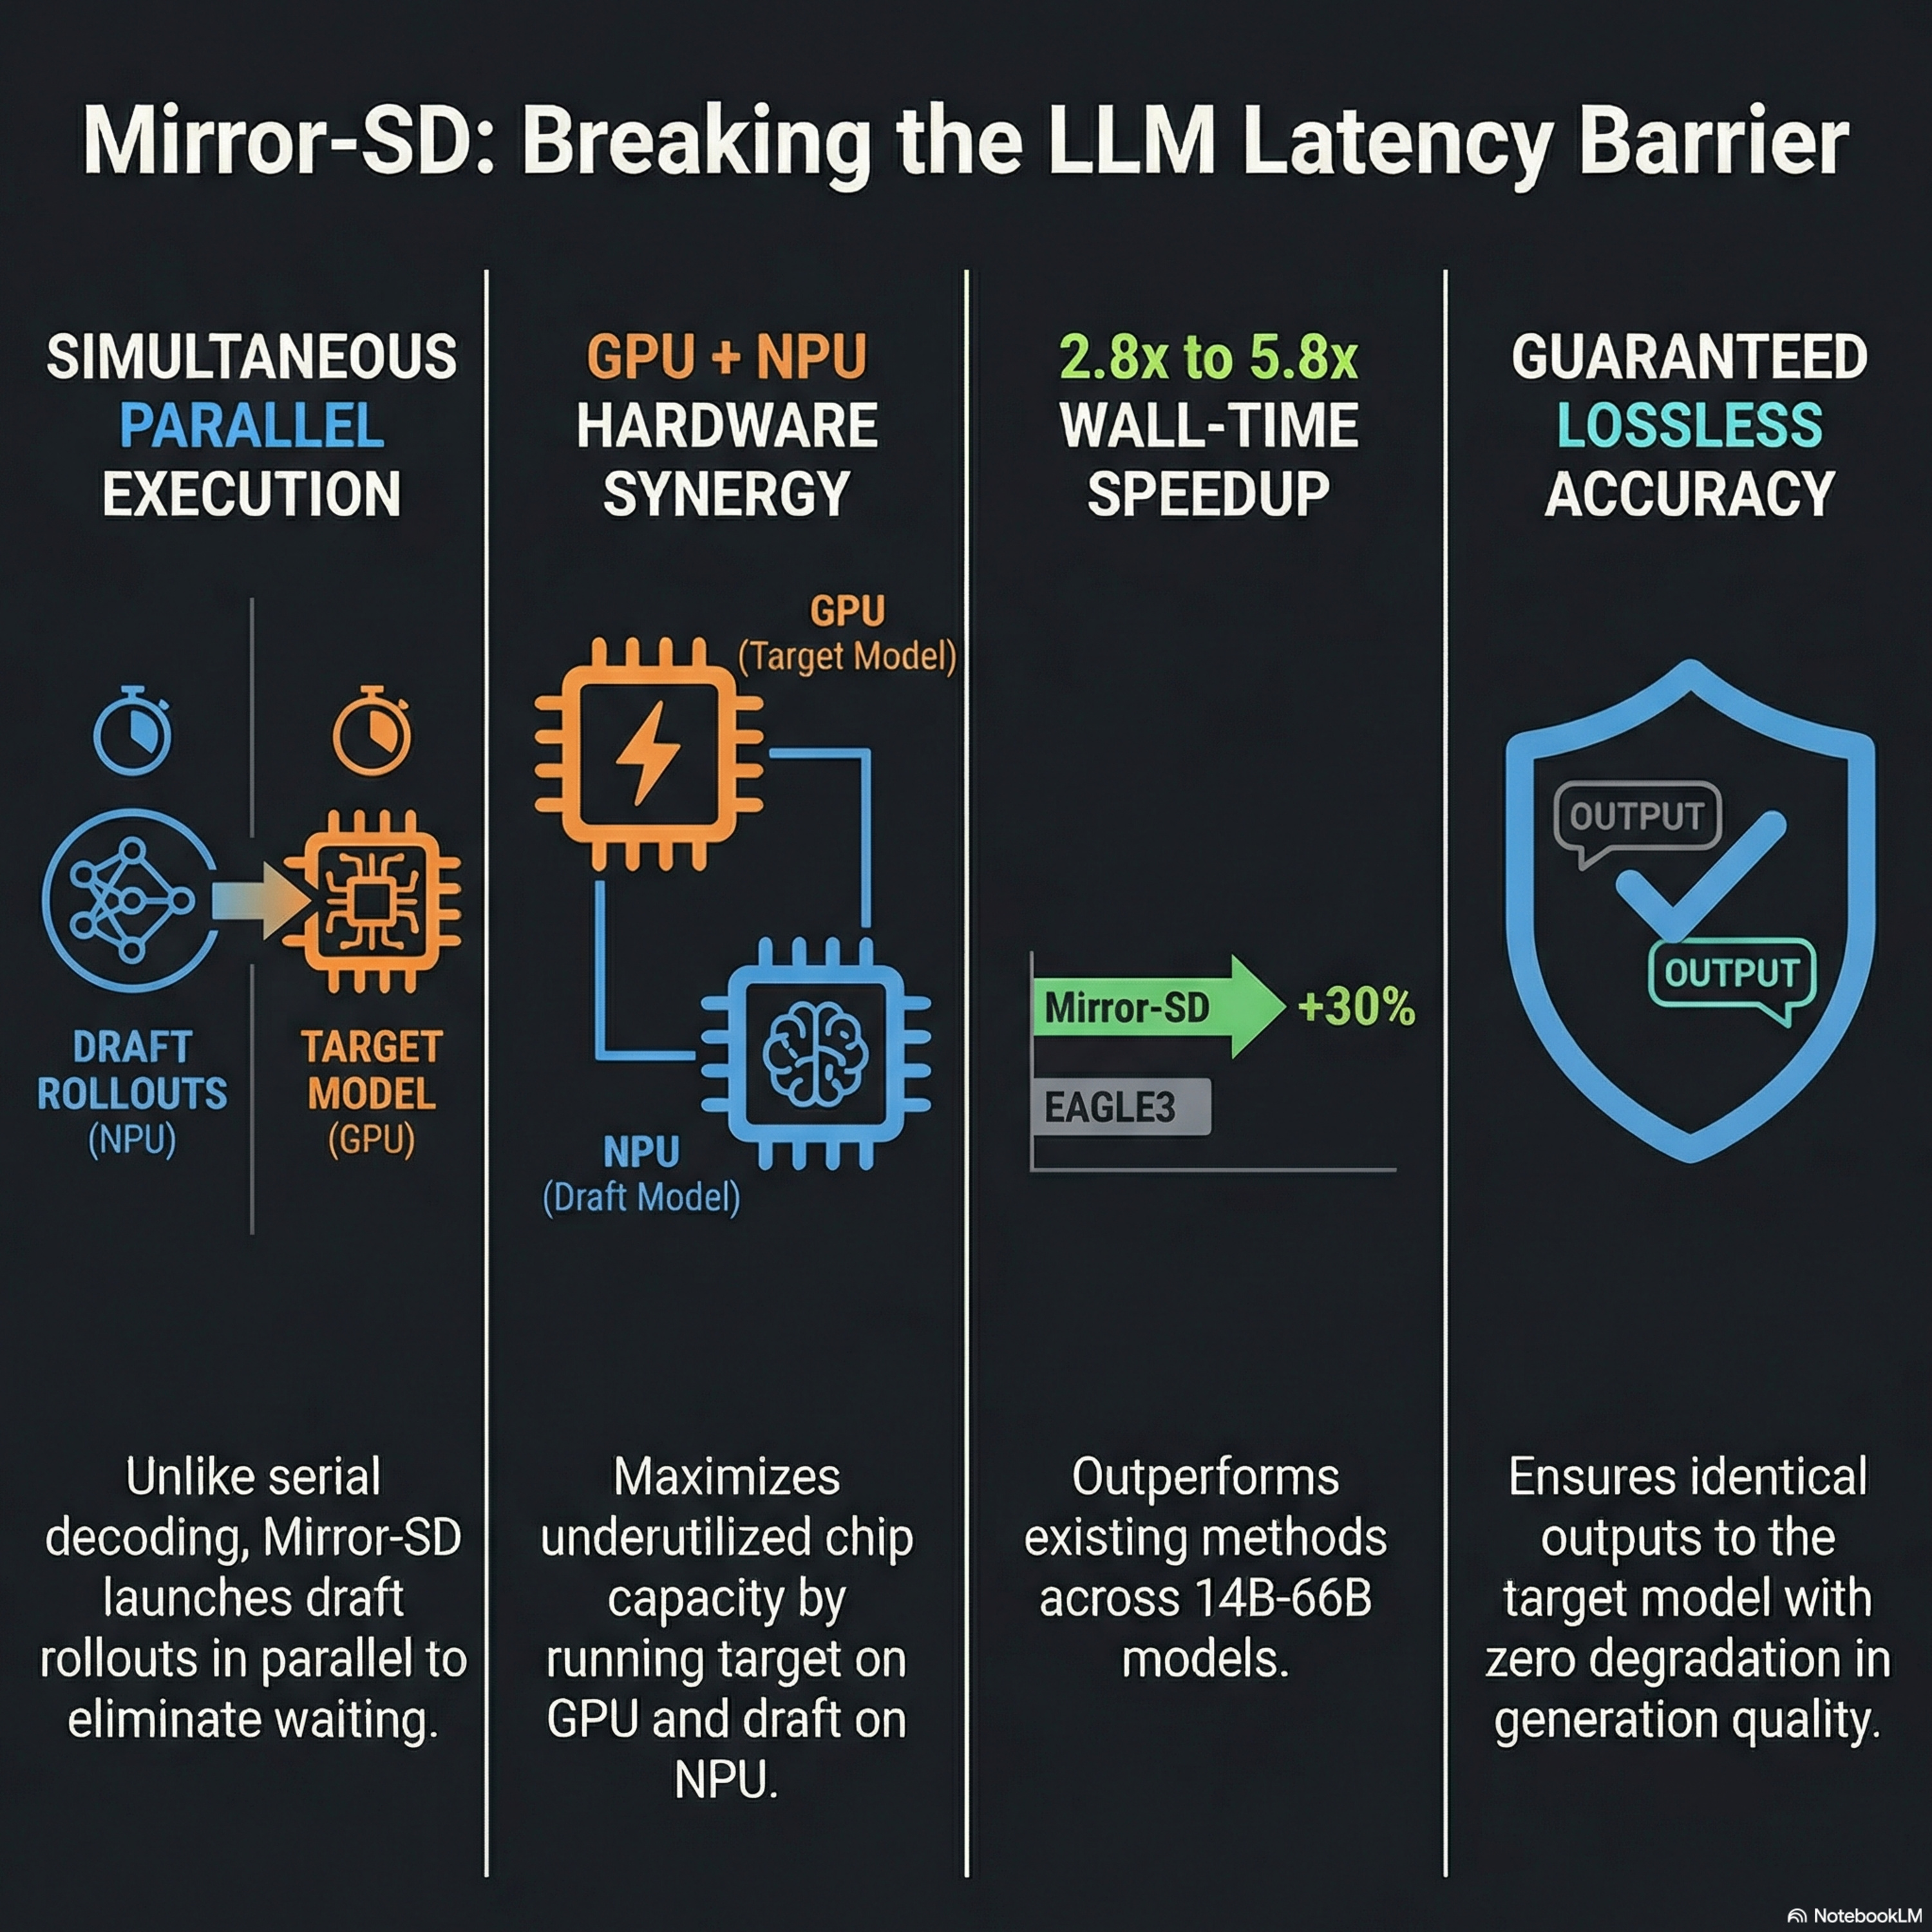
Apple's Mirror Speculative Decoding: Parallel LLM Inference via ...

Parallel LLM Decoding: Speculative and Diffusion

[Literature Review] PEARL: Parallel Speculative Decoding with Adaptive ...

Parallel LLM Decoding: Speculative and Diffusion
Speculative Decoding Production Guide: 2-5x Faster LLM Inference on GPU ...
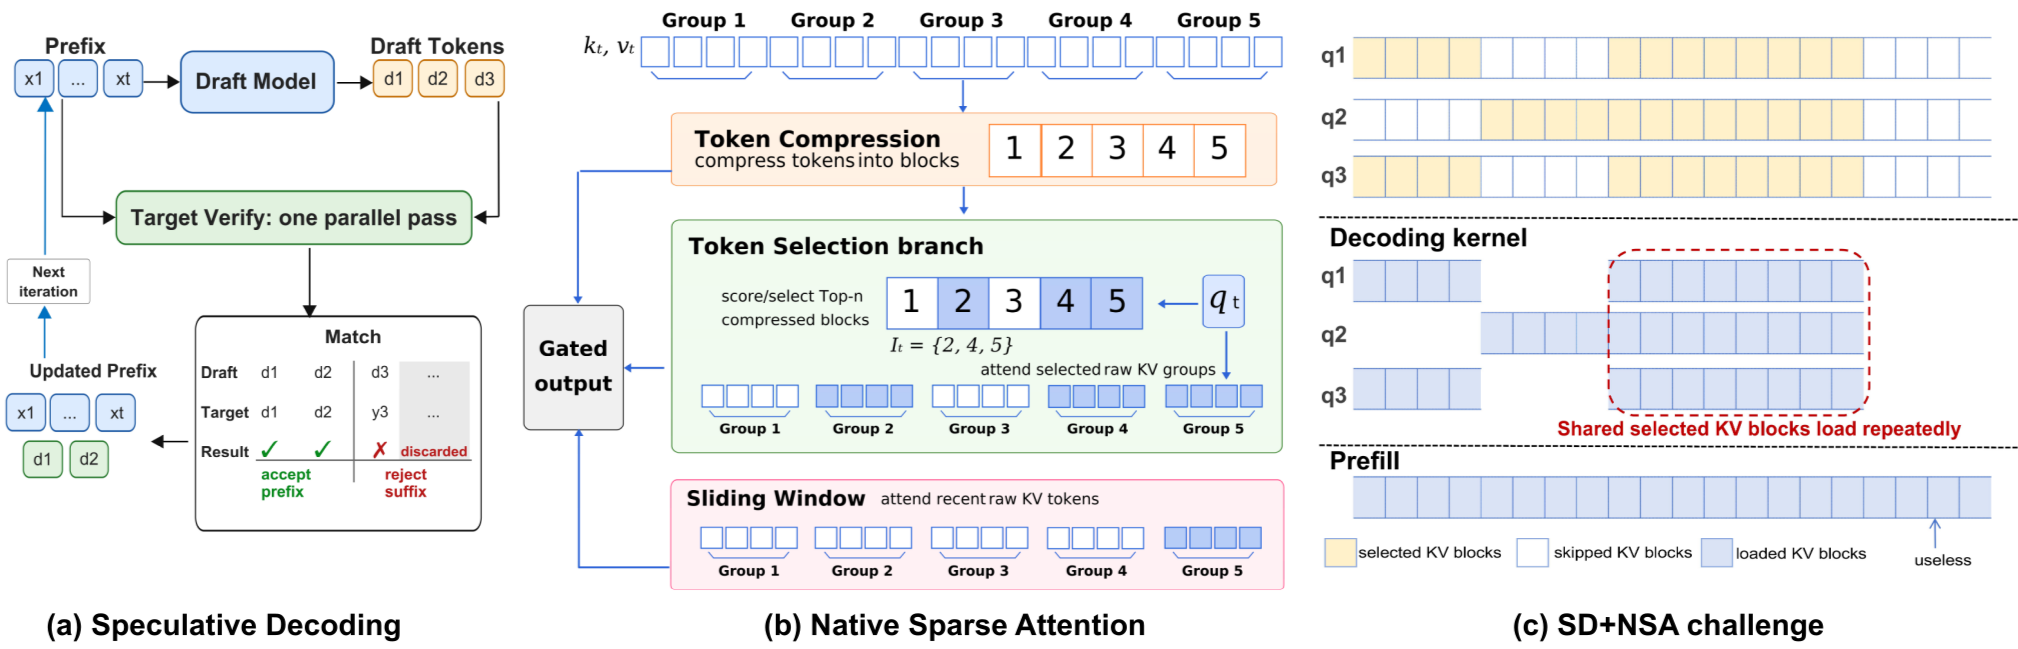
[论文评述] SpecSA: Bridging Speculative Decoding and Sparse Attention for ...

EasySpec: Layer-Parallel Speculative Decoding for Efficient Multi-GPU ...
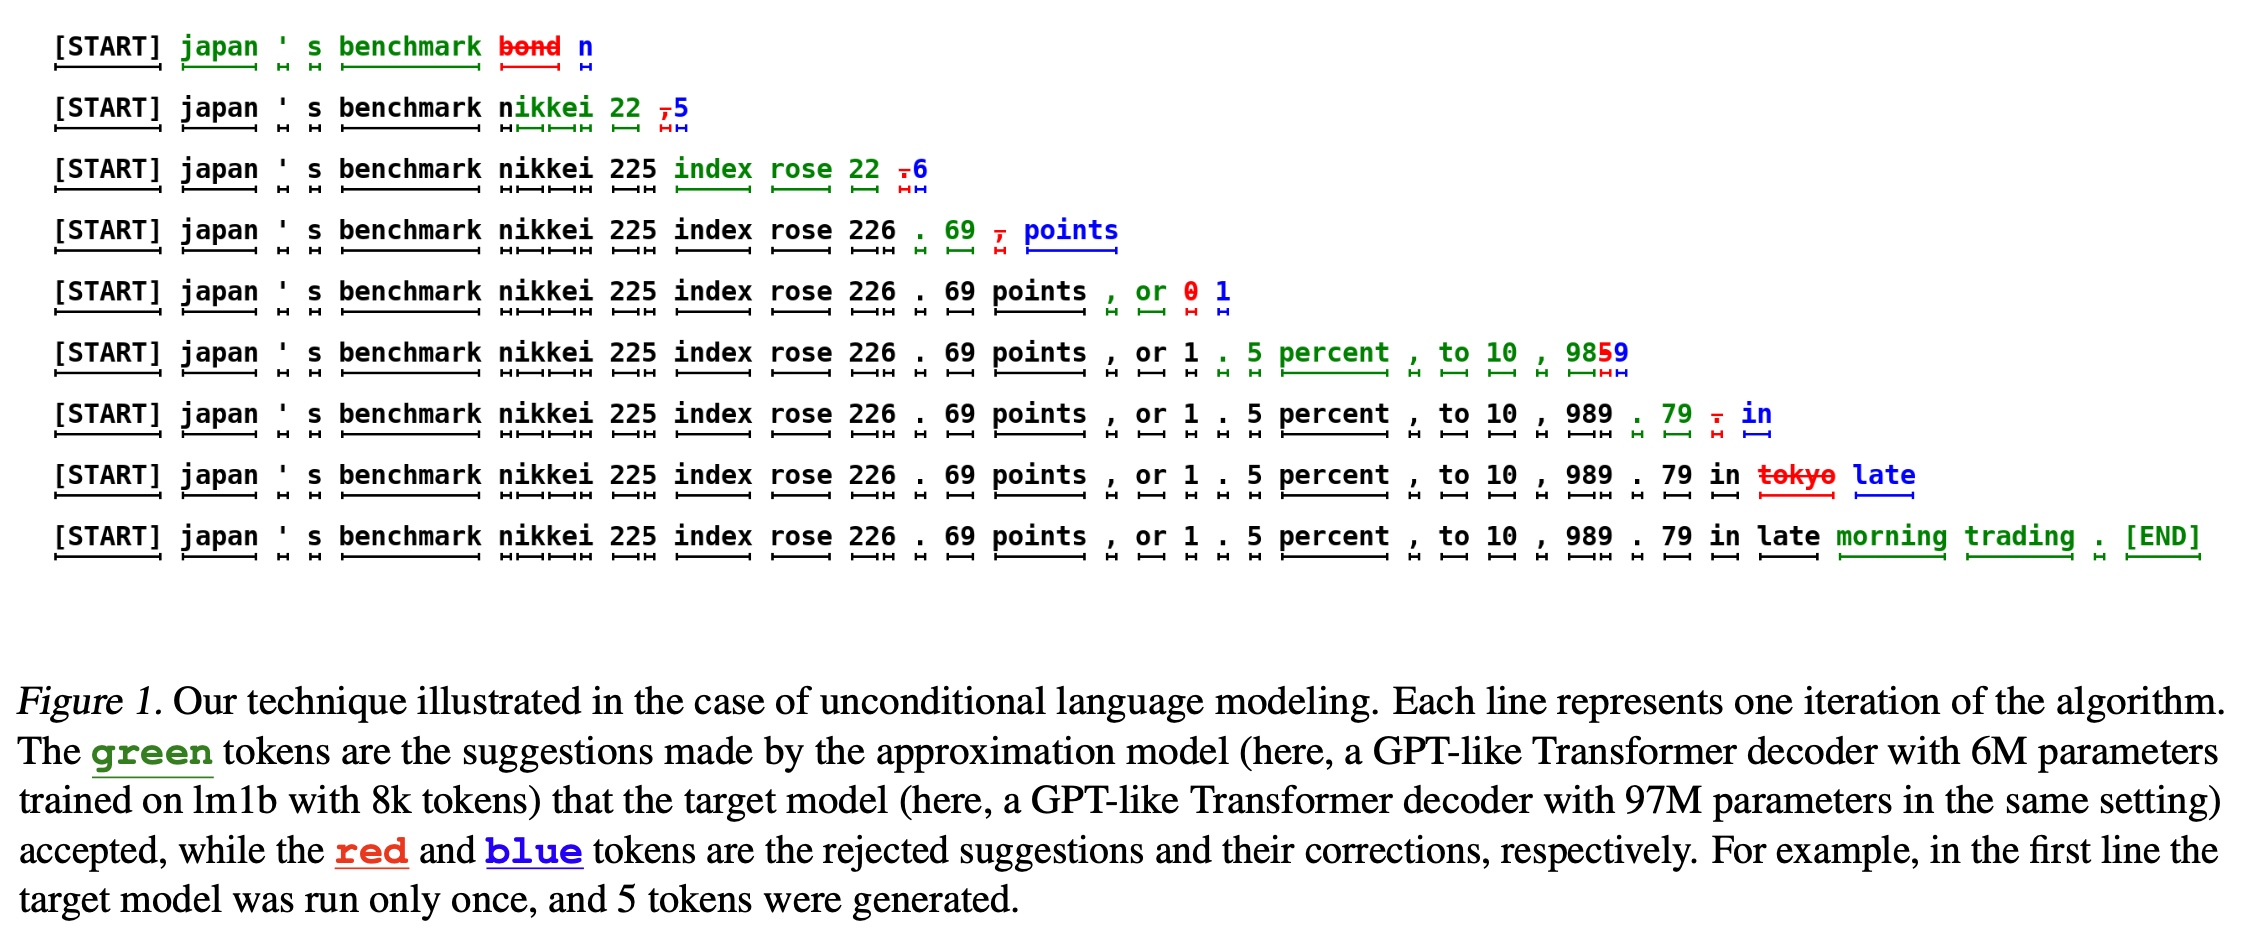
Accelerate LLM Inference with Speculative Decoding | Charles Xu

Speculative Decoding in Decentralized LLM Inference: Turning ...
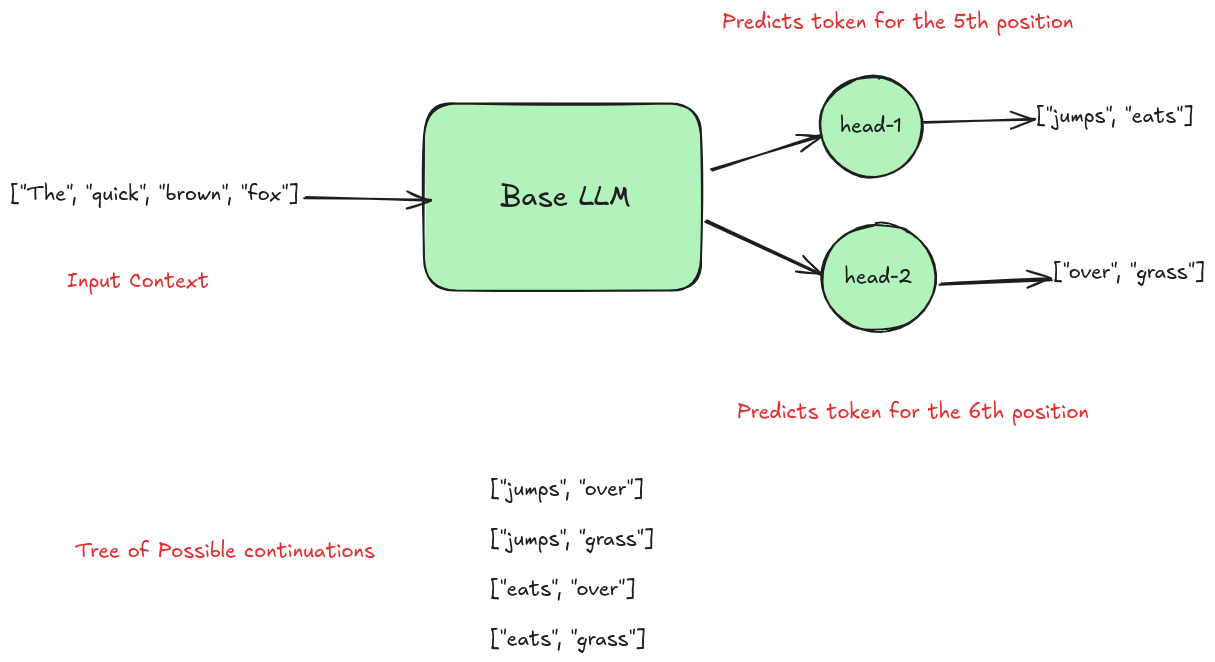
A Survey of Speculative Decoding Techniques in LLM Inference
Advertisement Space (336x280)

[논문 리뷰] SWIFT: On-the-Fly Self-Speculative Decoding for LLM Inference ...

An Introduction to Speculative Decoding for Reducing Latency in AI ...
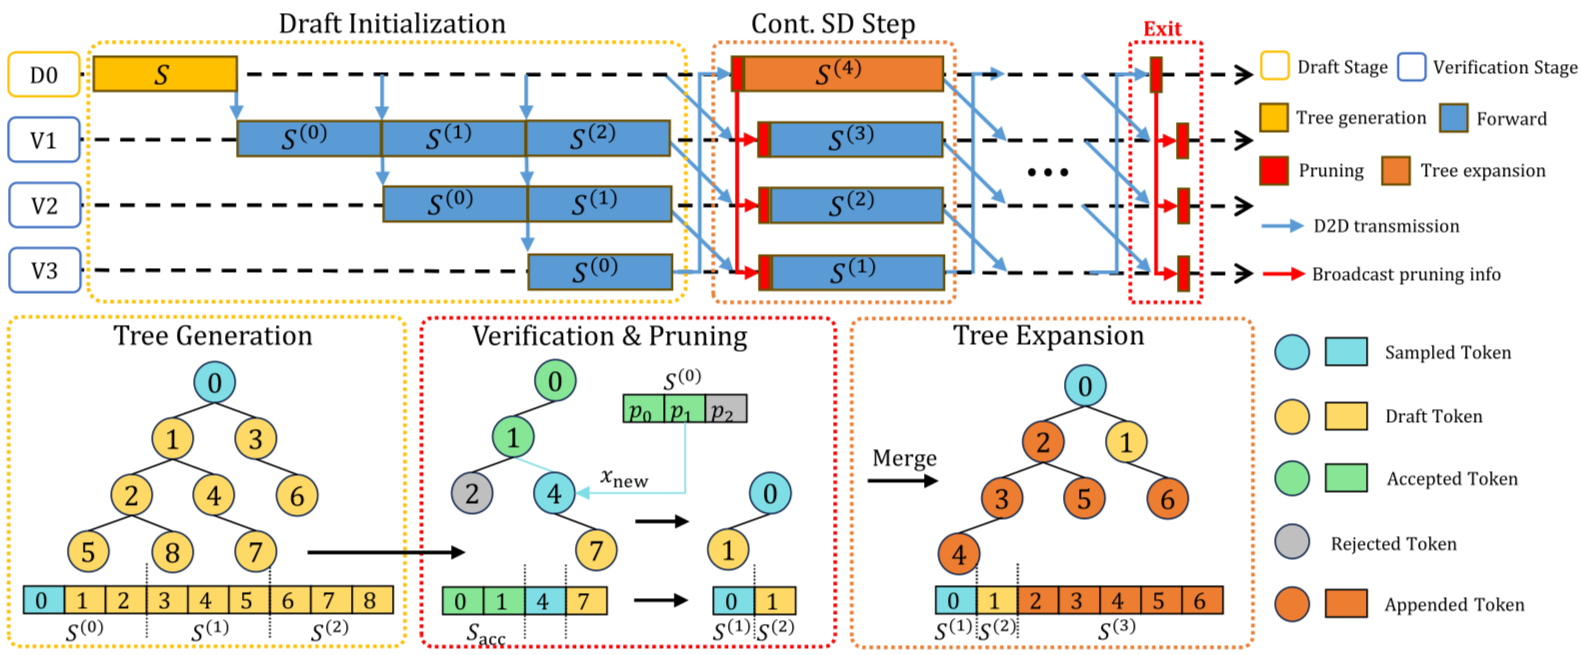
[논문 리뷰] FlowSpec: Continuous Pipelined Speculative Decoding for ...

Speeding Up LLM Output with Speculative Decoding — Arabian Post

This AI Paper Unveils the Potential of Speculative Decoding for Faster ...